A rectangular array whose entries are nondecreasing in each coordinate. Every subarray obtained by restricting to a row interval and a column interval has the same property. Comparing a target with the top-right entry discards a whole row or column, giving staircase matrix search in time linear in the sum of the dimensions.
A real symmetric matrix whose entries are the moments . Thus it is the Gram matrix of the monomials in the real L2 inner product on . For a nonzero real coefficient vector , , so every finite Hilbert matrix is positive-definite. The moment description connects these matrices with polynomial approximation and with the shifted Hilbert quadratic-form bound.
For real , put . The quadratic form equals , proving its nonnegativity. Apply the centred logarithmic keyhole identity bound to the entire function . Since , orthogonality of the finite Fourier sum gives . Multiplication by the contour estimate's factor proves the upper bound. The matrix is the principal submatrix of a Hilbert matrix obtained by deleting its first row and column.
The square matrix obtained by retaining the same index set of rows and columns of a square matrix . Its determinant is a principal minor. A leading principal submatrix uses the first indices.
Evaluate a scalar polynomial on a square matrix by replacing its variable with that matrix and its constant term with a multiple of the identity matrix. Powers of the same matrix commute, so . For an eigenvector , .
A matrix representing observations and their measured variables. A common convention uses observations as rows and variables as columns; stating this orientation avoids transposition ambiguities. Column centering subtracts each variable's sample mean, and is the sample covariance matrix of centered data when .
A real matrix is a matrix whose entries are real numbers. The vector space of real matrices is denoted .
A nonsymmetric matrix is a square matrix unequal to its transpose. Its right eigenvectors need not be orthogonal, and it need not be a diagonalizable matrix. For instance, has eigenvectors and for its distinct eigenvalues. A starting vector has nonzero inner product with but zero coefficient in that direction in the eigenbasis. This is why power iteration and inverse iteration require a nonzero spectral component rather than an ordinary nonorthogonality test in the general case.
Matrices of the same shape are added entry by entry. For fixed dimensions over a field, this operation and scalar multiplication make the matrices a vector space. A matrix product has a different dimension-matching rule: its inner dimensions must agree, whereas addition requires the entire shapes to agree.
A matrix whose entries are complex numbers. For an endomorphism of , Hermitian matrices and unitary matrices are distinguished by their behavior under the conjugate transpose.
An integer matrix is a matrix whose entries are integers. Sums and products of compatible integer matrices remain integer matrices, but a nonsingular square integer matrix can have a nonintegral inverse matrix. The unimodular matrix condition characterizes exactly when that inverse matrix also has integer entries.
A Cauchy matrix has entries with nonzero denominators. If are distinct, it is positive definite: is the Gram matrix of linearly independent exponential functions. This form occurs in finite-rank inverse scattering transform reconstructions.
A matrix norm is a norm on a vector space of matrices; common choices include induced operator norms and the Frobenius norm. A submultiplicative matrix norm additionally satisfies . The matrix 2-norm is the norm induced by Euclidean norms and equals the largest singular value.
A vector norm on a finite-dimensional real or complex vector space induces the displayed matrix norm on its linear operators. It is the corresponding operator norm, and the supremum can equivalently be taken over the unit sphere. Applying the length bound twice proves submultiplicativity: , hence .
For each row, the weighted Cauchy-Schwarz inequality gives . Summing over rows bounds the result by the maximum absolute row sum times the maximum absolute column sum times . Taking square roots and the supremum proves the displayed induced matrix norm inequality. It gives a Euclidean estimate directly from entries without computing singular values.
For a real symmetric positive-definite matrix , the energy norm is . In the defining supremum of the induced matrix norm, substitute . The matrix square root is an invertible matrix, so this ranges over every nonzero vector and proves the displayed identity. This matrix similarity is useful because contraction in the energy norm becomes an ordinary Euclidean operator norm estimate after a change of coordinates.
A matrix pencil is an affine one-parameter family of matrices. For square matrices of size , its determinant is a polynomial of degree at most . If is invertible, its leading coefficient is , so at most distinct parameters give a singular matrix. This translates linear dependence in a family of bases into polynomial root counting.
A real rectangular matrix is totally nonnegative if every square minor, with row and column indices in increasing order, is nonnegative. A nonnegative bidiagonal matrix is totally nonnegative, and products of compatible totally nonnegative matrices have the same property by the Cauchy–Binet formula. This controls signs of inverse entries and underlies stability and shape-preserving properties of B-spline collocation. Total nonnegativity permits zero minors; strict total positivity requires every such minor to be positive.
If an invertible square totally nonnegative matrix has size , then andIndeed the adjugate identity gives , and the deleted-row/deleted-column minor is nonnegative. Consequently an alternating vector gives .
An elementary column operation interchanges two columns of a matrix, scales one by a nonzero scalar, or adds a multiple of another column. It is an elementary row operation on the transpose. Hence it has the same three effects on the determinant: changing sign, multiplying by the scale factor, or leaving the determinant unchanged.
The reduced column echelon form of a matrix is defined by taking its transpose, forming the reduced row echelon form, and transposing back:It is obtained from by elementary column operations. Its nonzero columns precede its zero columns, the topmost nonzero entry of each nonzero column is , these leading entries move strictly downward as the column number increases, and each leading entry is the only nonzero entry in its row.
Every elementary column operation preserves the column space, because it and its inverse express each new column as a linear combination of the old columns. Thus the nonzero columns of the reduced form give a basis of the original column space. In contrast, elementary row operations preserve the row space. There is no general identity : the definition requires reducing , not .
For an invertible matrix of size , both reduced forms are . A singular example showing the distinction is
A Hadamard matrix is a real square matrix with entries and whose rows are pairwise orthogonal. Each row has squared norm , so and is an orthogonal matrix. In particular is invertible, with . The four-by-four exampleis symmetric and satisfies . It supplies an exact intertwiner in four-tile mixed-boundary transplantation between a disk and a nonorientable surface.
A matrix with the same number of rows and columns represents an endomorphism of a finite-dimensional vector space after choosing a basis. Square matrices support trace, determinant, powers and the matrix exponential.
For with real matrices , the same linear map viewed over the reals has block matrix in grouped real/imaginary coordinates. Interleaved coordinates merely permute the basis. Its complexification splits into the matrices and , giving the realification determinant identity.
The realification of a complex matrix has real determinant . Indeed the invertible complex coordinate change conjugates its complexified block matrix to . Taking determinants gives the identity, including singular matrices.
For a real matrix , the entrywise L1 norm is , the L1 norm of its vector of entries. It is the usual penalty in the all-entry convention for the Graphical Lasso.
Applying a scalar function separately to each matrix entry: . This differs from spectral matrix functional calculus. In particular, in Gaussian hyperplane rounding is entrywise, and its contribution to a matrix trace can be restricted to selected blocks by the support of the other matrix.
The matrix with entries . It differs from ordinary matrix multiplication. The Schur product theorem states that it preserves positive semidefiniteness when both factors are positive semidefinite matrices.
For integer , the entrywise power has entries and equals the repeated Hadamard product. The zero power is the all-ones matrix, even at zero entries, because it represents the constant function one. Every nonnegative integer Hadamard power of a positive semidefinite matrix is positive semidefinite by the Schur product theorem. It is not an ordinary matrix power.
The Hermite normal form is a canonical triangular form for an integer matrix under integer elementary row operations or, in the column convention, column operations. In the row convention for a nonsingular rank-two matrix, positive diagonal entries and reduction of the upper-right entry modulo the lower diagonal entry give the row Hermite normal form in rank two.
The row lattice of an integer matrix with rows is the set of their integer linear combinations. It is an Euclidean lattice in its real span, since it is contained in the discrete set and spans that real vector space. For a nonsingular two-by-two integer matrix, the row Hermite normal form in rank two gives a canonical basis and proves that its index in is the absolute value of its determinant.
For a finite-index subgroup , its projection to the first coordinate is and its intersection with the second axis is , with . Choose , reducing modulo . Together with it is a basis of this row lattice: subtracting a multiple of from any vector leaves a vector on the second axis. These parameters are unique, and reduction of the two coordinates shows . Consequently an integral matrix of positive determinant has a unique representative of this form under left multiplication by , with . This proves the lattice facts underlying determinant-n matrix representatives for Hecke operators.
A square real matrix is doubly stochastic if its entries are nonnegative and every row and column sums to . Its positive-entry support satisfies the condition of the Hall marriage theorem: for a row subset , by summing column capacities. Consequently its support contains a permutation matrix.
Let be a doubly stochastic matrix, let be a probability vector, and put . In row with , define on the support where . The positive row entries form a probability vector. Expanding relative entropy and using the column sums givesZero-output rows contribute zero because all their vanish. The row sums supply the normalized comparison laws, while the column sums preserve the input entropy contribution. Equality holds exactly when for every positive matrix entry , including the automatic zero values in zero-output rows.
This doubly stochastic matrix replaces two values by and , preserving their sum. It fixes all other coordinates when embedded in a larger matrix. A finite product of such averaging matrices and permutation matrices is again doubly stochastic.
Every doubly stochastic matrix is a convex combination of permutation matrices. Equivalently, the extreme points of the doubly stochastic convex polytope are exactly the permutation matrices. The extreme-point assertion follows from an alternating-cycle perturbation of a doubly stochastic matrix; the convex-hull assertion follows because a bounded finite-dimensional polytope is the convex hull of its vertices. Permutation matrices are extreme since their zero entries force the same zeros in every convex decomposition.
For a doubly stochastic matrix, the Hall marriage theorem supplies a perfect matching in its positive-entry support. Subtract the smallest matched entry times the corresponding permutation matrix. The residual has equal row and column sums and smaller support unless it vanishes. Repeating gives a convex combination of permutation matrices. With initially positive entries, there are at most terms, since a positive-mass residual has at least positive entries. Elementary augmenting-path matching gives arithmetic operations.
For a doubly stochastic matrix with a fractional entry, form the row-column bipartite graph of entries strictly between zero and one. Every incident vertex has degree at least two, so there is an even cycle. A matrix supported on that cycle with alternating entries has zero row and column sums. A sufficiently small positive multiple can be both added and subtracted while preserving entry bounds. The original matrix is then the midpoint of two distinct doubly stochastic matrices, so it is not an extreme point.
A rational matrix is a matrix whose entries are rational numbers. Multiplying by a common denominator produces an integer matrix and preserves its homogeneous solution set.
A real matrix is nonnegative when every entry is nonnegative. This entrywise condition differs from being a positive semidefinite matrix: the symmetric matrix is nonnegative but has eigenvalues and .
A square nonnegative matrix is irreducible if for each pair there is an integer with . This says that every index can reach every other through positive entries. The Perron–Frobenius theorem then gives a positive leading eigenvector and an algebraically simple eigenvalue. Irreducibility alone permits other eigenvalues of the same modulus: the cyclic permutation matrix has eigenvalues .
A square nonnegative matrix is primitive if some positive integer power has strictly positive entries. It is therefore an irreducible nonnegative matrix. The Perron–Frobenius theorem gives a leading eigenvalue whose modulus is strictly larger than that of every other eigenvalue. Every strictly positive matrix is primitive; the two-cycle permutation matrix is irreducible but not primitive.
The strictly positive case states that a real square matrix with has a positive simple eigenvalue and positive left and right eigenvectors, with all other eigenvalues strictly smaller in modulus. The Brouwer fixed-point theorem applied to on the nonnegative unit simplex gives and . For another eigenvector , maximize ; the triangle inequality gives . Equality forces every modulus ratio and complex argument to agree because every entry is positive, so is proportional to and . Apply the same argument to for a positive left eigenvector; its positive pairing with rules out a generalized eigenvector at , establishing algebraic simplicity. For merely nonnegative matrices a nonnegative leading eigenvector exists. An irreducible nonnegative matrix has a positive leading eigenvector and simple Perron eigenvalue; a primitive nonnegative matrix has the strict modulus gap.
The all-ones matrix has every entry equal to one, where . On , the matrix is the orthogonal projection matrix onto .
For , maps to . Therefore is an eigenvector with eigenvalue , while the zero-sum vector subspace is its kernel. For a basis of the kernel is . These vectors and form an eigenbasis, proving diagonalization and characteristic polynomial . Both algebraic multiplicity and geometric multiplicity are one at and at zero. At the sole eigenvalue is 1; the zero-sum space has dimension zero and contributes no additional root.
The row space of a matrix is the span of its rows, and its column space is the span of its columns. Both have dimension equal to the matrix rank, though they lie in different ambient coordinate spaces for a rectangular matrix.
The row space of a matrix is the linear span of its rows. It is the column space of the matrix transpose.
The column space of a matrix is the linear span of its columns. It is the image of a linear map represented by .
If an matrix has columns , then matrix multiplication gives . Thus its column space consists of exactly the attainable output vectors in , and has a solution exactly when belongs to this column space. Its dimension is the matrix rank; the kernel instead describes input vectors in whose contributions cancel.[ref]
Solution Sets. Interactive Linear Algebra, §2.4.3, Solution Sets and Column Spans: attainable outputs and input solution sets occupy different spaces
A basis of a matrix's column space. Row reduction identifies which original columns to select: take the original columns at the pivot columns of the reduced matrix. Row operations preserve column dependence relations, but generally change the column vectors and their span. Choosing columns of the reduced matrix instead therefore need not give the original column space.
A submatrix is obtained from a matrix by retaining selected rows and selected columns. A principal submatrix of a square matrix retains the same index set for its rows and columns.
A matrix minor is the determinant of a square submatrix obtained by selecting rows and columns of a matrix. Over a field, the matrix rank is less than exactly when every -by- matrix minor vanishes. In a matrix of regular functions, these equations define a closed rank-defect locus, explaining the determinantal variety construction.
A principal minor is the determinant of a square submatrix selected using the same index set for rows and columns. For a three-by-three matrix, the coefficient of in its monic characteristic polynomial is the sum of its three principal minors of order two.
A leading principal minor is a principal minor using the first rows and columns of a square matrix in a specified ordering. Sylvester's criterion uses these minors to characterize positive-definite matrices.
The entrywise maximum norm is the largest absolute value of a matrix entry. For compatible vectors and ,
A tridiagonal matrix has zero entries outside its main diagonal and the two adjacent diagonals. Linear systems with a nonsingular tridiagonal coefficient matrix can be solved in linear time by the Thomas algorithm.
A matrix decomposition expresses a matrix as a matrix product of factors with simpler structure. An LU decomposition uses triangular factors, a QR decomposition uses an orthogonal matrix and a triangular factor, and a singular value decomposition separates input directions, stretching factors and output directions. The factorization is an identity; the chosen structure determines what it helps compute.
For an original two-by-two example,The outer factors are a lower triangular matrix and an upper triangular matrix, each with unit diagonal as in a unit triangular matrix; the middle factor is a diagonal matrix. Their matrix product is , and the final diagonal entry is the Schur complement of the first entry . This is the scalar version of the factorization under block elimination.
To solve , solve with the three factors in their displayed order from left to right: first the lower triangular factor, then the diagonal factor, then the upper triangular factor. The intermediate vectors are and , giving the concise answer . A new right-hand side uses the same factors. This is why Reusing LU factors for multiple right-hand sides is useful: factorization records work that otherwise would be repeated, while forward substitution and back substitution apply it cheaply.[ref]
Convex Optimization by Stephen Boyd and Lieven Vandenberghe. §C.4.1, printed pp. 673–674: block factor-solve interpretation
Different decompositions reveal different features. A Cholesky decomposition uses positive definiteness of a symmetric matrix, while a singular value decomposition also applies to rectangular matrices and exposes matrix rank. The existence and numerical behaviour of the factors depend on their own hypotheses; for example, an unpivoted LU decomposition can fail when a chosen pivot element is zero even though the matrix is an invertible matrix.
An LQ decomposition factors a real matrix into a lower trapezoidal matrix and an orthogonal matrix . Transposing a QR decomposition of proves existence. Equivalently, right Householder transformations clear the part of each row beyond its diagonal while preserving earlier zeros. This factorization is useful for underdetermined systems, complementing the role of QR decomposition in overdetermined systems.
A block matrix partitions its rows and columns into rectangular submatrices called blocks, allowing a matrix calculation to be expressed in terms of those blocks.
A common symmetric saddle-point system couples primal unknowns with constraint multipliers through the displayed block matrix, with symmetric . At , full row rank of and a nonsingular reduced Hessian are exactly the nonsingularity conditions. Such matrices arise from equality-constrained quadratic models and mixed finite element methods. A regularized block also arises when an augmented linear system replaces a badly scaled quadratic-penalty Newton system.
A block matrix is block diagonal if all off-diagonal blocks vanish. It represents independent actions on a direct sum of vector spaces. Its determinant is the product of the diagonal-block determinants.
A block tridiagonal matrix has nonzero blocks only on its main block diagonal and the two adjacent block diagonals. It is the block analogue of a tridiagonal matrix.
A square matrix is diagonally dominant when the absolute value of every diagonal entry is at least the sum of the absolute values of the other entries in its row.
A matrix is strictly diagonally dominant when every diagonal-dominance inequality is strict. A real symmetric strictly diagonally dominant matrix with positive diagonal is positive definite by the Gershgorin circle theorem.
If , then is invertible and its operator norm on satisfies the displayed bound. For , choose maximizing . The reverse triangle inequality gives . Taking proves injectivity and hence invertibility in finite dimensions; taking arbitrary proves the bound. The estimate is useful for converting strict diagonal dominance into quantitative matrix inverse stability.
The matrix transpose interchanges rows and columns: . On a fixed matrix space, is the transposition map, a linear map that preserves the trace norm but is not completely positive in dimensions greater than one.
For real rectangular matrices, expanding leaves the quadratic remainder , whose matrix norm is . Thus the displayed Fréchet derivative is a linear map in the increment . At an orthogonal matrix, its kernel consists of increments with skew-symmetric. This is the tangent-space condition obtained by differentiating .
For compatible finite matrices, the transpose reverses the factor order. Entrywise, , proving the identity. The analogous formula for conjugate transpose is . Commutativity of scalar entries permits the last rearrangement; the matrix products themselves are not assumed to commute.
Over a field of characteristic two, the linear map , , has kernel of a linear map the symmetric matrices, of dimension . Its image of a linear map is the linear subspace of symmetric matrices with zero diagonal, of dimension . Indeed, means , and every symmetric zero-diagonal matrix is the image of the matrix obtained by retaining just its entries above the diagonal. Thus the two dimensions still add to , as required by the rank-nullity theorem.
For a matrix over the real numbers or complex numbers, applying the transpose twice to gives . A nonzero matrix is therefore possible only for or . These cases are precisely the symmetric matrices and skew-symmetric matrices, respectively. For every other scalar, the only solution is the zero matrix.
For a positive-definite Hermitian matrix with spectral decomposition , the matrix logarithm is . More generally it is a branch of the inverse of the matrix exponential when such a branch exists.
On complex symmetric matrices with positive-definite real part, the determinant has a nonzero analytic square root normalized positively on real positive matrices. It is continued within this accretive domain. For , put with real eigenvalues ; then , using positive-real-part roots for each factor. The principal scalar square root of the product determinant need not equal this continued root: accumulated determinant arguments can cross the scalar branch cut. The principal matrix logarithm instead tracks all factors consistently.
For a positive-definite Hermitian operator and a unit vector , the weights form a probability distribution. Scalar logarithmic concavity bounds their average of by the logarithm of their average of . Positive semidefinite operators follow by a limiting convention. Using the eigenbasis of a density operator gives , where is the spectrum of and the diagonal of in that basis. This yields nonnegativity of quantum relative entropy without commutativity.
An invertible complex Jordan block , with , has logarithm , where . Applying this construction blockwise and conjugating back proves surjectivity of the matrix exponential on the complex general linear group. There is no globally single-valued continuous choice of logarithm.
For positive-definite Hermitian matrices , Klein's inequality giveswith equality exactly when . To prove it, let be their eigenvalues and their orthonormal eigenvectors. The weights have row and column sums one. The difference between the two sides isby the scalar logarithm inequality . Equality requires whenever , implying . Limits extend the result to positive semidefinite matrices with the appropriate support condition. Applying it to trace-one matrices proves nonnegativity of quantum relative entropy.
A cube root of a matrix is a square matrix of the same size over the specified field satisfying . Every complex invertible matrix has one: put it in Jordan normal form, choose a scalar cube root of each nonzero eigenvalue, and apply the truncated binomial cube root of the identity plus a nilpotent matrix on each block. The Nilpotent Jordan block has none, even though its square is nonzero. If , then , making a nilpotent matrix of size three; the Cayley-Hamilton theorem then gives , a contradiction.
Compute a nonnegative integer power by repeated squaring. If , use ; if , use . This needs matrix multiplications and permits fast evaluation of fixed-order linear recurrences via a companion matrix. It is distinct from computing the matrix exponential .
If a diagonalizable matrix has distinct eigenvalues , its spectral projections of a diagonalizable matrix are and . Raising the diagonal form to a nonnegative integer power gives the displayed formula. Equivalently, interpolate the scalar function by a degree-one polynomial at , then apply it to . The diagonalizability assumption matters: knowledge of two eigenvalues alone does not exclude nontrivial Jordan blocks.
For a linear operator on an inner product space with an orthonormal basis , its matrix elements are , using the convention that the inner product is linear in its second argument. For a finite-dimensional space, the expansion explains why these numbers represent the linear operator in that basis. In quantum mechanics, the expression is also called a matrix element between the two states; it need not be diagonal or an expectation value.
A matrix element of an interaction operator between hadron states. It contains strong interaction dynamics beyond the explicit CKM matrix factors of a weak interaction decay; its magnitude and strong phase need not be identical for two different channels.
A sparse matrix has few nonzero matrix elements in each row or column compared with its dimension. Algorithms normally require an efficient oracle that lists the positions and values of those entries.
A band matrix has nonzero entries confined to a band around its main diagonal. The nonnegative integers in the displayed condition are its lower and upper bandwidths. A tridiagonal matrix has . Storing only the band reduces memory use; banded Gaussian elimination can exploit the same structure when the pivoting assumptions permit it.
Compressed sparse storage keeps a sparse matrix as numerical nonzero values, their row or column indices, and pointers to the start of each compressed column or row. It avoids allocating all entries. A sparse direct solver must additionally allocate possible fill-in predicted by symbolic factorization, because elimination can create entries absent from the input.
The bandwidth in this convention is the largest distance from the main diagonal of a nonzero matrix entry. A symmetric positive-definite matrix of bandwidth can be factored using operations and storage; its Cholesky decomposition does not introduce entries outside that band. A variable permutation changes bandwidth, so it is a property of both the sparsity pattern and its ordering.
The matrix unit has entry one in row , column , and zero in every other position. The matrix units form the standard basis of the vector space of matrices of a fixed size.
The matrix rank of an matrix over a field is the dimension of its column space, equivalently the dimension of its row space. It counts linearly independent column directions, with . Counting nonzero matrix entries gives a different quantity: an all-ones matrix can have arbitrarily many nonzero matrix entries and still have matrix rank one.[ref]
The Rank Theorem. Interactive Linear Algebra, §2.9, Definition: rank is column-space dimension; the row-space equality is proved below
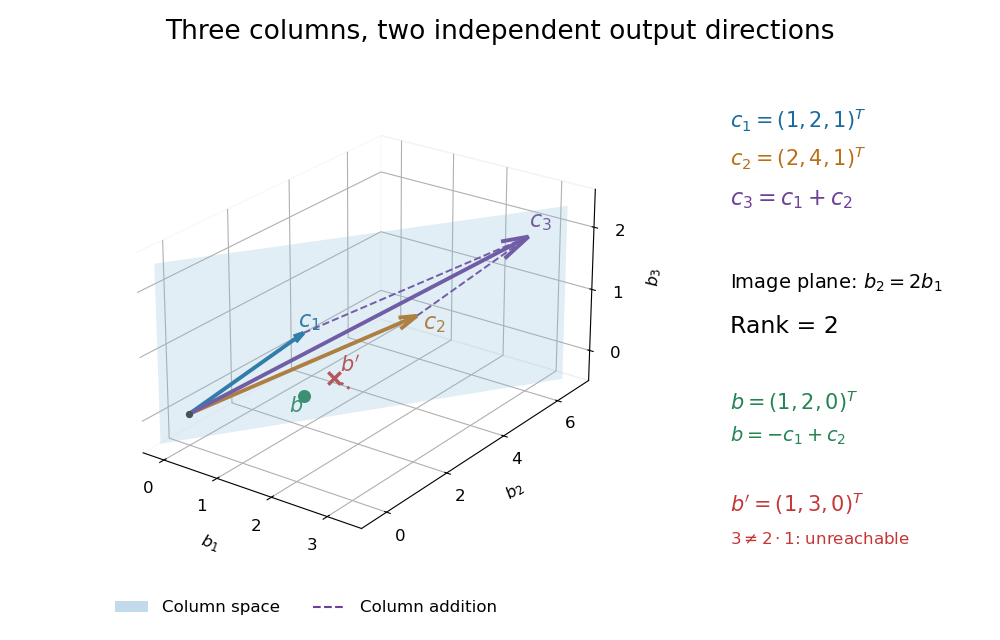
Consider the following matrix over the real numbers, with columns written as vectors:The vectors are linearly independent: requires both and , so . The third column adds no new direction to their linear span, hence despite all nine matrix entries being nonzero. The second row likewise repeats twice the first row.
The column space is a plane through the origin:Every output has second coordinate twice its first coordinate. Conversely, any vector equals , so this condition describes the entire plane, not just part of it. For example, is attainable, whereas lies outside the plane.
Elementary row operations expose the same count algebraically. Apply and , interchange the last two rows, multiply the second row by , and subtract twice the second row from the first. The resulting reduced row echelon form isThere are two pivot columns, so the matrix rank is two. The corresponding original columns form a basis of the original column space. The pivot columns of itself span the different plane with third coordinate zero: row operations preserve column linear relations, but generally move the column space.[ref]
Row Reduction. Interactive Linear Algebra, §1.2.2, Echelon Forms; §1.2.3, definitions of pivot position and pivot column
Solving the homogeneous linear system gives and . Taking the free variable givesThe kernel is the input direction that trades one unit of each of the first two columns for one unit of the third. This trade leaves the output unchanged. The rank-nullity theorem expresses the general balance: for an matrix of matrix rank , the nullity is . The column space describes reachable outputs; the kernel describes invisible changes to inputs.[ref]
The Rank Theorem. Interactive Linear Algebra, §2.9, Rank Theorem: rank plus nullity equals the number of columns
For the attainable output , one solution is . Every solution lies in the affine solution space of a linear equationIndeed, and . Conversely, subtracting from any solution gives a vector in the kernel, so this describes every solution. For , the same row operations on the augmented matrix expose : the second requirement demands where twice the first requires .
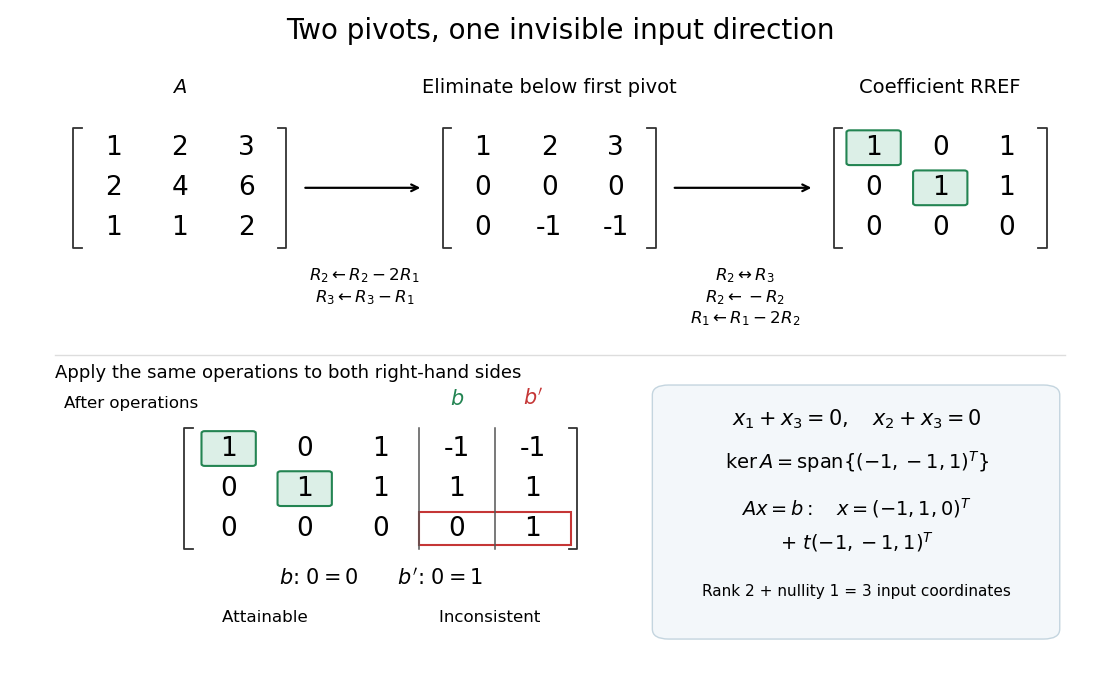
Two pivot columns, one kernel direction, and the same row operations distinguishing attainable from impossible
. Details. In general, a linear system is solvable exactly when appending leaves the matrix rank unchanged:Appending a vector outside the column space adds an independent direction. When a solution exists, every solution is , because . Thus one count predicts both how many output directions are reachable and, through the rank-nullity theorem, how many independent input directions remain free.[ref]
Solution Sets. Interactive Linear Algebra, §2.4.2, Key Observation and its proof; §2.4.3, Solution Sets and Column Spans
For a matrix of matrix rank , choose an ordered basis of its column space as the columns of . Express every column of in that basis and put its coordinates in . Then , has full column rank and has full row rank. Choosing independent original columns makes the corresponding columns of the standard basis vectors, directly proving its rank.
The basis choice is not unique: for any invertible matrix , the factors and have the same product. Once is fixed, its coordinate matrix is unique. For rank zero, the empty factors of the displayed shapes represent the zero matrix.
Let be a real matrix of matrix rank , and let the columns of be bases of and , respectively. Then has matrix rank , , and is an invertible matrix.
Proof. Since has independent columns, its Gram matrix is invertible, and maps onto . Thus and . The basis conditions give the two zero products. In particular,If , taking its dot product with gives . Hence and simultaneously . Therefore , and is invertible. The case is immediate.
For a common eigenvector of and , the two eigenvalues have zero product and positive sum: exactly one is zero. Thus the added term fills the missing orthogonal output directions without interfering with the original ones.
For composable linear maps, lies in and has dimension at most that of . This proves the bound on the rank of a matrix product. When is , is , and , the bound is attained by and .
The column rank of a matrix is the dimension of its image of a linear map, equivalently the dimension of the linear span of its columns. Multiplication on the left by an invertible matrix preserves all column linear relations, and elementary column operations preserve their linear span. In row echelon form the pivot columns form a basis of the column space. Its dimension equals the number of nonzero rows, and hence the row rank.
A pivot column of a matrix is a column whose position contains a leading nonzero matrix entry in its row echelon form. The corresponding columns of the original matrix form a basis of its column space. The column positions survive row operations, although the column vectors themselves generally change.[ref]
The row rank of a matrix is the dimension of the vector space spanned by its rows. Elementary row operations preserve this row space; multiplication on the right by an invertible matrix preserves all linear relations among the rows.
To see why row rank equals column rank, write a reduced row echelon form as , where is a product of elementary matrices and is an invertible matrix. Reversibility of the row operations gives equal row spaces for and . Also if and only if , so the columns have exactly the same linear relations. If has nonzero rows, its pivot columns are the first standard basis vectors of and span its column space. Its nonzero rows are linearly independent, since their matrix entries in the pivot positions form an identity matrix. Both dimensions therefore equal , and both counts transfer back to .
Two rectangular matrices are related by invertible left and right multiplication exactly when their ranks agree. The rank- orbit in has dimension : choose its image in a Grassmannian, then a surjective map to that image. These are the representation orbits of the one-arrow quiver.
The image of the linear map is contained in the sum of the images of and . Since the dimension of a vector space of this sum is at most the sum of their dimensions, matrix rank is subadditive. Iteration shows that a sum of matrices of matrix rank at most one has matrix rank at most , over any field.
An matrix has full column rank when its matrix rank is , equivalently when its columns are linearly independent vectors. This requires . Its kernel is , so the represented linear map is injective and every solvable linear system has a unique solution. It need not reach every output.[ref]
One-to-one and Onto Transformations. Interactive Linear Algebra, §3.2.1, One-to-one matrix transformations theorem and Wide matrices do not have one-to-one transformations
For example,has full column rank two, but its column space is the plane in . An attainable output fixes the input uniquely as ; an output outside this plane has no preimage.
An matrix has full row rank when its matrix rank is , equivalently when its rows are linearly independent vectors. This requires . Its column space is all of , so the represented linear map is surjective and every linear system is solvable. If , its nullity is , so solutions are not unique.[ref]
One-to-one and Onto Transformations. Interactive Linear Algebra, §3.2.2, Onto matrix transformations theorem and Tall matrices do not have onto transformations
For example, the matrix transpose of the matrix in full column rank isIt has full row rank two. Every output has solutions , with . A square matrix of size has full row rank and full column rank together exactly when its matrix rank is ; then it is an invertible matrix. A nonsquare matrix cannot have both properties, and has no two-sided inverse: such an inverse would make its linear map a linear isomorphism between vector spaces of different dimensions.
The identity matrix has ones on its main diagonal and zeros elsewhere, and satisfies whenever the products are defined.
Articles were limited to the first 100 out of 124 total.


