A disjoint-set data structure maintains a partition of a set. Its find operation returns a representative, equal for two elements exactly when they belong to the same block; its union operation merges two blocks. Kruskal's algorithm uses it to track connected components of a graph.
Start with a singleton set for every stored set element. Each disjoint-set find operation returns a disjoint-set representative; a disjoint-set union operation merges the containing blocks of a set partition. The interface does not split a block of a set partition or delete a member.[ref]
UF.java. Algorithms, 4th edition by Robert Sedgewick and others; UF.java, class documentation: initial singletons, representative equality and union interface
The partition of a set consists of nonempty disjoint blocks of a set partition covering the stored set; being in the same block of a set partition defines an equivalence relation. A disjoint-set representative names a whole block of a set partition, without requiring a list of its members.
A disjoint-set representative is a chosen member of a block of a set partition. It may be any member; it need not be the minimum, the first inserted member or a permanent identifier. A merge may change the disjoint-set representative of an existing member. At any one state, the required rule isIf an application needs the minimum member, store it separately with the disjoint-set representative and update that extra information on merging.
The disjoint-set find operation returns the disjoint-set representative of a stored set element . It preserves the partition of a set. With path compression, it can change internal pointers while answering the same membership question. Inputs outside the stored set require a specified error policy; they are not silently inserted here.
The disjoint-set union operation first uses the disjoint-set find operation to locate the blocks of a set partition containing . If they are different blocks of a set partition , replace them by their union ; every other block of a set partition stays as it was. If the two disjoint-set representatives agree, no merge is needed. Here
unite returns True exactly when it merges two different blocks of a set partition. A successful call decreases their count by one; a redundant call preserves it. The name union is also customary. Some interfaces instead accept already found disjoint-set representatives, making that linking step a separate operation.For an original example, initialize as seven singleton sets. Apply the calls in this order:The first five calls succeed. After the third, the partition of a set is ; after the fifth it is . The sixth returns
False: are already together. The blocks of a set partition number , counting the initial state. A disjoint-set find operation on cannot merge it with any other member.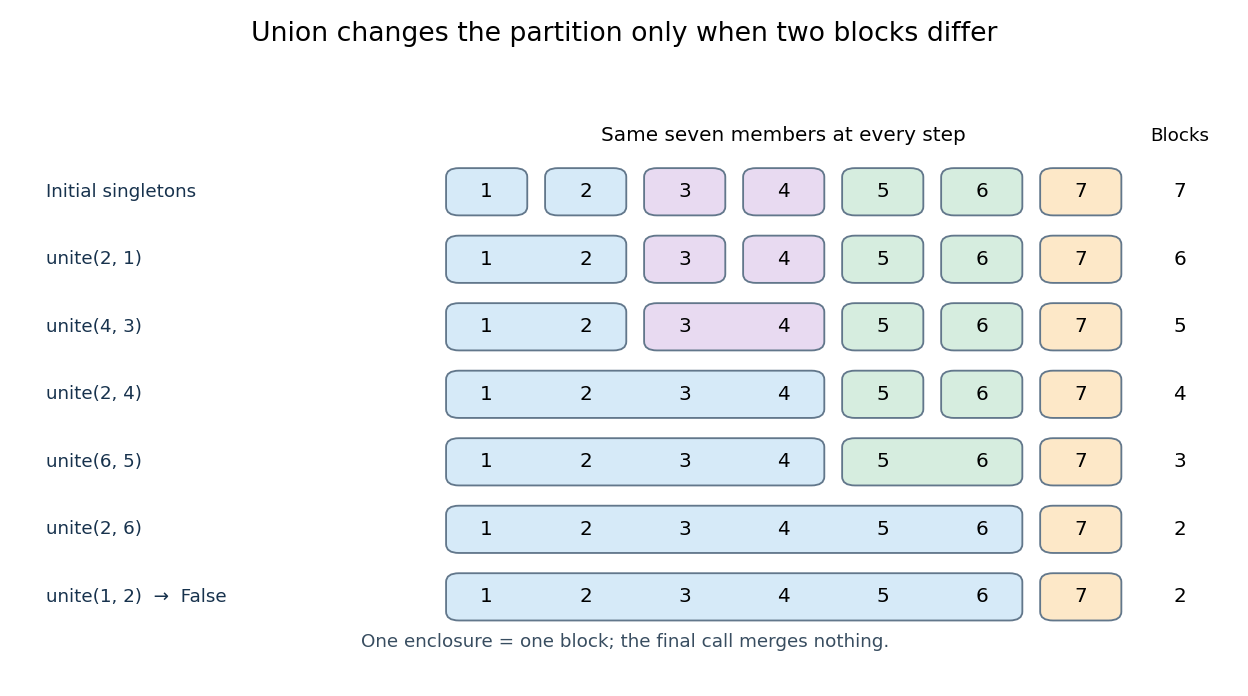
Five successful disjoint-set union operations and one redundant call on seven elements
. Each coloured enclosure is one block of a set partition. Columns identify the same seven members in every row; enclosures show membership rather than parent pointers. Details.This is exactly the kind of changing membership needed by Kruskal component merging: an accepted edge joins two current connected components of a graph, while an edge whose endpoints already have equal disjoint-set representatives is rejected. The existing Kruskal's algorithm worked example follows that application. A disjoint-set forest stores membership efficiently without repeatedly enumerating every block of a set partition.
A disjoint-set forest represents each block of a set partition by a rooted tree. Each set element stores a pointer to its parent in a rooted tree; the root of a tree stores a pointer to itself as a stopping convention. These self-pointers are sentinels, omitted from the forest's edges. Following parent pointers reaches the disjoint-set representative, the root of a tree. An indexed array
parent suffices when members are numbered consecutively. The rooted trees encode membership; their edges need not be edges of any input graph.To link different blocks of a set partition, point one root of a tree at the other root of a tree. Linking roots preserves every old membership and joins exactly the two rooted trees. Arbitrarily reparenting a nonroot could detach only part of a block of a set partition, so it would not implement the required disjoint-set union operation. The disjoint-set find operation terminates because each nonroot pointer moves towards the unique root of a tree; linking distinct roots cannot introduce a graph cycle.
Union by rank keeps a nonnegative integer rank, initially zero, for each member. For each input, obtain its root of a tree using the disjoint-set find operation, then compare the resulting ranks. Attach the lower-rank root of a tree below the higher-rank root of a tree, leaving both ranks unchanged. When the two disjoint-set representatives differ but their ranks are equal, choose either survivor and increase its rank by exactly one. A redundant disjoint-set union operation changes no ranks. Path compression also changes no ranks. The surviving root's rank bounds the height of its rooted tree, measured in edges; after path compression it need not equal that height.[ref]
COS 226 Bob’s Notes 1: Union-Find and Percolation (Version 2) by Robert Tarjan. Robert Tarjan, COS 226 Bob’s Notes 1: Union-Find and Percolation, Version 2, Fall 2010, p. 4: rank linking, equal-rank increment and upper-bound interpretation after compression
In our example, let the first argument's root of a tree survive equal-rank ties. The first two merges create roots , each of rank . The third gives and increases the rank of to . The fourth creates root of rank . The fifth attaches below without increasing any rank. Before any subsequent compression queries, the indexed arrays areThe redundant call on leaves these arrays unchanged. In particular, the disjoint-set representative of is , although is the minimum member of its block of a set partition.
Two short arguments explain the rank invariant. First, a root of rank has at least members in its block of a set partition: rank zero starts with one, and increasing rank combines two disjoint blocks of a set partition with at least members each. Unequal-rank linking only adds members. Thus every rank is at most for stored members, using the floor function and logarithm. Second, height is initially zero; unequal-rank linking adds at most one to the lower height, while equal-rank linking raises the available bound by one. Path compression only shortens routes. These arguments prove a height bound, not the stronger amortized analysis below.
Path compression changes parent pointers during a disjoint-set find operation so that future queries traverse fewer edges. Full path compression first follows the entire parent route to its root of a tree, then makes every member on that route point directly to that same root of a tree. No member changes its block of a set partition or its disjoint-set representative. Pointers outside the traversed route stay as they were. The following iterative Python implements full path compression and union by rank;
parent and rank are initially indexed arrays with parent[x] = x and rank[x] = 0 for every valid member.def find(x):
root = x
while parent[root] != root:
root = parent[root]
while parent[x] != x:
following = parent[x]
parent[x] = root
x = following
return root
def unite(x, y):
a, b = find(x), find(y)
if a == b:
return False
if rank[a] < rank[b]:
a, b = b, a
parent[b] = a
if rank[a] == rank[b]:
rank[a] += 1
return TrueStarting from the displayed disjoint-set forest,
find(3) traverses , returns and changes only from to . The route still has two edges. Then find(5) changes only from to . The final parent array is ; every stored rank retains its displayed value. The rooted tree at now has height one although its root's rank is two. Root still represents a separate singleton set.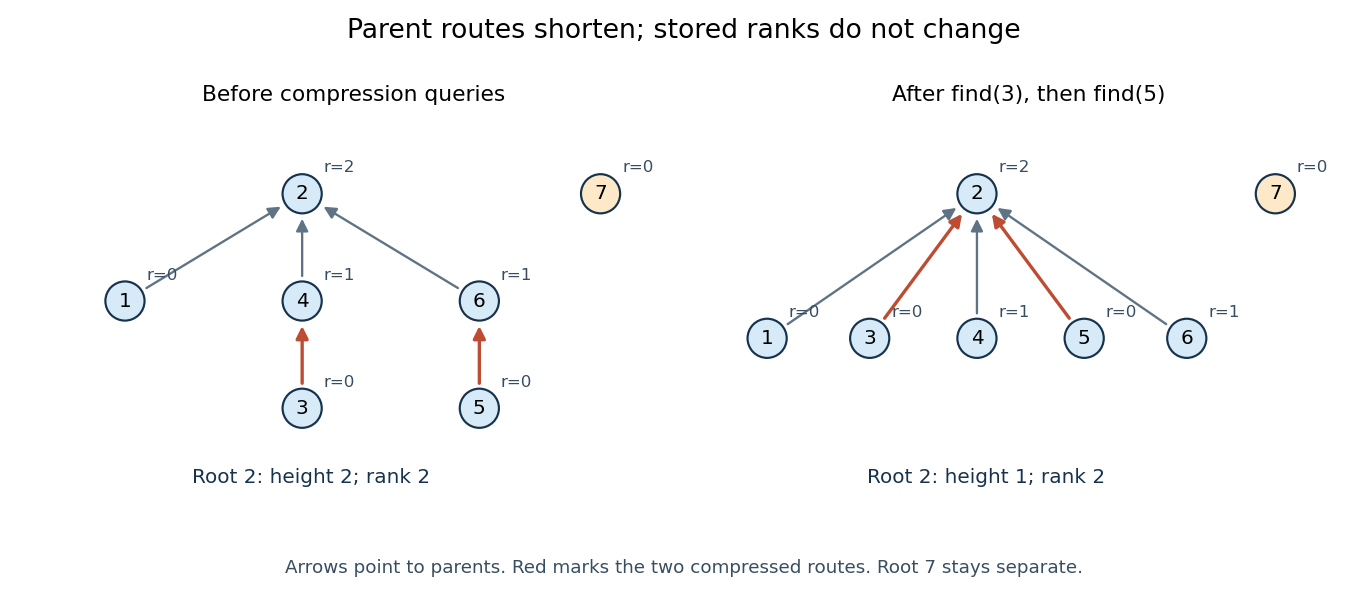
find(3) followed by find(5). Labels record stored ranks, including historical ranks at nonroots. Details.The two-pass algorithm first discovers the answer and then reuses it. During the second pass, saving
following before overwriting the pointer preserves the remaining route. Every replacement pointer targets the original root of a tree, proving that the partition of a set is unchanged.Full path compression is one specific rule. The authored
UF.java implementation instead uses path halving, redirecting a visited member to its parent's parent while advancing along the route. Its union by rank rule agrees with the one above.[ref]UF.java. Algorithms, 4th edition by Robert Sedgewick and others; UF.java, find and union methods: halving assignment versus the full-compression algorithm here; lower-rank linking and equal-rank increment
Assume identifiers, pointers and ranks fit into constant-size machine words, with constant-cost indexed array access, comparison and assignment. Initializing members costs time and machine words. With union by rank and full path compression, any sequence of disjoint-set find operations and disjoint-set union operations then has total time complexity, in Big O notation,Here is a conventionally normalized inverse Ackermann function. The documented path-halving implementation has the same amortized analysis bound.[ref]
UF.java. Algorithms, 4th edition by Robert Sedgewick and others; UF.java, class documentation: linear constructor, logarithmic worst-case operations and inverse-Ackermann sequence bound for rank with halving
A disjoint-set union operation includes two disjoint-set find operations and a constant amount of additional linking work. Including in the bound accounts for initialization even if no queries follow.
This is a bound on an entire sequence. It is not a worst-case constant bound for each call: a disjoint-set find operation can still encounter a previously uncompressed route of logarithmic length. The inverse Ackermann function grows extraordinarily slowly but is unbounded, so it cannot be replaced by a mathematical constant in this asymptotic statement. The general distinction between a per-operation maximum and a whole-sequence guarantee is explained in amortized analysis.
Robert Tarjan's 1975 paper established an inverse Ackermann function bound for set union. Its abstract states the sharper two-parameter form for representative queries and intermixed merges: the worst total cost is bounded above and below by positive constant multiples of . Those variables count different operations from the convenient formulation above; the abstract's matching lower bound is about its analyzed method, rather than a claim that every conceivable representation obeys the same lower bound.[ref]
The intuition is that union by rank limits how parent routes grow, while path compression makes an expensive traversal improve later queries. The rank argument alone proves only a logarithmic bound. Establishing the inverse Ackermann function bound requires a finer accounting of traversals across rank ranges; it does not follow merely from drawing a flatter rooted tree. The useful result is that repeated merging and membership queries can share the work of maintaining a changing partition of a set.
Articles by others on the same topic



A Disjoint-set data structure, also known as a union-find data structure, is a data structure that keeps track of a partition of a set into disjoint (non-overlapping) subsets. It supports two primary operations: 1. **Find**: This operation determines which subset a particular element is in. It can be used to check if two elements are in the same subset. 2. **Union**: This operation merges two subsets into a single subset.