A data structure organizes stored information together with operations for accessing and changing it. Choosing a data structure means choosing which questions should be cheap to answer: an array supports access by numbered position, a hash table supports lookup by key, and a priority queue supports selecting an item by priority. The operations and their time complexity matter as much as the stored values.
Suppose three requests arrive as , where the number is a priority and smaller numbers are more urgent. A FIFO queue removes Ada first because she arrived first. A minimum-oriented priority queue removes Bo first because is the least priority. An array can store the same three records in arrival order, but finding the least priority by scanning this representation takes three key inspections. A binary heap organizes these records so the least priority is immediately available. The information is the same; the representation changes the work needed to use it.
This is a useful design principle: preserve just enough organization for the operations the application needs. Maintaining a sorted array gives the whole order, but moving entries to insert a new key can be expensive. A binary heap keeps a weaker heap order that supports fast repeated selection without maintaining a sorted array. A good data structure makes an algorithm's next step easy.
Represent a finite set by a list of its elements. Allowing repeated elements makes set union cheap by list concatenation; imposing uniqueness requires membership checks. A representation sorted by a total order and containing no duplicates permits set union and set intersection by a simultaneous scan in linear time. These are different representation invariants for the same abstract set.
A skip list stores an ordered sequence in a bottom linked list, with successively sparser linked lists above it. Searching moves right while the next key is too small, then down a level. Randomly chosen node heights give logarithmic expected search and update time complexity with a suitable height policy. Repeated keys require distinguishing equal-valued nodes by identity when removing their links.
A balanced search tree used for database indexes. Records occur at the leaves; internal nodes direct searches using separator keys. A B+ tree with maximum fan-out has at most children per internal node.
An overflowing B+ tree node is replaced by two nodes and a separator is passed to its parent. Splitting the root creates a new root with two children and increases the height by one.
A distinguished value marking a boundary or special condition, such as the end of an input sequence. It must be distinguishable from every ordinary data value.
A decimal counter stores a nonnegative integer using an array of base-ten digits, with the least significant digit first. Increment resets trailing nines and increases the next digit, or wraps modulo if all digits are nines. Starting at zero, the exact number of digit changes in increments is . This is an aggregate analysis proving a constant amortized cost per increment under unit-cost digit updates. An arbitrary initial value contributes an additional in Big O notation.
A constraint requiring stored identifiers or references to denote valid represented entities, except for explicitly permitted absent-reference markers. For a node set with successor identifiers, integrity can require each nonnull successor identifier to equal the identifier of some node in . This is separate from identifier uniqueness and from order constraints on values along edges.
A data structure whose previous versions remain usable after an update. An immutable representation can return a new root while retaining old roots. Persistence is a version-availability property; it does not require copying the whole structure, and it does not by itself guarantee a particular time complexity or space complexity.
Path copying in a balanced tree can preserve old versions while allocating only the updated root-to-leaf path. A linked list can share an unchanged suffix but may copy a long prefix for a positional edit. Retained versions extend the lifetime of their reachable data, which matters when comparing snapshot history with edit-specific inverse commands.
An immutable multiset can expose a covariant type parameter because reading an element only produces that type. Addition accepts a new type parameter with a lower type bound,
add[U >: T](x: U), and returns a new ISet[U]. The old ISet[T] retains its contents and original element guarantee. Deletion returns both the removed value and a new remaining multiset; it does not mutate the old one. Duplicate occurrences are preserved.Different immutable versions reuse unchanged component software objects rather than duplicating them. Sharing a linked list suffix or unchanged subtrees saves storage while retaining distinct roots. The shared components must remain immutable for old versions to remain trustworthy. Merely sharing a mutable array does not create a stable snapshot.
Saving references to before/after versions adds constant reference storage per history entry, but the data reachable through those references may be much larger. With balanced-tree path copying, small updates to a size- structure can retain nodes. Whole-array copying can instead retain entries. The implementation and update pattern determine which bound applies.
A value that is either absent or contains one payload. In Haskell,
Maybe a uses Nothing for absence and Just x for presence. These alternatives distinguish an absent element from a present payload that may itself be undefined.A sequential-access object with a non-consuming current-value operation and a separate advance operation. Repeated reads of the current value leave its abstract sequence unchanged. Converting a consuming iterator into a cursor therefore needs a cache or an equivalent saved-current representation.
A stateful interface exposing a remaining sequence through an availability test and an operation returning and consuming its head. An iterator can represent an infinite sequence without materializing all elements, provided demanded steps terminate. Destructive iterators generally require exclusive ownership of their consumption state; sharing an iterator is not the same as creating a fresh independent traversal.
An iterator with forward and backward cursor movement. With the cursor between elements,
next crosses and returns the element to the right, and prev crosses and returns the element to the left. Memoizing a forward-only source's consumed prefix supports arbitrary backward travel over that prefix without replaying source effects. The required history storage grows with the farthest explored position, even if the current cursor later moves backward.An iterator that physically consumes and caches source elements to determine whether another logical result exists. A prepared optional result makes repeated availability queries idempotent. This is useful when a result requires a complete group of source elements and the underlying iterator exposes neither its remaining length nor a rewind operation. Source consumption is owned by the wrapper; clients must not independently advance the underlying iterator.
A new cursor with the same remaining sequence and an independent consumption position. Copying only a wrapper that still points to the same destructive source does not suffice: that gives shared iterator consumption. Cached lookahead and phase flags are part of the state that a snapshot must preserve. Element values need not be deep-copied merely to duplicate the cursor.
Represent a generated sequence by shared memoized lazy list cells and let each iterator hold its own current cell reference. Copy that reference into a new iterator object. Advancing one cursor changes no other cursor, while every cell's future tail is generated once. Thus even a privately stateful generator can supply identical future values to independently consumed snapshots, provided its state is owned by this shared sequence and not mutated externally. Retained older cursors can keep cached prefixes alive. [ref]
Represent each generated sequence position by an immutable head and a lazily memoized successor, and give each iterator its own pointer into the shared chain. Computing a successor invokes the privately owned generator once; lagging copies reuse that same successor. Consequently a mutable programming closure generating Fibonacci numbers can support interleaved independent cursor positions. Sharing only the generator and a copied current value would instead consume the generator's mutable state twice. This construction can retain all cells between the fastest and slowest live cursors; it does not guarantee constant memory usage.
Discard input values until the first one satisfying a predicate, then return that value and every remaining value without testing the predicate again. A demand-driven filtering iterator instead keeps testing and can discard later values too. A buffered first match must survive repeated availability tests and iterator snapshots. A flag distinguishes the initial seeking phase from the already-positioned remainder.
An iterator adapter that consumes underlying values only far enough to find the next value passing a predicate. Store at most one passing value in an optional value. With no cached value, its abstract remainder is the filtered underlying remainder; with cached , it is followed by that filtered remainder.
Construction performs no read. On
hasNext or next, consume rejected values until one passes or the input is exhausted. Cache the passing value immediately and stop. Repeated availability tests reuse it. Returning it clears the cache without prefetching another value. This gives a precise demand boundary even when producing source values is expensive. Availability need not terminate on an infinite input with no further passing value.Consume the first iterator until it is exhausted, then consume the second. Short-circuit availability testing avoids polling the second producer while the first still has entries. Construction need not request any entry. If both wrappers share an underlying cursor, however, draining the first may also consume entries the second would otherwise have returned.
A wrapper selecting alternate underlying entries can maintain one flag indicating whether the next entry must first be discarded. Construction performs no requests. On demand, skip at most that one entry, clear the flag, and leave the selected entry unconsumed until next is called. Returning a selected entry sets the flag again. Repeated availability tests cannot repeatedly skip; a final skipped entry may need to be consumed to establish exhaustion.
An iterator whose future observable sequence can be produced without changing cursor state. An infinite constant sequence is an example: removing its first element leaves the same sequence. A permanently empty iterator is another. Such cases show why an iterator interface does not logically force every implementing object to be mutable, although ordinary finite nonempty traversals need progress state somewhere.
Represent a sequence by a function mapping each value to its increasing list of occurrence positions. On finite inputs, querying a value produces every matching index and a terminating tail. On infinite inputs, absence of further occurrences may be uncomputable by a generic scan, as expressed by the absence-detection obstruction for infinite lists. Parity filtering and index rescaling represent alternate-element subsequences, but may fail to preserve productivity.
A suffix array stores starting positions of a string's suffixes in lexicographic order. All suffixes starting with a fixed query occupy a consecutive interval. This permits string-searching algorithms to search a compact list of positions instead of storing every suffix explicitly.
The length of a longest repeated substring equals the maximum longest-common-prefix length over adjacent suffixes in lexicographic order. Suffixes beginning with a fixed string form a consecutive interval: a string outside that string prefix software class differs earlier or ends sooner, putting it strictly to one side. Two occurrences of a longest repeated substring therefore bound an interval in which every adjacent pair shares that string prefix. At least one adjacent pair attains its length, and no pair can exceed the global maximum. This proves the result even when occurrences overlap; a text with fewer than two suffixes needs a separate empty-result convention.
A wavelet tree recursively partitions an alphabet and records bit sequences indicating which partition each character belongs to. A character rank query follows the relevant partitions while mapping the prefix length through the bit-sequence ranks. A balanced tree takes logarithmically many levels in the alphabet size.
A character rank query asks how many occurrences of character appear in the first positions of a sequence. A prefix sum array answers a single-character version in constant time after linear preprocessing; a wavelet tree supports many characters more compactly.
A list is an ordered collection in which entries may repeat. Removing duplicates would discard information about both multiplicity and, depending on the representation, order. A linked list and an array are different ways to implement list operations.
Replacing a list by a list containing each of its distinct elements once. Retaining first occurrences gives a stable order. A recursive implementation emits the head and removes all its occurrences from the tail before continuing. On an infinite input with only finitely many distinct values, detecting that there are no further new values may diverge; on an infinite input with infinitely many distinct values and terminating equality tests, each successive new value has a finite position and can be emitted.
Retain the first occurrence of each distinct value in a list. The right fold
foldr (\x ys -> x : filter (/= x) ys) [] preserves this order under lazy evaluation. With terminating equality tests, an infinite input containing infinitely many distinct values produces every finite output prefix. If only finitely many distinct values occur, those values appear but the remaining infinite input cannot generally be certified empty: the result has an undefined tail rather than a terminating empty list.Reverse the order of a finite list. Reversal is an involution and satisfies for list concatenation. In an array segment of length , exchanging symmetric offsets and for realizes reversal in constant auxiliary space.
A tree representation of a list with empty nodes, single-element nodes and binary concatenation nodes. Concatenation constructs one node without traversing either operand. The representation need not be unique: adding empty branches changes its size without changing the denoted list. An accumulator-based traversal gives linear flattening of a binary tree in the representation's size rather than merely the output length.
Combine corresponding entries of two lists into a list of tuples. The usual finite-list operation stops when either input ends. A lazy evaluation implementation can produce entries from infinite lists, but its exact strictness depends on the order of pattern matching in the definition.
Represent a finite list by a function from indices to optional values. There must be a length for which exactly the indices are present; later indices are absent, so the representation has no holes. Prepending and removing a head shift indices, taking restricts the present domain, and dropping translates it. Functional composition can accumulate query costs, so array-like constant-time access does not follow from the representation type.
A persistent list representation supporting positional lookup more efficiently than a conventional linked list. Different implementations trade lookup, insertion and deletion costs; “random-access” does not itself guarantee constant-time indexing. A skew-binary random-access list supports worst-case constant-time front insertion and removal with logarithmic worst-case lookup.
Represent a finite list by a forest of value-bearing perfect binary trees of sizes , in nondecreasing order, using the greedy largest sizes and allowing a repeated size only in the first two positions. Concatenated preorder traversals recover the list. Cached tree sizes guide indexing.
Front insertion merges the first two equal-size trees beneath a new root, or adds a singleton if they differ. Removing the first root either discards a singleton or splits its two children into the initial equal-size pair. Both operations inspect and allocate only a bounded number of constructors, taking worst-case constant time and sharing the remaining representation. A positional query skips whole cached tree sizes and then descends through one tree, taking time. Conversion in either direction takes linear time on finite input.
The duplicate-size restriction follows directly from greediness. If two size- trees had any preceding nonempty portion, there would be at least elements available, enough for the next larger perfect binary tree. Three equal-size trees would likewise suffice for that larger tree. Both contradict the greedy representation.
Represent a list by the function
\ys -> xs ++ ys. Concatenation becomes function composition, the empty list is represented by id, and applying to [] recovers the list. Only functions of this tail-prepending form are valid representations; arbitrary functions of the displayed type need not satisfy the invariant. A higher-order tree fold using difference lists produces an inorder traversal in linear time on every tree shape.For a leaf-labelled binary tree, define
go (One x) acc = x:acc and go (Two l r) acc = go l (go r acc), then apply go t []. The invariant in the title follows by structural induction and associativity of list concatenation. It proves preservation of leaf order. Each leaf supplies one output constructor and each internal node requires constant bookkeeping, giving linear time in the number of nodes. By contrast, flattening both subtrees and concatenating their results can copy prefixes of sizes on a left-branching tree, taking quadratic time. The accumulator is the already-known suffix in a difference list representation.Append the second list after the first. For a finite left list of length , consuming the concatenation costs to copy its spine and can share the second argument. Repeatedly appending large left lists can cause quadratic time complexity; difference lists make concatenation into function composition.
Concatenating the initial list prefix accepted by a predicate with the remaining list suffix reconstructs the input, provided every test reached before the first false result terminates. Prove the finite case by structural induction: a true test copies the head, and a false test returns the untouched list suffix. An undefined reached test is an obstruction because reconstruction loses an exposed cons cell. An infinite all-true list prefix can still reconstruct the input, since list concatenation never demands its second argument there.
A list obtained by dropping an initial segment. The whole list and, for finite lists, the empty list are suffixes. Proper suffixes exclude the whole list; nonempty suffixes exclude
[]. In a linked list, suffixes can share the original nodes, permitting a list of all suffixes to be constructed with linear additional space.An initial segment of a list, including the empty segment and, for finite lists, the whole list. A proper prefix excludes the whole list. Fully materialising all prefixes of a length- list needs element constructors, although the outer list of prefixes has only entries.
An initial segment of a string, including the empty string or the whole string. Two strings share a prefix exactly when their initial characters agree up to its length. The longest common prefix is the longest such shared initial segment.
A tree-based data structure that orders each parent relative to its children so that an extremal value is available at the root. In a max-heap, every parent is at least as large as its children. Heap implementations provide one way to realize a priority queue; the abstract queue and its implementing structure are distinct concepts.
A heap data structure stored as a complete rooted tree with up to children per vertex, where . The final level is filled from left to right. For zero-based array storage, the parent of entry is , and its child number has index when that index is inside the active heap. There are at most levels containing entries.
A d-ary heap in which each parent key is no greater than each child key. Transitivity makes the root a minimum. Removing the root requires choosing a smallest child at each downward step, taking time in the usual range. Decreasing a key or inserting a new leaf only compares along one chain of parents, taking time in that range. These priority queue bounds assume constant-time key comparisons and available array capacity. An indexed priority queue must also update its item-to-index table after every swap.
A heap data structure supporting a meld operation that combines two heaps into one while preserving the heap order. The cost of melding distinguishes implementations such as a leftist heap from ordinary binary heaps.
A meldable heap satisfying the min-heap ordering: each parent key is no greater than its children's keys. It combines efficient merging with access to the current minimum key.
A binary meldable heap satisfying heap order and the leftist condition: at each node, the shortest path to a missing child is no longer in the right subtree than in the left. Melding recurses down right spines, swaps children when needed, and takes logarithmic time.
A heap data structure in which every parent key is at least as large as its children's keys. The root therefore stores a largest key, allowing a priority queue to retrieve a current maximum efficiently.
A min-heap has every parent key no greater than its child keys. The root therefore contains a minimum key.
A collection associating keys with values and supporting lookup by key. Unlike an ordered list of guarded alternatives, a simple map does not directly represent sequentially evaluated, potentially repeated label expressions with first-match behavior.
An associative array represented by a list of key-value pairs. Looking up a key scans entries until a matching key is found, giving linear worst-case search cost in the number of entries when key comparisons have unit cost.
Represent a total function by storing only selected entries of a finite partial function and returning a fixed default for missing keys. A missing payment-count record can denote two zero counts. Storing an explicit default-valued record can have the same observable meaning, so the abstraction function need not be injective. Update operations must preserve all unrelated keys and establish the intended change whether or not the key was previously stored.
A treap is a binary search tree ordered by keys and simultaneously a binary heap ordered by priorities. Independent random priorities give logarithmic expected search depth. An implicit treap uses subtree sizes to address sequence positions instead of storing explicit keys.
An implicit treap represents a sequence in traversal order and uses subtree sizes to locate positions. Splits and merges therefore address sequence positions rather than explicit search keys.
A suffix automaton is a finite automaton recognizing all suffixes of a fixed string. With every reachable state accepting, it recognizes all substrings; its number of states and transitions is linear in the original string length for a fixed finite alphabet.
A deque can use two permanent stacks holding the front and back portions, plus an empty temporary stack. When removal encounters an empty side, park the top half of the other side in the temporary stack, reverse its remaining half into the empty side, and restore the parked half. This preserves order and balances the permanent stacks. The potential method with pays for the linear time transfer from the previous size imbalance, giving constant amortized cost for all four endpoint operations with only a fixed number of size counters.
In an endpoint-based doubly linked deque, the two endpoint references are simultaneously null exactly in the empty state. Otherwise the first predecessor and last successor are null, the finite chain is acyclic, and neighbouring links are reciprocal. Following successors and predecessors gives the same nodes in reverse order. Removing the sole node must therefore clear both endpoints; merely clearing the one used by the operation is insufficient.
A monotonic queue keeps candidate values in sorted order while a window moves through a sequence. For window maxima, discard smaller or equal values from the back before appending a new value, and remove expired indices from the front. The maximum is always at the front. Each index enters and leaves at most once, so all windows can be processed in linear time.
Use backtracking through a dictionary trie, decrementing and restoring the available count for each traversed letter. Visit each letter-labelled child once when its count is positive, rather than choosing between indistinguishable occurrences. Every reachable complete word is then produced once, including words using only a subcollection of the original letter multiset.
A binary trie stores bit strings by following one edge for each bit, with child edges labeled zero and one. A chosen direction of traversal fixes whether low or high bits are read first.
A stack whose stored values remain ordered by removing incompatible values before each insertion. In subarray-minimum counting, an entry can store a value and the number of suffixes for which it is currently minimal. Each item is pushed and popped at most once, giving linear total work for a full scan.
A monotone stack whose stored values are kept in increasing order from bottom to top. An implementation specifies whether equality is allowed; popping values greater than or equal to a new value leaves strictly increasing stored values.
A Fenwick tree stores a changing array so that a point update and a prefix sum query each take time with storage. With indices starting at , the entry at stores the sum over the final block of length ending at . A query repeatedly removes that final block, while an update visits the blocks containing the changed position.
A tree in which each internal node has four children, commonly representing the four equal quadrants of a square region. For image compression, a uniform square can be stored as one leaf; a mixed square is split recursively. Large uniform regions therefore need few nodes.
A binary tree organizing a fixed sequence into recursively subdivided contiguous intervals. Each node stores an aggregate for its interval. Range queries and point updates visit logarithmically many nodes; range-update variants store additional information such as a coverage count to maintain the length of a union of active intervals.
A lazy segment tree augments a segment tree with lazy propagation, allowing compatible interval updates and interval aggregate queries in logarithmic time.
Lazy propagation postpones an interval update at an internal node until its descendants are needed. Each node retains both its current aggregate and a pending update tag, which is composed with later tags.
A representation of a finite set of bounded nonnegative integers by a binary word: bit is 1 exactly when belongs to the set. Bitwise AND, OR, and XOR implement intersection, union, and symmetric difference. A large integer can store the whole word when the programming language provides arbitrary-precision integers.
An adjacency list represents a graph by keeping, for each vertex , a collection of the vertices reached by its outgoing edges. An array indexed by vertex identifiers can locate each collection; the collection itself may use a linked list or an array. In an undirected graph, each nonloop edge supplies an entry at both endpoints.[ref]
Graph.java. Graph.java, class documentation and fields: vertex-indexed adjacency collections; addEdge: entries at both endpoints
For a worked example, take the simple graphwhere denotes the unordered pair . Its adjacency lists, displayed in label order, areThus has three neighbours, although the graph has six vertices. Its list contains exactly the destinations available for a single step from ; no slots are reserved there for . The fourteen neighbour entries represent seven edges, with appearing as in 's list and as in 's list. The label order makes the example easy to read; an adjacency list need not be sorted.
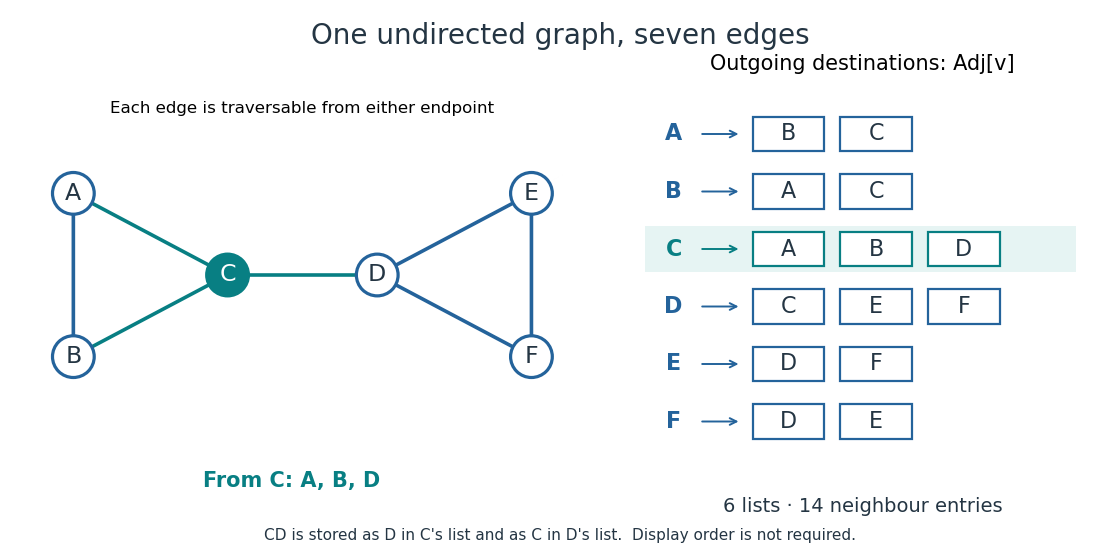
Seven undirected edges and their fourteen adjacency list entries
. Details. The useful idea is to store existing connections explicitly. Neighbour enumeration can then follow exactly the possible next steps, which is what breadth-first search and depth-first search need. In a sparse graph, most pairs of vertices have no edge; adjacency lists avoid reserving a separate adjacency matrix entry for every such absence. Whether this saves work depends on the question: neighbour enumeration and testing one proposed edge have different costs.
For a directed graph, store in for the edge . The reverse edge is separate and is stored only if it exists. Consequently, list length is outdegree, not indegree, and each directed edge contributes one entry in total. An incoming-list index is additional storage.[ref]
Digraph.java. Digraph.java, addEdge, adj and outdegree: one entry in the tail's collection; indegree is maintained separately
Orient the seven edges of our example from earlier to later labels. The resulting directed graph hasThere are now seven entries, with outdegrees . In particular, needs an empty list even though it is reached from : incoming edges do not make 's outgoing list nonempty. Replacing each directed edge by an undirected graph connection would lose this distinction.
Our running simple graph excludes self-loops and repeated edges. If those restrictions are relaxed, specify how the adjacency list encodes them. Here an undirected self-loop at contributes two copies of to , matching its contribution of two to the degree of a vertex. A directed self-loop contributes one copy, and one each to outdegree and indegree. Distinct parallel edges retain distinct entries; a multigraph's list length can therefore exceed its number of distinct neighbours.[ref]
Graph.java. Graph.java, class documentation: parallel edges and two-entry undirected self-loop convention; addEdge applies both insertions even when v equals w
[ref]Digraph.java. Digraph.java, class documentation and addEdge: parallel edges permitted; a directed self-loop adds one outgoing entry and increments indegree once
For example, add one undirected self-loop at to the seven-edge example. Its list becomes , the vertex degree of becomes four, and the total entry count becomes sixteen for eight edges. If an application instead stores a self-loop once, it must account for its doubled undirected vertex degree separately. In a weighted graph, an entry can be an ordered pair meaning destination and weight ; the weight belongs to the edge, not to the destination vertex.
Neighbour enumeration reports the neighbours of a specified vertex. For a simple graph, scan its adjacency list and report each entry. With constant-time list access and work per entry, a list of length needs time in Big O notation, conventionally written for nonempty lists. Use vertex degree for an undirected graph and outdegree for a directed graph. Obtaining the list reference can take constant time; consuming it requires visiting every entry.[ref]
Digraph.java. Digraph.java, class documentation and adj: obtaining the collection versus iterating in time proportional to outdegree
In our undirected example, enumerating 's neighbours reads : three entries. Scanning row of the full adjacency matrix reads six entries, , to produce the same answer. In the directed variant, enumerating 's outgoing neighbours reads no neighbour entries, but still needs constant work to locate and recognize its empty list. For a multigraph, scanning lists enumerates incident edges with multiplicity; reporting only distinct neighbours additionally requires removing repetitions.
For a short time complexity argument, each reported entry requires at least one output operation, and one scan suffices. Across all vertices, the undirected entry count is by the handshaking lemma; the directed count is . A graph search that processes each vertex once and scans each of its entries once therefore does structural work, provided its visited-state access and FIFO queue or stack operations also have the required constant-time costs. With a full adjacency matrix, scanning every row instead inspects entries. This is how the representation enters the analysis of breadth-first search and depth-first search.
Write and . Suppose each vertex identifier, list descriptor, link and optional edge weight occupies a constant number of machine words, and indexed array access and identifier comparison take constant time. There are list descriptors and directed, or undirected, neighbour entries. Hence adjacency lists use machine words in Big O notation. A full adjacency matrix has entries, regardless of . These are counts under a storage model, not fixed byte sizes.[ref]
Recitation 19: Graph Representations and Traversals (Cornell course page). Recitation 19, The Adjacency List and The Adjacency Matrix: directed and undirected entry totals, linear list storage, and quadratic full-matrix storage
Our undirected example has six list descriptors and fourteen neighbour entries, versus thirty-six full adjacency matrix entries. The numbers and count different kinds of logical items: they do not prove a particular byte saving. A linked list also needs links; an array may have unused capacity. Storing only half of a symmetric matrix changes its exact count while leaving quadratic growth. If identifiers or weights require growing numbers of machine words, their size must be included in the space complexity.
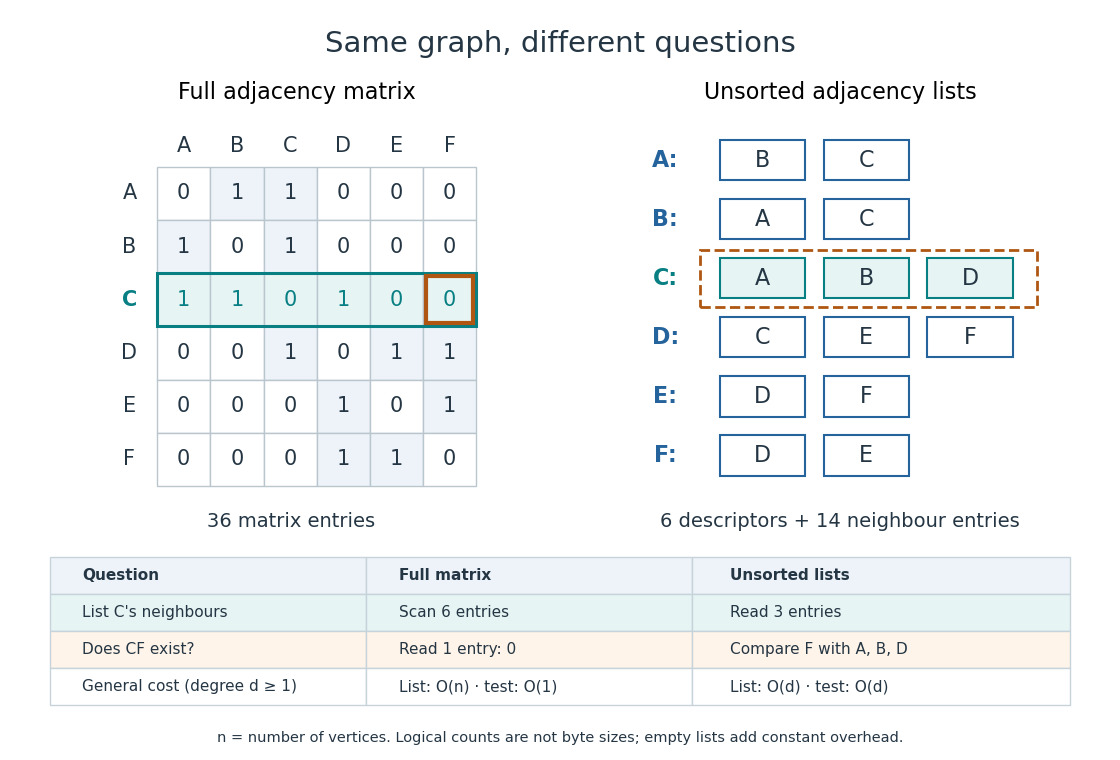
An unsorted adjacency list answers "does the edge exist?" by linear search through . In the worst case it inspects all entries, giving time, or for . Even if is absent, an uninspected entry could still contain it, so arbitrary lists require the whole scan. On our example, looking for in 's list compares with and fails after three comparisons. A full adjacency matrix instead answers from its single entry in time.[ref]
Recitation 19: Graph Representations and Traversals (Cornell course page). Recitation 19, The Adjacency List: edge-membership question; The Adjacency Matrix: constant-time edge-existence query
Different promises change the query. A sorted array of neighbour identifiers permits binary search in time, but maintaining order after insertion may require shifting entries. A per-vertex hash table permits expected constant-time membership under the hashing and load assumptions of that data structure; it does not give that guarantee to an arbitrary adjacency list. A stored list length can likewise make a vertex degree query constant-time even though neighbour enumeration still has to visit its entries.
The advantage grows with scale. For a graph path on vertices, , so there are undirected neighbour entries and descriptors, versus full adjacency matrix entries. Such a family is a sparse graph with . For a complete graph, , so the undirected neighbour entries already number : the adjacency list advantage in growth rate disappears. Choose by the workload: following existing edges favours adjacency lists; many arbitrary pair-membership queries can favour a full adjacency matrix. The representation organizes the same graph for different questions.
A priority queue stores items with comparable priority keys and supports insertion, inspection of a best-priority item, and removal of a best-priority item. Here we use the minimum convention: keys have a total order, and smaller means earlier. The operation
peek returns a stored item of minimum priority without removing it; extract-min removes and returns such an item. Both require a nonempty priority queue, or an explicitly specified empty-case result. A maximum-oriented priority queue reverses the choice.For the requests ,
peek returns Bo and leaves all three requests stored. extract-min returns Bo and leaves Ada and Cy; another peek returns Cy. Inserting now makes Dee the next request selected. This changing collection need not be a sorted array: only the next choice must be available.Distinct items may share a priority. Inserting alongside permits either item to be removed first. A priority queue does not inherently promise arrival order on ties. If that policy matters, compare priority first and a unique increasing arrival number second; the resulting total order makes earlier arrivals win equal-priority ties. This is analogous to the motivation for stable sorting, but it is an extra policy for the priority queue.
The interface specifies behavior; the data structure determines costs. A binary heap implements a priority queue with constant-time
peek and logarithmic-time insertion and extract-min, under the cost assumptions below. Scheduling by urgency or by the time of the next event needs exactly this repeated next-item selection. MIT's notes use these applications to motivate the priority queue interface.[ref]https://ocw.mit.edu/courses/6-006-introduction-to-algorithms-spring-2020/40d4851e550507ca14dc778b9b2266cc_MIT6_006S20_lec8.pdf. MIT 6.006, lecture 8: priority queues and binary heaps, pp. 1–2
A priority queue whose entries have stable identifiers and an auxiliary map from each identifier to its current storage location. An indexed binary heap can therefore support membership and locating an entry in constant time, followed by a key decrease in logarithmic time. Every heap swap must update both affected map entries; otherwise later updates can modify the wrong item.
A priority queue whose distinguished entry has largest key. A max-heap implements maximum inspection in constant time, and insertion, extraction of a maximum and increasing the key of a located entry in running time. An entry handle needs its current heap index to support that last bound; searching by an arbitrary key can take linear time. Multiple entries can have equal keys without requiring a particular tie order.
A binary heap represents a priority queue as a complete binary tree obeying a heap order. We use the minimum convention: the priority of every parent in a rooted tree is no greater than the priorities of its children in a rooted tree. Equal priorities are allowed. Each stored entry may be a record carrying a priority key; the numerical example below displays only keys. Reversing the inequalities gives the maximum convention.
The complete binary tree can be stored directly in a zero-indexed array : read its levels from top to bottom, left to right. The root of a tree is at index . The possible children in a rooted tree of index are at and , and an index denotes a present entry only when it is less than . For , its parent in a rooted tree is at , using the floor function. Thus the links of the complete binary tree are determined by arithmetic rather than separately stored pointers.
ConsiderThe children in a rooted tree of index have keys ; those of index have keys ; those of index have keys . The six comparisons , , , , , establish the heap order. At index , the parent in a rooted tree is index , carrying key .
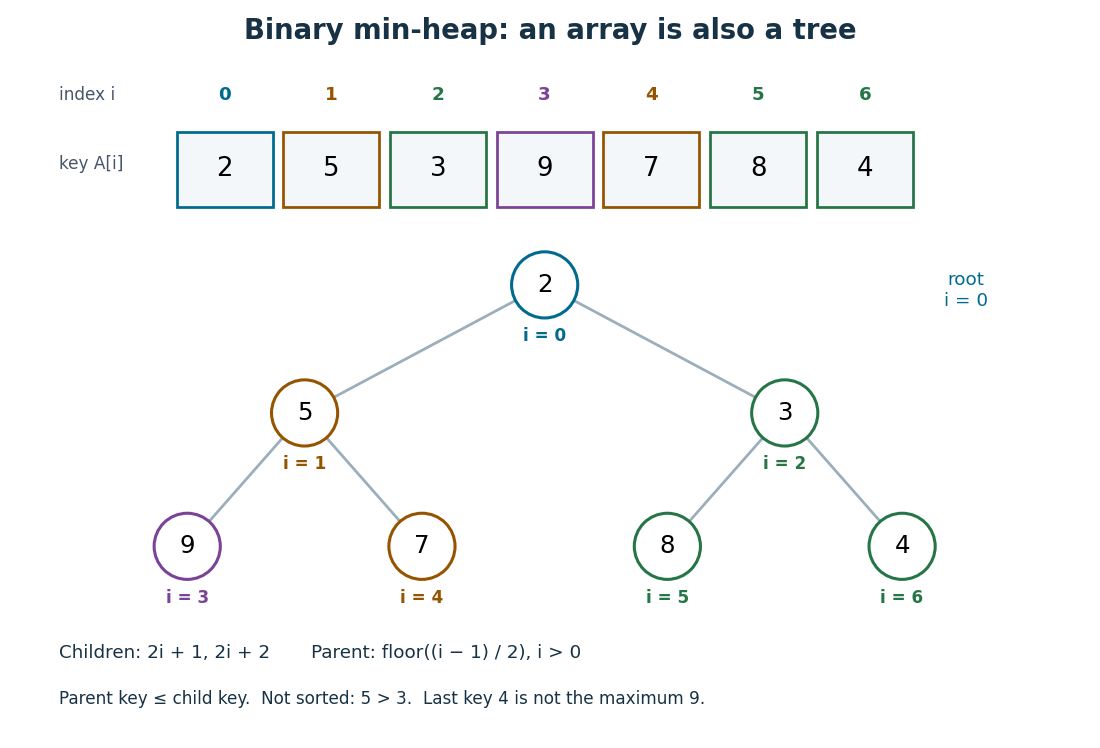
The array is visibly not a sorted array: precedes , and precedes . Nor is the last entry a maximum: it is , whereas the maximum is at index . The heap order compares ancestors and descendants, without imposing an order between separate branches. Nevertheless, following the graph path from the root of a tree to any entry gives a chain of nondecreasing priorities. This short argument proves that
peek can return , a minimum, without inspecting the other entries.Insertion appends an entry to the array, preserving the shape of the complete binary tree, then uses sift up to repair the heap order. Insert key into the displayed binary heap. It is appended at index , and exchanges with indices , , then :The moving key follows ; the keys each move down one level. Only this chain needs repair.
Now apply
extract-min. Save key , move the last key to the root of a tree, and shorten the array to length . Use sift down, always choosing the smaller of the present children in a rooted tree:First exchanges with key at index , since ; then with key at index , since . At index , the possible children in a rooted tree would be indices , both outside the shortened array, so the process stops. The returned key is , and the remaining binary heap is exactly the original one.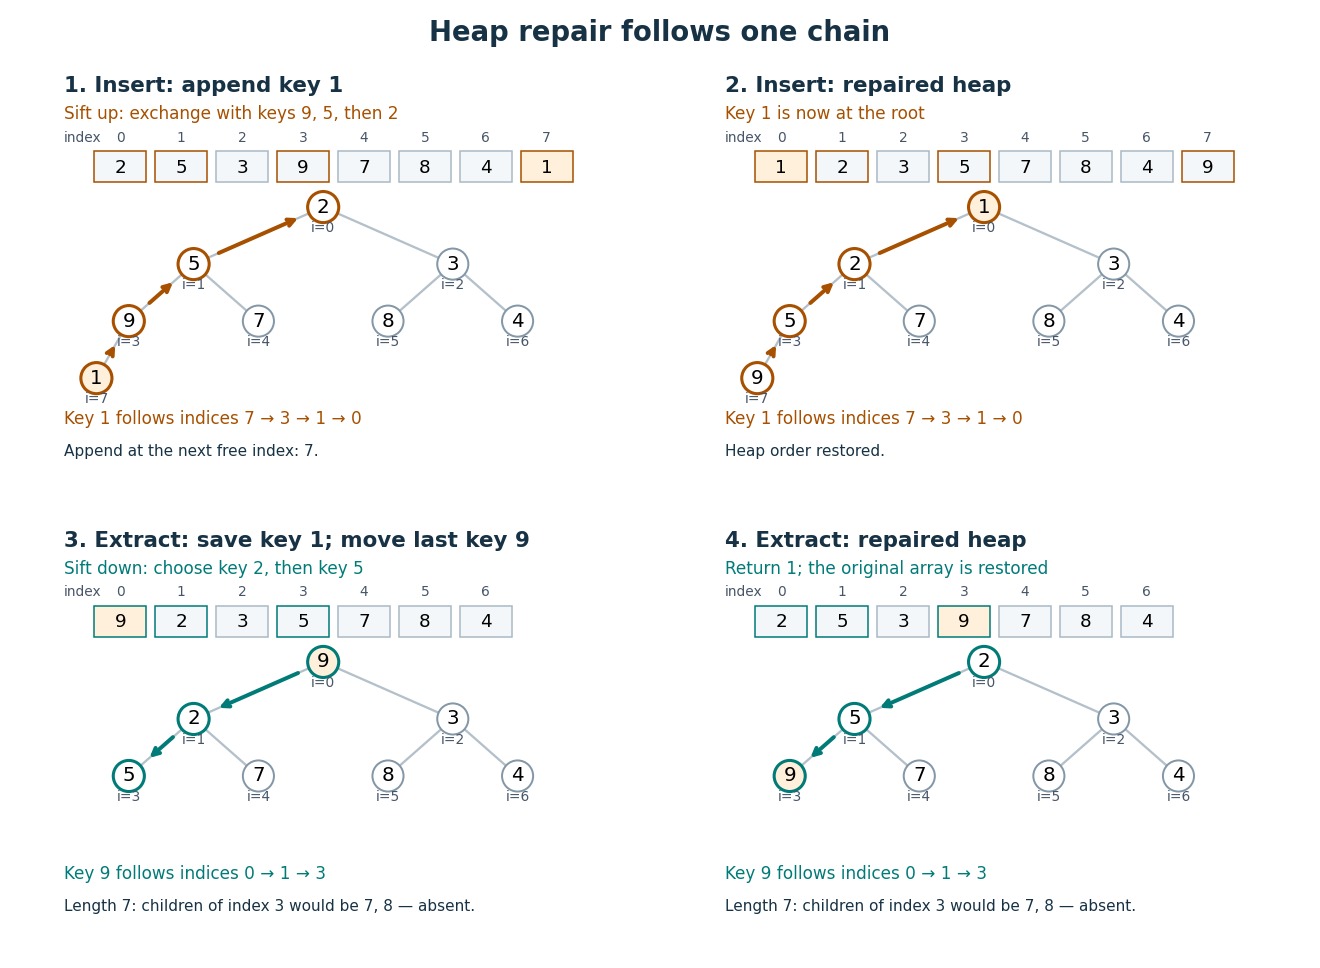
For a nonempty binary heap with entries, the deepest level is , using the floor function and logarithm. Each exchange moves one level and uses only a bounded number of comparisons. The resulting time complexity bounds, expressed in Big O notation, are:
| Operation | Time complexity | Reason |
|---|---|---|
peek | Read the root of a tree. | |
| Insert | for | Append, then sift up through at most the levels of the complete binary tree. |
extract-min | for | Move the last entry, then sift down through at most those levels. |
| Build from an arbitrary array | Apply sift down from the last index with children in a rooted tree back to index . |
These bounds assume constant-cost indexed access, key comparisons and exchanges, and available array capacity for insertion. Allocating and copying a larger array is a separate cost. Empty and one-entry cases take constant work.
To build a binary heap, begin at index and work backwards. Entries without children in a rooted tree already obey the heap order. Each sift down, also called heapify down, starts with every present smaller rooted tree below it already repaired. Most entries are close to the bottom and can move very little; successively longer repair distances occur for geometrically fewer entries. Summing these distances gives work, rather than charging to every entry. MIT's notes give this bottom-up construction and contrast it with repeated insertion.[ref]
https://ocw.mit.edu/courses/6-006-introduction-to-algorithms-spring-2020/40d4851e550507ca14dc778b9b2266cc_MIT6_006S20_lec8.pdf. MIT 6.006, lecture 8: implicit indices, heap repair and linear build, pp. 3–6
The Dijkstra algorithm additionally needs to decrease the priority of an existing vertex when its tentative distance improves. Given its current index, lowering the key followed by sift up takes time for . An indexed binary heap maintains a separate map from item identity to its current index and updates that map after every exchange. For vertices numbered in a fixed range, the map can be another array, giving constant-time index lookup. An ordinary unindexed binary heap supplies no such guarantee: locating an arbitrary item can require scanning entries. Item identity and priority must remain distinct, especially when several vertices have equal tentative distances.
The attractive compromise is local organization with global usefulness. A binary heap maintains only the heap order, yet every
extract-min gives the next smallest key. Repeated extraction of the original example gives , so a priority queue also supplies a sorting algorithm without storing a sorted array between extractions.In the implementation that exchanges the root with the final leaf and then applies heapify down, a max-heap of size at least four with distinct keys requires at least one downward exchange: the old final leaf's parent remains and has a larger key. One downward exchange can suffice, even for large heaps, by promoting the opposite root child and letting the moved key dominate that child's descendants. Thus the best case is two pairwise exchanges when the initial root/final-leaf exchange is counted. This is a convention about that implementation: a hole-moving implementation uses assignments rather than pairwise exchanges, and the worst case still has logarithmic time complexity.
Construct a binary heap from an array by processing internal nodes backwards, applying sift down at each. The complete binary tree shape ensures that the subtrees below the current node have already been repaired. The number of nodes whose height is at least is at most , so charging each repair by its height gives total work at most a constant multiple of . The construction takes time in either heap orientation, whereas inserting entries separately has an worst-case bound.
The minimum convention for heap order requires every parent in a rooted tree to have priority no greater than each of its children in a rooted tree. The displayed formula uses the array representation of a binary heap. It permits equal priorities and does not require a sorted array; the maximum convention reverses the inequality.
After inserting or lowering a key in a minimum-oriented binary heap, compare it with its parent in a rooted tree. Exchange them while the moving key is smaller, then continue at its new index. Stop at the root of a tree or when the heap order is satisfied. This repair assumes the rest of the binary heap was valid before the insertion or key decrease.
To repair a key in a minimum-oriented binary heap, choose the smaller-priority present entry among its children in a rooted tree. Exchange if that entry is smaller than the moving key, and continue at the new index. Stop when there are no children in a rooted tree or the heap order holds. The smaller rooted trees below the starting entry must already obey the heap order; choosing the larger child could leave a violation with the smaller one.
A hash table stores records by key: for example, a product number can select its current stock count without scanning every product. A hash function selects a hash bucket in an array, and a collision-handling method such as separate chaining retains distinct keys assigned to the same hash bucket. The useful idea is to narrow the search to one small collection, while key equality decides which record actually matches.
Use a map interface with one value per key:
get(k) returns the associated value or an explicit absent result; put(k,v) replaces the value if an equal key is present, otherwise inserts a new record; delete(k) removes the matching record if present. The absent result must be distinguishable from every permitted stored value. Replacing a value does not increase the record count . A hash collision between unequal keys must never cause one record to replace the other.[ref]Lecture 8: Hashing I. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; p. 1, dictionary operations and replacement of an existing key
Let denote the chosen key equality, an equivalence relation, and let be the bucket-index hash function for hash buckets. Correctness requiresThe converse is false: equal bucket indices merely identify candidates for a key equality comparison. If an implementation first computes a full hash value and then reduces it to a bucket index, equal keys must have equal values too. Keep both key equality and the hash function stable while a key is stored; changing the key so it selects another hash bucket can make its record unreachable. This distinction is explicit in the published
hashCode/equals contract.[ref]For a constructed integer example, use modular arithmetic to define and store keys with values . At , three records share hash bucket and one occupies hash bucket . The hash table load factor isIt is the mean number of records per hash bucket, including empty hash buckets, not a bound on the longest chain. With separate chaining, may exceed because records live in the chains rather than one record being confined to each array slot.
Growing this example to changes the bucket-index hash function: key now belongs to hash bucket , while keys still share hash bucket . Every record must be assigned using the new bucket-index hash function; copying the old array of chain heads unchanged is insufficient. The hash table load factor becomes .
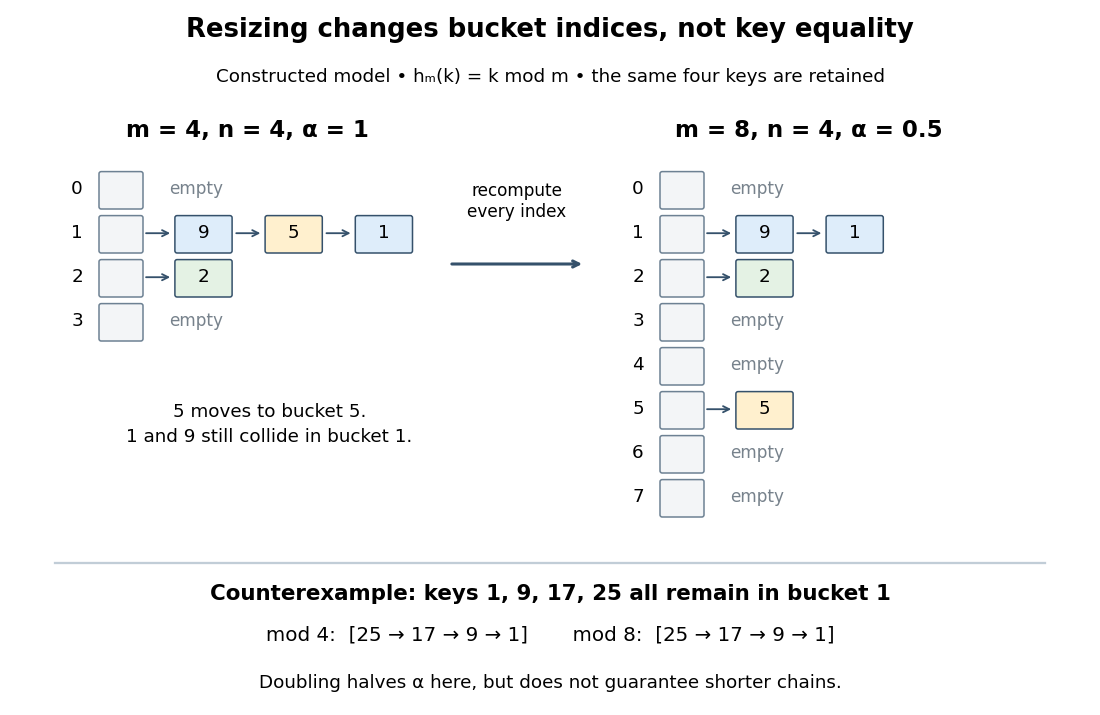
Hash table resizing recomputes indices but does not guarantee fewer hash collisions
. Original deterministic model using , not a measured implementation. The upper panels retain keys in four and eight hash buckets; chain order is illustrative. The lower counterexample retains all four keys in hash bucket even after doubling. Details.For an insertion-only sequence starting empty with constant initial capacity, one policy doubles before inserting a new key that would make . A rebuild for separate chaining allocates the new array and transfers each existing record directly into its new chain. Since keys are already distinct, transfer needs no duplicate search. With constant-cost hashing and linking, this takes time complexity, hence at a growth threshold. Amortized analysis charges the occasional rebuild across many insertions: the old capacities form a geometric series with sum , so total rebuilding work over insertions is . This gives amortized resizing overhead; an insertion that triggers a rebuild can still take .[ref]
Lecture 9: Hashing II. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; p. 2, rebuilding cost and geometric table doubling
The search to check for an existing key is additional work. Bounded hash table load factor together with the probabilistic assumptions in separate chaining gives expected amortized insertion, not worst-case . Rehashing alone gives no distribution guarantee: the diagram's keys all collide modulo both and . Even a low hash table load factor permits a long chain. If supporting shrinkage too, leave a gap between growth and shrink thresholds to avoid repeated rebuilding when insertions and deletions alternate near one threshold.[ref]
Lecture 9: Hashing II. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; p. 3, expected bounds and shrinking at one-quarter occupancy
A set data structure backed by a hash table. It stores each key at most once and supports membership tests, insertion, and removal with expected constant time under suitable hashing and load assumptions.
An associative array implemented with a hash table. It associates each stored key with a value and resolves collisions between keys with equal hash locations.
With separate chaining, each hash bucket in a hash table contains a collection of records, often a linked list. Lookup computes the bucket index, then follows that chain until a key equality comparison succeeds or the chain ends. A hash collision therefore affects the search work without merging unequal keys. Deletion searches the same chain and unlinks the matching record; in a singly linked list, remembering the preceding record during the search permits the unlink.[ref]
For the four-key integer example in hash table, insert a new record at the head of its chain after checking that its key is absent. Inserting in that order makes hash bucket hold , hash bucket hold , and the other two hash buckets empty. All five subsequent operations below select hash bucket because :
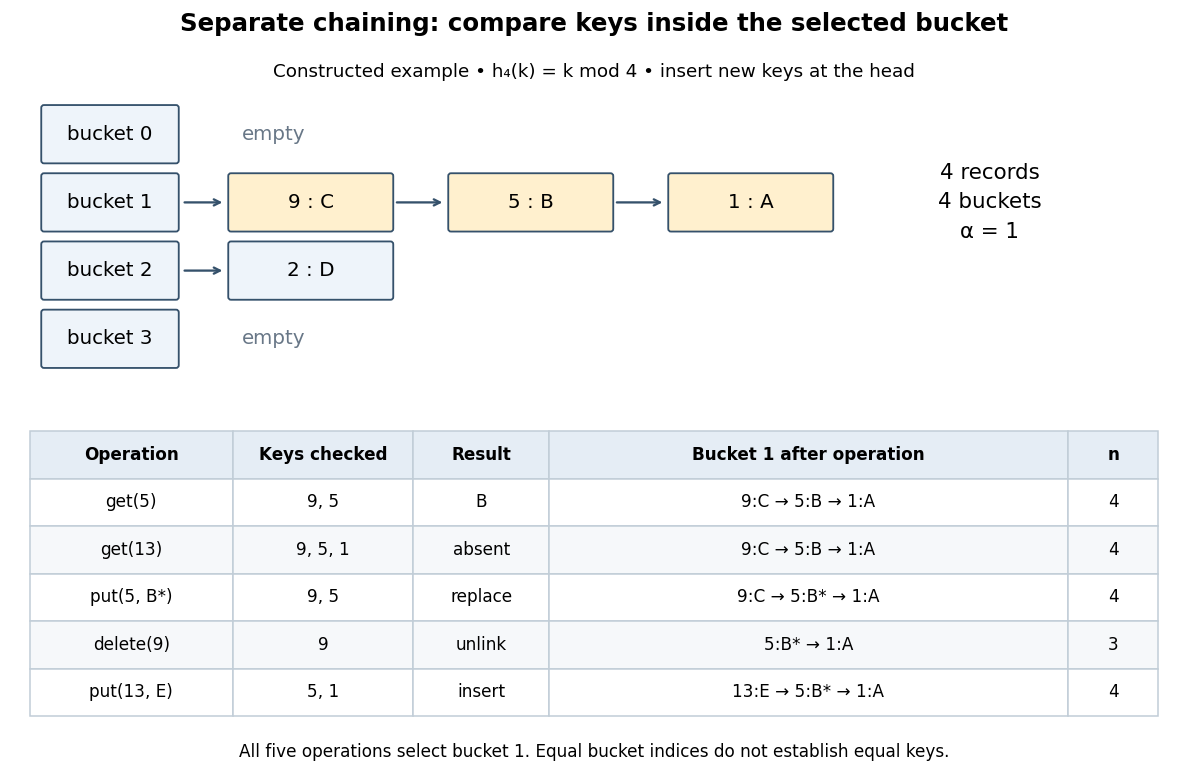
Separate chaining traces lookup, replacement, deletion and insertion through key equality
. Original deterministic model with . The table counts actual keys inspected, not elapsed machine time. Operations occur from top to bottom; only an absent key adds a new record, and the untouched record remains in hash bucket . Details.get(5) rejects key , accepts key , and returns after two key equality comparisons. get(13) rejects and reports absence after three comparisons. put(5,B*) examines and replaces the value without changing . delete(9) examines just the head record, removes it, and gives . Finally, put(13,E) rejects before inserting the new head record; returns to and the chain is . The successive hash table load factors are . These counts follow from the stipulated chain order; a different insertion policy changes the successful-search counts.For a chain of length , lookup and deletion by key take time complexity in Big O notation. The same applies to
put before any resizing, since replacement semantics require checking for an existing equal key. Head insertion alone is if absence is already known; that is a different precondition. These bounds assume bucket-index hashing, array access, key equality comparisons, allocation and link updates. A long string or large integer can make hashing or comparison depend on its encoded length, so counting record visits alone does not establish constant running time.Under simple uniform hashing, each distinct key's bucket index is an independent random variable with a uniform distribution on a finite set of indices. The keys and query are fixed independently of this random assignment. Then lookup has expected time complexity, where is the hash table load factor; it is expected when stays bounded. These are model assumptions, not an automatic consequence of using a deterministic hash function.[ref]
Lecture 8: Hashing I. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; pp. 4–5, chaining worst case and simple uniform hashing assumption
Here is the short calculation. For an absent query and stored keys , let be the indicator random variable of . The number of records inspected has expected valueby linearity of expectation. For a present fixed query, scanning its entire chain inspects at most itself plus all other colliding records, with expected value ; stopping at the match only decreases this upper bound. Adding constant hashing and bucket access yields expected for either query. The argument needs pairwise collision bounds; it does not require all the indicator random variables to be independent. A universal hash family can provide a related bound by random choice of a hash function for a fixed key set, as explained in that article.
The worst case remains , and an absent query takes comparisons if all records occupy its hash bucket. For instance, all collide under . Separate chaining remains correct, but a sequence of insertions that each checks the existing chain can take quadratic total work. Amortized analysis of resizing does not remove this search cost, and an adaptive choice of keys based on a known hash function is outside the stated simple uniform hashing model.
A probabilistic model assigning distinct keys independent bucket indices with a uniform distribution on a finite set. It supplies an expected value bound for separate chaining, not a guarantee for every deterministic hash function or workload.
A hash table collision-handling method storing at most one live record per array slot. A hash function chooses a starting slot, and a probe rule chooses further slots. Unlike separate chaining, records occupy the slots themselves.
An open addressing probe rule that visits modulo , using modular arithmetic, until a matching record or an appropriate stopping slot is found.[ref]
Lecture 10: Hashing III: Open Addressing. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; Lecture 10: Hashing III: Open Addressing, p. 3, Linear Probing formula
For capacity , the hash table probe numbered , starting at zero, inspects the array indexThe hash function gives the first array index. Each subsequent hash table probe moves one slot forward, wrapping from to by modular arithmetic. Keep the hash function and key equality fixed while hash table records are stored.
Use three distinguishable slot states: occupied by a live hash table record; never used since initialization or rebuilding, written
E; or deleted, written D, a tombstone in open addressing. Lookup compares occupied hash table keys using key equality, stops at E, and continues past D.[ref]5.2 LinearHashTable: Linear Probing. Open Data Structures: An Introduction by Pat Morin; Section 5.2, three entry types and find: nil stops lookup, del does not
For an original example, take an eight-slot array, integer hash table keys, and the hash function . Start with all slots
E and insert the hash table records in that order. The insertion hash table probe traces, expressed as array indices, areThe resulting array holds hash table keys at array indices , with E in the other four slots. The first three hash table keys have the same initial array index, a hash collision; the fourth begins at but joins the same linear probing cluster. Lookup of examines array indices , rejecting before returning . Lookup of absent examines , including the stopping E: five hash table probes for a hash table load factor .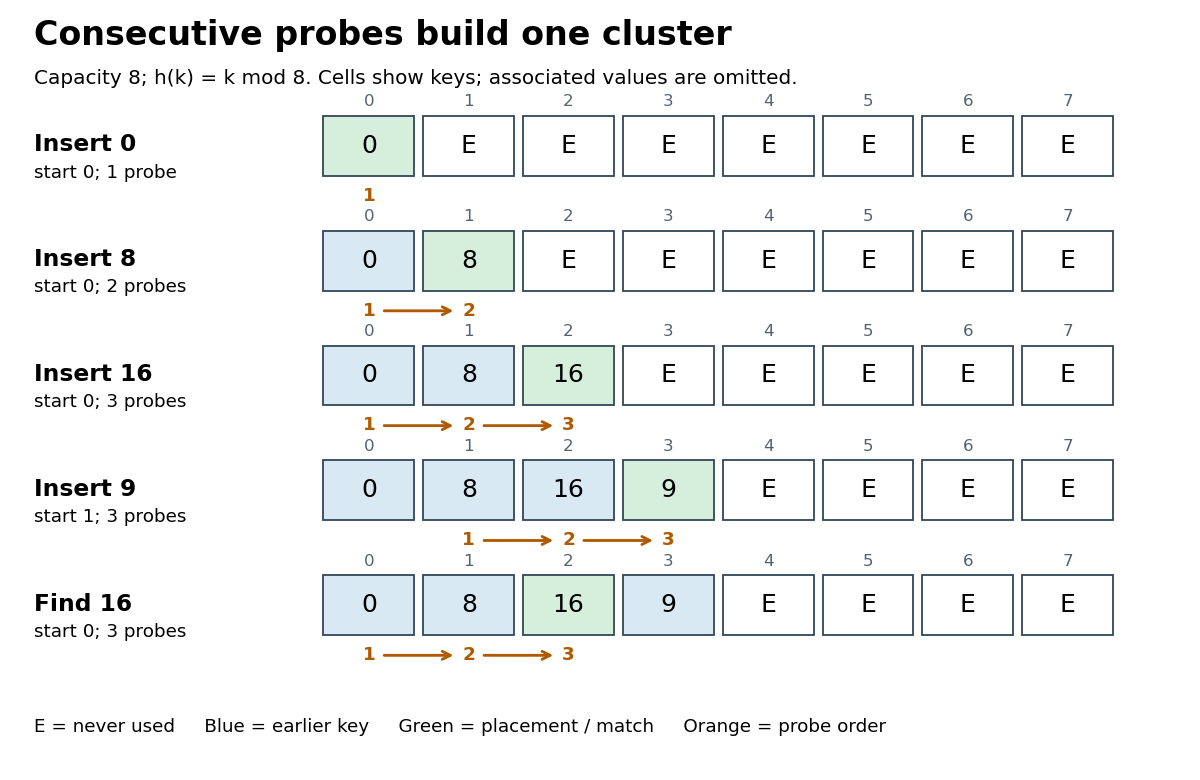
Bound lookup to at most hash table probes, even if no
E remains. For algorithm termination, the first array indices are distinct: equality of and implies that divides by modular arithmetic, and forces . They therefore cover the entire finite set of slots exactly once. If no occupied hash table key matches and no E is encountered, exhausting these hash table probes establishes absence; wrapping around again supplies no new information.[ref]Lecture 10: Hashing III: Open Addressing. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; Lecture 10: Hashing III: Open Addressing, pp. 1–2, probe permutation requirement and Search loop with m trials
The attraction is a compact array and a simple hash table probe rule. Consecutive slots can benefit from spatial locality, although actual memory cache behavior depends on representation and hardware. Correctness rests on preserving the search route; speed depends on how long that route becomes. The linear probing cluster below explains why even a moderate hash table load factor gives no universal constant lookup bound.
A maximal consecutive run of occupied or deleted slots in linear probing, bounded by never-used slots when any exist; adjacency wraps around by modular arithmetic. Deleted slots still belong to the search run.[ref]
5.2 LinearHashTable: Linear Probing. Open Data Structures: An Introduction by Pat Morin; Section 5.2.1, definition of a run using non-nil entries and modular indices
In the eight-slot example, array indices form one linear probing cluster. Inserting absent hash table key starts at , passes the occupied slots , and fills . This extends the same linear probing cluster despite having a different initial array index from . A hash collision at the initial slot is enough to make later slots compete too.
For a worst-case family, insert integer hash table keys into an empty capacity- array, using the hash function , where . They occupy array indices . Lookup of absent needs hash table probes. Taking gives hash table load factor at most while the number of hash table probes grows with . Thus occupancy alone cannot promise constant lookup work.
Before any rebuilding, bounded lookup, deletion by hash table key, and insertion with a duplicate check each have worst-case time complexity in Big O notation, assuming constant-cost hash function evaluation, array access and key equality. The counterexample gives a matching linear worst-case growth in the number of hash table probes. Hash table resizing is additional work; expensive string comparisons or hashing also fall outside these constant-cost assumptions.
In an insertion-only table, an absent hash table key starting anywhere inside a linear probing cluster reaches its far end. Filling a one-slot gap can merge two runs, joining hash table keys with different initial array indices into one long search route. The insertion of above exhibits this effect without a hash collision with at their initial slots.[ref]
Lecture 10: Hashing III: Open Addressing. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; Lecture 10: Hashing III: Open Addressing, pp. 3–4, Linear Probing and Figure 4: Primary Clustering
A deleted-slot marker in open addressing. Lookup continues past it because a hash collision may have displaced a match further along. Linear probing can reuse the slot for insertion after checking for an existing equal key. A genuinely empty slot can terminate lookup; this marker cannot.[ref]
5.2 LinearHashTable: Linear Probing. Open Data Structures: An Introduction by Pat Morin; section 5.2, find, add, remove, and correctness paragraph distinguishing del from nil
Delete hash table key from the original eight-slot example. Writing
E into array index makes lookup of inspect and incorrectly report absence, although its hash table record remains at . Writing D instead makes lookup pass and reach , returning after three hash table probes. The deleted slot must remember that the search route once continued through it.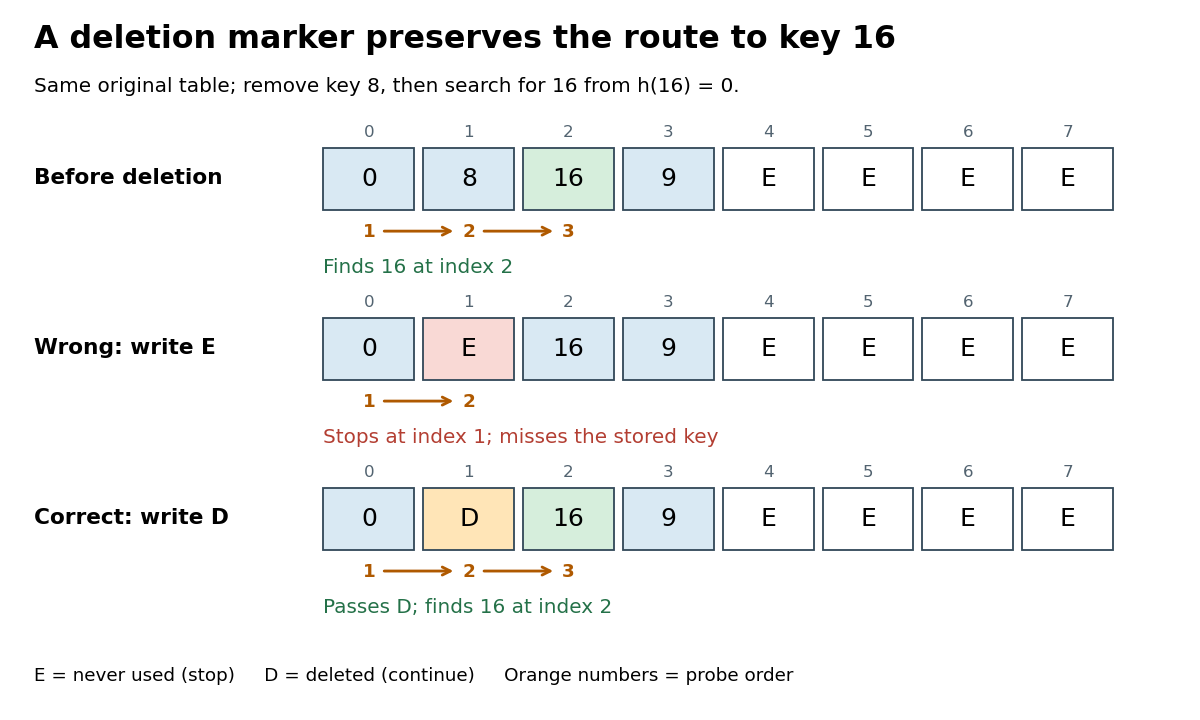
Deleting to an empty slot breaks lookup; a tombstone in open addressing preserves the search route
. Original deterministic comparison: the middle and lower rows are alternative deletions from the top row. E means never used and stops lookup; D means deleted and lets lookup continue. Orange numbers give the hash table probe order for hash table key . Details.A short algorithm correctness proof uses this invariant: no never-used slot precedes a stored hash table key along its linear probing route. Initially the claim is vacuous. Insertion places a new hash table record no later than the first
E, possibly at an earlier D, and cannot create an E before another stored hash table record. Replacing a value leaves all slots occupied as before. Deletion to D also creates no E. By mathematical induction over operations, the invariant persists, so stopping lookup at E is sound. Deletion directly to E invalidates that argument, as the diagram shows.To implement the hash table map operation
put(k,v) in one bounded scan, remember the first D encountered, but keep checking occupied hash table keys. A later key equality match means replace that hash table record's value and stop. Only after reaching E, or completing hash table probes, is absence established. Then insert at the remembered D, if any; otherwise use the stopping E. If all slots are occupied and no match exists, report full or rebuild before trying again. Merely finding D is not permission to create a second equal hash table key.[ref]Continue from the correctly deleted example, with hash table keys at array indices and
D at . put(16,Z) examines and updates the value at , leaving deleted and retaining three live hash table records. Inserting immediately at would instead create two copies of . Now put(24,W) examines , proves absence at E, and places the new hash table record at the remembered array index . The hash table load factor rises from to ; reusing D avoids extending the linear probing cluster to .For a boundary case, fill all eight slots with hash table keys and then delete all eight to
D. The live hash table load factor is zero, but absent lookup of still needs eight hash table probes. put(16,C) also checks eight slots before reusing the first D, at array index . A loop that waits indefinitely for E would never finish in this state. Rebuilding from the live hash table records into a fresh array removes each tombstone in open addressing and restores never-used stopping slots.[ref]5.2 LinearHashTable: Linear Probing. Open Data Structures: An Introduction by Pat Morin; Section 5.2, resize: reinsert live elements and reset the non-nil count to the live count
One inspection of an array slot during an open addressing operation. Its array index follows the chosen probing rule; its contents determine whether to continue, return a matching hash table record, or establish absence.
The collection of records assigned to one bucket index by a hash function. In separate chaining, an array slot refers to this collection, which may be empty.
For hash buckets, number them and write for the number of records in hash bucket . Each record belongs to exactly one hash bucket, soAn empty hash bucket contributes zero to this sum but still contributes one to the denominator . The hash table load factor therefore measures records per allocated hash bucket, not records per nonempty hash bucket. A hash bucket is a destination selected by the bucket-index hash function; with separate chaining, its records need not occupy consecutive positions in computer memory.
For the twelve-record concentrated placement in load factor of a hash table, one hash bucket contains twelve records and seven hash buckets are empty. Averaging only over nonempty hash buckets gives , whereas the hash table load factor is . This difference matters when deciding how much array capacity to allocate. For , the largest hash bucket satisfies ; the lower bound follows because at least one entry cannot be below the arithmetic mean. Neither inequality says that an actual hash function achieves a balanced placement.
The equivalence relation used to decide whether two keys name the same record. A hash function must respect key equality; a hash collision does not establish key equality.
The choice of key equality is part of the map's meaning. In the one-value-per-key policy of hash table, one record represents each stored equivalence class of keys:
put(k,v) updates an existing equal key and adds a record only if no equal key is present. A collection that deliberately retains repeated equal keys has a different policy; its load count must count those extra records too. Repeated calls and distinct stored records are different quantities.[ref]Lecture 8: Hashing I. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; p. 1, Dictionary Problem: distinct keys or replacement on repeated insertion
For an original example, restrict keys to two-letter strings using letters
A through Z or a through z. Declare two keys equal when replacing every uppercase letter by its lowercase counterpart gives the same string. Assign each letter its position in the alphabet, ignoring case, and define the bucket-index hash function as the sum of the two positions modulo , using modular arithmetic. Then AB and ab are equal keys and both select hash bucket . Key ba also selects hash bucket because , but is unequal to ab: order still matters. Starting empty, put(AB,7), put(ab,9), put(ba,4) leave two records, with values for the ab equivalence class and for ba; the hash table load factor is , not .The compatibility rule is one-way: . Otherwise a lookup using an equal spelling could search a different hash bucket and incorrectly report absence. Equal indices merely allow a key equality check. Both the equivalence relation and the hash function must stay consistent while records are stored; changing equality-relevant key contents can invalidate the lookup rule. The Java contract imposes these consistency and equality requirements on
equals and hashCode.[ref]Object (Java SE 25 & JDK 25). Java Platform, Standard Edition 25 API Specification by Oracle; Method Details, equals equivalence-relation contract and hashCode general contract
Articles were limited to the first 100 out of 211 total.



