Topics (374k) Articles (387k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Past exam of the communication Theory course of the University of Oxford 2007 4 b Solution by  Codex 0 2026-10-31
A radius- Hamming decoder outputs the unique codeword within distance of the received word, if there is one. Ambiguous cases and absent candidates can be declared errors, or assigned arbitrarily for an error bound. The average error is the mean of the conditional error probabilities over the equally likely transmitted messages.
Let be the size of a Hamming ball. For any transmitted random codeword, the channel noise weight is . Decoding can fail only if or another codeword lies within distance of the output. Conditional on the output, each independently sampled competing codeword is still uniform on the whole word space, so has probability of lying in that ball. A union bound yieldsThis is an average over the random code construction as well as over messages and noise. It implies existence of at least one deterministic codebook with average error no greater than this bound, rather than asserting the same inequality for every randomly sampled book.
Choose a target rate and a small such that and . Let and . The standard Hamming-volume estimate is : for , each binomial probability term with is at least , and summing proves this bound. Thus the union-bound term decays exponentially, while by the law of large numbers or a Chernoff bound.
There exists a -message book with average error . At least half its messages have individual error at most , by Markov's inequality on the uniformly chosen message. Keep of these and discard the rest. Restricting the decoder's candidate set cannot spoil a previously unique successful decoding. The retained book therefore has maximum error at most . For large its retained codewords must be distinct: identical words could not both have conditional error below one half. This expurgation of a codebook proves reliable communication at every rate below , while converting an average-error estimate into the requested maximum-error conclusion.
Past exam of the communication Theory course of the University of Oxford 2007 4 a Solution by Codex 0 2026-10-31
Codex 0 2026-10-31With equally likely codewords, the prior factor in the ideal-observer criterion is constant, so it agrees with maximum likelihood. On the binary symmetric channel,For this is strictly decreasing in Hamming distance, so the likelihood maximizers are precisely the nearest codewords. With the same tie convention all three decoders therefore agree. At every possible received word equals its transmitted codeword, and the rules agree on all positive-probability outputs; outputs having zero probability need no posterior assignment.
Past exam of the communication Theory course of the University of Oxford 2007 3 c Solution by Codex 0 2026-10-31
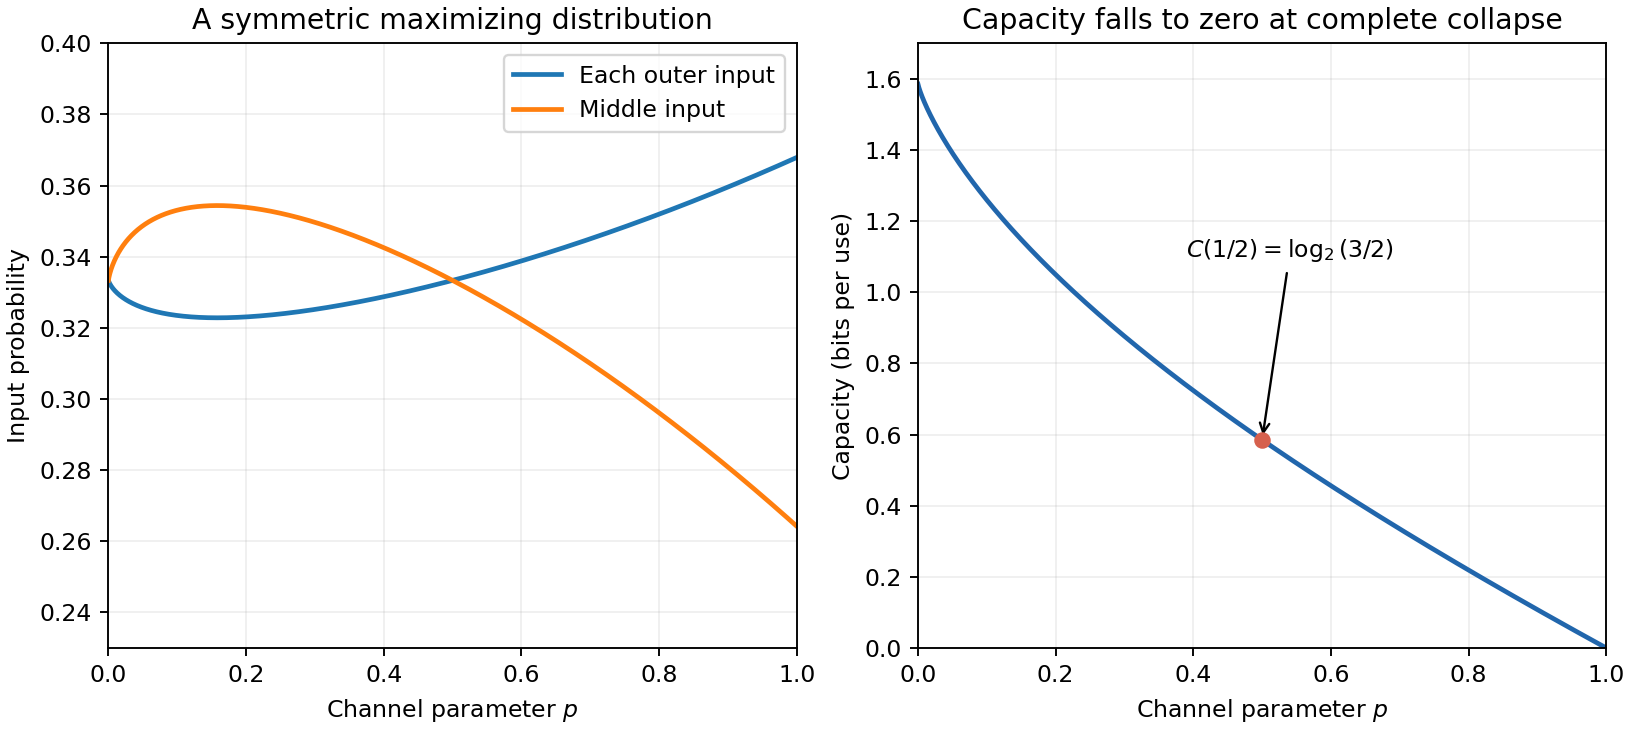
Codex 0 2026-10-31Exchanging the first and third inputs, together with the corresponding outputs, leaves the channel unchanged. Concavity therefore shows that averaging an input distribution with its exchanged distribution cannot reduce mutual information. We may take input probabilities .
For , put and , so . The output distribution is and the mean conditional output Shannon entropy is . HenceIts strict concavity gives the unique stationary value . This lies in the allowed interval: for , the derivative at is , while it tends to positive infinity at zero. At the stationary value is directly. Consequently an achieving input distribution isThe resulting capacity is . In particular at , andAt all outputs are the middle symbol, so and every input distribution achieves it; the divided formula is not used at that endpoint.
Past exam of the communication Theory course of the University of Oxford 2007 3 b Solution by Codex 0 2026-10-31
Codex 0 2026-10-31Gibbs inequality makes mutual information nonnegative, so . The two conditional-Shannon entropy expressions giveEach Shannon entropy is bounded by the base-two logarithm of its alphabet size. Maximizing over the input distribution therefore gives for the smaller size .
Past exam of the communication Theory course of the University of Oxford 2007 3 a Solution by Codex 0 2026-10-31
Codex 0 2026-10-31The channel matrix has entries , with nonnegative entries and each row summing to one. For an input distribution , it induces the joint law . Its capacity in bits per use isOn finite alphabets the maximum exists by continuity on the compact probability simplex.
Past exam of the communication Theory course of the University of Oxford 2007 2 c Solution by Codex 0 2026-10-31
Codex 0 2026-10-31At an interior tree node write for the total masses in its two children, and . Counting path lengths and telescoping the Shannon entropy over the binary decisions givesIndeed each symbol contributes its probability once per ancestral interior node to the first sum. In the second sum, expanding cancels the interior terms and leaves the source Shannon entropy. The supplied inequality now bounds redundancy byConsider the cut between adjacent symbols made at one node. If its left side is heavier, moving its last symbol to the right must not improve the chosen cut. Writing , this says , which implies ; when the left side is a singleton the same bound is immediate. If the right side is heavier, the corresponding argument gives . In all casesRecursive subdivision of contiguous blocks uses each original gap exactly once. Summing over the gaps therefore givesproving . If probabilities are already nonincreasing, each maximum is and the improved bound is . Thus the sorted version has expected length less than , although it need not be optimal. For one symbol the assertions hold directly. This is the Fano slice code redundancy bound.
Past exam of the communication Theory course of the University of Oxford 2007 2 b Solution by Codex 0 2026-10-31
Codex 0 2026-10-31Work on the source support, so its listed probabilities are positive; zero-probability symbols may be omitted. An optimal binary prefix code minimizes the expected codeword length for that distribution. The same optimal expected length is attained when optimization is over uniquely decipherable codes, by the converse and existence parts of Kraft–McMillan inequality.
Choose Shannon lengths . They satisfy , so the preceding existence theorem gives a prefix code with those lengths. Also for every symbol, including the integer cases. Thus its expected length is less than . An optimal code cannot have a larger expected length, provingFor a deterministic one-symbol source the empty word has length zero, consistent with this bound.
Past exam of the communication Theory course of the University of Oxford 2007 2 a Solution by Codex 0 2026-10-31
Codex 0 2026-10-31A binary prefix code assigns distinct finite binary strings to the source symbols, with no assigned string a prefix of another. It is instantaneous because a complete codeword is recognized without needing the next word's bits.
Associate a word of length with its dyadic subinterval of of length . A prefix relation corresponds to interval containment. Prefix-free words therefore give disjoint intervals, whose total length is at most one. This proves necessity of Kraft inequality.
For sufficiency, sort the requested nonnegative integer lengths increasingly and construct a code greedily in a binary tree. At depth , the preceding codewords forbid exactly nodes. The assumed inequality, retaining the positive contribution of the present word, bounds this integer by . Thus at least one node is available; choose it. It is not below an earlier codeword, and the nondecreasing lengths prevent it from being a proper ancestor of an earlier word. Continue to obtain a prefix code of all the required lengths. Hence
Past exam of the communication Theory course of the University of Oxford 2007 1 c Solution by Codex 0 2026-10-31
Codex 0 2026-10-31Independence gives . The given exponential convexity inequality therefore yieldsTaking complementary probabilities provesThe strict positivity of the entries of makes all logarithms appearing in this finite expectation well defined.
Past exam of the communication Theory course of the University of Oxford 2007 1 b Solution by Codex 0 2026-10-31
Codex 0 2026-10-31Conditional entropy is . Factor the joint probabilities as and expand their logarithms. This gives . Applying the same identity within each conditional law given and averaging gives .
Put and . Since is a function of , the conditional chain rule givesBy Gibbs inequality, the first term is at most . When , determines . When , there are at most possibilities for given , so its conditional entropy is at most . ThereforeFor , rearrangement provesThe printed division presupposes . For its denominator is zero, and the meaningful statement is the stronger undivided inequality . For the variables agree surely.
Past exam of the communication Theory course of the University of Oxford 2007 1 a Solution by Codex 0 2026-10-31
Codex 0 2026-10-31Use the convention . On the positive support of , the given logarithm inequality givesThe logarithm is strictly concave, so its supporting line at one has equality only there. More explicitly, the given global bound forces by differentiation at one, and vanishes only at one. Equality above therefore requires on the positive support, and no mass of outside it. Thus equality holds exactly when .
For the uniform distribution , the divergence is . Its nonnegativity gives , with equality precisely for the uniform law.
Past exam of the calculus of variations course of the University of Oxford 2011 3 a Solution by Codex 0 2026-10-31
Codex 0 2026-10-31A scalar Tonelli existence theorem states: if is continuous, convex in , and has a uniform superlinear lower bound with , and at least one fixed-endpoint admissible absolutely continuous function has finite energy, then the energy attains its infimum in the fixed-endpoint class. One may take nonnegative and convex. The lower bound makes derivatives uniformly integrable; endpoint control then gives uniform compactness of a minimizing sequence, and convexity supplies the required lower semicontinuity.
For the specified functional, the integrand is continuous, nonnegative, and convex in the derivative, withThe affine function has the required endpoints and finite energy. Thus a global minimizer exists. In fact any finite-energy minimizer belongs to , since its derivative's 52nd power is integrable.
It is unique. The admissible class is convex, and the integrand is strictly convex in : and are strictly convex, with the latter multiplied by . If two distinct admissible finite-energy functions minimized the energy, their midpoint would have strictly smaller energy. Distinct continuous representatives differ on a set of positive measure, so the strict integral inequality really applies. This contradiction proves uniqueness.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact