For finite discrete random variables, conditional entropy is the average remaining information entropy of after the value of is known:Each observation changes the probability distribution used to describe ; the average weights that uncertainty by how often the observation occurs. An observation can increase uncertainty for one particular outcome, even though conditioning reduces entropy on average for finite variables.
For example, let choose with probabilities , and let report whether . If it reports yes, there is no remaining uncertainty. Otherwise the conditional probabilities are , whose information entropy is bits. The two reports each occur with probability , so of a bit. The original uncertainty was bits: this observation removes exactly one bit on average.
If is a function of , then : the observation determines the answer. If and are independent random variables, then : the observation gives no improvement. These endpoints make conditional entropy useful for separating relevant observations from irrelevant ones. They also lead to the chain rule for information entropy, , which counts the first uncertainty and the remaining uncertainty without double counting.
For discrete random variables with finite information entropy , Gibbs inequality givesEquality holds exactly when and are independent random variables. Finiteness matters: if has infinite information entropy and is independent of a fair bit , then and are dependent but .
// Target: probability-and-statistics.bigb
For classical finite random variables, . Each identity follows by inserting the corresponding joint entropy into . The two orders are particularly useful when one variable is a deterministic function of the others, as in Fano's inequality via an error indicator.
If is a bijection of for every fixed , thenIn particular, translating a random variable in a finite group by a value determined by the conditioning variable does not change its conditional entropy.
For finite discrete random variables , knowing reduces the information entropy of on average:Equality holds exactly when and are independent random variables. The average over observations is essential: can exceed for a particular . All logarithms here have base two, giving bits, and zero-probability terms contribute zero.[ref]
For Bayesian inference, this compares a prior distribution with the posterior distributions produced by possible observations. An unexpected report can make previously unlikely alternatives plausible, while useful reports reduce uncertainty overall. For lossless source coding, an observation shared by encoder and decoder lets them choose descriptions for the appropriate conditional distribution; sending that observation also has a cost. The example below makes both the saving and that cost explicit.
In A Mathematical Theory of Communication by Claude Shannon (1948), the definition of conditional entropy is already an average over observations, followed by the inequality and its independence condition in section 6, property 6. The phrase “knowledge reduces uncertainty” must be read with that averaging convention.[ref]
A Mathematical Theory of Communication by Claude Shannon. p. 12; title page identifies C. E. Shannon and the 1948 journal publication
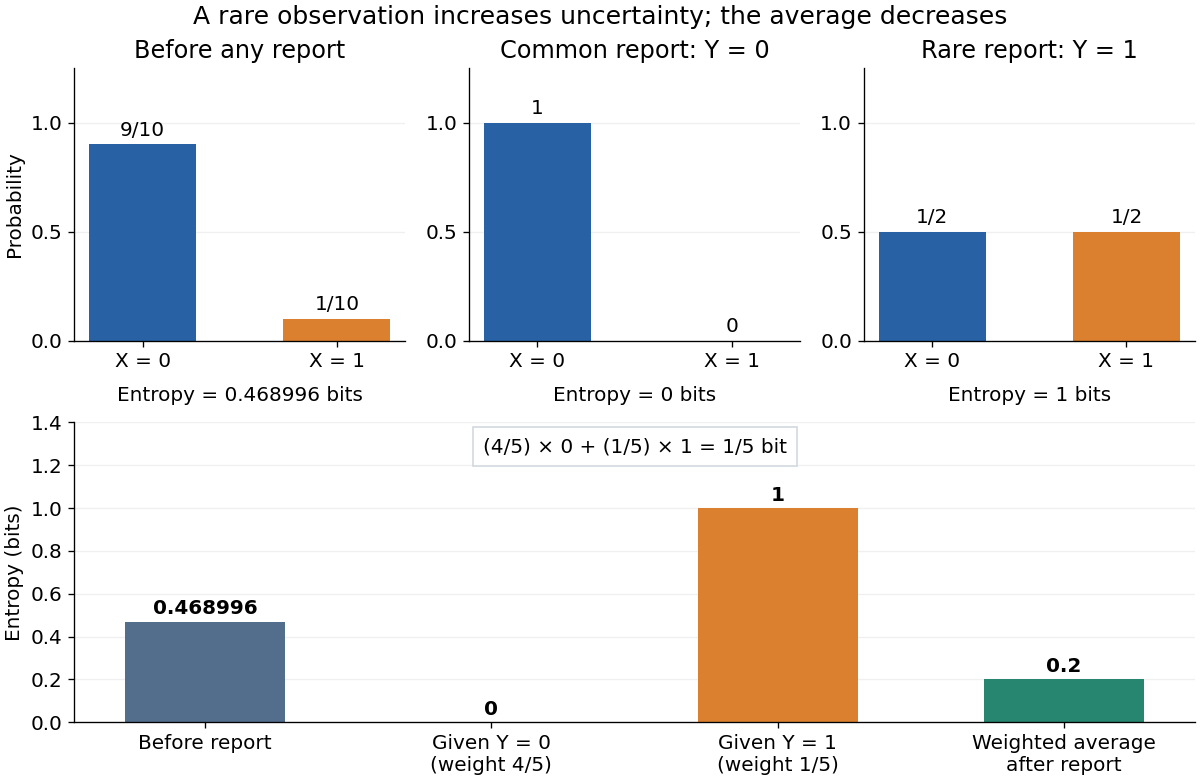
Consider a binary state and a report with the following joint probability mass function:Before the report, is strongly favored: its information entropy is bits, where is binary entropy. A report makes the two states equally likely, so bit, strictly larger than before. This report occurs with probability . The more common report determines , giving . Therefore the averaged conditional entropy isThe resulting mutual information is bits. The rare report increases uncertainty about the state; that increase does not make the report useless. Together the reports remove uncertainty on average. These are stipulated probabilities in an exact model, not measured frequencies.
Let be a Bernoulli random variable with . Independently of , a Bernoulli random variable with decides whether to reveal it:The symbol means “hidden” and is distinct from both binary states. This is a binary erasure channel with erasure probability . The hidden report leaves the posterior distribution equal to the prior distribution, because hiding is independent of the state. Either visible report determines . Weighting these three reports gives the exact conditional entropy and mutual information:For and , bits, while bits. With the report tells us nothing; with it reveals the state completely. If , every positive reveal probability makes the conditioning inequality strict. At or , the state was already known and every value of gives equality.
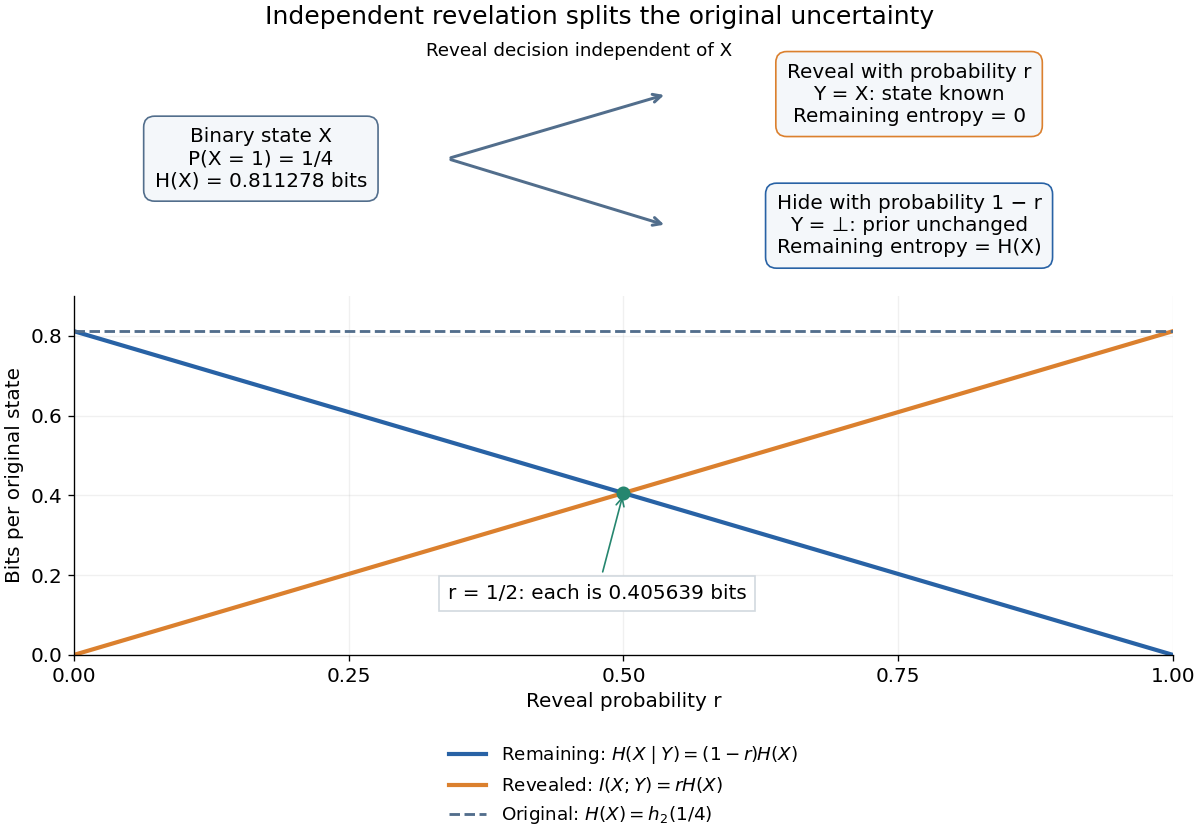
For a Bayesian inference problem, this model distinguishes an uninformative missing report from a decisive observed state. If hiding depended on , even could carry mutual information, and the displayed calculation would change. In lossless source coding, suppose both encoder and decoder already know the reveal pattern for repeated independent and identically distributed pairs. Only the hidden states require descriptions. Applying Shannon's source coding theorem to those states gives an asymptotic average rate bits per original state. A single hidden state need not have a codeword of that fractional length.
The reveal pattern itself has information entropy . If that pattern must also be sent, the chain rule for information entropy gives , since and are independent random variables. Equivalently, and . Thus a saving in the description of given assumes that is already available; it is not a free saving in the description of the whole pair.
For finite discrete random variables , retaining and also observing givesEquality means conditional independence of and given . Both sides average over reports; the additional observation is retained alongside .[ref]
Chapter 2: Information Measures: Mutual Information. Definition 2.4 and Theorem 2.5(1), printed pp. 26–27
A short proof of the original inequality uses Kullback-Leibler divergence:Gibbs inequality makes each term nonnegative, vanishing exactly when : independence for every possible report. Applying this within each and averaging proves the additional-conditioning inequality.[ref]
With appropriate probability density functions and finite differential entropies, , with equality iff independence. Differential entropy does not reverse the inequality; infinite or undefined quantities cannot justify subtraction.[ref]
Chapter 2: Information Measures: Mutual Information. Theorem 2.4(3), printed p. 24: density and finiteness hypotheses for the differential-entropy identity
However, differential entropy can be negative and depends on the choice of coordinates. For with a uniform distribution on an interval of length , ; in particular gives . Rescaling by a constant adds to both and , whenever they are finite, leaving the mutual information unchanged.[ref]
A Mathematical Theory of Communication by Claude Shannon. pp. 37–38: coordinate dependence, negative entropy, and linear rescaling
If a continuously distributed is revealed exactly, its conditional distribution is a Dirac measure with no ordinary probability density function. The discrete identity has no finite differential entropy counterpart. Mutual information, defined through relative entropy, is infinite here.[ref]
Fano's inequality turns remaining uncertainty into a constraint on decision errors. If an observation leaves many plausible answers, a decoder cannot usually recover the answer reliably. Its elegant idea is to separate two uncertainties: whether the guess was wrong, and which alternative was correct when it was wrong.
Let be discrete random variables, with taking values in a finite alphabet of cardinality . Choose any deterministic decoder whose output lies in , and define its average error probability . With base-two logarithms, Fano's inequality statesHere is conditional entropy and is binary entropy, with at the endpoints. Both sides are measured in bits; using natural logarithms throughout gives the same inequality in nats. No uniform source, independence of , or optimality of the decoder is assumed. Requiring its output to belong to the same alphabet is what leaves at most alternatives after an error.[ref]
For an exact toy example, give the discrete uniform distribution on . A channel reports with probability and reports each of the other three symbols with probability , where . Use the decoder . The output is uniform, and the conditional probabilities after any report areThus and direct calculation of the conditional entropy givesThis is equality in Fano's inequality for every . At , each report leaves probabilities , up to their order, and bits. The two contributions are bits for the error flag and bits for identifying the correct alternative after an error. These are theoretical probabilities, not measured data.
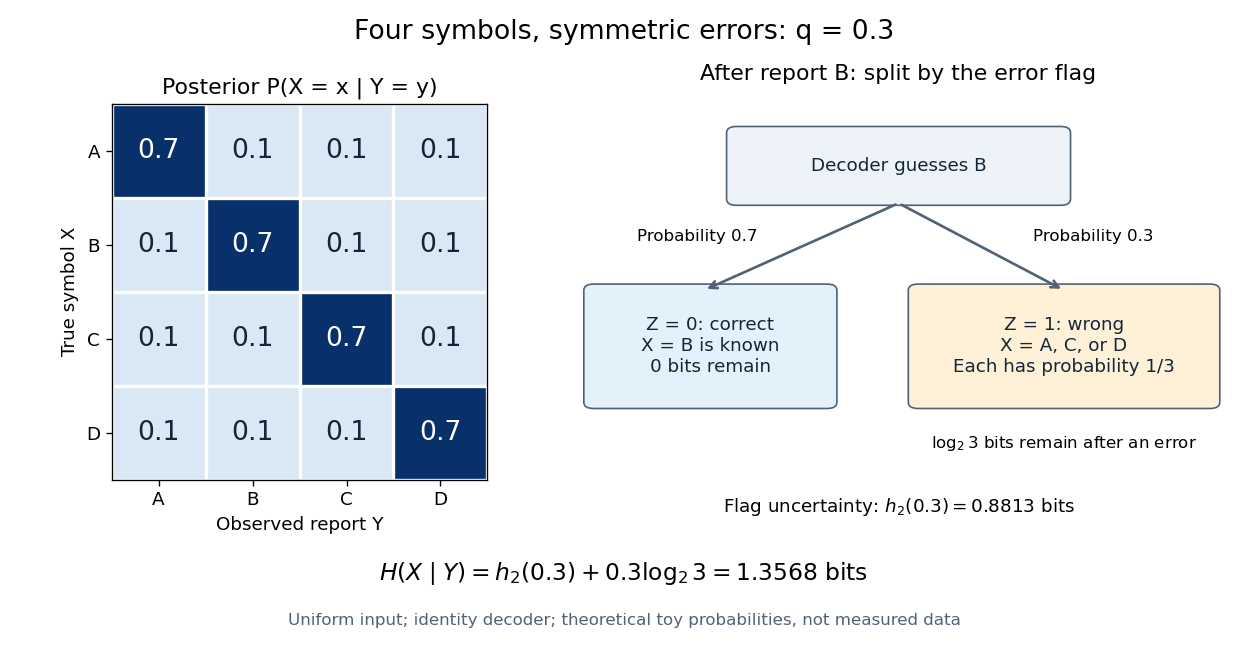
The identity decoder in this example minimizes error only for : its guessed symbol has the largest posterior probability exactly when . At , are independent random variables and all four guesses tie. For , guessing any one of the three other symbols has error probability . Equality in Fano's inequality therefore does not certify an optimal decoder.
For usefulness, combine with to obtain the simpler consequenceFor a uniform , , so this becomes . This connects mutual information to unavoidable decision error in channel coding or classification in statistical learning; it can rule out reliable recovery regardless of the chosen decoder.[ref]
https://web.stanford.edu/class/ee376a/files/lecture_notes.pdf. Weissman, Ochoa and Tatwawadi, EE376A course notes, Sections 5.7–5.8
The sharper right-hand side increases from zero to on , then decreases: in the interior, . When interpreting the inequality by inverting a curve, use its increasing branch to obtain a lower error threshold. A decoder that chooses a largest posterior probability, as in maximum a posteriori decoding, always has , since the largest of conditional probabilities is at least . Arbitrary decoders can have larger error. In particular, low conditional entropy does not force every decoder to work well: with a fair binary and , the rule has even though . Fano's inequality supplies a constraint, not an exact error prediction for each rule.
Under the hypotheses of Fano's inequality, let , , and let be the indicator random variable of an error. Its probability of being one is . The in the displayed bound denotes binary entropy in bits. Since is a deterministic function of , . Applying the chain rule for conditional entropy in both orders gives the exact decompositionThe first term is bounded by , because conditioning reduces entropy. For the second term, fix a report : if , then is known; if , then lies among at most other symbols. Maximum entropy on a finite alphabet bounds the latter uncertainty by . Averaging over the reports and the error flag givesThis proves Fano's inequality. Events of zero probability contribute zero to this average, so the proof also covers without assigning a conditional distribution to an impossible event.[ref]
https://web.stanford.edu/class/ee376a/files/lecture_notes.pdf. Weissman, Ochoa and Tatwawadi, EE376A course notes, Section 5.7, proof of Theorem 46
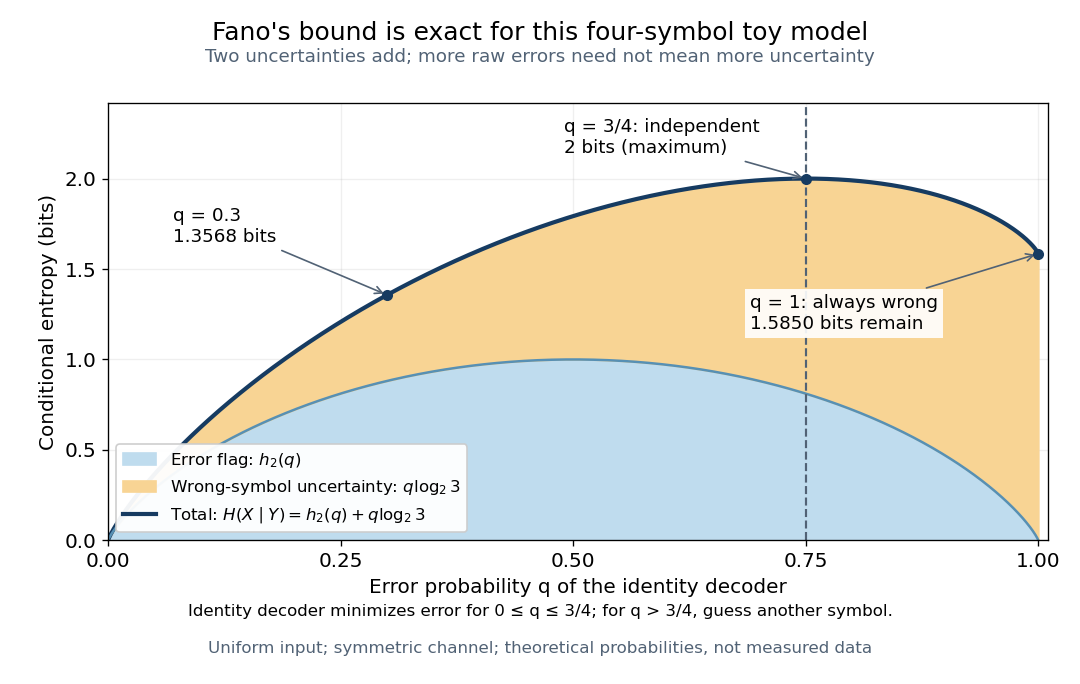
The four-symbol entropy budget peaks at chance-level error and separates the error flag from the three alternatives
. Details. The decomposition also explains equality. The first bound is exact when the indicator random variable and are independent random variables: knowing the report does not change the error probability. The second is exact when, for every report with positive error probability, the wrong-symbol conditional distribution is uniform on all alternatives. Both conditions hold in the four-symbol toy channel of Fano's inequality. At , the second condition is vacuous; at , the flag is constant but three alternatives remain, giving . For , there is just one alternative after an error, so the second term vanishes: all remaining uncertainty is whether the single alternative must replace the guess.
If a uniform index has possibilities and every proposed success neighbourhood contains at most possibilities, then any estimator has failure probability at least the displayed expression. Condition on its success indicator: conditional entropy is at most . Subtract this from to bound the mutual information and rearrange. A metric Hamming ball gives approximate recovery rather than exact index decoding.
If independent random variables take values in a finite additive group, thenIndeed, , and symmetrically for . Independence is essential: taking makes the sum constant.
Articles by others on the same topic



Conditional entropy is a concept from information theory that quantifies the amount of uncertainty or information required to describe the outcome of a random variable, given that the value of another random variable is known. It effectively measures how much additional information is needed to describe a random variable \( Y \) when the value of another variable \( X \) is known.