For finite discrete random variables, mutual information is the reduction of information entropy provided by observing the other variable:The last expression makes the symmetry visible. It is nonnegative and is zero exactly when and are independent random variables. One way to see both facts iswhere is the Kullback-Leibler divergence with base-two logarithms. The Gibbs inequality gives nonnegativity; equality means that the joint probability distribution factors. The statement extends to more general distributions via relative entropy, but differences of infinite information entropies must not be used as if they were finite numbers.
A binary symmetric channel gives a useful example. Let be a fair bit, let be an independent Bernoulli random variable with error probability , and set , where is exclusive or. The output is also a fair bit, but knowing the input leaves just the error uncertainty:Here is binary entropy. At , , so the output carries about bits of mutual information about the input per use. This is an average uncertainty reduction, not a claim that each observed symbol can be divided into fractional physical bits.
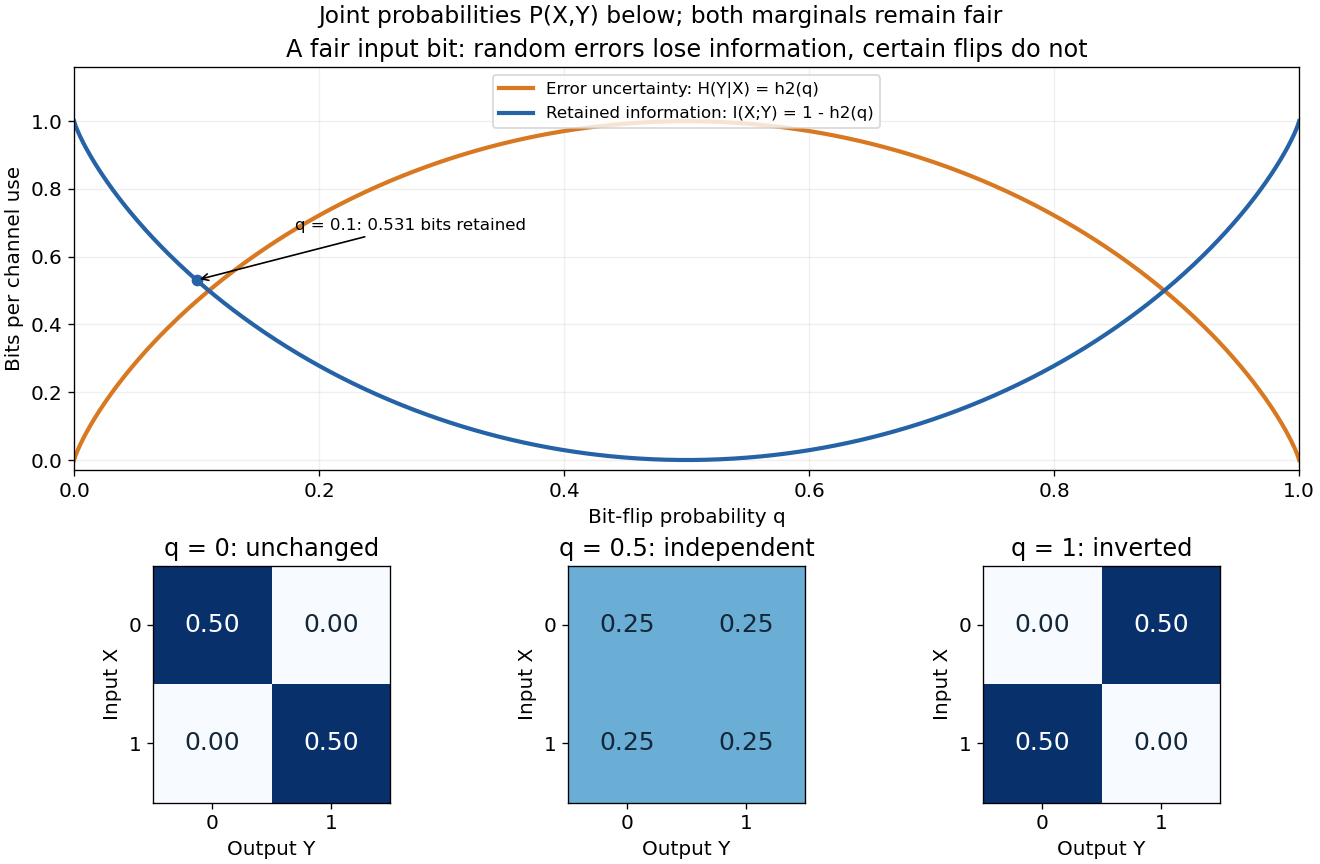
Binary entropy and retained information distinguish noisy transmission from predictable bit inversion
. Details. At , every output is equally likely for either input, so . At , the output is always the inverted input: knowing this rule lets the receiver recover the input exactly, so again. A high raw error rate need not mean low mutual information when the errors are predictable. For this particular channel the fair input is optimal, giving the binary symmetric channel capacity .
Mutual information detects dependence that ordinary correlation can miss. Let be uniform on and . Symmetry gives , hence zero covariance and zero correlation, while is completely determined by . Thus . This distinction is useful whenever a relationship is nonlinear: knowing one variable can reveal another without a linear trend.
For a fixed finite discrete memoryless channel , the function is concave on the input probability simplex. Indeed, the induced output law is linear in , the output Shannon entropy is concave, and is linear. Their difference is therefore concave. Equivalently, at a mixture , the concavity gap is by Gibbs inequality. Thus every local maximum is a global maximum, and averaging over symmetries of the fixed channel cannot decrease mutual information.
For discrete random variables ,The difference between the left- and right-hand sides is the nonnegative conditional mutual information .
A union-intersection compression can only decrease the sum of information entropies for a finite-valued random vector . Each elementary step follows from entropy submodularity; iteration proves the assertion with multiset multiplicities. Uniform coordinate multiplicity gives Shearer inequality by compressing to repeated full sets and empty sets.
Let be a finite multiset of subsets and let count its occurrences of coordinate . Its nested compression consists of . Then , by repeated entropy submodularity. This is the compression formulation in Balister and Bollobás, "Projections, Entropy and Sumsets".
For a nonempty ordered coordinate set , write and . An exact -cover satisfies . A short proof uses the chain rule for information entropy contributions : each conditional subset entropy bounds on the appropriate side, by conditioning reduces entropy. Weighting gives the lower inequality for a fractional packing and the upper inequality for a fractional cover. See Madiman and Tetali, "Information Inequalities for Joint Distributions".
Let be a discrete random vector, and let be a collection of subsets of in which every index occurs at least times. ThenApply the chain rule for information entropy to each projection and use conditioning reduces entropy to compare every term with the corresponding conditional entropy in the full chain rule.
If every pair of graphs in a family on has a graph intersection without an isolated vertex, the family has at most members. At each vertex, its possible graph neighbourhoods form an intersecting family, of size at most . Every edge occurs in two such neighbourhood projections. Shearer inequality bounds twice the full information entropy by the sum of their information entropies.
For finite discrete random variables, conditional mutual information measures the average reduction in uncertainty about from observing , when is already known. With base-two logarithms, it is measured in bits:The second expression follows from the chain rule for conditional entropy and makes the symmetry in visible. Equivalently, compute the mutual information separately in each conditional probability distribution and then average:Here is the Kullback-Leibler divergence, also computed with base-two logarithms; zero-probability terms contribute zero. The Gibbs inequality gives , with equality exactly when and have conditional independence given : the conditional joint probability mass function factors for every of positive probability.[ref]
For a fully computed example, take independent random variables that are fair bits, and let , where is exclusive or. The complete joint probability distribution has only these four positive entries:
Table 1. .
Every pair has probability , so . But . Given , the pairs each have conditional probability , while both conditional marginals are fair. ThusGiven , the pairs give the same calculation. ThereforeThe conditional entropy calculation tells the same story: because either value of leaves fair, whereas because . Learning the exclusive or does not reveal either bit alone; it reveals whether they agree, so learning one then determines the other.
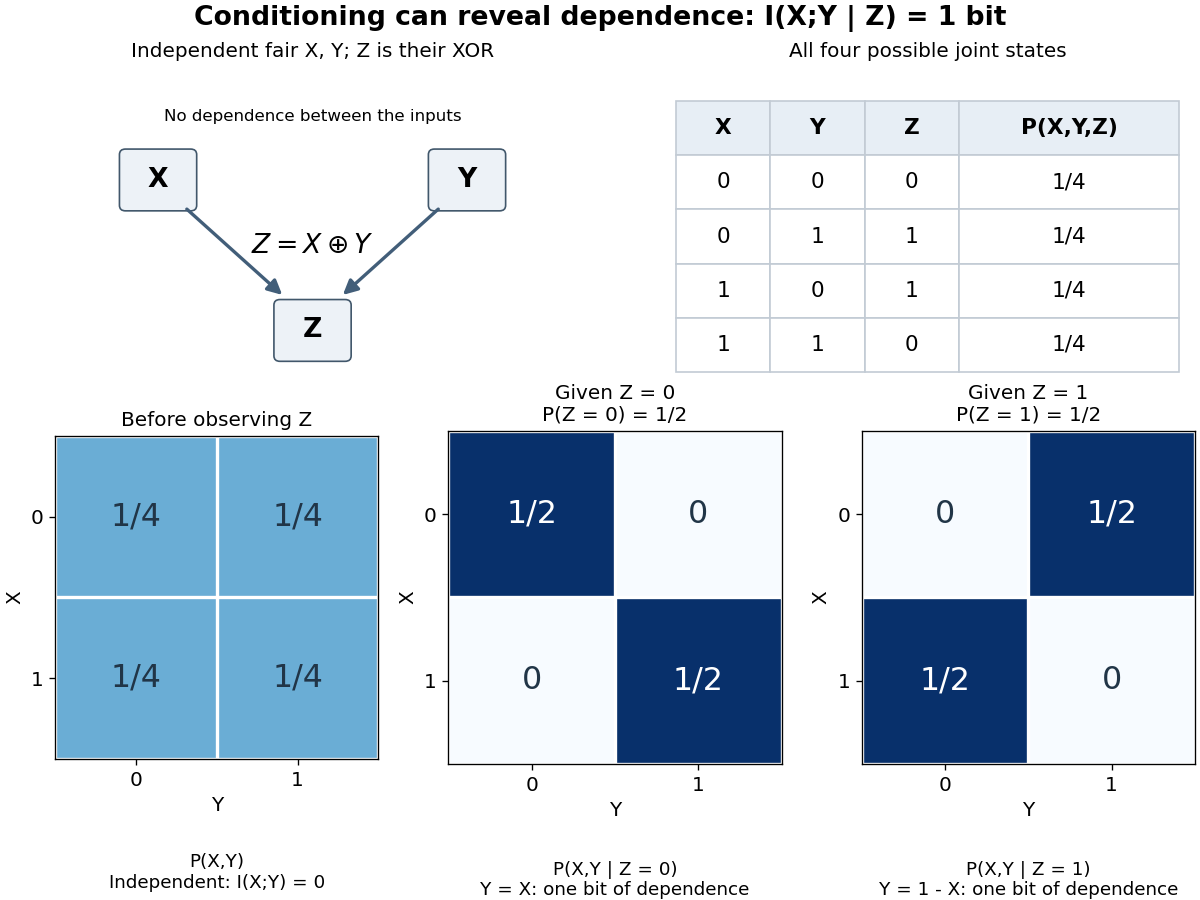
This example distinguishes conditional independence from ordinary independence. It also disproves the claim that conditioning always reduces mutual information, despite conditioning reduces entropy. There is no general ordering between and : the example above increases it from zero to one, while taking and for a fair bit decreases it from one to zero. The chain rule for mutual information explains why both are possible.[ref]
Conditional mutual information is useful for asking whether an additional observation tells us anything after information already available has been accounted for. Its zero case expresses conditional independence exactly; in a Markov chain, this is the step that turns the chain rule for mutual information into the data processing inequality.
If outputs are conditionally independent given , then . Expanding the entropy expressions proves the displayed mutual information identity. The chain rule also gives , while the identity and nonnegativity give the upper bound by their sum. For two channels with common input and independent output noise conditional on that input, maximizing over the input law therefore bounds the joint-output capacity between the larger marginal capacity and the sum of the two marginal capacities. Their unconditional output dependence need not vanish: the subtracted measures information shared through the common input.
Suppose a fair input bit is independent of a publicly known channel-position label . At position , let the channel be a binary symmetric channel with error probability . Forgetting gives a binary symmetric channel with error . ThereforeThe chain rule for mutual information and show that their difference is the nonnegative conditional mutual information . Equivalently, the inequality follows from concavity of binary entropy. For with equal position weights, the known-position value is bits and the pooled value is bits. These quantities answer different statistical questions.
For finite discrete random variables, the mutual information supplied by two observations equals the information supplied by the first plus the additional conditional mutual information supplied by the second:The order changes the individual contributions but leaves the total unchanged.[ref]
https://web.stanford.edu/class/ee376a/files/lecture_3.pdf. Stanford EE376A/STATS376A, Lecture 3, Definition 7 and equations (48)–(51)
To prove the first identity, add and subtract the intermediate conditional entropy:With base-two logarithms, all contributions are in bits. Repeatedly inserting intermediate conditional entropies makes them cancel, as in a telescoping series, and gives the rule for any finite list of observations:where the term is . The same calculation with already known gives .For the fair-bit exclusive or example in conditional mutual information, observing alone tells nothing about , but observing after tells everything:Here by independence and because . In the reverse order, , so and : the two observations are individually uninformative but jointly reveal one bit. Simply adding their separate mutual informations would miss all of it.
The chain rule is useful for measuring the value of each new observation without double counting information already supplied. It also guarantees by nonnegativity of conditional mutual information. Keeping and adding can help, even though discarding and retaining only a processed is constrained by the data processing inequality. Equating the two observation orders gives the precise identitywhich explains why there is no general rule that conditioning decreases mutual information.
For finite discrete random variables, suppose is a Markov chain: the final channel uses only , so and have conditional independence given . In terms of the joint probability mass function,and hence . Then the two data processing inequalities areAll mutual informations here use base-two logarithms. Thus deterministic or randomized processing cannot increase the information shared with an unprocessed variable.[ref]
https://web.stanford.edu/class/cs229t/scribe_notes/12_05_final.pdf. Stanford CS229T/STATS231, Theorem 2.1 and its chain-rule proof
For a concrete cascade, take a fair bit and Bernoulli random variables with probabilities , of being one. Assume are jointly independent random variables, and pass through two binary symmetric channels:The second noise is independent of both and , so this is a Markov chain. Both and are fair bits. The net exclusive or error is one exactly when one noise flips the bit and the other does not:Using the binary entropy , the three mutual informations are fully determined:All numbers are in bits. The two losses are and . Thus the cascade retains less information about the original source than either individual channel shares between its own input and output.
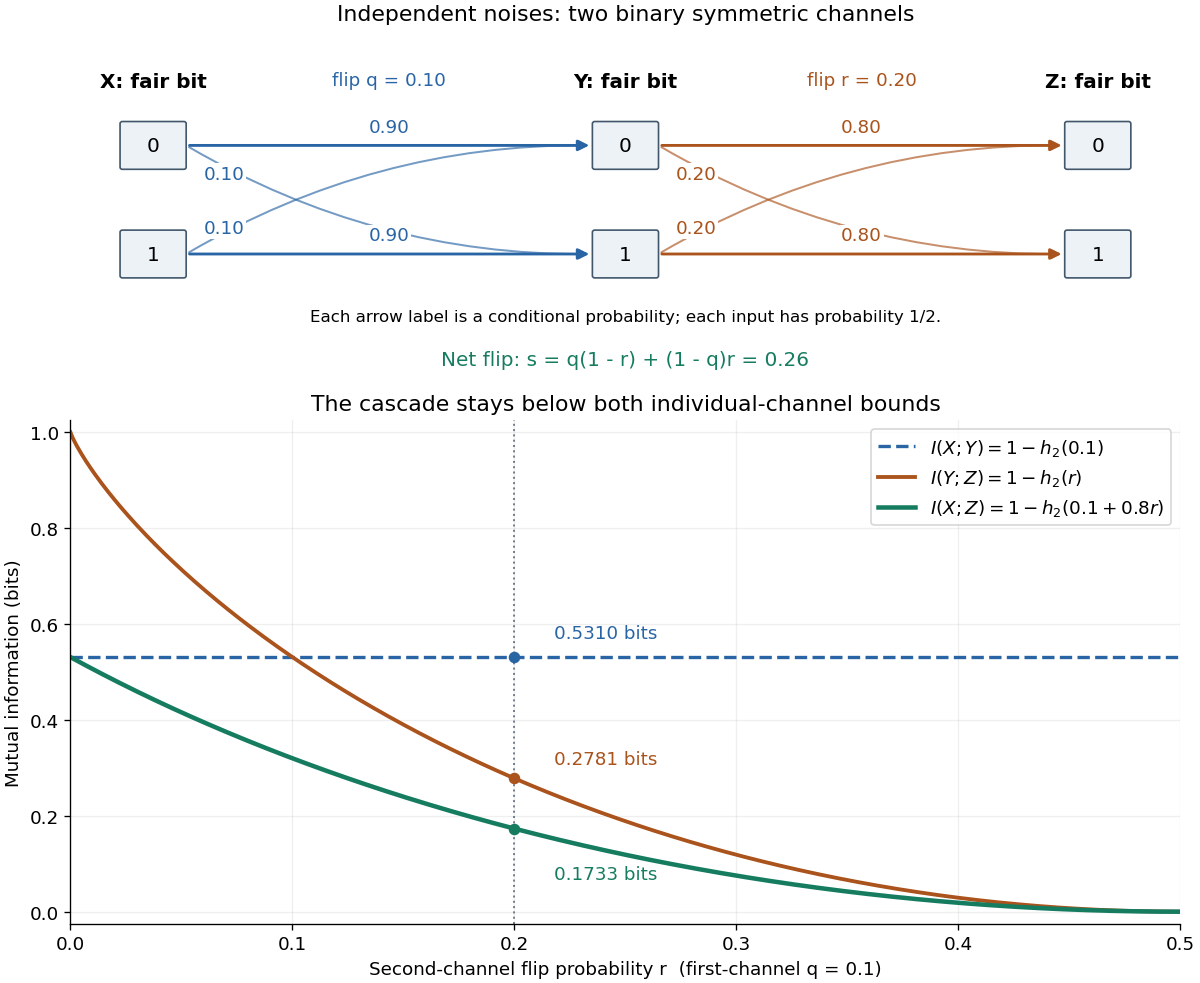
With fixed and , the effective error is . At , and ; at , is independent of the previous variables and . The diagram plots these endpoints and the computed example.
The data processing inequality is useful for testing what a proposed decoder or data summary could possibly reveal: if its only input is , even randomized processing cannot provide more mutual information about than already contains. The Markov chain hypothesis matters. In the exclusive or example from conditional mutual information, allowing a processor to use both and reveals exactly; that processor has additional input, so the conclusion for processing alone does not apply.
The chain rule for mutual information proves both inequalities and identifies their exact gaps. First expand the information about in the two observation orders:Therefore . Next use as the variable being learned:Symmetry of mutual information gives . Both signs follow from the nonnegativity of conditional mutual information; the first gap also gives equality in data processing inequality.
Under the finite Markov chain hypothesis , the gap identity in the data processing inequality givesBy the zero criterion for conditional mutual information, equality means that and have conditional independence given . After seeing the processed output, the original observation provides no additional information about . Similarly, equality in the other bound, , holds exactly when .
Equality does not require retaining every detail of . Let be independent fair bits, put , and let the processed output be , the first coordinate of . This is a Markov chain, andAlso . The output discards the entire unrelated bit , reducing to , while preserving all mutual information about . This is what makes equality useful for choosing a compact observation that retains all information about the quantity of interest.
If is a Markov chain conditionally on , thenIt follows by applying ordinary data processing inside every conditional distribution and averaging over .
Send a uniform bit twice through independent binary symmetric channels of crossover probability . The first received bit supplies bits. Since the received bits disagree with probability , the additional information in the second bit is
Articles by others on the same topic



Mutual information is a fundamental concept in information theory that measures the degree of dependence or association between two random variables. It quantifies the amount of information obtained about one random variable through the other. In essence, mutual information captures how much knowing one of the variables reduces uncertainty about the other.