A function on a convex set is a convex function if, for every and ,Geometrically, a line segment joining two points of its graph of a function lies on or above that graph of a function. The convex set condition ensures that the intermediate input stays in the domain of a function. An affine function satisfies the defining inequality with equality.
For the quadratic function , the inputs and have equally weighted arithmetic mean . Evaluating at the arithmetic mean gives , whereas averaging the outputs gives . Averaging first saves one unit in this example. More generally, direct expansion givesThis identity proves convexity and also shows exactly when its defining inequality is strict.
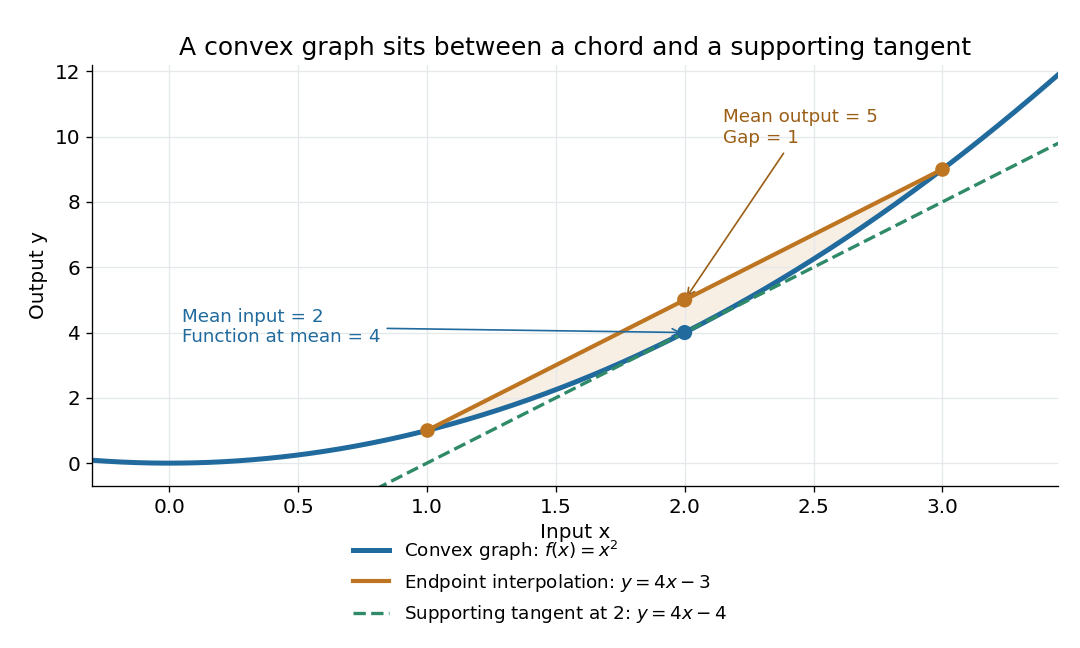
The graph of a convex quadratic lies below its endpoint interpolation and above its supporting tangent
. For , the line segment through and has height at , while the graph of a function has height . The tangent line is an affine minorant: everywhere. Details.For a differentiable convex function, the tangent line in one dimension, or the corresponding supporting affine function in several dimensions, lies below the entire graph of a function. This is the subgradient inequality. The equivalent geometric statement is that the epigraph, consisting of points on or above the graph of a function, is a convex set. These characterizations are developed in Boyd and Vandenberghe's convex-function slides, sections 3.1–3.4.
Convexity does not require differentiability: the absolute value function is a convex function with a corner at . When a function is twice continuously differentiable on an open interval, it is a convex function exactly when its second derivative is nonnegative throughout that interval. In several dimensions, the corresponding criterion on an open convex set is that its Hessian matrix is positive semidefinite everywhere. The domain of a function matters: is a convex function on , but not on all of . A strictly positive second derivative is sufficient for strict convexity, but is not necessary: is a strictly convex function although its second derivative vanishes at .
The usefulness of convexity is that local information can certify a global conclusion. Every local minimum of a convex function on a convex set is a global minimum: if a lower value existed elsewhere, the defining inequality would produce lower values arbitrarily close to the proposed local minimum. For a differentiable convex function on an open convex set, a zero gradient therefore certifies a global minimum. Strict convexity gives uniqueness when a global minimum exists; it does not supply existence by itself. These facts explain the role of convex functions in convex optimization.
For a differentiable real function , a point of convexity is a point whose tangent line lies below the entire graph. The function need not be convex at other points. The Weierstrass excess function is exactly the difference between the function and this tangent line when applied to a variational integrand as a function of slope.
On an open convex set, a twice-differentiable real-valued function is convex if and only if its Hessian matrix is a positive semidefinite matrix at every point. In particular continuous second partial derivatives suffice for the differentiability hypothesis. Restrict to any line segment: has . The second-derivative criterion for convexity proves both implications, because convexity is equivalent to convexity of all such restrictions.
A twice-differentiable real-valued function on an open interval is convex if and only if its second derivative is nonnegative everywhere. If , the mean value theorem makes nondecreasing, which implies the supporting-line and chord inequalities for convexity. Conversely, the slopes of a convex function are ordered; where the second derivative exists, this gives . Strict positivity of is sufficient for strict convexity, but is not necessary: is strictly convex despite .
The affine functions and are both convex functions on , but their product is . Its value at zero exceeds the average of its values at and , contradicting convexity. Thus closure under nonnegative linear combinations does not imply closure under products.
For a differentiable real-valued function on an open convex set, convexity is equivalent to the displayed inequality for all in its domain. To prove the forward direction, convexity gives for . Take the limit as using first-order Taylor expansion.
Conversely, put and apply the supporting inequality at to both and . Multiply the two inequalities by and and add them. The gradient terms cancel because , leaving . This is the defining convexity inequality. The endpoint values hold as equalities.
Let be a finite convex function on a neighbourhood of , and suppose its first partial derivatives exist at . For any fixed vector , convexity givesThe equality uses the one-dimensional first-order Taylor expansion along each coordinate line; no continuity of second partial derivatives is assumed. Applying this upper bound to and using gives the matching lower bound. Hence the displayed directional expansion holds. This supplies the expansion used in the supporting inequality for a differentiable convex function even when continuous second partial derivatives have not been postulated.
For a continuous convex function on , where , its integral average lies between its midpoint value and the average of its endpoint values. For a concave function both inequalities reverse. The bound involving endpoints follows by comparison with the affine function joining them and monotonicity of the Riemann integral. The midpoint bound follows from the Jensen inequality on equal-weight midpoint tags and the Riemann sum convergence theorem.
A functional on a real vector space is convex when it is a convex function: for . For a symmetric nonnegative bilinear form and a linear functional , the quadratic functional is convex, since its convexity difference is .
The greatest convex function lying below a given function, when such an envelope is considered in the specified domain. A convex combination of phase compositions and their Gibbs free energies constructs candidate mixtures; the equilibrium free energy is their lower convex envelope. For two differentiable coexisting branches, the supporting line is a common tangent.
For a finite real convex function on an entire real vector space, apply the convex domination form of the Hahn-Banach theorem to and the zero functional on . It supplies a linear functional dominated by this translated function. The affine function lies below everywhere and equals it at . Taking the supremum proves the formula. These are algebraic affine minorants; continuity requires additional topological hypotheses.
An extended-real convex function is essentially smooth if its effective domain has nonempty interior, it is differentiable throughout that interior, and whenever interior points converge to a finite boundary point of the domain. A differentiable convex function finite on all of satisfies the boundary condition vacuously. The cumulant-generating function on has derivative and is essentially smooth. Restricting its domain to destroys this property. This distinction matters in the lower bounds of the Gärtner–Ellis theorem.
A convex quadratic function on has the form with a symmetric positive semidefinite matrix . Its Hessian is , and , proving convexity directly. A stationary point is a global minimum. On a compact polytope, a minimum either is stationary in the interior or minimizes a restriction to a boundary face.
Let a real convex function satisfy on the open unit ball of a normed space. For , points satisfy . Extend the segment from through to length ; its endpoint still lies in the domain, and convexity bounds the difference by . Reverse for the opposite inequality. Unlike finite-dimensional local continuity theorems, this argument applies in arbitrary dimension because boundedness on a full neighborhood is assumed.
For a finite convex function , its negative part is globally Lipschitz continuous. The negative sublevel set is an interval. If bounded, local Lipschitz continuity of finite convex functions bounds the slopes on its closure. If it is a left ray, any negative slope there would force positive far to the left by the supporting-line inequality; all slopes on that ray are therefore nonnegative and bounded above near its finite endpoint. For a right ray the analogous slopes are nonpositive and bounded below. If is negative everywhere, convexity and boundedness above force it to be constant. These cases bound the slopes of globally, including its zero extension outside the interval. In particular, integrability of implies integrability of the negative part of every fixed translate .
An affine minorant of is a function that is everywhere at most . Every proper lower-semicontinuous convex function has such a minorant, by separating a point below its closed epigraph. Adding a positive quadratic then yields a coercive function, which establishes existence in proximal minimization.
A proper convex function is both a convex function and a proper extended-real function. For example, the total variation seminorm on a domain is nonnegative, finite at zero, and a supremum of linear functionals, making it proper and convex.
A real function on an interval is operator convex whenin the Loewner order for all Hermitian operators with spectra in and every .
A function is operator concave when its negative is operator convex. Equivalently, the defining operator-convexity inequality is reversed.
A finite convex function on an open convex subset of a finite-dimensional real vector space is locally Lipschitz, and therefore continuous. In one dimension this follows by bounding its secant slopes between two slightly wider endpoints.
For a real number , its absolute value is when and otherwise; for a complex number , it is the nonnegative magnitude .
Suppose a real function is differentiable at , with and . The derivative definition gives . The reverse triangle inequality then impliesThus has unequal one-sided derivatives, on the right and on the left. More generally, multiplication by a function continuous at with gives right and left slopes and . This elementary expansion explains how a smooth oscillation can acquire infinitely many corners under the absolute value function, even after multiplication by a factor that makes it differentiable at an accumulation point.
Let the locations be distinct and bounded, and let with . The Weierstrass M-test gives locally uniform convergence of , so the uniform limit theorem makes it continuous. The reverse triangle inequality bounds each term's difference quotient by . Consequently a uniformly small tail permits passing each one-sided difference-quotient limit through the series. At every point outside the locations, ; at , the right derivative minus the left derivative is . Thus the function has precisely the prescribed cusp locations, even when they accumulate at another point where the function remains differentiable.
For a differentiable strongly convex function with modulus and global minimizer , the supporting inequality givesCompleting the square shows that the last two terms are at least , which proves the result. Combining this with the descent lemma converts squared gradient decrease into a contraction of the objective function gap.
Target: mathematical-optimization.bigb, under Line search.A gradient integrand is uniformly convex in this elliptic variational sense when its Hessian matrix in the gradient variables has a common positive lower bound. Then . Averaging along a line segment in gradient space preserves the same lower bound.
For scalar minimizers of with and globally bounded uniformly positive Hessian matrix, no higher differentiability of is needed for interior gradient Hölder continuity. The weak Euler-Lagrange equation is . Difference quotients solve uniformly elliptic equations with coefficient matrices obtained by averaging along gradient segments. The Caccioppoli inequality and difference quotient characterization give . The Sobolev chain rule then gives . The De Giorgi-Nash-Moser theorem makes each derivative Hölder continuous, with exponent depending only on dimension and the ellipticity ratio. This scalar conclusion should not be assumed for vector-valued elliptic systems.
On a bounded domain, classical solutions continuous on the closure have difference satisfying , where . The coefficients are uniformly elliptic and locally smooth. Apply the weak maximum principle on inner domains whose closures lie in the original domain, then let their boundary distances tend to zero. The common continuous boundary values make their boundary differences tend uniformly to zero, proving uniqueness without assuming global bounds on derivatives of the linearized coefficients.
A strictly convex function has at most one minimizer: if distinct points attained the same minimum, every strict convex combination of them would have a smaller value.
The Hessian matrix ofis positive semidefinite exactly whenThis region is convex: for it is the epigraph of in the positive quadrant, and for it is the closed first quadrant.
A real convex function locally bounded on an open convex set has a continuous supporting linear functional at every interior point. Apply the dominated Hahn-Banach theorem to its sublinear directional derivative to obtain . Increasing secant slopes imply whenever the endpoint is in the domain. A local Lipschitz continuity bound gives both and , proving continuity.
A proper convex function is minimized at exactly when . For a differentiable convex term and another convex term , the subdifferential sum rule gives the condition .
The absolute value function has
Jensen's inequality says that applying a convex function to a weighted mean cannot exceed the same weighted mean of its outputs. For nonnegative weights with and inputs in a convex set,Nonnegative weights are essential: this is a convex combination, rather than an arbitrary affine combination. For two inputs it is precisely the defining inequality for a convex function; repeatedly grouping inputs gives the finite weighted version.
Take , weights and , and inputs and . Their weighted mean is , so the two sides areThe Jensen gap is . The inequality measures the effect of replacing distinct inputs by one representative input before applying a nonlinear function.
The probabilistic form uses an integrable random variable taking values in an interval where is a convex function. If is also an integrable random variable and belongs to that interval, thenThe direction reverses for a concave function. For a strictly convex function, equality in the finite weighted form requires all inputs having positive weight to be equal; in the probabilistic form it requires to be constant almost surely. An affine function gives equality for any admissible distribution. [ref]
https://stanford.edu/~boyd/cvxbook/bv_cvxslides.pdf. Boyd and Vandenberghe's slides, section 3.14, state the expectation form
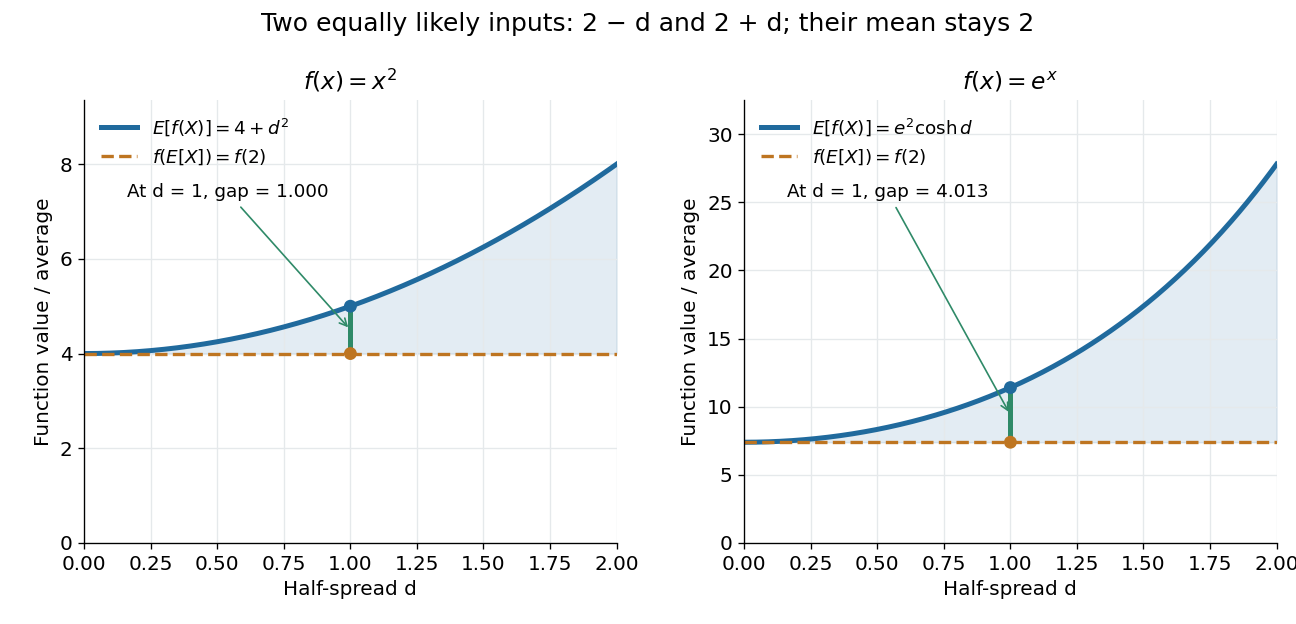
.For the quadratic function and a random variable with a finite second moment, the difference between the two sides is exactly its variance:Consider two equally likely values and . Their expected value stays at as increases, but their variance is . Thus the expected value of the square grows from to . For the exponential function, the same two-point distribution gives , while . Both are examples of Jensen's inequality, but their Jensen gaps depend differently on the spread of the inputs.
Another useful choice is the concave function on positive inputs. Its version of Jensen's inequality gives . Applying the increasing exponential function shows that the weighted geometric mean cannot exceed the weighted arithmetic mean. For the equally weighted inputs and , these are and . This recovers the arithmetic-geometric mean inequality and illustrates how choosing one function can generate an entire family of bounds.
A short proof idea explains the probabilistic form. If has a subgradient at , the supporting affine function gives . Taking the expected value cancels the linear term because . This argument applies, for example, to finite convex functions on ; more general domains of a function need attention to endpoints and the existence of a subgradient.
Johan Jensen's 1906 paper “Sur les fonctions convexes et les inégalités entre les valeurs moyennes” is an early source for the connection between convex functions and inequalities for means. [ref]
https://zenodo.org/records/2371297. Jensen's original article and publication record, DOI 10.1007/BF02418571
.Let be an integrable random variable taking values in an open interval . Suppose is a differentiable strictly convex function. Then its expected value has equality in Jensen's inequality exactly when is constant almost surely.
First lies in : at each finite endpoint, taking the expected value of the strictly positive distance to that endpoint gives a strictly positive distance for . A tangent affine function supports at , soStrict convexity forces for . Indeed, equality at another point would force the graph to coincide with its supporting line on the connecting line segment, contradicting strict convexity. Thereforeand the right side is zero exactly when almost surely.
The tangent affine function of is an integrable random variable, so has an integrable negative part. Thus is well defined, possibly , even if absolute integrability was not assumed. Equality to automatically excludes that infinite case.
The Jensen gap is the nonnegative difference in Jensen's inequality, under its integrability assumptions. It quantifies how much applying a convex function before averaging differs from applying it afterward. For it is the variance of ; for an affine function it is zero. For general convex functions, it depends on both the function and the distribution of , and is not determined by the variance alone.
Apply Jensen's inequality to the two equally weighted values and the convex function . Equality for proves that is the smallest possible constant. For , strict convexity makes equality equivalent to ; for , equality holds for every pair.


