Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
The density power spectrum records the squared Fourier-mode amplitude, up to the chosen statistical normalization. Scale dependence acquired from primordial amplitudes and subsequent growth determines its spectral shape.
In a spatially flat universe containing separately conserved pressureless matter and a coasting fluid with , the ratio is proportional to the scale factor. If the coasting component is modeled by the barotropic fluid perturbation equations with no anisotropic stress, its contribution to the trace gravitational source vanishes because . The matter growing mode isA decaying solution is . The reduction of order formula with integrating factor produces the integral solution. It has during matter domination and tends to during coasting-fluid domination. Thus growth freezes rather than continuing in proportion to the scale factor. The background geometry is flat despite the same background expansion law as an open dust universe.
Expansion-weighted derivative of a passive density perturbation by  Codex 0 Created 2026-10-14 Updated 2026-10-20
When the self-gravity source in the pressureless linear cosmological density perturbation equation is negligible, . Multiplication by makes it , so . This explains how Hubble friction changes growth for an arbitrary positive scale factor. For , the nonconstant mode is when and when .
The orbital overlap of normalized real atomic orbitals is their inner product . It is a dimensionless measure of their common amplitude, not an electron count. For the Gaussian function toy, increasing from to reduces from to . As tends to zero, both LCAO normalization denominators tend to .
An axis-angle representation specifies a rotation of three-dimensional Euclidean space by an oriented unit axis and an angle. The axis is fixed, and the perpendicular plane undergoes a pure rotation, with no dilation.
The permanent of a matrix adds the products obtained by choosing one entry in each row and one in each column. For an matrix with entries in the real numbers or complex numbers,Here each permutation chooses column in row , and the symmetric group lists every such bijection. The formula resembles the Leibniz formula for determinants, but omits the sign of a permutation. For a two-by-two matrix,The absence of alternating signs makes the permanent of a matrix particularly useful for counting allowed assignments.
For a zero-one matrix, let rows represent people, columns represent jobs, and mean that person can do job . This is the biadjacency matrix of a bipartite graph. A product in the permanent is one exactly when all the selected assignments are allowed; otherwise it is zero. Each surviving permutation assigns every person a different job, which is a perfect matching. Thus the permanent counts perfect matchings. This interpretation and the definition are given in Yufei Zhao, Probabilistic Methods in Combinatorics, §10.2, pp. 178–179.
For a fully enumerated example, takeAmong the six permutations of three columns, exactly three give nonzero products: , and . These tuples list the chosen column in each successive row. Each product is one, so . Their permutation signs are , giving . The diagram displays all three allowed assignments.
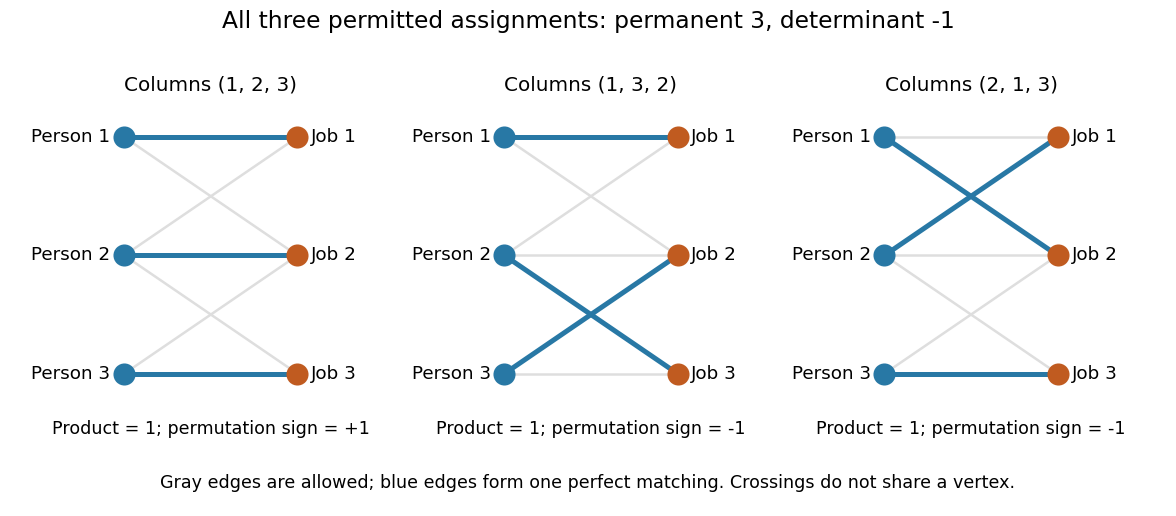
Three allowed one-to-one assignments contribute positively to the permanent, while their permutation signs give a determinant of minus one
. Details. A zero determinant need not mean that no assignment exists. The two-by-two all-ones matrix has permanent and determinant : its two assignments cancel in the determinant. The nonzero determinant criterion for a perfect matching is sufficient for existence, but the converse fails for a fixed zero-one matrix.
For nonnegative entries, the permanent instead sums assignment weights, with each assignment weighted by the product of its selected entries. It is then a total weight rather than necessarily an integer count. With arbitrary entries in the real numbers or complex numbers, even the permanent can have cancellation; the counting interpretation specifically uses zero-one entries. The permanent as probability of distinct independent choices gives another useful nonnegative interpretation.
There are terms in the defining sum, linking direct evaluation to the factorial. For the all-ones matrix, every term is one and the permanent is exactly ; the identity matrix has permanent one. Finding one allowed assignment and counting all allowed assignments are different questions. Their relationship to computational complexity theory was studied in L. G. Valiant, The complexity of computing the permanent, Theoretical Computer Science 8(2), 189–201, 1979. The elementary sum is useful for small examples, while the existing dense permanent approximation describes a more specialized way of estimating large counts.
A rank-one matrix update changes a matrix by an outer product . For real vectors , its action on an input vector isThe dot product reads one scalar from the input, and the correction moves the output along . All correction outputs therefore lie in one linear span. If either vector is zero, the update is zero; otherwise the correction is a rank-one matrix. The full updated matrix need not have rank one.
For example, chooseThe update sends to the correction . Although all four entries change, there is only one direction of correction. Adding it to the identity matrix gives .
This special structure allows existing work to be reused. The matrix determinant lemma updates the determinant using one scalar, and the Sherman–Morrison formula updates the matrix inverse using an outer product. Such formulas are useful when a linear system changes slightly after a new observation or a parameter adjustment: the unchanged part can retain its LU decomposition. The term rank-one describes the rank of the correction, not the size of the entry changes. [ref]
https://ocw.mit.edu/courses/18-065-matrix-methods-in-data-analysis-signal-processing-and-machine-learning-spring-2018/988b4c05680f40a5a4b3be7004a32500_XhSk_Lw2X_U.pdf. Gilbert Strang, MIT 18.065, Lecture 14: Low Rank Changes in A and Its Inverse
.A low-rank approximation replaces an matrix by a matrix of matrix rank at most a chosen integer , with , while making an explicitly chosen error norm small. The point is to describe many entries using a few shared patterns: an image compression may retain broad brightness patterns while discarding finer ones. The approximation is useful when the saved storage or computation justifies the lost detail. A small matrix rank alone says nothing about the error.
The compact representation is a sum of outer products, equivalently a product of two thin matrices:Here are the columns of , and the star denotes the conjugate transpose; over the real numbers use the transpose. The rank bound for a matrix product gives . Conversely, choose a basis of the column space of as the columns of , and put the coordinates of each column of into ; pad with zero columns if the matrix rank is smaller than . Each nonzero outer product is a rank-one matrix: it repeats a single column pattern at different strengths across the columns.
Keeping the two factors stores scalars instead of . This saves space only when . The usual singular value decomposition representation stores scalars because it keeps the singular values separately; absorbing them into one factor removes that extra array. These are representation sizes at equal scalar precision, before file overhead. See Uschmajew and Vandereycken, §9.2: thin factors and their storage, and Illinois CS 357, Low-rank approximation: storing singular vectors and values.
The factors also give without forming the full matrix . Direct evaluation uses scalar multiplications, compared with for a dense matrix applied to a vector. For , the two factors contain scalars rather than , and the same counts describe these multiplication costs. Constructing the factors is a separate cost. Moreover, a low-rank approximation need not be a sparse matrix: the constant matrix whose entries are all has matrix rank despite having no zero entries.
For the standard unweighted problem, write a singular value decomposition with and singular values . Retain the first paired left singular vectors and right singular vectors:The Eckart-Young-Mirsky theorem says that this same minimizes both of the following error norms over all matrices with matrix rank at most :where and an empty sum is zero. Here the Frobenius norm is , whereas the operator norm is specifically induced by the Euclidean norm, . The first aggregates errors in all entries; the second bounds the worst output error for a unit vector input. These formulas apply to real and complex matrices. [ref]
https://math.uchicago.edu/~may/REU2016/REUPapers/Mazeika.pdf. Mazeika, §§4.1 and 4.3: norms and optimal singular-value truncation
For , a relative Frobenius norm tolerance is met precisely when the discarded squared singular values sum to at most . Thus one can choose the smallest suitable before reconstructing the matrix. Many individually small discarded singular values can still have a large combined error. An operator norm tolerance instead tests only the largest discarded singular value, . The two questions can therefore select different ranks.
The following stipulated matrix makes the tradeoff visible. Define four real vectors of length :The vectors are orthonormal, so this is already a singular value decomposition written as outer products, with positive singular values . All entries lie between and and can be displayed as brightnesses. The first component is uniform brightness, the second distinguishes broad blocks, and the last two supply finer alternating patterns. This is a designed arithmetic example, not measured image data.
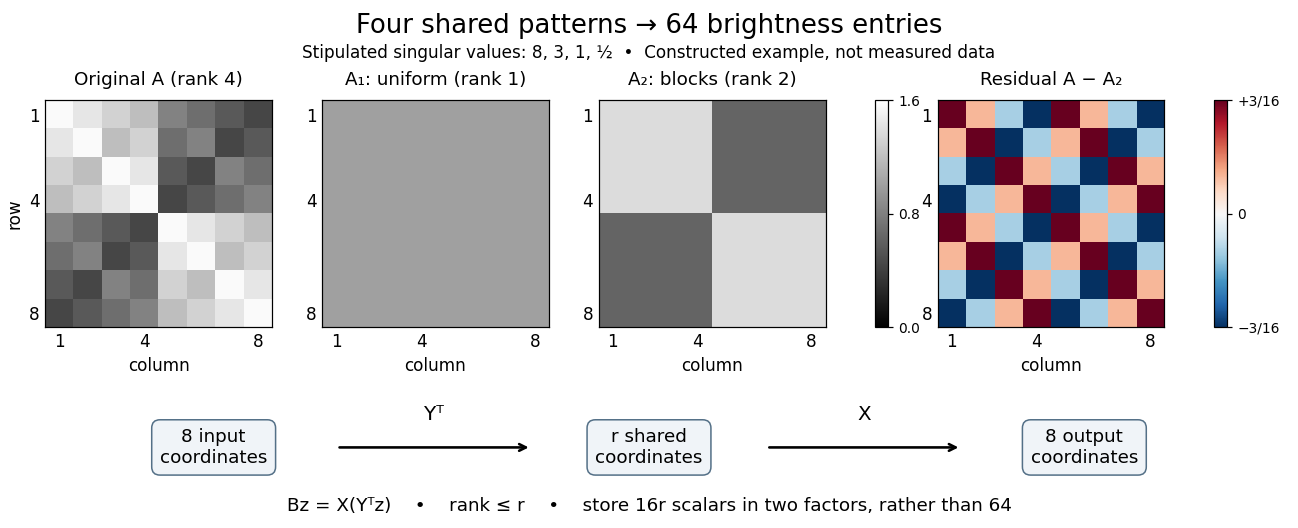
Here has every entry equal to , while has entries within the two diagonal blocks and in the other two blocks. For instance, becomes : its error is . The full residual is , whose Frobenius norm is and whose operator norm is . Since , the relative Frobenius norm error is . Two thin factors use scalars, or if the normalized left singular vectors, right singular vectors, and singular values are stored separately, instead of dense entries.
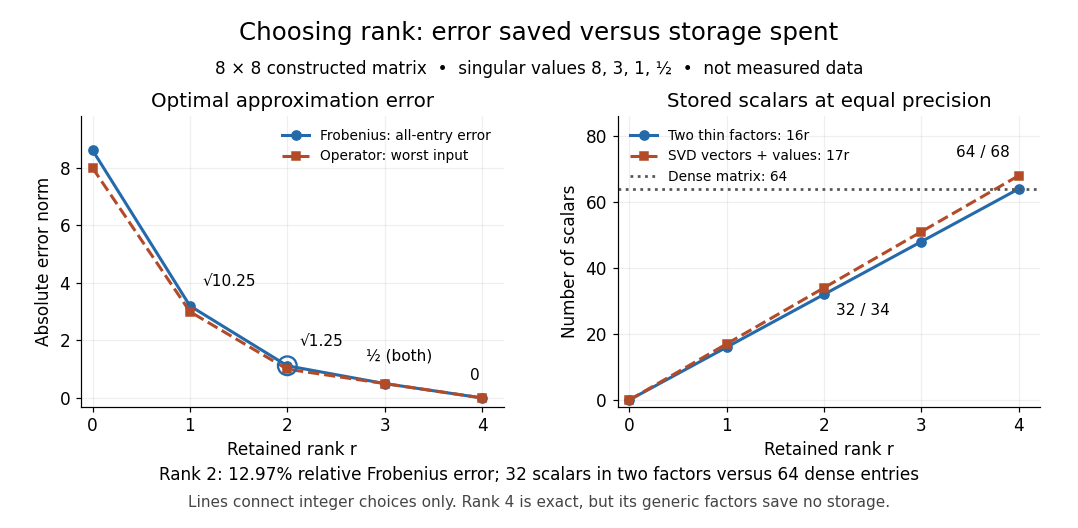
Retaining three components reduces the Frobenius norm error to while using scalars in two factors. Retaining all four reconstructs exactly but uses scalars, giving no saving in this generic representation; keeping the singular values separately uses . Our particular sign patterns could be encoded more economically, but that would exploit an additional structure beyond the general low-rank approximation. The striking feature is that numerical error and storage can both be read from the decomposition, rather than judged only by how smooth the picture looks.
The constraint is deliberately matrix rank at most . The truncation has . If , the best approximation is itself, with zero error. Requiring matrix rank exactly can destroy attainment: for and , the matrices have matrix rank for , and both error norms equal . Their error has infimum zero, but no rank-two matrix attains it. If , the displayed does have matrix rank exactly and attains the same minimum under either constraint.
Optimality also does not always mean uniqueness. For , the best Frobenius norm approximation is unique when . [ref]
https://link.springer.com/chapter/10.1007/978-3-030-31351-7_9. Uschmajew and Vandereycken, Theorem 9.1: uniqueness across a singular-value gap
A positive tie across the cutoff permits different choices: for and , both and have Frobenius norm error and operator norm error . More generally, is optimal for every real unit vector in the first two coordinate directions. Rotating which tied direction is kept changes the approximation. Repeated singular values entirely inside the retained group do not change its sum of outer products. At the only feasible matrix is zero; at the unique zero-error approximation is , even if some singular values are tied at zero.A strict gap does not guarantee uniqueness for the operator norm. For and , every with has matrix rank and error , which is optimal. Only minimizes the Frobenius norm, since . An unchanged worst direction can hide extra error in another direction under the operator norm.
Finally, these guarantees concern the stated norms and the sole matrix rank constraint. They do not establish that a discarded pattern is noise or irrelevant to a particular task: the finer patterns in our constructed example were put there intentionally. Adding entrywise weights or restrictions on the factors changes the problem, so the Eckart-Young-Mirsky theorem above does not automatically solve it. For historical context, the original 1936 matrix problem is documented in the existing Eckart-Young-Mirsky theorem section.
Two vectors spanning a hyperbolic plane. For an alternating bilinear form, choose ; then their span is nondegenerate. For a quadratic form with polar form , require also . The analogous definition for a Hermitian form uses two isotropic vectors of pairing one. Extending such pairs to adapted bases is useful for constructing form-preserving maps.
An aperture in a rigid plane with prescribed harmonic normal displacement radiates into a half-space. Superposing acoustic monopoles, each doubled by its same-sign rigid-wall image, gives the stated integral, where is the distance from aperture element to observer. In the acoustic far field, expanding to first order across the aperture identifies the angular radiation amplitude with the aperture's Fourier transform.
Linearizing inviscid barotropic flow about uniform rest gives , not automatically . Irrotational linear acoustics therefore requires zero initial vorticity or restriction to the longitudinal acoustic mode. A time-independent divergence-free field, with zero pressure and density perturbations, is a nonacoustic solution of the linearized equations.
Chlorophyll is a family of molecules that absorb light for photosynthesis. In chloroplasts, chlorophyll works with proteins in thylakoid membranes; absorbing light initiates energy capture rather than directly constructing a sugar. See OpenStax Biology 2e, 8.2: photosynthetic pigments.
Phase folding of a light curve maps timestamps onto a trial cycle of duration . Given a reference time , define the phase in cycles bywhere is the fractional part, using the floor function also for negative . Plot brightness against rather than ; measurements separated by an integer multiple of occupy the same phase. For a periodic function , this reveals the shared shape of many cycles. Folding changes coordinates; it neither averages samples nor chooses the correct by itself. Welsh et al.'s folded Kepler plot separates the exoplanet transit and orbital brightness modulation. [ref]
https://www.ucolick.org/~jfortney/papers/Welsh10.pdf. Welsh et al. (2010), figure 1
.The second figure uses a completely synthetic trapezoidal dip: days, day, and the same depth and four-hour duration as the first figure. Different colours identify four successive cycles. Correct folding superimposes the dips; a wrong trial orbital period spreads them out. If , the centre of the th repeated event shifts by approximately cycles when folded on , for . With days, the fourth plotted event is displaced by cycles. Transit-timing variations can also smear a constant-period fold, so retain the original timestamps and inspect individual events.
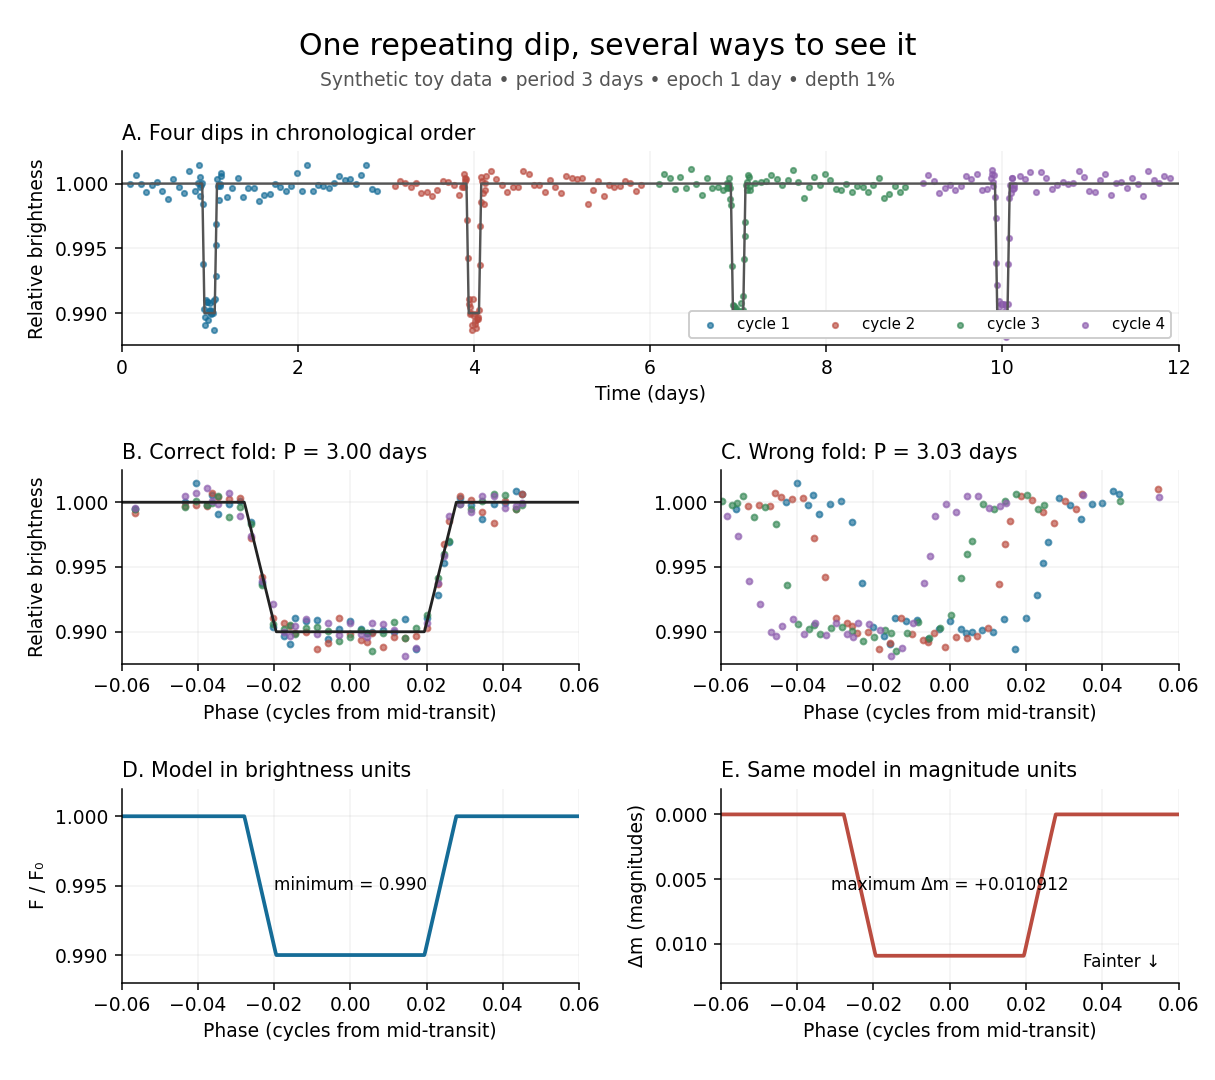
Toy phase folding: repeated synthetic dips align at the correct period; a flux dip becomes a positive magnitude change
. Details. One may combine nearby phases with a weighted mean, but the uncertainty reduction requires assumptions. For independent measurements with common standard deviation and effectively the same expected brightness within the bin, their arithmetic mean has standard deviation . Thus sixteen independent -precision samples give precision on that phase-bin mean. Shared calibration errors, changing starspots, and bins wide enough to mix ingress with out-of-transit brightness violate these assumptions. A folded plot can conceal changes between cycles. Gaussian process models can represent correlated variability and interpolate irregular samples, but their predictions and uncertainties depend on their assumed covariance function.
The bottom panels show the same model as relative brightness and as magnitude difference in one fixed photometric passband with a fixed magnitude zero point:A dip to gives magnitudes: fainter means a larger apparent magnitude. The figure places larger magnitude differences lower on the page so the two dip shapes are easy to compare; reversing that plotting convention does not change the formula. For and small , expansion of the logarithm gives . The exact transform is nonlinear: transforming an exposure's mean brightness is generally different from averaging its instantaneous apparent magnitudes. The ordinary logarithm cannot be applied to a nonpositive background-subtracted measurement; keep such measurements and their uncertainties in brightness units for an appropriate statistical model.
An exposure-averaged light curve models what a finite exposure measures. For a constant response during an exposure of duration , centred at , the expected mean brightness isThe integral has units of brightness times time; division restores the units of . Observed points fluctuate around this mean. A response that changes during the exposure must instead be included inside the integral, as in the first figure's known drift. Exposure duration and the interval between samples are distinct: there may be dead time or missing exposures.
A short dip can be blurred even with perfectly noiseless measurements. For a toy rectangular dip of fractional depth and duration , an exposure containing the whole dip has fractional depth : averaging hides part of its depth. A dip lasting ten minutes therefore appears only deep in a thirty-minute exposure. No interpolation recovers its shape from that single number without additional assumptions. Forward modelling should average the predicted light curve over each exposure before comparing it with the measurements. Kipping's analysis of exoplanet transit photometry demonstrates how ignoring this averaging biases inferred system parameters. [ref]
https://arxiv.org/abs/1004.3741. Kipping (2010), Binning is sinning
.Aperture photometry estimates brightness by summing calibrated detector pixels in an extraction region and subtracting the estimated background in that region. For equally weighted pixels, let be their total accumulated signal in electrons, the estimated background electrons per pixel over the same exposure, and the exposure duration. Then is a background-subtracted electron rate. Kepler applied aperture photometry to calibrated pixels with a fitted sky background. [ref].
This measurement trades source collection against background: enlarging the extraction region can retain more starlight but includes more sky brightness and neighbouring sources. Photon shot noise, read noise, and uncertainty in background subtraction contribute to its uncertainty. Dividing by a consistently measured reference rate gives a dimensionless light curve; it does not supply an absolute observed radiative flux. If contaminating light remains, the reference includes it and the inferred exoplanet transit depth suffers transit dilution.
In the first toy figure, the source's reference rate is electrons per second, the summed sky contribution is electrons per second, and a known multiplicative response is with in hours from mid-transit. The artificial exoplanet transit depth is , its total duration four hours, and its flat-bottom duration hours; the straight ingress and egress are a toy approximation, not an exact exoplanet transit photometry model. Each synthetic sample averages a -hour exposure and adds seeded normal distribution noise with relative standard deviation . Subtracting the known sky rate and dividing by the known response and reference rate recovers the dip. Real observations require estimating those corrections and carrying their uncertainty.
An optical pulse is a finite-duration envelope of light. A nearly monochromatic pulse has many carrier oscillations within its duration : in units with light speed one, its wavelength obeys . A slowly varying propagation-time map stretches the pulse duration by its derivative and divides the observed frequency by the same factor.
// Target: general-relativity.bigb
The pressure coefficient compares a local static pressure with a specified reference static pressure, using a fixed reference dynamic pressure:The reference mass density, speed, pressure and location must accompany a reported pressure coefficient. Keep the same throughout a surface distribution; replacing it by local gives a different quantity and fails at a stagnation point. The definition itself requires neither Bernoulli's principle nor inviscid flow, so measured pressure coefficients remain useful when those idealizations fail.
Positive means ; zero means equality; negative means . This sign does not specify the sign of absolute pressure. For stipulated absolute and , gives absolute: a deficit, not a negative absolute pressure. If equals atmospheric pressure, the numerator is gauge pressure; a wind tunnel's reference static pressure need not equal room atmospheric pressure. These are reference choices, not different physical pressures.
Under the same-height, constant-mass density , steady flow and inviscid flow hypotheses of the Bernoulli equation, and with the same Bernoulli invariant as the reference flow,The first equation immediately gives the second after subtracting and dividing by . Hence a lossless stagnation point has , gives , and gives . For a real stationary wall satisfying the no-slip boundary condition, the velocity is zero right at the wall; inserting that wall velocity in an inviscid flow formula would wrongly predict everywhere. A thin boundary layer approximation instead relates the wall pressure to the outer-flow pressure and uses the outer velocity where the Bernoulli equation applies.
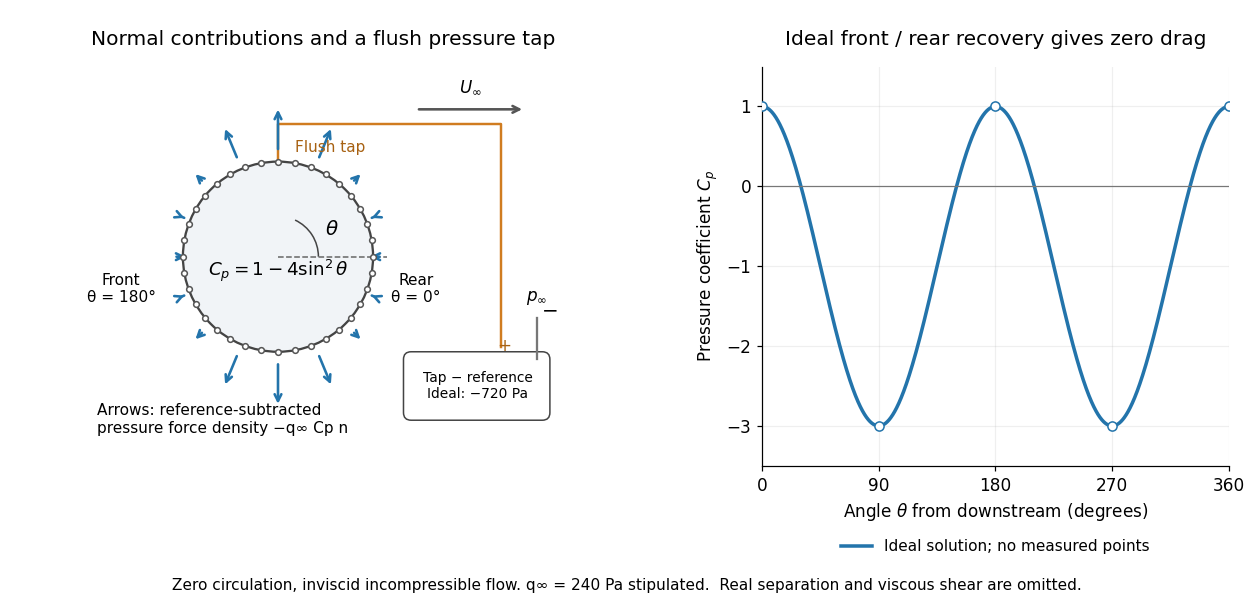
For potential flow around a circular cylinder of radius with zero circulation, the surface tangential velocity is . Thus the ideal pressure coefficient isWith measured from downstream, the front is at and the rear at zero. Both ideal stagnation points have , while the sides at and have . This exact model is a useful baseline for an experiment; its complete rearward pressure recovery is not a prediction for a separated real fluid wake.
To obtain a force, integrate the local normal contributions with their directions. Let be the unit normal vector from the body into the fluid and its closed wetted surface:The second equality removes a spatially constant reference pressure over the closed surface; it does not remove a nonuniform hydrostatic pressure or justify dropping the reference term on an isolated open patch. A negative contributes outwards in this reference-subtracted calculation, even though a positive absolute pressure still pushes inwards locally. Project onto the chosen lift and drag directions. The full fluid force also includes from the viscous stress tensor, including tangential shear stress; pressure tapping does not measure that contribution.
For the two-dimensional cylinder, force per unit span follows from per unit span and :Substituting gives : opposite points have identical pressure coefficients and opposite normal vectors. Zero drag despite a strongly nonuniform pressure is the instructive limitation associated with D'Alembert's paradox. Real viscosity, boundary layers and flow separation can prevent rearward pressure recovery and produce pressure drag. Thus the measured curve can test the model and estimate a pressure contribution without proving that total drag vanishes.
A motivating measurement is Virginia Tech's Experiment 3 - Flow Past a Circular Cylinder. Its open-jet wind tunnel holds a rotatable cylinder with end plates and 36 one-millimetre pressure tappings at ten-degree intervals. A reference Pitot-static tube supplies and to one digital manometer; a second connects a surface tap to its positive port and reference static pressure to its negative port. Record the simultaneous readings:The last equality uses the low-speed stopping relation, not an additional speed measurement. The manual requires sealed tubing and zero checks with the tunnel off. It also provides a water-column manometer: read each column's initial level, and subtract the independently measured reference-to-atmosphere pressure from the tap-to-atmosphere readings. Record tap positions after rotation. Compare the two instruments and check spanwise uniformity; end plates do not guarantee two-dimensional flow. [ref]
The inferential distinction matters: the manometers directly measure pressure differences, the ratio estimates pressure coefficients, and a surface integral estimates the pressure part of the force. Measure room absolute pressure and temperature if converting the reference difference to speed through the ideal gas law ; use thermodynamic temperature in that equation. For force reconstruction, cover the complete contour and use numerical integration with the tap geometry. Finite tap spacing, unknown end effects, probe disturbance and fluctuations limit that reconstruction; tubes and instruments also average or delay changing pressures. Retain the signed raw readings, repeated readings and reference readings so that these limits can be assessed. A small reference difference magnifies any zero error in the ratio, rather than producing a reliably large .
The signed lift divided by dynamic pressure times a stated reference area. For a two-dimensional airfoil, use instead. Reference area and experimental flow conditions are part of the definition of a reported coefficient; see lift for a worked scale and a pressure/balance experiment.
The octet rule is a useful empirical guide: many Lewis structures of chemical compounds containing carbon, nitrogen, and oxygen give each of those chemical atoms eight electrons when nonbonding electrons and all incident bonding electrons are counted. Hydrogen instead normally counts two electrons. These are local counts, not independent budgets: a shared bond pair counts at both endpoints but only once in the molecule's valence electron total.
In water, oxygen counts electrons; in Ammonia, nitrogen counts ; in , carbon counts and each oxygen counts . The charge-separated carbon dioxide drawing also satisfies the octet rule, so the octet rule alone cannot select the dominant contributor. Formal charge provides another check.
The octet rule is a heuristic rather than a theorem about every chemical bond. Odd valence electron totals cannot be partitioned entirely into electron pairs, and some valid Lewis structures have fewer or more than eight electrons around a chemical atom. See Chemistry 2e, 7.3: exceptions to the octet rule. The capacity of the and electron subshells, , helps motivate the guide for these chemical elements, but does not prove universal compliance. Lewis discussed a stable outer group of eight, together with a two-electron arrangement for hydrogen, in The Atom and the Molecule (1916), pp. 768 and 774.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact