A finite control equipped with an unbounded stack. A move reads one input symbol or the empty word, examines the top stack symbol, changes control state and replaces that top by a finite word over the stack alphabet. Nondeterministic choices give finitely many possible moves. With acceptance by final state and the entire input consumed, pushdown automata recognize exactly the context-free languages.
A pushdown automaton accepts a word if some finite run consumes all its input and reaches a designated final control state, regardless of the remaining stack contents. Reaching a final control state while leaving unread input is insufficient.
The control state , unread input word , and stack contents of a pushdown automaton. A fixed convention must say which end of is the top. With the top on the left, replacing top by changes into .
A formal language with finitely many words. Every finite language is a regular language: take a finite union of the regular expressions spelling its members, with the empty language represented separately when there are no members.
The shuffle of two formal languages consists of words whose positions can be partitioned into two subsequences, each preserving its order, with the two resulting words belonging to the respective languages. For regular languages, a product-state nondeterministic finite automaton advances exactly one coordinate for each letter. Common letters allow either choice; the powerset construction proves closure.
For a word and a formal language , the left quotient is the possible continuation language after the prefix . Two prefixes have the same left quotient exactly when they are Myhill-Nerode equivalent. For a regular language only finitely many distinct left quotients occur.
The padded convolution of words reads two finite words over an alphabet in parallel, extending the shorter with a fresh padding symbol until the longer ends. Its length is . Padding may only occur as a suffix, and a column is excluded. This encodes synchronous two-tape relations as formal languages over a finite paired alphabet.
A formal language is decidable if a Turing machine halts on every input and correctly determines membership. Equivalently its encoded words form a recursive set. A computably enumerable language requires only a machine that eventually accepts every member; it may run forever on nonmembers.
For a fixed natural number and a standard encoding of natural numbers, validate the input and compare its encoded value with . This decides . A well-ordering argument can prove that an upward-closed set of natural numbers has this form without calculating its least element. A decider may contain that fixed least element in its finite description; its existence does not give a uniform method to discover the least element from another program.
A word over an alphabet is a finite sequence of symbols from . The empty word has length zero, and denotes the set of all finite words.
A comparison of strings that disregards a chosen distinction between uppercase and lowercase characters. A simple convention compares characterwise lowercase forms. Full Unicode case folding is a distinct normalization operation and can change character counts.
The longest common prefix of two strings is the longest string that is a string prefix of both. Its length is the number of matching initial characters before the first mismatch or the end of a string. A direct scan maintains equality of the processed prefixes and takes time linear in that length plus one. For suffixes represented by indices in a shared array, no character copying is needed.
A string suffix consists of all characters from some position to the end of a string. For example, TAC has suffixes TAC, AC, C and the empty string. Sorting these in lexicographic order groups all suffixes beginning with a given query into one interval.
A cyclic rotation of a string is the string , where and are consecutive pieces. For example, rotating ABC left once gives BCA. A length- string has rotation positions, though repeated letters can make some resulting strings identical.
A substring is a contiguous segment of a string. It differs from a subsequence, whose selected characters need not be adjacent.
An infinite binary word is Sturmian if it has exactly distinct contiguous subwords of length for every positive integer .
A palindrome is a finite string equal to its reversal. For example, the strings and are palindromes.
Decide whether a finite string is a palindrome by comparing corresponding symbols from opposite ends. The test needs at most half as many symbol comparisons as the string length and can use constant auxiliary space.
Concatenation joins two strings end to end, retaining the order of their symbols. For example, joining and gives . It has the associative property: joining or gives the same word over an alphabet. The empty word is its identity element. All finite words over an alphabet with this binary operation form a free monoid.
The length of a word over an alphabet is the number of symbol positions in that finite string, counting repetitions. Thus and for the empty word. Concatenation satisfies . This differs from the word length of a group element, which minimizes over representing words using a chosen generating set of a group.
A run of a word over an alphabet is a maximal consecutive block of one repeated letter. For a nonempty word of length , its number of runs isReplacing a consecutive constant block changes this count only through its boundaries with the neighboring letters.
A border of a word is a nonempty prefix that is also a suffix. The full word is counted as a border; a shorter border records a way in which one occurrence can overlap the next.
A regular expression is built from alphabet symbols, the empty language and the empty word using finite union, concatenation and Kleene star.
The Kleene star of a language consists of every finite concatenation of words from , including the empty concatenation.
This theorem characterizes a regular language by regular expressions and acceptance by a finite-state automaton. Kleene's theorem states that a language is denoted by a regular expression exactly when it is accepted by a finite automaton.
A formation rule specifies how well-formed expressions can be constructed from simpler expressions in a formal language. The formal grammar of propositional formulas has rules for propositional variables, negation and binary logical implication.
A variable-based grammar has disjoint finite terminal and variable alphabets , a start variable , and productions in which and contains at least one variable.
A nonterminal is unreachable when no word derivable from the start symbol contains it. Productions whose left sides are unreachable do not affect the generated language.
A nonterminal is nonproductive when no word derived from it consists entirely of terminal symbols. Every derivation containing such a symbol therefore fails to produce a word in the generated language.
A right-linear regular grammar has productions of the forms and , where are variables and is a terminal word.
Every sentential form reachable from the start variable of a right-linear grammar is either a terminal word or , where is the unique variable and occurs at the right end.
If a finite right-linear grammar generates an infinite language, some variable is accessible, looping, and terminable. It is the repeated variable on a sufficiently long accepting derivation.
For grammars and with disjoint variable sets, introduce a new variable and setIf both input grammars are variable based, then .
Retain every production of whose right-hand side contains a variable, replace every production with by , include , and use as start variable. If and are right-linear, the resulting grammar is right-linear and generates .
The regular construction relies on a regular derivation having exactly one terminal rule, at its end. In a general variable-based grammar several variables may each use terminal productions, so replacing every such production can introduce several copies of the second start variable.
Even if both input grammars are regular, the added production has two variables on its right-hand side and therefore need not be a regular production.
A context-free language recognized by scanning a string over the alphabet from right to left, counting 0 as and 1 as , and requiring every partial count to remain nonnegative. A context-free grammar with a unique parse tree for each generated string is , . To see uniqueness, reverse the strings: every nonempty nonnegative path either never returns to zero after its first step, or has a unique first return. These two cases determine the production and its component substrings.
A context-free grammar consists of terminal and nonterminal alphabets, a start symbol, and productions whose left side is one nonterminal. A derivation records the order of substitutions, while a parse tree records their hierarchical structure, so several derivations can represent one parse tree.
Store the start nonterminal symbol on a stack. An epsilon transition nondeterministically replaces its top nonterminal symbol by a production rule right-hand side. A top terminal symbol can be removed only while consuming the same input symbol. With a protected stack bottom marker, enter a final control state when that marker is exposed. Requiring all input to have been read implements acceptance by final state. The stack records the unprocessed suffix of a leftmost derivation, proving equality of the recognized and generated formal languages.
A context-free grammar is ambiguous when some accepted token sequence has two distinct parse trees. Giving a language an unambiguous context-free grammar requires specifying grouping in the productions themselves, rather than relying on an unstated parser conflict rule.
An operation associated with a context-free grammar production, performed when that production is recognized. Semantic actions can construct an abstract syntax tree by combining the trees attached to its child nonterminal symbols.
A right-linear grammar has productions of the form or , where are nonterminals and is a terminal word, possibly empty. Each right-hand side has at most one nonterminal, at its right end. Such grammars generate exactly regular languages: regard nonterminals as states and expand each terminal word into a finite path to another state or an accepting endpoint. Conversely the transition graph of a deterministic finite automaton gives these productions directly.
A terminal symbol belongs to the alphabet of completed words and is not replaced by a grammar production.
A production rule specifies a permitted replacement during a grammar derivation. In a context-free grammar it has the form , with one nonterminal on the left.
A grammar derivation is a finite sequence of words in which each step replaces one occurrence of a production's left side by its right side. A leftmost derivation always replaces the leftmost available nonterminal.
A grammar derivation that always expands the leftmost remaining nonterminal symbol. In a context-free grammar, each parse tree specifies exactly one leftmost derivation. Two distinct leftmost derivations of the same word therefore prove that the context-free grammar is an ambiguous grammar.
A parse tree places the start symbol at its root, the symbols on the right side of a production at the children of its left-side nonterminal, and terminal symbols at its leaves. Reading the leaves from left to right gives the tree's yield.
Two grammars are equivalent when they generate the same formal language.
Two grammars over a common terminal alphabet are isomorphic when a bijection between their nonterminal alphabets maps one start symbol to the other and maps their productions bijectively after being extended to fix every terminal symbol. Isomorphic grammars are equivalent.
A context-free grammar is in Chomsky normal form when every production has the form or , with nonterminals and a terminal. If the empty word belongs to the language, one commonly also permits the exceptional rule under the usual restriction on the start symbol.
To convert a context-free grammar to Chomsky normal form, first add a fresh start symbol. Remove epsilon productions, retaining the exceptional start production only when the empty word is to remain in the language; then remove unit productions and symbols that cannot participate in a terminal derivation. Replace each terminal occurring in a right-hand side of length at least two by a new nonterminal that produces that terminal. Finally split every right-hand side of length greater than two into binary productions using fresh nonterminals.
A Chomsky-normal-form parse tree for a word of length has terminal productions and binary productions. Every derivation represented by the tree therefore has exactly steps.
The CYK algorithm decides membership in a context-free language given by a grammar in Chomsky normal form. It records, for every substring, the nonterminals that derive that substring and combines adjacent substrings using binary productions. For a word of length and a fixed grammar, it runs in time.
Weak Chomsky normal form additionally permits ternary productions . Compressing a two-step pattern , into preserves its generated yields whenever the intermediate variable has no other role, and saves one derivation step each time the pattern is used.
The intersection of a context-free language with a regular language is context-free, because a pushdown automaton and a finite automaton can be run in product.
If context-free grammars with disjoint nonterminal alphabets have start symbols , adjoining a new start symbol and the production gives a context-free grammar for the concatenation of their languages.
If a context-free grammar for has start symbol , adjoining a new start symbol and productions gives a context-free grammar for the Kleene star .
Every context-free language over a one-symbol alphabet is a regular language. Equivalently, the set of word lengths of a unary context-free language is ultimately periodic. This follows, for example, from the one-dimensional case of Parikh's theorem.
A context-free grammar can enforce sums such as by nesting one matched terminal pair for each independent count.
For some , every sufficiently long in a context-free language has with , , and in the language for all .
This formal language is not a context-free language. For pumping length , use . A pumpable window of length at most cannot meet both outer blocks. If pumping adds copies of , then and . Preserving the product constraint would require , impossible both when and when it is positive. This contradicts the pumping lemma for context-free languages.
The language is not context-free. For a proposed pumping length, start with a larger prime . Pumping unequal numbers of zeros and ones breaks equality; if the positive changes are equal to , pumping with exponent gives the composite common block length .
For a word consisting of three long constrained blocks, a pumpable window shorter than each block cannot alter both outer blocks; pumping then breaks a required three-way count relation.
A pumping length is a threshold beyond which every word in the language has a decomposition satisfying the conclusion of the relevant pumping lemma.
The language is not context-free. Pump a word with both block lengths . Unequal changes to the blocks destroy equality; an equal positive change makes both lengths , which lies strictly between consecutive squares and .
A finite-state machine processes inputs using a finite set of automaton states and input-dependent automaton transitions. An automaton state records everything the machine remembers; an automaton transition says how that memory changes on the next symbol. A finite-state machine may also emit outputs. Here the emphasis is on recognizing a formal language: start in a designated automaton state, read a word from an alphabet, and accept exactly when the final automaton state is designated accepting.
Finite memory does not impose a maximum input length. A finite-state machine can read arbitrarily long words, revisiting its automaton states indefinitely. The restriction is that the part already read must be compressed into one of finitely many summaries. For divisibility by three, a word of binary digits can describe an enormous integer, yet its congruence class modulo three is all that the machine needs to retain. Two already-read words giving the same automaton state behave identically under every subsequent continuation in a DFA.
This makes finite-state machines useful whenever past details can be forgotten safely: checking whether a sequence of commands follows an allowed order, or recognizing a pattern with a regular expression. The beautiful design question is which distinctions about the past matter to the future. DFA minimization makes that question precise by merging indistinguishable states of a deterministic finite automaton. Both DFAs and NFAs recognize exactly the regular languages.
For a deterministic finite automaton with automaton state set and input alphabet , the function specifies the next automaton state after reading one input symbol. A nondeterministic finite automaton instead allows a set of possible next automaton states.
To decide whether a finite-state automaton accepts exactly one distinct word, first obtain some accepted word by a finite automaton emptiness test. If there is none, answer no. Otherwise construct a finite-state automaton for the accepted formal language minus the singleton and test it for emptiness. Answer yes exactly when that difference is empty. Subset construction handles multiple accepting runs without confusing runs with distinct words.
A finite-state automaton recognizes a nonempty formal language exactly when some accepting automaton state is reachable from an initial automaton state. Reachability in a graph decides this in a finite transition graph. For an Epsilon-NFA, include its epsilon transitions; the non-epsilon labels of a successful graph path give an accepted word.
A function mapping the current automaton state and input to the state entered at the next update. In a Moore machine, a separate output function depends only on the current state; in a Mealy machine, it may also depend on the current input.
A hardware finite-state machine whose implemented transitions eventually leave every unused state encoding and enter the intended valid state set. If recovery must hold for arbitrary inputs, it is not enough that some input sequence can escape: there must be no indefinitely surviving unused-state path under any input sequence. Since the unused-state graph is finite, absence of a directed cycle among unused states gives a uniform finite recovery bound. A reset or initialization rule may still be required to give the valid state its intended meaning.
A table specifying the next state for each present state and input combination, together with the output if needed. For a Moore machine, output depends only on the state; for a Mealy machine, it may also depend on the current input. A state-transition diagram gives the same transitions as labelled directed edges.
An injective assignment of abstract finite-state machine states to stored bit patterns. distinct states require at least binary storage elements. Encodings with unused patterns can simplify Boolean functions through don't-care conditions, but the implemented next-state equations determine what those unused patterns actually do.
A pulse sequencer can separate event capture from output timing. A short interrupt handler acknowledges the event latch and increments a pending count. An independent finite-state machine consumes one count on entering
ON, changes to GAP after the pulse width, and enters IDLE only after the mandatory off interval. Even an empty queue must not bypass GAP: an arrival immediately after light-off would otherwise start too soon.The pending count equals recorded events minus started pulses. A critical section protects its read-modify-write operations; declaring shared state as in volatile-qualified objects in C does not alone make each update an atomic operation. Separate sequencers for different channels allow simultaneous pulses while one hardware timer schedules their earliest deadline. Finite queue capacity, detector rearming and dispatch resolution remain explicit assumptions.
A Moore machine is a finite-state machine whose output depends only on the current state. In a clocked implementation, a state entered at a clock edge determines the following period's output. Specifying an initial state is necessary to define startup behavior.
A synchronous sequential circuit can use three states: armed, pulse, and waiting. Only the pulse state has output one. A reset input rearms the circuit, including when it arrives during the pulse cycle; this permits pulses on alternate clock cycles while each pulse still lasts exactly one cycle.
Enter a distinguished Moore machine state whose output is active, and ensure that every outgoing transition leaves that state for an inactive-output state. The output then lasts one clock period. Its outgoing transitions may simultaneously recognize the start of the next event, avoiding an unnecessary idle cycle. The one-period statement refers to the synchronous logical model, with ordinary propagation delay after each clock edge.
For a fixed word , store the length of the longest suffix of the received stream that is also a prefix of . On a new input symbol, append it to the represented prefix and select the longest resulting suffix that is a prefix of . The complete-word state signals recognition. Its outgoing transitions retain proper suffix matches, allowing overlapping occurrences rather than automatically restarting from the empty prefix. This is the finite-state form of the prefix information used by the Knuth-Morris-Pratt algorithm.
For example, recognizing needs suffix-prefix states of lengths zero through four. After a complete match followed by one, the last two symbols are , so the next state retains length two. This permits the second match in without clearing the useful suffix.
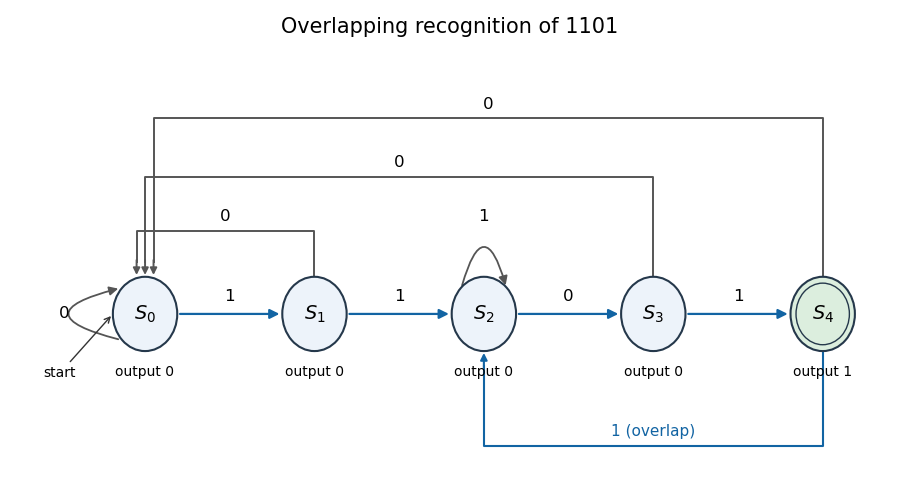
An overlapping prefix-suffix sequence recognizer for
. Details. A sampled toggle controller can reject short disturbances by requiring three consecutive high samples to toggle, and then three consecutive low samples before another high run is allowed to toggle. One four-bit synchronous sequential circuit stores output , an armed bit , and input history . Initially . SetThe two three-sample run detectors cannot assert simultaneously. A high run toggles once and clears ; only a complete low run rearms it. All right-hand sides use the old state, so the toggling event occurs at the third qualifying clock edge.
The controller has twelve distinguishable behaviours: for each , three armed states count trailing highs of lengths , and three disarmed states count trailing lows of lengths . The run lengths are distinguished by the number of further matching samples needed before a toggle or rearm. Armed and disarmed states are distinguished by an all-high continuation. Thus at least state bits are required, and the displayed design attains that bound.
Store the two previous input bits in . At the next clock edge, use and update . The output is high exactly when the present input and previous two samples are all high. Replacing each input by its negation detects a three-sample low run. Both detectors can share the same two history bits, using and . With initial history zero, the high detector cannot trigger before three actual high samples have occurred.
A synchronous sequential circuit stores a finite collection of bits , reads inputs , and updates all stored bits at each clock edge according to a specified next-state function . A combinational output is ; an output that is itself stored is included among the state bits. An initial state is part of a complete design. These equations provide a precise implementation-level description of a finite-state machine without requiring a particular gate drawing.
A sampled Boolean circuit that suppresses short input changes using recent samples. A three-sample majority function removes isolated one-sample changes; a stateful variant updates its stored output only after three equal input samples. These are different specifications.
A synchronous sequential circuit emitting a one-cycle pulse at the first low sample after at least two consecutive high samples. Three D flip-flops can implement , , and , with all updates using the old state. Initializing all state bits to zero excludes a false startup history. The stored output changes only at clock edges. After a detecting low sample, becomes zero, so the next output is zero regardless of the next input. A longer high run still ends with the same three-sample pattern.
A digital counter is a finite-state circuit that increments its stored value on each qualifying clock or event. A binary -bit implementation naturally has modulus . Dividing counted ticks by a known clock frequency gives a time interval, subject to wrap ambiguity and sampling accuracy.
Coupled digital counters sharing one clock, with a slower stage enabled by a terminal-state decode of a faster stage. Both stages sample the old state at the same clock edge. An enable changes whether a stage advances; it does not create a separate clock from a combinational decode.
Articles were limited to the first 100 out of 155 total.

