A low-rank approximation replaces an matrix by a matrix of matrix rank at most a chosen integer , with , while making an explicitly chosen error norm small. The point is to describe many entries using a few shared patterns: an image compression may retain broad brightness patterns while discarding finer ones. The approximation is useful when the saved storage or computation justifies the lost detail. A small matrix rank alone says nothing about the error.
The compact representation is a sum of outer products, equivalently a product of two thin matrices:Here are the columns of , and the star denotes the conjugate transpose; over the real numbers use the transpose. The rank bound for a matrix product gives . Conversely, choose a basis of the column space of as the columns of , and put the coordinates of each column of into ; pad with zero columns if the matrix rank is smaller than . Each nonzero outer product is a rank-one matrix: it repeats a single column pattern at different strengths across the columns.
Keeping the two factors stores scalars instead of . This saves space only when . The usual singular value decomposition representation stores scalars because it keeps the singular values separately; absorbing them into one factor removes that extra array. These are representation sizes at equal scalar precision, before file overhead. See Uschmajew and Vandereycken, §9.2: thin factors and their storage, and Illinois CS 357, Low-rank approximation: storing singular vectors and values.
The factors also give without forming the full matrix . Direct evaluation uses scalar multiplications, compared with for a dense matrix applied to a vector. For , the two factors contain scalars rather than , and the same counts describe these multiplication costs. Constructing the factors is a separate cost. Moreover, a low-rank approximation need not be a sparse matrix: the constant matrix whose entries are all has matrix rank despite having no zero entries.
For the standard unweighted problem, write a singular value decomposition with and singular values . Retain the first paired left singular vectors and right singular vectors:The Eckart-Young-Mirsky theorem says that this same minimizes both of the following error norms over all matrices with matrix rank at most :where and an empty sum is zero. Here the Frobenius norm is , whereas the operator norm is specifically induced by the Euclidean norm, . The first aggregates errors in all entries; the second bounds the worst output error for a unit vector input. These formulas apply to real and complex matrices. [ref]
https://math.uchicago.edu/~may/REU2016/REUPapers/Mazeika.pdf. Mazeika, §§4.1 and 4.3: norms and optimal singular-value truncation
For , a relative Frobenius norm tolerance is met precisely when the discarded squared singular values sum to at most . Thus one can choose the smallest suitable before reconstructing the matrix. Many individually small discarded singular values can still have a large combined error. An operator norm tolerance instead tests only the largest discarded singular value, . The two questions can therefore select different ranks.
The following stipulated matrix makes the tradeoff visible. Define four real vectors of length :The vectors are orthonormal, so this is already a singular value decomposition written as outer products, with positive singular values . All entries lie between and and can be displayed as brightnesses. The first component is uniform brightness, the second distinguishes broad blocks, and the last two supply finer alternating patterns. This is a designed arithmetic example, not measured image data.
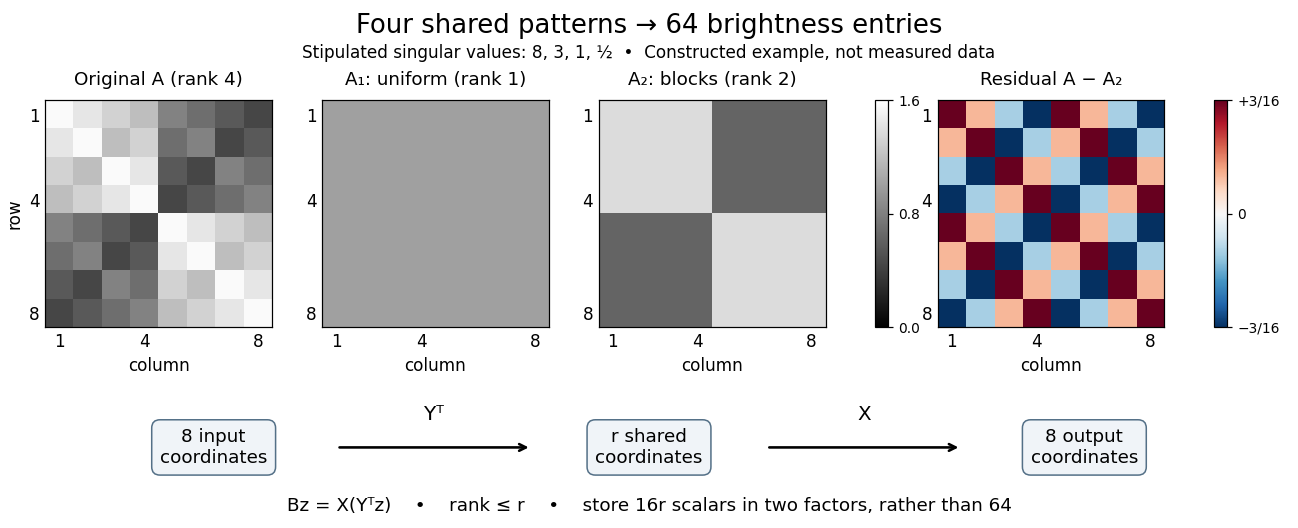
Here has every entry equal to , while has entries within the two diagonal blocks and in the other two blocks. For instance, becomes : its error is . The full residual is , whose Frobenius norm is and whose operator norm is . Since , the relative Frobenius norm error is . Two thin factors use scalars, or if the normalized left singular vectors, right singular vectors, and singular values are stored separately, instead of dense entries.
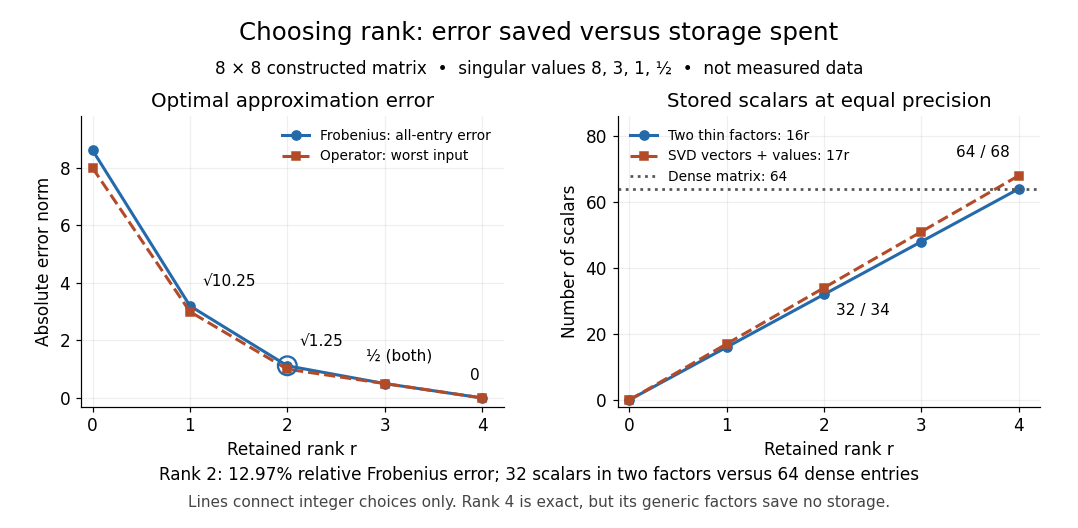
Retaining three components reduces the Frobenius norm error to while using scalars in two factors. Retaining all four reconstructs exactly but uses scalars, giving no saving in this generic representation; keeping the singular values separately uses . Our particular sign patterns could be encoded more economically, but that would exploit an additional structure beyond the general low-rank approximation. The striking feature is that numerical error and storage can both be read from the decomposition, rather than judged only by how smooth the picture looks.
The constraint is deliberately matrix rank at most . The truncation has . If , the best approximation is itself, with zero error. Requiring matrix rank exactly can destroy attainment: for and , the matrices have matrix rank for , and both error norms equal . Their error has infimum zero, but no rank-two matrix attains it. If , the displayed does have matrix rank exactly and attains the same minimum under either constraint.
Optimality also does not always mean uniqueness. For , the best Frobenius norm approximation is unique when . [ref]
https://link.springer.com/chapter/10.1007/978-3-030-31351-7_9. Uschmajew and Vandereycken, Theorem 9.1: uniqueness across a singular-value gap
A positive tie across the cutoff permits different choices: for and , both and have Frobenius norm error and operator norm error . More generally, is optimal for every real unit vector in the first two coordinate directions. Rotating which tied direction is kept changes the approximation. Repeated singular values entirely inside the retained group do not change its sum of outer products. At the only feasible matrix is zero; at the unique zero-error approximation is , even if some singular values are tied at zero.A strict gap does not guarantee uniqueness for the operator norm. For and , every with has matrix rank and error , which is optimal. Only minimizes the Frobenius norm, since . An unchanged worst direction can hide extra error in another direction under the operator norm.
Finally, these guarantees concern the stated norms and the sole matrix rank constraint. They do not establish that a discarded pattern is noise or irrelevant to a particular task: the finer patterns in our constructed example were put there intentionally. Adding entrywise weights or restrictions on the factors changes the problem, so the Eckart-Young-Mirsky theorem above does not automatically solve it. For historical context, the original 1936 matrix problem is documented in the existing Eckart-Young-Mirsky theorem section.
Articles by others on the same topic



Low-rank approximation is a mathematical technique used in various fields such as machine learning, statistics, and signal processing to simplify data that is represented in high-dimensional space. The idea behind low-rank approximation is to approximate a given high-rank matrix (or a dataset) with a matrix of lower rank while retaining as much of the important information as possible.