Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Optimal prefix code
For a complete binary prefix code with lengths , the Kraft inequality is an equality: . Put . The difference between expected codeword length and Shannon entropy isThe Kullback-Leibler divergence is nonnegative and vanishes exactly when . Hence a complete code is entropy-tight exactly for its dyadic matching source. For example, lengths match probabilities . Being an optimal prefix code among symbol-by-symbol codes is a weaker condition and does not imply this equality.
Huffman code Created 2026-10-14 Updated 2026-10-25
A Huffman code is the prefix code returned by Huffman coding; the algorithm chooses a code tree, while the code specifies the actual symbol-to-codeword assignment. For the probability distribution in symbol order , the illustrated binary tree givesThe codeword lengths are . This is a prefix code because no complete codeword is an initial segment of another complete codeword. Thus a decoder can start at the root of a tree, follow one edge per bit, emit a symbol on reaching its leaf, then restart at the root of a tree. In particular,
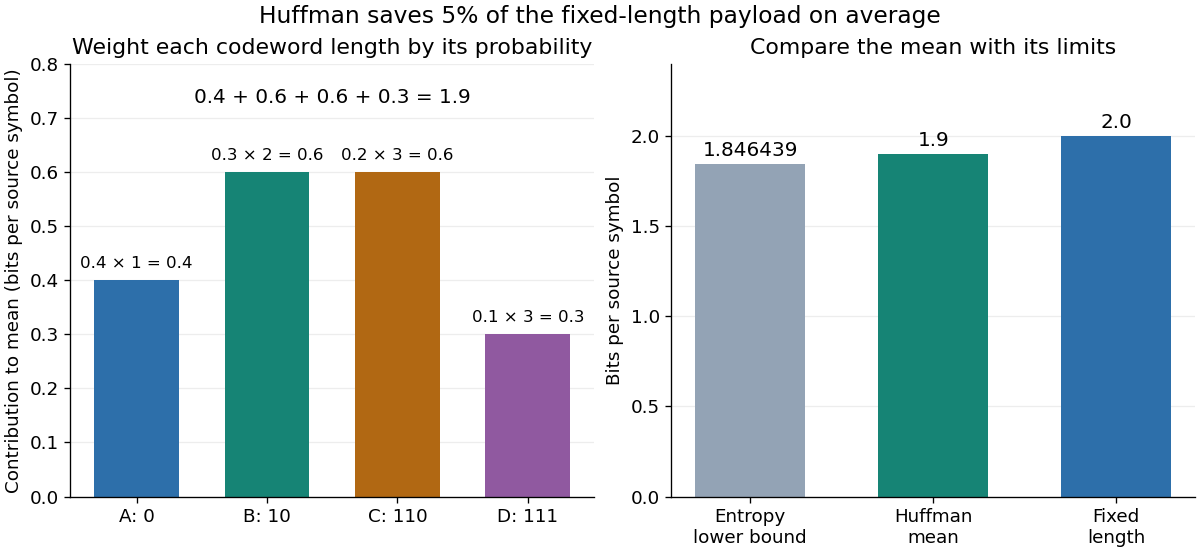
011010111 splits as 0 | 110 | 10 | 111 and decodes to . No separators are transmitted: the leaf tells the decoder where a codeword ends.The expected codeword length isbits per source symbol. Four symbols would require bits each if all codewords had the same length, so this Huffman code saves bit per symbol on average, or of that fixed-length payload. A particular message can grow: uses nine bits here instead of eight. These lengths count the encoded symbols only; transmitting a code description or message framing can add further cost.
The Kraft inequality is saturated by this Huffman code:Its Shannon entropy isbits per symbol, slightly below the expected codeword length . The entropy lower bound for prefix codes applies to every binary prefix code for this probability distribution. It need not be attainable with integer codeword lengths for individual symbols; Huffman coding reaches the best mean within that class. [ref]
https://web.iitd.ac.in/~sumeet/mackay.pdf. David J. C. MacKay, Information Theory, Inference, and Learning Algorithms, chapter 5, section 5.4: symbol-code bounds
A Huffman code need not be unique. In the first example, the tied and weights can exchange their edge labels, changing codewords but preserving their codeword lengths. Ties can also change the lengths themselves. For a second probability distribution , first merge to weight . The next merge can join with either or the subtree, since both have weight . Joining with permits , with all lengths . Joining with the subtree permits , with lengths . Both are optimal prefix codes with expected codeword length : for the latter, . Tie choices can change the code tree without changing the minimum mean.
// Target: algebra.bigb
Huffman coding Created 2026-09-24 Updated 2026-10-14
Huffman coding makes frequent symbols cheap to store by giving them short codewords, while allowing rare symbols longer codewords. For a known probability distribution on a finite alphabet with at least two positive-probability symbols, binary Huffman coding constructs a prefix code minimizing expected codeword length among binary prefix codes that encode one source symbol at a time. The objective is an average under that probability distribution; it does not promise to shorten every message. Encoder and decoder must agree on the resulting Huffman code. [ref]
The construction grows a binary tree from its leaves towards its root of a tree. Start with one leaf per symbol, weighted by its probability. Repeatedly join the two currently smallest weights beneath a new parent in a rooted tree, whose weight is their sum, and replace the pair by that subtree. Include newly formed subtrees when choosing the next pair. When one tree remains, label the two outgoing edges at every internal vertex with and ; the labels on the graph path from the root of a tree to a symbol give its codeword. This is a greedy algorithm: each step makes a locally cheapest merge, yet the result is an optimal prefix code.
For a concrete example, use probabilities , , , . First join and , creating weight . The remaining weights are for , for the subtree, and for . Join the two weights to make , then join with that subtree to make . The merge weights are therefore . Each merge adds one bit to every codeword below it, so their sum is the expected codeword length: bits per source symbol. The diagram fixes the edge labels to produce the Huffman code used below.
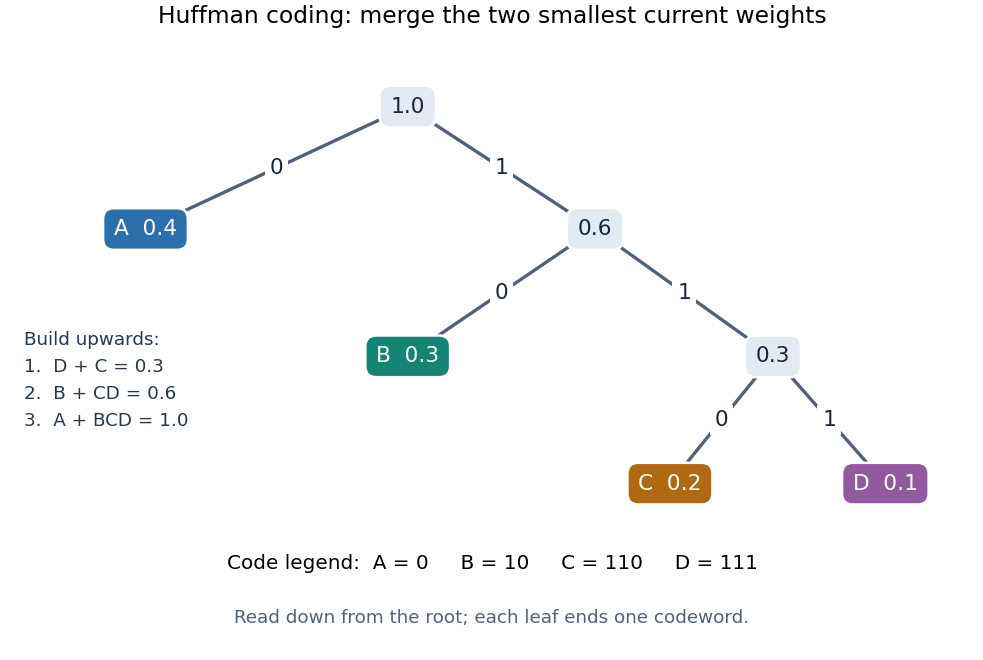


The useful insight is that choosing short codewords is a resource allocation problem: the prefix code condition constrains the available codeword lengths through the Kraft inequality. Huffman coding solves this one-symbol problem exactly for the supplied probability distribution. For repeated emissions of a memoryless classical information source, the same Huffman code can be applied symbol by symbol. More general compression can exploit dependencies or encode groups of symbols; the one-symbol optimality statement does not compare all such methods.
Huffman sibling contraction 2026-10-14
Replace sibling leaves in a code tree labelled by their common parent in a rooted tree, now a leaf labelled of weight . All other codewords stay fixed; each of loses one bit. For any such code tree and the contracted code tree , their weighted costs satisfyIf have two least weights, the Huffman sibling property gives an optimal prefix code containing this pair. Its contracted prefix code must be optimal for the reduced weights : any cheaper reduced prefix code could be expanded at by appending , giving a cheaper original prefix code. Conversely, expanding any optimal reduced prefix code adds precisely and attains the original minimum. This is optimal substructure, the justification for repeating the merge in Huffman coding. [ref]
In the exchange diagram, contract to weight at leaf depth in a code tree . The reduced expected codeword length is bits; expanding restores bits. For , the reduction leaves one symbol: allow its temporary codeword to be empty, of cost zero, so expansion gives the two one-bit codewords. This convention is only the terminal reduced problem; the original source has at least two symbols.
Huffman sibling property Created 2026-09-24 Updated 2026-10-14
For a finite source alphabet of symbols with positive weights , choose any two least weights, breaking ties arbitrarily. There exists an optimal prefix code over the binary output alphabet whose chosen symbols occupy sibling leaves in a code tree at maximum leaf depth in a code tree. Weights may be counts or probabilities: dividing every weight by gives the same minimizers. The existence statement is what makes the first merge of Huffman coding safe. It does not say that every optimal prefix code already has the chosen pair together.[ref]
A Method for the Construction of Minimum-Redundancy Codes by David A. Huffman. p. 1099: Derived Coding Requirements and Optimum Binary Code
An exchange makes the idea tangible. Take probabilities . The prefix code , , , has expected codeword length bits. Exchange only the symbols at their existing leaves: the available codewords and code tree shape stay fixed, but the codeword lengths in symbol order become . The new expected codeword length is bits, and the two least probabilities, those of , now occupy deepest sibling leaves in a code tree. The saving is bit per source symbol.
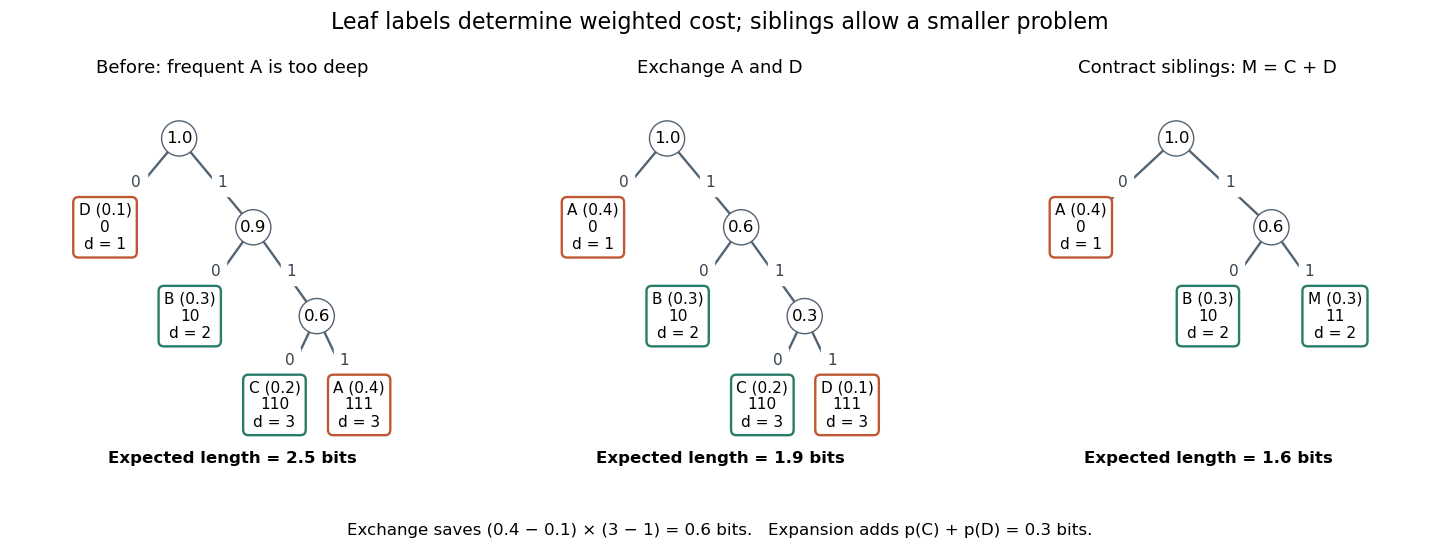
Exchanging two leaf labels reduces expected length from 2.5 to 1.9 bits; contracting the least-probability siblings leaves cost 1.6
. Details. 
Here is the short proof outline. An optimal prefix code with positive weights has a full binary tree as its code tree: suppressing a vertex with only one child shortens every codeword in that subtree and strictly reduces cost. A deepest leaf therefore has a leaf as its sibling, giving the deepest sibling property of an optimal prefix code. Put the two chosen least weights at these positions by successive exchanges of leaf labels. Moving a weight from leaf depth in a code tree to a deepest position , occupied by , changes the weighted sum byFix one chosen weight there, then move the other into the neighbouring deepest position; if it is already there, no exchange is needed. The prefix code condition survives because the set of codewords is unchanged. Starting from an optimal prefix code, the cost cannot decrease below the minimum, so these exchanges preserve optimality. Strictly unequal weights at unequal depths would give a strict decrease, explaining probability monotonicity of optimal prefix-code lengths. Equal weights or equal depths allow cost-neutral exchanges. [ref]
Nonunique optimal prefix code Created 2026-09-24 Updated 2026-10-14
An optimal prefix code can be nonunique in several different senses. Exchanging the labels on the outgoing edges of an internal vertex changes codewords while preserving every symbol's codeword length, the code tree shape, and expected codeword length. This freedom exists even with strictly unequal probabilities. Exchanging equal-probability symbols between leaves also preserves expected codeword length; if their leaf depths in a code tree differ, their individual codeword lengths change, though the set of leaf depths does not. For example, three equiprobable symbols have optimal codeword lengths : any of the three can receive the one-bit codeword.[ref]
A Method for the Construction of Minimum-Redundancy Codes by David A. Huffman. p. 1099, Derived Coding Requirements: equal-probability messages may have unequal lengths and may exchange codes without changing the mean
Ties between weights of entire subtrees during Huffman coding can go further and change the code tree shape and its collection of codeword lengths. Take and first merge , creating weight . Next, of weight can merge either with or with the subtree, both of weight . The two resulting prefix codes areFor the second prefix code, bits. Both merge sequences add weights , whose sum is . Enumerating the full binary trees with four leaves also proves optimality independently: costs , while the least cost of is again . The two code trees cannot be obtained from each other merely by relabelling leaves or exchanging edge labels: their collections of leaf depths in a code tree differ.
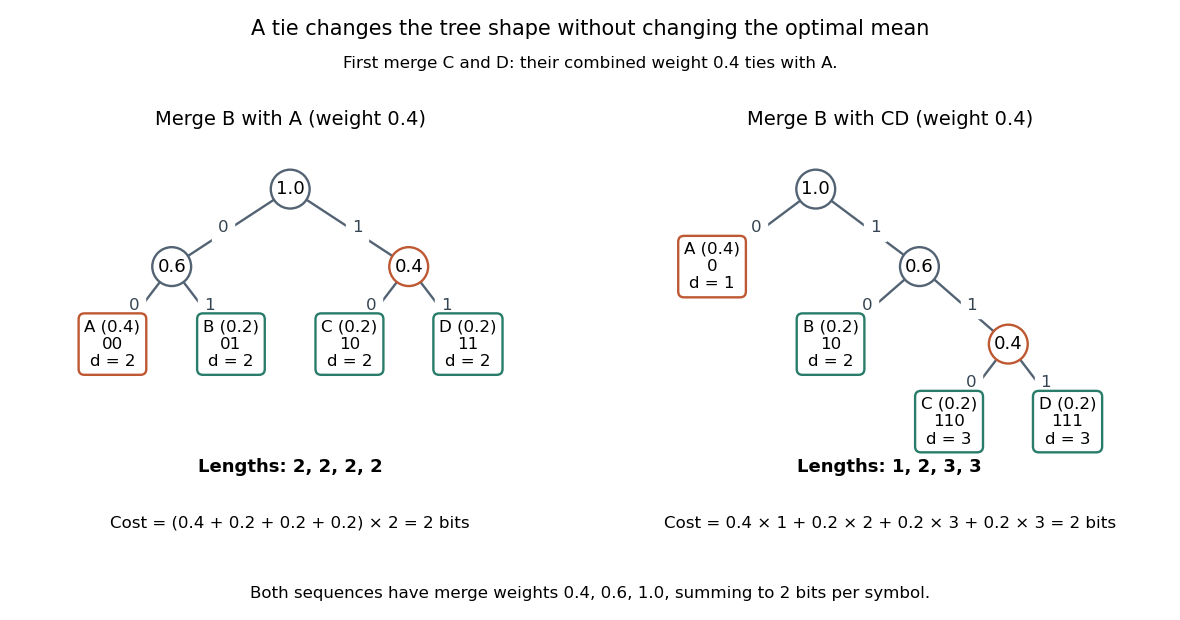
A tie between a symbol and a merged subtree gives two optimal prefix trees, with depths 2,2,2,2 and 1,2,3,3
. Details. 
The quantifier in the Huffman sibling property is visible here too. Choose as two least-probability symbols. In the displayed balanced optimal prefix code, they are not sibling leaves in a code tree. Exchanging , which have equal probabilities, produces another balanced optimal prefix code in which are deepest sibling leaves in a code tree. Thus the proof supplies an optimal representative with the chosen pair together. It does not force that labelling on every optimum. An implementation can make its tie choices and edge assignments deterministic when encoder and decoder need to reproduce the same codewords; optimal mean length alone does not specify them.
Optimal prefix code Created 2026-09-24 Updated 2026-10-14
An optimal prefix code minimizes expected codeword length for a fixed source probability distribution. Here the source alphabet is finite, has symbols, and has for every symbol; each source symbol receives one codeword over the binary output alphabet . Its code tree puts the symbols at leaves. Reading the edges along the graph path from the root of a tree to a leaf produces its codeword, so the leaf depth in a code tree is exactly its codeword length. ThusFor unnormalized positive weights, minimize instead; the corresponding expected codeword length is . This connects the abstract optimization to storage or transmission: counts the bits charged when symbol occurs. Huffman coding attains this minimum; the Huffman sibling property and Huffman sibling contraction explain why. [ref]
For , a balanced code tree charges every symbol two bits, giving . The codeword lengths charge the most frequent symbol only one bit, giving . The choice concerns weighted cost, not just the greatest codeword length: increasing that maximum from two to three can improve the average.
The search over prefix codes looks infinite, but positivity reduces it to finitely many full binary trees with leaves. A vertex with one child can be suppressed to improve cost, and a full binary tree with leaves has internal vertices. There are consequently finitely many such shapes and symbol assignments, so the minimum exists. For four leaves, the only possible sorted codeword lengths in a full binary tree are and . Probability monotonicity of optimal prefix-code lengths assigns larger probabilities to shallower leaves, giving respective minimum costs and in this example. This is an independent small-instance check of the Huffman code.
These hypotheses matter. With zero weights, suppressing a subtree carrying only zero weight need not strictly improve cost, so an optimal prefix code need not have a full binary tree. A one-symbol source raises the convention of whether an empty codeword is allowed. Both cases are outside the original statement here. Encoding groups of symbols changes the source alphabet and the optimization problem; the minimum here concerns one source symbol per codeword.
Past exam of the communication Theory course of the University of Oxford 2009 2 a iii Solution 2026-10-31
A compact code or optimal prefix code minimizes the expected codeword length for the given source probabilities and coding alphabet. The relevant comparison here is among binary prefix codes. The minimum is also the minimum among uniquely decodable codes, since the Kraft-McMillan inequality permits every uniquely decodable length list to be realized by a prefix code with the same lengths.
A realized message has self-information . The average information per source message is its Shannon entropy,The average reaches bits per message at . Individual rare realizations can have larger self-information; this bound concerns the average.
The given strings form a prefix code with lengths and . To attain the entropy bound without redundancy, the resulting long bit stream must carry one bit of information per bit: unbiased bits with no predictable dependence. For an independent source, the dyadic source matched to a complete prefix code hasThese probabilities make the encoded stream equivalent to parsing independent fair bits using the code tree. Its expected codeword length and source entropy agree:Here “optimal” means attaining the Shannon bound. If it means only an optimal prefix code among symbol-by-symbol binary prefix codes, the probabilities are not unique: for three positive-probability symbols, this tree is optimal whenever is a largest probability. Huffman coding need not attain entropy exactly for nondyadic probabilities.
Concatenating the specified source-message encodings givesPack consecutive bits in pairs, rather than allocating a fresh Bell pair to each variable-length source word:Under the mapping in part 1, transmitThe block uses six message-bearing qubit transmissions and six preshared Bell pairs. Source-message boundaries are recovered by parsing the decoded prefix bit stream.
Past exam of the mathematics course of the University of Cambridge 2023 ii Paper 1 3I a Solution Created 2026-09-24 Updated 2026-09-25
A binary code is a prefix code when no codeword is a proper prefix of another. If the source letters have probabilities and codeword lengths , the expected value of its codeword length isIt is an optimal prefix code when it minimizes among all binary prefix codes for that source.
Suppose but . Exchanging the codewords assigned to and leaves the set of words, and hence prefix-freeness, unchanged. The change in expected length iscontradicting optimality. Thuswhich is the probability monotonicity of optimal prefix-code lengths.
Represent the code by its binary prefix tree and choose a codeword of maximal length, where . Its sibling is . If that sibling were not a codeword, it could not have a codeword below it either, since such a word would be longer than . Replacing by would then preserve prefix-freeness and strictly reduce . This is impossible for an optimal code, so is also a maximal-length codeword. The pair differs only in its last digit, proving the deepest sibling property of an optimal prefix code.
Past exam of the mathematics course of the University of Cambridge 2023 ii Paper 2 3I a ii Solution Created 2026-09-24 Updated 2026-10-03
For a Bernoulli source, independence makes entropy additive, soIts information rate is therefore . If is an optimal prefix code and is its expected codeword length, the Shannon noiseless coding theorem givesConsequently the information rate is at most the expected word length of the optimal code.
Sibling leaves in a code tree Created 2026-10-14 Updated 2026-10-25
Two leaves of a code tree with the same parent in a rooted tree. Their codewords have a common initial segment and differ only in the final bit: . Their leaf depth in a code tree is equal. The Huffman sibling property places two chosen least weights at such leaves in some optimal prefix code.