A binary tree, in the data structure convention used here, is a rooted tree in which each vertex has zero, one or two children in a rooted tree, occupying distinct left and right positions. A single left child and a single right child give different binary trees. A vertex with no children in a rooted tree is called a leaf. An empty binary tree has no root of a tree and is also allowed as a storage case. [ref]
For example, give the root of a tree label , its left child label and its right child label . Attach as the left and right children in a rooted tree of , and as those of . This binary tree has seven vertices, six edges, and height of a binary tree : a longest downward graph path contains two edges. The binary search tree lookup illustration below shows this shape alongside the binary tree consisting only of successive right children , whose height of a binary tree is .
Left and right positions specify an ordered shape, not a numerical total order on stored labels. Swapping labels and in the first example still gives a binary tree, but destroys the binary search tree property. Nor must a binary tree be balanced: the right-child chain is just as valid. The same shape convention supports a binary heap, a Huffman code, or a binary search tree, each with its own additional rules. The useful idea is to describe two smaller subtrees at each vertex, making structural recursion natural.
For a precise recursive description, a finite binary tree is either empty or a root of a tree carrying a value together with an ordered pair of disjoint smaller binary trees. The entries of this ordered pair are its left and right subtrees, each of which may be empty. Thus two binary tree child slots exist even when fewer than two children in a rooted tree exist; an empty slot does not denote an extra vertex. This decomposition is the basis of structural recursion.[ref]
4.4 Symbol Tables. Introduction to Programming in Java, section 4.4, Binary search trees: recursive definition and node representation
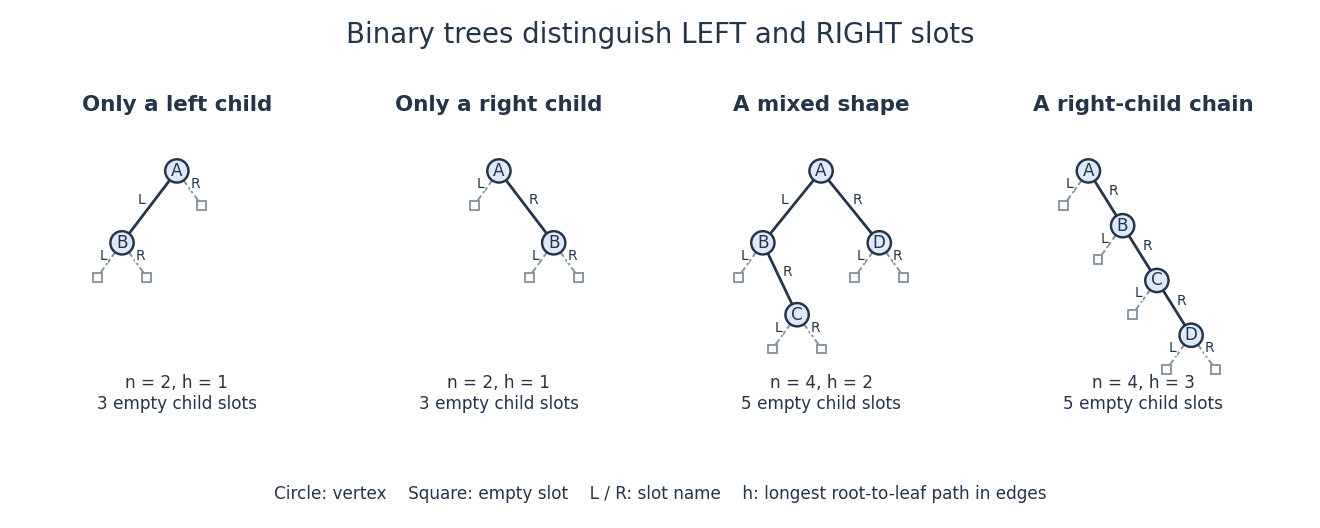
Left and right binary tree child slots distinguish shapes even with just one child
. Solid circles are vertices; outlined squares mark empty binary tree child slots. The first two binary trees differ only in the occupied slot at . The last two have the same four labels but different height of a binary tree. Details.In the four-vertex mixed example, has left child and right child , while has only a right child . Count its vertices by structural recursion: the empty binary tree contributes zero and each nonempty binary tree contributes one plus the counts of its left and right subtrees. Thus contributes , and contributes . The same decomposition computes height of a binary tree, supports inorder traversal, and supplies short proofs by structural induction. It separates shape from the values stored in a data structure.
Ignoring values, let count finite binary tree shapes with vertices, retaining left and right slots and counting the empty shape once. Splitting at the root of a tree gives the recurrence relationFor each left subtree size , choose its shape and the right subtree shape independently. This yields the Catalan numbers: , , and . The two shapes at are exactly the left-only and right-only examples. Forgetting the slot distinction would change the counting problem.
A binary tree with each data label stored at a leaf of a tree. One useful Haskell datatype has constructors
One a for a leaf and Two (Tree a) (Tree a) for an internal node. Every finite inhabitant has at least one leaf, so this datatype cannot encode an empty leaf sequence. Its natural tree fold has a leaf operation a -> b and an internal operation b -> b -> b; replacing the two constructors by those operations defines the structural recursion.Define and . Subtracting the right-spine length from total size gives the same quantity, because every node lies either on that spine or in one of its disjoint left subtrees. A right tree rotation at the root decreases this potential by exactly one; removing a root with no left child preserves it. Thus repeated root rotations and inorder removals take linear total work.
A local change of root and child pointers that preserves inorder order. A right rotation promotes a left child, moves that child's right subtree to the old root's left position, and makes the old root its right child. The five inorder pieces remain in the same order; a left rotation reverses this transformation. Rotation does not by itself require search-tree key ordering.
For old root with left child and untouched subtrees , change the shape from to . Both have inorder sequence . In a destructive traversal that only rotates at the current root, this transformation extends the right spine by one node and decreases the left-size potential by one.
A binary tree whose subtree sizes or heights satisfy a stated balance condition. Recursively splitting an -element sorted list into sizes and gives logarithmic height and child sizes differing by at most one. This is a static construction; ordinary binary search tree insertion does not automatically retain balance.
A leaf-labelled binary tree is leaf-balanced when the leaf counts of the two subtrees at every internal node differ by at most one. Splitting a finite nonempty list into pieces of sizes and and applying the same construction recursively preserves the original leaf order and gives this balance condition. Both pieces are nonempty for and strictly shorter than the input; induction proves termination and balance. This leaf-count convention is different from demanding equal subtree heights.
The condition that each binary-tree vertex has child subtrees whose node counts differ by at most one. Recursively choosing the middle entry of an index interval establishes this condition at every vertex, with exactly one allocated node per entry. No ordering assumption on the stored values is needed for the balance property or for reproducing the input's inorder sequence.
A binary tree representing a mathematical expression, with values at its leaves and binary operations at internal nodes. The tree records which pair of intermediate values is combined at each step.
One of the two distinguished positions, left or right, at a vertex of a binary tree. Each binary tree child slot is occupied by a child and its subtree, or is empty. A reference representation can use
null for an empty binary tree child slot. Two slots are capacity for at most two children in a rooted tree, rather than a requirement for two actual vertices.Every nonempty finite binary tree with vertices has exactly empty binary tree child slots. There are slots altogether, and precisely occupied slots, one for each edge of its underlying tree. ThereforeThis counts missing child references, not vertices or leaves. In the mixed four-vertex example, has no empty binary tree child slots, has one, and each have two: . The four-vertex chain also has five: one at each of its first three vertices and two at the last. For , there are no vertices and hence no child fields; the empty binary tree instead has a single empty root position if it is represented by a root reference.
A second proof uses the recursive decomposition. Count every empty subtree occurrence, including the root position for the empty binary tree: let . For a nonempty binary tree, . If the two subtrees have vertices, structural induction gives . Distinct empty positions may share the same
null value; these are occurrences, not separately allocated objects. This count is useful when analysing the base cases reached by a structural recursion that calls both subtrees of every vertex.For a vertex in a rooted tree, its subtree contains and every vertex reachable by repeatedly following children in a rooted tree, together with the connecting edges; its root of a tree is . In a binary tree, the left subtree is rooted at the left child, and is empty when that child is absent; the right subtree is defined similarly. A binary search tree constrains every key in these subtrees.
For a nonempty binary tree, the largest number of edges on a downward graph path from its root of a tree to a leaf. A single vertex has height of a binary tree ; a chain of vertices has height of a binary tree . A convenient recursion convention assigns an empty binary tree height , giving for the left and right subtrees. A binary search tree lookup visits at most vertices.
The convention counts edges, rather than vertices on the longest graph path. Its recursive form is[ref]
For a leaf, both subtrees are empty, giving . For the mixed four-vertex example, , , and . The four-vertex chain has height of a binary tree . A convention that counts vertices would add one to every nonempty binary tree height, so a height formula must specify its convention.
At distance from the root of a tree, there are at most vertices: each vertex in the preceding level has at most two children in a rooted tree. Summing this geometric series and using the longest graph path gives, for ,The upper bound is attained by a chain; a perfect binary tree attains the capacity bound. For , the minimum possible height of a binary tree is , as in the mixed example, while the maximum is . The binary tree definition permits both extremes. Small height of a binary tree bounds the length of a directed lookup in a binary search tree; evaluating the height of a binary tree by the displayed structural recursion still examines all vertices, requiring time complexity under constant-cost child access and arithmetic.
An inorder traversal of a binary tree uses recursion to visit the left subtree, output the current vertex, and visit the right subtree; an empty subtree outputs nothing. This is a depth-first traversal of a tree with output between the two recursive calls. It produces sorted keys for a binary search tree, but arbitrary labels in a binary tree need not appear in total order.
// Target: computer-science.bigb
While the remaining root has a left child, apply a right tree rotation there. Once the left child is null, output the root and advance to its right child. The output already produced followed by the remaining inorder sequence is invariant. There are exactly output removals and rotations, because rotations decrease the left-size potential and removals preserve it. The algorithm therefore takes linear time and constant auxiliary pointer space, at the cost of changing the input links.
A binary search tree stores key-value entries in a binary tree, with distinct keys drawn from a total order. At every vertex, all keys in its left subtree must be smaller than its own key, and all keys in its right subtree must be larger. Thus the entries represent a partial function from keys to values: a key has at most one associated value and may be absent. [ref]
Lookup starts at the root of a tree. Compare the target with the current key: equality returns its value, a smaller target continues into the left subtree, and a larger target continues into the right subtree. Reaching an empty subtree reports absence. The ordering rule justifies discarding the other subtree at every step; this is the algorithm correctness argument for lookup. It applies to the entire subtree, even if that subtree contains many vertices. [ref]
In the seven-key example, search for . At , the comparison selects the right subtree; at , selects the left subtree; at , equality ends the search. The visited keys are , three key comparisons. The right-child chain stores exactly the same keys and satisfies the same binary search tree rule, but lookup of visits , five comparisons. Searching for absent key visits in the first binary search tree and all seven keys in the chain before reaching an empty right subtree.
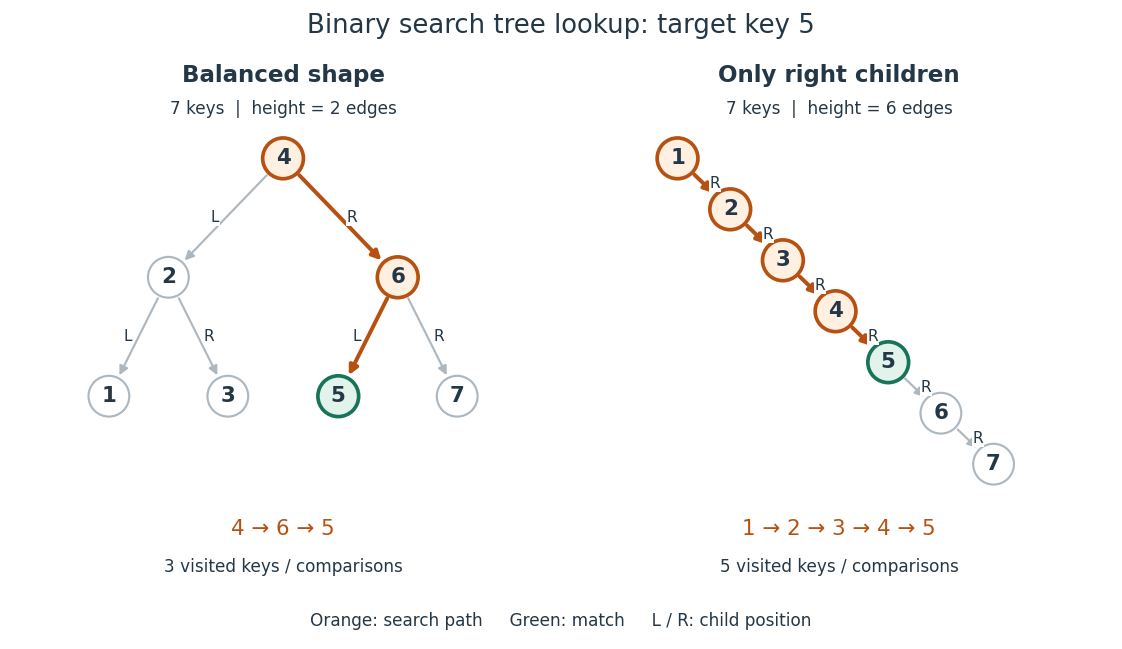
Lookup of key in two binary search trees containing the same seven keys
. Orange highlights visited keys and edges; green marks the match. The balanced shape has height of a binary tree and requires three visits, while the chain has height of a binary tree and requires five visits for this target. Details.For a nonempty binary search tree of height of a binary tree , lookup inspects at most vertices. Under constant-cost key comparisons and child-reference access, its time complexity is in Big O notation, usually written for . With entries, , giving worst-case lookup. If the shape is kept balanced so that , lookup takes for . The empty and one-entry cases take constant work. The worst-case linear bound also appears in Sedgewick and Wayne's ordinary, unbalanced implementation. [ref]
https://raw.githubusercontent.com/kevin-wayne/algs4/master/src/main/java/edu/princeton/cs/algs4/BST.java. Sedgewick and Wayne, Algorithms: BST implementation, complexity contract and get method
In a shape with every level full, there are vertices, a geometric series. This explains how a small height of a binary tree can accommodate many entries. The binary search tree ordering rule alone does not guarantee this shape or logarithmic time complexity. Breadth-first search also gains no logarithmic key-lookup guarantee merely from having a binary tree: in the displayed balanced example, its left-to-right level order is , so it inspects six keys before finding , and an absent target requires all seven. Directed lookup uses the total order to choose one branch.
The ordering requirement includes every ancestor on the graph path from the root of a tree. Consider the smaller binary tree with root key , left child , right child , and right child under . Key must satisfy both , from its immediate parent in a rooted tree, and , from its position in the root's left subtree. Replacing by preserves all immediate parent-child comparisons, including , but violates . Lookup for would incorrectly go from to and then to an empty left subtree, overlooking the stored key.
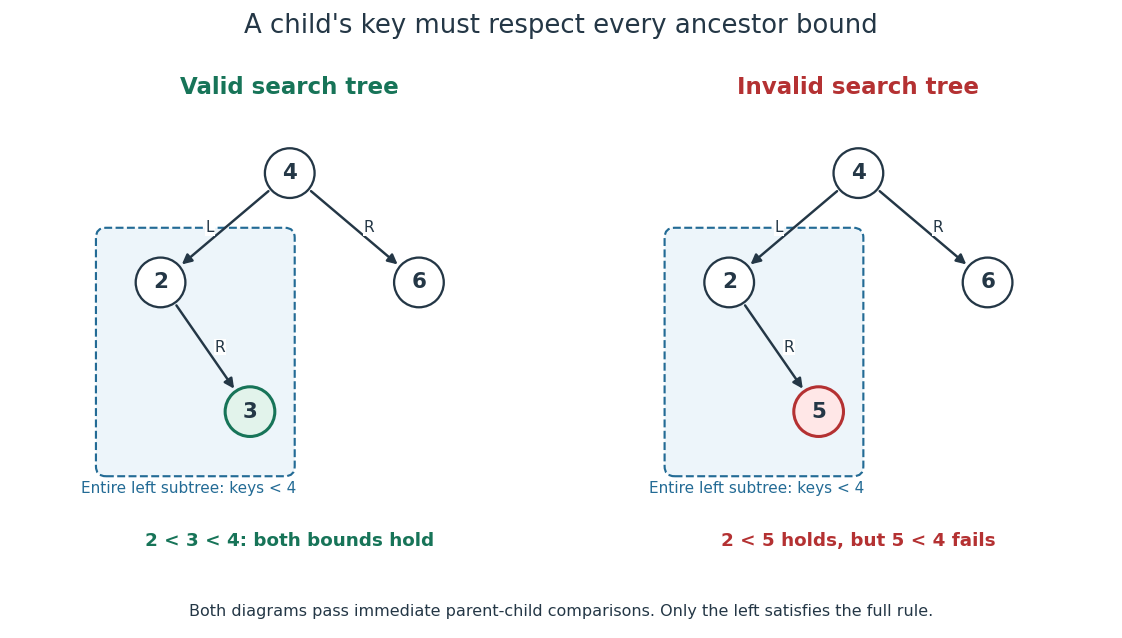
The binary search tree ordering rule constrains an entire subtree
. The valid example has . The invalid example passes immediate parent-child comparisons, but key lies in the left subtree of key and violates its inherited upper bound. Details.An inorder traversal visits a left subtree, then its own vertex, then a right subtree. On the valid small example its output is ; on the invalid example it is , exposing the descent from to . Both seven-key binary search trees yield . The theorem is that an inorder traversal of a finite binary search tree with distinct keys lists every key once in strictly increasing total order. For a short proof outline, use mathematical induction on the number of vertices: each smaller subtree produces its own sorted list, and the full ordering rule places every left key before the current key and every right key after it. Concatenating these three parts preserves strict order. Sedgewick and Wayne's
keys method uses this left-current-right order. [ref]https://raw.githubusercontent.com/kevin-wayne/algs4/master/src/main/java/edu/princeton/cs/algs4/BST.java. Sedgewick and Wayne, Algorithms: BST keys method and inherited-bound isBST check
This combination is useful and attractive: one data structure supports directed lookup and ordered enumeration. An inorder traversal costs time complexity for entries, since it visits every vertex; balance accelerates lookup but cannot eliminate the work of outputting all keys.
// Destination: computer-science.bigb
A pure function deletes a key from a binary search tree by rebuilding its search path and sharing untouched subtrees. At a matching node with two children, replace its key by the least key in its right subtree, removing that occurrence from the right subtree. The ordering invariant is preserved, with time complexity and fresh-node allocation proportional to the height of a binary tree.
Turn a binary search tree into a sorted doubly linked list by reusing each linked list node's left and right child fields as predecessor and successor fields. An inorder traversal determines the required order. A recursive implementation first saves both child references, flattens the disjoint child subtrees, and splices their endpoints around the root. Structural induction proves that it preserves every original entry exactly once and produces reciprocal links with null outside endpoints. An explicit stack implements the same traversal without recursive calls; each original right child must be saved before its field is overwritten. Both versions take linear time complexity and auxiliary space for original height . The old binary search tree representation is consumed, so outside aliases must not continue to interpret the changed links as child pointers.
A red-black tree colours each stored node red or black, treats absent-child sentinels as black, permits no red node to have a red child, and gives every path from a node to an absent-child sentinel the same number of black nodes. We also require a black root. These invariants bound its height of a binary tree by for stored keys: a path has at most twice as many real nodes as black nodes, and a subtree of black height has at least real nodes by mathematical induction. The structure therefore supports logarithmic-time directed binary search tree lookup.
In the usual bottom-up algorithm, insert a red node by the binary search tree rule. If its parent is black, no repair is needed. If its parent and uncle are red, recolour both black and recolour the grandparent red, then continue upward. If the uncle is black, an inner configuration first rotates the parent to become an outer configuration; rotating the grandparent and exchanging its colour with the parent's resolves the red-red conflict. Apply the left/right mirror cases as needed and finish with a black root. The tree rotations preserve key order, and the colour changes preserve equal black height. Different valid insertion conventions can produce different valid red-black trees, so a worked trace must identify its convention.
A red-black tree with no red stored nodes is a perfect binary tree. Indeed, every root-to-sentinel path has equal length because every real node is black; a missing branch at an earlier level would make its path shorter. Thus every real level is full. Its size is for some number of real levels. Conversely, colouring every stored node of a perfect binary tree black satisfies every red-black invariant. This proves both directions of the size criterion.
For a node of a red-black tree, count black nodes strictly below on any path to an absent-child sentinel, including that black sentinel. The red-black invariants make this count independent of the path. Other conventions omit the sentinel or count ; specify the convention when using numerical values. Equality of the counts, rather than their common additive offset, is what the balancing condition requires.
Two stored keys are consecutive when no stored key lies strictly between them. Their numerical difference need not be one. After splaying on followed by splaying on , the node is the left child of with an empty right subtree. To prove this, after the first call is the minimum of the right subtree of . The last step crossing is either a zig step or a right-left zig-zag step; both make the left child of . A nonempty right subtree of would require a stored key strictly between them.
A splay tree is a binary search tree whose access operations use splaying to move a selected key to the root through tree rotations. It stores no explicit balance or height information. A single access can take linear time, while the standard operations have logarithmic amortized time complexity. The distinction matters: amortized analysis bounds the total cost of an operation sequence, not the worst cost of every individual operation.[ref]
Self-Adjusting Binary Search Trees by Daniel Sleator and Robert Tarjan. Author-hosted abstract: representation, operations and amortized logarithmic bound
In ordinary bottom-up splaying, locate the selected node by a binary search tree search and repeatedly move it toward the root. If its parent is the root, perform a zig step. Otherwise use a zig-zig step when the node and its parent occupy the same left/right directions, or a zig-zag step when their directions differ. Each tree rotation preserves the inorder traversal and hence the represented key order. The process ends with the selected key at the root. Unsuccessful access policies can instead move the last visited node to the root; arguments about successful calls should say the requested key exists.
Every node of a splay tree with at least four distinct keys can become a leaf of a rooted tree using only successful splaying operations. At an extreme key, access that key and then its sole adjacent stored key; the consecutive keys in a binary search tree property makes the extreme key a leaf. For an interior key with two larger stored keys, take consecutive and access ; the mirror construction handles two smaller keys.
For a quick shape proof, use for a node and its two subtrees. After accessing , the right subtree of can only be , , , or , with outside subtrees below and above . This follows by inspecting the final zig step, zig-zig step or zig-zag step that moves above the former root . In each case, accessing yields , where is a leaf and denotes an empty subtree. These rotations prove the bound for arbitrary outside subtrees.
When a node and its parent occupy opposite left/right directions, rotate the selected node above its parent and then above its grandparent. These two tree rotations move the selected node two levels upward while preserving the binary search tree ordering.
When a node and its parent are both left children, first apply a right tree rotation to the grandparent, moving the parent upward, and then another right tree rotation moving the selected node upward. Use the left-right mirror image when both are right children. The order of these two tree rotations distinguishes the operation from repeatedly rotating only the selected node.
A single tree rotation moving a node above its parent when that parent is the root. A left child uses a right tree rotation, and a right child uses a left tree rotation.
If a key is smaller than every key of a finite binary search tree , insert and then delete the minimum: the original tree, including its shape, is recovered. The insertion follows the leftmost search route and creates a new minimum leaf; deleting that leaf reverses the same route. The symmetric statement uses a fresh maximum. At a node with root , the bounds on its children therefore let a direct tree fold reconstruct an untouched child from that child's insertion result. This gives a direct fold implementation of insertion without assuming that insertion is injective on arbitrary trees.
For partial maps , retain exactly entries for which both maps define the same value at . Merely sharing a key is insufficient. Traverse one binary search tree, look up each key in the other, and insert only equal-value matches into the result.
// Destination: computer-science.bigb
A complete binary tree is a binary tree whose levels are full except possibly the deepest, which is filled from left to right with no gaps.[ref]
9.1 Binary trees. Data Structures and Algorithms, section 9.1.1: complete shape and binary heap example
Here a level groups vertices by their graph distance from the root of a tree. A binary heap uses this shape to maintain logarithmic height of a binary tree. Completeness differs from the two-children condition of a full binary tree.
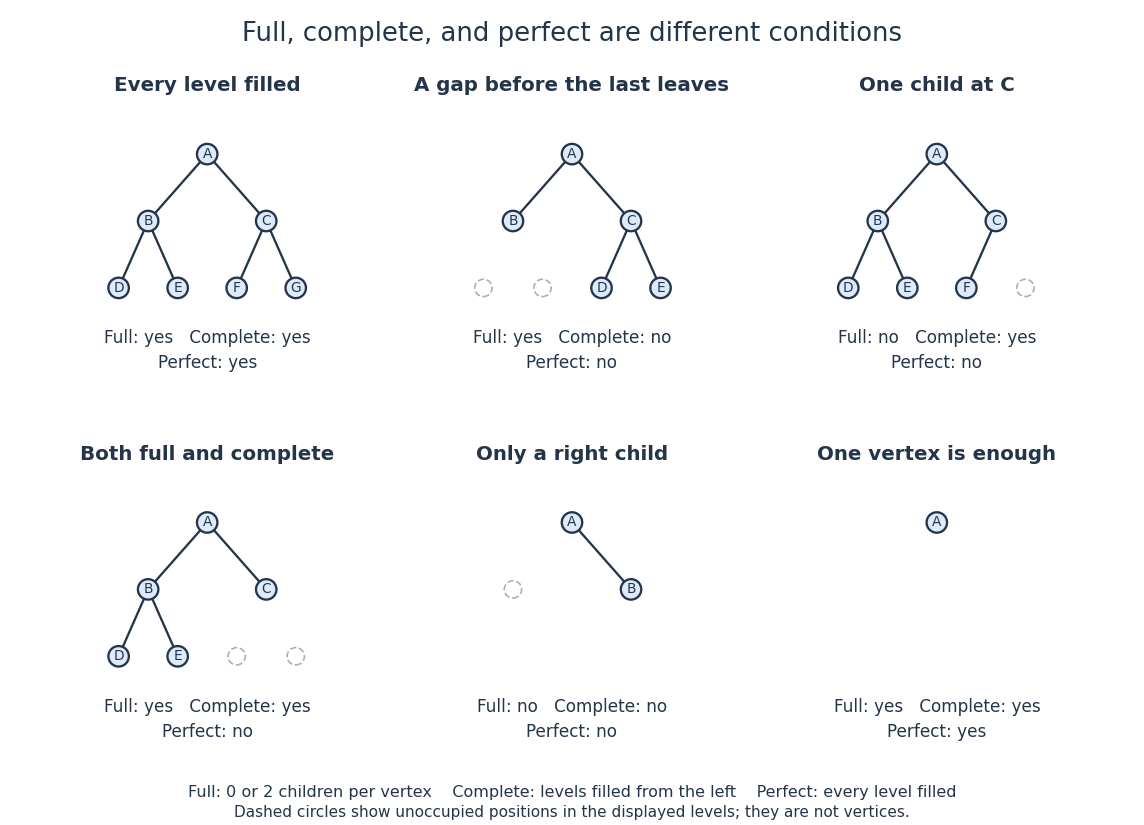
Full binary trees, complete binary trees, and perfect binary trees impose different shape conditions
. Each panel states all three properties. Outlined positions expose gaps in the last level. In particular, the five-vertex example in the lower left is both full and complete but is not perfect. Details.For a six-vertex example, give two children in a rooted tree , give two children in a rooted tree , and give only a left child . The levels have vertices, and the last occupies its first three positions, so this is a complete binary tree. It is not a full binary tree, since has exactly one child. Moving to the right slot of preserves and height of a binary tree , but leaves a gap before and destroys completeness. Merely keeping the deepest vertices near the left side is insufficient; every earlier position must be occupied.
Number positions by the left-to-right level order of breadth-first search, beginning with root position . The children of position have positions and . A nonempty complete binary tree occupies exactly positions , so its height of a binary tree is : positions form level . This consecutive occupancy explains the compact array representation of a binary heap, while heap order is a separate condition on values. Neither completeness nor the binary tree definition supplies the binary search tree ordering rule.
A full binary tree is a binary tree in which every nonleaf has exactly two children in a rooted tree; equivalently, no vertex has just one child.[ref]
9.1 Binary trees. Data Structures and Algorithms, section 9.1.1: full shape and Huffman coding tree example
A binary Huffman code with at least two positive-probability symbols has a full code tree: a vertex with only one child could be suppressed to shorten all codewords below it.
Let have children in a rooted tree , and let have children in a rooted tree , with leaves. Every vertex has zero or two children in a rooted tree, so this five-vertex binary tree is full. It is not a complete binary tree: level has empty positions under before the occupied positions under . Instead put under and leave a leaf. The resulting five-vertex binary tree is both full and complete, yet is not a perfect binary tree because its leaves occur at two different distances from the root of a tree.
If a nonempty finite full binary tree has nonleaf vertices and leaves, then its edges can be counted as , two leaving each nonleaf, or as , using the tree count. HenceThus is odd, but odd size alone does not imply fullness: a three-vertex chain is a counterexample. Nor does fullness guarantee small height of a binary tree. Repeatedly give one continuing vertex a leaf in one slot and another continuing vertex in the other, ending with two leaves. With nonleaf vertices, this constructs a full binary tree of vertices and height of a binary tree . The two-children rule permits height growing linearly with size.
A nonempty binary tree in which every level, including the deepest, contains all its possible vertices. Equivalently, it is a full binary tree whose leaves are all at the same graph distance from the root of a tree.[ref]
9.1 Binary trees. Data Structures and Algorithms, section 9.1.1: perfect shape, equal leaf levels, and Figure 9.4
Every perfect binary tree is both a full binary tree and a complete binary tree; the five-vertex example above shows that the converse fails even when both properties hold. These definitions fix the terminology used here.
For height of a binary tree , the level sizes are , giving by a geometric series. There are leaves. The seven-vertex example has level sizes and height of a binary tree ; the single-vertex binary tree is already perfect, with . More generally, joining two perfect binary trees of equal height of a binary tree under a fresh root of a tree gives the next such shape. Equal heights are essential: fullness alone allows unequal leaf distances. A perfect binary tree realizes the maximum number of vertices for its height of a binary tree, making the exponential capacity behind short lookup graph paths visible.
// Target: probability-and-statistics.bigb



