An optimizer update changes the adjustable parameters of an optimization problem according to an algorithm's current information. Evaluating a loss function, computing its gradient and changing the parameters are distinct operations. A general update may also change an optimizer state, such as stored information from previous steps:Here is the supplied gradient and a learning rate. The PyTorch interface makes this separation explicit with gradient computation followed by
optimizer.step().[ref]torch.optim in the PyTorch documentation. PyTorch2.15, Taking an optimization step, optimizer.step() example; Optimizer base class
For plain gradient descent with no extra state, . In an original scalar example, choose , and . The gradient is 2, so the update gives and lowers the loss from 2 to 1.62. Recompute the gradient at the new parameter value to obtain . Reusing the old gradient 2 instead would give 1.6. This explicitly locates where the algorithm obtains its information.[ref]
An update is not automatically an improvement: using for the first step above gives and loss 8. With gradient accumulation, several gradient calculations instead contribute before a single optimizer update; their weighting sets the effective batch size. Track the update count separately from the number of processed groups, particularly when applying a learning rate schedule.
Weight decay supplies a parameter-shrinkage contribution to an optimizer update, with a coefficient commonly denoted . Two implementations must be distinguished. Coupled L2 regularization adds the penalty to the objective function, replacing its data gradient by . Decoupled weight decay applies parameter shrinkage separately from the optimizer's processing of the data gradient. These operations are equivalent for plain gradient descent with matched coefficients, but not in general for an adaptive gradient method.[ref]
Decoupled Weight Decay Regularization by Ilya Loshchilov and Frank Hutter. Version3, section2, propositions1–2 and AppendixA
Use the PyTorch convention here: a decoupled update shrinks parameters by , where is the learning rate. A source writing instead has absorbed the step-size factor into its decay coefficient. For an unmodified gradient step,In AdamW, the decay contribution does not enter the stored first- or second-moment estimates of the gradient.[ref]
AdamW in the PyTorch documentation. PyTorch2.15, algorithm, separate parameter-decay line and moment updates
An original fixed-scaling example exposes the difference. Let , , , and diagonal matrix . Applying the same scaling to the entire coupled gradient givesSeparating uniform parameter shrinkage givesThe second coordinate receives different shrinkage. This is an illustrative fixed matrix, not a full AdamW simulation. With history-dependent scaling, coupling the penalty into the gradient can also alter the optimizer state. State the update equation and coefficient convention when reporting a decay setting; the label alone does not specify either.
Decoupled weight decay applies a parameter-shrinkage contribution separately from the optimizer's processing of the data gradient. Write for the processed data-gradient direction, including any algorithm-specific optimizer state. Using the coefficient convention documented for PyTorch AdamW,The shrinkage term uses the pre-update parameter and is not inserted into the gradient moments.[ref]
AdamW in the PyTorch documentation. PyTorch2.15, algorithm: separate parameter-decay line before the adaptive update
This differs from coupled L2 regularization, which processes as a single gradient input. Decoupled weight decay was introduced for adaptive optimization in the AdamW work; the original paper also writes decay coefficients with the learning-rate factor absorbed differently, so its coefficient must be translated before comparing equations.[ref]
Decoupled Weight Decay Regularization by Ilya Loshchilov and Frank Hutter. Version3, section2 and Algorithm2
An original limiting case isolates the shrinkage. Suppose the processed direction is zero at every step and are constant. Repeated substitution givesWith , and , one update gives 0.98 and 50 updates give approximately 0.36417. For varying learning rates, the corresponding factor isThus the same numerical decay coefficient can have a different accumulated effect under a different learning rate schedule. In this zero-direction model, gives sign-preserving shrinkage; other factors have different behaviour.
The update order is also part of the definition. For , , and , the stated formula gives . Applying shrinkage after first taking the gradient step would instead give . Both operations may be described informally as decay plus a step, but they are different recurrences. An optimization checkpoint must retain the relevant state and settings to reproduce the chosen one.
Coupled L2 regularization adds a quadratic parameter penalty to the objective function and sends its gradient through the same optimizer update as the data gradient. With coefficient , defineSince the gradient of the squared Euclidean norm divided by two is , a supplied data gradient becomesThe factor fixes the convention: a penalty written as instead contributes .
For plain gradient descent, this substitution givesIt is therefore equivalent to decoupled weight decay with the matched coefficient in this particular update. The equivalence need not survive coordinate-dependent processing of the gradient.[ref]
Decoupled Weight Decay Regularization by Ilya Loshchilov and Frank Hutter. Version3, section2, propositions1–2 and AppendixA
For an original fixed-scaling example, let , , , and diagonal matrix . Applying to the whole coupled gradient givesThe same quadratic penalty produces unequal coordinate shrinkage after this scaling. Uniform decoupled weight decay would instead give . The example isolates a fixed scaling operation, rather than claiming to simulate a complete adaptive gradient method.
Coupling can also change the optimizer state. For example, a momentum buffer formed from stores contributions from along with the data gradient. If an adaptive accumulator uses squared gradient entries, it receives , including a cross term . Subsequent updates can therefore differ even when the next data gradient is the same. State both the penalty convention and the optimizer's gradient-processing rule when describing an L2 setting.
The optimizer state is information retained by an optimization algorithm beyond the current parameter values. It can include a momentum buffer and algorithm-specific counters or running estimates. Consequently, two runs with identical parameters and current gradients can produce different next optimizer updates if their stored states differ.
For an original scalar example, minimize with the recurrenceThis is the momentum form with dampening, decay and the
nesterov flag disabled in the PyTorch stochastic gradient descent implementation.[ref]SGD in the PyTorch documentation. PyTorch2.15, algorithm pseudocode; momentum and dampening description
At , and , a stored gives and . A stored instead gives and . The current parameter and gradient were identical; the difference came from history.An optimization checkpoint that saves only the parameters cannot reproduce that next step. In PyTorch,
Optimizer.state_dict() stores per-parameter state and parameter-group settings such as learning rate, but not the parameter values themselves. Its parameter identifiers associate state with ordered parameter groups and are not a check of semantic parameter identity during loading.[ref]torch.optim in the PyTorch documentation. PyTorch2.15, Optimizer.state_dict API, state/param_groups entries and loading note
Save and restore the corresponding parameters separately and keep the state-to-parameter association consistent. Reproducing an entire training run may additionally require the data order and other changing state.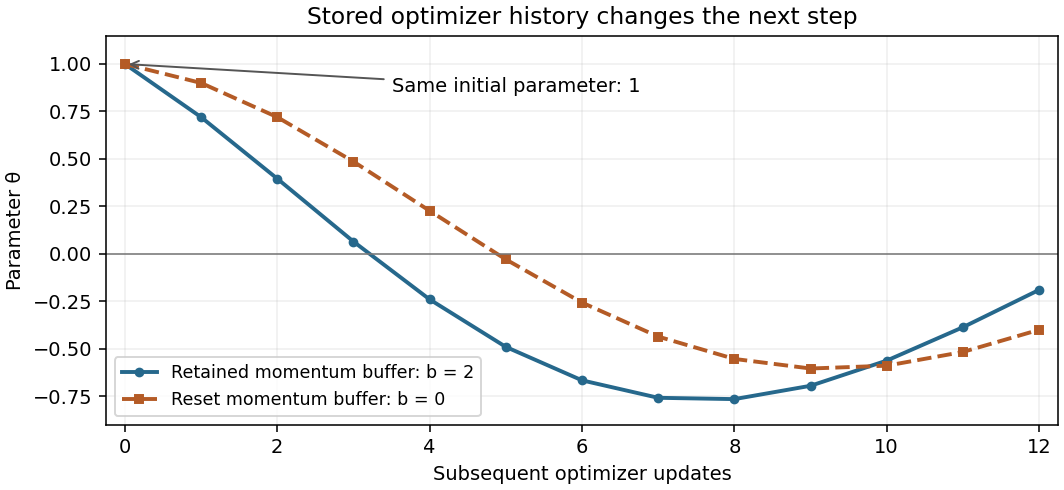
Original deterministic quadratic model: keeping or resetting the momentum buffer gives different trajectories from the same parameter value
. Details. 
An optimization checkpoint is a saved description of an ongoing optimization algorithm from which its optimizer updates can resume. It combines the current parameters with the relevant optimizer state. The practical criterion is optimizer restart equivalence: after restoring the saved information and supplying the same subsequent inputs, the chosen update rule should produce the same subsequent states.
For a deterministic scalar example, minimize the quadratic function with gradient , learning rate and momentum buffer recurrence , followed by . Start with . After one step the saved pair is . Restoring both gives and . Restoring only and initializing a new momentum buffer to zero gives and . Equal saved parameters can therefore lead to unequal continuations. These numbers are an original calculation for the declared recurrence.
In PyTorch, a general training checkpoint commonly serializes separate model and optimizer dictionaries, together with the training position. The model dictionary contains learned parameters and registered model buffers; the optimizer dictionary contains its own changing state and group settings.[ref]
Saving and Loading Models in the PyTorch tutorials. What is a state_dict?; Saving & Loading a General Checkpoint for Inference and/or Resuming Training
Restoring the optimizer state-to-parameter association also matters: the optimizer loader pairs stored identifiers with parameters in group order, without independently establishing that they denote the same mathematical parameters.[ref]torch.optim in the PyTorch documentation. PyTorch2.15, Optimizer.state_dict, state/param_groups and loading note
The required checkpoint boundary depends on the computation being resumed. A changing learning rate schedule, the next position in the training data, and the state of a pseudorandom number generator can influence future updates. Matching them is part of computational reproducibility; a saved parameter vector alone does not specify the whole training process.
Optimizer state-to-parameter association identifies which parameter each saved piece of optimizer state belongs to. An optimization checkpoint can contain every stored number and still resume incorrectly if those numbers are attached to different parameters. Equal shapes and data types do not establish mathematical identity.
The PyTorch optimizer dictionary separates per-parameter state from parameter-group settings. Its loader pairs saved parameter identifiers with the current parameters in group order, without independently verifying the intended association.[ref]
torch.optim in the PyTorch documentation. PyTorch2.15, Optimizer.state_dict, state/param_groups and loading note
For an original two-parameter example, use and . Let the named parameters be and , their current gradients both be 1, and their saved momentum buffers be and . Correct restoration givesIf a reversed parameter ordering attaches the same saved buffers to the wrong scalar parameters, the result is insteadBoth buffers had valid scalar shapes, so a shape check would not expose this error.
Consistently permuting the parameters, gradients and state is merely a change of ordering; permuting only the state changes the algorithm's continuation. Record a stable parameter schema and group order with the checkpoint, and check any intentional remapping against that schema. Parameter values and optimizer dictionaries are distinct saved objects, so restoring one does not automatically restore the other's meaning.[ref]
Saving and Loading Models in the PyTorch tutorials. What is a state_dict?; Saving & Loading a General Checkpoint
Optimizer restart equivalence means that restoring an optimization checkpoint reproduces the uninterrupted optimizer's parameter sequence for a specified subsequent computation. State the optimizer update rule, continuation inputs and intended notion of equality. Exact mathematical equality and agreement within a numerical tolerance are different claims.
For a deterministic algorithm modeled by , equality of the restored full state at step , together with the same update rule and future inputs , is sufficient. One application of gives equal next states; mathematical induction then gives equal continuations. This is a sufficient condition for the chosen observations, not a claim that every internal field must always affect them.
For an original exact example, take andFrom , one step gives . Restoring that pair gives and , exactly as uninterrupted execution. Resetting the buffer while restoring gives and . Thus a parameter-only save is not restart-equivalent for this recurrence.
Practical checkpoints must also retain the optimizer state-to-parameter association and the relevant settings, update position, learning rate schedule, data position and pseudorandom number generator state.[ref]
Saving and Loading Models in the PyTorch tutorials. General checkpoint for resuming training: model and optimizer dictionaries and training position
Fixing a random seed alone does not specify all of this continuation. Floating-point arithmetic and nondeterministic operations can additionally affect exact reproduction across environments; the primary documentation does not guarantee identical results across releases or platforms.[ref]Reproducibility in the PyTorch documentation. PyTorch2.15, opening reproducibility statement and controlling randomness
A momentum buffer stores an accumulated history of gradients for an optimization algorithm. In one common convention, a parameter vector , supplied gradient , learning rate and constant coefficient obey the recurrence relationThe buffer belongs to the optimizer state: it remembers earlier inputs even when the current parameters are unchanged. This is the undampened momentum convention used by PyTorch stochastic gradient descent with weight decay and the Nesterov accelerated gradient method disabled; its documented first buffer is the first gradient, agreeing with this recurrence from . Other conventions absorb the learning rate into the stored buffer, so a buffer value needs its update convention to be interpreted.[ref]
SGD in the PyTorch documentation. PyTorch2.15, algorithm and note comparing momentum conventions and first-step initialization
Repeated substitution gives the exponentially weighted gradient historyTo verify this identity, substitute its expression for into : multiplication by raises every old exponent by one, and the added is precisely the new exponent-zero term. The formula holds at because its sum is empty, completing the mathematical induction.
For an original scalar example with and a constant supplied gradient , the geometric series yields . At , and the limit is 10. The buffer is an unnormalized sum: multiplying it by changes its scale, and would require a corresponding learning rate adjustment to preserve these parameter updates.
The same memory explains why momentum can temporarily oppose the current gradient. If , and the new scalar gradient is , then . With a positive learning rate, the parameter still decreases, although the present negative gradient alone would call for an increase. Persistence can carry motion through rapidly alternating gradients, but this example also shows why the rule need not decrease the objective function at every step.
A momentum buffer can retain enough earlier history that it points against the current gradient. For the undampened rulethe parameter step is for positive learning rate . If , then the directional derivative in direction is . The actual update direction is therefore locally uphill for a differentiable objective function, even though gradient descent would use the opposite direction. This history-dependent recurrence is the non-Nesterov momentum convention documented for stochastic gradient descent with dampening and weight decay disabled.[ref]
For an original scalar example, let , current , stored buffer , coefficient and . The new gradient is 1, butThe objective increases from to . This is a fully specified finite step, not only a first-order prediction.
More generally,An old buffer sufficiently opposed to the new gradient makes this negative. At , that mechanism disappears. The example explains why a momentum method need not decrease the objective at every step; it does not imply that retaining gradient history always harms convergence. A descent direction test concerns the direction at the current point, while a convergence claim concerns an entire sequence.
An exponentially weighted gradient history assigns geometrically decreasing coefficients to older supplied gradients. For constant and momentum buffer recurrence ,Each additional update multiplies an old contribution by . The formula follows by substituting the expression for into the recurrence and adding the newest exponent-zero term. The same undampened recurrence, including its initialization convention, appears in the primary stochastic gradient descent documentation.[ref]
SGD in the PyTorch documentation. PyTorch2.15, momentum algorithm and first-buffer initialization note
For an original example, choose , and gradients , , . Successive buffers are 2, −1, 3.5. Directly expanding the third buffer givesThe newest contribution has coefficient 1; the oldest has coefficient 1/4. The buffer is a weighted sum, not yet a weighted mean. At , its coefficient sum is the geometric seriesHere , so the normalized weighted mean is , rather than the ordinary mean .
The coefficients also give a concrete memory scale. In the infinite geometric sequence, the fraction assigned to the newest gradients is . At , 29 gradients account for at least 95% of that coefficient mass, because whereas . This is a statement about coefficients, not a guarantee that gradients at different times are independent or that the optimizer averages a stationary process.
Articles by others on the same topic
There are currently no matching articles.