Numerical analysis designs algorithms that approximate mathematical answers while controlling cost and error. Its central question is how much of a computed answer can be trusted. Finding a zero of a function, evaluating an integral, solving a linear system, and evolving an ordinary differential equation all demand choices about accuracy, work, and the information available. MIT's numerical-methods course explicitly treats performance and accuracy as joint concerns.[ref]
https://ocw.mit.edu/courses/18-335j-introduction-to-numerical-methods-spring-2019/pages/week-1/. Steven G. Johnson, MIT 18.335J, Week 1, 2019
Three questions organize error analysis. Truncation error measures the approximation introduced by an algorithm even in exact arithmetic; roundoff error comes from finite precision; the condition number measures sensitivity inherent in the problem. Numerical stability asks how the chosen algorithm propagates perturbations. These distinctions suggest different remedies: refine an approximation, change precision or arithmetic, or improve the accuracy of the input.
For example, the square root has relative condition number for : a small relative change in produces about half that relative change in . In contrast, has relative condition number . Changing to changes to about : an input change of about produces an output change of about . This sensitivity exists even with exact arithmetic. MIT's conditioning lecture separates the condition number from roundoff error in precisely this way.[ref]
https://ocw.mit.edu/courses/18-335j-introduction-to-numerical-methods-spring-2019/pages/week-2/. Steven G. Johnson, MIT 18.335J, Lecture 5: Condition Numbers, 2019
Lloyd's algorithm alternates two updates to reduce squared-distance distortion for a fixed number of centers: assign each data point to a nearest center, then replace each nonempty cluster's center by its arithmetic mean. For a probability distribution, the corresponding center is the conditional expectation on the assigned region. The scalar quantization problem was the motivation in Stuart P. Lloyd's paper.[ref]
Least Squares Quantization in PCM by Stuart P. Lloyd. Sections IV–VI, printed pages130–132, equations14 and17 and Quantization Procedures
Write the objective as , where identifies the assigned center. With centers fixed, each point minimizes its own contribution by choosing a nearest center. For a nonempty cluster , its arithmetic mean satisfiesThus the center update minimizes the contribution for fixed assignments. Both steps make nonincreasing, but this does not guarantee a global minimum.
An original example makes initialization matter. For the six scalar data points , two initial centers give a boundary at . Assign the tied value to the first center. The clusters become and , with means . Their new boundary is , preserving the assignments, and .
Instead initialize at . The boundary gives clusters and . Their means have boundary , again preserving the assignments, but now . This second fixed configuration cannot be globally optimal because the first is a better feasible configuration. Lloyd explicitly distinguishes stationary configurations from the absolute optimum.[ref]
Least Squares Quantization in PCM by Stuart P. Lloyd. SectionVI and AppendixB: necessary conditions, saddle points and multiple minima
An implementation must specify tie handling and what to do with empty clusters, whose arithmetic means are undefined. Objective decrease is a useful check; it does not certify discovery of a unique underlying grouping.
A pseudospectral method represents an approximate solution through a global basis or its interpolating values and imposes equations at selected collocation points. In a periodic problem the basis is often a Fourier series; on an interval, polynomial collocation is common. The adjective spectral refers to the representation, not to computing the eigenvalues of an arbitrary matrix.[ref]
Spectral Methods in MATLAB by Lloyd N. Trefethen. Author's description and sample chapters on spectral differentiation and collocation
For periodic data at , the discrete Fourier transform gives coefficients of a trigonometric interpolant. Its derivative is obtained by multiplying coefficient by and transforming back. For nonlinear equations, products can be evaluated on the physical grid, while derivatives are computed in Fourier coordinates. A Fast Fourier transform makes these representation changes efficient.
The grid can confuse unresolved frequencies with resolved ones. With , take . Its exact square isAt the eight grid points, , so the sampled product appears to contain wave number instead of . This is aliasing created by the nonlinear product, even though the input wave number was representable. Additional grid resolution, padding or appropriate filtering is needed when such products are used to evolve retained modes.
For sufficiently smooth solutions, spectral representations can converge rapidly as resolution increases. Discontinuities, boundary incompatibilities and unresolved fine structure change that behavior. A pseudospectral method therefore needs checks on both approximation error and the nonlinear operations performed on its grid.
Operator splitting approximates evolution generated by a sum of operators through separate evolutions of its parts. For bounded matrices , one step of the Lie product approximation to isExpanding both matrix exponentials gives . Thus noncommutativity creates the leading local error; if and commute, the step is exact.
The symmetric composition cancels the quadratic local error and has local error for bounded matrices. With suitable stability over a fixed time interval this gives second-order global accuracy. In a reaction-diffusion equation, separate reaction and diffusion substeps can each use a method suited to that process. For unbounded differential operators, boundary conditions and regularity require additional analysis rather than a formal transfer of the matrix calculation.[ref]
Splitting methods with complex coefficients by Sergio Blanes and others. Introduction, Lie-Trotter and Strang compositions
Approximation theory asks how well members of a chosen class can represent a target function, using a specified measure of error. For a norm and an approximation space , a fundamental quantity is . The choice of norm distinguishes controlling the worst error from controlling an average squared error.
For on , approximate by a constant . The uniform norm error is , minimized at with error . Under the squared L2 space error, differentiating gives the different optimum . Neither constant is universally best: each solves a different problem.
Polynomial approximation, Fourier series and splines provide different approximation classes. Smoothness of the target controls attainable rates, while numerical conditioning controls whether a representation can be computed reliably. A small best-approximation error alone does not guarantee a stable algorithm.
A general linear method advances an ordinary differential equation using internal stages and a retained external vector . For an autonomous equation , its block form isWith stages and external components, have sizes , , , respectively.
The retained components can encode previous values or derivative information. Runge-Kutta and linear multistep methods fit this framework. With one scalar stage and external component, , gives explicit Euler. The word linear describes these combinations, not a requirement that the differential equation itself be linear.[ref]
A time-stepping method approximates the evolution of an ordinary differential equation by successive updates at discrete times. It can be applied after a spatial finite element method has converted a time-dependent partial differential equation into an ordinary differential equation system. The implicit time-stepping method is one class of such methods.
An implicit time-stepping method determines a new solution value through an equation involving that same value. A small-step contraction mapping argument often establishes local solvability when the vector field is Lipschitz continuous. Examples include the Backward Euler method, implicit Runge-Kutta methods and implicit linear multistep methods. Solvability of the update is a separate issue from stability of a numerical method.
Numerical differentiation estimates derivatives from finitely many function values, often by differentiating an interpolation polynomial or using a finite difference. Its error combines truncation error from the formula with errors already present in the sampled values and additional roundoff error. Decreasing the sample spacing can decrease truncation error while increasing the effect of uncertain values. This tradeoff is explained by the ill-posedness of numerical differentiation when only an absolute value-error bound is available.
Recovering a derivative from values controlled only in the uniform norm is an ill-posed problem: the differentiation map is not continuous in those norms. On , take . Then , while has uniform norm one for every . Arbitrarily small value perturbations can therefore conceal nonvanishing derivative changes.
Numerical differentiation can still be useful when additional smoothness bounds, a suitable sampling scale, or a regularization method control the admissible changes. The basic noise amplification by differentiation of a linear interpolant gives a finite-data version: endpoint uncertainty of size produces derivative uncertainty of order at spacing .
For linear interpolation at zero and , an error in the second sampled value, with the first exact, changes the linear interpolant by . On , its uniform norm is exactly , whereas the derivative change is the constant . With independent absolute bounds on both samples, the value change remains at most and the derivative change is at most , attained for opposite endpoint errors.
Thus bounded absolute sample noise can remain bounded under value interpolation while becoming unbounded under numerical differentiation as . Fixed nonzero sample noise also prevents exact convergence of the value approximation; stability against perturbations and convergence to exact data are different assertions. For a second-sample error with fixed , value convergence requires , while derivative convergence requires in little o notation, in addition to vanishing truncation error.
Discretization replaces a continuous mathematical problem by equations for finitely many unknowns. A spatial grid samples a function; a finite element method instead chooses coefficients in a finite-dimensional trial space. A time discretization supplies update equations at selected times. These choices specify what is computed, before any roundoff error is introduced.
For the heat equation , a uniform spatial grid givesThis is a semidiscretization: time remains continuous. Applying the Forward Euler method gives a fully discrete updateFor a smooth exact solution, the normalized local truncation error is . Convergence additionally requires stability of a numerical method; for this one-dimensional update, makes each new value a convex combination of neighboring values. Spatial and temporal refinement therefore interact, rather than giving two independent accuracy knobs.
Semidiscretization discretizes some variables of a differential equation while leaving others continuous. A spatial discretization of the heat equation gives interior grid values satisfyingBoundary values complete this ordinary differential equation system; time has not yet been replaced by a sequence of steps.
Applying explicit Euler later gives a fully discrete method with stability restriction for the standard uniform-grid diffusion model. Keeping the two stages separate makes spatial approximation error distinct from time-integration error and allows a different time solver to be used with the same spatial operator.[ref]
Finite Difference Computing with PDEs by Hans Petter Langtangen and Svein Linge. Chapter 3, spatial second differences and time-stepping diffusion
A method defining the next state through equations involving that unknown state. Solving these equations can be costly, while enlarged stability regions are useful for stiff problems.
A method whose next state is obtained from known stages without solving simultaneous equations involving the unknown next state. Stability may restrict its admissible step sizes.
A one-step method approximates an ordinary differential equation using the current approximate solution and evaluations within the next step. The function is its increment function. A Runge-Kutta method may use several intermediate stages while remaining a one-step method: it does not require additional previous solution values as a linear multistep method does. Its consistency error is the exact-start update defect divided by .
A Runge-Kutta method advances an initial value problem , , by sampling its vector field at several trial states within one time step. These samples are Runge-Kutta stages; a weighted combination of their slopes produces the next state. The construction improves on the single tangent line used by the Euler method while requiring evaluations of , rather than explicit higher derivatives of the solution. It applies to scalar equations and systems of ordinary differential equations alike. The coefficient choices distinguish methods such as Heun's method, the classical fourth-order Runge-Kutta method and implicit Runge-Kutta methods.
For stages, write for the stage matrix, for relative time nodes and for output weights. A time step of length computesHere is a slope, with units of state per time; is a state increment. Another common convention writes , so its stage states are and its output is . These are equivalent conventions: including both inside and again in the output would count the time step twice. The textbook formulation uses the increment convention.[ref]
6.4 Runge-Kutta methods. Fundamentals of Numerical Computation, §6.4.3, equations 6.4.10–6.4.11: multistage recipe and tableau
Usually the Butcher tableau obeys , called internal consistency. Stage then combines slopes over an effective time . The second-order conditions with independent Runge-Kutta abscissae explain what changes when time nodes are specified independently. A Runge-Kutta stage is generally an auxiliary approximation, not a separate accepted solution value at its node. Several stages can even have the same time node but different state arguments, as in the classical fourth-order Runge-Kutta method.
The useful idea is to approximate the integral without knowing the intermediate exact trajectory. Trial states provide places to sample , and Butcher order conditions make the resulting combination agree with the exact Taylor expansion. More stages alone do not guarantee a higher order of a numerical method: their coefficients must satisfy the appropriate conditions. Embedded Runge-Kutta pairs reuse these same samples for a second output and a practical local error estimator.
A Runge-Kutta stage consists of a trial state at the time node and the corresponding vector field evaluation . In the slope convention, . Stages belong to the construction of one Runge-Kutta method step; they need not have the same accuracy as its final output. Stage states can leave the physically allowed region even when the endpoint lies inside it, so must be defined at every stage used.
An explicit Runge-Kutta method has whenever . Its stage matrix is strictly lower triangular: compute each Runge-Kutta stage using already known slopes, starting with . In contrast, an implicit Runge-Kutta method requires solving coupled stage equations, whose existence is addressed by stage solvability of an implicit Runge-Kutta method.
Here Heun's method means the explicit endpoint-averaging Runge-Kutta method: take an Euler predictor , sample there, and average it with for the output. The second Runge-Kutta stage is evaluated at the predictor, not at the corrected endpoint. In particular it requires no implicit solve as the ODE trapezoidal rule does. Naming conventions vary between books; the formulas specify the method unambiguously.[ref]
Numerical solution of ordinary differential equations: One step methods by André Jürgen Massing. André Massing, Numerical solution of ordinary differential equations: One step methods, October 3, 2021, page 1, Example 1.1: Euler and Heun increment functions
For smooth , a Taylor expansion about gives , where is the state Jacobian matrix. Consequently the output is , matching the exact solution through degree two by the chain rule. This gives local truncation error and, with the usual bounded smoothness and Lipschitz continuity hypotheses on a fixed finite interval, global error . The Euler-Heun embedded pair compares this output with its Euler predictor.
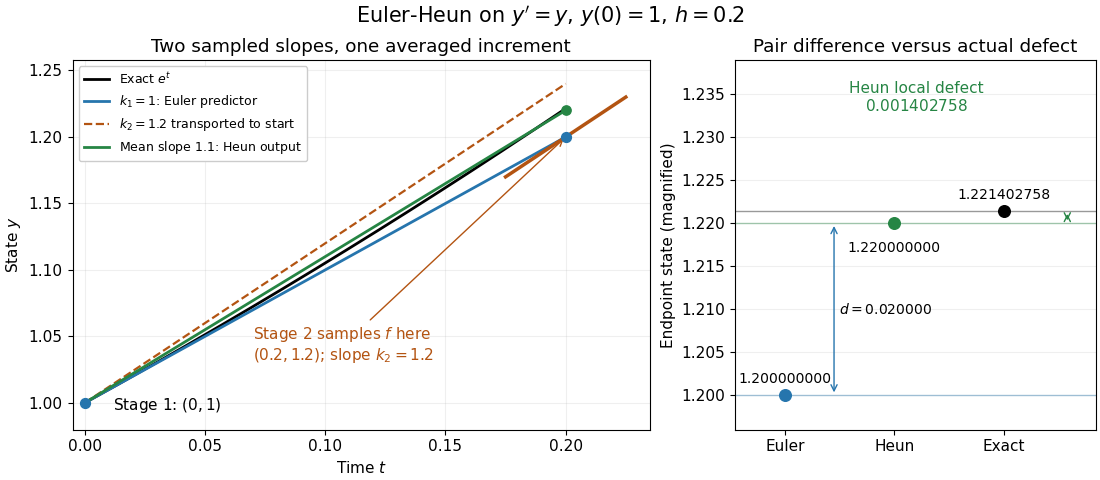
Euler-Heun stage geometry for y prime equals y: sample at the Euler predictor, then average slopes for the corrected endpoint
. Details. For , and , the sampled slopes are and . Transporting the second slope to the starting point would end at ; the average slope instead ends at . The exact exponential function reaches . The magnified endpoint comparison separates the pair difference from the actual Heun local defect .
An -stage Runge-Kutta method has stability function , a rational function with numerator and denominator degrees at most . Order forces , so uniqueness of the diagonal Padé approximant identifies with . That approximant has no poles in the closed left half-plane and modulus at most one there. Hence every such maximal-order method is A-stable. Since the Padé approximant numerator and denominator are coprime and both have degree , the original stage determinant cannot have hidden canceled poles in that half-plane.
This one-step family interpolates between the Forward Euler method at , the trapezoidal rule at , and the Backward Euler method at . Its stability function is . It is first order except at one half, where it is second order. Applying it to spatial diffusion gives the theta diffusion stability criterion.
On an orthogonal diffusion eigenmode, the theta method has the displayed amplification with . The identity proves contraction at all nonnegative exactly when . For , contraction holds up to , with a positive denominator in that range. Orthogonality is what transfers these modal bounds to a full L2 norm estimate.
At , arbitrarily stiff heat modes approach amplification : the Crank-Nicolson method is contractive but does not rapidly damp unresolved rough components. The Backward Euler method instead has limit zero. Thus unconditional linear stability and strong stiff decay are different requirements. High smooth-data consistency order alone does not imply a uniform high-order estimate down to the initial instant for arbitrary L2 initial conditions.
A strong stability preserving Runge-Kutta method writes its stages as convex combinations of previously computed states and suitable Forward Euler method steps. It transfers any convex-functional nonincrease property of the forward step, such as a norm bound, under a proportionally scaled time-step restriction.
For example, if is nonexpansive in a norm, then and is also nonexpansive: the triangle inequality bounds the new difference by one half of the initial difference plus one half of the twice-advanced difference. Both are at most the initial difference. A Taylor expansion yields , so this is a second-order Runge-Kutta method. The forward-step hypothesis must hold on the stage states; preservation of one chosen convex bound is not the same as unconditional B-stability.
The classical four-stage explicit Runge-Kutta method usesIt satisfies the fourth-order conditions for a Runge-Kutta method. Its polynomial stability function excludes A-stability, while gives the imaginary-axis stability interval .
A Butcher tableau records a Runge-Kutta method's stage matrix , time nodes , and output weights in the block arrayRead row above the line as the recipe for Runge-Kutta stage : the left entry gives , and the right entries give the coefficients in . Below the line, weights slope in the final update. Zeros on and above the diagonal identify an Explicit Runge-Kutta method. For the internally consistent convention, row sums of equal ; first-order consistency of a numerical method also requires . An embedded Runge-Kutta pair adds another weight row while retaining .
A Butcher order condition equates the coefficient assigned by a Runge-Kutta method to a rooted tree with the corresponding exact Taylor coefficient. Satisfying every condition through tree order is equivalent to Runge–Kutta order at least .
For a general nonautonomous Runge-Kutta method, Taylor expansion of stage gives . Matching the exact increment gives the three displayed conditions. When internal consistency is imposed, the last two coincide. Internal consistency is a usual tableau convention, but is not logically necessary for order two of a generalized tableau.
With and , a Runge-Kutta method has order at least four exactly when the eight Butcher order conditionshold; powers of are componentwise. These conditions match the numerical and exact coefficients indexed by rooted trees through order four. Matching the scalar Dahlquist test equation alone is insufficient to check the nonlinear Butcher order conditions.
An implicit Runge-Kutta method defines at least one Runge-Kutta stage using an equation that involves that stage or a later unresolved stage. In the slope convention,An Explicit Runge-Kutta method has strictly lower-triangular , so the slopes are computed sequentially. An implicit tableau instead requires one or more algebraic solves, usually nonlinear when the vector field is nonlinear. Existence, uniqueness and numerical accuracy of those solves are additional requirements; A-stability of the scalar test equation does not establish them.
For the implicit midpoint rule, and . On with , the stage is and the update factor is . This linear example needs only one division, whereas a nonlinear generally requires an iterative solve. The stage solvability of an implicit Runge-Kutta method gives a sufficient small-step contraction condition.
For stages and with update , the method has order two for every fixed real . The third-order coefficient of is always , not , so no parameter gives third order on general nonlinear equations. The displayed stability function is bounded throughout the left half-plane only when , when it is the A-stable trapezoidal function . It is not L-stable.
For a vector field uniformly Lipschitz continuous in the state with constant , the stage fixed-point map of an implicit Runge-Kutta method is a contraction in the maximum stage norm if . The contraction mapping theorem then gives unique stages. This is a sufficient small-step condition; a dissipative vector field may permit solvability for larger steps. An algebraic stability or B-stability estimate compares existing stage solutions and should not be mistaken for an unqualified stage-existence theorem.
The implicit midpoint rule advances an autonomous ordinary differential equation byIt is a second-order, A-stable, time-symmetric numerical method.
The implicit midpoint rule is the midpoint method with . It is a one-stage implicit Runge-Kutta method.
For a uniformly Lipschitz continuous state field with constant , an implicit midpoint rule step is uniquely solvable when , by the contraction mapping theorem. Write its step map as , where . Subtracting the increment equations givesTherefore , and the triangle inequality gives the bound for . Combining it with the implicit midpoint consistency bound yieldsfor . This follows by summing the geometric error recurrence with forcing . For and , , proving second-order global error with exact starting data. If , the direct bound is .
For an exact solution , define the normalized local truncation error of the implicit midpoint rule byIf , and the state Jacobian matrix of has operator norm at most on the intervening state segments, then the displayed bound holds uniformly on a fixed finite interval. To prove it, put . Symmetric Taylor expansions giveFor the first bound, integrate the second-order remainder of over the symmetric step; for the second, average the second-order remainders of at the endpoints. The odd terms cancel. The Lipschitz condition for and finish the proof by the triangle inequality. The unnormalized step residual is .
The Crank--Nicolson method applies the trapezoidal rule to a semidiscrete evolution equation. For a linear system its update is
For symmetric negative semidefinite matrices , each factor has norm at most one, since its eigenvalues are with . The same holds for , so their ordered product is a contraction for every , whether or not commute. This proves unconditional discrete L2 norm stability of the split Crank-Nicolson method for directional diffusion. Its splitting error remains first order in general, because the product's quadratic defect is .
Given distinct nodes , a collocation Runge-Kutta method uses the Lagrange basis with and . Its stages enforce the differential equation at the collocation nodes.
This applies the collocation method to the time-step polynomial of an ordinary differential equation.
For distinct nodes , the two-stage collocation Runge-Kutta method has stability functionThe denominator has no zeros in the closed left half-plane. On the imaginary axis the denominator's squared modulus minus the numerator's is . Thus , equivalently , is necessary and sufficient for A-stability, using the maximum modulus principle and the bound at infinity.
For distinct collocation nodes, let . If for , and the next moment is nonzero, the associated interpolatory quadrature has order , and the collocation Runge-Kutta method has the same classical order for sufficiently smooth differential equations. Here . Equivalently, if the quadrature is exact through degree but not degree , the method has order . The generic order is at least , Gauss collocation methods reach , and Radau IIA methods reach .
For collocation nodes, the residual of the collocation polynomial vanishes at each node and contains the factor . Quadrature exactness through degree implies for every polynomial of degree at most . Expand the smooth vector-field interpolation error and the derivative of the exact flow in powers of the step. Every endpoint-error term of degree below has this vanishing weighted moment, so the endpoint local error is , although the interior stage accuracy is generally only . A step Lipschitz estimate and discrete Gronwall inequality then give global order . Gaussian nodes attain , while the first nonexact quadrature moment bounds the order from above.
For a collocation Runge-Kutta method, , where the Lagrange interpolation basis obeys . Hence each row sum is its collocation node. Failure of this identity disproves a claimed collocation tableau with those nodes. The identity alone is necessary rather than sufficient: the individual integrated basis coefficients must also agree.
A Lobatto IIIA method collocates at the Lobatto quadrature nodes, including both endpoints of the time interval. Its three-stage version hasThe Butcher order conditions give order four. Its stability function iswhich is A-stable but not L-stable. It is not algebraically stable: the first diagonal entry of the defining matrix is . This distinguishes linear A-stability from nonlinear algebraic stability.
The -stage Gauss--Legendre Runge--Kutta method collocates at the Gauss--Legendre quadrature nodes on . It is symmetric, A-stable, and has order .
Choose as the polynomial roots of in , and form the Lagrange interpolation polynomials . The Gauss collocation method has and . This gives explicit coefficient formulas after finding polynomial roots: if , these integrals are and . Gaussian quadrature gives order .
The two-stage Gauss--Legendre Runge-Kutta method uses nodes , weights and coefficients , , . The Butcher order conditions give order four. Its stability function is the displayed rational function, which is A-stable. The algebraic stability matrix is zero, so positive weights also give nonlinear contractivity for dissipative vector fields.
An -stage Radau IIA method collocates at the right-endpoint Radau nodes. It has order and is both algebraically stable and L-stable.
Suppose an -stage Runge-Kutta method has order , an invertible matrix , and . Its stability function is . The adjugate matrix formula gives a rational function with denominator degree and numerator degree at most ; its zero limit at infinity lowers the latter degree to at most . The order of a numerical method gives , identifying the Padé approximant. Uniqueness follows because the cross-multiplied difference of two candidates has degree at most but a zero of order at least , so is identically zero. The A-stability of near-diagonal exponential Padé approximants then proves A-stability, and the zero limit proves L-stability. These conditions identify the stability function; they do not alone claim uniqueness of all entries of the Runge-Kutta method tableau.
A Runge-Kutta method is algebraically stable when and the matrix with is positive semidefinite. Algebraic stability implies contractivity for dissipative differential equations.
For stage states and a vector field with , expansion of the new squared norm gives , where . Hence preserves the quadratic form exactly for every well-defined step. The same argument with a fixed symmetric matrix in the inner product preserves any quadratic invariant of the vector field. In particular it preserves the Euclidean norm for a skew-symmetric matrix differential equation.
An algebraically stable Runge-Kutta method is B-stable: for a dissipative vector field, a well-defined step cannot increase the distance between two starting values. This assumes that the compared stage equations have solutions, as required by stage solvability of an implicit Runge-Kutta method. The Runge-Kutta contractivity identity expresses the distance change as a nonpositive weighted term coming from the dissipative vector field minus a nonnegative quadratic form involving the matrix defining algebraic stability. Positive weights also rule out stage poles in the open left half-plane on the scalar test equation, giving A-stability there; zero-weight redundant stages need separate solvability attention.
For differences between corresponding stages and differences between their vector fields, a Runge--Kutta step satisfiesTo derive the identity, expand the squared norm of and substitute in the linear term. Symmetrizing the double sum gives the displayed coefficients . For a dissipative vector field, the first sum is nonpositive when , and the second sum is nonnegative when the matrix is a positive semidefinite matrix. Thus algebraic stability implies B-stability.
As a quadrature rule, the trapezoidal rule replaces an integrand by the linear interpolation joining its two endpoint values:For nonnegative endpoint values, this is the area of a trapezoid; in general it is a signed area. The quadrature nodes are , each with quadrature weight . Unlike the midpoint quadrature rule, it uses endpoint samples, which can be reused between adjacent panels.
Every affine function agrees with its linear interpolation, so the trapezoidal rule integrates it exactly. On , gives . On , the polynomial instead gives , exceeding by . Its degree of precision of a quadrature rule is exactly one.
If , its signed approximation error satisfiesA convex function lies below its endpoint chord, so the trapezoidal rule overestimates its integral; a concave function gives the reverse inequality. The error formula assumes that the second derivative exists and is a continuous function throughout the closed interval.[ref]
3.5 Quadrature, subsection (i) Trapezoidal Rules. §3.5(i), equation 3.5.1 and its C² hypothesis; the source writes integral minus rule
A short derivation is the identityobtained by two integrations by parts. The nonnegative Peano kernel has integral , and the weighted mean value theorem for integrals gives the formula.The trapezoidal rule for an ordinary differential equation averages vector fields at the old and new states and is A-stable.
This time-stepping use applies the same trapezoidal rule to the integral of the derivative in an ordinary differential equation. That connection explains its place under implicit Runge-Kutta methods; its quadrature behavior and the nonlinear issue in trapezoidal rule fails B-stability concern different uses of the same endpoint averaging.
For with , the trapezoidal rule satisfies the displayed bound, and the constant is best possible. The polynomial interpolation error for the endpoint linear interpolant satisfies , where . Integrating this inequality and using the triangle inequality for an integral proves the bound because . Equality holds for : the exact integral is , its trapezoidal rule estimate is , and .
On an equal-panel partition of an interval, with , sum the trapezoidal rule over adjacent panels:There are distinct quadrature nodes. Each interior sample belongs to two panels and therefore has quadrature weight , while each endpoint has quadrature weight . Equivalently, the composite trapezoidal rule integrates the piecewise linear function obtained by linear interpolation exactly.[ref]
For and , summing panel quadrature errors givesfor some . Thus panel quadrature errors of order accumulate to order , using big O notation.[ref]
3.5 Quadrature, subsection (i) Trapezoidal Rules. §3.5(i), equations 3.5.2–3.5.3: composite formula and signed error
On a nonuniform partition of an interval with widths and largest width , the bound is .For the polynomial on , direct summation yieldsBoth quadrature errors shrink by exactly four when doubles, with opposite signs. This exact relation belongs to this polynomial example; the trapezoidal rule is not always twice as inaccurate as the midpoint quadrature rule.
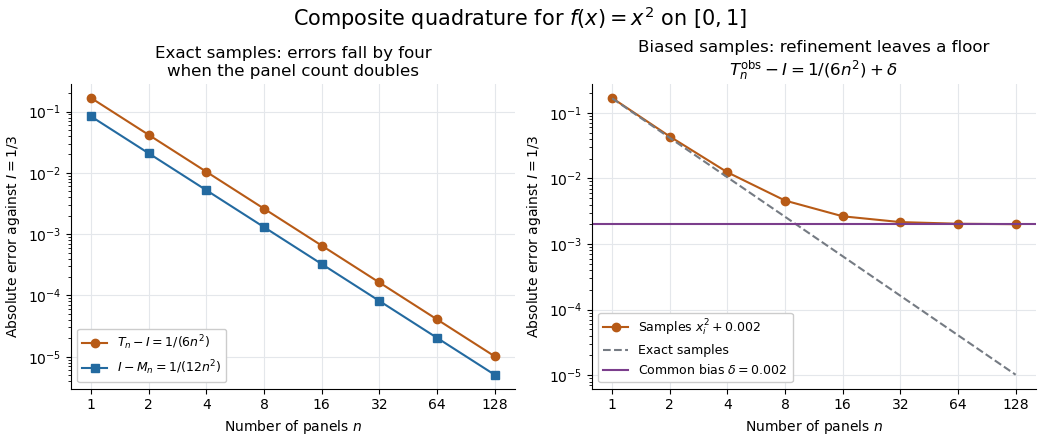
Quadratic quadrature errors fall by four on refinement while a common sample bias persists
. Details. The left plot uses exact polynomial sums; the right adds a common sample bias to the composite trapezoidal rule. That mathematical model converges to , showing why smaller panels alone do not ensure accuracy for noisy samples. It illustrates noise sensitivity of a quadrature rule, rather than measured data.
On a partition of an interval symmetric about zero, the composite trapezoidal rule gives opposite quadrature nodes equal quadrature weights. Samples of an odd function cancel pairwise, and a zero quadrature node contributes zero. For a continuous odd function, its exact integral over is also zero. Adding any affine function preserves exactness by linearity of the integral and of the quadrature rule. For example, is nonpolynomial but both the exact integral and every uniform-grid composite trapezoidal rule value on are two.
On a uniform partition of with width , the right Riemann sum and the composite trapezoidal rule have equal weights at every interior mesh point. They differ only by adding half a final-endpoint weight and removing half an initial-endpoint weight. This proves the displayed identity. For continuous , both converge to its definite integral; their finite endpoint correction need not be confused with the smaller trapezoidal discretization error for a smooth integrand.
If is twice continuously differentiable on , take a uniform bound . On one panel , two integrations by parts give the signed quadrature errorThe nonnegative kernel has integral , so the absolute error is at most . Summing equal panels proves the displayed bound. The maximum exists on the closed interval; a supremum or any known uniform bound also suffices. The estimate certifies a sufficient panel count, which need not be the least count achieving a particular actual error.
The trapezoidal rule is A-stable but is not B-stable. For the dissipative vector field at step size one, its uniquely defined step map obeys . At , and implicit differentiation gives , so nearby states expand rather than contract. This is a concrete nonlinear obstruction, rather than merely failure of the sufficient algebraic stability criterion.
A time-symmetric numerical method is a one-step numerical method with a locally invertible step map satisfyingFor a nonautonomous ordinary differential equation, include time in the state or explicitly reverse the step's time endpoints. The definition means that applying the same rule backward undoes its forward step; it does not by itself claim small discretization error.
The implicit midpoint rule illustrates this directly: swapping and replacing by leaves its midpoint equation unchanged, wherever the local solve is unique. By contrast, forward Euler method has factor on , and the backward factor gives product , not one.
Assume a consistent method has a smooth integer-power local-error expansion of finite order , with nonzero leading defect . Composing its forward and backward steps leaves leading defect . Symmetry forces this coefficient to vanish. Thus is odd and is even. The finite leading-error and regular expansion assumptions are needed for this parity argument.
A Runge-Kutta method has classical order when its one-step map started from exact data agrees with the exact flow through powers for every sufficiently smooth ordinary differential equation. Its local truncation error is then , with a nonzero coefficient at that order for some problem if is the exact finite order.
For example, forward Euler method on , , returns , while the exact solution is . The first omitted term is quadratic, so the local error is and the method is first order. On a fixed time interval, Lipschitz continuity and a stable error-propagation estimate turn local defects into global error .[ref]
Numerical solution of ordinary differential equations: One step methods by André Jürgen Massing. One-step error analysis, Euler/Heun examples and local-to-global convergence
Matching the Dahlquist test equation checks only the linear stability expansion. The nonlinear Butcher order conditions must also hold; agreement on one scalar equation alone does not prove classical order. Stage accuracy is a separate property, so the number or individual precision of Runge-Kutta stages should not be substituted for the order of the final update.
For an explicit Runge-Kutta method with coefficients , put and let mean componentwise squaring. The conditions , , and match the exact flow expansion through degree three: the two cubic differentials are and . For sufficiently smooth vector fields these give local error and, under the usual finite-interval Lipschitz continuity assumptions, global error .
For a computed state and an exact state , an energy error is for a specified energy function . If the exact dynamics conserve , the reference is simply . This is a scalar diagnostic; it does not by itself bound position or phase errors.
For the unit-frequency harmonic oscillator , , the exact energy is . The Forward Euler method givesThus a fixed positive step produces systematic energy growth even though the exact oscillator has constant energy. A bounded oscillatory energy error has a different long-time meaning from such cumulative drift. Comparing methods also requires the same step size, reference trajectory and observation interval.
A manufactured solution is a deliberately chosen smooth function used to construct a differential equation problem with a known exact answer. Substituting it into the differential equation determines the forcing, while its boundary and initial values determine matching data. The resulting computation tests a numerical implementation against that answer.
For example, on , choose and consider the forced heat equationUse zero Dirichlet boundary conditions and initial data . Direct differentiation verifies that solves this problem. At a fixed final time, compute an error norm against on successively refined grids. A second-order spatial scheme should show a factor near four when the spatial step is halved, once time, solver and roundoff errors are smaller than the spatial error. This checks the implemented equations and their order of a numerical method; it does not establish that those equations model a particular physical system correctly.
An error norm measures a numerical error vector or error function in a specified norm. For nodal errors on a one-dimensional uniform grid of spacing , common choices areThe first controls the largest nodal error. The second approximates a continuum L2 norm on a fixed domain. For nonuniform grids, quadrature or finite-element mass weights replace the common factor .
Mesh weighting matters in a refinement study. If on cells of a unit interval with , then , whereas the unweighted Euclidean norm is . The latter grows solely because the number of entries grows. Compare the same norm on the same physical domain and, for an evolution problem, at the same physical time.
Vectorized numerical computation applies numerical operations to entire arrays of values instead of explicitly iterating over scalar entries. For a power series, constructing a vector of term indices, evaluating all corresponding terms and summing that vector is a vectorized evaluation. A loop over bounded blocks can control memory while preserving vectorized computation within each block.
A numerical algorithm is backward stable when its computed output is the exact output for input data perturbed by an amount comparable to the arithmetic's round-off error. The allowed input perturbations and their norm must be specified. A bound on backward error gives a forward error bound only after accounting for the problem's condition number. For example, a singular value decomposition with orthonormal computed outer factors is backward stable in the spectral norm if , with machine precision and a modest dimension-dependent constant .
Find a value satisfying for a given function. Methods include the bisection method, which retains a bracket around a root, and derivative-based iteration. Finding a root numerically is distinct from the root as a mathematical object.
Suppose is continuous on an interval, differentiable in its interior, and throughout the interior. If is a root in the interval and is another point in it, the mean value theorem gives for an intermediate point . Taking absolute values proves the stated bound from the residual of a root equation. This converts an observed residual into a stopping certificate, provided the evaluation error in that residual is also controlled.
The residual of a root equation at a proposed solution is the value . It measures violation of the equation, while the forward error measures distance from a chosen exact root. Rescaling rescales the residual of a root equation without moving its roots, so a small residual needs a scale or a derivative bound before it certifies a small forward error.
The secant method approximates a zero of a function by repeatedly taking the zero of a secant line through the two most recent sampled points. The formula follows by setting the line equal to zero. It requires distinct sampled positions and a nonzero difference of sampled values, unless a root has already been found. After initialization it needs one new function evaluation per step. Unlike bisection, it need not retain a bracket. For a sufficiently smooth function near a simple root, its usual local order of convergence is .[ref]
Fixed-point iteration seeks a fixed point of a map by repeatedly setting . Convergence requires additional hypotheses; for example, a contraction mapping on a complete metric space has a unique fixed point reached by this iteration.
Iterating an affine map gives . A fixed point exists exactly when is in the image of a linear map . If the spectral radius of is below one, its matrix powers tend to zero and every orbit converges to the unique fixed point .
An iteration converging to has exact asymptotic order if its nonzero errors satisfy the displayed limit. A bound instead asserts at least order . Finite termination is treated separately because the error ratios become undefined.
An iteration of a map has linear convergence to its limit when its nonzero errors satisfy for some . The error eventually shrinks by approximately the same factor at each step. This is exact order of convergence one, in contrast to quadratic convergence.
A sequence with errors converges Q-linearly in a specified norm if there is a constant with eventually. The limsup of consecutive nonzero error ratios is its asymptotic factor. This is stronger than merely having a bound , which is called R-linear convergence. The norm and whether an iteration is one coordinate step or an entire sweep must be specified when quoting a factor.
An iteration has at least cubic convergence when its errors eventually satisfy the displayed inequality with fixed . Exact order of convergence three requires a positive finite limit of . If , setting gives , hence .
Fixed-point arithmetic represents values as integer multiples of a fixed scale . Integer operations on , followed by the required rescaling and rounding, implement arithmetic on these values. Unlike floating-point arithmetic, the spacing is constant throughout the representable range.
For , the stored integer represents . Multiplying two encoded values and gives , so returning to the original scale requires dividing the integer product by with a stated rounding rule. Fixed spacing makes resolution predictable, but the chosen integer width limits range and can cause integer overflow.
Rounding replaces a number by a permitted representable value according to a specified rule. Rounding to nearest minimizes absolute error; directed rounding instead selects the next permitted value toward positive infinity, negative infinity or zero. A tie between equally near values needs an explicit convention.
On the decimal grid with spacing , rounds to nearest as , with error . Rounding to nearest has error at most half the grid spacing. In normal floating-point arithmetic, that spacing depends on magnitude, leading to a relative-error bound described by unit roundoff. The IEEE round-to-nearest-even rule resolves ties by an even final significand digit.[ref]
IEEE arithmetic in Oracle's Numerical Computation Guide. Chapter 2, IEEE Arithmetic Model, four rounding directions
The shooting method converts a boundary value problem into a root finding for unknown initial data. For , , , solve the initial value problem with trial slope , and define . A zero of gives the desired endpoint value.
For , , , the trial solution is , so and the correct slope is one. For unstable differential equations, tiny initial-slope errors can grow enormously before reaching ; the method can then be poorly conditioned even when a direct boundary discretization is effective. Multiple shooting reduces the length over which each initial-value integration must propagate.
An optimization algorithm that brackets an extremum of a unimodal function on an interval. Two interior probes divide the bracket in the golden ratio; after discarding one side, one probe can be reused, so each subsequent contraction needs only one new function evaluation.
In numerical analysis, significant figures record how many meaningful digits are retained in a written numerical value. Leading zeros locate the decimal point rather than adding precision: and each have two significant figures. Trailing zeros may require an explicit convention to distinguish measured precision from positional notation.
A numerical method is an algorithm for computing an exact or approximate solution to a mathematical problem through finitely many arithmetic operations and other prescribed steps. For example, Gaussian elimination solves a linear system exactly in exact arithmetic, whereas finite precision can introduce roundoff error.
For an ordinary differential equation with acceleration independent of velocity, the velocity Verlet method advances position and velocity byHere is the time step and . For sufficiently smooth , the global error on a fixed time interval is , so halving reduces the leading global error by a factor of four once the asymptotic regime is reached.
A numerical algorithm implements a numerical method through specified finite computation steps, including arithmetic operations and any required function evaluations.
Floating-point arithmetic represents a real number by a sign, a fixed number of significant digits, and a scale. It trades exactness for a compact representation spanning many orders of magnitude. The picture shows the essential compromise: with the same precision, large numbers have wider gaps between representable neighbors. Thus accuracy is naturally relative to magnitude, rather than a fixed distance along the number line.
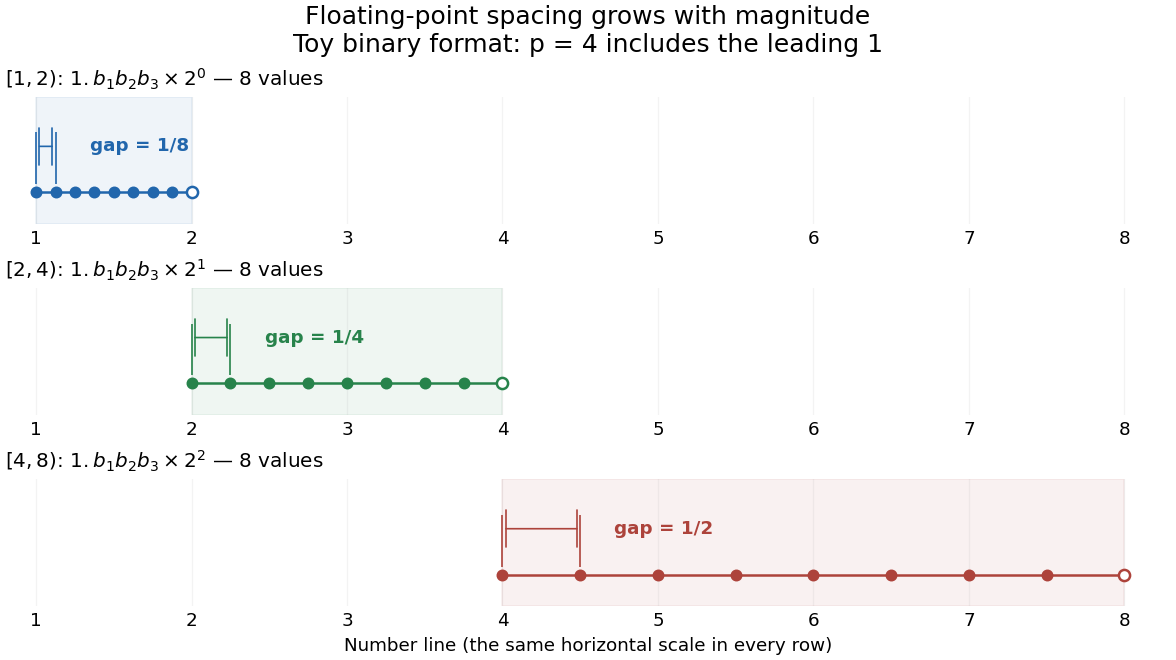
Eight normalized four-bit binary values in each of three intervals, with gaps doubling from one eighth to one half
. Details. In radix , an integer at least two, a nonzero normalized value has the positional notationwhere the digits and exponent are integers. The parenthesized factor is the significand; counts all its significant digits, including the leading digit. Normalization means , so the same value has one such representation. The allowed exponents satisfy . Finite precision restricts the available digits, while the exponent bounds restrict the range. Zero needs a separate representation. This scales a digit string in positional notation by a power of its base.[ref]
https://docs.oracle.com/cd/E19957-01/806-3568/ncg_goldberg.html. David Goldberg, What Every Computer Scientist Should Know About Floating-Point Arithmetic, §Floating-point Formats, 1991; Oracle's authorized edited reprint
For positive normalized values in , increasing the last digit by one gives the constant neighbor spacingAt the next scale, the spacing is multiplied by . In the binary numeral system with , the values in are ; those in are ; those in are . The respective gaps are , , and . Although absolute resolution deteriorates with magnitude, stays between and . This scale invariance is why floating-point arithmetic suits both microscopic and astronomical calculations.
The IEEE 754 binary64 format uses the binary numeral system with , including an implicit leading one for normalized values, and normal exponents . Its 64 stored binary digits comprise one sign digit, 11 exponent digits and 52 trailing significand digits. Subnormal numbers extend the range toward zero with a different leading-digit rule. In rounding to nearest, an operation returns the representable value closest to its exact result; a tie goes to the value whose last significant binary digit is even. Machine epsilon describes the gap just above one, whereas unit roundoff bounds a single relative rounding error in the normal range. These format and rounding rules are presented in MIT's floating-point lecture.[ref]
https://ocw.mit.edu/courses/18-335j-introduction-to-numerical-methods-spring-2019/2f313023ae3404bc217a81a31b227170_MIT18_335JS19_lec2.pdf. Per-Olof Persson, MIT 18.335J, Lecture 2: Floating-Point Arithmetic, the IEEE Standard, slides 6–9, 2019
Even an ordinary terminating decimal can require rounding in the binary numeral system. The rational number has the repeating positional notation . Every finite binary fraction has a reduced denominator that is a power of two, so the factor five in prevents an exact finite binary representation. In binary64, the exact stored values of three decimal literals and their computed sum areThe exact sum of the first two stored rational numbers is , halfway between two binary64 values. The even-last-digit tie rule rounds it upward. The printed result is
0.30000000000000004, one step above stored 0.3, so 0.1 + 0.2 == 0.3 is false. Both conversion of the inputs and rounding of the addition matter here.To reproduce the table on a Python installation using binary64, inspect exact fractions rather than only their printed decimal representations:Python's
import sys
assert (sys.float_info.radix, sys.float_info.mant_dig) == (2, 53)
for value in (0.1, 0.2, 0.3, 0.1 + 0.2):
    print(repr(value), value.as_integer_ratio())
print(0.1 + 0.2 == 0.3) # Falseas_integer_ratio() returns a pair of integers whose quotient equals the stored finite value exactly.[ref]https://docs.python.org/3.14/library/stdtypes.html#float.as_integer_ratio. Python 3.14 documentation, float.as_integer_ratio
Exact rational numbers are also useful for checking floating-point arithmetic: a short decimal printout can hide the approximation being made.Historically, David Goldberg's March 1991 ACM Computing Surveys paper explained representation, rounding and catastrophic cancellation together with the IEEE standard's design choices. Oracle provides an authorized edited reprint. Its enduring lesson is practical: use the spacing to understand roundoff error, and inspect intermediate values when mathematically equivalent algorithms behave differently.[ref]
https://docs.oracle.com/cd/E19957-01/806-3568/ncg_goldberg.html. Goldberg, 1991, reprint notice and §§Rounding Error, Cancellation
A floating-point operation is one arithmetic operation on values represented in floating-point arithmetic. Algorithmic counts commonly count addition, subtraction, multiplication and division separately. A fused multiply-add can therefore count as two arithmetic operations even when executed by one hardware instruction. Such counts describe work, while elapsed time also depends on memory traffic, parallelism and the implementation.
To add two finite floating-point numbers, compare their exponents, shift the smaller significand to a common exponent, add or subtract the signed significands, normalize the result, and apply floating-point rounding. Extra low-order bits are needed to determine correct rounding when shifting or cancellation discards information. A carry beyond the leading digit increases the exponent; cancellation can decrease it. Unlike exact real addition, this operation need not be associative. Changing the child evaluation order in a fixed binary expression tree need not change its parenthesization, whereas reassociation changes which intermediate results undergo floating-point rounding.
A sixteen-bit floating-point representation with one sign bit, five exponent bits and ten stored fraction bits. For sign , stored exponent and fraction integer , normal finite values areThe implicit leading one gives eleven significant binary digits. With , the value is , including signed zero at and subnormal numbers otherwise. The stored exponent is reserved for infinities at and NaN otherwise. The positive normal range is through ; the least positive subnormal number is .
A floating-point representation occupying bits, or bytes, with one sign bit, exponent bits and explicitly stored fraction bits. The implicit leading bit of a normal number gives bits of significand precision. Near one, adjacent numbers are separated by ; rounding to nearest has unit roundoff in the normal range. These are relative precision scales, distinct from underflow limits or a universal absolute error bound.[ref]
IEEE arithmetic in Oracle's Numerical Computation Guide. Chapter 2, IEEE Arithmetic Model and Double Format, Table 2-5
Floating-point overflow occurs when the magnitude of a computed result exceeds the largest finite representable floating-point number. Large values of an exponential function are a common source. In a normalized weighted sum, replacing exponentials by before division prevents this particular overflow while leaving the normalized weights unchanged; this is an application of the log-sum-exp construction.
NaN, meaning “not a number”, is a special datum in floating-point arithmetic used for an invalid real operation or a propagated undefined result. Examples include and the real square root of a negative number. It is distinct from the positive or negative infinity produced by some other exceptional operations.
Ordinary ordered comparisons involving NaN are false, and even equality of NaN with itself is false; use a dedicated NaN test rather than equality to detect it. A missing numerical estimate or a displayed NaN is consequently not a numerical zero and cannot serve as a valid p-value.[ref]
https://docs.oracle.com/cd/E19957-01/806-3568/ncg_goldberg.html. Goldberg, Special Quantities and Comparison: NaNs, propagation and unordered comparisons
Replacement of an exact real arithmetic result by a representable floating-point number under a specified rounding rule. Repeated products can depend on evaluation order, so a recursive rewrite intended to reproduce a floating-point loop should preserve its sequence of accumulator operations. An exact algebraic invariant does not by itself establish equality of rounded machine results.
Floating-point underflow occurs when a nonzero numerical result is smaller in magnitude than the representable range or loses precision in the subnormal range. A long product of probabilities can become zero despite a mathematically positive result. Adding logarithms avoids forming the product; adding alternative path probabilities then requires log-sum-exp or controlled rescaling.
A finite normal floating-point representation stores a sign, a significand and a bounded integer exponent, representing in radix . Fixing the number of significand digits gives roughly constant relative precision across a wide dynamic range; the gap between adjacent representable values grows with the exponent.
For example, in the binary numeral system. The normal leading binary digit is one and can be implicit in storage. Subnormal numbers use a different leading-digit rule near zero. IEEE formats also reserve encodings for signed zero, infinities and NaN, so the bit pattern cannot always be interpreted by the normal finite formula.[ref]
IEEE arithmetic in Oracle's Numerical Computation Guide. §2.2, IEEE formats and normal/subnormal representations
The significant-digit factor in a floating-point representation , where is the sign bit, the radix and the exponent. For a normal positive binary significand, , and the leading one need not be stored. In a subnormal number, the leading digit is zero at the minimum normal exponent scale. The significand is a numerical factor, distinct from the stored trailing fraction bits that encode part of it.
A finite floating-point number is a value representable in a specified floating-point representation. For fixed precision and exponent bounds, only finitely many real values are available. Most real numbers therefore require rounding before storage.
In binary arithmetic, is exact but is not: a finite binary fraction has a reduced denominator that is a power of two. This is a property of the representation, even before any arithmetic operation occurs. The associated IEEE encodings additionally include infinities and NaN; NaN is a special arithmetic datum rather than a real value.[ref]
Compensated summation retains a correction for low-order information lost to roundoff error in successive floating-point arithmetic additions. Kahan summation is a common implementation; it can substantially reduce accumulated error when many terms are added.
The Kahan summation algorithm computes a sum in floating-point arithmetic while carrying a correction for low-order information lost by successive additions. With accumulator and correction initially zero, process each input in this order:Every operation shown is rounded in the working floating-point representation. The new approximates the portion added too much or too little in the rounded , so the next input subtracts it. For binary64 inputs in that order, ordinary left-to-right summation loses both small increments, returning one; this algorithm recovers .
y = x - c
t = s + y
c = (t - s) - y
s = tThe correction substantially improves many long sums, but is not an exact summation method and does not remove ill-conditioning when large opposite-sign terms nearly cancel. Its operation order is essential: a compiler that rewrites as exact algebraic zero destroys the correction.[ref]
https://docs.oracle.com/cd/E19957-01/806-3568/ncg_goldberg.html. Goldberg, Errors in Summation and Optimizers: compensated summation and why reassociation invalidates it
Here machine epsilon means the gap from one to the next larger value in normalized floating-point arithmetic:It is a relative resolution scale near one, not the smallest positive representable value and not a fixed absolute error for all magnitudes. In binary64, giveswhere is unit roundoff for rounding to nearest. Some authors instead call their machine epsilon; MIT 18.335J uses this half-gap convention. Always check which definition an error bound uses.[ref]
https://ocw.mit.edu/courses/18-335j-introduction-to-numerical-methods-spring-2019/2f313023ae3404bc217a81a31b227170_MIT18_335JS19_lec2.pdf. Persson, MIT 18.335J, Lecture 2, slides 3, 8–9: the half-gap convention
The gap below one is smaller: the preceding binary64 value is , whereas the next value above one is . Under nearest-even rounding,
1.0 + 2.0**-53 is exactly 1.0: the exact sum is a tie and one has the even final binary digit. By contrast, 1.0 + 2.0**-52 is the next value. Thus searching for the smallest increment that changes one by trial addition also depends on the rounding convention. At the next larger binary64 value is , illustrating why a small absolute increment can disappear at large magnitude. Articles were limited to the first 100 out of 911 total.
Articles by others on the same topic

Numerical analysis is a branch of mathematics that focuses on developing and analyzing numerical methods for solving mathematical problems that cannot be easily solved analytically. This field encompasses various techniques for approximating solutions to problems in areas such as algebra, calculus, differential equations, and optimization. Key aspects of numerical analysis include: 1. **Algorithm Development**: Creating algorithms to obtain numerical solutions to problems. This can involve iterative methods, interpolation, or numerical integration.



Techniques to get numerical approximations to numeric mathematical problems.
The entire field comes down to estimating the true values with a known error bound, and creating algorithms that make those error bounds asymptotically smaller.
Not the most beautiful field of pure mathematics, but fundamentally useful since we can't solve almost any useful equation without computers!
The solution visualizations can also provide valuable intuition however.
Important numerical analysis problems include solving: