Gradient descent is an iterative method for minimizing a differentiable function : choose an initial vector and repeatedly move opposite its gradient.[ref]
With a fixed positive step size , the update isThe direction and the step size play different roles: the gradient supplies local information about increase, while determines how far that information is trusted. A varying step size gives instead; exact line search for a positive-definite quadratic chooses it by minimizing along the current direction.
Why is this the steepest direction? For a unit vector in the Euclidean norm, the directional derivative is . The Cauchy-Schwarz inequality bounds it below by , attained by when the gradient is nonzero. This is steepest descent relative to the Euclidean norm; changing the norm can change the steepest direction. A finite step need not decrease , because a directional derivative describes infinitesimal motion.
For the quadratic form with linear term , assuming is a symmetric matrix, the negative gradient is the linear-system residual . Thus gradient descent turns the linear system into repeated residual corrections; a positive-definite matrix makes its solution the unique global minimum. This is useful when applying the linear map is affordable but directly solving the linear system is costly.
The attraction is that a gradient evaluation gives an entire update without solving a new linear system. The difficulty is choosing a step size that progresses along gently curved directions without overshooting steep ones. Fixed-step gradient descent on a positive-definite quadratic makes this tension exact: every eigenvector direction has its own multiplier, determined by its eigenvalue. The resulting condition number dependence explains why a narrow valley can slow even an inexpensive iterative method.
The simplicity of the gradient update and its sensitivity to the condition number of the Hessian matrix are central practical features.[ref]
Convex Optimization by Stephen Boyd and Lieven Vandenberghe. §9.3.1, pp. 466–468, and §9.3.2, p. 475, Conclusions: convergence and conditioning
A warm restart continues an optimization process from an already obtained solution while restarting specified algorithm controls or history. Its meaning depends on which fields are retained. In SGDR, the current parameters are retained while the learning rate schedule starts another cycle; the original paper explicitly distinguishes this from starting the optimization from scratch.[ref]
SGDR: Stochastic Gradient Descent with Warm Restarts by Ilya Loshchilov and Frank Hutter. Version5, section3, printed p4, retained current solution and restarted learning rate
Write a complete algorithm state as , where holds parameters, is optimizer state and holds controls such as the schedule phase. A restart map can retain while replacing , or can also replace selected parts of . Saying only “restart” does not specify the next optimizer update.
For an original scalar example, take and the momentum buffer recurrenceAt current , stored , and restarted learning rate , retaining the buffer givesRetaining the same parameters but resetting the buffer to zero gives and . Both runs start the next update at ; they differ in the history carried through the restart.
A schedule-only restart can also change the next step without changing stored parameters immediately. In a plain gradient descent update from , increasing the learning rate from 0.01 to 0.1 changes the next value from 1.98 to 1.8. The change takes effect through the subsequent gradient step.
An optimization checkpoint instead records enough information to reproduce a specified continuation. A deliberate warm restart may intentionally alter some of that information. Record the retained parameter state, the new schedule phase and the policy for buffers or counters before comparing trajectories or claiming optimizer restart equivalence.
An adaptive gradient method uses information from supplied gradients to adjust subsequent optimizer updates, often with a different scale for each coordinate. A useful diagonal form iswhere is the current gradient, is a scalar learning rate and is a positive diagonal matrix computed from gradient history. A learning rate schedule can still control independently of the coordinate adaptation. The broader family includes AdaGrad, Adam and AdamW.
The 2011 AdaGrad paper by John Duchi, Elad Hazan and Yoram Singer formalized adaptive geometry from accumulated gradient information, including diagonal and full-matrix constructions.[ref]
Adaptive Subgradient Methods for Online Learning and Stochastic Optimization by John Duchi and others. Section1.1, printed pp2122–2124, Eq1 and Eq5
An unconstrained diagonal specialization maintainsHere specifies additive stabilization outside the square root. The accumulator is part of the optimizer state, rather than determined by the current parameters alone.For an original example, start at and supply , with and . Both accumulated entries are positive, so the denominators are defined. The first step givesPlain gradient descent with the same scalar learning rate would instead give . If the next supplied gradient is again , then and each coordinate's additional movement is . These are explicit supplied-gradient calculations, rather than a convergence claim.
In this cumulative version, an accumulated squared-gradient entry never decreases, so its effective coordinate learning rate does not increase. Other adaptive gradient methods retain decaying averages instead, changing how strongly old gradients influence later updates. Adaptation therefore specifies both the state recurrence and how that state transforms the gradient; the word “adaptive” alone does not determine either.
Adam, named for adaptive moment estimation, is an adaptive gradient method that scales a running gradient estimate by a running squared-gradient estimate. Diederik P. Kingma and Jimmy Lei Ba presented it as a first-order method for stochastic optimization. Its state makes the next optimizer update depend on gradient history as well as the current parameters.[ref]
Adam: A Method for Stochastic Optimization by Diederik P. Kingma and Jimmy Lei Ba. Version9, printed pp1–2, Introduction and Algorithm1
Starting from , the basic minimization rule isHere is the supplied gradient, is the learning rate, , and . The Hadamard product, square root and division act coordinatewise. Adam bias correction supplies the two normalization factors. The accumulator concerns a raw second moment, rather than a centered variance.[ref]
Adam: A Method for Stochastic Optimization by Diederik P. Kingma and Jimmy Lei Ba. Algorithm1, printed p2, epsilon outside the square root
For an original scalar calculation, choose , , and , and supply , . The first step hasThe second hasEqual and opposite supplied gradients have not undone one another: the running histories give the second step a different magnitude. Plain gradient descent with the same constant learning rate would return to zero for this sequence.
The calculation specifies the recurrence, rather than a convergence guarantee for an unspecified objective function. An optimization checkpoint needs these histories and the step count to reproduce subsequent steps. AdamW adds decoupled weight decay; feeding a penalty gradient into Adam instead implements coupled L2 regularization and changes the histories.
Adam bias correction compensates for the initial zero values in Adam's exponentially weighted gradient histories. The basic algorithm usesThese factors normalize the coefficient sums of the two running histories.[ref]
Adam: A Method for Stochastic Optimization by Diederik P. Kingma and Jimmy Lei Ba. Algorithm1, printed p2; section3, Initialization Bias Correction, printed p3
For a scalar coordinate, suppose andExpanding the recurrence relation givesIf every has the same expectation , linearity of expectation and the geometric series yieldThus is an unbiased estimator of under these assumptions. Correlation between different times is allowed by this argument. Applying the same calculation to squared gradients with constant raw second moment gives and .
For a constant supplied gradient of 2, choose and . The first uncorrected histories are and , while their corrected values are 2 and 4. The normalization removes the missing coefficient mass caused by initialization.
It does not make a changing history equal to the latest gradient. For an original deterministic example, let , and . Then , sowhich differs from . More generally, changing moment expectations produce a weighted average of past expectations. State the moment assumptions before interpreting “bias-corrected” as unbiased for a present distribution. The nonlinear parameter update built from the corrected histories is a separate object from either moment estimator.
AdaGrad is a family of adaptive gradient methods that derives update geometry from accumulated gradient information. Its diagonal form uses a separate cumulative squared-gradient history for each coordinate. John Duchi, Elad Hazan and Yoram Singer's original paper develops diagonal and full-matrix versions, including constrained and regularized settings.[ref]
Adaptive Subgradient Methods for Online Learning and Stochastic Optimization by John Duchi and others. Section1.1, printed pp2122–2124, Eq1 and Eq5
For an unconstrained diagonal specialization, start with and usewhere is the base learning rate, keeps the denominator positive, and is a gradient or suitable subgradient. The additive stabilizer is outside the square root in this declared variant. The accumulator belongs to the optimizer state and must be retained to reproduce later updates.
For an original history example, supply two-coordinate gradientsAfter 100 observations,Choose and . The effective coordinate learning rates are thenAlthough the recent supplied gradients agree, the early large first-coordinate value still strongly reduces its update scale.
Each is nondecreasing, so with fixed and the corresponding effective learning rate is nonincreasing. For a constant nonzero supplied scalar gradient , the history is and the update magnitude isThis tends to zero as the cumulative history grows. Adam instead uses a decaying squared-gradient history, giving old observations a different influence. The choice between these histories is part of the algorithm, rather than merely a different initial learning rate.
The diagonal AdaGrad accumulator stores a cumulative squared-gradient total for each coordinate:These quantities form part of AdaGrad's optimizer state. An unconstrained diagonal update uses them through a coordinate scale such as with a declared positive stabilizer . The accumulator itself and its inverse-square-root transformation are distinct objects.[ref]
Adaptive Subgradient Methods for Online Learning and Stochastic Optimization by John Duchi and others. Section1.1, printed pp2122–2124, Eq1 and Eq5
The relation to the full gradient history is exact. Form the sum of outer productsThen . Retaining only this diagonal is cheaper than retaining every entry of , but discards cross-coordinate information.
For an original two-step example, compare historiesBoth give . Their full matrices differ:The diagonal state cannot distinguish those joint gradient patterns. If both are next supplied with , both accumulators become and produce the same coordinate scaling for that update.
Every entry is nonnegative and nondecreasing, since each added square is nonnegative. Alternating gradient signs therefore cannot cancel their contribution to this state. For example, scalar gradients 3 and −3 give accumulated value 18 rather than 0. A saved parameter vector does not reconstruct that history: resuming the same AdaGrad recurrence requires the corresponding accumulator and settings in the optimization checkpoint.
AdamW combines the adaptive update of Adam with decoupled weight decay. It maintains exponentially weighted histories of the supplied data gradient and its componentwise square, while applying parameter shrinkage separately. Ilya Loshchilov and Frank Hutter presented the method in their work on decoupling decay from gradient-based regularization.[ref]
Decoupled Weight Decay Regularization by Ilya Loshchilov and Frank Hutter. Version3, Algorithm2, AdamW
For minimization without optional algorithm variants, initialize . In the convention documented by PyTorch, step usesThe product is a Hadamard product; square roots and division are also coordinatewise. Assume , and the stated learning rate . The decay coefficient is . This explicitly fixes epsilon placement and the decay convention.[ref]
AdamW in the PyTorch documentation. PyTorch2.15, algorithm with amsgrad and maximize disabled
The denominators and perform Adam bias correction for zero-initialized histories. For a constant supplied scalar gradient , the corresponding geometric sums give and . Their corrected values are therefore and . The squared-gradient quantity concerns a raw second moment, rather than a centered variance: a constant gradient of 2 has square 4 even though its variance is zero.
For an original first-step example, choose , , , , , and . ThenandThe constants are chosen for transparent arithmetic. Feeding into the same adaptive formulas instead, with no separate shrinkage, would give approximately . That coupled L2 regularization also changes the stored histories. Resuming AdamW therefore requires the relevant optimizer state and step count as well as the parameter values and settings.
An optimizer update changes the adjustable parameters of an optimization problem according to an algorithm's current information. Evaluating a loss function, computing its gradient and changing the parameters are distinct operations. A general update may also change an optimizer state, such as stored information from previous steps:Here is the supplied gradient and a learning rate. The PyTorch interface makes this separation explicit with gradient computation followed by
optimizer.step().[ref]torch.optim in the PyTorch documentation. PyTorch2.15, Taking an optimization step, optimizer.step() example; Optimizer base class
For plain gradient descent with no extra state, . In an original scalar example, choose , and . The gradient is 2, so the update gives and lowers the loss from 2 to 1.62. Recompute the gradient at the new parameter value to obtain . Reusing the old gradient 2 instead would give 1.6. This explicitly locates where the algorithm obtains its information.[ref]
An update is not automatically an improvement: using for the first step above gives and loss 8. With gradient accumulation, several gradient calculations instead contribute before a single optimizer update; their weighting sets the effective batch size. Track the update count separately from the number of processed groups, particularly when applying a learning rate schedule.
Weight decay supplies a parameter-shrinkage contribution to an optimizer update, with a coefficient commonly denoted . Two implementations must be distinguished. Coupled L2 regularization adds the penalty to the objective function, replacing its data gradient by . Decoupled weight decay applies parameter shrinkage separately from the optimizer's processing of the data gradient. These operations are equivalent for plain gradient descent with matched coefficients, but not in general for an adaptive gradient method.[ref]
Decoupled Weight Decay Regularization by Ilya Loshchilov and Frank Hutter. Version3, section2, propositions1–2 and AppendixA
Use the PyTorch convention here: a decoupled update shrinks parameters by , where is the learning rate. A source writing instead has absorbed the step-size factor into its decay coefficient. For an unmodified gradient step,In AdamW, the decay contribution does not enter the stored first- or second-moment estimates of the gradient.[ref]
AdamW in the PyTorch documentation. PyTorch2.15, algorithm, separate parameter-decay line and moment updates
An original fixed-scaling example exposes the difference. Let , , , and diagonal matrix . Applying the same scaling to the entire coupled gradient givesSeparating uniform parameter shrinkage givesThe second coordinate receives different shrinkage. This is an illustrative fixed matrix, not a full AdamW simulation. With history-dependent scaling, coupling the penalty into the gradient can also alter the optimizer state. State the update equation and coefficient convention when reporting a decay setting; the label alone does not specify either.
Decoupled weight decay applies a parameter-shrinkage contribution separately from the optimizer's processing of the data gradient. Write for the processed data-gradient direction, including any algorithm-specific optimizer state. Using the coefficient convention documented for PyTorch AdamW,The shrinkage term uses the pre-update parameter and is not inserted into the gradient moments.[ref]
AdamW in the PyTorch documentation. PyTorch2.15, algorithm: separate parameter-decay line before the adaptive update
This differs from coupled L2 regularization, which processes as a single gradient input. Decoupled weight decay was introduced for adaptive optimization in the AdamW work; the original paper also writes decay coefficients with the learning-rate factor absorbed differently, so its coefficient must be translated before comparing equations.[ref]
Decoupled Weight Decay Regularization by Ilya Loshchilov and Frank Hutter. Version3, section2 and Algorithm2
An original limiting case isolates the shrinkage. Suppose the processed direction is zero at every step and are constant. Repeated substitution givesWith , and , one update gives 0.98 and 50 updates give approximately 0.36417. For varying learning rates, the corresponding factor isThus the same numerical decay coefficient can have a different accumulated effect under a different learning rate schedule. In this zero-direction model, gives sign-preserving shrinkage; other factors have different behaviour.
The update order is also part of the definition. For , , and , the stated formula gives . Applying shrinkage after first taking the gradient step would instead give . Both operations may be described informally as decay plus a step, but they are different recurrences. An optimization checkpoint must retain the relevant state and settings to reproduce the chosen one.
Coupled L2 regularization adds a quadratic parameter penalty to the objective function and sends its gradient through the same optimizer update as the data gradient. With coefficient , defineSince the gradient of the squared Euclidean norm divided by two is , a supplied data gradient becomesThe factor fixes the convention: a penalty written as instead contributes .
For plain gradient descent, this substitution givesIt is therefore equivalent to decoupled weight decay with the matched coefficient in this particular update. The equivalence need not survive coordinate-dependent processing of the gradient.[ref]
Decoupled Weight Decay Regularization by Ilya Loshchilov and Frank Hutter. Version3, section2, propositions1–2 and AppendixA
For an original fixed-scaling example, let , , , and diagonal matrix . Applying to the whole coupled gradient givesThe same quadratic penalty produces unequal coordinate shrinkage after this scaling. Uniform decoupled weight decay would instead give . The example isolates a fixed scaling operation, rather than claiming to simulate a complete adaptive gradient method.
Coupling can also change the optimizer state. For example, a momentum buffer formed from stores contributions from along with the data gradient. If an adaptive accumulator uses squared gradient entries, it receives , including a cross term . Subsequent updates can therefore differ even when the next data gradient is the same. State both the penalty convention and the optimizer's gradient-processing rule when describing an L2 setting.
The optimizer state is information retained by an optimization algorithm beyond the current parameter values. It can include a momentum buffer and algorithm-specific counters or running estimates. Consequently, two runs with identical parameters and current gradients can produce different next optimizer updates if their stored states differ.
For an original scalar example, minimize with the recurrenceThis is the momentum form with dampening, decay and the
nesterov flag disabled in the PyTorch stochastic gradient descent implementation.[ref]SGD in the PyTorch documentation. PyTorch2.15, algorithm pseudocode; momentum and dampening description
At , and , a stored gives and . A stored instead gives and . The current parameter and gradient were identical; the difference came from history.An optimization checkpoint that saves only the parameters cannot reproduce that next step. In PyTorch,
Optimizer.state_dict() stores per-parameter state and parameter-group settings such as learning rate, but not the parameter values themselves. Its parameter identifiers associate state with ordered parameter groups and are not a check of semantic parameter identity during loading.[ref]torch.optim in the PyTorch documentation. PyTorch2.15, Optimizer.state_dict API, state/param_groups entries and loading note
Save and restore the corresponding parameters separately and keep the state-to-parameter association consistent. Reproducing an entire training run may additionally require the data order and other changing state.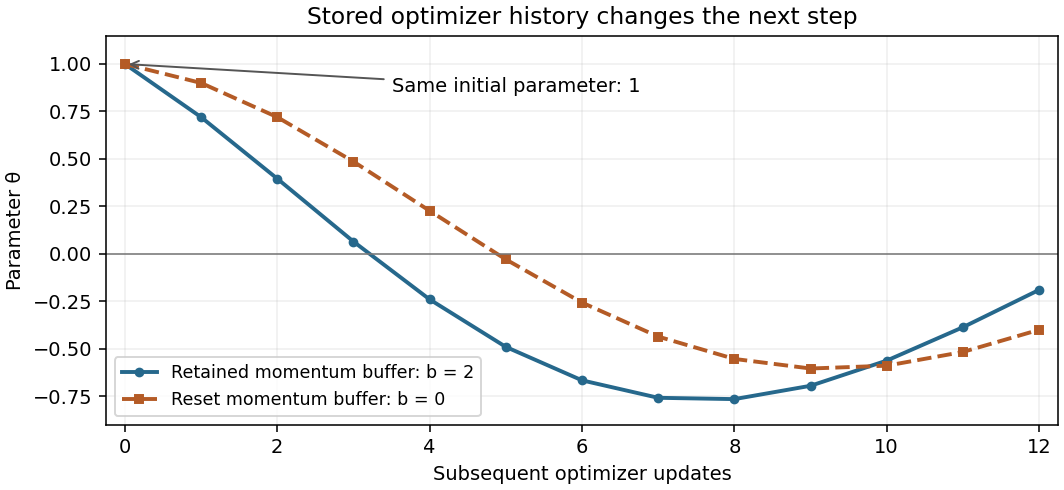
Original deterministic quadratic model: keeping or resetting the momentum buffer gives different trajectories from the same parameter value
. Details. An optimization checkpoint is a saved description of an ongoing optimization algorithm from which its optimizer updates can resume. It combines the current parameters with the relevant optimizer state. The practical criterion is optimizer restart equivalence: after restoring the saved information and supplying the same subsequent inputs, the chosen update rule should produce the same subsequent states.
For a deterministic scalar example, minimize the quadratic function with gradient , learning rate and momentum buffer recurrence , followed by . Start with . After one step the saved pair is . Restoring both gives and . Restoring only and initializing a new momentum buffer to zero gives and . Equal saved parameters can therefore lead to unequal continuations. These numbers are an original calculation for the declared recurrence.
In PyTorch, a general training checkpoint commonly serializes separate model and optimizer dictionaries, together with the training position. The model dictionary contains learned parameters and registered model buffers; the optimizer dictionary contains its own changing state and group settings.[ref]
Saving and Loading Models in the PyTorch tutorials. What is a state_dict?; Saving & Loading a General Checkpoint for Inference and/or Resuming Training
Restoring the optimizer state-to-parameter association also matters: the optimizer loader pairs stored identifiers with parameters in group order, without independently establishing that they denote the same mathematical parameters.[ref]torch.optim in the PyTorch documentation. PyTorch2.15, Optimizer.state_dict, state/param_groups and loading note
The required checkpoint boundary depends on the computation being resumed. A changing learning rate schedule, the next position in the training data, and the state of a pseudorandom number generator can influence future updates. Matching them is part of computational reproducibility; a saved parameter vector alone does not specify the whole training process.
Optimizer state-to-parameter association identifies which parameter each saved piece of optimizer state belongs to. An optimization checkpoint can contain every stored number and still resume incorrectly if those numbers are attached to different parameters. Equal shapes and data types do not establish mathematical identity.
The PyTorch optimizer dictionary separates per-parameter state from parameter-group settings. Its loader pairs saved parameter identifiers with the current parameters in group order, without independently verifying the intended association.[ref]
torch.optim in the PyTorch documentation. PyTorch2.15, Optimizer.state_dict, state/param_groups and loading note
For an original two-parameter example, use and . Let the named parameters be and , their current gradients both be 1, and their saved momentum buffers be and . Correct restoration givesIf a reversed parameter ordering attaches the same saved buffers to the wrong scalar parameters, the result is insteadBoth buffers had valid scalar shapes, so a shape check would not expose this error.
Consistently permuting the parameters, gradients and state is merely a change of ordering; permuting only the state changes the algorithm's continuation. Record a stable parameter schema and group order with the checkpoint, and check any intentional remapping against that schema. Parameter values and optimizer dictionaries are distinct saved objects, so restoring one does not automatically restore the other's meaning.[ref]
Saving and Loading Models in the PyTorch tutorials. What is a state_dict?; Saving & Loading a General Checkpoint
Optimizer restart equivalence means that restoring an optimization checkpoint reproduces the uninterrupted optimizer's parameter sequence for a specified subsequent computation. State the optimizer update rule, continuation inputs and intended notion of equality. Exact mathematical equality and agreement within a numerical tolerance are different claims.
For a deterministic algorithm modeled by , equality of the restored full state at step , together with the same update rule and future inputs , is sufficient. One application of gives equal next states; mathematical induction then gives equal continuations. This is a sufficient condition for the chosen observations, not a claim that every internal field must always affect them.
For an original exact example, take andFrom , one step gives . Restoring that pair gives and , exactly as uninterrupted execution. Resetting the buffer while restoring gives and . Thus a parameter-only save is not restart-equivalent for this recurrence.
Practical checkpoints must also retain the optimizer state-to-parameter association and the relevant settings, update position, learning rate schedule, data position and pseudorandom number generator state.[ref]
Saving and Loading Models in the PyTorch tutorials. General checkpoint for resuming training: model and optimizer dictionaries and training position
Fixing a random seed alone does not specify all of this continuation. Floating-point arithmetic and nondeterministic operations can additionally affect exact reproduction across environments; the primary documentation does not guarantee identical results across releases or platforms.[ref]Reproducibility in the PyTorch documentation. PyTorch2.15, opening reproducibility statement and controlling randomness
A momentum buffer stores an accumulated history of gradients for an optimization algorithm. In one common convention, a parameter vector , supplied gradient , learning rate and constant coefficient obey the recurrence relationThe buffer belongs to the optimizer state: it remembers earlier inputs even when the current parameters are unchanged. This is the undampened momentum convention used by PyTorch stochastic gradient descent with weight decay and the Nesterov accelerated gradient method disabled; its documented first buffer is the first gradient, agreeing with this recurrence from . Other conventions absorb the learning rate into the stored buffer, so a buffer value needs its update convention to be interpreted.[ref]
SGD in the PyTorch documentation. PyTorch2.15, algorithm and note comparing momentum conventions and first-step initialization
Repeated substitution gives the exponentially weighted gradient historyTo verify this identity, substitute its expression for into : multiplication by raises every old exponent by one, and the added is precisely the new exponent-zero term. The formula holds at because its sum is empty, completing the mathematical induction.
For an original scalar example with and a constant supplied gradient , the geometric series yields . At , and the limit is 10. The buffer is an unnormalized sum: multiplying it by changes its scale, and would require a corresponding learning rate adjustment to preserve these parameter updates.
The same memory explains why momentum can temporarily oppose the current gradient. If , and the new scalar gradient is , then . With a positive learning rate, the parameter still decreases, although the present negative gradient alone would call for an increase. Persistence can carry motion through rapidly alternating gradients, but this example also shows why the rule need not decrease the objective function at every step.
A momentum buffer can retain enough earlier history that it points against the current gradient. For the undampened rulethe parameter step is for positive learning rate . If , then the directional derivative in direction is . The actual update direction is therefore locally uphill for a differentiable objective function, even though gradient descent would use the opposite direction. This history-dependent recurrence is the non-Nesterov momentum convention documented for stochastic gradient descent with dampening and weight decay disabled.[ref]
For an original scalar example, let , current , stored buffer , coefficient and . The new gradient is 1, butThe objective increases from to . This is a fully specified finite step, not only a first-order prediction.
More generally,An old buffer sufficiently opposed to the new gradient makes this negative. At , that mechanism disappears. The example explains why a momentum method need not decrease the objective at every step; it does not imply that retaining gradient history always harms convergence. A descent direction test concerns the direction at the current point, while a convergence claim concerns an entire sequence.
An exponentially weighted gradient history assigns geometrically decreasing coefficients to older supplied gradients. For constant and momentum buffer recurrence ,Each additional update multiplies an old contribution by . The formula follows by substituting the expression for into the recurrence and adding the newest exponent-zero term. The same undampened recurrence, including its initialization convention, appears in the primary stochastic gradient descent documentation.[ref]
SGD in the PyTorch documentation. PyTorch2.15, momentum algorithm and first-buffer initialization note
For an original example, choose , and gradients , , . Successive buffers are 2, −1, 3.5. Directly expanding the third buffer givesThe newest contribution has coefficient 1; the oldest has coefficient 1/4. The buffer is a weighted sum, not yet a weighted mean. At , its coefficient sum is the geometric seriesHere , so the normalized weighted mean is , rather than the ordinary mean .
The coefficients also give a concrete memory scale. In the infinite geometric sequence, the fraction assigned to the newest gradients is . At , 29 gradients account for at least 95% of that coefficient mass, because whereas . This is a statement about coefficients, not a guarantee that gradients at different times are independent or that the optimizer averages a stationary process.
For this nonsymmetric matrix, consider the formal residual update , with nonzero . Put and . Algebra gives when . But and . Hence and for every defined nonzero step. At , the quotient is undefined. Thus the iteration cannot converge to zero linear-system residual from any nonzero initial residual. This concrete divergence proof distinguishes failure of an algorithm from mere failure to meet a sufficient theorem's hypotheses.
Let be real symmetric, let be a unit eigenvector satisfying , and use scalar step sizes . The gradient of the displayed cubic polynomial function isOn the eigenline, , so a gradient descent update remains on that same line and obeys the scalar recurrence in the title. Induction proves invariance for every iterate starting on the line, including an iterate that reaches zero. This is a statement about the geometry of the updates, not a convergence theorem: when , the restriction is unbounded below in one direction.
The number of optimization epochs needed to meet a stated accuracy criterion. Comparisons must specify the work counted by an optimization epoch, the accuracy measure, and whether a random method is controlled in expectation or with a stated probability. Counting coordinate partial derivatives is useful for comparing randomized block coordinate descent with gradient descent, but need not match elapsed computation time.
Target: gradient-descent.bigb, under Stochastic gradient descent.A unit of work corresponding to one full pass through the components used to measure an iterative method. For coordinate descent in coordinates, count coordinate partial derivative evaluations as an optimization epoch: updates on blocks of size require updates per optimization epoch. For stochastic gradient descent on a finite sum of losses, a common different convention counts one evaluation of every loss component. The convention must be specified. Random sampling with replacement need not visit every component during one such unit of work.
Target: gradient-descent.bigb, under Gradient descent.Consider the original two-dimensional exampleThe Hessian matrix is , a symmetric matrix and positive-definite matrix. Its eigenvectors are the coordinate directions, its eigenvalues are and , and its Euclidean norm condition number is . The unique global minimum is , so the error equals . The linear map , with the identity matrix, givesFor , the two coordinate error multipliers are and . Consequently , , and the second coordinate changes sign at every step while both shrink. The Euclidean norm of the error contracts by each step. The objective gap, which we call the quadratic energy, contracts by its square:The level sets of are ellipses. Oscillation across their narrow direction is compatible with strictly decreasing energy.
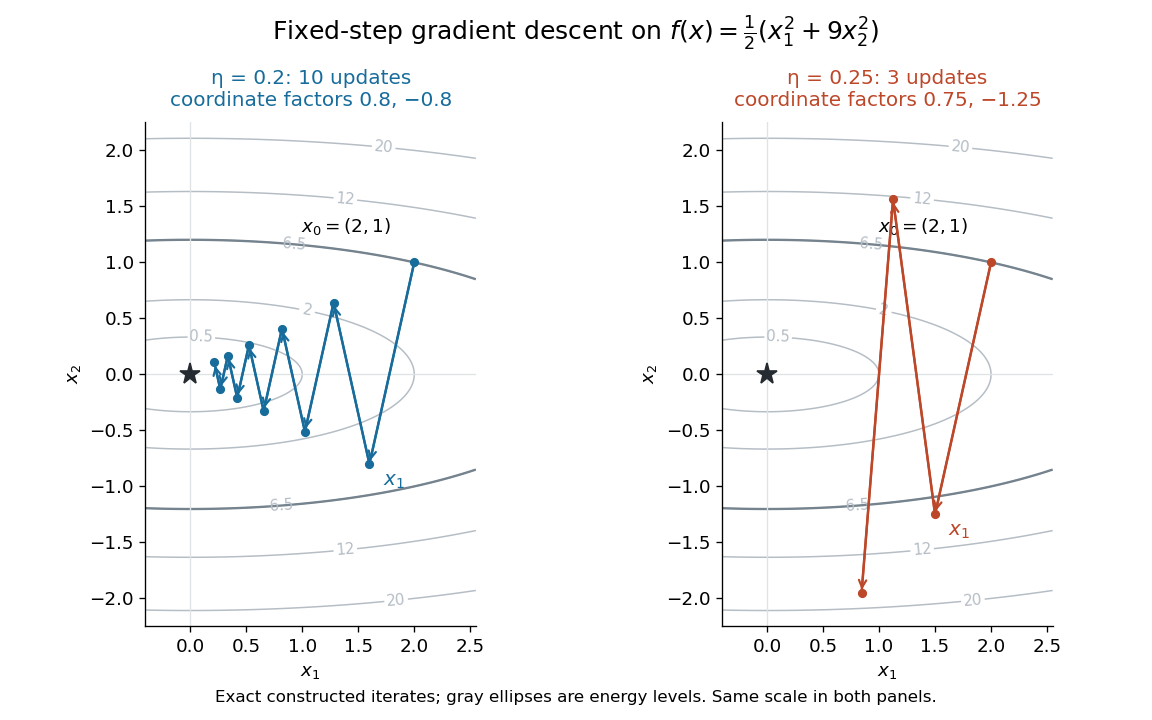
Original gradient descent iterates on : step size contracts both directions, whereas expands the second
. Details. For , the coordinate error multipliers become and , giving . The first coordinate still tends to zero, but the second alternates and grows. Direct substitution givesThus a larger positive step size can turn a strictly convex function into a divergent iteration. Energy and error are different quantities: coordinate errors carry signed multipliers, while each coordinate's contribution to energy carries the squared multiplier.
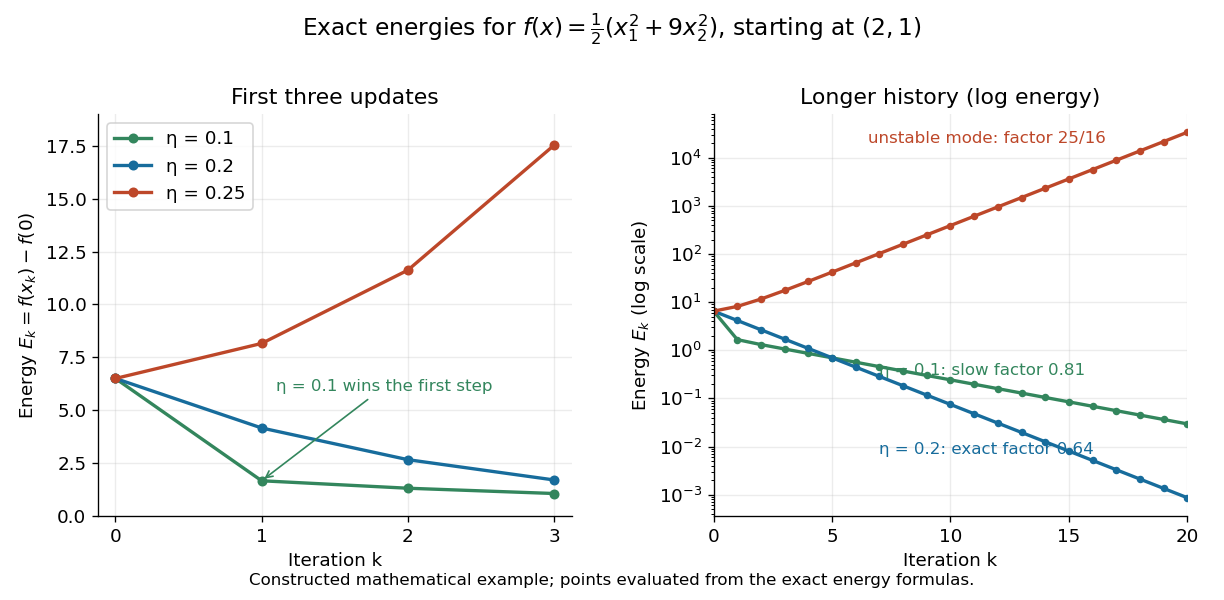
For the general quadratic form with linear termthe error obeys the same linear map . The spectral theorem for real symmetric matrices supplies an orthonormal basis of eigenvectors with positive eigenvalues . Writing gives the exact solution and energy identityTherefore convergence from every initial vector is equivalent toAt , a nonzero error component along a largest-eigenvalue eigenvector flips sign without shrinking. Above that threshold it grows. A particular start can still converge if it has zero components in every unstable direction; the interval is the condition for all starts. If , then and . These bounds follow by summing the squared components in the orthonormal basis.
For a fixed symmetric matrix and positive-definite matrix , what positive step size minimizes the largest coordinate error multiplier over all eigenvector directions? Let and . Since is a convex function of , its maximum over the eigenvalues occurs at an endpoint:Balance the two extremes by solving :Here is the Euclidean norm condition number of . This balance is optimal: for the endpoint exceeds , and for the endpoint exceeds . The optimal worst-case energy factor is , rather than . This optimizes a uniform one-step bound; a particular initial error supported on fewer eigenvectors can have a different best step size.
In the example , , so and . Both eigenvalue directions attain that energy factor, making the displayed history exact. The smaller step size instead givesIts first step reaches , below for , but subsequent progress is limited by the first direction's energy factor . By , the energies are approximately and , respectively; by , the iteration is ahead. A better first step need not yield a faster long-run history.
As the condition number grows, approaches one: stability in the direction of the largest eigenvalue forces small movement along the smallest-eigenvalue direction. This is a precise reason to improve scaling or use a method such as the conjugate gradient method, rather than merely increasing the step size. When , choosing eliminates every error component in one step.
Gradient ascent seeks a maximum by stepping along the gradient of a differentiable objective. It is gradient descent applied to . Taylor expansion gives , so sufficiently small positive steps improve the objective when the gradient is nonzero. Line search, projection onto admissible controls, and noise-aware gradient estimates are common practical modifications; a local stationary result need not be globally optimal.
Stochastic gradient descent updates an optimization parameter using a random estimate of the gradient:For a finite-sum objective , selecting an index uniformly and taking gives an unbiased stochastic gradient. Averaging several selected gradients gives a mini-batch gradient. The saving is fewer component evaluations per update, while the randomness adds variance. Unbiasedness or a controlled bias is an assumption, rather than an automatic property of any approximate gradient.[ref]
https://leon.bottou.org/publications/pdf/sirev-2018.pdf. Bottou, Curtis and Nocedal, Optimization Methods for Large-Scale Machine Learning, §4, stochastic-gradient formulation and noise/stepsize trade-offs
A simple noise example is and , where independent centered noises have variance . With a constant step size ,Its mean tends to zero, but its limiting variance is : solve . Thus constant steps can leave a stochastic gradient noise floor even for this strictly convex quadratic. Smaller or diminishing steps change the balance between progress and noise; a nonconvex stationarity estimate must not be read as guaranteed convergence to a global minimum.
SGDR means stochastic gradient descent with warm restarts. Its learning rate schedule repeatedly lowers the learning rate along a cosine curve, then raises it to begin another cycle while retaining the current parameters. Ilya Loshchilov and Frank Hutter's method uses this warm restart to continue an existing optimization trajectory.[ref]
SGDR: Stochastic Gradient Descent with Warm Restarts by Ilya Loshchilov and Frank Hutter. Version5, section3, printed p4
In cycle , let be elapsed training time since the last restart and the cycle duration, measured in the same units. The cosine learning rate schedule isIt starts at , reaches the midpoint of the two bounds at , and reaches at the cycle endpoint. The original implementation updates the elapsed training epoch count within each mini-batch, allowing fractional epoch progress.[ref]
SGDR: Stochastic Gradient Descent with Warm Restarts by Ilya Loshchilov and Frank Hutter. Section3, Eq5 and definition of T_cur
For an original schedule, choose bounds 0 and 0.1, initial duration epochs and duration multiplier 2. The successive cycle lengths are 4, 8 and 16 epochs, with restart boundaries at total elapsed times 4, 12 and 28. In the first continuous cycle, the rates at are respectively .
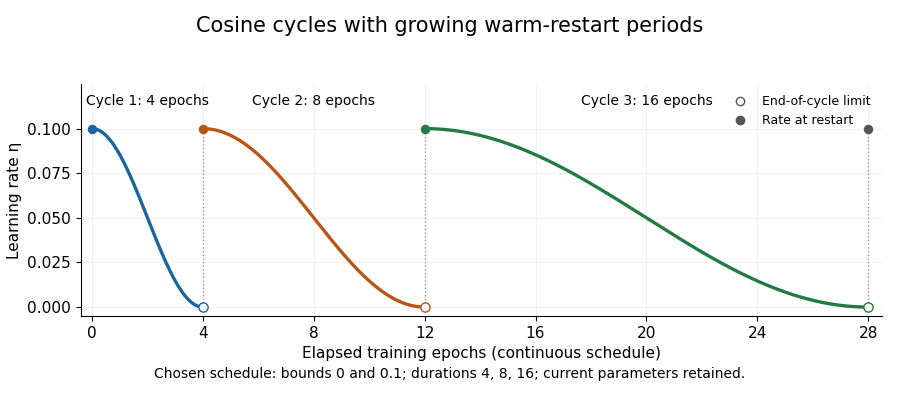
Cosine learning-rate cycles with doubling restart periods
. Own chosen schedule with bounds0 and0.1 and durations4,8,16epochs. Open markers show end-of-cycle limits; filled markers show the rate after restart. The figure plots a schedule, not measured training performance. Details.A discrete convention must specify which update uses the endpoint. For example, sampling phases in the first cycle and restarting before the next step gives rates approximately , followed by . The zero endpoint in the continuous curve is then a limit, rather than an additional zero-rate optimizer step.
Retaining parameters also has a concrete meaning. In an original deterministic gradient descent example with and current , resetting only the schedule leaves . The next step at learning rate0.1 gives0.45; a step at0.01 would give0.495. The restart changes the next movement rather than drawing a new initial parameter. Handling a momentum buffer is a further state convention; restarting the schedule and discarding all optimizer state are different operations. Record cycle phase, durations and rate bounds with an optimization checkpoint.
A mini-batch is a group of training examples processed together in one iteration of a learning algorithm. Its batch size counts examples, while a training epoch usually counts one pass over the available training data. In stochastic gradient descent, a mini-batch gradient combines the component gradients from the selected examples; the group of examples and the resulting numerical estimate are distinct objects.[ref]
Optimizing Model Parameters in the PyTorch tutorials. Hyperparameters and Optimization Loop: batch size, epochs and updates.
For an original counting example, partition eight examples into mini-batches with nominal batch size three and retain the final partial group. The sizes are , giving three updates in one training epoch if each group produces one update. Discarding the final partial group changes which observations participate.
Unequal group sizes also matter when reporting a loss function. At fixed model parameters, suppose the three mini-batch mean losses are . Their unweighted mean is , but the mean over all eight examples isThe smaller last group must not receive the same weight as a larger group when the intended statistic is a per-example sample mean. This bookkeeping issue is separate from the randomness used to select a mini-batch.
Batch size counts the examples combined in a mini-batch. In the simple stochastic gradient descent loop where each group produces one parameter update, it controls how many examples contribute to that update. It differs from a training epoch, which counts a pass over the available training data.[ref]
Optimizing Model Parameters in the PyTorch tutorials. Hyperparameters and Optimization Loop
For an original counting example, partition ten examples with nominal batch size and retain the remainder. The actual sizes are , giving updates per training epoch. Discarding the remainder instead gives two updates and uses only eight examples. More generally the retained-remainder update count is for examples, provided there is one update per group.
Batch size also changes gradient sampling noise. If independently sampled component gradients at a fixed parameter have scalar variance , their sample mean hasFor an original exact example, suppose one component gradient is equally likely to be 0 or 2. Its mean is 1 and variance is 1. A two-example mini-batch gradient takes values with probabilities , giving variance . This calculation holds parameters fixed and assumes independent sampling; sampling without replacement has a finite population correction.
With gradient accumulation, several groups may contribute before an update. Two full four-example groups then involve eight examples per update if their gradients are normalized consistently. State whether a reported size counts the processed group or all examples contributing to an update. Lower sampling variance alone does not establish faster training for a fixed computation budget.
Gradient accumulation combines gradient contributions from several processed mini-batches before one optimizer update. Parameters stay fixed while those contributions are evaluated. With consistent normalization, an additive per-example loss function can therefore use an effective batch size larger than the group processed at once.[ref]
Automatic Mixed Precision examples in the PyTorch documentation. Gradient accumulation subsection and example loop
For an original example, let per-example scalar gradients be at the same parameter value. Process the first two together and the last separately. Their means are 2 and 8. The combined per-example mean isThe unweighted mean of group means is 5 and gives the smaller group too much weight. One implementation accumulates each group's summed loss divided by the total example count, then performs one update.
Accumulation is also different from consecutive updates. Let , with , starting at and using step size . One accumulated mean-gradient step gives . Updating first on the two-example mean gives ; the last example then has gradient , and a second step gives .
The distinction is where the gradients are evaluated. Agreement with one larger group requires fixed parameters and compatible model state, additive losses and consistent weighting. A method whose calculations depend on the whole group can violate those assumptions. State whether batch size denotes a processed group or the complete set contributing to an update.
The effective batch size counts the example contributions combined in one optimizer update, including gradient accumulation and contributions from parallel workers. With workers, accumulated groups per worker and examples in each full group,The PyTorch documentation uses this count to specify when accumulated gradients are unscaled and the optimizer is stepped.[ref]
Automatic Mixed Precision examples in the PyTorch documentation. PyTorch 2.15, Gradient accumulation subsection, effective-batch formula and example loop
For an original example, two workers each process three groups of four examples before updating: . For an additive per-example loss function, the desired gradient is , evaluated at unchanged parameters . If each worker accumulates the three group-mean gradients divided by three, then averaging the two workers' results gives that normalization. Summing the workers instead would double the gradient.
Incomplete groups require their actual counts. Group sizes on each of two workers give , and the combined mini-batch gradient weights each group mean by its example count. Dividing all six group means by six would overweight the two-example groups.
The count describes contributions, not necessarily distinct examples. If both workers process the same twelve example identifiers, there are 24 contributions but only twelve distinct examples. The usual inverse-count reduction of variance requires assumptions about independent random variables; duplication can violate them. Nor does this bookkeeping by itself establish a rule for changing the learning rate.
A mini-batch gradient averages gradients of several sampled components of a finite-sum objective. For and batch indices ,With independent uniform draws at fixed , it is an unbiased stochastic gradient: . Its covariance matrix is , where is the covariance of one sampled gradient. The factor follows because centered independent cross terms have expectation zero.
If the indices are sampled uniformly without replacement, the covariance is instead for , when uses the uniform-population normalization. At this gives the exact full gradient. Larger batches reduce sampling variance but require more component evaluations per update; biased sampling or data dependence requires its own analysis.
Suppose a fixed-step size stochastic gradient descent iteration satisfiesand has a global minimizer . Taking expectations and forming a telescoping sum proves the displayed bound with and deterministic . The Cauchy-Schwarz inequality then bounds the averaged, or the best, expected gradient Euclidean norm by . This is a guarantee of stationarity in the indicated senses, rather than a last-iterate convergence assertion. The additive is a stochastic gradient noise floor.
Target: real-analysis.bigb, under Strongly convex function.A residual accuracy level in a bound for stochastic gradient descent with a fixed step size and nonvanishing gradient noise. For a convex function with an -Lipschitz gradient, step size and conditional total variance at most , typical bounds have floors for averaged squared gradient norms, for averaged gradient norms, and for the best expected objective function gap. Such floors are upper bounds depending on the analysis and assumptions, rather than claims that these exact values are attained or that every last iterate converges.
Target: gradient-descent.bigb, under Stochastic gradient descent.Projected stochastic gradient descent combines a random gradient step with the Euclidean projection onto a convex set:In a finite-dimensional Euclidean space, a nonempty closed convex set has a unique projection. This ensures that the iteration is well defined and feasible. For the scalar constraint , the update is simply .
For every feasible , projection is nonexpansive and fixes , so . This inequality underlies convergence estimates after taking conditional expectations. On a general closed nonconvex feasible set, nearest points may not be unique and this convex projection argument does not apply.
A random vector is an unbiased stochastic gradient at an iterate ifFor an adaptive iteration it is often useful to require the stronger historical condition , where contains all information available before drawing the new sample. This states explicitly which information is held fixed in the conditional expectation.
For , a conditionally uniform index gives . If index instead has positive sampling probability , then is the correctly weighted estimate. Omitting these factors generally changes its expectation.
For example, average and . The two sampled gradients are and , whose average is the true gradient . At the minimizer zero, each sample is nonzero even though its mean vanishes; unbiasedness does not mean zero variance.
For an unbiased stochastic gradient at with finite conditional second moment, expand in the squared Euclidean norm. The cross term has zero conditional expectation, which proves the displayed identity. It separates the squared true gradient from the total conditional variance of its random estimate.
Target: gradient-descent.bigb, under Stochastic gradient descent.A differentiable function has a -Lipschitz gradient on a set if its gradient satisfies Lipschitz continuity there:All norms here are the Euclidean norm. The constant limits how fast the gradient changes; it is not a bound on the magnitude of the gradient. For , the gradient is the linear map . Its operator norm is , so works globally and is sharp by taking . The gradient itself is unbounded on the whole Euclidean space.
If has a continuous Hessian matrix on an open convex set and throughout , integrate that linear map along the line segment from to :The operator norm bound proves the displayed Lipschitz continuity. Convexity of the domain keeps the entire line segment inside it. Bounding the Hessian matrix only at the endpoints is insufficient.
For a continuously differentiable convex function on with coordinate Lipschitz continuity constants , its block coordinate gradient is Lipschitz continuous along each corresponding coordinate subspace, with constant at most .
To prove this without assuming a Hessian matrix, put . Sum the coordinate derivative bound by Bregman divergence over the block, then repeat with interchanged and average:If is supported in the block, the dot product uses only . The Cauchy-Schwarz inequality and cancellation of its Euclidean norm give the result, including the zero case separately. Taking the full block supplies a global Lipschitz gradient constant .
Target: convex-optimization.bigb, under Coordinate descent.Suppose is a differentiable convex function with coordinate Lipschitz continuity constant . Put , the Bregman divergence from the supporting affine function at . The subgradient inequality gives , and its coordinate Lipschitz constant is still . The coordinate descent lemma with step size yieldsSince , rearrangement proves the bound. Continuous differentiability suffices; a Hessian matrix is unnecessary.
Target: gradient-descent.bigb, under Lipschitz gradient.The displayed estimate, for all and real , defines a coordinate Lipschitz constant for the partial derivative in coordinate . It implies the coordinate descent lemmaby the fundamental theorem of calculus and integration of the Lipschitz continuity estimate. Subtracting an affine function leaves these constants unchanged.
The apparently weaker estimate along the singleton negative gradient direction is equivalent when every real step size is allowed: if the initial partial derivative is nonzero, any displacement can be written ; if it is zero but the final partial derivative is nonzero, reverse the endpoints; if both vanish the estimate is trivial.
Target: gradient-descent.bigb, under Lipschitz gradient.Suppose is a differentiable function on an open convex set and has an -Lipschitz gradient there, in the Euclidean norm. For , the descent lemma statesA bounded continuous Hessian matrix gives one sufficient route to this estimate.[ref]
For a short proof, put . The fundamental theorem of calculus along the line segment givesThe Cauchy-Schwarz inequality and the Lipschitz gradient bound make the integrand at most ; its integral is . This proof needs no assumption that is a convex function.
For the gradient descent update , provided , substitution yieldsFor and , this ensures strict decrease whenever the gradient is nonzero. At it guarantees only nonincrease; the quadratic example has a nonshrinking alternating component at this endpoint. At the guaranteed decrease is . A bound valid only on cannot justify a step leaving .
If a fixed admissible step size is used forever, every iterate stays in , and has a finite lower bound, summing this inequality shows , hence . That conclusion alone gives neither convergence of the iterates nor a global minimum. For example, the smooth polynomial has and : gradient descent started at zero never moves, although . On , , so the Lipschitz gradient hypothesis holds on this domain. Convex functions and strongly convex functions provide additional structure; the exact quadratic convergence result above uses a positive-definite matrix.
For with a real symmetric positive-definite matrix and nonzero linear-system residual , exact line search along usesThe objective error contracts by
The objective gap is , so the first ratio is exact. The spectral bounds and prove the displayed inequality. At , the solution is already reached and the step quotient should not be evaluated.
For a real symmetric positive-definite matrix and nonzero linear-system residual , minimize for . Differentiating with respect to gives , yielding the displayed positive step. Positive definiteness makes it the unique minimum along the line. Applying the same quotient to a nonsymmetric or indefinite matrix is a formal iteration, but this minimization proof and its convergence consequences no longer apply.
The conjugate gradient method solves for a real symmetric positive-definite matrix by minimizing over expanding affine Krylov subspaces. Its successive nonzero search directions are A-conjugate directions, so a new line minimization preserves the optimality already obtained along earlier directions.
Start with and stop if it is zero; otherwise put . The recurrence isStop when the new residual is zero, before attempting another division. Each step uses a matrix-vector product, a few inner products and vector updates; a sparse or implicit linear operator can therefore be used without forming its inverse.[ref]
https://netlib.org/templates/templates.html. Templates for the Solution of Linear Systems, §2.3.1, conjugate gradients and symmetric positive-definite assumptions
For , and , the first step has , and . The next conjugate direction is and its step size is , giving the exact solution . Finite termination of the conjugate gradient method is an exact-arithmetic statement; floating-point loss of orthogonality changes the practical stopping analysis.
For a symmetric positive-definite matrix, choose an orthonormal eigenbasis and write the exact solution as . Starting at zero, the conjugate gradient method chooses an admissible polynomial of degree at most the iteration count that minimizes the displayed error. The weights depend on both the eigenvalues and the solution coefficients. For two eigenvalues , the first polynomial is , with . Comparable nonzero coefficients and large give , so the high-eigenvalue error is removed first. A sufficiently tiny high-mode coefficient changes this behavior; the spectrum alone does not determine the first step.
Nonzero vectors are conjugate directions with respect to a symmetric positive-definite matrix when they are pairwise orthogonal in the inner product . They need not be orthogonal in the ordinary Euclidean inner product. They are linearly independent: multiplying a vanishing linear combination by isolates its th coefficient times .
Let be conjugate directions for a symmetric positive-definite matrix . Starting from any , minimize successively along those full lines, stopping early if the linear-system residual vanishes. The quadratic minimization along a line uses and gives .
This makes . For , conjugacy preserves . By mathematical induction, is orthogonal to all preceding search vectors. The conjugate directions are linearly independent and hence form a basis, so . Thus the method reaches the unique solution of the linear system in at most steps in exact arithmetic. The conjugate gradient method generates such directions without storing a complete prescribed basis in advance.
For a symmetric positive-definite matrix , the Conjugate gradient method minimizes the error in the induced weighted norm over its affine Krylov subspace. Writing the error as givesFor , choose the scaled Chebyshev polynomial . On the spectral interval its numerator has absolute value at most one. With , the denominator equals . This proves the displayed bound. If the two endpoints coincide, is a positive scalar multiple of the identity and one iteration solves the system exactly.
The residual of an approximate solution of is . It is the unbalanced right-hand side, while, for an invertible matrix , the solution error is . The conjugate gradient method makes residuals orthogonal to successive Krylov subspaces.
The norm of a linear-system residual, used to measure how closely an approximate solution satisfies its linear system. It differs from the solution-error norm . Their relationship depends on the matrix inverse and the condition number, so a small residual alone is not a scale-free relative-error guarantee.
For a real symmetric positive-definite matrix in exact arithmetic, iteration of the conjugate gradient method satisfiesand itself lies in . These Galerkin conditions imply finite termination once the Krylov subspace becomes invariant under .
The residual orthogonality is the first-order optimality condition for minimizing the quadratic objective on . Floating-point roundoff can destroy exact residual orthogonality, so the identity is a structural exact-arithmetic result.
For a real symmetric positive-definite matrix , choose an invertible change of variables and solveThe transformed matrix is symmetric positive definite because for nonzero . The aim is to improve its condition number or eigenvalue clustering while keeping the transformation inexpensive. The change-of-variables matrix itself need not be symmetric.
A common convention starts instead from a symmetric positive-definite approximate matrix and uses conceptually. If is a Cholesky decomposition, choosing gives an equivalent symmetric transformation. Practical iterations can apply solves with or its factors without explicitly constructing a matrix square root. Applying ordinary Euclidean conjugate gradients directly to the generally nonsymmetric matrix would require accounting for the appropriate transformed inner product.
For a real symmetric positive-definite matrix , choosing gives , so conjugate gradients terminates in at most one step. Constructing or applying the exact inverse square root is generally as expensive as solving the original system.
With zero initial guess, the generalized minimal residual method minimizes the Euclidean norm of the linear-system residual over each Krylov subspace. The Arnoldi decomposition reduces this to , followed by . Givens rotations solve the small problem in operations once the decomposition is available. For an invertible matrix , the same iterate minimizes the error in the weighted norm induced by , because .
One step of restarted GMRES searches along the current residual. In the displayed nonsingular system, the first residual minimization is , whose minimizer is zero. Restarting then repeats the same problem forever and never moves. Unrestarted GMRES instead solves exactly at step two, since span the entire space. Thus a smaller search-space cost can come at the price of stagnation; nonsingularity alone does not guarantee progress for one-step restarting.
Starting with , the Arnoldi iteration constructs an orthonormal basis of successive Krylov subspaces. At step , orthogonalize against , and normalize the remainder as if it is nonzero. The coefficients form an upper Hessenberg matrix and satisfy . A zero remainder means the current Krylov subspace is invariant under .
For a real symmetric matrix , the leading block of the Arnoldi decomposition is both symmetric and an upper Hessenberg matrix, hence a tridiagonal matrix. The resulting three-term recurrence is the Lanczos algorithm. If is a symmetric positive-definite matrix, its compression is too, since for nonzero .
The factorization produced by the Arnoldi iteration, with orthonormal and an upper Hessenberg matrix . Multiplying by identifies its leading square block as .
For a diagonalizable finite-dimensional operator, write with nonzero in distinct eigenspaces of eigenvalues . Then . The Vandermonde matrix of the first powers is invertible for distinct eigenvalues, so these powers span exactly the independent components . Thus the stabilized Krylov subspace dimension is . It counts distinct spectral components, not the number of nonzero coefficients in an arbitrary eigenbasis: , has Krylov dimension one. Equivalently it is the minimum number of eigenvectors needed when those vectors may be chosen freely.
For a real symmetric positive-definite matrix , the conjugate gradient method reaches the exact solution in exact arithmetic after at most the number of distinct eigenvalues active in the initial error, hence after at most steps in dimension .
If those eigenvalues are , the polynomial satisfies and . This is an admissible error polynomial at step . Krylov-space minimization in the energy norm does at least as well, so its error must also be zero. Repeated eigenvalues and absent spectral components can make much smaller than .
The proof assumes exact arithmetic. Roundoff error can spoil exact conjugacy and create residual components absent in the ideal recurrence, so a numerical implementation needs an accuracy-based stopping criterion.
For the quadratic objective with a real symmetric matrix , the Heavy-ball method takesMultiplying by and adding givesUnder the usual zero-initial-momentum choice , one has , so induction expresses every residual as a polynomial in applied to . It belongs to the associated Krylov subspace. With two arbitrary starting iterates, the general expression instead combines polynomials applied to both starting residuals; a single-residual polynomial claim then needs an additional relation between them.
Let with , choose , and put and . The two-by-two heavy-ball error propagation matrix for a scalar eigenvalue has characteristic polynomialAt , its middle coefficient is , giving a repeated root . At , the polynomial is , whose roots are complex conjugates with modulus . Thus the full propagation matrix has spectral radius exactly .
The repeated root can produce an error term , so the spectral radius is an asymptotic rate and does not assert a stepwise error bound with one fixed constant times . For , the parameters reduce to , and the identity-matrix problem is solved in one update. Values are outside the displayed rate convention.
Articles by others on the same topic



Gradient descent is an optimization algorithm used to minimize a function by iteratively moving towards the steepest descent direction, which is indicated by the negative gradient of the function. It is widely used in machine learning and deep learning to minimize loss functions during the training of models.