Solutions to all eight questions of the 18 June 2014 paper. The Scala fragments use the paper's Scala 2 style. Unless stated otherwise, array dimensions and array indices meet the supplied preconditions, and size calculations fit
Int.[ref]Imperative Programming examination paper by the University of Oxford (2014). Cover and pp. 2–15, Questions 1–8
Maintain a processed prefix split into values below the pivot and values at least the pivot. The remaining suffix has not yet been classified. Here The loop invariant isIn addition, the active segment remains a permutation of its original contents, and every entry outside it remains unchanged. If
a and N are the given array and its length.def partition(l: Int, r: Int, p: Int): Int = {
require(0 <= l && l <= r && r <= N)
var k = l
var j = l
while (j < r) {
if (a(j) < p) {
val t = a(k); a(k) = a(j); a(j) = t
k += 1
}
j += 1
}
k
}a(j) < p, swapping it with a(k) extends the first region; the displaced entry, when the two positions differ, already belongs in the second region. Otherwise only the second region grows. The loop variant is . At termination , soThere are exactly iterations, giving time complexity and constant auxiliary space.Take an integer pivot . There are possible values in but only occurrences of such values in the whole array. When , the pigeonhole principle givesRepeated values do not invalidate the argument: they can only reduce the number of distinct values represented by those occurrences. The other side might also contain a missing value.
There are candidate values in and exactly occurrences there. If , thenThus the pigeonhole principle givesThis conclusion does not assert that every value on the lower side is present; duplicates may leave both sides deficient.
Use missing-value search by deficient value intervals: halve the candidate value interval, and apply array partitioning only to the array segment whose entries lie in that interval.The loop invariant is , , andMore precisely, the segment contains all occurrences of original values in , and the complete array remains a permutation of its original state. The occurrences statement is essential: absence from the final segment must imply absence from the original array.
def missing(): Int = {
  require(N < Int.MaxValue)
  var lo = 0; var hi = N + 1
  var l = 0; var r = N
  while (hi - lo > 1) {
    val p = lo + (hi - lo) / 2
    val k = partition(l, r, p)
    if (k - l < p - lo) {
      hi = p; r = k
    } else {
      lo = p; l = k
    }
  }
  lo
}After array partitioning, let , , , and . If , retain the left side. Otherwise the right side hasoccurrences. Either choice preserves the strict deficiency and the all-occurrences condition. The positive integer width decreases, proving termination. At width one, the active segment has fewer than one entry and is empty. ThereforeFor the time complexity, after splits the width is at most , and the scan length is smaller than that width. Summing over the levels gives a geometric series plus logarithmic overhead, hence overall, conventionally for . This proof bounds the retained occurrence count by the retained value width; it does not assume that each array partitioning splits the number of occurrences in half. The case returns zero immediately.
For each row, keep the row run length of the processed prefix. A false entry resets the length to zero; a true entry extends it by one.The outer loop invariant states that rows before
val rowCount = Array.ofDim[Int](N, N)
var i = 0
while (i < N) {
  var j = 0
  var run = 0
  while (j < N) {
    if (a(i)(j)) run += 1 else run = 0
    rowCount(i)(j) = run
    j += 1
  }
  i += 1
}i have all their correct row run lengths. The inner loop invariant states that columns before j in row i are correct and that run is the length of the all-true suffix of a(i)[0..j). Initially this suffix is empty. Updating run gives exactly the suffix length ending at column j, proving the required formula, including zero at a false entry. Every cell is visited once:where the fictitious value at column is zero. The table itself uses storage.Fix the top-right corner and a bottom boundary . A width is feasible precisely when every row has at least consecutive true entries ending at column . Thus the largest feasible width is the minimum of those row run lengths, and the area is that width times .At the loop head, the loop invariant is ,The initial cap makes the empty-prefix case well-defined and cannot restrict any actual run. Each iteration incorporates one new row and tests its corresponding bottom boundary. The loop variant is , soA zero width contributes area zero, covering the case where no nonempty all-true rectangle starts at that corner.
def maxRectangleAt(i: Int, j: Int): Int = {
  var k = i
  var width = j + 1
  var best = 0
  while (k < N) {
    width = math.min(width, rowCount(k)(j))
    k += 1
    best = math.max(best, (k - i) * width)
  }
  best
}Every nonempty axis-aligned rectangle has a top-right corner. Enumerate all such corners and retain the greatest area from part (b).The loop invariant is that
var best = 0
var i = 0
while (i < N) {
  var j = 0
  while (j < N) {
    best = math.max(best, maxRectangleAt(i, j))
    j += 1
  }
  i += 1
}best is the greatest area obtained from the corners processed so far, or zero if there are none. ConsequentlyThe preprocessing cost from part (a) is included. An entirely false matrix, or an empty one, returns zero. In the printed example, rows through and columns through give area ; exhaustive corner enumeration confirms that no larger all-true rectangle exists.[ref]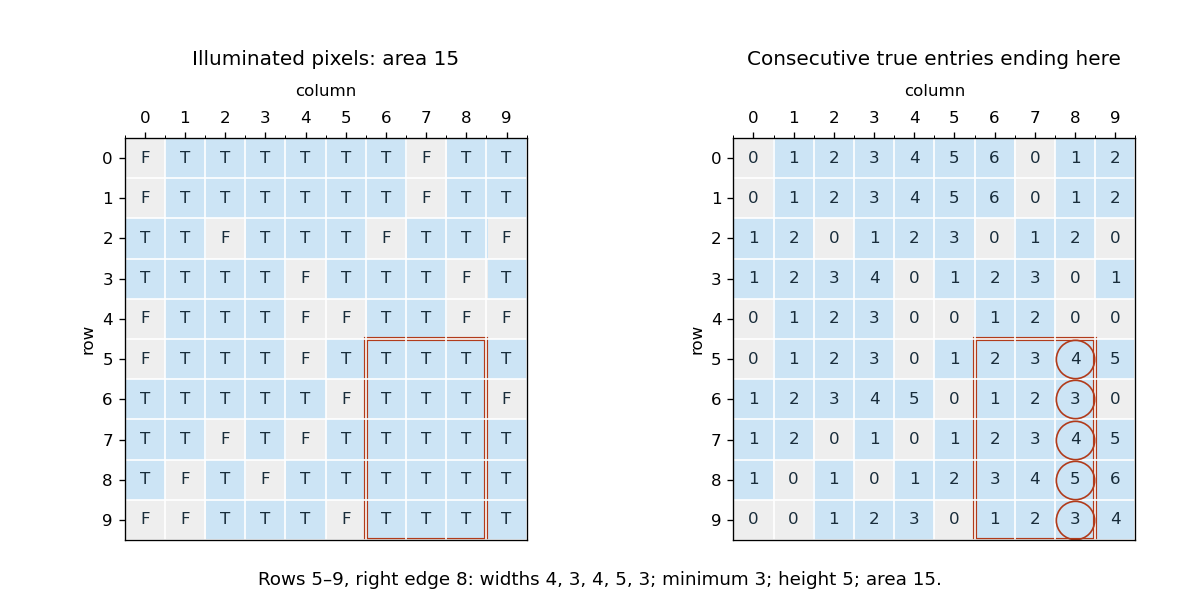

Assume The empty skip list therefore hasThe forbidden data values distinguish the sentinel nodes from genuine entries.
NumLevels >= 1. Both sentinel nodes occur on every level; the tail ends every linked list.val head = new Node(Int.MinValue)
val tail = new Node(Int.MaxValue)
for (level <- 0 until NumLevels) {
head.nexts(level) = tail
tail.nexts(level) = null
}Follow the next reference for the desired level, stopping at the tail. This returns the genuine nodes in their linked list order, excluding both sentinel nodes.Write for the resulting sequence of nodes at level . The abstraction function isIt preserves repetitions, because distinct nodes may carry equal values. A suitable representation invariant requires the following:
def nodesAt(level: Int): List[Node] = {
  require(0 <= level && level < NumLevels)
  val out = scala.collection.mutable.ListBuffer.empty[Node]
  var n = head.nexts(level)
  while (n ne tail) {
    out += n
    n = n.nexts(level)
  }
  out.toList
}headandtailare distinct sentinel nodes with the specified extreme values; every node has anextsarray of lengthNumLevels.- For each level, following references from
headgives a finite acyclic chain ending attail, thennull; the data along that chain are nondecreasing. Genuine values lie strictly between the sentinel values. - Each is a subsequence of by node identity, so the relative order of equal-valued nodes agrees across levels. Every genuine node occurs in and on a contiguous initial collection of levels.
- A genuine node absent from a level has
nullin that level's slot. Tail slots are allnull; every other slot on a chain points to the next member of that chain.
These structural requirements make the traversal terminate and make descending through levels valid. A probabilistic height distribution is a performance policy, rather than a condition needed for the abstraction function to describe an ordered sequence.
Start at the highest level. Move right only while the next key is strictly smaller than At each inner loop head,
x, then descend without returning to head.def findPreds(x: Int): Array[Node] = {
require(Int.MinValue < x && x < Int.MaxValue)
val preds = new Array[Node](NumLevels)
var n = head
var level = NumLevels - 1
while (level >= 0) {
while (n.nexts(level).datum < x) {
n = n.nexts(level)
}
preds(level) = n
level -= 1
}
preds
}n belongs to the current level and has key below x. Every node already passed has key below x. The representation invariant ensures that n also belongs to the next lower level. Stopping just before a key at least x therefore givesThe tail prevents a null dereference during the comparison. Strict comparison makes the predecessor lie before the first occurrence of x, including duplicates. On the source diagram, findPreds(14) yields data , in increasing level order.[ref]Imperative Programming examination paper by the University of Oxford (2014). p. 4, skiplist diagram and Question 3(c)
With the customary random-level policy this has expected logarithmic time complexity for a suitably sized level cap; an unlucky skip list can require a linear scan. No deterministic logarithmic guarantee is claimed.
The level-zero successor of the predecessor is the first node whose value is at least In particular, the tail is never reported as a genuine member:The additional work after the skip list search is constant.
x. Thus only one equality test remains.def contains(x: Int): Boolean = {
if (x == Int.MinValue || x == Int.MaxValue) false
else {
val n = findPreds(x)(0).nexts(0)
(n ne tail) && n.datum == x
}
}Pick the new node's highest level once, and splice the same node into every level up to that height. The fresh array contains
pickLevel must return a value in 0 until NumLevels.def add(x: Int): Unit = {
require(Int.MinValue < x && x < Int.MaxValue)
val preds = findPreds(x)
val highest = pickLevel
require(0 <= highest && highest < NumLevels)
val n = new Node(x)
for (level <- 0 to highest) {
n.nexts(level) = preds(level).nexts(level)
preds(level).nexts(level) = n
}
}null above the chosen height. At each changed level the new node lies after a smaller value and before a value at least x. Every new occurrence is placed before all previous equal-valued nodes, consistently across levels. Therefore the representation invariant is preserved andThe splice work is in addition to one skip list search.Identify the first matching node at level zero, then bypass that node wherever it appears. Comparing keys alone at higher levels could accidentally remove links to a different occurrence with the same key.Because higher-level chains are subsequences of level zero, the predecessor found for any level containing
def delete(x: Int): Unit = {
  if (x != Int.MinValue && x != Int.MaxValue) {
    val preds = findPreds(x)
    val victim = preds(0).nexts(0)
    if ((victim ne tail) && victim.datum == x) {
      for (level <- 0 until NumLevels) {
        if (preds(level).nexts(level) eq victim) {
          preds(level).nexts(level) = victim.nexts(level)
        }
      }
    }
  }
}victim points directly to it: no earlier equal-valued node can intervene before the first level-zero occurrence. Bypassing it preserves the order and nesting of all the linked lists. Levels lacking it are unchanged. ThusThe additional work is . With the usual level cap and random heights, updates have the expected logarithmic time complexity associated with a skip list.The fresh array initially holds null references, whereas a zero row must be an empty list. Initialize every slot explicitly:ThenThe following methods belong inside
for (i <- 0 until N) rows(i) = List.empty[Entry]SparseMatrix, using the supplied Entry and Row type aliases.The representation invariant is ,
rows.length == N, and every rows(i) is a nonnull finite list of entries satisfyingStrict increase excludes repeated columns. The abstraction function gives when the unique entry occurs in rows(i), and otherwise. Thus omitted positions represent zero; omission does not mean an unknown matrix entry.Select entries having the requested column. The representation invariant ensures that the selected list has length at most one.ConsequentlyThis version follows the hint and has time complexity linear in the number of stored entries in row
def get(i: Int, j: Int): Double = {
  require(0 <= i && i < N && 0 <= j && j < N)
  val entries = rows(i).filter(e => e._1 == j)
  if (entries.isEmpty) 0.0 else entries.head._2
}i. An ordered early-exit scan is also possible.Keep the entries before column All indices in
j, discard any old entry at j, and retain those after it. Insert the replacement only when it is nonzero.def set(i: Int, j: Int, x: Double): Unit = {
require(0 <= i && i < N && 0 <= j && j < N)
val before = rows(i).takeWhile(e => e._1 < j)
val after = rows(i).dropWhile(e => e._1 <= j)
val middle: Row = if (x == 0.0) Nil else List((j, x))
rows(i) = before ::: middle ::: after
}before are below j and all in after are above it, so the representation invariant is preserved. Other rows and all other column values remain unchanged:Assigning zero removes storage for that entry. The time complexity is linear in the stored row length.Construct a fresh sparse matrix, transform each stored value, and omit products that become zero.Filtering preserves column order. It handles
def scale(s: Double): SparseMatrix = {
  val out = new SparseMatrix(N)
  for (i <- 0 until N) {
    out.rows(i) = rows(i).map { case (j, x) => (j, s * x) }
      .filter(e => e._2 != 0.0)
  }
  out
}s == 0.0 and any floating point underflow producing zero. Sharing immutable list structure elsewhere would be safe; this code constructs new transformed rows. Within the class, Scala's ordinary private permits access to out.rows. The result isThe time complexity is for stored entries. As usual for the supplied Double model, arithmetic means machine arithmetic; for a finite-real interpretation assume finite operands and products, excluding infinities and NaNs.Entry in source row Before processing source row
i becomes entry in destination row j. Visit source rows in descending order and prepend, producing increasing destination column order without a sorting pass.def transpose: SparseMatrix = {
val out = new SparseMatrix(N)
var i = N - 1
while (i >= 0) {
for ((j, x) <- rows(i)) {
out.rows(j) = (i, x) :: out.rows(j)
}
i -= 1
}
out
}i, each destination row contains exactly the contributions from source rows with index greater than i, in increasing index order. Prepending index i preserves that order, and each source position is unique. Hence the representation invariant holds andThe source sparse matrix is unchanged.For each source row, use a temporary dense array to accumulate contributions from nonzero pairs. For every stored , traverse stored entries in row of the other sparse matrix.During accumulation,
def mult(that: SparseMatrix): SparseMatrix = {
  require(N == that.N)
  val out = new SparseMatrix(N)
  for (i <- 0 until N) {
    val acc = Array.fill[Double](N)(0.0)
    for ((k, x) <- rows(i)) {
      for ((j, y) <- that.rows(k)) {
        acc(j) += x * y
      }
    }
    var j = N - 1
    var result: Row = Nil
    while (j >= 0) {
      if (acc(j) != 0.0) result = (j, acc(j)) :: result
      j -= 1
    }
    out.rows(i) = result
  }
  out
}acc(j) is the sum of the already processed terms contributing to position . Missing entries multiply to zero, so ignoring them loses no contribution under the finite arithmetic convention of part (e). At completion,Descending j and prepending produce strictly increasing stored indices. Omitting zero also handles cancellation. The temporary array uses auxiliary space beyond the output. The time complexity isat worst , but potentially much smaller when the matrices are sparse. The term covers clearing and scanning the row accumulators. Finite-precision rounding can affect the numerical result, as in any Double matrix multiplication.Interpret After calls to
step as a positive increment, consistent with the increasing sequence and exclusive upper bound. State this precondition explicitly; a zero increment would not define the intended finite progression. Use a wider cursor to avoid integer overflow on the update after the last valid Int result.class RangeIter(lower: Int, upper: Int, step: Int) extends Iter[Int] {
require(step > 0)
private var current = lower.toLong
def hasNext: Boolean = current < upper.toLong
def next(): Int = {
require(hasNext)
val answer = current.toInt
current += step.toLong
answer
}
}next, the abstraction function is the sequence of values with , in increasing order. Repeated calls to hasNext do not change it; next removes precisely its first value. ThereforeIf lower >= upper, the represented sequence is empty immediately. The paper does not specify a descending-range convention; this implementation exposes its positive-step precondition rather than assigning one implicitly.A demand-driven filtering iterator needs one cached accepted value. Otherwise The representation invariant says that
hasNext would either lose an element or consume another accepted value every time it is queried.def filterIter[T](p: T => Boolean, it: Iter[T]): Iter[T] =
new Iter[T] {
private var buffered: Option[T] = None
private var finished = false
private def fill(): Unit = {
while (buffered.isEmpty && !finished) {
if (!it.hasNext) finished = true
else {
val x = it.next()
if (p(x)) buffered = Some(x)
}
}
}
def hasNext: Boolean = {
fill()
buffered.nonEmpty
}
def next(): T = {
fill()
require(buffered.nonEmpty)
val answer = buffered.get
buffered = None
answer
}
}buffered holds at most one accepted value. The represented sequence is the buffered value, if present, followed by the subsequence of the underlying remainder satisfying the predicate. Filling moves the next accepted value into the cache and discards only rejected values, so this abstract sequence is unchanged by hasNext. Clearing the cache in next removes its head. Thusnext works even when the client has not first called hasNext; exhaustion violates its stated precondition. As with ordinary iterator adapters, clients should give this wrapper exclusive consumption of it, and the predicate should give a stable answer for each element. One call may scan several rejected elements, but across a complete traversal each source element is consumed once. Cache storage is constant.Use the iterator adapter from part (b) with a primality test by trial division. A composite positive integer has a divisor no greater than its square root.Before each trial division iteration, no integer in divides
def primeIter(upperBound: Int): Iter[Int] = {
  def isPrime(n: Int): Boolean = {
    if (n < 2) false
    else {
      var d = 2
      while (d <= n / d && n % d != 0) d += 1
      d > n / d
    }
  }
  filterIter[Int](isPrime _, new RangeIter(2, upperBound, 1))
}n. If division succeeds, the condition becomes false with , and isPrime returns false. Otherwise the loop ends with , so every possible small divisor has been excluded. The quotient comparison is equivalent to for positive values and avoids integer overflow in d*d.Bounds at most two give an empty iterator. This method tests candidates lazily and uses trial divisions for candidate ; no efficiency requirement in the question forces a sieve of Eratosthenes implementation.Apply overload selection followed by dynamic dispatch: the receiver's static type determines visible signatures, and argument static types choose the overload. The receiver's runtime type then selects its override. A
super call starts at the inherited implementation instead of redispatching to the override just entered.For
c.f1(y), the Y overload is visible on C, so its body in C runs. For a.f2(x), the X signature is selected and its override in C calls C.f1(X). For a.f2(y), the Y signature is selected; its body in C calls super.f1(y). The superclass B has only f1(X), so that call uses B.f1(X).For
b.f3(y), the static type B exposes only f3(X). Its override in C calls super.f2(x), entering B.f2(X). The unqualified f1(x) inside that body still uses dynamic dispatch on the original C instance, so it calls C.f1(X).Finally
c.f4(x) invokes the companion object C, which is a separate receiver extending B. Its f3(X) calls inherited B.f2(X), whose f1 call dispatches to ObjC.f1(X).[ref]Imperative Programming examination paper by the University of Oxford (2014). p. 10, Question 6(a), method bodies and calls
The exact five output lines, including the final comma and space on each line, are:
f1(y:Y) in C,
f1(x:X) in C, f2(x:X) in C,
f1(x:X) in B, f2(y:Y) in C,
f1(x:X) in C, f2(x:X) in B, f3(x:X) in C,
f1(x:X) in ObjC, f2(x:X) in B, f3(x:X) in ObjC, f4(x:X) in C, In Scala trait linearization, the rightmost mixed-in trait takes priority. Merge inherited linearizations while retaining a shared ancestor only at its final position; For example,
super advances to the next implementation in the resulting chain. Ignoring predefined bases, the lookup orders areLife1, Exercise, Work, Life
Life2, Dance, Exercise, Program, Study, Work, Fun, Life
Life3, Program, Study, Work, Dance, Fun, Exercise, LifeDance alone has order Dance, Fun, Exercise, Life. In Life2, the additional Program branch already contains Fun before Life; keeping that shared ancestry in its later position moves Fun after Work, while Dance still takes priority. Reversing the mixins yields the third chain above.Each The
describe first delegates and then prints, so the lines appear in the reverse of the method lookup order. The exact output, including the two blank lines, isI live.
I work.
I exercise.
I live.
I have fun.
I work.
I study.
I program.
I exercise.
I dance.
I live.
I exercise.
I have fun.
I dance.
I work.
I study.
I program.super inside a trait therefore need not call that trait's isolated textual parent; the receiving object's full Scala trait linearization controls the next body.Store characters in a mutable dynamic array. Its length is maintained by the collection, giving constant-time The representation invariant requires a nonnull private dynamic array containing a finite sequence of characters, with its internal collection invariant maintained by the library. The abstraction function isInsertion allows the end position and shifts the suffix right; deletion returns exactly the removed character and shifts the suffix left.
size.class DocImpl extends Doc {
private val text = scala.collection.mutable.ArrayBuffer.empty[Char]
def insert(x: Char, pos: Int): Unit = {
require(0 <= pos && pos <= text.length)
text.insert(pos, x)
}
def delete(pos: Int): Char = {
require(0 <= pos && pos < text.length)
text.remove(pos)
}
def read(pos: Int): Char = {
require(0 <= pos && pos < text.length)
text(pos)
}
def size: Int = text.length
}read leaves the abstract state unchanged. size equals the abstract sequence length in time complexity. Indexed reads are also constant time; insertion and deletion may take linear time, which the question permits.Keep 26 cached counts, updating them after a successful delegated edit. Count exactly lowercase letters; the query alphabet does not make uppercase letters the same character.For an initially empty underlying document that stores inserted arguments unchanged, the representation invariant isInsertion increments precisely the inserted lowercase character's count. Deletion uses the returned character, avoiding an extra indexed read and decrementing the character actually removed. Updating after
trait CharTrackPlugIn extends Doc {
  private val counts = Array.fill[Int](26)(0)
  private def lower(x: Char): Boolean = 'a' <= x && x <= 'z'
  abstract override def insert(x: Char, pos: Int): Unit = {
    super.insert(x, pos)
    if (lower(x)) counts(x - 'a') += 1
  }
  abstract override def delete(pos: Int): Char = {
    val x = super.delete(pos)
    if (lower(x)) counts(x - 'a') -= 1
    x
  }
  def getCount(x: Char): Int = {
    assert(lower(x))
    counts(x - 'a')
  }
}super means a rejected edit leaves the counts unchanged. Both the added update work and getCount use time complexity and fixed storage.The
abstract override methods implement a stackable trait modification: they require a concrete document implementation further along the delegation chain. The invariant above depends on subsequent layers preserving inserted characters. Part (d) deliberately composes a transforming layer that can break this assumption; that is the transform-sensitive trait frequency counter phenomenon.Convert lowercase alphabet letters before passing them to the next implementation. Already uppercase letters and other characters pass through unchanged.The character conversion uses the paper's contiguous lowercase and uppercase Latin ranges. ThusDeletion, reading, and size need no overrides.
trait CapitalisePlugIn extends Doc {
  abstract override def insert(x: Char, pos: Int): Unit = {
    val y = if ('a' <= x && x <= 'z') ('A' + (x - 'a')).toChar else x
    super.insert(y, pos)
  }
}
The rightmost trait intercepts insertion first. In
A, capitalization runs before counting, so the counter receives uppercase A and does not increment the lowercase count. In B, counting receives lowercase a, delegates to capitalization, and then increments the original lowercase argument's counter. Both concrete documents store uppercase A.The exact output isThis illustrates an order-sensitive stackable trait modification. In the second composition the cached count describes intercepted insertion arguments, and no longer the actual lowercase characters in the stored document. For example, deleting its uppercase
0
1A would not decrement the lowercase counter. A counter required to track actual contents under arbitrary transforming mixins would need a stronger composition contract or would inspect the stored character after insertion; such a change would alter the intended behavior of this example.The interval containment order compares the lower endpoints in reverse and the upper endpoints in their ordinary order. The smallest containing integer interval uses the smaller lower endpoint and the larger upper endpoint.Endpoint comparison immediately proves reflexivity, transitivity, and antisymmetry on interval values. If two separately allocated instances have the same endpoints, they denote the same abstract interval; object identity is not the mathematical equality used by this partial order.
class Interval(val l: Int, val u: Int) extends Ordered[Interval] {
  require(l <= u)
  def <=(that: Interval): Boolean = that.l <= l && u <= that.u
  def lub(that: Interval): Interval =
    new Interval(math.min(l, that.l), math.max(u, that.u))
}The returned interval contains both operands. Every other containing interval has a lower endpoint at most both original lower endpoints and an upper endpoint at least both original upper endpoints, so it also contains the returned hull. HenceThis least upper bound need not equal the ordinary union: the hull of and is , including the gap.
Keep precisely those elements with no strictly smaller element in the input. Express strictness using the partial order itself, avoiding reliance on Scala reference equality.In a partial order, means and . ThereforeThe empty set produces the empty set. An incomparable pair is retained in full; a minimal element need not be a least element. At most order comparisons are needed, and only the supplied F-bounded generic interface is required.
def minimal[T <: Ordered[T]](xs: Set[T]): Set[T] =
  xs.filter { x =>
    !xs.exists(y => (y <= x) && !(x <= y))
}Store the minimal elements of the finite generating set. The represented upper set itself may be infinite; the code manipulates its finite basis.The abstraction function and representation invariant areRemoving nonminimal generators preserves the upward closure: in a finite generating set, repeatedly descending below any discarded element must reach a retained minimal element. Thus the constructor represents exactly the required finitely generated upper set.
class UpSet[T <: Ordered[T]](c: Set[T]) extends Ordered[UpSet[T]] {
  private val basis: Set[T] = minimal(c)
  def contains(x: T): Boolean = basis.exists(a => a <= x)
  def intersection(that: UpSet[T]): UpSet[T] = {
    val generators: Set[T] =
      for (a <- basis; b <- that.basis) yield a.lub(b)
    new UpSet[T](generators)
  }
  def <=(that: UpSet[T]): Boolean = basis.forall(a => that.contains(a))
  def lub(that: UpSet[T]): UpSet[T] =
    new UpSet[T](basis union that.basis)
}Membership follows directly from the abstraction function. For intersection, an element lies above some and some exactly when it lies above their least upper bound:The forward implication is the defining leastness property; the reverse uses that is an upper bound and transitivity. ConsequentlyRecomputing minimal elements therefore yields a finite basis for the exact intersection.
For subset inclusion, it suffices that every generator of the left-hand upper set belongs to the right-hand upper set. Necessity holds because each generator belongs to its own closure by reflexivity. Sufficiency holds because the right-hand set is upward closed. Finally,Thus
lub computes union, which is the least upper bound under subset inclusion. The empty basis represents the empty set; all four methods handle it without a special case. As in part (a), two distinct Scala objects may denote the same abstract ordered value. Retaining several equivalent representatives is harmless: they generate the same upward closure, and the strict-comparison test removes only genuinely nonminimal values. Articles by others on the same topic
There are currently no matching articles.