
Past exam of the communication Theory course of the University of Oxford 2008 3 b Solution 2026-10-31
The entropy isTo construct a Huffman code, work with integer weights . Merge the two twos to make four. Of the remaining weights , merge three with the original four to make seven, and merge the new four with five to make nine. Finally merge seven with nine. Resolving the tie in this way gives, for example,This is a prefix code and Huffman's optimality theorem makes it optimal. Its expected length isDifferent choices at a tied merge can give different optimal codewords with the same expected length.
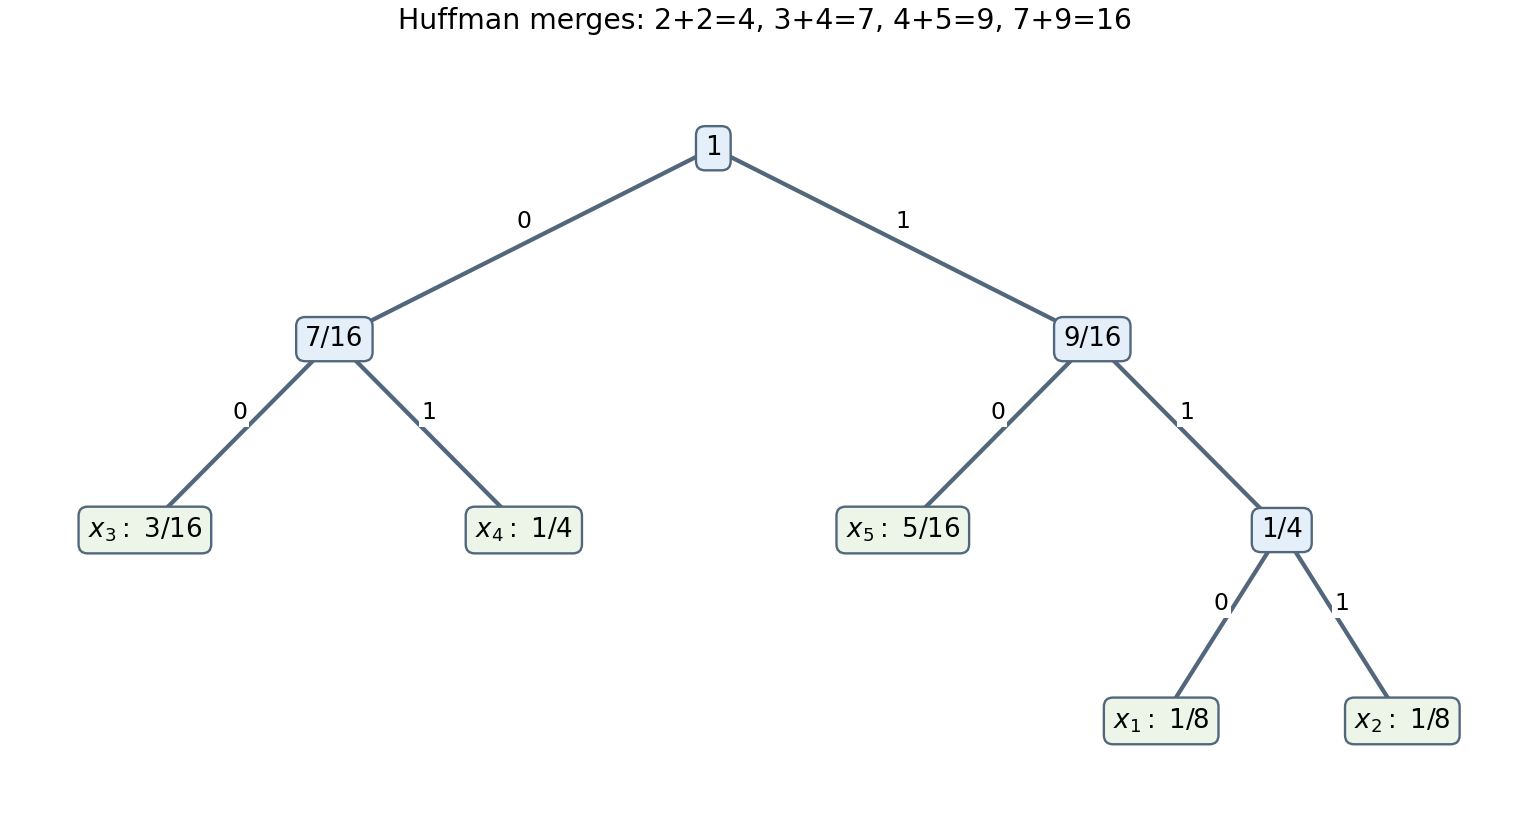
An optimal five-symbol Huffman tree
. Edge labels give the binary digits, leaf labels give the source symbols and their probabilities, and interior labels give total descendant probability. Details. Past exam of the communication Theory course of the University of Oxford 2008 3 a Solution 2026-10-31
Unique decipherability makes the map from to the concatenated binary string injective. Entropy is unchanged by an injective relabelling, and memorylessness gives independence, henceGiven , the string has at most possibilities. The entropy bound for finite alphabets therefore gives . Averaging,The random length cannot simply be discarded: it can also carry information. Let be the maximum codeword length, finite since the alphabet is finite. Since is a function of and takes at most values,Divide by and let . This proves . The conclusion also covers a deterministic source; the source's lowercase in its final expectation denotes the random source letter.
Past exam of the communication Theory course of the University of Oxford 2008 2 b Solution 2026-10-31
Define . The joint entropy identity follows by writing and expanding its logarithm. If , then and , giving the desired decomposition.
Group the first two symbols together and keep the third separate. If , the identity becomeswhere . Binary entropy is at most one, with equality precisely at . HenceEquality holds exactly when . When , , so the same conclusion holds at the boundary.
Past exam of the communication Theory course of the University of Oxford 2008 2 a Solution 2026-10-31
For a finite probability distribution,with . If the positive support has size , apply the given strict Jensen inequality to the random variable :Equality requires and constant almost surely, so all probabilities are . Conversely the uniform distribution attains this bound. Thus , with exactly that equality case.
Past exam of the communication Theory course of the University of Oxford 2008 1 b Solution 2026-10-31
The conditional output distributions are permutations of the same triple, so both conditional entropies equalWith input probability , the three output probabilities are , , and . ThereforeDifferentiating, the constant terms cancel because :Thus there is a unique maximum. Its stationary equation reduces to , whose root in isThe other root is negative; strict concavity proves this is the global maximum.
Past exam of the communication Theory course of the University of Oxford 2007 4 b Solution 2026-10-31
A radius- Hamming decoder outputs the unique codeword within distance of the received word, if there is one. Ambiguous cases and absent candidates can be declared errors, or assigned arbitrarily for an error bound. The average error is the mean of the conditional error probabilities over the equally likely transmitted messages.
Let be the size of a Hamming ball. For any transmitted random codeword, the channel noise weight is . Decoding can fail only if or another codeword lies within distance of the output. Conditional on the output, each independently sampled competing codeword is still uniform on the whole word space, so has probability of lying in that ball. A union bound yieldsThis is an average over the random code construction as well as over messages and noise. It implies existence of at least one deterministic codebook with average error no greater than this bound, rather than asserting the same inequality for every randomly sampled book.
Choose a target rate and a small such that and . Let and . The standard Hamming-volume estimate is : for , each binomial probability term with is at least , and summing proves this bound. Thus the union-bound term decays exponentially, while by the law of large numbers or a Chernoff bound.
There exists a -message book with average error . At least half its messages have individual error at most , by Markov's inequality on the uniformly chosen message. Keep of these and discard the rest. Restricting the decoder's candidate set cannot spoil a previously unique successful decoding. The retained book therefore has maximum error at most . For large its retained codewords must be distinct: identical words could not both have conditional error below one half. This expurgation of a codebook proves reliable communication at every rate below , while converting an average-error estimate into the requested maximum-error conclusion.
Past exam of the communication Theory course of the University of Oxford 2007 4 a Solution 2026-10-31
With equally likely codewords, the prior factor in the ideal-observer criterion is constant, so it agrees with maximum likelihood. On the binary symmetric channel,For this is strictly decreasing in Hamming distance, so the likelihood maximizers are precisely the nearest codewords. With the same tie convention all three decoders therefore agree. At every possible received word equals its transmitted codeword, and the rules agree on all positive-probability outputs; outputs having zero probability need no posterior assignment.
Past exam of the communication Theory course of the University of Oxford 2007 3 c Solution 2026-10-31
Exchanging the first and third inputs, together with the corresponding outputs, leaves the channel unchanged. Concavity therefore shows that averaging an input distribution with its exchanged distribution cannot reduce mutual information. We may take input probabilities .
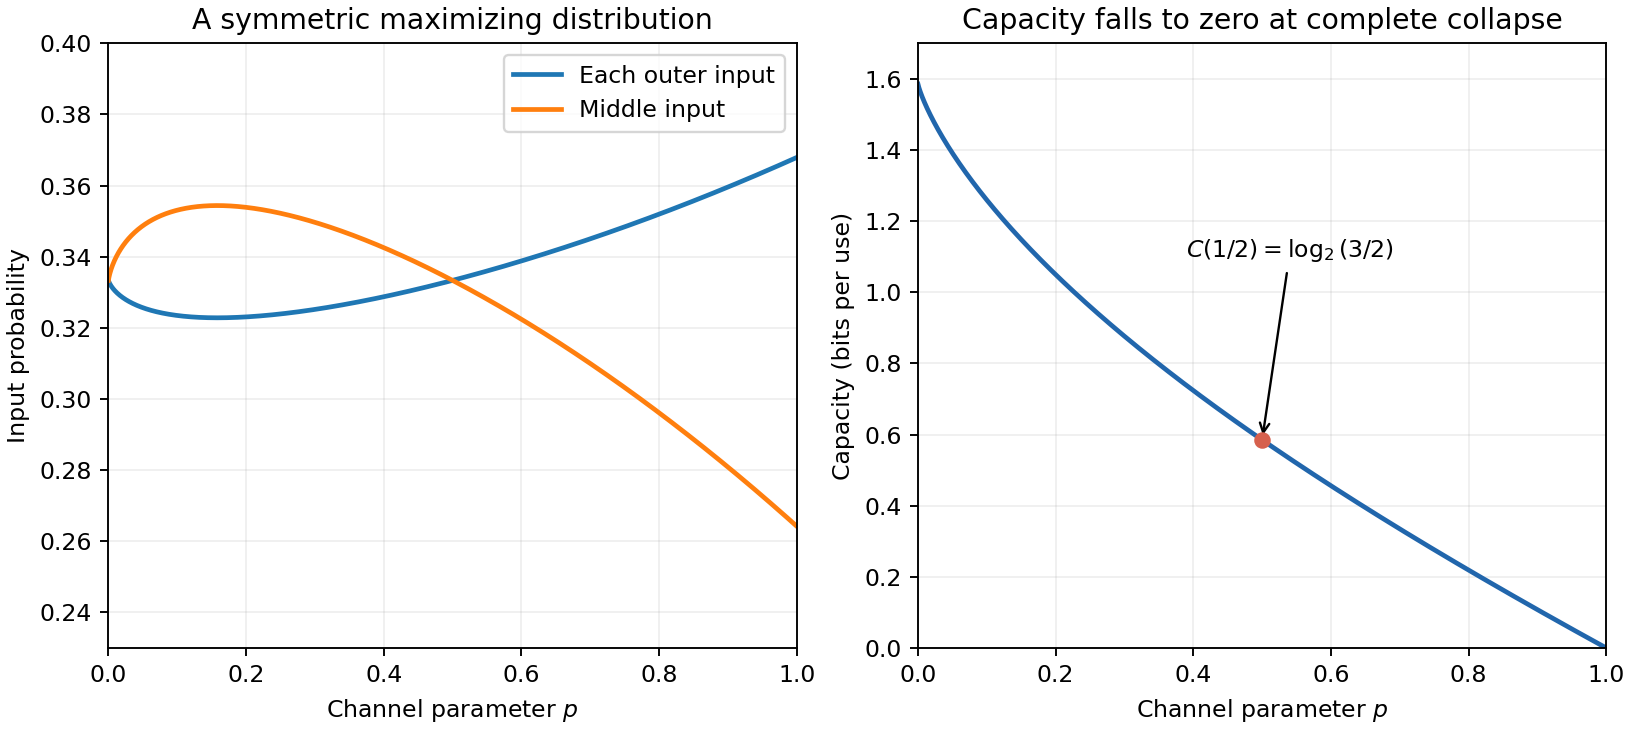
For , put and , so . The output distribution is and the mean conditional output Shannon entropy is . HenceIts strict concavity gives the unique stationary value . This lies in the allowed interval: for , the derivative at is , while it tends to positive infinity at zero. At the stationary value is directly. Consequently an achieving input distribution isThe resulting capacity is . In particular at , andAt all outputs are the middle symbol, so and every input distribution achieves it; the divided formula is not used at that endpoint.


Past exam of the communication Theory course of the University of Oxford 2007 3 b Solution 2026-10-31
Gibbs inequality makes mutual information nonnegative, so . The two conditional-Shannon entropy expressions giveEach Shannon entropy is bounded by the base-two logarithm of its alphabet size. Maximizing over the input distribution therefore gives for the smaller size .
Past exam of the communication Theory course of the University of Oxford 2007 3 a Solution 2026-10-31
The channel matrix has entries , with nonnegative entries and each row summing to one. For an input distribution , it induces the joint law . Its capacity in bits per use isOn finite alphabets the maximum exists by continuity on the compact probability simplex.
Past exam of the communication Theory course of the University of Oxford 2007 2 c Solution 2026-10-31
At an interior tree node write for the total masses in its two children, and . Counting path lengths and telescoping the Shannon entropy over the binary decisions givesIndeed each symbol contributes its probability once per ancestral interior node to the first sum. In the second sum, expanding cancels the interior terms and leaves the source Shannon entropy. The supplied inequality now bounds redundancy byConsider the cut between adjacent symbols made at one node. If its left side is heavier, moving its last symbol to the right must not improve the chosen cut. Writing , this says , which implies ; when the left side is a singleton the same bound is immediate. If the right side is heavier, the corresponding argument gives . In all casesRecursive subdivision of contiguous blocks uses each original gap exactly once. Summing over the gaps therefore givesproving . If probabilities are already nonincreasing, each maximum is and the improved bound is . Thus the sorted version has expected length less than , although it need not be optimal. For one symbol the assertions hold directly. This is the Fano slice code redundancy bound.
Past exam of the communication Theory course of the University of Oxford 2007 2 b Solution 2026-10-31
Work on the source support, so its listed probabilities are positive; zero-probability symbols may be omitted. An optimal binary prefix code minimizes the expected codeword length for that distribution. The same optimal expected length is attained when optimization is over uniquely decipherable codes, by the converse and existence parts of Kraft–McMillan inequality.
Choose Shannon lengths . They satisfy , so the preceding existence theorem gives a prefix code with those lengths. Also for every symbol, including the integer cases. Thus its expected length is less than . An optimal code cannot have a larger expected length, provingFor a deterministic one-symbol source the empty word has length zero, consistent with this bound.
Past exam of the communication Theory course of the University of Oxford 2007 2 a Solution 2026-10-31
A binary prefix code assigns distinct finite binary strings to the source symbols, with no assigned string a prefix of another. It is instantaneous because a complete codeword is recognized without needing the next word's bits.
Associate a word of length with its dyadic subinterval of of length . A prefix relation corresponds to interval containment. Prefix-free words therefore give disjoint intervals, whose total length is at most one. This proves necessity of Kraft inequality.
For sufficiency, sort the requested nonnegative integer lengths increasingly and construct a code greedily in a binary tree. At depth , the preceding codewords forbid exactly nodes. The assumed inequality, retaining the positive contribution of the present word, bounds this integer by . Thus at least one node is available; choose it. It is not below an earlier codeword, and the nondecreasing lengths prevent it from being a proper ancestor of an earlier word. Continue to obtain a prefix code of all the required lengths. Hence
There are unlisted articles, also show them or only show them.