
Past exam of the communication Theory course of the University of Oxford 2011 2 c Solution 2026-10-31
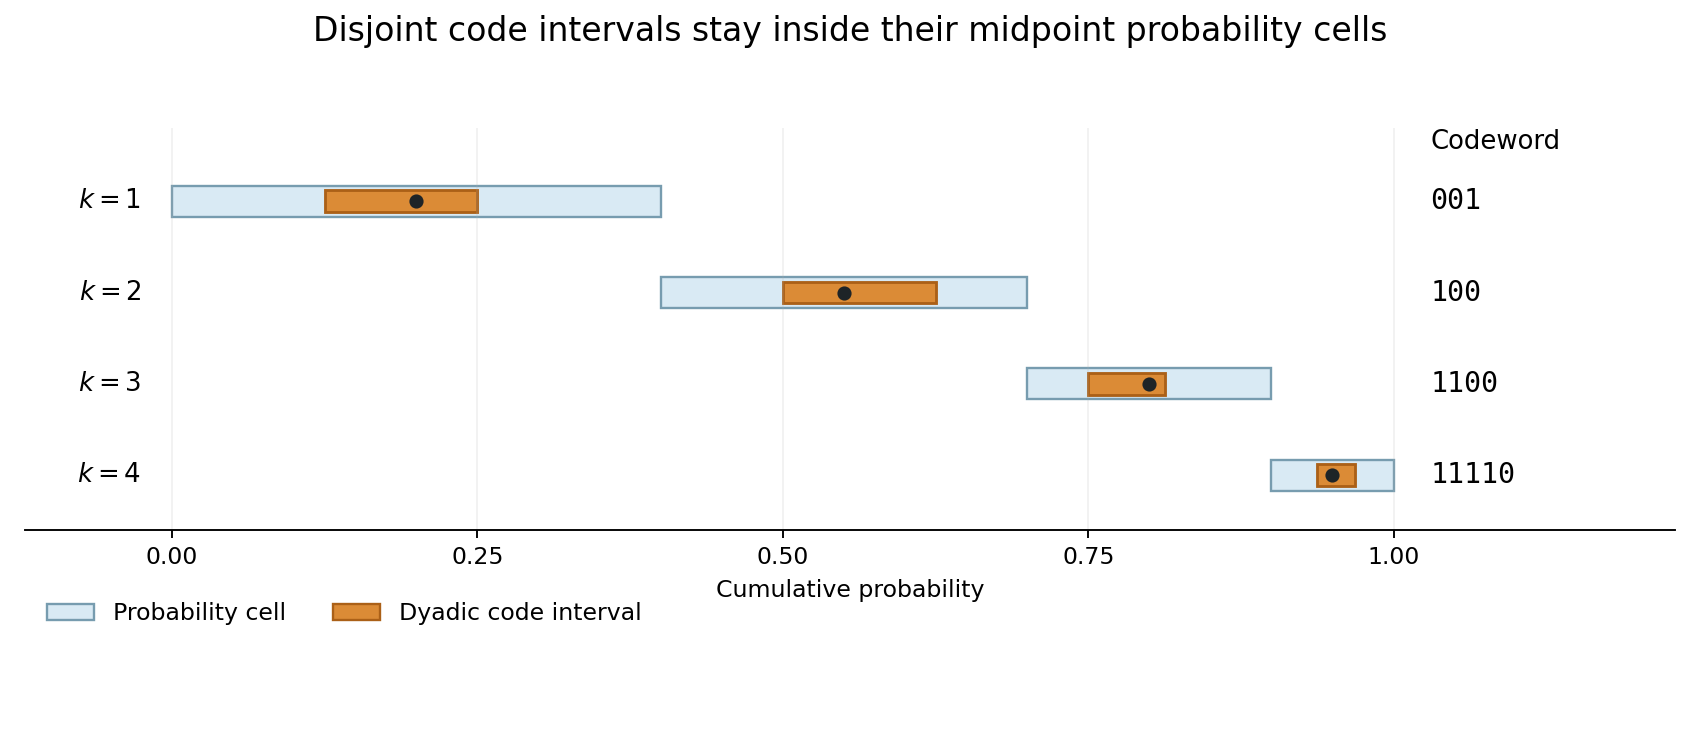
Let and let be the probability cell of symbol . Its midpoint is . Use the binary expansion terminating in zeros at a dyadic rational, so truncation to bits givesThe chosen codeword corresponds to the dyadic interval . It contains , and its width satisfies . ConsequentlyThus . The probability cells are disjoint, so the code intervals are disjoint. If one binary codeword were a prefix of another, its dyadic interval would contain the other's interval, contradicting this disjointness. Hence the code is instantaneous.
Finally, . Multiplying by and summing yieldsThis is the Shannon-Fano-Elias code: the extra bit makes the dyadic interval narrow enough to remain inside the cell around its midpoint.

Past exam of the communication Theory course of the University of Oxford 2011 1 c Solution 2026-10-31
Write . For each row put ; the positive row entries form a probability distribution because the row sum is one. When , define the probability distributionPart (a), applied on this row support, gives . Its weighted sum expands asRows with contribute zero, since all in such a row vanish. Using the convention that zero-weight logarithmic terms are zero, the result isBoth stochasticity conditions have a role: row sums normalize the comparison distributions, while column sums preserve the total contribution from .
Past exam of the communication Theory course of the University of Oxford 2011 1 a Solution 2026-10-31
Use the continuous convention . Let . Applying the allowed logarithm inequality to for givesHence . Equality forces . Since every is strictly positive, this makes the entire alphabet. Equality in every weighted logarithm inequality then forces for every . Conversely makes every summand zero. ThusThis is Gibbs inequality for relative entropy, with zero probabilities in the first argument handled explicitly.
Past exam of the communication Theory course of the University of Oxford 2010 3 b Solution 2026-10-31
Fix the channel matrix . The mixed input induces the mixed output . The concavity of information entropy impliesFor completeness, the difference is by Gibbs inequality, including zero coordinates with the usual conventions.
On the other hand, conditional output entropy is linear in the input law:Subtracting gives the concavity of mutual information in the input distribution:This makes maximizing mutual information over the input probability simplex a concave optimization problem: a local maximum is global. It also justifies averaging input distributions over channel symmetries when searching for an optimum, since symmetry averaging cannot lower the achieved mutual information. The channel itself is held fixed throughout.
Past exam of the communication Theory course of the University of Oxford 2010 3 a Solution 2026-10-31
For a finite joint distribution, the mutual information isZero-probability terms contribute zero. It measures the reduction in uncertainty about one variable upon observing the other.
A discrete memoryless channel has discrete input/output alphabets and a fixed transition matrix . Over successive uses it obeysThus the output at a use depends on that input and no other channel history. Its channel capacity isin bits per use for base-two logarithms. On finite alphabets the maximum exists by continuity on the probability simplex; for more general discrete alphabets one uses a supremum.
Past exam of the communication Theory course of the University of Oxford 2010 2 c Solution 2026-10-31
Given an output of positive probability, the ideal observer chooses a symbol maximizing the posterior:Ties may be broken arbitrarily, and the choice at an impossible output does not matter. This is maximum a posteriori decoding. It minimizes conditional error at each , because a deterministic decision is correct with probability ; a randomized decision is a weighted average of these success probabilities and cannot exceed their maximum.
Write . Then . Applying the two cases from part (b) to the posterior distribution givesAverage with respect to the output law to obtain the conditional entropy upper bound on minimum decoding error:This is an upper bound on the optimum error probability; it does not hold for arbitrary deliberately poor decoding rules.
There are unlisted articles, also show them or only show them.