
Read the lower-left entry of each cell as player 1's payoff and the upper-right entry as player 2's payoff, as indicated by the source diagram. Against , player 1 strictly prefers because ; against , player 1 strictly prefers because . Against , player 2 strictly prefers because ; against , player 2 strictly prefers because . Thus the pure strategy Nash equilibria are
For a fully mixed strategy Nash equilibrium, write and . Player 1's expected payoffs from the two pure strategies areEquality, required when both pure strategies have positive probability, givesPlayer 2's corresponding expected payoffs areso equality givesBoth probabilities lie strictly between zero and one. Hence the unique fully mixed strategy Nash equilibrium iswith complementary probabilities on and . Its expected payoffs are
These are all three Nash equilibria. There are no equilibria with just one player genuinely mixing: against each opposing pure strategy, the other player's best response is unique, so that player cannot mix. When both players mix, the two linear indifference equations have the unique solution just obtained. This is support enumeration for a bimatrix game with all possible supports checked.
For the intended finite representation, put . For each , form the mintermA Boolean valuation satisfies exactly when its selected subset is . Therefore the weighted formula utility representationrepresents exactly: at the Boolean valuation for , only that minterm contributes, with weight . This proves completeness and the bound of rules simultaneously. Zero-weight rules may be omitted. The bound counts rules; writing each minterm also requires symbols in Big O notation.
For the computational question, assume rule weights are rational numbers encoded in binary. This makes exact equality of sums a finite computational task. With this conventional encoding, equivalence of weighted formula utility representations is co-NP-complete.
For membership, the complement has a short witness: a Boolean valuation on the variables occurring in either rule base. Evaluate each propositional formula, sum the weights of satisfied rules, and accept the witness if the sums differ. Propositional formula evaluation takes polynomial time. Exact sums of binary rational numbers also have polynomially bounded bit lengths: the product of their denominators has bit length at most the sum of the input denominator lengths. Thus non-equivalence lies in NP, and equivalence lies in co-NP.
For hardness, take a Boolean satisfiability problem instance and constructThe first utility function is one at satisfying Boolean valuations and zero elsewhere, while the second is always zero. ConsequentlyThe unsatisfiable Boolean formula problem is co-NP-complete, as the complement of the NP-complete Boolean satisfiability problem. The construction is a polynomial-time reduction, proving hardness even with the single weight .
Two qualifications matter in the literal wording. First, unrestricted real weights have no specified finite encoding, so a standard bit-complexity classification needs the encoding assumption above. Second, the problem says only that is nonempty. If infinite is allowed while rule bases remain finite, its completeness claim is false. For , take when is infinite and when is finite. A finite rule base mentions only a finite subset of the variables. The Boolean valuations for and agree on all those variables but have different required values. No such rule base represents this . Thus the construction answers the intended finite-set question and identifies the missing hypothesis in the unrestricted statement.
Yes: the stated order has an expected utility representation. For outcomes whose monetary amounts are , respectively, chooseThenSince , this utility function gives exactly the required strict preferences.
The distinction is that the expected utility hypothesis does not by itself require the utility function to increase with monetary amount. This nonmonotone monetary utility ranks the outcome paying 2 below the outcome paying 1. If increasing monetary utility were imposed as an additional assumption, the stated order would fail: requires becauseThat additional monotonicity assumption is not printed in this part.
Under the expected utility hypothesis, use positive affine uniqueness of affine preference representations to normalize the extreme outcomes to and . The stated indifference relations then giveThe two lotteries have expected utilitiesHence , with normalized expected utility difference . Equivalently, substitution reduces them to lotteries with probabilities and of the better extreme outcome. The inference uses the independence axiom for lottery preferences; the three displayed outcome comparisons alone would not determine preferences over all compound lotteries without the expected utility hypothesis.
Assume the standard empty-coalition normalization . A convex cooperative game has increasing marginal contributions: whenever and ,This follows from the supermodular inequality applied to and . Fix a permutation of all players, let be the players preceding , and form its marginal contribution vectorSumming along the full permutation is a telescoping sum, so . For an arbitrary coalition , list its members in their induced order , and put . Since , increasing marginal contributions giveThus every marginal contribution vector belongs to the core. The vector of Shapley values is exactly their uniform average over the permutations, hence a convex combination. By the preceding part, that average is in the core. This proves that the Shapley value allocation belongs to the core of a convex cooperative game, including every coalition constraint. It is the result Shapley value belongs to the core of a convex game.
Write . The core of a cooperative game isTake any and , and form the convex combination . Its total payoff is . For every coalition ,Hence remains in the core. The core is a convex set, even when the transferable utility game is not a convex cooperative game. An empty core is a convex set vacuously; the argument does not claim nonemptiness. Geometrically, the same conclusion follows because the constraints intersect an affine hyperplane with closed half-spaces.
Against Tit for tat, let be an arbitrary deviator's action at round , and set to encode the opponent's initial cooperation. The opponent then plays . Define and . The four possible transitions giveThus every stage payoff is at most . The telescoping sum yields the uniform payoff bound against Tit for tat:After division by , no long-run average payoff can exceed three. The bound applies to every action sequence, so in particular it covers every finite-state machine representing a unilateral deviation. Mutual Tit for tat produces in every round and gives each player three. Neither player can improve, proving is a Nash equilibrium.
Another pair is . Here grim trigger initially cooperates and continues cooperating until the opponent first defects, after which it defects forever. Both strategies are two-state finite-state machines: Tit for tat records the opponent's previous action, while grim trigger records whether defection has ever occurred. Their prescribed play again consists entirely of cooperation and gives .
The player using grim trigger faces Tit for tat, so every unilateral deviation is bounded by the same telescoping sum and cannot improve on three. The player using Tit for tat faces grim trigger. If that player never defects, the payoff remains three. If the first defection occurs at a finite round , it gives a one-time payoff six; thereafter the opponent always defects, against which each subsequent payoff is at most one. Any finite initial prefix has zero contribution to the long-run average payoff, so such a unilateral deviation has limiting upper average at most one. It cannot improve on three either. Both players are therefore best responses, proving the second claimed Nash equilibrium.
For deterministic finite-state machines, the joint state path is eventually periodic, so the displayed averages have a limit. The first bound also controls the limiting upper average for arbitrary action sequences, making the no-improvement argument stronger than an enumeration of finite-state deviations. Notice that equality in the bound permits alternating exploitation to average three: equilibrium requires absence of a strict improvement, not uniqueness of a best response.
There is no perfect recall. Player 1's later information set joins histories following both of her initial actions, so she has forgotten whether she chose or . It also hides player 2's intervening action, but failure to observe another player's action is imperfect information, whereas forgetting one's own earlier action is the particular violation of perfect recall. Player 2's two nodes form a single information set because player 2 does not observe the initial choice.
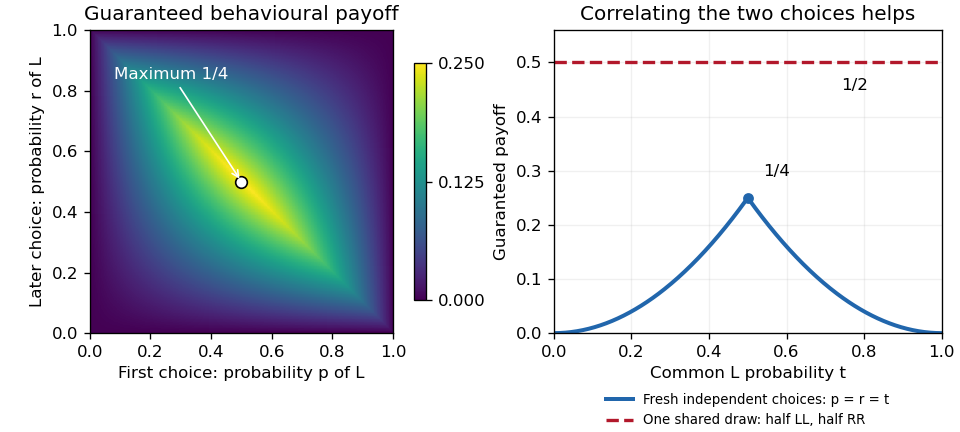
For a behavioural strategy, let be player 1's initial probability of and her later probability of . These are separate information sets, so and need not be equal; their random draws are independent. Name player 2's unlabeled branches left and right, and let be the probability of taking the left branch. The only unit-payoff paths are left–left–left and right–right–right. ConsequentlyBecause this is a zero-sum game, the natural meaning of the claimed best behavioural strategy is its maximum guaranteed expected payoff. Player 2 can choose either branch, so the guarantee at isFor nonnegative numbers, their minimum is at most their geometric mean. Also and , henceTaking makes both possible branch-conditioned success probabilities , so this upper bound is attained against every . Thus the optimal guaranteed behavioural strategy success probability is .
A mixed strategy can instead select the complete plan with probability and the complete plan with probability . The two choices within a sampled plan are correlated. If player 2 chooses left, exactly the sampled plan succeeds; if player 2 chooses right, exactly succeeds. Therefore the success probability isagainst every opposing mixed strategy. It is optimal among mixed strategies too: player 2's uniform mixture gives success probability to each of and zero to , so no mixture of the four plans can exceed against that opponent. This establishes mixed and behavioural security levels without perfect recall directly.

The succinct input is the players' variable-control sets, their goal propositional formulas, and a complete candidate Boolean valuation; an exponentially expanded payoff matrix is not part of the input. This representation is essential to candidate equilibrium checking in a Boolean game.
For membership in co-NP, consider the complement: the candidate is not a Nash equilibrium. A complexity certificate consists of a player and an alternative Boolean valuation of that player's controlled Boolean variables. Evaluate the current goal and the goal after this unilateral deviation, keeping every other player's variables fixed. A profitable unilateral deviation exists precisely when the current goal is false and the new goal is true. The certificate has at most the number of input variables plus the player index, and both propositional formula evaluations take polynomial time. Thus the complement belongs to NP, and the original decision problem belongs to co-NP.
For hardness, start with a propositional formula and introduce a fresh Boolean variable . Construct a one-player Boolean game in which that player controls and has goalChoose the candidate pure strategy assigning every variable false. Its payoff is zero because is false, regardless of . If has a satisfying assignment, changing to that assignment and to true is a profitable unilateral deviation. If is an unsatisfiable Boolean formula, no unilateral deviation can satisfy the goal. ThereforeThe construction increases the formula length by only a constant and writes a candidate of linear length, so it is a polynomial-time many-one reduction. Unsatisfiability is co-NP-complete; combining hardness and membership proves that candidate Nash equilibrium checking for Boolean games is co-NP-complete. If a convention requires at least two players, add a player controlling a fresh unused variable and having the always-true goal; this changes neither direction of the proof.
Represent satisfied and unsatisfied goals by payoffs one and zero. The second player's goal is an exclusive or: it is true precisely when , independently of . The first goal is false only when all three Boolean variables are false. The resulting payoff matrix is below; each boxed entry marks that player's best response to the opposing pure strategy, including ties:For player 1, choosing satisfies the goal against every opposing pure strategy. Choosing does equally well except against , where it does worse. Thus is player 1's unique dominant strategy in the weak sense, and there is no strictly dominant strategy. The ties are why most first-player entries in both rows are boxed.
For player 2, either pure strategy with is a best response against , while either with is a best response against . No one choice of works against both rows, so player 2 has no dominant strategy, and there is no dominant-strategy equilibrium. The value of does not affect player 2's own payoff.
The cells with both entries boxed give exactly four pure strategy Nash equilibria:All four give payoffs . In particular, the weakly dominated choice can occur in a Nash equilibrium because player 1 is already satisfied there and cannot strictly improve.
Reading the lower-left number in each source cell as player 1's payoff, against an opponent playing the player's own payoffs from are ; against they are . For , identify with aggressive defection and with yielding cooperation. The standard payoffs then have valuesThe prisoner's dilemma ordering holds precisely for and with this labeling. For example, gives . Each player then has the strictly dominant strategy , although gives both a larger payoff than . Here as well, so the optional weak aggregate-payoff condition is met with equality.
For the Chicken payoff ordering, the collision outcome must be worse than yielding to an aggressive opponent: . This holds for and , for example . Against , the best response is because ; against , it is because . Consequently and are the two pure strategy Nash equilibria, and mutual aggression is the worst outcome for both.
If action names may be exchanged, there is another prisoner's dilemma region: take as cooperation and as defection. Then , so and also work, for example . This relabeling explains why the first displayed region is not a necessary condition without an action convention. Equality at any of these boundaries destroys the strict ordering.
First evaluate the inner lottery: . By reduction of compound lotteries, the outer expected utility isSince lies in the permitted real interval, the square is minimized there. The unique maximizer and maximum expected utility are and . Directly flattening the lottery gives probabilities , and for the three outcomes; these sum to one and give the same expression.
Write and for the two deterministic outcomes. Under the expected utility hypothesis, indifference between them implies . The expected utility of the fair lottery is consequentlyIt must therefore be indifferent to each deterministic outcome, contradicting the asserted strict preference. These preferences do not admit an expected utility representation over the stated outcomes. Equivalently, affine utility on probability measures preserves this indifference under mixing, as required by the independence axiom for lottery preferences.
A concern for the fairness of the procedure can be perfectly intelligible. It would require enlarging the outcome description to include the procedure; it cannot be represented by an expected utility over only the two final gift recipients while retaining the stated strict preference.
Let denote the monetary reward. Its expected value and expected utility are different quantities:Thus indifference to a sure nonnegative reward requires , giving dollars. This is the certainty equivalent, hence the lottery's monetary value in the question's comparison with a sure reward. The utility function is increasing and strictly convex on nonnegative monetary amounts. Its certainty equivalent exceeds its expected value, , demonstrating risk seeking; the same conclusion follows from the Jensen inequality.
The wording about paying an entry fee needs a qualification. A certainty equivalent compares a gross lottery with a sure gross reward; a literal utility indifference price also accounts for the fee's effect on wealth. If instead describes final wealth, with initial wealth and fee , the comparison is , on a domain where the utility function is increasing. Here , so the nonnegative-wealth branch gives whenever that branch is admissible. An initial wealth and an admissible payment domain are not specified. Therefore is the determined certainty equivalent, while a literal wealth-dependent maximum fee is not uniquely determined. This is the distinction in certainty equivalent and willingness to pay. If negative rewards were allowed without requiring an increasing utility function, the equation for also has the algebraic root ; the usual nonnegative-reward interpretation selects the positive root.
There are unlisted articles, also show them or only show them.