A complexity class is a collection of computational problems sharing specified resource bounds and a computational model.
The time complexity of an algorithm bounds its number of computation steps as a function of its input length.
Specify both the size parameter and the operations counted. For binary search, take to be the number of array entries and count a three-way comparison of the target with one entry as one operation. Code using separate equality and less-than tests may perform two primitive tests per inspected entry; this changes a constant factor. The input size in bits is a different parameter when entries have variable-length representations.
Worst-case time complexity maximizes the count over permitted inputs of size . An absent target forces comparisons in linear search. For binary search, the worst-case count is for , attained by a target larger than every entry. Both have a best case of one comparison when the first inspected entry matches.
In Big O notation, the worst-case bounds are and respectively. Here means that fixed constants exist with for all . It is an upper bound, so a logarithmic count is also ; the sharper bound communicates its scaling better. The base of the logarithm changes only a constant factor.
For , linear search can require comparisons, whereas binary search needs at most , since . Doubling adds just one to the worst-case binary search count. These are operation counts, not measured machine runtimes. Translating them into logarithmic execution time assumes constant-cost indexed access, comparison and index arithmetic. Long entries can make comparison expensive; a linked list does not provide constant-cost access to an arbitrary middle index. Building or sorting the array is additional work: merge sort can provide order for many subsequent searches, but its cost belongs in the analysis too.
A time complexity bounded by for a polynomial , where is the encoded input length. This usage includes bounds such as ; it need not mean only .
The complexity class of formal languages decidable in deterministic exponential time. It contains NP: enumerate the finitely many choices of a polynomial-length nondeterministic computation and simulate each branch with a polynomial time cutoff. There are at most branches for fixed branching bound and polynomial .
For every constant , a deterministic multitape Turing machine with more than one tape and time complexity bounded by has an equivalent machine with the same tape count and bound , allowing a larger finite control and tape alphabet. Blocks of old symbols become single new symbols, and finite control implements blocks of old steps. The linear overhead accounts for initial input packing. If , the overhead can be absorbed to obtain any fixed constant speed increase for sufficiently large inputs. This does not supply unlimited speed increases for operations on fixed hardware.[ref]
Computational Complexity, slides 1 by Paul W. Goldberg (2023). Slides 47–48, PDF pp. 62–63: formal statement and block-simulation construction
A computation-cost convention assigning constant cost to specified primitive operations. For exact unbounded integer arithmetic this can differ substantially from bit complexity: a multiplication of increasingly large values is one primitive operation but requires more bit operations. State which convention is used when estimating an algorithm's running time.
A combinatorial explosion is a rapid increase in the number of candidates generated by a search over combinations, often exponential or factorial in an input parameter. For example, listing all subsets of an -element set produces candidates, while listing all permutations produces candidates. In contrast, listing only fixed-size -element subsets has time complexity at least for fixed : potentially large, but polynomial rather than exponential in .
A time complexity polynomial in numerical input values, which need not be polynomial in their binary encoding lengths. For example, an knapsack algorithm depends on the capacity , while its input representation needs only bits for that capacity.
A time complexity bounded by for input size . Examining every ordered pair of entries with constant work per pair has this bound.
A time complexity bounded by for input size . A single pass with constant work per input entry has this bound.
A time complexity bounded by independently of input size, under a stated computational cost model. Fixed-size machine arithmetic may be constant time, whereas arbitrary-precision arithmetic depends on operand length.
An algorithm has pseudo-polynomial time when its running time is bounded by a polynomial in the numerical magnitudes of input quantities, rather than necessarily in their encoded length. The dynamic programming table for the 0-1 knapsack problem uses arithmetic operations for items and capacity . A binary numeral system encoding needs only bits for that capacity, so the table bound can be exponential in the number of capacity bits. This distinction does not claim that every input requires exponential work.
Amortized analysis bounds the total cost of every permitted sequence of operations from a specified initial state. An amortized bound means that some constants satisfy for every such sequence of length . The cost model and allowed operations are part of the claim; Big O notation alone does not specify them.
- A worst-case bound for one operation limits its cost in any reachable state. Summing these separate maxima can overestimate the cost of a whole sequence because expensive states may take many cheap operations to rebuild.
- An amortized analysis limits the total over every allowed sequence, including an unfavourably chosen one. Dividing that bound by the number of operations is a deterministic guarantee about the sequence.
- A probabilistic average-case analysis bounds an expected value under a stated probability distribution on inputs. For a randomized algorithm, an expected value can instead average over its random choices. Neither interpretation is required by a deterministic amortized analysis.
This distinction, and the credit and potential method viewpoints, are developed in R. Endre Tarjan's 1985 paper Amortized Computational Complexity, sections 1–2, pp. 306–308. The dynamic array doubling example below shows how an expensive operation can pay for itself through the cheap operations that precede it.
For an initially zero -bit binary counter, suppose changing bit costs . It changes exactly times in increments. Consequently the total is for . The upper bound counts at most cost at each active position; the lower bound uses for . This shows why exponential position costs cancel the decreasing carry frequencies that make the ordinary binary counter have constant amortized cost.
An amortized analysis can bound the total time complexity of every allowed sequence of operations by , where is a size parameter and accounts for initialization or the specified initial state. The bound is then an amortized per-operation time complexity. Dividing the total bound by explains the averaging; it is a guarantee over every permitted sequence, without an assumed probability distribution on requests. Individual operations can cost more than .
Consider a dynamic array holding fixed-size entries. Its size is the number of occupied slots and its capacity is the number of allocated slots. Start with , . The only operation is append: if , allocate a new array of capacity , copy the existing entries, and release the old array; then write the new entry and increase by one. There is no reserve operation, deletion or shrinking in this model.
Count one unit for writing the new entry and one unit per existing entry copied during resizing. Thus the th append has actual cost without resizing and when the old capacity is full. Copying an entry, including its read and write, is one counted action. Allocation, deallocation, index arithmetic operations and the initial one-slot allocation are outside this exact count. If these add only a constant per ordinary append and a linear cost per resize, the Big O notation conclusions still hold, with different constants; costly entry copies require their own cost model.
The first ten costs are . For example, append copies eight entries and writes one, so . At that point the capacity becomes , but the total cost of all nine appends is only .
For , the final capacity is . Every earlier capacity was copied once. This geometric series sums to , including the empty sum when . Therefore aggregate analysis gives the exact totalConsequently , so append has amortized cost in Big O notation for every prefix from this empty initial state. The values being appended do not affect the count. In contrast, an append to a full dynamic array with entries costs : its worst-case cost is , and actually grows linearly along full-capacity states. A bound on total work does not promise a constant response time for each call.
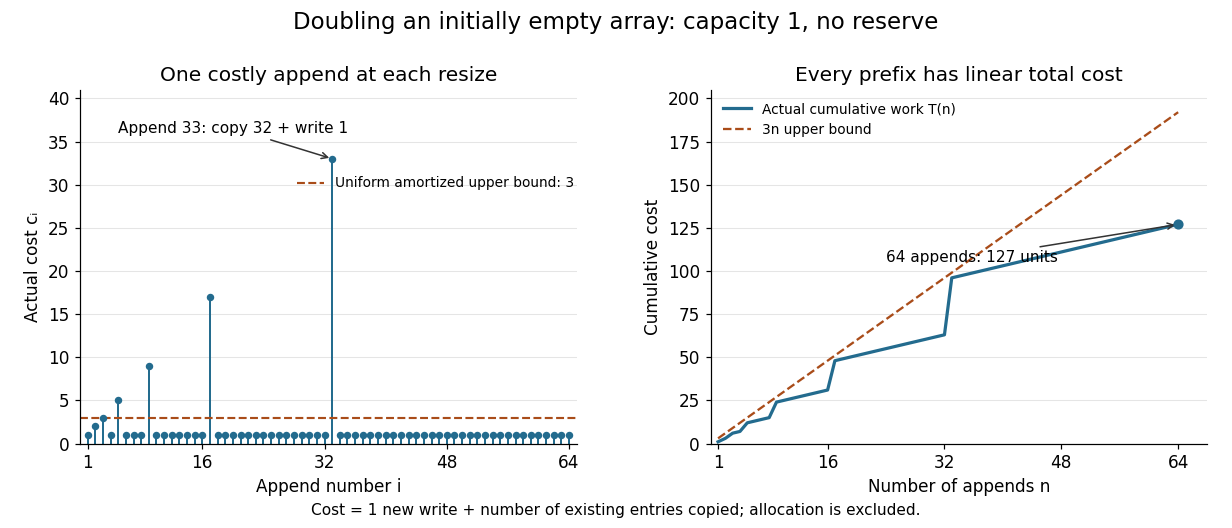
Individual append costs and cumulative work under dynamic array doubling
. The spikes include every copied entry and the new write. At append 33 the actual cost is 33; at append 64 the total cost is 127. Every prefix lies below the line . Details.The same policy controls computer memory: after each completed append, for , so fewer than slots are unused. This is a bound on the retained backing array, with fixed-size slots. During a resize from full capacity to , a copying implementation can temporarily hold both arrays, totalling allocated slots before releasing the old one. Thus the retained-capacity bound does not bound this temporary peak by twice the live size. Allocator metadata and separately allocated objects are additional computer memory costs.
The geometric series is the source of the efficiency. If capacity instead increases by one each time, the same count becomes , a quadratic total. Dynamic array doubling buys a linear total with bounded spare capacity, even when the final length is unknown.
The potential method assigns a number to each state of a data structure. Let be the state after operation , , and its actual cost. Its amortized cost is the actual cost plus the change in potential. Summing and cancelling adjacent potentials gives a telescoping sum:If and every reachable , the sum of amortized costs bounds the actual total for every prefix. A nonzero initial potential contributes the explicit additive term . Potential is proof bookkeeping; the algorithm need not store it.[ref]
Lecture 20: Hash tables and amortized analysis. CS 312 at Cornell University; CS 312, lecture 20, “Amortized analysis”: definition of amortized time and cancellation of successive potential changes
For dynamic array doubling, chooseThe potential method now starts at . After every nonempty reachable state, , so the maximum equals . There are just three cases for append:
For every , the total charge is , and the telescoping sum provesThis agrees exactly with . The unmodified choice has initial value , so calling it nonnegative at the empty state would be incorrect. It also works if that initial constant is retained in the identity; alternatively, starts at zero and is nonnegative on these reachable states. The maximum above keeps a literal nonnegative credit balance from the beginning. The proof covers append alone; allowing reserve or arbitrary deletion changes the reachable states and requires a new argument.
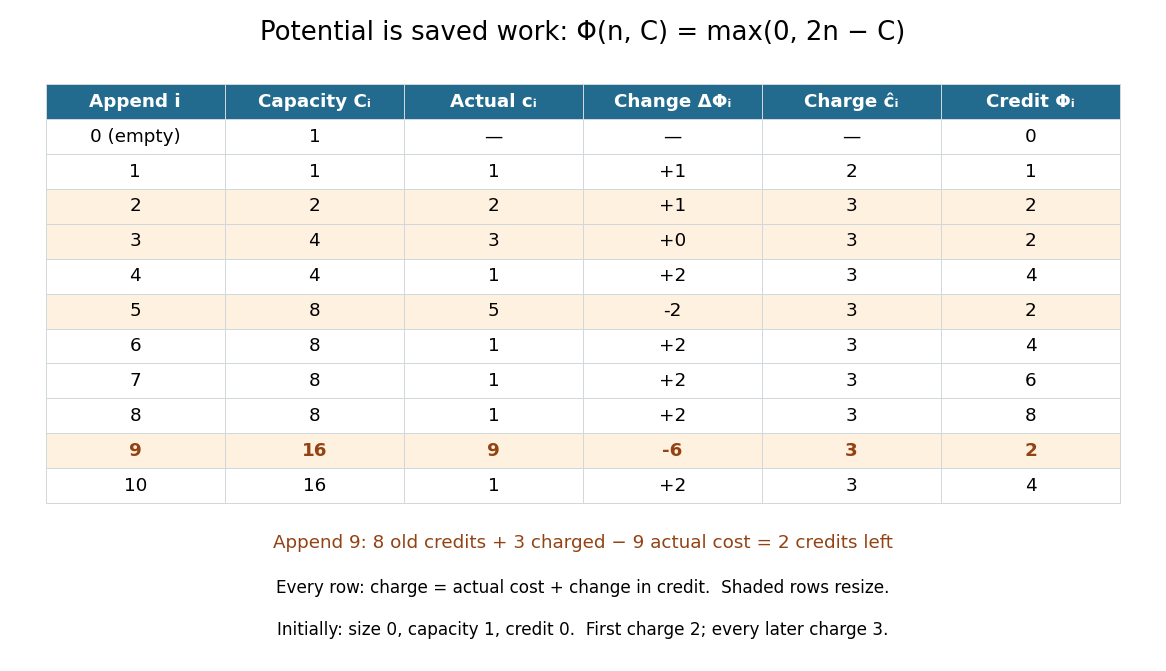
In the potential method, an operation's amortized cost is . It can exceed or fall below its actual cost . The endpoint potentials determine how the total charge compares with the total actual cost.
Aggregate analysis bounds the total cost of a whole sequence directly, then divides by its length to obtain an amortized bound. Summing the copied capacities as a geometric series in dynamic array doubling is an example.
The accounting method charges operations enough to pay for their work and save credits for later work. A nonnegative balance from an initially empty account makes every prefix's total charge an upper bound on its actual cost. Choosing the balance to be gives the potential method; the ledger for dynamic array doubling illustrates this equivalence.[ref]
https://www.math.u-szeged.hu/~hajnal/courses/MSc_AlgoBony/2021/Tarjan.pdf. Robert Endre Tarjan, Amortized Computational Complexity, section 2, pp. 307–308: banker's credits and equivalence with the potential viewpoint
// Destination: computer-science.bigb
An algorithm runs in polynomial time when its running time is at most for some constant , where is the input length.
An algorithm runs in polynomial time if its worst-case running time is bounded by a fixed polynomial in the input length. Arithmetic with fixed-degree algebraic numbers also needs polynomial bit cost when used in such a guarantee. The Edmonds–Karp algorithm and the method of conditional probabilities with efficiently computable clause expectations are examples.
The complexity class of complements of formal languages in P. A deterministic polynomial-time algorithm deciding a formal language can have its accepting and rejecting outcomes interchanged, so P is closed under complement and equals co-P.
A language in P to which every P language has a logspace many-one reduction. The reduction strength matters: using arbitrary polynomial-time reductions instead would make completeness trivial for nontrivial P decision problems.
is the class of decision problems whose positive instances have polynomial-length certificates verifiable in polynomial time. Equivalently, it is polynomial time on a nondeterministic computation.
A certificate for a positive instance is a polynomial-length string that makes a polynomial-time verifier accept that instance.
The space complexity of an algorithm bounds the amount of working memory it uses as a function of input length.
An algorithm uses polynomial space if its working memory is bounded by a fixed polynomial in the input length. Exponentially many possibilities can still be searched when each candidate and the search counter need polynomial space and storage is reused. The decision problems with deterministic polynomial-space algorithms form PSPACE.
Languages accepted by Nondeterministic Turing machines using work space on every computation path, with acceptance defined by existence of an accepting path. Bounded-space loops do not prevent the reachability interpretation in the finite configuration graph.
Reachability within steps can be tested by enumerating a midpoint and recursively testing two half-paths. Configurations have bits and recursion depth , yielding deterministic space . The space-bound discovery by exit reachability permits this simulation without assuming that the supplied function is constructible.
For a bounded-space machine, start with a logarithmic work budget and test accepting reachability and reachability of a transition leaving the budget. Accept if acceptance is found, double the budget if an exit is reachable, and otherwise reject. If all paths use at most space, doubling stops at . Each budget test uses the Savitch theorem recursion and the storage is reused. The method discovers a sufficient bound without computing .
Languages decidable by deterministic Turing machines using work-tape cells with a read-only input. Input-head addresses take bits, while the input itself is not charged to work space. The definition does not require the bound to be computed by the deciding machine.
PSPACE consists of decision problems solvable using a polynomial amount of work space. Running time may be exponential. Enumerating all polynomial-length relation encodings and reusing working storage preserves this bound, as does complementation. In particular fixed-sentence second-order logic model checking lies in PSPACE.
A polynomial-register real-arithmetic computation stores polynomially many real numbers and may use arbitrarily many additions, subtractions and multiplications, with comparison tests for decisions. Register count does not bound precision or time. Fixed gate constants or sufficiently accurate computable approximations must be specified. This resource model is distinct from ordinary bit-cost computation.
For canonical positive binary numeral system inputs, a logspace transducer can emit the canonical representation of their sum most significant digit first. Count the operand lengths, compute the final arithmetic carry to determine output length, and then compute each requested result digit by restarting the least-significant-first column recurrence. Each pass uses only a fixed number of -bit indices and one arithmetic carry. The binary-addition carry invariant proves correctness. Logspace composition by recomputation consequently permits any L property of the resulting digit string, including being a binary palindrome, to be tested without storing the sum.
A deterministic Turing machine with read-only input, work space, and successive write-only output whose contents it cannot inspect. A transducer for a total function halts on every input. It has a polynomial number of internal Turing machine configurations, so a halting run emits only a polynomial number of symbols. The unreadable output position does not affect subsequent transitions.
A total function computed by a halting logspace transducer. Its output may be much longer than its work tapes. Logspace-computable functions compose using logspace composition by recomputation.
To simulate on the virtual input , store the simulated input-head position and rerun the logspace transducer for whenever an input symbol is requested. Count emitted symbols until the requested position is reached. The intermediate output has polynomial length, so its positions take bits, and the work space of is also . Storage used by successive recomputations is reused. This proves closure of logspace-computable functions under composition and transitivity of logspace many-one reductions.
A decision problem is NL-complete when it belongs to NL and every problem in NL reduces to it by a deterministic logarithmic-space many-one reduction.
Decide whether a directed graph has a nonempty directed cycle; self-loops count. This problem is NL-complete. Membership guesses a returning walk of at most the vertex count. For hardness, layer a reachability instance into layers with wait arcs, then add only the backward edge from the target in the last layer to the source in the first. The otherwise acyclic layering has a cycle exactly when the original target is reachable. Zero-length paths must not be treated as cycles.
The directed graph reachability problem asks whether a directed graph contains a directed path from a specified vertex to a specified vertex . It is NL-complete.
Decide whether a finite directed graph has an even-length directed walk from a specified source to a specified target . Vertices may repeat and a zero-length walk is allowed. The NL-completeness proof uses the graph of pairs with tracking integer parity: every original edge flips , and acceptance means reaching from . At most steps are needed in the parity graph. For hardness, subdivide every edge of an ordinary reachability instance into two directed edges. Both constructions are computable by logspace transducers. Requiring a simple path in a graph in the original graph changes the question; deleting an odd closed portion need not preserve integer parity.
The configuration graph of a machine on a fixed input has one vertex for each machine configuration and a directed edge for each valid computation step.
consists of complements of languages in NL.
The Immerman–Szelepcsényi theorem states that . Its proof uses inductive counting of reachable configurations.
Articles by others on the same topic

Complexity classes are categories used in computational theory to classify problems based on the resources needed to solve them, such as time and space. They help in understanding how difficult a problem is to solve, depending on the computational model used. ### Key Complexity Classes: 1. **P (Polynomial Time)**: - Contains decision problems that can be solved by a deterministic Turing machine in polynomial time. Problems in P are generally considered "efficiently solvable.


