Computational complexity theory classifies computational problems by the resources needed to solve them.
The number of elementary operations on bits required by an algorithm. Arithmetic-operation counts treat operations on entire integers as units, whereas bit complexity charges for the sizes of their operands. An algorithm using few multiplications can therefore require substantially more bit operations when the operands grow. State the model when comparing bounds for repeated squaring or dynamic programming counts.
Parameterized complexity studies an algorithm's resource use as a function of both the encoded input length and a distinguished nonnegative integer parameter . A small solution size, a dimension or a structural property of a graph can serve as the parameter. Fixed-parameter tractability allows arbitrary computable dependence on while keeping the exponent of independent of .
A kernelization is a polynomial-time algorithm mapping a parameterized decision problem instance to an equivalent instance of the same problem, with both encoded length and parameter bounded by a computable function of . Equivalent means that both instances have the same yes/no answer. The bound need not be a polynomial in ; a polynomial kernel is the stronger requirement that it is. For a decidable problem, exhaustively solving the bounded output leaves only a computable dependence on , so kernelization yields fixed-parameter tractability.
A parameterized decision problem is fixed-parameter tractable if an algorithm decides every instance of encoded length and parameter in running time at most , for a computable function and a constant independent of . The distinction is in the exponent: has this form, whereas an bound alone does not establish fixed-parameter tractability. Branching on an uncovered edge gives a fixed-parameter tractable vertex cover decision problem.
Decide whether all input elements are distinct. In the comparison model, this needs comparisons in the worst case. An accepting decision-tree leaf for distinct keys must force a total order: incomparable keys could otherwise be made equal consistently with its strict comparison outcomes. Thus the possible orders require different accepting leaves, giving a decision-tree depth of at least even for three-way comparisons.
A model in which an algorithm learns the relative order or equality of input keys by comparisons. Lower-bound reductions must preserve the information available to each comparison; transforming numbers and allowing stronger tests without justification can change the model. For intervals built from integers, every endpoint comparison can be simulated by comparing original keys and then fixed offsets.
A single comparison returning one of three outcomes: less than, equal to, or greater than. A comparison model may count this as one operation even when a programming language expresses the outcomes using multiple Boolean tests. Binary search on ordered keys uses one such comparison per inspected position.
Given two weighted formula utility representations with binary rational numbers as weights, decide whether their values agree on every Boolean valuation. This problem is co-NP-complete.
For membership, a valuation witnessing unequal values certifies non-equivalence. Evaluate all propositional formulas and add their weights exactly in polynomial time. For hardness, compare the one-rule base with the empty base. They are equivalent exactly when is an unsatisfiable Boolean formula. Thus even very small weighted rule bases express a universal equivalence question.
The class of decision problems whose complements belong to NP. Equivalently, negative instances admit polynomially bounded witnesses verifiable in polynomial time. A problem is co-NP-complete when it is in co-NP and every problem in co-NP has a polynomial-time reduction to it. Unsatisfiability of a propositional formula is a basic example: its complement is the NP-complete Boolean satisfiability problem.
The number of accesses to an unknown input needed to solve a specified task. The input might be a string with individually readable entries, or an implicitly supplied function. A complete statement specifies deterministic, randomized, or quantum access, the accepted error, and worst-case or expected cost. Quantum query complexity permits coherent input access through a quantum oracle.
Suppose an unknown function on has exactly one essential variable. Query the diagonal inputs to find two coordinates values giving distinct outputs; at most function-evaluation oracle calls suffice because the unary dependence is nonconstant. A query taking value on an index subset and outside it then tests whether the essential coordinate lies in . Repeated halving locates it in at most further queries. If , no query is needed.
For a matching lower bound with fixed , restrict to when and otherwise. Every query has only two possible replies. A binary decision tree distinguishing the possible essential indices needs at least leaves and depth . Integer outputs in the unrestricted problem need not be binary; the restricted family is what makes this query complexity argument valid.
In exact classical identification of an unknown linear Boolean function , a function oracle call returns one bit . The query complexity is exactly for . Queries on the standard basis inputs reveal , proving sufficiency. For necessity, a depth- decision tree has at most answer histories and must distinguish hidden binary strings; hence , even with adaptive inputs. A reversible circuit that preserves and updates a known target by exclusive or reveals the same one bit per call.
There is also a useful linear algebra proof. Along a fixed history, the chosen inputs form the rows of a matrix over the two-element finite field, and the replies specify . If there are queries, the rank-nullity theorem gives a nonzero vector with . Then and give identical replies throughout this history. This also explains why adaptive choices cannot evade the bound: equal earlier replies force the same later choices.
Communication complexity studies how much information distributed parties must exchange to compute a function of their separately held inputs. Local computation is free; the resource being counted is communicated bits or qubits, with the allowed shared randomness, quantum entanglement or other correlations specified separately. For a Boolean function , a one-way exact protocol has the receiver output correctly for every input after a single message. One-bit computation using Popescu–Rohrlich boxes shows that this resource measure changes drastically if ideal superquantum boxes are available.
For even positive , share the maximally entangled state . Each party applies a phase oracle from its input binary string, producing . Its overlap with is the displayed expression because the Hamming distance counts exactly the negative signs. Under the promise , the output either equals or is orthogonal to it. Sending one subsystem lets the receiver distinguish the cases with the projective measurement . The transmitted system needs qubits, including when is not a power of two.
A promise problem consists of disjoint sets of YES and NO instances. An algorithm or verifier must obey its correctness guarantees only on their union. Energy problems with separated thresholds are naturally promise problems because intermediate-energy instances require no prescribed answer.
Quantum complexity theory studies resources needed by quantum circuits and quantum algorithms, including time, workspace, and quantum query complexity. Its models specify which input oracles and gate implementations are available; counting oracle calls is different from counting all elementary gates.
BQP is the class of promise problems decided by uniform polynomial-size quantum circuits with bounded error. Completeness and soundness are conventional; BQP error reduction shows that other fixed separated thresholds give the same class.
Independent runs of a BQP algorithm with fresh ancilla qubits can be combined by a classical threshold rule. If completeness exceeds soundness by , a Hoeffding inequality bounds the error after runs by . Polynomial repetition handles inverse-polynomial gaps. This does not automatically preserve the restricted gate and measurement rules of a stoquastic circuit.
A quantum witness is a polynomial-size quantum state supplied to a verifier as evidence for a YES instance. The verifier fixes its own ancilla qubits independently. Pure quantum witnesses suffice when maximizing a linear acceptance functional on density operators. Quantum witnesses are not generally restricted to basis vectors or product states.
StoqMA is a restricted quantum-verifier class using stoquastic circuits and polynomial-size quantum witnesses. A YES instance has a quantum witness accepted with probability at least ; on a NO instance every quantum witness has acceptance at most , with an inverse-polynomial gap . An optimal quantum witness can be chosen with nonnegative amplitudes, since the witness acceptance operator is entrywise nonnegative. The quantum witness is generally a superposition, rather than a computational basis vector. The stoquastic acceptance floor explains the lower limit for a nontrivial soundness promise.
QMA is the class of promise problems with a polynomial-size quantum witness checked by a uniform polynomial-size quantum circuit. YES instances have an accepting witness with probability at least ; NO instances have acceptance at most for every witness, including mixed states. The verifier's acceptance is linear in the witness density operator. Inverse-polynomial or exponentially small error can be obtained through QMA error reduction.
For quantum witness embedding , verifier unitary and accepting projector , the witness acceptance operator is the positive contraction . The maximum acceptance over normalized quantum witnesses is by the Rayleigh quotient. Restricting to basis quantum witnesses only tests its diagonal entries and need not find that maximum.
For a positive witness acceptance operator on dimension , large trace powers approximate its largest eigenvalue. With an -qubit QMA quantum witness and , the usual NO instances give and YES instances give a value above . A closed product-index expansion computes the trace by recomputation with polynomial storage, avoiding logarithms and roots in a real-arithmetic implementation.
Starting from completeness and soundness , run an odd number of parallel copies and take majority. The QMA parallel repetition with entangled witnesses argument proves soundness for arbitrary repeated witnesses. Exponential Markov's inequality gives majority error at most . Hence copies suffice for error , with polynomial overhead when the target error is inverse-polynomial or exponentially small in input length.
Independent verifier circuits on witness registers induce a threshold acceptance effect built from tensor products of and , where is the quantum verifier acceptance operator. In a product eigenbasis of , the effect's eigenvalues are threshold probabilities for independent Bernoulli random variables with parameters given by the selected eigenvalues of . Bounding every parameter on a NO instance bounds the effect's operator norm, even if the actual submitted witness is entangled. Independence is used only for the spectral calculation, not assumed for the witness.
A verifier with clean ancillas and a designated output measurement induces an effect on the witness register. Its acceptance probability is , and the largest possible acceptance is . Spectral bounds on make the soundness quantifier over all witnesses, including entangled repeated witnesses, explicit.
The quantum query complexity of a task counts uses of an input oracle by a quantum circuit, for a specified success probability. Known gates and workspace operations are not counted as oracle queries, although they contribute to the circuit's full runtime. An efficient query bound therefore need not, by itself, be an efficient gate bound.
A quantum oracle supplies coherent access to a function through a specified unitary operator. For a function with binary string output, the standard construction retains the input and adds the output into an answer quantum register by bitwise exclusive or. This operation is its own inverse, even when the function is not injective. A Boolean quantum oracle is the single-output-bit case; Simon's algorithm uses several answer qubits. Other encodings, such as a modular-addition quantum oracle or a phase gate encoding, require their own explicit query conventions.
A phase oracle encodes a Boolean function in the signs of computational basis states. Its diagonal entries have modulus one, so it is a unitary operator. The usual convention changes the sign when . A complemented convention instead changes the sign when , with ; denotes exclusive or. The two conventions differ by a global phase when used without coherent control, but the global phase of a controlled quantum gate makes that difference observable when the quantum oracle is controlled.
An unrestricted Boolean function on inputs cannot be classified as constant or nonconstant with certainty using a single phase oracle query, even with quantum ancillas. Write a purified query input as with and . The zero constant function leaves it unchanged; the function supported only at produces a vector with inner product with it. Perfect discrimination of pure states requires orthogonality, forcing for all and thus , a contradiction. This is an exact quantum query complexity obstruction for all nonconstant inputs, rather than the restricted promise used by the Deutsch-Jozsa algorithm.
After input-bit queries, every probability amplitude is a polynomial of degree at most , because the bit-query matrix entries are affine in the input bits. An acceptance probability is a sum of squared absolute amplitudes and has polynomial degree at most . Multilinear reduction on the Boolean cube does not increase degree. Exact acceptance therefore implies . For bounded error the acceptance polynomial only approximates the Boolean function; its exact representing degree is not the relevant bound.
The least worst-case number of input-oracle calls made by a quantum circuit that computes a Boolean function with zero error on every input. Known unitary gates and classical processing do not count toward this quantity; their runtime is a separate cost.
One exact parity query determines whether the first two bits agree. If they agree, a second query reads one of them; otherwise it reads the third bit. Those values respectively determine the three-bit majority function. The matching lower bound follows from its degree-three multilinear polynomial.
Given a function with an -bit output, accessed through the unitary operator , quantum collision finding asks for distinct inputs with equal outputs. Here is bitwise exclusive or on the -bit answer quantum register. The distinctness requirement excludes the uninformative pair . For a two-to-one function on inputs, Grover search algorithm methods yield a cube-root quantum query complexity, despite a square-root cost for finding a partner of just one preselected input.
Query a known set of inputs and store its output table. If no function collision occurs there, each of its distinct outputs has exactly one partner in the complement, for a two-to-one function. A compute-phase-uncompute construction marks those partners using two function queries and reversible table comparison. Known-subset Grover search then uses such phase queries. Including table preparation and a final verification query givesChoosing balances both terms and gives . The Grover rotation angle rounding bound gives success tending to one. This is a query bound; it does not make reversible table lookup free in a gate or physical-memory cost model.
A decision tree represents a deterministic computation of a known Boolean function by inspecting input bits. Each internal vertex of its binary tree names a coordinate to query, its two outgoing edges carry answers 0 and 1, and each leaf carries the output 0 or 1. Starting at the root of a tree, read the named bit, follow its answer edge, and repeat until a leaf is reached. Correctness requires the leaf's label to equal for every input .[ref]
Complexity Measures and Decision Tree Complexity: A Survey by Harry Buhrman and Ronald de Wolf. Buhrman and de Wolf, Complexity Measures and Decision Tree Complexity: A Survey, section 3.1, manuscript p. 5: deterministic trees and D(f)
The next coordinate, or the decision to stop, can depend on earlier answers: this is adaptive querying. The same input always follows the same graph path; adaptivity does not require randomness. A correct leaf must have the same output for every completion of the observed bits. Thus a decision tree can stop as soon as the observations form a query certificate. Querying an already known coordinate adds no information, so we use decision trees without repeated coordinates on a graph path; an efficient tree also removes queries made after the output is already forced.
The motivation is exact computation with shortcuts. If inspecting an input entry is expensive, the question is how much of the input must actually be read. The decision-tree query cost counts these inspections, while local calculations on known values are free in this model; this cost need not equal an implementation's time complexity. Here the Boolean function is specified in advance and must be computed exactly on every input. Decision tree learning instead fits a predictor from data, with a different objective.
Three votes give a small but revealing majority function:Our decision tree queries , then . If these bits agree, return their common value: two equal votes already force the majority function. If they disagree, query and return its value. The first two queries have a fixed order, but whether a third query occurs is adaptive.
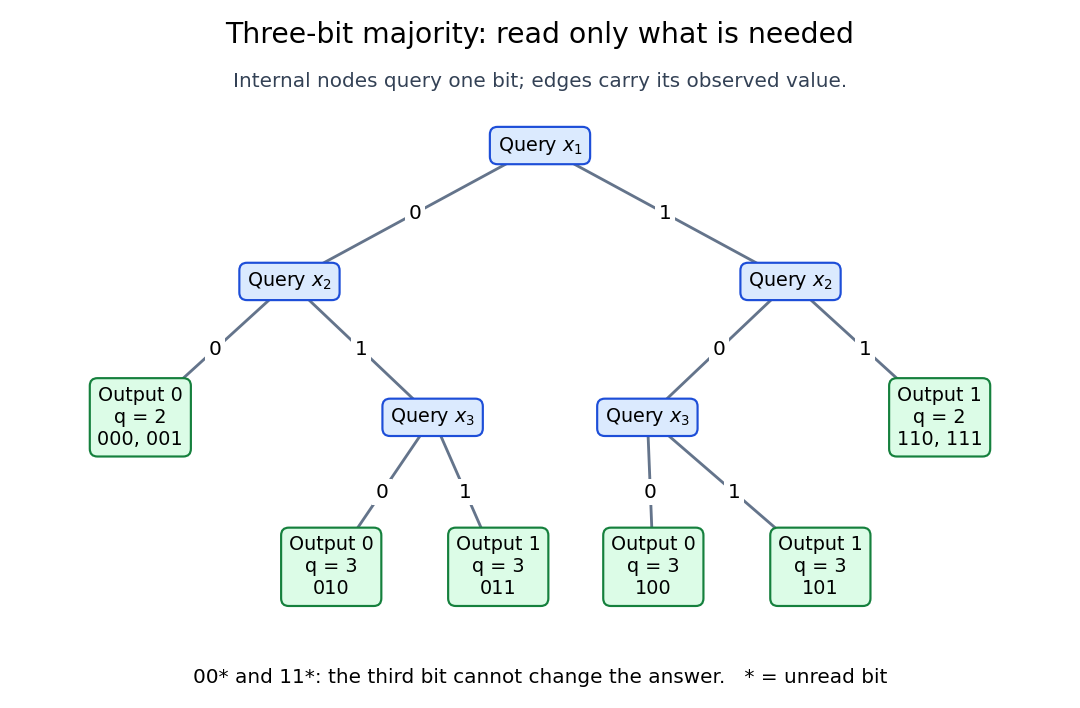
Each internal label in the diagram names the next bit to inspect. Each leaf lists its output, decision-tree query cost , and compatible inputs; an asterisk denotes an unread bit. The two shallow leaves each cover two inputs, while each deeper leaf covers one. Reading every bit would also compute the majority function, but would miss these exact shortcuts.
All eight inputs give the following exhaustive check. The parity column is the parity of , computed by exclusive or; its decision-tree query cost is justified under parity lower bound for Boolean queries.
The worst inputs for this decision tree are , exactly those with . Its actual depth is three. Every exact decision tree for this majority function has depth at least three: after the first query, an adversary can answer the second distinct query with the opposite bit, leaving the last bit decisive. Consequently its optimal decision-tree depth is , even though some inputs finish sooner. Every input has a two-bit query certificate, namely two agreeing votes; locating those votes can require a third query. This separates having a short query certificate from finding one.
For three bits, the Boolean function outputs one when is odd, where denotes exclusive or. Unlike the three-bit majority decision tree, an exact decision tree computing parity must inspect all three bits on every input. If any coordinate is unread, two completions differing only at that coordinate follow the same observed graph path but have opposite parity. A single leaf cannot correctly label both.
The same argument works for bits: parity needs all queries on every input, whatever their order. Thus its decision-tree depth is , its expected query cost is for every input probability distribution, and each coordinate revealment is one. The algorithm remains required to be correct on the whole Boolean cube, even if the chosen probability distribution assigns some inputs zero probability; a promise restricting permitted inputs would be a different computational problem.
For a particular decision tree , its decision-tree query cost is the number of queries along the graph path followed by input . Its actual tree depth isThe query vertices count as operations; each is followed by one answer edge. Thus a leaf reached after queries has graph path length , and a tree consisting only of an output leaf has depth zero. With no repeated coordinates, . The decision-tree depth minimizes over all correct decision trees for ; measures the chosen algorithm, while measures the Boolean function.
Choose an input probability distribution and let have that distribution. Then is a random variable even when the decision tree is deterministic. Its probability mass function describes how often each path length occurs, and its expected value is the expected query cost. None of these quantities changes the actual maximum depth of .
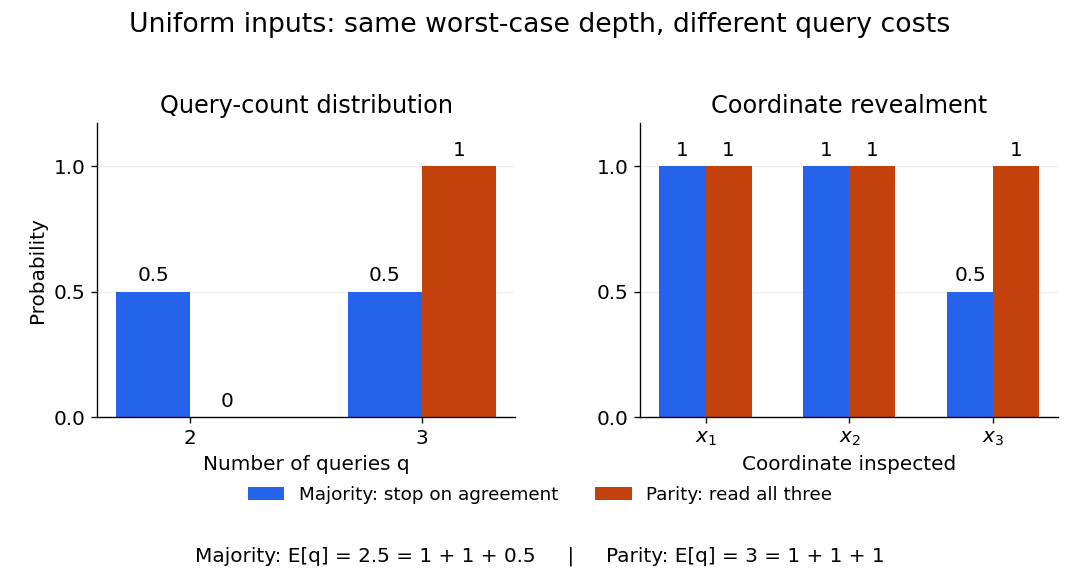
Uniform three-bit inputs: query-count distributions and coordinate revealment for majority and parity
. Details. The left panel aggregates the eight inputs from the three-bit majority decision tree: four cost two queries and four cost three. Parity always costs three. The right panel asks a different question, which coordinates are inspected: the majority function algorithm always queries coordinates 1 and 2, but queries coordinate 3 only on disagreements. These are probabilities of inspection, not probabilities that a bit equals one.
For a fixed decision tree and input probability distribution , its expected query cost isUnder the discrete uniform distribution on the eight three-bit inputs, the three-bit majority decision tree hasThis is an exact average, not a fractional query made during one execution. It is also optimal among exact deterministic decision trees under this discrete uniform distribution: one observed bit never determines the majority function; whichever two distinct coordinates are inspected first, their values disagree with probability , forcing a third query. In comparison, querying all three bits unconditionally has the same actual depth three but expected query cost three.
For an arbitrary input probability distribution, the same fixed three-bit majority decision tree gives . For three independent random variables, each a Bernoulli random variable with common one-probability , this becomes ; the value depends on . Averaging over inputs should also be distinguished from averaging over an algorithm's internal random choices at a fixed input.[ref]
The coordinate revealment of coordinate for a decision tree under input probability distribution isIt depends on the chosen decision tree and the probability distribution, not just on the Boolean function. Since no coordinate is queried twice on a graph path, indicator functions giveThe second equality uses linearity of expectation; it does not require independence of random variables or a product measure. The cited paper defines these inspection probabilities and their sum for product measures; the displayed indicator function argument extends the identity to any input probability distribution.[ref]
For the three-bit majority decision tree under the discrete uniform distribution, , whose sum is . Reading coordinate 3 first, then coordinate 1, and stopping on agreement gives the same majority function, depth and expected query cost, but coordinate revealments . The asymmetry belongs to the chosen query order. Parity gives for every exact decision tree without repeated queries. If repeated queries were charged, inspection probabilities would count distinct coordinates; total query count would instead require expected multiplicities.
The decision-tree depth of a Boolean function is the smallest possible maximum number of input coordinates queried along any root-to-leaf graph path of a decision tree computing :The actual depth of a particular decision tree can exceed this optimum. A constant function admits a depth-zero tree even though an inefficient algorithm could inspect its entire input before returning that constant. Expected query cost and coordinate revealment additionally require an input probability distribution; does not. The three-bit majority decision tree and three-bit parity both have optimal decision-tree depth three, although only the former has the two-query shortcuts described above.
A query certificate fixes some input coordinates to their values in a chosen input and must force the output for every completion. The smallest such size is ; maximizing over accepted or rejected inputs gives or , and maximizing both gives . A one-sided maximum over an empty output class is defined as zero. This is query certificate complexity, distinct from polynomial verification of a witness in NP.
For a Boolean function and a chosen input , a set of coordinates is a query certificate if every agreeing with on has . It fixes actual input bits rather than supplying an independently guessed certificate to an NP verifier. Minimizing its size at each input and then maximizing gives query certificate complexity.
A Boolean function is evasive when every deterministic decision tree computing it has a worst-case path that queries all input bits. The alternating-sum criterion for decision-tree evasiveness is one sufficient method for proving this lower bound.
A leaf reached before all input bits are queried leaves at least one coordinate free. Flipping that coordinate pairs its inputs with opposite alternating signs and equal output. Thus every such leaf contributes zero. If the total alternating sum is nonzero, a depth below is impossible.
To prove that a threshold function requires every input bit in the worst case, an adversary answers queries while keeping completions on both sides of the threshold possible. If this remains true until the final unqueried bit, every decision tree has depth equal to the number of variables.
A decision problem asks for one of two answers, conventionally encoded as zero and one. Equivalently, it asks whether an input belongs to a formal language.
A search problem asks for a witness satisfying a specified relation rather than only whether one exists.
A search problem whose states are words of fixed length, with a transition changing exactly one letter and requiring the resulting word to belong to a specified dictionary. Unit path costs make a shortest graph path a minimum-mutation solution. Hamming distance to the target is a consistent heuristic: one transition changes this distance by at most one. Dictionary restrictions may force a longer solution or make the target unreachable.
A state satisfying a problem's goal test. Whether its generation or its later selection terminates a search algorithm affects optimality for algorithms such as A-star search. A goal state's remaining optimal cost is zero, whereas its accumulated path cost need not be zero.
The sum of step costs along the action history represented by a search node. Positive costs give lower bounds on search depth, and the same physical state can have different path costs when reached along different histories. Uniform-cost search orders by accumulated cost; A-star search adds an estimate of remaining cost.
A step cost is the cost of one action or transition in a search problem. The accumulated path cost is the sum of the step costs along its action history. A uniform positive lower bound on step costs makes every bounded-cost action history have bounded search depth; positivity of each individual term alone does not establish such a bound.
Exploration of a game tree containing choices by competing decision makers. A maximizing node chooses the largest successor value; a minimizing opponent chooses the smallest. Known random outcomes instead require chance nodes and expected values, as in expectimax. A game tree representation can combine controlled choices and chance without assuming that chance maliciously chooses its worst outcome.
Backward induction on a finite game tree containing maximizing choices, minimizing choices and chance nodes. Terminal utilities are backed up by , and , respectively. Exact chance node evaluation generally needs every positive-probability outcome; ordinary alpha-beta pruning does not transfer unchanged because one child's value does not bound the full weighted sum.
A game tree evaluation rule using maxima at the controlled player’s decision nodes and expected values at chance nodes:respectively. Terminal utilities fix the boundary values. These rules exactly optimize a finite-horizon expected utility objective by backward induction. For cyclic infinite-horizon reachability problems, a finite Markov decision process formulation and value iteration replace naive expansion of an infinite game tree. Start with one at successful terminal states and zero elsewhere, keep terminal values fixed, and apply the maximizing/expectation backups repeatedly. The th iterate is the greatest success probability achievable within transitions, by backward induction. These values are nondecreasing and bounded by one. For every policy, eventual success is the increasing set union of success within finite horizons, so its probability is the limit of those finite-horizon probabilities. Taking the supremum over policies and horizons in either order proves that the iterates converge to the optimal eventual-success probability. The limiting fixed-point equations can also admit larger solutions, so the initialization from terminal-success indicators matters.
Two controlled walkers on the same connected undirected graph can each traverse one edge or wait in each unit-cost step. If they meet only by occupying the same vertex at the same time, their minimum meeting time iswhere is the shortest path distance. A common meeting point after steps implies by the triangle inequality. Conversely, choose a middle vertex of a shortest connecting graph path; both walkers reach it within steps, and the earlier arrival waits. The wait is essential when the path length is an odd integer. This distance on the joint Cartesian product state space is a consistent heuristic: each joint move changes the walkers’ separation by at most two. Replacing by an obstacle-free Manhattan distance preserves admissible heuristic and consistent heuristic guarantees.
A search problem in which the available observations need not identify the current physical state. The controller must choose the same action for physical states that its observed history cannot distinguish. A belief state summarizes those possibilities; contingent planning selects future actions according to subsequent observations.
Sensorless planning chooses one action sequence that succeeds from every possible initial physical state without receiving distinguishing observations during execution. A belief state is a set of possibilities. For a deterministic search transition model , an applicable action maps to ; for nondeterministic outcomes, take the union of all possible successors. Applicability must hold for every member of , and success requires the resulting belief state to be a subset of the physical goal set.
Every fixed action sequence preserves inclusion of the initial belief states. Consequently, a successful plan for also succeeds for every subset of . Success on a superset is an additional requirement, so cannot be inferred from success on alone. This property supports incremental belief-state search.
An incremental belief-state search initially plans for a small subset of the possible initial states, then tests the candidate plan on the full initial belief state . If a state in makes an action inapplicable or fails the final goal test, add that counterexample to and solve the enlarged problem. The new search may need to revise the entire plan, rather than append actions to the previous candidate.
With finitely many initial states and a complete finite-model solver for each restricted problem, at most state additions are required. Failure to find a plan even for a restricted subset proves that none can work for the whole belief state. A candidate that passes full validation is a genuine plan for sensorless planning. The advantage is selective tracking: a small number of representative initial states may force a universally successful plan without constructing the full power set search space.
Without a prior probability distribution, a belief state is the set of physical states still compatible with an observed history. If the physical search transition model is deterministic, , and the sensor map is , action followed by observation givesFor a set-valued outcome relation, replace the image by the set union of all possible successors before filtering. A guaranteed-success goal test requires every member of the surviving belief state to satisfy the physical goal. A probabilistic belief is instead a posterior probability distribution, requiring a specified prior and observation law.
A heuristic function obtained by solving an easier problem that permits every original transition and possibly additional ones, with original transitions costing no more in the easier problem. Every original solution remains available, so the easier optimum is an admissible heuristic.
If is the exact distance to the relaxed goal set, each original transition also gives by taking that transition and then a relaxed optimal continuation. Thus this construction gives a consistent heuristic when original goals have relaxed distance zero. For a four-direction grid walk, deleting obstacles gives Manhattan distance; deleting a pursuer's capture constraint supplies another relaxation. The resulting estimate can remain finite when the original goal is unreachable.
Map original states to simpler abstract states, include every projected original transition at no greater cost, and map original goals to abstract goals. An original goal-reaching graph path then projects to an abstract goal-reaching walk, so the exact abstract distance is an admissible heuristic. A pattern database stores such distances for repeated lookup.
A table of precomputed exact abstract goal distances used as an abstraction heuristic. Retaining a subset of the disks of a Tower of Hanoi instance gives a smaller abstract puzzle: moving an ignored disk does not change the abstract state, and moving a retained disk projects to a legal abstract move. Taking maxima of pattern database estimates preserves admissibility; summing them requires an additional cost-partition argument.
For positive-precondition STRIPS with a positive conjunctive goal, remove every delete effect and use the exact shortest relaxed plan cost. Every original plan still succeeds in the relaxed model because facts can only accumulate, so its relaxed optimum is an admissible heuristic. The cost of an arbitrary relaxed plan is an upper bound on the relaxed optimum and need not be an admissible heuristic for the original problem.
A heuristic function is consistent if at every goal andfor every permitted transition with step cost . Summing these inequalities along a finite route to a goal gives its total cost. Taking the minimum over such routes proves that every consistent heuristic is an admissible heuristic.
A heuristic function bounded above by the minimum remaining goal cost . When no goal is reachable, take . Admissibility is a lower-bound guarantee, rather than a statement that the estimate is usually numerically accurate. Ignoring constraints can produce a relaxation heuristic because it enlarges the available solution set.
If , their pointwise minimum, pointwise maximum and each convex combination with are admissible heuristics. Each inequality follows directly by comparison with . The maximum has heuristic dominance over the minimum and every such convex combination.
A sum need not be an admissible heuristic: two exact estimates of the same cost-one remaining action sum to two. A sufficient condition for a valid additive construction is separate nonnegative action-cost allocations with , and estimates bounded by the corresponding optimal allocated costs. Every goal-reaching graph path then costs at least under its original costs. Taking the minimum proves admissibility without counting the same work twice.
If are consistent heuristics, their maximum, minimum and fixed convex combinations are also consistent heuristics. For the maximum, choose an index attaining it at the source and bound its successor by the successor maximum. For the minimum, choose an index attaining it at the successor and bound the source minimum by that component. For a convex combination, multiply the two consistency inequalities by their nonnegative weights and add them. All these combinations vanish at goals when the inputs do.
A function estimating the remaining cost from a state to a goal in a search problem. The estimate is an admissible heuristic when it never exceeds the true minimum remaining cost. A consistent heuristic satisfies an additional local inequality along each permitted transition.
The exact minimum remaining path cost from a state to a goal state, with value when no goal is reachable. For nonnegative step costs, at goals and on every transition. Thus a perfect heuristic is a consistent heuristic and an admissible heuristic. It measures remaining cost; a greedy best-first search decision using only this number can still take an excessively costly incoming edge.
A comparison oracle revealing the ordering of remaining optimal costs without returning their magnitudes. It supplies enough information for greedy best-first search. Its ordering alone does not provide the numerical differences needed to compare sums with independently varying accumulated costs. For , , remaining costs and have the same pairwise order but give opposite orderings of .
A heuristic function dominates if everywhere. When both are admissible heuristics, the larger estimate is at least as informative for A-star search: for a fixed accumulated path cost and optimal solution cost , implies . This compares the compulsory search region, not arbitrary tie handling at , evaluation overhead or wall-clock time.
A condition deciding whether a state successfully completes a search problem. Its timing must agree with the search transition model: arriving at a destination before an adversary's compulsory response need not be a successful terminal state.
The rule giving the successor state of each permitted state-action pair in a search problem. A compound action may include deterministic environmental responses. If a game state is sampled at full-turn boundaries, its search transition model must still detect terminal events occurring inside the turn. Otherwise an intermediate failure can be incorrectly hidden by the final position. All information needed for future successors and the goal test must be encoded in the state or supplied as fixed problem data.
A rooted tree whose nodes are partial search states and whose children are possible next choices. Leaves represent completed candidates or terminated branches. Backtracking traverses this tree while storing the current path, and search pruning removes branches that cannot yield a useful completion.
The number of action edges between a search node and the root of its search tree. It is zero at the root. When every step costs more than , a positive-depth node satisfies , connecting depth finiteness to path cost bounds.
An entry in a search tree representing a particular action history. It normally stores the current state, its parent, its last action and accumulated path cost . Distinct search nodes can represent the same state; identifying them changes tree search into a form of graph search and requires an appropriate repeated-state policy.
The generated but unexpanded search nodes maintained by a search algorithm. Best-first search selects the next expansion from this frontier using a priority queue or an equivalent ordering operation. A lower-bound argument about a frontier node on an optimal path is central to A-star search correctness.
The number of children of a node in a search tree, or an upper bound on that number over the tree. With branching factor at most and depth at most , a complete traversal visits at most nodes.
Assign values from specified domains to variables so that all stated constraints hold simultaneously. A partial assignment can be rejected when it violates a constraint or leaves an unassigned variable with no permissible value. Backtracking applies this test during a depth-first search.
The hypergraph whose vertices are the variables of a constraint satisfaction problem and whose hypergraph edges are its constraint scopes. Several constraints can have the same scope. An incidence drawing uses extra scope nodes for display; these do not become extra variables of the original problem. Ordinary treewidth of a constraint hypergraph refers to treewidth of its primal graph, equivalently to a tree decomposition covering each whole scope, not to generalized hypergraph width measures.
The graph with one vertex per variable and an edge between distinct variables occurring in a common constraint scope. Each hypergraph edge of the constraint hypergraph becomes a clique. A constraint satisfaction problem consisting only of all-different constraints on a common constraint domain is exactly a proper graph colouring problem on this primal graph.
A cardinality constraint restricts how many members of a specified collection are selected or satisfy a property. For Boolean variables, exactly selected entries gives the displayed sum; upper and lower bounds give at-most and at-least variants. Constraint propagation can maintain the number already selected and the number still available. A requirement involving many variables is a global constraint, even when it has a compact arithmetic description.
Choose distinct squares of an chessboard so that no chosen pair has absolute coordinate differences or . One constraint satisfaction problem representation has square-valued variables, requiring distinctness and pairwise nonattack. Another has one Boolean variable per square, a cardinality constraint fixing their sum to , and one mutual-exclusion constraint for every edge of the knight attack graph. The first has fewer variables when is small but represents each unlabelled placement up to times; the second uses only binary constraint domains and sparse local attack restrictions.
The knight attack graph has one vertex per chessboard square and an edge between squares linked by a knight move. A nonattacking placement is an independent set. Colouring squares by the parity of the coordinate sum makes this a bipartite graph, because every knight move changes that parity. Every vertex has degree at most eight, with fewer attacks near the boundary.
Represent each original value choice by a Boolean variable and impose an exactly-one constraint for each original variable. For every forbidden tuple of a constraint with scope , add the Boolean clause . A complete original assignment satisfies every constraint exactly when its one-hot indicators satisfy all these Boolean clauses: each forbidden-tuple Boolean clause excludes precisely that joint choice. A satisfying assignment decodes by reading the unique true indicator for each original variable.
For constraint domain sizes , pairwise uniqueness requires Boolean clauses. If a constraint has forbidden tuples and arity , its contribution is Boolean clauses and literal occurrences. Thus bounded arity gives a polynomial-size encoding in explicitly listed domains, whereas enumerating a succinct high-arity relation can be exponential in its description length. Unit propagation on this encoding can be weaker than arc consistency on the original binary constraints.
Enumerate assignments to a cycle cutset, reject internal violations, filter all crossing binary constraints, and solve the residual forest by tree-structured constraint satisfaction. A full solution restricts to one enumerated cutset assignment; the residual tree passes preserve all its values. Conversely, a consistent cutset assignment combined with supported residual solutions satisfies every constraint. These observations prove completeness and soundness.
With variables, maximum constraint domain size and cutset size , there are at most assignments and residual tree work per assignment. Internal cutset and crossing-constraint tests require additional accounting. The method is attractive when a small cycle cutset is available.[ref]
Choose an unassigned variable constrained to the greatest number of other unassigned variables. This is commonly a tie-breaker after minimum remaining values. The relevant vertex degree is computed in the remaining constraint graph, rather than counting neighbors already assigned. It aims to make each decision constrain many future decisions without changing the solution set.
A restriction on the value of one variable. In a finite-domain constraint satisfaction problem, it can be applied by deleting disallowed values from that variable's constraint domain before search. It introduces no edge in the binary constraint graph.
Place queens on an chessboard so that none share a row, column or diagonal. One constraint satisfaction problem encoding uses a column variable for each row, with and whenever . The pigeonhole principle explains why one queen per row loses no solutions. Prescribed occupied cells give the queens completion problem.
Complete a prescribed subset of occupied cells to a solution of the N-queens problem while retaining every prescribed queen. In a row-variable constraint satisfaction problem, a clue gives the singleton constraint domain . Conflicting clues prove impossibility immediately, but nonattacking clues need not extend to a full solution. Backtracking decides the finite problem; hill climbing can search large candidate boards without an exhaustive guarantee.
A binary constraint satisfaction problem whose constraint graph is a tree. Restrict constraint domains by unary conditions first. Choose a rooted tree orientation and process children before parents. For each child of , retain in only values having a compatible value in the already reduced . Thus every retained parent value has support in each child subtree.
If the root constraint domain becomes empty, no solution exists. Otherwise choose any root value, then recursively choose supported child values. A child-to-parent arc consistency pass need not enforce full arc consistency in both directions; the chosen directional condition suffices for this construction.
The proof uses mathematical induction on subtrees. A retained leaf value satisfies its unary requirements. Each retained parent value has a supported value in every child subtree. Those subtree solutions can be combined because the tree has no edges between different child subtrees. Therefore every retained parent value extends to a whole subtree solution, and every retained root value extends to a complete solution without backtracking.
For variables and maximum constraint domain size , scanning all value pairs once per edge costs time complexity in Big O notation, when one binary constraint evaluation has unit cost. If a constraint requires summing bundle values, its evaluation cost must also be counted.
A directed requirement for a binary constraint : every remaining has at least one support with . Revising the arc deletes unsupported values from ; it does not directly delete values from . Full arc consistency requires the condition in both directions on every edge of the constraint graph. On general graphs, it need not imply that a complete solution exists.
Compute an arc-consistency closure by revising every directed constrained pair in complete sweeps until one sweep deletes nothing. The first sweep is unconditional. With variables, maximum constraint domain size , and constrained pairs, at most deletions permit at most sweeps. At per revision plus per emptiness scan, a direct time complexity bound is . AC-3 uses a work list to avoid scanning unrelated arcs after each local change.
Articles were limited to the first 100 out of 293 total.
Articles by others on the same topic



Computational complexity theory is a branch of theoretical computer science that studies the resources required for solving computational problems. The primary focus is on classifying problems according to their inherent difficulty and understanding the limits of what can be computed efficiently. Here are some key concepts and elements of computational complexity theory: 1. **Complexity Classes**: Problems are grouped into complexity classes based on the resources needed to solve them, primarily time and space.