Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Long-run variance of a stationary process
Autocovariance Created 2026-09-28 Updated 2026-10-14
The autocovariance measures how two observations of the same stochastic process vary together. For a real weakly stationary process of mean , it isWeak stationarity removes dependence on the absolute time . Without it, the covariance function generally needs two time arguments. Lag zero is the variance, ; symmetry of real covariance gives . Positive values favor deviations from the mean in the same direction; negative values favor opposite directions. The units are the square of the observation units. See Bartlett, lecture 2: autocovariance examples.
For example, if with centered unit-variance white noise, expanding the product leaves only matching noise times. Thus , , and for . This MA(1) has a positive lag-one autocovariance because adjacent observations share one disturbance. Rescaling every observation by multiplies every autocovariance by , while leaving autocorrelation unchanged.
The autocovariance is useful beyond comparing pairs: it determines the variance of any finite linear combination of observations. For the sample mean ,Each separation occurs in pairs. For the preceding MA(1) and , this is , compared with for four uncorrelated random variables of the same variance. This is the finite-record counterpart of the long-run variance of a stationary process.
Effective sample size of a stationary sample 2026-10-06
When the long-run variance of a stationary process is positive, matching the variance of its average to an average of independent observations gives . Positive aggregate correlation reduces this size; negative aggregate correlation can increase it beyond the observation count. This extends the variance interpretation of effective sample size of a Markov chain.
Odd-subsample long-run variance of a moving average Created 2026-10-06 Updated 2026-10-14
For coefficients , the long-run variance of a stationary process sampled every second time is . It equals .
Past exam of the mathematics course of the University of Cambridge 2001 iii Paper 26 4 Solution Created 2026-10-03 Updated 2026-10-14
Write for work arriving in slot and for the service rate of a queue. For a work-conserving single-server queue, the Lindley recursion is . For stable independent and identically distributed random variables with mean , its stationary workload supremum has the formDifferent scaling limits of a queue concern different quantities growing large; they need not share either a probability speed or a likely path to overflow.
For large-buffer queue scaling, fix the input law and and let the buffer size of a queue . Assume finite exponential moments around a positive root of . An overflow accumulated in slots requires an average input about , so Cramér's theorem assigns logarithmic cost . Optimizing the duration gives the Cramér-Lundberg workload exponentFor an interior root with , Fenchel–Young inequality verifies the minimization: the lower bound is because , and equality occurs at . The exponential workload bound from cumulative arrival moments gives the upper exponent for every ; an exponentially tilted positive-drift path or the duration calculation gives the matching lower exponent. In effective bandwidth notation, . This regime measures long accumulation into a large buffer with a fixed positive stability margin.
For many-source queue scaling, superpose independent copies of an input process, give the server capacity , and give it buffer size . For each lookback horizon , the average of the source cumulative arrivals has a large deviation principle with rate function . Overflow at that horizon costs . Optimizing the lookback horizon suggestsFor independent slots, , giving . The integer horizon is important in a slotted system. For temporally dependent sources, use the cumulative-input cumulant-generating function, rather than multiplying a one-slot formula by . The heuristic needs uniform control of the tail of the stationary supremum to justify optimizing an unbounded set of horizons; stability and suitable exponential-moment estimates provide this in the usual models. The growing quantity here is the number of independent sources, while per-source capacity and buffer remain fixed.
For moderate-deviation queue scaling, consider a bufferless queue with aggregate Poisson input of mean and capacity , . The spare capacity is much larger than the ordinary central limit theorem scale but much smaller than . The Poisson sample-mean rate function near its minimum has expansionWith , the cost is asymptotic to . Hence Poisson moderate deviations give . The quadratic cost comes from a shrinking neighborhood of the mean, rather than from a fixed macroscopic overload. The regime is useful for a large aggregate whose service margin lies between its typical fluctuation scale and its mean scale.
For a heavy-traffic limit of a queue, instead hold the input law fixed with mean and positive finite variance , and let with and . In slots the net input has mean about and random fluctuation of size . Thus the functional central limit theorem, followed by the Skorokhod reflection map on the half-line, suggestswhere is reflected Brownian motion with negative drift and variance parameter . The stationary law of negatively drifted reflected Brownian motion has tail . When passing the stationary distribution through the limit is justified, this predictsFor dependent input satisfying a suitable invariance principle, replace by its long-run variance of a stationary process. This regime is appropriate near critical load and on long time scales; a functional transient limit alone does not automatically justify the stationary-limit interchange.
A different large-service regime holds the input law fixed. With Poisson distribution of mean and bufferless capacity , let . The single-point lower bound and the optimized Chernoff bound for , using Stirling's formula, give the Poisson large-service overflow asymptoticHere the service rate grows while the input mean does not. A quadratic moderate-deviation approximation would describe the wrong part of the Poisson tail.
To choose a regime, compare the spare capacity, typical fluctuations, number of sources and buffer size before selecting a formula. Use the large-buffer exponent for a fixed stable input and a long overload episode; use the many-source variational cost when independent flows and resources grow together; use moderate deviations for an intermediate safety margin; use the heavy-traffic diffusion when the stability margin tends to zero; and use the fixed-input Poisson tail when service alone becomes very large. Check temporal dependence and exponential-moment assumptions. For heavy-tailed subexponential distributions, a single exceptionally large arrival can dominate overflow, so a finite exponential workload root and a Brownian approximation to the far tail need not apply. These comparisons explain why the same nominal queueing theory system can have different useful asymptotic descriptions.
Past exam of the mathematics course of the University of Cambridge 2016 iii Paper 208 2 1 Solution Created 2026-10-03 Updated 2026-10-06
For a causal autoregressive model of order , the population partial autocorrelation function cuts off after lag , whereas the autocorrelation function generally decays. For an invertible moving-average model of order , the autocorrelation function cuts off after lag , whereas the partial correlation coefficients generally decay. For a mixed autoregressive moving-average model, both generally decay. Exponential decay may alternate in sign or show damped oscillations. Sample correlation coefficients only approximate these patterns, so isolated crossings of the significance bands are not exact order tests.
In PDF Figure 1, the autocorrelation function alternates sign, with a large negative lag-one correlation coefficient and geometrically decreasing magnitude. The partial autocorrelation function has essentially one substantial spike, negative at lag one and about ; later values mostly lie within the displayed bands. Thus a stationary AR(1) with a negative coefficient is the natural first model, with initially near . The trace fluctuates around an approximately constant mean and shows no evident deterministic trend.
Fit that model, compare nearby low-order alternatives using likelihood function and an Akaike information criterion or Bayesian information criterion, and inspect the residual autocorrelation function and residual variance. A few small later PACF spikes are expected in a plot with many lags. The roughly white noise bands are a guide, rather than simultaneous guarantees for every lag.
The sign alternation also suggests concentration of spectral power near the high-frequency end: the AR(1) denominator is smallest near when . From estimated and lag-one correlation coefficient one can estimate innovation variance as . The persistence parameter controls the decay rate and long-run variance of a stationary process. These plots do not establish a normal distribution, independence, or the absence of nonlinear dependence; correlation coefficients of squared residuals can provide a separate variance diagnostic.
Past exam of the mathematics course of the University of Cambridge 2016 iii Paper 208 2 2 3 Solution Created 2026-10-03 Updated 2026-10-06
First, the absolute values in the printed limit are an error: the correct long-run variance of a stationary process is the signed sum of autocovariances. Directly,soEach coefficient tends to and has absolute value at most . Absolute summability and the dominated convergence theorem therefore giveThe sum of absolute values is an upper bound, not the general limit. For a concrete counterexample to the printed assertion, take with unit-variance iid noise. Then , , and other covariances vanish. The absolute sum is , but , so .
For correlated data the central limit theorem can still hold under suitable strong mixing of a stationary process and moment conditions, but the limiting variance is the long-run variance of a stationary process, rather than the one-observation variance. When it is positive,Positive serial dependence usually increases the standard error, while negative dependence can reduce it. The approximate effective sample size of a stationary sample is when that denominator is positive. A long-memory time series can require a different normalization or a different limit law. Absolute covariance summability alone does not prove a CLT: if with a common independent random scale taking values and with equal probabilities and iid with the standard normal distribution, the off-diagonal covariances are zero, yet has the nonnormal scale-mixture law . The example is not an ergodic stationary process. If the long-run variance of a stationary process is zero, the usual nondegenerate square-root- CLT is unavailable.
For the causal AR(1), andThe conditional distribution follows because the current innovation is independent of the past.
For a fixed known , condition on the observed and use the transitions . Their conditional maximum likelihood criterion is, up to constants,Differentiating in yieldsSince ,Thus it is an unbiased estimator, even conditionally on , andIt has statistical consistency with mean-square convergence, and the iid-noise strong law of large numbers also gives almost-sure statistical consistency. Its conditional distribution is exactly normal with the displayed mean and variance. If is also observed and all transitions are used, replace by .
The fixed- qualification is necessary for the exact finite-sample claims. If is jointly estimated, conditional likelihood function is linear regression with an intercept: writing and , the unconstrained estimators areThis ratio is not generally an unbiased estimator and does not have the preceding finite-sample variance. Under the usual stationary regression conditions it has statistical consistency; its asymptotic variance is . Indeed, it differs from by , an asymptotically negligible endpoint term. Profiling an unknown innovation variance does not change the fixed- estimate of .
Past exam of the mathematics course of the University of Cambridge 2016 iii Paper 208 5 a Solution Created 2026-10-03 Updated 2026-10-06
Let be iid with density , set , and put and . The finite-second-moment assumption gives, for ,The sample variance consistently estimates . The central limit theorem and Slutsky theorem therefore give the asymptotic confidence intervalIts confidence probability is approximately , conventionally written ; the printed omits the factor . For , almost surely and the estimator has zero error. This interval concerns iid Monte Carlo estimators; correlated simulation output requires a long-run variance of a stationary process estimate instead of the iid sample variance.
Short-memory time series 2026-10-06
In a second-order sense a weakly stationary process has short memory when its autocovariance is absolutely summable. Then its spectral density of a stationary process is continuous and its sample-mean variance has the usual finite long-run variance of a stationary process. A central limit theorem still needs additional conditions.
Time series Created 2026-09-28 Updated 2026-10-13
A time series is a sequence of observations indexed by time: hourly temperatures, daily sales, or successive measurements of a fluctuating signal. A probabilistic model treats these observations as one sample path of a stochastic process . For equally spaced observations, take and measure a lag of a time series in observation intervals. The order matters: shuffling a record preserves its observed values but destroys information about how one value follows another.
Two basic ways to model temporal dependence are an autoregressive model, which feeds past observations into the next value, and a moving-average model, which combines present and past white noise. An AR(1) carries a disturbance forward with diminishing weights; an MA(1) carries it into just two observations. Their autocorrelation functions make this difference visible. A weakly stationary process supplies a common mean and a lag-dependent autocovariance with which to describe that dependence.
These models help forecast future observations and quantify the uncertainty of averages. Successive measurements need not provide as much information as the same number of independent random variables: the long-run variance of a stationary process accounts for their accumulated covariances. Trend and seasonality require attention before fitting a stationary model; differencing and a seasonal difference operator can help, but do not automatically make every process stationary. See Peter Bartlett, Introduction to Time Series Analysis, lecture 1: objectives and models.
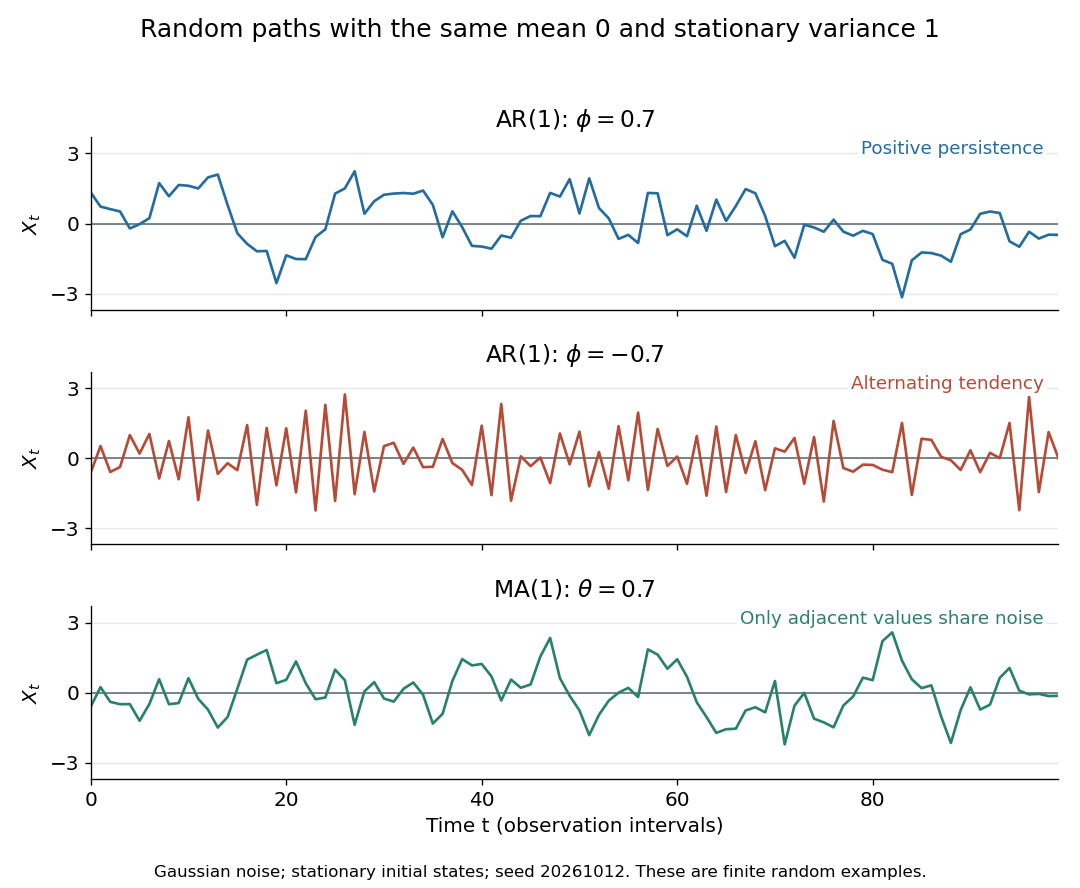
Stationary Gaussian examples: positive AR(1) persistence, negative AR(1) alternation, and MA(1) short memory
. Details. 
The three illustrated sample paths have zero mean and unit variance, so the visual comparison concerns dependence rather than scale. The AR(1) paths start from their stationary normal distribution, independently of future discrete Gaussian white noise; the MA(1) path includes the noise preceding its first observation. These are finite random examples, not exact pictures of an ACF. Compare their theoretical autocorrelation functions in autocorrelation.
Historically, Yule's 1927 study investigated disturbed periodicities in sunspot observations; it should not be read as the discovery of the particular AR(1) examples here. Slutsky studied how summing random inputs could produce wave-like records, a warning against inferring a periodic cause from appearance alone. The editorial note to his 1937 English paper identifies the 1927 Russian original. See G. Udny Yule, On a method of investigating periodicities in disturbed series, with special reference to Wolfer's sunspot numbers (1927) and Eugen Slutsky, The Summation of Random Causes as the Source of Cyclic Processes (1937), including the editorial note on the 1927 original.