Let be real independent and identically distributed random variables with , and let be their expected value. Their sample mean satisfiesThis is almost sure convergence: with probability one, an entire infinite sequence of observations has averages that eventually stay within every prescribed positive tolerance of . The variance need not be finite. The strong law of large numbers implies the weak law of large numbers, which asserts convergence in probability at each increasing sample size.
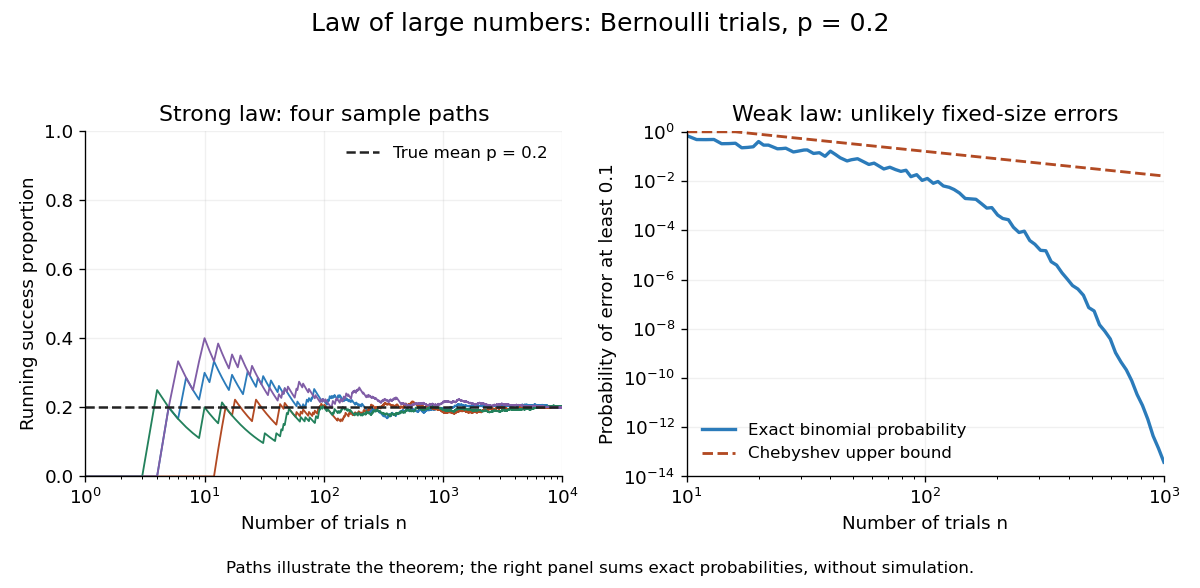
For independent trials with a Bernoulli distribution of parameter , is one for success and zero for failure. Then is the observed success proportion, and the strong law of large numbers says almost surely. This turns a theoretical probability into a quantity one can estimate by repetition. It does not say that each new trial improves the estimate: a long string of failures can move the proportion away from before later observations bring it back.

The strong law of large numbers gives the limiting location of the sample mean, while the central limit theorem describes its fluctuations when the variance is finite and positive. The two assertions can hold together:The first error shrinks to zero; the second has been enlarged enough to retain a nontrivial probability distribution. The second assertion is convergence in distribution, not a claim that the enlarged error along one sequence approaches a particular normal random variable.
The assumptions make a practical difference. If every observation repeats the same nonconstant Bernoulli random variable, , then for all : identical probability distributions alone do not make repeated observations informative. For independent observations with a Standard Cauchy distribution, the Cauchy sample mean has an unchanged distribution, so it does not concentrate around a constant. Its expected value is undefined, and ; neither example contradicts the stated strong law of large numbers.
A brief proof outline in the case of finite variance uses the Kolmogorov maximal inequality for the centered partial sums. The probability that their maximum up to exceeds is at most . These bounds are summable, so the Borel-Cantelli lemma controls all sufficiently large such blocks and hence every intermediate sample size. The general case requires truncation to control large observations; the argument using finite variance alone does not prove that full version.
For independent identically distributed random variables, the tail-sum formula applied to shows that for every when the first absolute moment is infinite. The Borel-Cantelli second lemma, followed by a countable intersection over positive integer , gives the first limsup assertion.
If had finite limsup along such a sample path, it would eventually be bounded by some finite constant . Then would imply eventually, a contradiction. This is a necessary-integrability counterpart to the strong law of large numbers; without a finite first absolute moment, the normalized sums cannot converge to any finite value.
Take independent random variables equal to and with probability each, and otherwise equal to one. Their first absolute deviations are , so in L1 convergence. The same triangle-inequality argument gives convergence in of their arithmetic averages to one. For , however, .
The exceptional jumps occur infinitely often almost surely by the Borel-Cantelli second lemma, since . If the arithmetic averages converged to any finite value along a sample path, then would tend to zero. At each exceptional jump its magnitude is at least one. Thus the averages have no finite almost sure limit. Independence and convergence of first-moment averages do not alone give a strong law of large numbers.
If the positive factors are independent and identically distributed and , the strong law of large numbers applied to their logarithms gives the displayed almost sure convergence. A negative limit forces the products to tend to zero; a positive limit forces them to tend to infinity. A zero limit alone gives neither conclusion. For a uniform distribution on , the logarithmic expected value is , so the products tend to zero almost surely for and to infinity almost surely for .
For independent and identically distributed random variables with and , the sample mean of tends to almost surely. Split into odd and even indexed products; each subsequence consists of independent and identically distributed random variables that are integrable random variables. Apply the strong law of large numbers separately.
Articles by others on the same topic
There are currently no matching articles.