Let be real independent and identically distributed random variables with expected value and finite, strictly positive variance . Write and for their sum and sample mean. The central limit theorem statesPrecisely, for every real ,where is the standard normal distribution function. The conclusion is convergence in distribution to the standard normal distribution. If the variance is zero, every observation equals almost surely; the displayed normalization is then undefined and there is no fluctuating error to describe.
The striking feature is that the observations need not have a normal distribution. They may be binary, bounded, or strongly skewed. Their detailed probability distribution disappears from this limit except through the expected value and variance. The subtraction removes predictable growth: . The division implements variance normalization: variance additivity for independent random variables gives , so every has expected value zero and variance one. For nonzero , an uncentered sum drifts; without rescaling its spread grows.
For a concrete example, let each have a Bernoulli distribution with success probability . Then has a binomial distribution, with expected value and variance . Its exact probability mass function and its normalized count areHere is a binomial coefficient. Individual trials are conspicuously skewed, yet their centered, rescaled counts approach the same standard normal distribution as sums of fair trials.
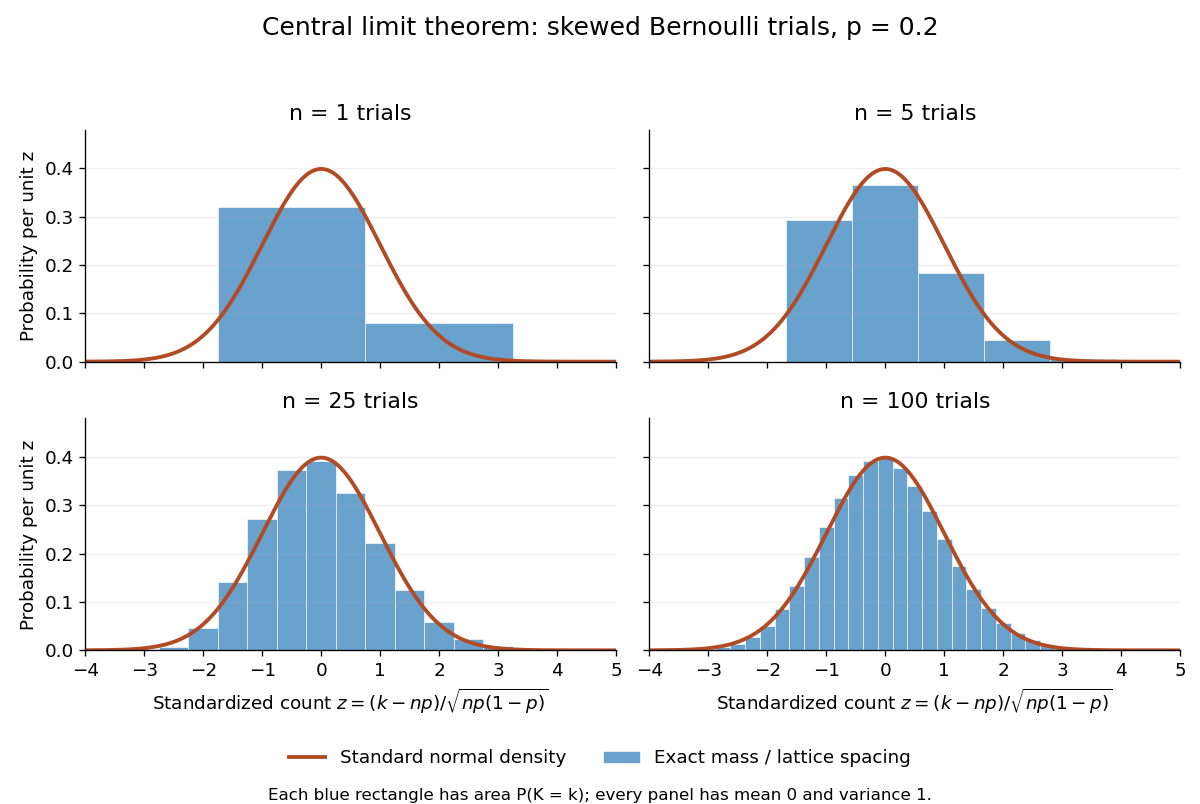
Exact standardized binomial distributions approach the standard normal curve
. For independent Bernoulli trials with , each blue bar has width equal to the normalized lattice spacing and area equal to the exact binomial distribution mass at its center. Heights are mass divided by spacing, so they can be compared with the orange probability density function of the standard normal distribution. All four normalized counts have expected value zero and variance one. The rectangles visualize discrete masses; they do not make the discrete probability distributions continuous. Details.At , has expected value and standard deviation . The exact binomial distribution gives . A normal approximation with the continuity correction uses the interval to :The small discrepancy is an approximation error, not an equality supplied by the central limit theorem.
The strong law of large numbers and weak law of large numbers locate the average: , respectively by almost sure convergence and convergence in probability. The central limit theorem magnifies that shrinking error and describes its shape. In terms of the sample mean, the resulting normal approximation is , with standard error . This explains why four times as many independent observations halve the standard error. When is known, has approximately coverage for at large , giving a confidence interval. This coverage refers to repeated samples, not a guarantee for an individual interval.
A useful application is the Monte Carlo method: estimate a success probability by the proportion of successful simulated trials. Nicholas Metropolis and S. Ulam's original paper, "The Monte Carlo Method" (1949), illustrates this with games of solitaire and estimation of a region's volume by randomly selected points, and discusses why estimates require probabilistic error control. The strong law of large numbers justifies convergence of such proportions for independent repetitions; the central limit theorem supplies their large-sample error scale when .[ref]
https://hedibert.org/wp-content/uploads/2013/12/1949MetropolisUlam.pdf. Metropolis and Ulam, The Monte Carlo Method, JASA 44 (1949), 335–341, especially pp. 336–337
There are three useful limits to this picture:
- A heavy-tailed distribution can have infinite variance, so the displayed hypothesis must be checked. A Pareto distribution with minimum one and shape has finite expected value three but infinite variance. The strong law of large numbers still applies, but the stated central limit theorem does not. More dramatically, the Cauchy sample mean has an unchanged distribution: even averaging need not concentrate when the expected value is undefined. A heavy-tailed distribution with finite variance is allowed by the stated central limit theorem.
- Independence matters. If all equal the same nonconstant Bernoulli random variable, then and . There is no accumulation of new information, and the variance of the sum grows like , not . Other versions of the central limit theorem can allow dependence, but require hypotheses controlling it.
- Convergence in distribution is a limiting assertion, with no universal sample size or error rate under finite variance alone. It does not automatically give accurate relative estimates of very small tail probabilities. Nor does it mean that discrete point masses converge as probability density functions: a binomial distribution remains discrete for every finite . If the success probability changes with so that and , the relevant result is the Poisson limit theorem, rather than the fixed- argument above.
A historical original-paper reference is J. W. Lindeberg's "Eine neue Herleitung des Exponentialgesetzes in der Wahrscheinlichkeitsrechnung" (1922), published in Mathematische Zeitschrift 15, pp. 211–225. The Lindeberg condition and Lindeberg-Feller central limit theorem below describe a version for sums whose summands need not share a probability distribution.[ref]
https://doi.org/10.1007/BF01494395. Lindeberg, Eine neue Herleitung des Exponentialgesetzes in der Wahrscheinlichkeitsrechnung (1922)
A brief proof outline uses the characteristic function of . Its expected value is zero and its variance is one, so the finite second moment givesThe Taylor expansion of the complex exponential, with its remainder controlled by , and the dominated convergence theorem justify this step without a third-moment assumption. Independence then gives the characteristic function of :The limit is the characteristic function of the standard normal distribution; the Lévy continuity theorem turns this into convergence in distribution.
Let be independent and identically distributed random variables with expected value zero, variance one, and a moment-generating function finite in a neighborhood of zero. Each row of deterministic real weights is finite. If and , then the weighted sums converge in distribution to a normal distribution with mean zero and variance ; denotes the constant zero.
By the quadratic expansion of a cumulant-generating function, write with . For a fixed real , put , with the supremum taken as zero if its range is empty. Then andThus the log moment-generating function of the sum tends to . The convergence theorem for moment-generating functions proves the conclusion. The supremum is the step that makes the remainder estimate uniform across the row; a separate little-o assertion for each term would not justify summing an increasing number of terms.
For each , let be independent centered random variables. If the sum of their variances tends to and for every , their sum converges in distribution to the centered normal distribution with variance . The second hypothesis is the Lindeberg condition. If the total variance tends to zero, the corresponding degenerate limit follows directly from the Chebyshev inequality.
For independent centered random variables with total variance , the Lyapunov condition requires the displayed expression to tend to zero for some . The inequality implies the Lindeberg condition after normalization. The Lindeberg-Feller central limit theorem then makes the normalized sum converge to the standard normal distribution.
For independent identically distributed mean-zero variables with finite positive variance, the central limit theorem gives a positive eventual lower bound for for every finite . The decreasing events have probabilities bounded below, so continuity from above of a measure gives positive probability that the limsup is at least . The limsup itself is unchanged by removing any finite initial sum, hence is tail measurable. Kolmogorov zero-one law makes each event “limsup at least ” certain; intersect over integer . The result is false for zero variance. One should apply the zero-one law to the limsup, rather than assume the exact threshold infinitely-often event is unaffected by a vanishing change.
A normal approximation replaces a sampling distribution by a normal distribution, often through a central limit theorem. In a Wald test, approximate statistical power is determined by the standardized difference under the alternative. This yields Neyman allocation for fixed treatment-specific variances.
A continuity correction shifts a discrete probability boundary by half a lattice spacing before using a continuous normal approximation. For an upper-tail event on a unit lattice, the approximation is . Lower tails use the boundary . The correction is used in approximate Wilcoxon signed-rank tests and Wilcoxon rank sum tests; tied ranks also require the appropriate variance adjustment.
The Lindeberg condition requires the contribution of unusually large summands in a triangular array to become negligible compared with the array's total variance. Together with convergence of that variance, it gives the Lindeberg central limit theorem.
For independent identically distributed centered random variables in a separable Hilbert space with finite second moment, converges in distribution to a centered Gaussian random element with the same covariance operator.
For independent identically distributed with mean zero and variance one,The numerator obeys the central limit theorem, the denominator converges almost surely to one by the strong law, and Slutsky's theorem combines them.
For independent identically distributed increments of mean zero and variance one, the diffusively rescaled, linearly interpolated random walk converges weakly in to Brownian motion.
For centered unit-variance independent and identically distributed increments with , an interpolated increment is . Here is the length of the overlap of with the th unit cell, so and . Independence gives its fourth moment as . This is at most , and gives the bound, including intervals crossing a mesh point. A uniform fourth-moment continuity criterion yields tightness of probability measures on .
For a random walk with centered independent identically distributed increments of variance one, the maximum of its polygonal interpolation is the maximum at its grid vertices. The maximum functional is Lipschitz for the supremum norm, so the continuous mapping theorem applied to the Donsker invariance principle proves the displayed convergence in distribution. The Brownian reflection principle then gives upper-tail limits at all , since the limiting maximum has no atom there.
For a random walk with independent identically distributed steps of mean zero and variance one, the Donsker invariance principle and the continuous mapping theorem for integration give this limit. The integral of the polygonal interpolation differs from the right-endpoint sum by , whose squared expectation is . The Slutsky theorem removes that error. The limiting variable is the time-one value of integrated Brownian motion, with law .
Articles by others on the same topic


The Central Limit Theorem (CLT) is a fundamental statistical principle that states that, under certain conditions, the distribution of the sum (or average) of a large number of independent, identically distributed random variables will approximate a normal distribution (Gaussian distribution), regardless of the original distribution of the variables. Here are the key points of the Central Limit Theorem: 1. **Independent and Identically Distributed (i.i.d.