Linear regression models a response's conditional expectation as a linear combination of specified predictors. In matrix form,where the design matrix describes the observations, contains the regression coefficients, and contains the errors. The fitted values estimate the response means. The model is linear in its regression coefficients; its columns may include powers, interactions, or other transformed predictors, so polynomial regression can fit curved relationships using the same machinery.
For a concrete example, take five constructed observationsAn ordinary least squares fit with an intercept gives the line . Its regression residuals are and its residual sum of squares is . A one-unit increase in the predictor corresponds to a one-unit increase in the fitted response. This is a description of this fitted association; interpreting a change as a causal effect requires the assumptions of a causal inference problem.
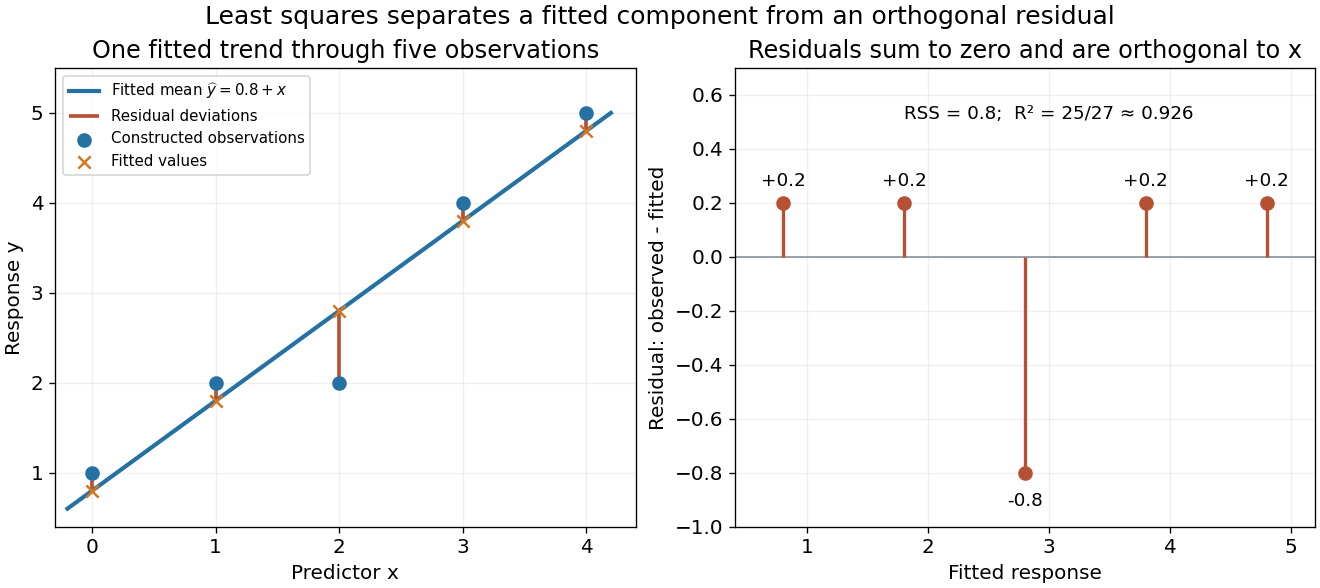
A five-point least-squares fit separates the fitted trend from residual deviations
. Details. The geometric reason for the fit is simple. The possible mean vectors form the column space of . Ordinary least squares chooses the orthogonal projection of the data vector onto that vector subspace, so the remaining regression residual is orthogonal to every permitted fitted direction. The least-squares normal equations express this orthogonality as . The data's explained component and unexplained component are therefore separated by the same geometry used in a Hilbert space.
The optimization definition makes sense for any observed data. Quantifying the uncertainty of the regression coefficients needs additional assumptions about the sampling and errors. With fixed of full column rank and mean-zero errors with covariance matrix , ordinary least squares is unbiased and has covariance ; the Gauss-Markov theorem compares it with other linear unbiased estimators. A normal linear model additionally makes Student t-distribution intervals and tests exact in finite samples. Model adequacy and predictive assessment remain relevant even when these calculations are available.
Two historical settings help explain the subject's appeal. Adrien-Marie Legendre's Nouvelles méthodes pour la détermination des orbites des comètes (1805) includes an appendix on the method of least squares: observations give more equations than unknowns, and squared errors provide a criterion for reconciling them. Its astronomical setting shows the motivation for combining imperfect measurements. [ref]
https://www.e-rara.ch/zut/content/titleinfo/10838079. Legendre, Nouvelles méthodes pour la détermination des orbites des comètes, 1805, appendix pp. 72–80
Francis Galton's Regression Towards Mediocrity in Hereditary Stature (1886) examines the association between parental and offspring heights and the tendency of group averages toward the population average. This is a historical use of the regression name; the modern linear model is a general statistical formulation. [ref]https://zenodo.org/records/1449548. Galton, Regression Towards Mediocrity in Hereditary Stature, 1886, original article
Fit a quadratic mean at three temperatures , with equal replication at the off-center temperatures and any positive replication at the center. The three parameters fit the three group means exactly, giving the displayed estimates. Independent Gaussian errors make these estimates jointly normal. Their covariance is , so they are independent. Equal off-center replication is essential to this cancellation.
At symmetric design points, the columns , and are mutually orthogonal. Their squared lengths give the diagonal entries of the normal-equation matrix and hence separate least-squares coefficient variances. At the seven integer points from minus three to three, these squared lengths are .
Suppose are independent and identically distributed with mean zero and finite variance . For deterministic weights , put . Ifthen the Lindeberg-Feller central limit theorem givesThis is the condition that no observation dominates the weighted error sum. In a centered linear regression with orthogonal explanatory columns, , so the result justifies a normal approximation with variance .
To verify the Lindeberg condition, write and . For each ,The inequality uses , and the limit follows from the finite second moment. Without the maximum-weight condition, adding observations with zero explanatory value can leave the slope determined by a fixed number of nonnormal errors for every sample size.
A statistical model specifying a response as a linear combination of known regressor columns and an error. Common assumptions are and , although a normal distribution is an additional assumption, not part of the displayed equation alone. Full column rank of the design matrix makes the coefficients identifiable. Statistical association does not by itself give a causal effect.
An exponential decay rate becomes a straight line in and , where is a fixed reference rate. Constant small fractional rate errors become approximately constant vertical errors by propagation of uncertainty. With independent Gaussian log-rate errors, linear least squares gives and .
The covariance matrix is obtained by applying the variance rules to these linear estimators:Transforming back gives , , and . If a candidate lifetime fixes the slope , the intercept must be refitted as . The profiled objective obeysThis follows by separating the centred slope residual from the unrestricted regression residual, whose inner product with the design columns is zero by the normal equations for linear least squares. Known supplied measurement errors are not rescaled by the observed reduced chi-squared. This log-error model is an approximation for proportional errors, not an exact replacement for every raw-count likelihood.
Multiple linear regression models a scalar response by an intercept and several predictors. It is linear in the regression coefficients, even when predictors include transformed variables or interactions. In an observational study, adjustment can address measured confounding, but does not automatically identify a causal effect. Improvements in fitted coefficient of determination require external predictive assessment rather than being treated as proof of improved future prediction.
Minimizing gives the displayed equations by differentiation. Equivalently, the regression residual satisfies : it is orthogonal to every column of the design matrix. If has full column rank, the minimizer is unique and the fitted values are the orthogonal projection of onto its column space. A rank-deficient design matrix can give multiple coefficient vectors, while the projected fitted vector is still unique.
For an intercept and one predictor, put and . The equations give and , provided . In the five-point example in linear regression, , , and , giving and .
The normal equations describe the mathematical optimum, but explicitly forming and inverting can amplify numerical problems. A QR decomposition computes the same least-squares solution through orthogonal coordinates; a singular value decomposition also exposes nearly dependent columns. This connects statistical fitting to numerical linear algebra and the choice of a stable algorithm. [ref]
https://ocw.mit.edu/courses/18-06sc-linear-algebra-fall-2011/. MIT 18.06SC, Projections onto Subspaces and Least Squares
If the true conditional mean is , the population slope from regressing on alone is , assuming a mean-zero error uncorrelated with the predictors. The omitted predictor can steepen, flatten, or reverse the pooled association. The same identity holds for fitted coefficients and empirical covariances when comparing nested ordinary least-squares fits. Adjustment changes the comparison being described; a causal interpretation requires additional assumptions.
Replacing a numerical predictor by preserves the fitted mean space and slope in a linear regression containing an intercept. The intercept becomes the fitted mean at . In simple linear regression, centering at the sample mean makes intercept and slope estimates uncorrelated under a normal linear model. This changes coefficient interpretation, not predictions.
Regression diagnostics check assumptions and influential observations in a fitted regression function. Residual-versus-fitted plots can reveal omitted mean structure or nonconstant variance; a quantile-quantile plot checks a specified error distribution. Regression leverage measures unusual predictor configurations, and Cook's distance combines leverage and residual size to measure coefficient sensitivity. Independence may require checking collection order and the study design in addition to residual plots.
An influential observation substantially changes a fitted model or its predictions when removed or perturbed. In a linear regression, influence depends jointly on residual size and regression leverage. Large predictor leverage with a small residual and a large residual at ordinary leverage can have different consequences. Regression diagnostics examine this sensitivity; influence is not synonymous with an invalid observation.
A regression outlier has a response unusually far from its fitted conditional mean. A standardized regression residual adjusts for regression leverage; an externally studentized residual also estimates noise variance with the observation deleted. Selecting the largest residual among many observations changes its reference distribution. An outlier need not be an influential observation, and unusual valid data should not be discarded solely for being unusual.
A piecewise linear regression-path algorithm which starts at zero, activates a predictor with maximal absolute residual score, and moves in a direction that decreases all active absolute scores equally until another predictor ties them. With and active correlation signs , the coefficient direction is . Ordinary LAR does not drop a predictor when its coefficient crosses zero; sign compatibility of LAR and Lasso characterizes when its path also obeys the Lasso KKT conditions.
With signed active covariate columns and their positive-definite Gram matrix , the displayed direction has unit norm and . Thus it makes equal angles with unit-length signed active covariates, and movement along it reduces their signed residual correlations at the common rate . The regression coefficient direction is , with inactive components zero.
If every nonzero active coefficient has the sign of its residual score along the least angle regression path, the LAR active correlation invariant and inactive bounds give the Karush-Kuhn-Tucker conditions for the Lasso. A unique Lasso solution then equals the LAR path. Zero coefficients use a subgradient interval; literal sign equality with sign(0)=0 is not appropriate for a newly entering coefficient at a positive knot.
Each least angle regression segment starts with all active scores at magnitude . Moving with direction changes the score vector to . The first-hit rule bounds every inactive score in magnitude by . This is the key Lasso optimality link.
On a segment starting at residual-score level , an inactive score evolves as while the active level is . Solving gives distances and . The smallest positive admissible distance determines the next entry; reaching level zero ends the algorithm.
A reciprocal-predictor linear regression uses for nonzero predictor . It remains linear in its coefficients. Its flattening shape can suit a saturating response over a positive predictor range; residual checks and cross-validation must assess adequacy, and extrapolation toward zero is hazardous.
The intercept is the coefficient of the constant design column. Adding a constant to a predictor can be absorbed by changing the intercept, leaving fitted values and all slope coefficients unchanged.
For a Gaussian linear model with an intercept and one explanatory variable, and , the regression intercept estimator is normal with variance . The residual variance estimate is independent of the coefficient estimators and has a chi-squared distribution with degrees of freedom. Consequently the displayed statistic has a Student t-distribution under , and a two-sided level- test rejects for .
// Target: mathematical-optimization.bigb
A linear regression in the coefficients with a polynomial mean function . Successive degrees define nested models that can be compared by an F-test.
With independent prior distributions and in a normal distribution regression model, the conditional posterior distribution of has covariance matrix and mean . The conditional posterior distribution of is inverse-gamma distribution . The shape contains no half-dimension contribution from , since its prior distribution is independent of . These conditionals give a two-block Gibbs sampler.
A polynomial regression of degree two is linear in its unknown regression coefficients despite being curved in the predictor. Its design matrix has columns ; three distinct predictor values give full column matrix rank.
In an ordinary least squares regression with an intercept and a nonconstant response, . It measures the fitted proportion of sample variation relative to an intercept-only baseline. It increases when regressors are added, even if those regressors are unhelpful for prediction. A high value does not establish the assumptions of a normal linear model or rule out a systematic regression residual pattern.
For the five-point example in linear regression, the total centered sum of squares is and the residual sum of squares is , so . This summarizes the fitted reduction in squared error. It does not record the order or shape of the regression residuals, which are worth examining in a residual-versus-fitted plot.
Here is a fully constructed illustration. Use and the same fitted line for both datasets. Add respectively the residual vectorsBoth sum to zero, both have zero inner product with , and both have squared norm . Their ordinary least squares fit is therefore exactly the same line, with the same . But the first residual is , a systematic quadratic shape, while the second changes direction across the predictor values. These examples show directly which information the scalar discards; neither constructed pattern proves a random-error model.
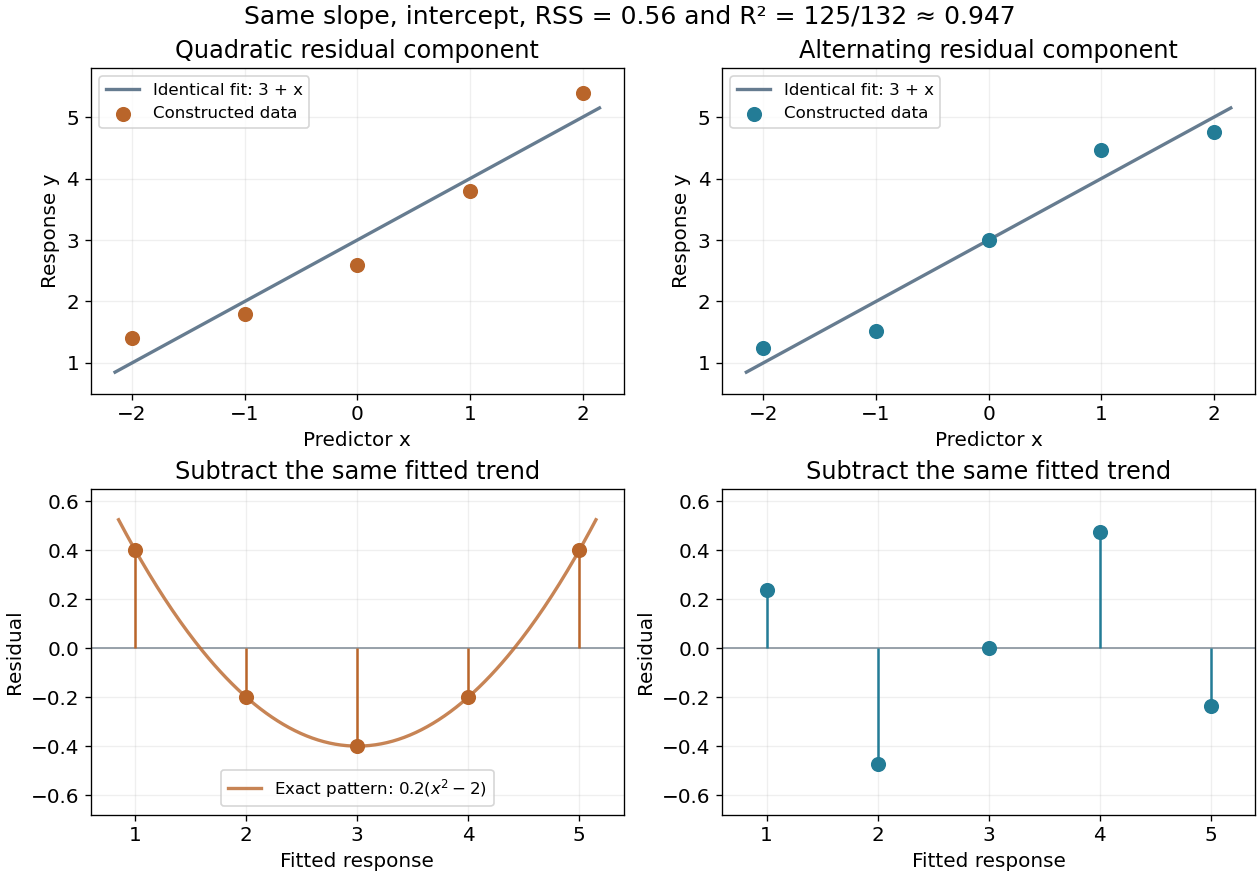
In a normal linear model with an intercept, observations and independent mean coefficients, adjusted isIt compares the residual variance estimate with the unmodelled sample variance, adjusting the raw coefficient of determination for fitted dimension. It can be negative and is not guaranteed to increase when another regressor is added. In penalized regression a related convention uses the fit's effective degrees of freedom instead of ; the precise smoothing-software variance convention should be specified.
A residual-versus-fitted plot displays residuals vertically against predicted responses horizontally. Curvature suggests an incorrect conditional-mean model; a fan-shaped spread suggests heteroscedasticity, while isolated large residuals may indicate unusual observations. It does not alone measure leverage or influence: regression leverage records unusual predictor combinations, and Cook's distance combines leverage and residual size.
The figure in coefficient of determination shows why the plot is useful: subtracting the fitted linear trend makes a small curved component easy to see. A visible pattern supplies a reason to investigate the model, while the absence of a pattern in a small sample does not establish that all assumptions hold. Other views address other questions: regression residuals against observation order can reveal temporal dependence, and a normal probability plot examines distributional shape. NIST's statistical handbook develops this use of graphical residual analysis for model validation. [ref]
https://www.itl.nist.gov/div898/handbook/pmd/section4/pmd44.htm. NIST, How can I tell if a model fits my data?
A scale-location plot compares the square root of the absolute standardized regression residual with the fitted values. Systematic changes in level or spread suggest heteroscedasticity. It assesses the error scale, while a residual-versus-fitted plot primarily reveals mean patterns as well as changing spread.
Analysis of variance decomposes variation into contributions associated with model terms and residual error. For nested normal linear models, differences of residual sums of squares give sequential or partial F-tests.
An analysis of variance comparing a quantitative response variable across levels of one factor. The ordinary independent-groups F-test evaluates equality of group population means under the one-way normal linear model. Rejection says that not all means are equal, rather than identifying every differing pair.
A heteroscedastic extension of independent-groups one-way analysis of variance, allowing unequal group variances. It does not make paired or clustered observations independent.
An analysis of variance for a design containing repeated observations on the same experimental units, with an appropriate within-unit error structure. It differs from treating every recorded response as independent. The allocation and covariance assumptions, not just the factor count, determine the applicable tests.
Multivariate analysis of variance compares mean vectors of several groups while accounting for correlations between their response variables. In the one-way normal model, independent observations share a positive-definite covariance matrix. Put and . Under equal means, these matrices have independent Wishart distributions with degrees of freedom and , respectively. This follows by separating the Gaussian data into orthogonal within-group and between-group projections. The Wilks lambda statistic tests equality of the means using both matrices, rather than independently testing each coordinate.
For groups with sizes , means , and overall mean , define and . Expanding gives total scatter because each within-group residual sum vanishes. Both matrices are positive semidefinite, and . They separate within-group noise from between-group mean separation.
For nonsingular within-group scatter and between-group scatter , the statistic is , where solve the generalized eigenvalue problem . It is small when the group means differ strongly relative to within-group variation. Maximizing a common-covariance normal likelihood under equal and unrestricted means gives the likelihood ratio . Its determinant factors cancel under any nonsingular change of response coordinates. For one response it is equivalent to the analysis of variance F-test.
An additive two-factor Gaussian model separates row and column effects. With one observation in each of cells, constraints fixing one row and column effect leave mean parameters and residual degrees of freedom. Balanced least squares gives fitted values equal to row mean plus column mean minus grand mean. With no cell replication, unrestricted interactions are confounded with residual error; the additive interpretation requires an assumption that those interactions are absent or negligible.
In a fully balanced crossed design, centered indicator columns for the two factors are orthogonal because each pair of levels occurs equally often. Missing cells can change the level-pair counts so that the displayed cross-product becomes nonzero. Then sequential sums of squares depend on term order, although the final additive fit is unchanged. Testing either factor conditional on the other requires its extra sum of squares from the appropriate reduced model.
For observed cells with means , form a bipartite graph joining row to column when that cell is observed. If all levels occur, the design rank is , where is the number of connected components. Indeed a coefficient perturbation in the kernel satisfies on every observed edge, and hence has exactly one freely chosen constant on each component. A connected design has rank and is identifiable after a single reference constraint. Missing cells destroy the balanced-design orthogonality of row and column effects, so sequential sums of squares can depend on order.
A two-way analysis of variance with the full interaction and one observation in each observed factor cell has one independently varying fitted cell mean per observation. A cell-indicator design matrix has full row matrix rank, even when some combinations are missing, so the model is a saturated statistical model. Its residual sum of squares is zero and its residual degrees of freedom are zero. Missing combinations make some coefficients nonidentifiable; they do not restore a pure-error estimate. Standard errors and an ordinary residual-based F-test for interactions therefore cannot be recovered merely by fitting this larger model.
For an ordered sequence of nested linear regression models , the sequential sum of squares for the th added term is . These are also called type-I sums of squares. They depend on term order when the design is not orthogonal. Dividing by the number of newly added coefficients and the full model's residual mean square gives the sequential F-test. A covariate added first is tested before adjustment for later terms, whereas a treatment added after the covariate is tested with that covariate already included.
For an orthogonal projection matrix , a sum of squares in ANOVA is . Mutually orthogonal projections yield an additive decomposition of total squared response magnitude. Removing the grand mean gives the corrected total.
A mean square in ANOVA divides a sum of squares in ANOVA by its positive number of statistical degrees of freedom. If the corresponding residual subspace has scalar error covariance , its expectation is . Its scale depends on whether raw observations or group means were projected.
An ANOVA stratum is an orthogonal response subspace representing one level of experimental variation, such as between blocks or within blocks. In a covariance model scalar on each such subspace, its eigenvalue supplies the common variance scale for its projected coordinates. Treatment and residual sums of squares in ANOVA must be compared within appropriate strata.
The within-block ANOVA stratum contains response vectors whose coordinates sum to zero separately in every block. For blocks of size its dimension is . A shared additive block effect cancels in every vector in this subspace.
In a complete two-factor design with equal cell replication, centred factor indicator columns for different factors have zero cross-products. Consequently the two main effects in an additive normal linear model are orthogonal, and their extra sums of squares do not depend on the order in which these main effects are entered. An omitted interaction term can still require a separate adequacy check.
The Frisch–Waugh–Lovell theorem says that a regression coefficient can be obtained by residualizing both the response and its predictor against the remaining predictors and then regressing one residual on the other.
Simple linear regression uses one predictor and an intercept, , with . The regression coefficients describe a straight conditional-mean line: is its value at zero and its rate of change per unit of the predictor. When zero is outside the observed range, predictor centering can make the intercept refer to a more representative predictor value.
For fixed predictors and uncorrelated mean-zero errors of common variance , with ,A larger predictor spread improves slope precision under this model. In the worked example and ; the estimated error variance is . A normal linear model gives the slope pivot a Student t-distribution with degrees of freedom. The distinction between a fitted line and a reliable uncertainty statement is precisely the role of the error assumptions.
Consider ordinary least squares with an intercept, one nonconstant predictor, cases, a nonconstant response, and a positive residual sum of squares. With the usual common-variance standard error, put . ThenThe least-squares normal equations give zero residual sum and zero residual inner product with the centred predictor, proving the first identity and . The fitted centred sum of squares is . Dividing it by gives the one-predictor F statistic and the squared zero-slope t statistic. Dividing fitted and residual sums of squares by their total gives the last expression. If , the adjusted coefficient of determination is .
These are algebraic consistency identities for one specified fit; the mean identity needs no normal-error assumption. A normal linear model supplies the usual finite-sample t and F reference distributions. Heteroscedasticity-robust standard errors need not satisfy the displayed F=t-squared relationship to the classical sums-of-squares F statistic. Rounding can create small discrepancies, while different analysed records or a changed model can create larger ones; neither should be silently treated as the same fit.[ref]
Summarizing Linear Model Fits in the R documentation. Value: coefficient matrix, sigma, df, fstatistic and r.squared
In simple linear regression written as , the constant and centred predictor columns are orthogonal. Differentiating the sum of squared residuals gives the displayed ordinary least squares estimators, provided . For independent mean-zero errors of common variance , both estimators are unbiased, their variances are and , and their covariance is zero. The uncentred intercept is .
The residual sum of squares measures how far the observed responses lie from their fitted values. If is the th regression residual, thenIt is the squared Euclidean norm of the regression residual vector. Squaring prevents positive and negative deviations from cancelling and gives large deviations more weight. In the constructed five-point example in linear regression, the regression residuals are , so the residual sum of squares is .
Ordinary least squares minimizes the residual sum of squares over the chosen linear regression family; ridge regression minimizes the residual sum of squares plus a penalty. Consequently the ridge regression fit can have a larger residual sum of squares than the ordinary least squares fit on exactly the same design matrix. For the one-predictor construction in ridge regression, the residual sum of squares rises from to when the penalty changes from to ; that increase is the cost of shrinking the fitted slope.
Dividing the residual sum of squares by gives the training error for squared-error loss, not an estimate based on fresh responses. Its units are squared response units, and it adds across observations, so raw totals need not be comparable across different response scales or sample sizes. Comparing fits to the same responses is useful, but choosing a ridge regression penalty by minimum training residual sum of squares favors the unpenalized fit. Assess prediction error using a validation set or cross-validation instead.[ref]
Model selection and validation 1: Cross-validation. slides 6–8 and 11–14: fresh-response error, training error and held-out scoring
Ridge regression fits a linear regression model while penalizing the size of its slope regression coefficients. For a fixed design matrix containing the slope predictors, observed responses , and an unpenalized regression intercept , the objective isHere is the all-ones vector, and is the squared Euclidean norm of the slopes alone. The first term is the residual sum of squares; the second implements regularization. No random-error assumption is needed to define this fit. The convention is a summed squared-error loss: writing the objective as gives the same fit when .[ref]
Modern regression 1: Ridge regression. slides 5 and 7: summed squared-error objective and unpenalized intercept
For an exact example, reuse the constructed pairs from linear regression. Their sample means are and , and the centered cross-products are and . ThusThe ordinary least squares line has slope and residual sum of squares . At , ridge regression has slope , regression intercept , and residual sum of squares ; at these become , , and . Every line passes through : the penalty reduces the slope while retaining the response sample mean.
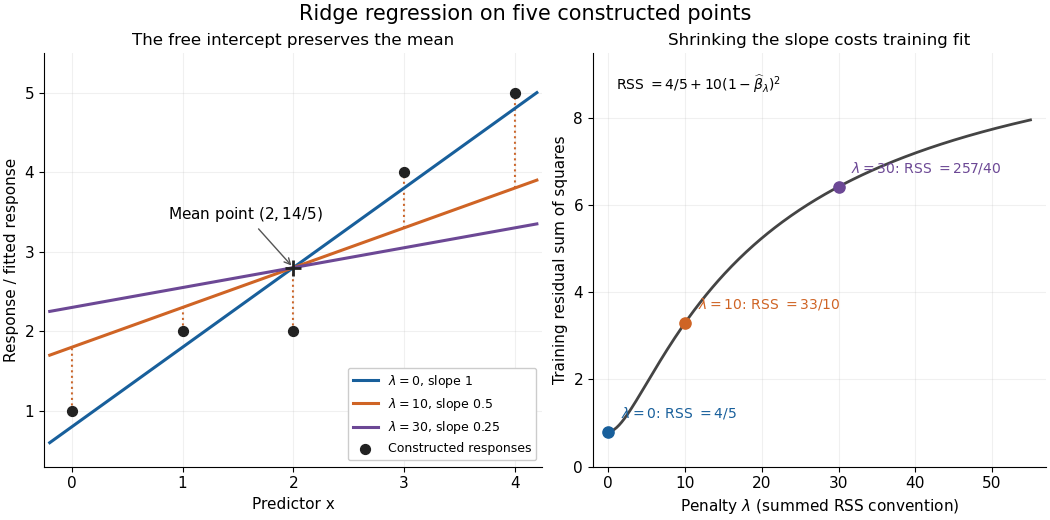
The computational benefit is visible after predictor centering. Write for the design matrix with each column's sample mean subtracted, and . The unpenalized intercept in ridge regression gives , and the closed-form ridge regression estimator solvesFor any nonzero vector and , . This positive-definite matrix is therefore invertible even when lacks full column rank, including repeated columns or . The unique penalized slopes resolve the ambiguity of rank-deficient ordinary least squares; they do not supply evidence about slope directions absent from the data. This makes ridge regression useful for multicollinearity.[ref]
High-Dimensional Regression: Ridge. p. 1, equations (1)–(2): uniqueness for positive penalty regardless of design rank
Predictor centering and scaling serve different purposes. Centering handles the free regression intercept. Scaling determines what counts as a large slope: replacing by changes its coefficient to for the same predictions, changing its contribution to an unweighted penalty. A common convention forms standard scores using each nonconstant predictor's sample standard deviation , then penalizes slopes in those coordinates. Since , this is the weighted penalty in the original units. Constant columns have and must be removed before this scaling. Scaling is a modelling choice; equal penalties in original units and in standardized units define different fits.[ref]
Modern regression 1: Ridge regression. slide 7: center predictors, leave the intercept free and scale predictors to sample variance one
The singular value decomposition explains the shrinkage. If is the compact decomposition using the positive singular values , with columns of , thenThe principal-component shrinkage by ridge regression factors are between and : directions with small singular values are damped most. As , the fitted values approach ; the vanishing-penalty ridge limit recovers the ordinary least squares fitted vector as , even if the slope estimates at zero penalty are nonunique. The covariance and bias of a ridge regression estimator describes the resulting bias-variance tradeoff. A penalty can reduce variance of an estimator while introducing bias of an estimator; the unbounded directional risk of fixed ridge shrinkage rules out a uniform improvement for a fixed positive penalty over all possible signals.[ref]
For a second exact construction, choose a centered orthonormal set of three vectors,and set and . The squared singular values are and . At , the fitted coordinates along are , retaining and of their ordinary least squares values . At they become , retaining and . The unfittable component contributes to every residual sum of squares, giving total values , , and at penalties . These are constructed fits, not measured prediction results.
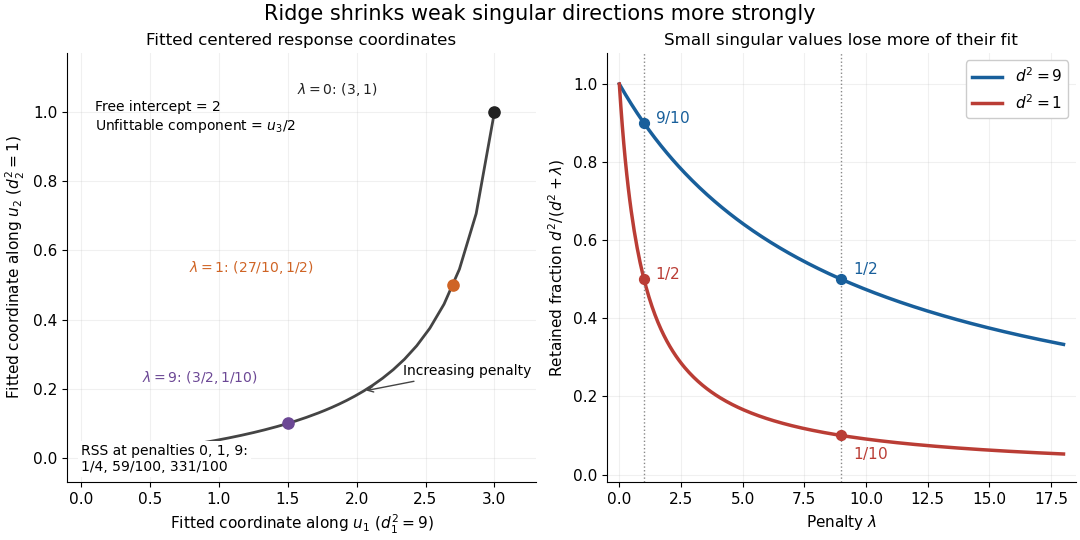
Exact synthetic ridge shrinkage retains the strong singular direction longer than the weak one
. Details. The penalty is a hyperparameter, so fitting slopes at a fixed value and selecting that value are separate tasks. Use a validation set or K-fold cross-validation to compare candidate penalties by held-out squared-error loss. In each split, compute predictor sample means and scales from that split's training data, apply the same transformation to its validation set, and refit the slopes; using held-out information in preprocessing introduces data leakage. Minimum training residual sum of squares cannot select useful shrinkage: ordinary least squares already attains the smallest possible value.[ref]
Model selection and validation 1: Cross-validation. slides 5–8 and 11–14: tuning for prediction, training error and refitting on each training fold
After model selection, refit on all training data with the selected penalty. A separate test set or nested cross-validation assesses the entire selection procedure; a low selected validation score alone is no performance guarantee.[ref]On Over-fitting in Model Selection and Subsequent Selection Bias in Performance Evaluation by Gavin C. Cawley and others. pp. 2079–2080: selection as part of fitting and nested assessment
For likelihood and independent prior , the posterior distribution is Gaussian with covariance as displayed and mean . Its mean and mode therefore coincide with the ridge regression coefficient estimate. A Gaussian prior alone does not imply this conclusion without the stated likelihood.
// Target: foundations-of-mathematics.bigb
For fixed positive ridge regression penalty, choose a unit eigenvector of with eigenvalue , and signal . The directional ridge risk is , whereas ordinary least squares has risk . Letting grow makes the ridge squared bias arbitrarily large.
For a full-rank centred design, unscaled ridge regression and zero-mean errors with covariance , put and . The ordinary-least-squares risk matrix minus the ridge risk matrix is . It is positive definite whenever , including every positive when . Thus one signal-dependent small penalty improves every nonzero-direction mean squared error.
In ridge regression, penalize slopes but ordinarily leave the regression intercept free. Centering gives and . An exactly centered predictor matrix has for every penalty. A table with a penalty-dependent intercept therefore cannot arise from exactly centered columns under this convention.
For a fixed centered design matrix , independent errors of variance , and objective , put and . The ridge regression estimator hasThus its standard error alone does not justify centering a confidence interval for at the biased estimator. A penalty chosen from the responses also changes its sampling distribution.
For , the ridge regression objective has gradient . The matrix is positive definite, so the unique minimizer is .
In an eigenbasis of , ridge regression divides the corresponding component of by . If , its eigenvector satisfies , and hence exactly. Only positive eigenvalues contribute to the limit, giving the Moore-Penrose inverse expression for the minimum-norm least-squares solution. No full-rank or sample-size assumption is needed.
For any real design matrix and , . Multiplication by identifies the primal ridge regression fitted values with , , the kernel-ridge hat matrix for the linear kernel. No rank assumption is needed.
For , ridge regression multiplies the fitted response along the th normalized sample principal component by the shrinkage factor . Directions with variance much larger than are nearly retained, while directions with variance much smaller than are nearly removed.
Fitted values are the predictions at the predictor values used to fit a regression model. In linear regression with an explicit regression intercept,Here is the slope design matrix, and is the regression residual vector. The fitted values estimate the regression function at the observed predictors; they need not equal the observed responses, which may also contain random errors. Prediction at a new predictor vector uses with the same centering and scaling used in fitting. A prediction interval addresses uncertainty in a new response rather than just displaying this point prediction.
For the five constructed observations in linear regression, ordinary least squares gives fitted values . The ridge regression fit at instead gives . Both fitted vectors have sample mean because the regression intercept is unpenalized; their regression residuals differ and their residual sums of squares are and , respectively.
For ordinary least squares, the fitted values are the orthogonal projection of onto the column space of the complete design matrix, including its regression intercept column. They remain unique even in rank-deficient ordinary least squares, although the regression coefficients can be nonunique. The regression residuals are then orthogonal to every column.[ref]
Regression 1: Different perspectives. slides 6–10: fitted values, hat matrix, projection and orthogonal residuals
With centered slopes, ridge regression instead satisfies , so the regression residuals need not be orthogonal to the slope columns. Their sum is still zero because the regression intercept remains free.For fixed predictors and scales and a fixed positive penalty, ridge regression gives a linear smoother,For with at least one nonzero slope direction, this matrix is not an orthogonal projection matrix: applying it twice shrinks that direction again. Its effective degrees of freedom are , where are the positive singular values of ; the extra counts the free regression intercept. If the penalty is selected using , the resulting fitting rule need not be a linear smoother, since its chosen also depends on .
A linear smoother has fitted-value vector , where the smoother matrix depends on the covariates and tuning parameters but not on the response vector.
For a linear smoother , its effective degrees of freedom are . This measures sensitivity of fitted values to responses even when is not an orthogonal projection.
The design matrix has one row for each observation and one column for each regression coefficient, so the linear predictor is .
If each level of one categorical variable belongs to exactly one level of another, indicators for the coarser levels are sums of indicators for the finer levels. Including unrestricted fixed effects for both therefore gives a rank-deficient ordinary least squares: the separate effects lack identifiability without additional constraints.
A regression coefficient is a component of measuring the change in the linear predictor associated with its design-matrix column.
These are the parameters of a linear regression predictor, rather than the regression procedure itself.
In an ordinary linear regression with nonzero response and predictor standard deviations, the coefficient after rescaling predictor and the response to standard-deviation units is the displayed quantity. An unstandardized coefficient table does not automatically report it. Standardization and reference coding must be explicit.
In a simple linear regression with conditional mean , the slope is the change in that mean per unit increase in the predictor. The ordinary least squares estimate is when . It describes a statistical association; a causal interpretation requires further assumptions.
If but the predictor is observed as , with independent centred errors, the population regression slope isMeasurement error in the predictor therefore shrinks the slope toward zero, while independent response noise changes its uncertainty but not its population value.



