Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Page table
Context switch 2026-10-13
A context switch transfers CPU execution from one operating-system process or software thread to another while preserving enough execution context for the suspended task to resume. The operating-system kernel saves the outgoing task's processor registers, including its resume program counter and stack pointer, and restores the incoming task's saved state. Hardware entry and software switching divide this work differently across architectures; the diagram groups them into logical save and load steps. During the transition the same CPU executes the operating-system kernel's scheduler and switching code. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/cpu-mechanisms.pdf. Remzi H. Arpaci-Dusseau and Andrea C. Arpaci-Dusseau, Operating Systems: Three Easy Pieces, chapter 6, section 6.3: saving and restoring context
For a schematic switch from A to B, let A's resume program counter be , its stack pointer , and one illustrative data processor register contain 7. B's saved values are . Saving A retains in A's execution context; loading B establishes before B resumes. These are selected fields, not a complete architecture-specific execution context. Later restoring A recovers its 7 even though B has used the same physical processor register for 42.
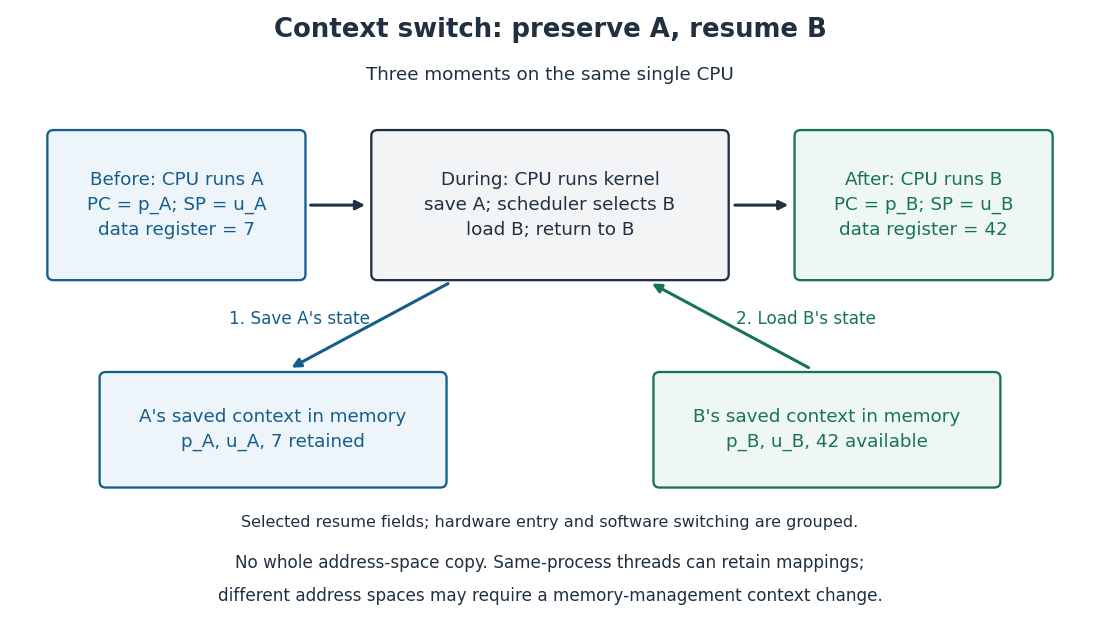
The useful invariant is that each suspended task retains its own resume state, so another task's use of the processor registers does not erase it. This is what makes repeated turns under round-robin scheduling possible. Saving an execution context does not copy the entire address space. Switching between software threads of one operating-system process can retain the same address space; switching between operating-system processes with different address spaces may also require changing the memory management unit's translation context, such as the active page table and associated address space identifier, depending on the architecture. Their contents remain in computer memory. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/threads-intro.pdf. Remzi H. Arpaci-Dusseau and Andrea C. Arpaci-Dusseau, Operating Systems: Three Easy Pieces, chapter 26, introduction: thread contexts and shared address spaces
Entering the operating-system kernel through an interrupt, synchronous processor exception or system call does not automatically imply a context switch to another task. The handler may return to the same task; process scheduling determines whether another runnable task should take over. A context switch consumes time, and a changed memory cache or translation lookaside buffer working environment can add subsequent costs. Those costs are excluded from the toy process scheduling timelines, which are calculations rather than operating system benchmarks. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/cpu-mechanisms.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 6, section 6.3: continue the current process or switch
[ref]https://pages.cs.wisc.edu/~remzi/OSTEP/cpu-sched.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 7, section 7.7: direct and indirect switching costs
Copy-on-write 2026-10-13
Copy-on-write defers copying until a modification needs private storage. With paging, separate address spaces can map their memory pages to the same page frames, using memory protection to prevent writes to the common contents. Reads need no copy. A permitted write to a shared page frame first separates the writer's storage, so the other operating-system process keeps the old contents. Sharing is safe because the common contents remain unchanged while shared; the logical private copies can still evolve independently.[ref]
Complete Virtual Memory Systems. pp. 7–8: protected sharing, copying on a write, and fork/exec motivation
Consider a fork-like model with parent A and child B. Each has a separate page table, with three inherited private, logically writable memory pages. Both initially map virtual page numbers
0x12, 0x13, 0x14 to page frames F0, F1, F2. The page table entries temporarily deny writes for copy-on-write; a read of x at offset 0x34 in virtual page 0x12 returns 7 in either address space. Separate page tables do not imply separate stored bytes.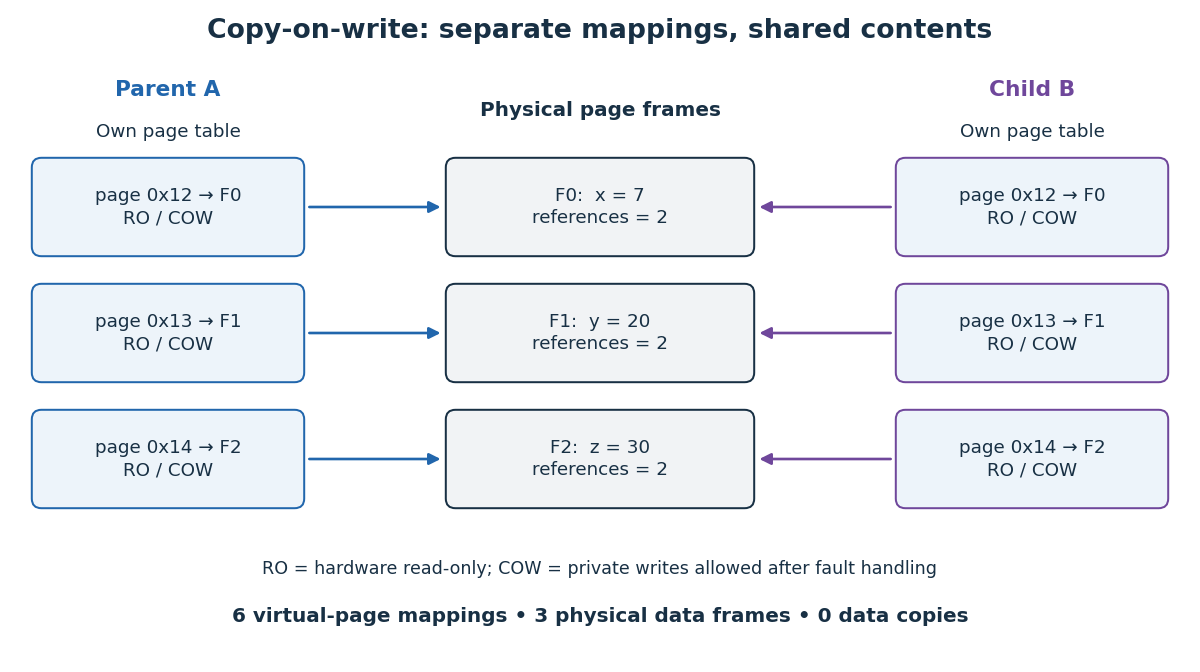
Now B writes
x = 42. In this model, copy-on-write fault handling allocates F3, copies all of F0's contents into F3, redirects only B's page table entry, enables its write, and retries the store. A still reads 7 through F0; B reads 42 through F3 at the same virtual address. F1 and F2 remain shared. The reference counting labels count mappings in this example: F0 drops from two to one, while F3 starts at one. Updating one byte can therefore copy a whole memory page.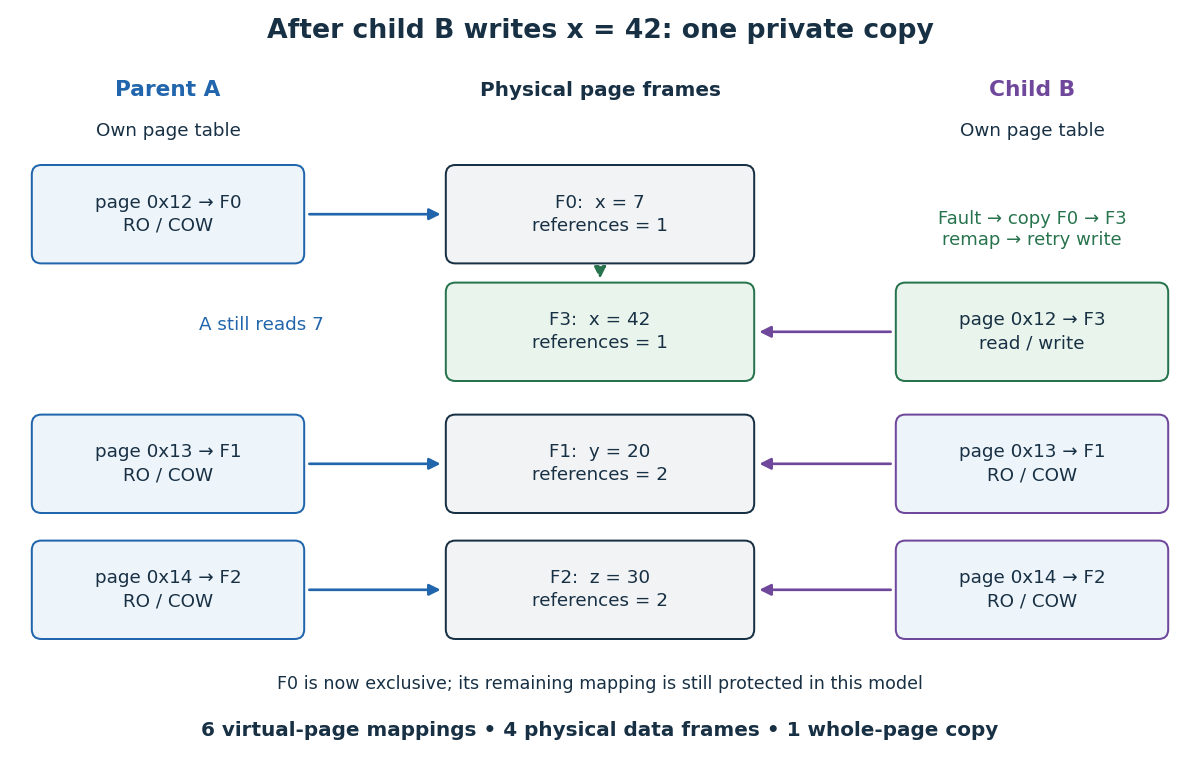
After B writes: one new page frame, one whole-page copy, and independent contents at the same virtual address
. Details. The attraction is avoiding work that may never be needed. If B only reads, this model makes no data copies; if B replaces its program and discards these mappings, copying them beforehand would have been wasted. Copy-on-write trades eager copying for protected sharing and later page faults. The page tables, reference counting, and operating-system process records still cost time and computer memory.[ref]
Complete Virtual Memory Systems. pp. 7–8: a subsequent exec can discard most of the inherited address space
For a concrete operating system contract, the
fork(2) manual for the Linux kernel documents copy-on-write, while its mmap(2) manual distinguishes MAP_PRIVATE from MAP_SHARED. Writes through MAP_PRIVATE are not propagated to other mappings or the underlying file; writes through MAP_SHARED are visible to other operating-system processes mapping that region. An inherited shared mapping therefore retains shared-write behavior. For a private memory-mapped file, visibility of later changes to the underlying file is unspecified: private writes alone do not guarantee a frozen snapshot of the file. [ref][ref]Nor does fork make every resource independent. With the Linux kernel, inherited file descriptors refer to the same open file descriptions, including shared file positions. Special mapping policies can omit a region from inheritance or zero it in the child. Thus the diagrams describe ordinary inherited private memory pages, not every resource reachable by a parent. [ref]
Copy-on-write fault handling 2026-10-14
The operating-system kernel must distinguish a temporarily protected copy-on-write mapping from one whose writes are forbidden. The teaching procedure in MIT's xv6 lab protects both page tables, copies the shared page frame on a valid write page fault, and installs a writable page table entry. Originally read-only code remains read-only. Its reference counting increments on sharing and decrements on removal; storage is freed only after the last reference disappears. The lab also requires kernel writes into user storage to respect copy-on-write, and specifies failure if no free storage remains. [ref]
Every write must respect the sharing policy, but every write need not copy. Repeated writes to B's already private writable F3 need no further copy-on-write page fault. If A later writes F0, an implementation can reuse F0 when it establishes exclusive, writable ownership; A's remaining read-only page table entry may still need a page fault to enable the write. This exclusive-reuse rule is an assumption of copy-on-write page accounting below, not a promise that every operating system uses that path. A count of one alone is not a universal permission to alter storage belonging to a memory-mapped file or another owner.
Changing mappings or permissions must also make cached address translations consistent. [ref] Concurrent software threads require synchronization around ownership checks, copying, and installation to prevent a race condition; neither diagrams nor counts specify a production operating-system kernel's locking or hardware invalidation protocol.
Copy-on-write page accounting 2026-10-14
Assume exactly two operating-system processes, initially resident private memory pages of bytes each, initially distinct page frames shared by A and B. Neither unmaps, exits, forks again, or encounters page replacement; no other owner exists, allocation succeeds, and a first write copies one whole shared memory page. Once a page frame is exclusively owned it is reused on writes, without another copy; writable mappings remain writable. Count data storage only, excluding page tables and other bookkeeping. With B as the only writer, writing distinct memory pages givesThis depends on distinct written memory pages, not the number of store instructions or reads. For the diagrams, take and an illustrative bytes:
| Access pattern | New page frames | Whole-page copies | Resident data bytes |
|---|---|---|---|
| Both only read | 0 | 0 | 12288 |
B writes memory page 0x12 once | 1 | 1 | 16384 |
B writes memory page 0x12 one hundred times | 1 | 1 | 16384 |
B writes memory pages 0x12 and 0x14 | 2 | 2 | 20480 |
| B writes all three memory pages | 3 | 3 | 24576 |
B then A each write memory page 0x12 | 1 | 1 | 16384 |
For both writers, let be the sets of initial memory page numbers written by A and B. Under these assumptions, new allocations and copies both equal , the cardinality of their set union, while resident data storage is . Each initially shared page frame needs at most one split: after the first writer copies it, the other owns the original exclusively. Both writing the same memory page therefore produces two versions with one copy, even if the final values happen to match. The last row can incur two protection page faults, one for each writer, while making only one copy. A handler that always allocates on a protected write can make a second copy and free the now-unreferenced original: allocation counts and final resident storage are different observables.
These are model counts, not measured Linux costs or a guaranteed bound on total computer memory. More descendants, other owners, demand paging, page replacement, different memory page sizes, and different exclusive-ownership rules change the accounting. The useful claim is conditional: deferred data copying can cost in proportion to the distinct shared memory pages that are written, while creating separate page tables has its own cost.
// Target: computer-science.bigb
David S. Miller Created 2026-10-13 Updated 2026-11-05
David S. Miller authored Cache and TLB Flushing Under Linux by David S. Miller, which specifies the effects required of Linux kernel cache and translation-invalidation interfaces. When page tables change, an old translation lookaside buffer entry may still describe an obsolete mapping. The documented flush operations make those changes effective for the relevant address spaces and CPUs.[ref]
Cache and TLB Flushing Under Linux by David S. Miller. opening TLB discussion and flush_tlb interfaces

Portrait of David S. Miller
. James Morris. CC BY 2.0, via Wikimedia Commons. Source. Memory management unit Created 2026-10-13 Updated 2026-10-14
The hardware that performs address translation and access checks. Whether a TLB miss is resolved entirely by hardware or with operating system assistance depends on the architecture.
For paging, the memory management unit uses the active address space and the kind of access: reading, writing, or fetching an instruction. Processor privilege level can also affect permission. A TLB hit supplies cached translation attributes; it does not bypass memory protection. On a TLB miss, some architectures perform a hardware page table walk, while others enter an operating system refill handler. Both can resolve a resident mapping without a nonresident page fault.[ref]
Paging: Faster Translations (TLBs). Operating Systems: Three Easy Pieces, chapter 19, Paging: Faster Translations (TLBs), sections 19.1, 19.3–19.4, printed pp. 2, 6, 8: permission checks, refill ownership, and cached attributes
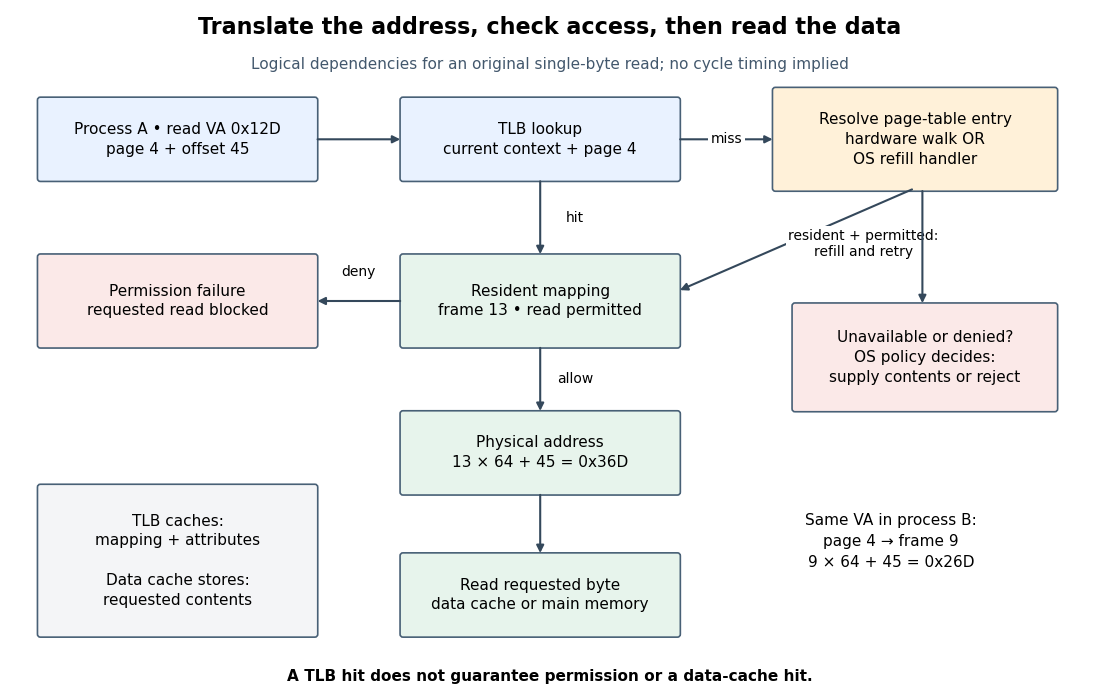
Logical address translation control path: a cached mapping, refill, permission check, and separate data read
. Details. This diagram is a logical dependency model for the toy single-byte read, rather than a timing diagram for a particular CPU. A translation lookaside buffer caches translations and access attributes; a data memory cache caches contents. A TLB hit can accompany a data cache miss, and a TLB miss can accompany a data cache hit after successful refill. Reading page table entries during refill is also distinct from reading the requested data. Actual implementations may overlap steps.
Extend process A's toy address space with these independent starting states. Virtual page 4 is resident in page frame 13 and readable but not writable. Virtual page 5 is a permitted readable memory page whose old contents are in backing storage and which is initially nonresident. Virtual page 6 has no mapping authorized by the operating system. Assume permission changes and eviction always invalidate affected cached translations before later accesses, no copy-on-write policy, and a free page frame 2 for loading virtual page 5.
- Read
0x12Dwith an empty translation lookaside buffer: a TLB miss discovers resident virtual page 4, caches its attributes, and reads physical address0x36D. There is no nonresident page fault. - Write
0x12Dwith that translation already cached: a TLB hit finds the mapping, but memory protection denies the write. The target byte remains unchanged even though its page frame is resident. - Read
0x16D: virtual page 5 and offset 45 are permitted but nonresident. A page fault lets the operating system load the contents into page frame 2, update the page table, and retry. Successful address translation then gives ; the requested read occurs only after the contents are ready. - Read
0x1AD: virtual page 6 and offset 45 have no authorized mapping. The operating system rejects the access in this model; finding a free page frame would not supply authorization.
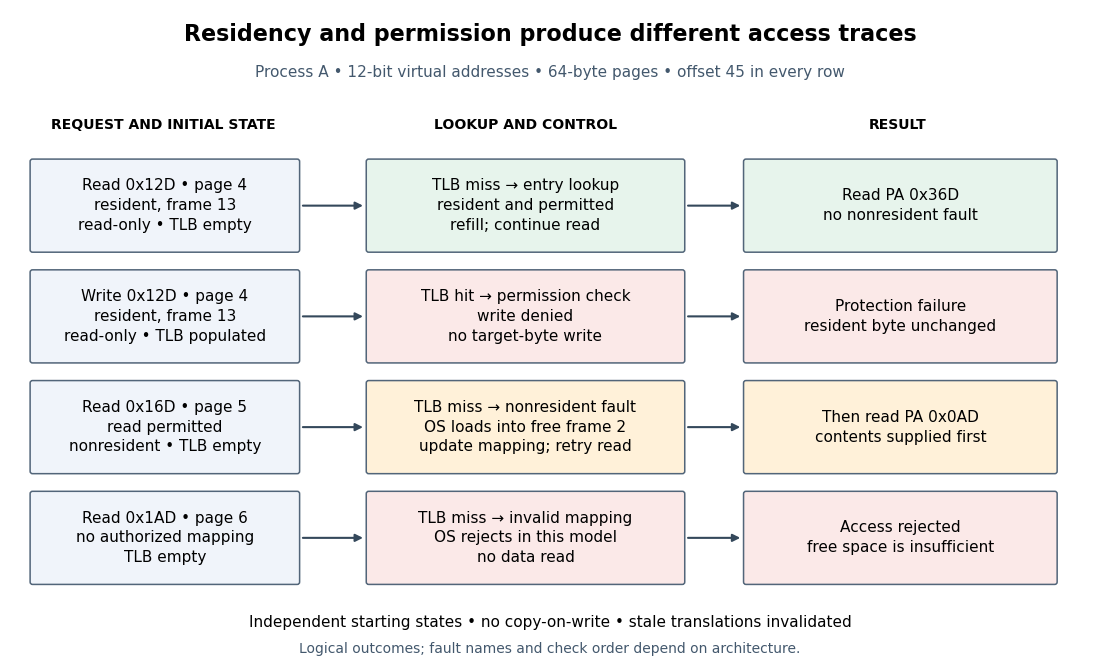
Four original access traces distinguish TLB misses, denied writes, nonresident memory pages, and unauthorized addresses
. Details. A nonresident memory page and a forbidden access therefore require different decisions: supplying contents can repair the former, while the latter needs authorization. Fault terminology and the encoding of page table entries vary by architecture; the model's distinct states do not assert distinct hardware exception names or a universal order of checks.[ref]
Beyond Physical Memory: Mechanisms. Operating Systems: Three Easy Pieces, chapter 21, Beyond Physical Memory: Mechanisms, sections 21.2–21.5, printed pp. 3–7, especially the terminology aside and Figures 21.2–21.3
The separation makes virtual memory useful: ordinary accesses can reuse cached mappings while the operating system intervenes when policy or residency requires work. It also makes failures easier to diagnose. A lost cached translation, unavailable contents, and denied permission are three different obstacles, even when all interrupt the same requested read.
Memory-mapped file 2026-10-13
A memory-mapped file makes a range of a file accessible through an operating-system process's virtual memory address space. Once the mapping exists, ordinary loads and stores address its contents instead of explicitly reading them into a separate application buffer. This is attractive for jumping between records in a large file: an offset becomes an address calculation, and demand paging can supply the needed memory pages. It removes the application's explicit read-and-copy step; it does not promise that every access avoids copying, input-output, page faults or overhead, or that mapping is universally faster.
The backing file, page cache contents and each operating-system process's page table play different roles. For ordinary buffered Linux kernel mappings, the page cache holds reusable file contents; normal reads and writes also use it. A valid mapping can exist before this operating-system process has a usable page table entry. A first load can therefore trigger a page fault even when another reader has already brought the contents into computer memory. If the contents are absent, servicing the page fault can require input-output; if present, the handler can install an address translation without that read. Special paths that bypass the page cache are outside this explanation.[ref]
Page Cache by The kernel development community. Page Cache, opening paragraph: normal reads, writes and mmaps go through the page cache; bypass paths exist
The following example and diagrams are an original toy model, not an actual benchmark or a trace of a running operating system. They assume ordinary buffered file mappings, successful accesses, two cooperating operating-system processes, no concurrent resizing, and explicitly ordered actions. Memory-mapped file offset translation explains where the accesses land; shared file mappings and private file mappings explain whose contents change; memory-mapped file synchronization explains the separate persistence boundary.
Memory-mapped file offset translation 2026-10-14
Let be the memory page size, the aligned starting file offset, the mapping length and its base virtual address. A valid displacement with corresponds to file offsetHere is the relative memory page index, the floor function selects its integer part, and Euclidean division gives the within-page displacement . The backing page begins at . This identifies file contents; the page table separately selects a resident page frame and enforces permissions.
Take , and bytes in a file of at least 12288 bytes. A has a shared file mapping at . B has a shared file mapping at and a private file mapping at . These bases are illustrative chosen results, not requested fixed addresses. All three mappings cover the same two backing pages: file offsets 4096–8191 and 8192–12287. Displacement selects relative page 1, within-page displacement 37 and file offset . Thus A's
0x10001025, B's shared 0x20001025 and B's private 0x30001025 initially identify the same byte. The adjacent displacement 4134 identifies file offset 8230. Different virtual addresses can reach the same backing contents.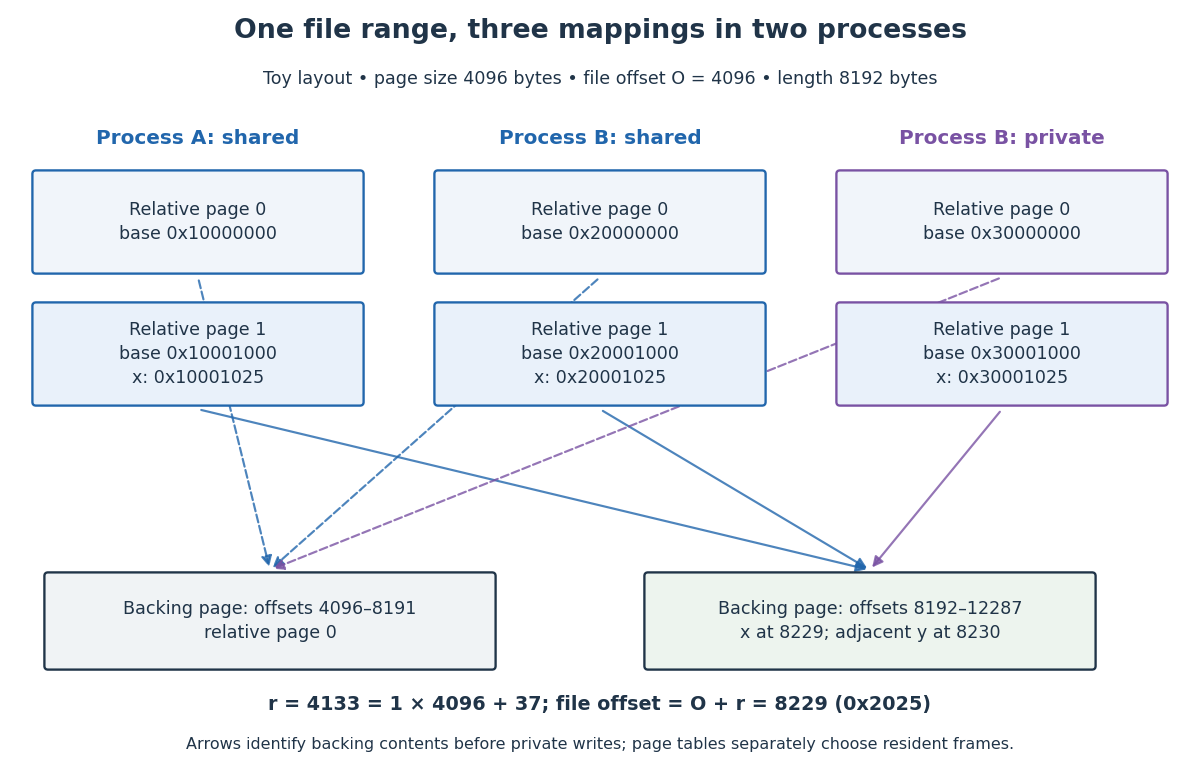
Two operating-system processes map two backing pages at different virtual addresses; displacement 4133 identifies file offset 8229
. Details. To access a requested file offset that is not aligned, choose and displacement . Mapping enough bytes to cover that displacement plus the requested length makes the desired data start inside the aligned mapping. Do not pass the unaligned directly as the Linux kernel
mmap offset. For example, uses and displacement 37; that one-page start differs from our two-page mapping's . Multi-level page table 2026-10-14
A hierarchy of page tables indexed by successive groups of virtual page number bits. Unused regions can omit lower-level tables.
The useful omission is an entire lower-level array, not merely an invalid page table entry. One absent upper-level entry can represent a large unmapped interval of the address space. The Linux kernel's documented hierarchy uses this idea to avoid allocating tables for unused regions; its software levels can also be folded to match the hardware. [ref]
Page Tables by The kernel development community. Page Tables: opening hierarchy discussion, paragraph beginning "One could of course imagine"; Page Table Folding
Page fault Created 2026-10-14 Updated 2026-10-14
A page fault transfers control to the operating system when an access cannot proceed under the current paging translation or protection rules. The term includes both unavailable translations and forbidden accesses on x86. Intel's manual distinguishes these causes; AMD's error code likewise distinguishes ordinary not-present faults from protection violations. Other architectural causes, including malformed page table entries, also exist. [ref]
https://cdrdv2-public.intel.com/671200/325462-sdm-vol-1-2abcd-3abcd.pdf. Intel SDM, volume 3A, section 4.7: Page-Fault Exceptions
[ref]https://docs.amd.com/api/khub/documents/sD1_QL~h4Afq2_tvzxqqSQ/content. AMD64 Architecture Programmer's Manual, volume 2, revision 3.44, section 8.4.2: Page-Fault Error Code
The illustrative page table in paging separates three situations:
- A read at virtual address
0x1434targets a permitted but nonresident memory page. The operating system may supply it and retry the access. - A write at virtual address
0x1234targets a resident, read-only memory page. The page fault is caused by missing write permission, not by missing contents. - A read at virtual address
0x1534targets an unmapped part of the address space. The operating system must reject it unless its policy authorizes creating a mapping.
A page fault is not necessarily a program error or a storage-device read. Demand paging can allocate a zero-filled page frame without reading secondary storage. A copy-on-write write deliberately encounters read-only permissions; the operating system supplies a private copy and enables the write. A truly forbidden access may instead terminate the operating-system process. The handler interprets the fault using both architectural fault information and its own mapping policy. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/vm-complete.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 23: demand zeroing and copy-on-write
For a nonresident memory page whose contents must be loaded, the handler obtains a page frame, possibly invokes page replacement, supplies the contents, updates the page table, arranges any necessary translation lookaside buffer invalidation, and resumes the operation. If no mapping or permission can legally be supplied, it reports failure. This mechanism lets ordinary accesses request work only when it becomes necessary. [ref]
Beyond Physical Memory: Mechanisms. Operating Systems: Three Easy Pieces by Remzi H. Arpaci-Dusseau and others; Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 21: Beyond Physical Memory, Mechanisms, sections 21.3–21.5
// Target: computer-science.bigb
Page table 2026-10-14
A page table is the data structure describing an address space's mappings from virtual page numbers to page frames, together with access and status information. A page table entry can describe a resident memory page and its permissions. Nonresident or unmapped memory pages require a representation that lets the operating system distinguish them; a hardware not-present flag alone need not make that distinction. On x86, additional operating system information determines whether a not-present mapping is legitimate. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/vm-paging.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 18, section 18.3: page-table contents and the x86 present bit
The four rows drawn under paging are an illustrative model, combining page table and operating system information: virtual page
0x12 is resident in physical frame 0x07 with read-only permission; 0x13 is resident in 0x02 with read/write permission; 0x14 is mapped read/write but nonresident; 0x15 is unmapped. The labels deliberately separate mapping policy, residency and permission. They are not a literal x86 entry layout. A translation lookaside buffer valid flag is a fourth, independent notion: it says that a cached translation can be considered, not that every resident memory page has a cached translation.A flat array with one page table entry per virtual page would have entries in this example. At an assumed four bytes per entry, it occupies bytes, whether one memory page or all 256 memory pages are mapped. A multi-level page table saves space in sparse address spaces by allocating lower-level tables only for the regions that need them. The tradeoff is extra dependent lookups during a page table walk; a translation lookaside buffer avoids repeating those lookups on a hit. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/vm-smalltables.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 20: Paging, Smaller Tables, section 20.3
Page table entry 2026-10-14
One record in a page table, holding a page frame number or a next-level table reference together with architecture-dependent flags. Effective permissions in a multi-level page table can depend on several entries, not just the final one.
Paging 2026-10-13
Paging divides an address space into fixed-size memory pages and main computer memory into equally sized page frames. Here assume byte addressing, one memory page size bytes, and an unsigned virtual address . Its virtual page number and offset areThe brackets denote the floor function, and gives the remainder in Euclidean division. If the page table maps to physical frame number and permits the access, the physical address isThe low bits are unchanged; the other bits select the memory page or page frame. A bit shift and bit mask can extract these fields. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/vm-paging.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 18: Paging, Introduction, sections 18.1–18.2
For a 16-bit virtual address and bytes, take in hexadecimal. Then and . A mapping to givesThus the eight high bits choose a mapping; the eight low bits choose the same position in the resulting page frame. The 256-byte size is for illustration, not a claim about an actual architecture's supported memory page sizes.
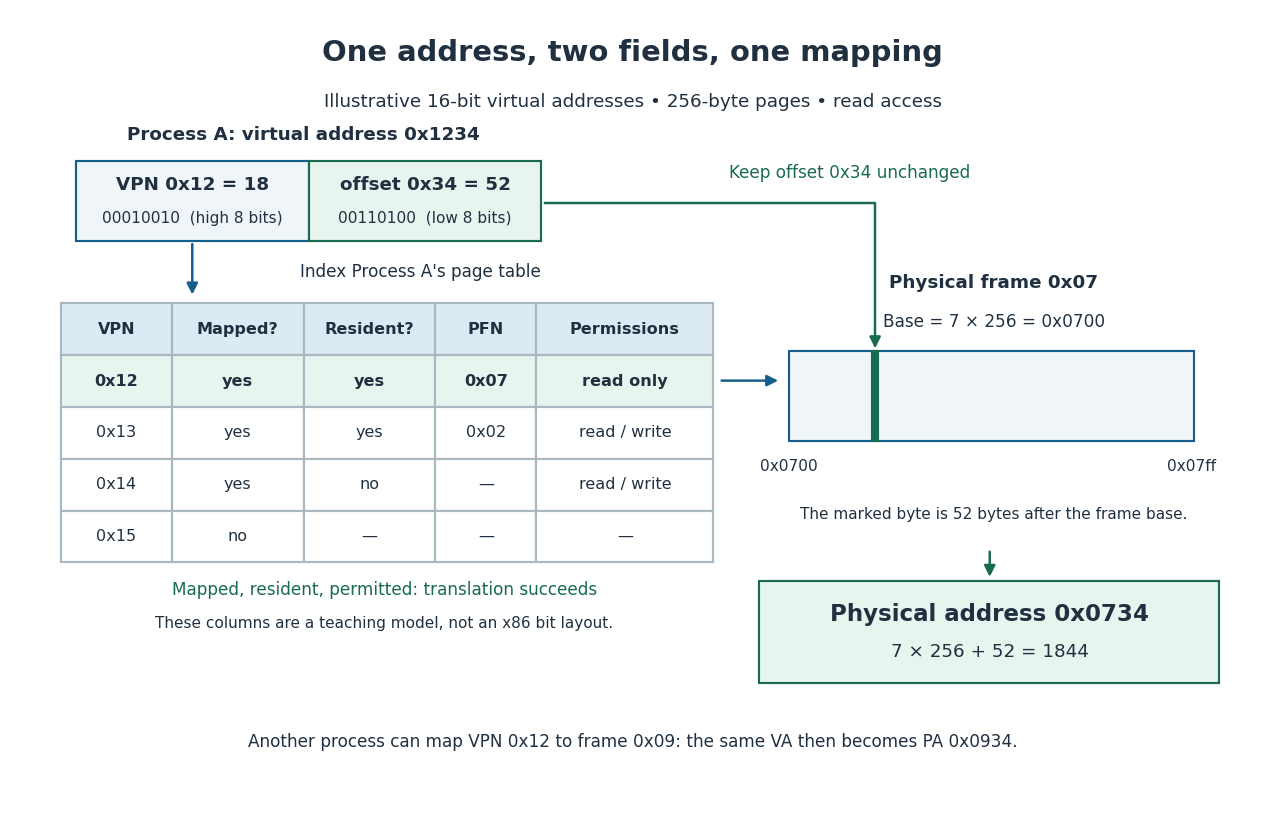
Translating 0x1234 through an illustrative page table, with a separate offset and access check
. Details. The useful freedom is that adjacent memory pages can occupy unrelated page frames. In the diagram, virtual pages
0x12 and 0x13 occupy page frames 0x07 and 0x02; virtual addresses 0x12ff and 0x1300 are consecutive, but translate to physical addresses 0x07ff and 0x0200. Uniform units simplify placement and page replacement, at the cost of page table storage and unused bytes within partly filled memory pages. For example, placing 300 bytes in exclusive 256-byte page frames requires two page frames, leaving bytes unused. Past exam of the mathematics course of the University of Cambridge 2006 ia Paper 5 7 a ii Solution Created 2026-09-24 Updated 2026-10-14
Emulate reference observations using page table protection and page faults. When resetting a page's reference state, temporarily revoke access to its resident mapping and invalidate any corresponding translation lookaside buffer entry. The first subsequent access traps. The handler recognizes an intentionally protected resident page, sets a software reference flag and restores the mapping without performing a disk read. A later CLOCK page replacement scan can use and clear this software flag.
One protection fault records the first access after each reset, rather than trapping on every access. All mappings that can access the frame must be considered. The method requires ordinary memory-protection traps, even though hardware reference bits are absent, and adds a fault cost that native reference flags avoid.
Past exam of the mathematics course of the University of Cambridge 2007 ia Paper 5 7 a Solution Created 2026-09-24 Updated 2026-10-14
A 4096-byte page has a 12-bit offset. Each 1024-entry page table needs a 10-bit index, so partition the virtual address asThe current process's page-table root points to the first-level directory. The processor first looks for a cached translation of the virtual page in the translation lookaside buffer. On a hit it checks the cached access permissions and combines the physical frame base with the unchanged byte offset.
On a miss, use bits 31--22 to select a directory entry. Its frame address identifies the relevant second-level page table. Bits 21--12 select the entry giving the data page's physical frame and permissions. With four-byte entries in the usual layout, the entry addresses are directory-base plus four times the first index, and second-level-table-base plus four times the second index. After validity and permission checks, formPopulate the translation cache so subsequent accesses avoid the two table reads. A missing or disallowed entry causes a page fault. The operating system can supply a valid absent page, update the mapping and restart the instruction, or reject a prohibited access. Table entries and processor state are protected from ordinary user modification. The address-space identifier or root-context rules prevent a cached translation from a different process being used accidentally.
Past exam of the mathematics course of the University of Cambridge 2007 ia Paper 5 7 b Solution Created 2026-09-24 Updated 2026-10-14
A page table entry normally supplies validity and access controls. A present/valid bit distinguishes a usable resident translation from an absent or unmapped page; an absent entry forces a page fault. A user/supervisor control restricts access to privileged execution or permits user access. Read/write control permits writing or enforces read-only access, protecting code, constants or shared mappings; an attempted forbidden write faults.
Where the architecture supports it, execute permission or a non-executable bit separates instruction fetch from data reads, so writable data need not be executable. Some processors offer separate read, write and execute controls; in the classic 32-bit non-PAE x86 layout matching the stated two-level geometry, there is no independent page execute-disable bit, and a read-only page can still be read and executed. Permissions of every level involved in the page walk must permit the access; the leaf entry cannot override an upper-level restriction.
Accessed/reference and dirty/modified bits are also expected, but they are management information rather than permission bits. They record use and writes for replacement and writeback decisions. Cache-control bits similarly govern memory behavior rather than access authorization. Validity, privilege and write permission are fundamental; execute permission is architecture-dependent.
Past exam of the mathematics course of the University of Cambridge 2007 ia Paper 5 7 c Solution Created 2026-09-24 Updated 2026-10-14
Paging divides a virtual address space into fixed-size pages mapped independently to fixed-size physical frames. It avoids external fragmentation of physical memory, although the last page of an allocation can contain unused space. Pages are principally allocation units and need not coincide with meaningful program objects.
Memory segmentation instead presents logical variable-sized regions such as code, a stack or a data object. An address contains a segment identifier and an offset; a segment descriptor gives a base, limit and permissions. The offset is checked against the limit. Pure contiguous physical segmentation can suffer external fragmentation and may need relocation or compaction, but its object-level boundaries aid protection and sharing.
Combine the two by mapping a segment offset to a linear virtual address and then using paging for physical allocation, or by having each segment descriptor refer to its own page table. Cache descriptors and translations so ordinary references do not repeatedly traverse all tables. Segment pages may occupy noncontiguous frames, while bounds and rights remain defined at segment granularity. Segmentation supplies logical objects and bounds; paging supplies efficient noncontiguous physical storage.
Past exam of the mathematics course of the University of Cambridge 2007 ia Paper 5 7 d Solution Created 2026-09-24 Updated 2026-10-14
Reserve a large sparse region of the 64-bit virtual memory space for each open file, returning its base address or a segment handle. Access byte through the address base plus . Choose nonoverlapping page-aligned reservations, retain a file-identifier/offset/length mapping descriptor and apply file access rights as memory permissions. A conceptual division into high-order file-slot bits and low-order offset bits is possible, but the split is a design choice and must leave adequate maximum file size and slot count.
Use sparse multilevel page tables: reserving an address interval must not allocate physical storage or a dense table for every possible byte. A first access produces a page fault, locates the corresponding file page in the filesystem/page cache, reads it if absent, installs a mapping and restarts the instruction. Several processes mapping the same file page can share the same physical frame, maintaining one coherent cached copy. Read-only mappings forbid stores; writable mappings mark dirty pages for eventual writeback, with an explicit synchronization operation when durability is required.
Opening and mapping records the virtual reservation; closing or unmapping removes it and performs required writeback. Extension may enlarge the mapping and file according to the API, while access beyond the logical end or after truncation must be checked and reported rather than silently exposing another object. The spare bytes of the last page need an explicit convention, since page-granularity hardware alone cannot enforce every byte-level file limit. Sharing, concurrent edits and stale handles require suitable locking, mapping invalidation and lifecycle rules. Demand-paged memory-mapped files realize the Multics view without reading entire files or allocating their whole address reservations in RAM. A nominal 64-bit address type does not guarantee that every hardware implementation exposes all addresses, so reservations use the supported range.
Sv39 page table 2026-10-14
The actual Sv39 page table geometry uses three nine-bit indices and a twelve-bit offset for base 4096-byte memory pages. Each table contains 512 eight-byte page table entries, exactly one 4096-byte memory page; the
satp processor register identifies the root. A 64-bit virtual address must repeat bit 38 in bits 63 through 39. Higher-level terminal entries can also map aligned larger memory pages, shortening the page table walk. These rules differ from the 16-bit, four-byte-entry two-level address translation model. [ref]For ordinary Sv39 page tables, valid nonterminal page table entries reference the next table with read, write, and execute flags clear; those clear flags do not prohibit reading the eventual data. The terminal entry supplies access permissions, with additional processor privilege level and status checks. An invalid entry, malformed encoding, or denied access can cause a page fault. Thus the model's set intersection of read/write permissions at both levels must not be applied mechanically to Sv39 page tables. [ref]
In xv6 RISC-V source code, root allocation is separate from lower-level allocation:
uvmcreate() allocates and clears a root page table, while walk() with allocation enabled allocates and clears missing lower-level tables and installs valid references to them. With allocation disabled, a missing table makes walk() return failure. This software routine finds a page table entry for the operating system; it is not the hardware's complete permission-checking page table walk. [ref] Two-level address translation 2026-10-14
Choose an original teaching model with 16-bit virtual addresses, 16-bit physical addresses, and 256-byte memory pages and page frames. The eight high bits identify a virtual memory page; divide these into two four-bit indices. The eight low bits are the offset within the memory page. Thus each page table has 16 entries: the root selects a lower-level page table, and that table selects a data page frame. Every page table entry is four bytes, including its reference and flags. These are chosen model parameters, not a hardware entry encoding.
For a virtual address , extract the root index , lower-level index , and offset by Euclidean division:Here is the floor function and denotes the remainder in Euclidean division. Each index ranges from 0 to 15, and ranges from 0 to 255. In hexadecimal, virtual address
0x1234 splits into , , and ; its binary numeral system representation is 0001 | 0010 | 00110100.Fix the requested operation to be a one-byte user read. Assume both table nodes and the data page frame are resident, table reads are allowed, and no mapping changes during the page table walk. The model requires presence at both levels and takes the set intersection of the two entries' read, write, execute, and user-access permissions. This is an explicit memory protection rule for this model; Sv39 page tables use different rules. The root's physical address is
0x8000; the relevant entries are:| Record | Physical address of record | Reference held in the page table entry | Presence and permissions |
|---|---|---|---|
| Root entry 1 | 0x8000 + 1*4 = 0x8004 | Lower-level table at 0x9000 | Present; user; read/write; no execute |
| Lower-level entry 2 | 0x9000 + 2*4 = 0x9008 | Data page frame 0x07, base 0x0700 | Present; user; read-only; no execute |
The first lookup obtains a table reference, not the final data physical address. The second lookup obtains page frame number 7. Both entries permit a user read, so the original offset is added to the data page frame base:The page table walk therefore reads records at
0x8004 and 0x9008, then the requested read accesses data at 0x0734. All three are distinct physical addresses. These are two dependent table lookups followed by one data access, not a claim of three accesses to main computer memory: a memory cache can satisfy table lookups, and cached intermediate translations can skip them.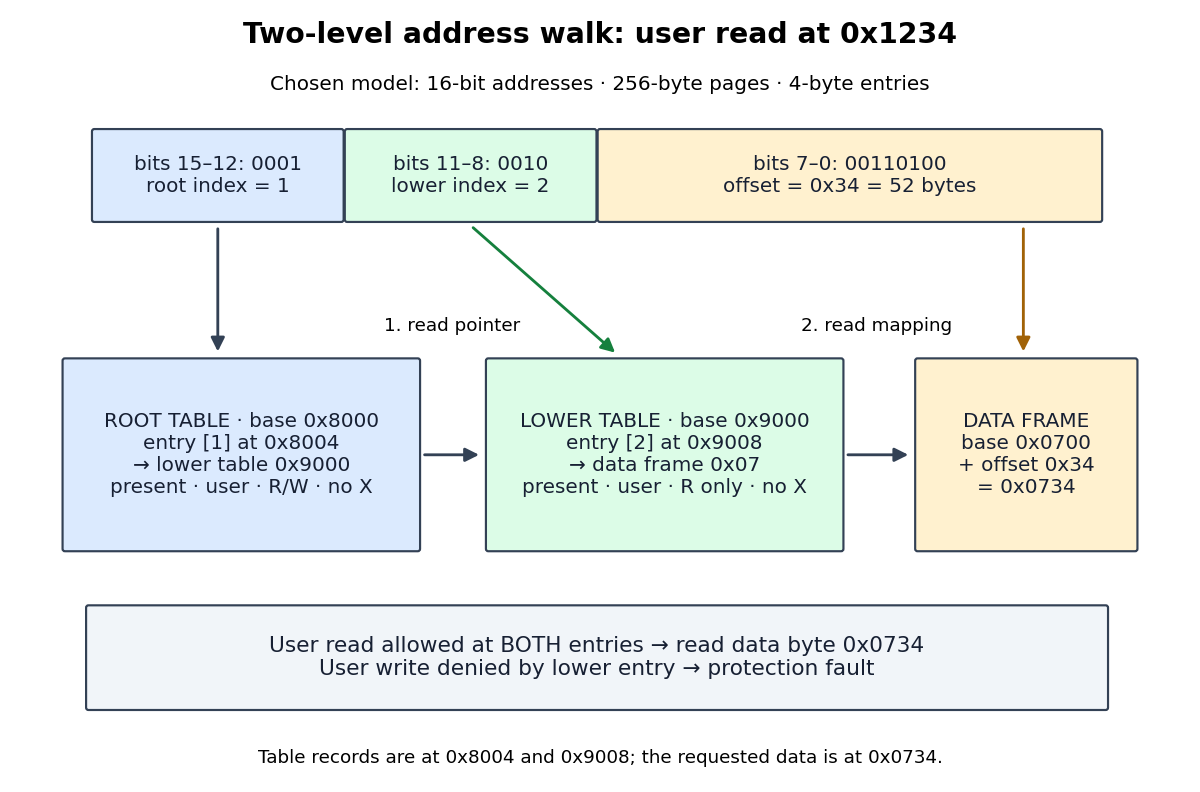


Under the same memory protection rule, a user write at
0x1234 fails because lower-level entry 2 denies writes, even though root entry 1 allows them. Clearing either entry's presence flag also prevents the access. An absent root entry stops the page table walk before any lower-level lookup. A page fault then requires the operating system to determine whether a permitted mapping needs storage or the access is invalid; absence alone does not establish demand paging eligibility.With an empty translation lookaside buffer, the permitted read causes a TLB miss and this successful page table walk, with no page fault. If the resulting mapping and permissions are cached for the current address space, a later read at
0x1235 can use a TLB hit to reach 0x0735. A later write can cause a protection page fault on a TLB hit because the cached mapping remains read-only. Assume cached permissions are current; changing them requires the architecture's prescribed invalidation. A TLB miss describes a missing cached translation, while a page fault describes an access that cannot proceed under the translation or protection rules. [ref]Page Tables by The kernel development community. MMU, TLB, and Page Faults: translation caches, page walks, and faults for missing or forbidden mappings