For a finite joint distribution, the mutual information isZero-probability terms contribute zero. It measures the reduction in uncertainty about one variable upon observing the other.
A discrete memoryless channel has discrete input/output alphabets and a fixed transition matrix . Over successive uses it obeysThus the output at a use depends on that input and no other channel history. Its channel capacity isin bits per use for base-two logarithms. On finite alphabets the maximum exists by continuity on the probability simplex; for more general discrete alphabets one uses a supremum.
Fix the channel matrix . The mixed input induces the mixed output . The concavity of information entropy impliesFor completeness, the difference is by Gibbs inequality, including zero coordinates with the usual conventions.
On the other hand, conditional output entropy is linear in the input law:Subtracting gives the concavity of mutual information in the input distribution:This makes maximizing mutual information over the input probability simplex a concave optimization problem: a local maximum is global. It also justifies averaging input distributions over channel symmetries when searching for an optimum, since symmetry averaging cannot lower the achieved mutual information. The channel itself is held fixed throughout.
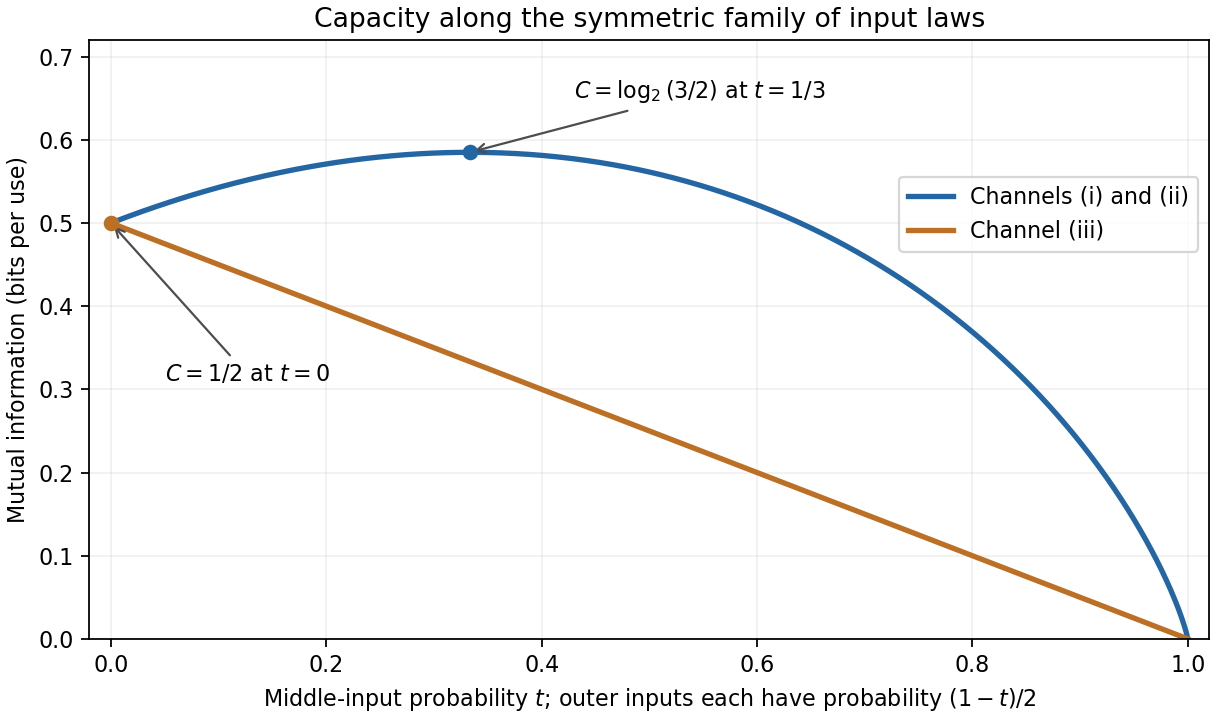
Let the input probabilities be and put . The output distribution and conditional entropy areFor fixed , the first and third output masses sum to . Their entropy is maximized when they are equal, so . Equivalently, if ,The same bound holds at by continuity. Therefore , with equality for symmetric outer input probabilities. Writing , differentiate:The unique zero is ; strict concavity makes it the global maximum. Thus andThe optimum output is .
Every row has Shannon entropy , so for every input law. Since the output alphabet has three symbols, Gibbs inequality gives . The uniform input givesso it attains the upper bound. ThereforeUniform output is necessary for equality in the entropy bound, and the three displayed equations then force the uniform input, so this optimum input law is unique.
Let the input law again be . The second output symbol has probability regardless of the input, and the two remaining output probabilities sum to . Hencewith equality when the first and third output symbols each have probability . The row entropies are , soTake and . The output is and both bounds are attained. ThereforeThe equality conditions also show uniqueness of the optimum input law. The middle row is the average of the outer rows and carries extra conditional entropy without introducing a new output law; removing a redundant input symbol from a channel explains why it need not be used.

Articles by others on the same topic
There are currently no matching articles.