Channel capacity is the best reliable information rate available through a specified communication channel. For a discrete memoryless channel with finite input and output alphabets, fixed transition probabilities , and no input-cost constraint, it isin bits per channel use, when the mutual information uses base-two logarithms. The maximization varies the input probability distribution, while keeping the communication channel fixed. A large input alphabet or a large output information entropy alone does not determine how much information gets through: the receiver needs information about the input, rather than merely unpredictable output.
The operational meaning comes from the Shannon second coding theorem. A block code represents one of possible messages by a word of length , giving a rate bits per use. Take the message label from the uniform distribution on a finite set of those choices when measuring average decoding-error probability. For every fixed rate , there are sequences of such block codes whose decoding-error probability tends to zero as grows; a rate above cannot have vanishing decoding-error probability. This is an asymptotic limit, rather than a promise that an arbitrary finite block code at a rate below works well. See MIT 18.310, Shannon's Noisy Coding Theorem, sections 1–2.
For a binary symmetric channel with crossover probability , the binary symmetric channel capacity is approximately bits per use. Thus a binary code rate lies below the limit, while lies above it. At , two transmitted symbols represent one message bit on average; the redundancy helps distinguish messages after noise. This does not split individual physical symbols into fractional pieces.
The result is useful because it separates two tasks. Computing channel capacity establishes the target imposed by the transition probabilities; constructing an effective block code attempts to approach that target with acceptable delay and decoding effort. The surprise is that reliability can improve indefinitely without forcing every positive rate to disappear. In his 1948 paper, Shannon defines noisy channel capacity in section 12 and develops its operational significance in section 13, Theorem 11. His original formulation uses information per unit time; the fixed-duration channel-use convention here expresses the same rate question per symbol. [ref].
Pass the output of a discrete memoryless channel of channel capacity through an independent finite-alphabet erasure channel with erasure probability . Its capacity becomes .
To prove it, let be the original input, the original output, the erasure indicator, and the final output. Since the erasure marker is distinguishable, is determined by . It is independent of , so the chain rule for mutual information gives . Maximization over the same input distributions proves the formula. For the maximizing distributions are exactly the original channel's maximizers. For , every input distribution attains the zero capacity. Input-dependent erasure need not satisfy this scaling identity.
Suppose one row of a finite discrete memoryless channel is a convex combination of other rows: . Deleting input leaves the channel capacity unchanged. Given any input law with mass on , move that mass to the other symbols in proportions . The output law stays the same. By the concavity of information entropy, , so this replacement cannot increase conditional entropy and cannot decrease mutual information. Taking maxima proves the claim; the smaller channel is also trivially a restriction of the original one. If the entropy inequality is strict, every positive use of the redundant row is strictly suboptimal compared with its redistribution.
Combine finitely many discrete memoryless channels with disjoint input alphabets and disjoint output alphabets into a block-diagonal channel. The block label is determined by both input and output. If it has law , the mutual information is at most , attained by using each block's capacity-achieving conditional input law. Put and . The expression equals , so Gibbs inequality proves the displayed capacity, attained for block probabilities . Even blocks of capacity zero contribute distinguishable block choices; three disjoint zero-capacity blocks give capacity .
For a finite discrete memoryless channel and a deterministic output map , the data processing inequality gives . Equality holds exactly when an original capacity-achieving input law satisfies . Sufficiency follows from the gap identity . For necessity, take an input law maximizing . If this maximum is , both inequalities are equalities at that law. Injectivity of on reachable outputs is a sufficient condition, since then determines ; it is unnecessary if the discarded distinctions convey no further information about at some maximizing input law.
For a discrete memoryless channel with output symbols, suppose every row of the transition matrix is a permutation of every other row and all column sums agree. Such a communication channel hasThe row Shannon entropy is the same for every input, so has that fixed value for every input probability distribution. The remaining term is at most by maximum entropy on a finite alphabet.
A uniform input attains the bound. If there are input symbols, the total of all transition probabilities in the matrix is ; equal column sums must therefore each be . Multiplication by the uniform input mass gives output mass in each column. Hence , which proves the displayed formula. The cyclic ternary channel capacity, binary symmetric channel capacity, and ternary symmetric channel capacity are concrete applications of this symmetry calculation.
A discrete memoryless channel on the additive group maps to with probability and to with probability . Every input gives the same conditional entropy , whereas the output Shannon entropy is at most . A uniform input produces a uniform output since every column of the transition matrix sums to one. Hence the channel capacity is bits per use. This cyclic-error channel differs from a channel distributing its error probability equally over both other output symbols.
A binary symmetric channel independently flips each transmitted bit with crossover probability . Its channel capacity isin bits per use, where is binary entropy and the endpoint convention is . Knowing the input leaves just the uncertainty of the flip, so for every input probability distribution. Since the output is a bit, , and thus . A fair input produces a fair output and reaches the bound. This is the two-symbol case of weakly symmetric channel capacity; Eytan Modiano, MIT 16.36, Channel Capacity and Coding, slides 4–5 gives this calculation.
For crossover probabilities , the resulting channel capacities are approximately , , and bits per use. At , the communication channel is noiseless; at , the output is independent of the input and the capacity is zero. At , every bit is inverted, a known reversible rule, and capacity is one again. More generally , because inverting every received bit exchanges the two crossover probabilities. The existing mutual information figure shows this full symmetric curve.
An uncoded transmission illustrates why the raw bit-error probability is not itself channel capacity. At , transmitting 100 uncoded bits succeeds on all of them with probability . The probability of at least one error is therefore approximately . A suitable block code changes which received words count as recoverable evidence of a message; simply repeating uncoded transmission at rate one does not obtain the reliability promised at rates below .
Let for the input bit of a binary symmetric channel with crossover probability . The law of total probability givesConsequently its mutual information isHere specifies the noise and specifies the input bias; they are different choices. At and , the output has , giving and bits. With the same noise and the fair input , the output becomes fair and bits, attaining binary symmetric channel capacity.
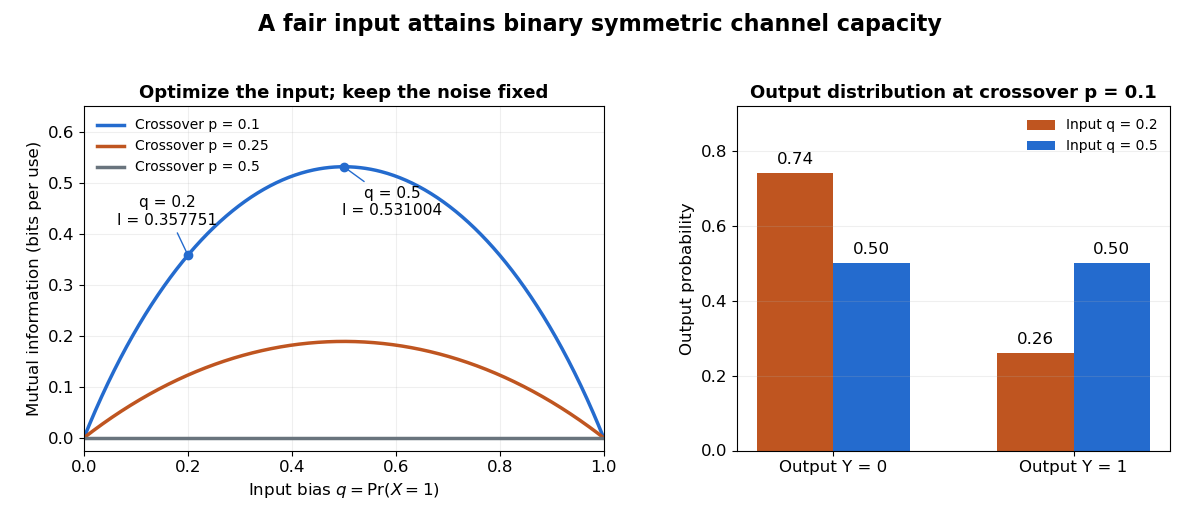
For , binary entropy reaches one only at output mass , and the equation forces . Thus the maximizing input is unique in those cases. For , every input produces the same fair output and zero mutual information, so every input bias is optimal and none transmits information. A fixed input or also carries zero mutual information for every : noise can make its output unpredictable without creating an unknown message to recover.
A binary erasure channel marks its failed transmissions with a special output symbol, whereas a binary symmetric channel changes a bit without announcing whether it changed. At the same nominal failure probability , the two communication channels therefore leave different uncertainty. With a fair input, an unerased output determines the input exactly, while the erasure flag leaves one bit of conditional entropy. Thus and for the binary erasure channel. This is the binary case of capacity of a finite-alphabet erasure channel.
For the binary symmetric channel at , neither possible received symbol rules out either input, and . Its channel capacity is only . A receiver benefits from knowing where information was lost, even when the fraction of affected transmissions is the same.
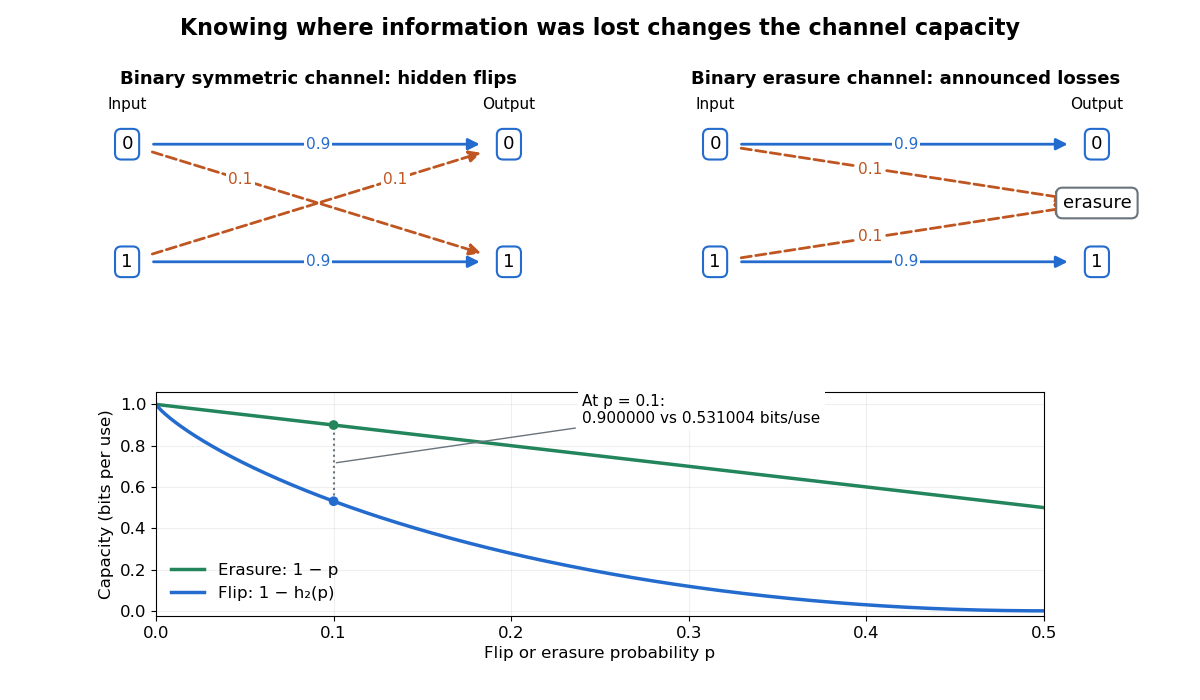
This comparison concerns the specified transition probabilities, rather than a general ordering of every error mechanism. In particular, at , an erasure flag conveys no input information, while deterministic inversion still conveys a full bit. Reporting only an error percentage loses the distinction between hidden corruption, announced loss, and a predictable reversible transformation.
Articles by others on the same topic



Channel capacity is a fundamental concept in information theory that represents the maximum rate at which information can be reliably transmitted over a communication channel. More specifically, it refers to the highest data rate (measured in bits per second, bps) that can be achieved without significant errors as the length of transmission approaches infinity. The concept was introduced by Claude Shannon in his seminal 1948 paper "A Mathematical Theory of Communication.