Solutions to the paper dated 4 June 2015. The original cover gives a ninety-minute examination with a choice of two questions; all three questions are solved here.[ref]
Use an abstract syntax tree with the following constructors. Here
Expr denotes the separate abstract syntax tree type for a program expression, Name identifies a variable assignment target, and the square brackets denote an ordered list.Stmt = Assign(Name, Expr)
| Seq(Stmt, Stmt)
| Case(Expr, [(Expr, Stmt)])The list in
Case must be nonempty. Its first field is the controlling program expression; each pair contains a label program expression and the corresponding body. Keep the pairs in source order and keep repeated labels: this is an ordered search, with the first successful equality test choosing the body. A label is an abstract syntax tree for a program expression, not a previously evaluated integer or a key in a map data structure. Evaluating or reordering labels during compilation would change the specified programming language semantics.Seq(s,t) executes s before t. The delimiters begin and end need no surviving constructor: the parser uses them to determine the abstract syntax tree's grouping and then returns the enclosed tree. There are no declarations in these blocks that would require a separate binding environment. A list of statements could replace binary Seq; below we choose right-associated binary trees so that the semantic actions are precise.The essential representation is an ordered, nonempty list of expression/body pairs, together with assignment and sequencing nodes. In constructor notation,
Take the lexical tokens
ID, ASSIGN, SEMI, BEGIN, END, CASE, OF, COLON, and BAR, corresponding to identifiers and the displayed punctuation or keywords. Let E be the already defined context-free grammar category for a program expression, with attribute E.tree; expressions do not consume statement delimiters except inside their own explicitly delimited constructs. ID.name is the recognized program identifier. The following context-free grammar uses S for a statement, C for a closed elementary statement, D for a nonempty sequence of closed statements, and A for a nonempty arm list. The braces in this display are semantic actions, not input lexical tokens.S -> C { S.tree = C.tree }
S -> C SEMI S1 { S.tree = Seq(C.tree, S1.tree) }
S -> CASE E OF A { S.tree = Case(E.tree, A.arms) }
C -> ID ASSIGN E { C.tree = Assign(ID.name, E.tree) }
C -> BEGIN S END { C.tree = S.tree }
D -> C { D.tree = C.tree }
D -> C SEMI D1 { D.tree = Seq(C.tree, D1.tree) }
A -> E COLON S { A.arms = [(E.tree, S.tree)] }
A -> E COLON D BAR A1 { A.arms = [(E.tree, D.tree)] ++ A1.arms }Here
++ is list concatenation, and distinct suffixes distinguish occurrences of the same nonterminal symbol. Every statement and arm body is nonempty; no empty statement or optional trailing semicolon is needed for the supplied language.The distinction between
D and S resolves both possible sources of grammar ambiguity. First, an unbracketed CASE can occur only at the right end of an S: there is no production S -> S SEMI S. Consequently all semicolon-separated statements after such a CASE enter its last arm. Enclosing that whole CASE in BEGIN ... END turns it into a C, which can be followed by another statement outside the CASE.Second, an arm followed by another arm at the same level must have a
D body. Such a body contains no unbracketed CASE. If an arm body does contain an unbracketed CASE, only the final-arm production A -> E COLON S can apply, and every following BAR before the enclosing END or end of input must be consumed by the inner CASE. Thus each bar belongs to the nearest preceding CASE whose block has not ended. A CASE inside BEGIN ... END is hidden from that rule outside its block.For uniqueness, at any statement level an initial
ID or BEGIN determines a C; an immediately following SEMI determines the recursive sequence production. An initial CASE determines the third S production. In an arm, a bar at the current block level either follows an entirely closed body, forcing the second A production, or follows an unbracketed nested CASE, forcing it into that inner arm list. With an unambiguous expression sublanguage these choices leave a unique parse tree. Closed bodies before an outer bar, and a possibly open body only in the final arm, enforce the required interpretation. Thus the context-free grammar implementsLet
expr(e) generate postfix code that evaluates a program expression once, leaving one value above an otherwise unchanged evaluation stack. Let stmt(s) preserve the evaluation stack's height. Use EQ to pop two integers and push their Boolean equality result; JZ L pops that result and jumps to L when it is false. JMP is unconditional. All labels returned by fresh() are distinct, including labels inside recursively generated bodies.generateCase(Case(control, arms)):
done := fresh()
emit expr(control)
for (labelExpression, body) in arms, in source order:
next := fresh()
emit DUP
emit expr(labelExpression)
emit EQ
emit JZ next
emit POP
emit stmt(body)
emit JMP done
emit LABEL next
emit POP
emit LABEL doneTo verify the stack invariant, write the incoming evaluation stack as . Immediately before any label test it is , where is the controlling value.
DUP, evaluation of the label with value , and EQ change this to . JZ removes the Boolean. On failure the surviving is available for the next label; on success POP removes it before the body runs. The body therefore starts and ends with and jumps past every remaining label. If every label fails, the final POP restores .The controlling expression is evaluated once, each reached label is evaluated once, and no later label or arm is evaluated after a match. Keeping on the evaluation stack also preserves its original value if a label evaluation has a side effect that changes a variable appearing in the controlling program expression. A nested
Case uses the same stack invariant relative to whatever stack it receives. The concise contract isThe surviving call stack, from oldest to newest, is
main, p, r, s, q. A dynamic link identifies the caller's stack frame, whereas a static link identifies the current activation of the lexically enclosing procedure. These need not identify the same stack frame.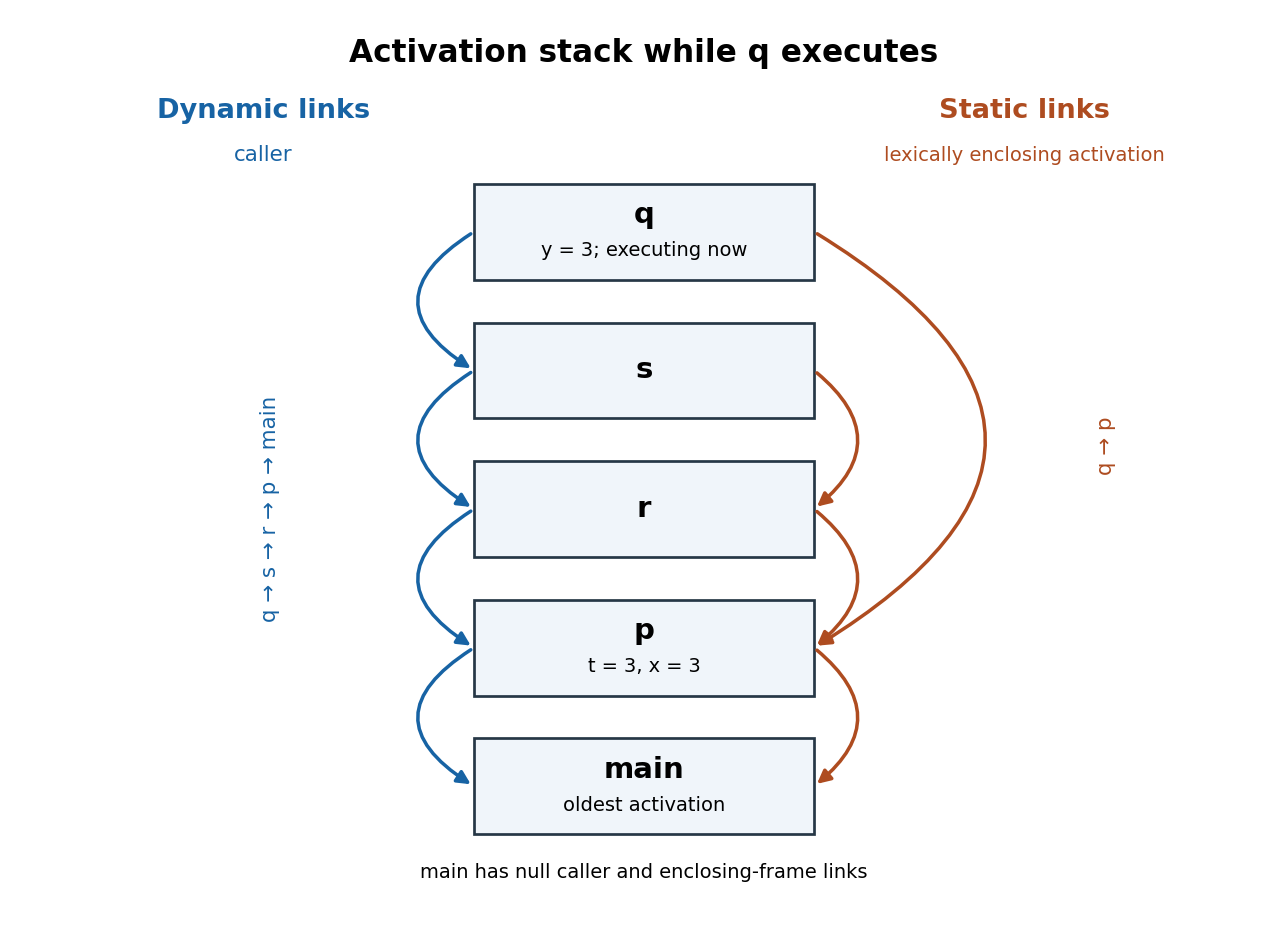
The call stack during
. Details. q, with dynamic links on the left and static links on the right; arrows point to older stack frames
The dynamic chain isThe individual static links are
main has no enclosing procedure; its links can be null. The p stack frame contains t=3 and x=3, and the q stack frame contains y=3. Return addresses are code addresses, not links to another stack frame. In particular, q returns dynamically to s while obtaining x statically from p.We specify a small stack machine instruction convention because the paper does not prescribe instruction spellings or numeric stack frame offsets.
PUSHFP pushes the current frame pointer. LOAD k replaces a stack-top frame address by the value at fixed offset k in that frame. Let SL be the static link offset, X the offset of p's x, and Y the offset of q's parameter y. ADD pops two integers and pushes their sum. RETVAL returns the stack-top value, removes the current activation and restores the caller through the usual calling convention.PUSHFP ; address of q's frame
LOAD SL ; q's static link: address of p's frame
LOAD X ; value of p.x
PUSHFP ; address of q's frame, above x
LOAD Y ; q's local parameter y
ADD ; x + y
RETVAL ; return the sum to sOne static link traversal suffices for
x, despite three intervening calls in the dynamic chain. y is local to q. In this execution the two loads produce and , so the returned integer is .Continue the instruction convention above. The current stack frame is now
s's. Its static chain passes through r to p; q is declared directly inside p, so the new q activation must receive a static link to that same p stack frame. Let T be the offset of p's parameter t.Define
CALL q,1 to expect, above the pre-existing evaluation stack, the static link for q followed by its one argument. It consumes these, creates q's stack frame with its dynamic link pointing to the current s activation, and leaves one return value when q returns. This explicit convention avoids dependence on a particular real instruction set architecture.PUSHFP ; s
LOAD SL ; r
LOAD SL ; p, the required static parent of q
DUP ; preserve p for CALL while also using it to read t
LOAD T ; replace the duplicate p address by p.t
CALL q,1 ; q(p.t), with static parent p and dynamic caller s
RETVAL ; return q's result from s to rImmediately before
CALL, the evaluation stack ends in p-frame, 3. Two static link traversals find both the argument's environment and the environment to pass to q. In terms of the hidden argument and ordinary argument, An implementation that places the hidden static link after the ordinary argument could use a different ordering of these same operations.Use mathematical induction on the sequence of call and return events. The invariant concerns the static chain of the currently executing activation: every stack frame on that chain is the most recent surviving activation of the procedure it represents. It need not hold for the saved chain of an arbitrary suspended caller while a recursive callee is running.
Initially only
main is active, so the claim holds. Suppose it holds just before a direct call to a procedure , whose lexical parent is . Without procedural parameters, visibility of means that its declaration lies in the current procedure or in a lexically enclosing procedure. Therefore the activation of needed for the call is on the caller's static chain. By the induction hypothesis, it is the newest surviving activation of .Create a new activation of whose static link points to this activation. The inherited chain is a suffix of the caller's chain, so its stack frames still represent the newest surviving activations of their procedures. Adding does not make any of those inherited activations out of date: cannot be its own lexical ancestor. The new activation itself is plainly the newest activation of . This covers recursive calls too: an older activation of may survive on the dynamic chain, but is absent from the new activation's static chain.
On return, the callee and every call it made have finished. The caller's saved stack frame and static chain are restored. Any temporarily newer activation of a procedure represented on that chain has returned, so each restored activation is again the most recent surviving one. Thus return preserves the invariant as well.
The claim holds for the executing procedure's static chain throughout every execution using direct calls under lexical scope. Equivalently, writing for the procedure represented by a stack frame ,
Searching the dynamic chain would require identifying the procedure associated with each visited stack frame. More seriously, the search length is bounded by the number of active calls, not by lexical nesting depth. Recursion in procedures unrelated to the desired enclosing declaration can make arbitrarily large. Thus a single nonlocal variable access can take time complexity, whereas a conventional static chain access needs only traversals for lexical distance .
Instead give each procedure a known global pointer cell
current[P]. On entry to , save its previous value in the new stack frame and set current[P] to the new frame pointer. On return, restore the saved value. A nonlocal variable declared in is then loaded using current[P] and its known frame offset. The proof in part (d) justifies that lookup in the absence of procedural parameters. This is a procedure-indexed version of a display for lexical scope; a conventional display for lexical scope can instead use lexical levels as indices.With procedures and active calls, the procedure-indexed table needs additional global words and one saved previous pointer per active stack frame, hence activation storage. The saved word can replace the conventional per-frame static link if that link is no longer needed. A conventional static chain has one pointer per active stack frame and no such -entry table. Both schemes retain ordinary dynamic links and return information.
The table gives constant-time nonlocal access and constant-time save/restore work on each entry/return, independently of lexical distance. Conventional static chain access costs per access, and establishing the callee's static link may also require following an appropriate portion of the caller's chain. For a fixed program is statically bounded, but it still affects generated instruction counts. These costs assume constant-cost pointer operations and omit shared ordinary call overhead. For the procedure-indexed table,
No: a procedural parameter can carry an older lexical environment past a newer recursive activation. Here is typed, Pascal-like pseudocode; a function-valued parameter is represented by a programming closure, comprising code and its defining environment.
procedure dummy(): integer;
begin return 0 end;

procedure P(n: integer; f: procedure(): integer): integer;
    var x: integer;
    procedure Q(): integer;
    begin return x end;
begin
    x := n;
    if n = 1 then return P(2, Q)
             else return f()
end;

begin print P(1, dummy) end.
Call the first
P activation . It sets its own x to and passes the programming closure into a recursive activation . That activation sets its own x to and calls its parameter f. The resulting activation of Q has its static link pointing to , because that is where the passed procedure was defined. Its dynamic link points to , because that is where it was called.During this call the dynamic chain contains
Q, P2, P1, main, while Q's static chain contains Q, P1, main. The newest surviving activation of P is , but the static chain deliberately uses . Correct lexical scope therefore prints ; blindly consulting current[P] would produce . Both enclosing activations remain alive, so no issue of a returned procedure or dangling pointer is involved.The failed step in part (d) is precisely the assumption that the callee's lexical environment is a suffix of the direct caller's static chain. A passed programming closure can specify a different, still surviving environment. An implementation supporting such calls must preserve that environment; a table implementation requires additional environment installation and restoration rather than merely consulting newest activations.
Use the following explicit tree notation for the intermediate representation.
C(k) is a constant, R(r) a processor register, M(e) a word load from memory address e, ADD addition, and SHL(e,2) a left shift by two bits. MOVE(destination,source) assigns either a processor register or the computer memory word designated by M. Parentheses show complete tree structure, so these displays specify trees rather than already shared Directed acyclic graphs.Let be the constant base memory address of the global array
a, and the constant offset of local i from the frame pointer fp. Each integer occupies four bytes, and array indices are zero-based; a fixed nonzero lower bound can instead be absorbed into . Local t is represented by R(t). After replacing multiplication by four with a left shift, the three trees are:MOVE(R(t),
M(ADD(C(A),
SHL(M(ADD(C(A),
SHL(M(ADD(R(fp),C(I))),2))),2))))
MOVE(M(ADD(C(A),
SHL(M(ADD(C(A),
SHL(M(ADD(R(fp),C(I))),2))),2))),
M(ADD(C(A),SHL(M(ADD(R(fp),C(I))),2))))
MOVE(M(ADD(C(A),SHL(M(ADD(R(fp),C(I))),2))),
R(t))Every
M(ADD(R(fp),C(I))) loads i; the next enclosing M loads a[i]; the outermost M in the first tree loads a[a[i]]. Each array index is converted to a byte offset by a left shift of two bits. The address rule used in all three trees is The source language's array bounds checks are omitted as requested.The useful repeated program expressions, nested inside one another, are the memory address of
a[i], its value, and the memory address of a[a[i]]. Materialize each maximal reusable tree at the level at which it is shared, using fresh temporary variables u, v, and w:MOVE(R(u), ADD(C(A),SHL(M(ADD(R(fp),C(I))),2)))
MOVE(R(v), M(R(u)))
MOVE(R(w), ADD(C(A),SHL(R(v),2)))
MOVE(R(t), M(R(w)))
MOVE(M(R(w)), R(v))
MOVE(M(R(u)), R(t))Thus
u is a saved memory address, v the old integer value of a[i], w the second saved memory address, and t the old value at that second location. The two large address trees occur both in loads and as store destinations. After extracting them, the repeated load of a[i] inside the second address and as the middle assignment's source becomes v. Extracting every smaller nested tree again would add no benefit.The relevant alias analysis facts are that local
i does not occupy any location written through global a, that frame pointer fp and base stay fixed, and that t,u,v,w are distinct processor registers or otherwise nonoverlapping temporary variables. There are no intervening calls, volatile memory accesses, or concurrent changes. Under these assumptions, loading i once remains valid even across the array stores. Before the middle store, no array location has yet changed, so both its target memory address and its source value can be computed and saved earlier.No assumption that the two array locations are distinct is required. The middle store may change
a[i] when its target coincides with it, but v is not loaded again afterwards: only the saved address u is needed for the final store. It would be unsound to retain an arbitrary array load across an aliasing store and then treat it as the new contents; that is not what these trees do.For a language with a true global array, a distinct local variable, and no arbitrary means of fabricating pointers to unrelated storage, these facts follow simply from declarations and the stack frame layout. Accesses must denote valid array elements. In an unrestricted low-level language with overlapping storage, arbitrary pointer arithmetic or unchecked out-of-range accesses, that conclusion requires extra guarantees. Omitting emitted array bounds checks does not itself prove that all memory addresses are valid. If denotes a word load, the saved quantities are
Here is a literal instruction selection for the trees in part (b), with the temporary variables allocated to processor registers.
MOV r,#k loads an arbitrary constant in one instruction. LD and ST load and store one four-byte word; [r] denotes zero-offset access. LSL is a left shift. We use conventional base-plus-immediate access for the fixed local offset I.MOV rb, #A
LD ri, [fp + I]
LSL ru, ri, #2
ADD ru, rb, ru
LD rv, [ru]
LSL rw, rv, #2
ADD rw, rb, rw
LD rt, [rw]
ST rv, [rw]
ST rt, [ru]The first four instructions construct
u, the fifth obtains v, the next two construct w, and the last three perform the remaining load and the two stores. Each destructive update of ru or rw reuses a processor register whose previous value is no longer needed. We assume enough processor registers to avoid a register spill.If the target offers only the explicitly mentioned two-register register-offset addressing and lacks base-plus-immediate access, replace the one local load by
MOV rk,#I; LD ri,[fp+rk]; all other conclusions are unchanged. A zero processor register or a zero-offset load supplies the notation [ru] and [rw] as usual. This direct translation takes ten instructions with immediate local addressing, or eleven with the stated replacement. Thus These are instruction counts for the specified abstract target, not measured execution times.The target's register-offset addressing already performs the addition of the array base and a scaled index as part of each load or store. Materializing a maximal common address expression into a processor register introduces an explicit
ADD that this addressing mode could have supplied. Here the extra address temporary variables save no arithmetic that the memory instructions need to perform separately.Instead keep the scaled indices, share the loaded old value of
a[i], and fold the base addition into each memory operand:MOV rb, #A
LD ri, [fp + I]
LSL rj, ri, #2
LD rv, [rb + rj]
LSL rk, rv, #2
LD rt, [rb + rk]
ST rv, [rb + rk]
ST rt, [rb + rj]rj remains the original index's byte offset, rv is its old element, and rk remains the second element's byte offset. Both stores use those saved offsets. Folding address additions into the memory instructions removes two instructions, reducing ten to eight, or eleven to nine if the local load requires the alternative sequence described in part (c). ThereforeThis illustrates why common subexpression elimination must interact with instruction selection: a larger repeated tree is not automatically a better value to materialize. A useful refinement retains common scaled-index trees, or propagates the address addition trees back into their memory uses. The calculation establishes an instruction-count improvement under the stated instruction set architecture; scheduling and actual timing depend on further machine details.
The source rewrite already saves the old
a[i] in register-allocated t. Denote the original integer index by , its original element by , and the original element there by . The second fragment first sets t=j, then writes to a[i0], and finally writes to a[j]. Thus it performs the same intended swap without needing to recompute the second memory address from a possibly modified array element.For completeness, the first fragment is also correct when the two locations might alias. If , its middle store changes only
a[j], so the final a[i] still denotes the first location. If , then , and the supposed swap is a no-op in both fragments. There is no need to assume distinct locations.For the second fragment, common subexpression elimination of maximal addresses gives, using
z for the second address:MOVE(R(u), ADD(C(A),SHL(M(ADD(R(fp),C(I))),2)))
MOVE(R(t), M(R(u)))
MOVE(R(z), ADD(C(A),SHL(R(t),2)))
MOVE(M(R(u)), M(R(z)))
MOVE(M(R(z)), R(t))The nested memory-to-memory assignment requires an additional scratch processor register
rv on a reduced instruction set computer. A direct translation is therefore:MOV rb, #A
LD ri, [fp + I]
LSL ru, ri, #2
ADD ru, rb, ru
LD rt, [ru]
LSL rz, rt, #2
ADD rz, rb, rz
LD rv, [rz]
ST rv, [ru]
ST rt, [rz]The same compiler need not produce any better code: this has the same ten-instruction count as part (c). It still performs two element loads, two element stores, two shifts and two separately materialized address additions, plus the base and local-index setup. The processor register roles and store order differ, but the work is the same. The corresponding folding of register-offset addressing removes both
ADD instructions here too, yielding the same eight-instruction count as part (d).The key alias analysis advantage available in both fragments is that
i remains unchanged by the array stores. In the second fragment, t is also unchanged after its first assignment because it lives in a processor register. Its name alone does not produce a further saving beyond what the first fragment's common subexpression elimination already achieves. Exact instruction selection is not uniquely prescribed by the paper; these explicit translations demonstrate why the claimed source-level efficiency advantage does not follow: Articles by others on the same topic
There are currently no matching articles.