Source release: www.whatdotheyknow.com/request/admission_statistics_and_past_pa/response/2722250/attach/2/Exam%20papers.zip?cookie_passthrough=1
A null hypothesis specifies the population comparison to be tested, for example equality of the population means for women and their complement. The alternative hypothesis for a two-sided test is a nonzero difference. A Student's t-test measures an estimated difference in units of its estimated standard error:On the reported calibration, the sampling distribution under the null hypothesis is Student's t-distribution with statistical degrees of freedom. Consequently the two-sided test has p-valueWith this many statistical degrees of freedom, the Student t-distribution is close to the standard normal distribution: exceeds the approximate two-sided critical value , but falls short of the value . Using the supplied calibration, reject at the significance level, but not at . The large statistical degrees of freedom justify this comparison; a value need not be significant for an arbitrary very small number of statistical degrees of freedom.
The p-value is the probability, under the specified null hypothesis and sampling assumptions, of a test statistic at least as discrepant as the observed one. It is not the probability that the null hypothesis is true, nor the probability that the observed difference happened “by chance”. A significance level of controls the long-run type I error rate of the testing procedure when its assumptions hold. Failing to reject at does not prove equality. Statistical significance also does not measure the substantive size or importance of a difference.
The reported sample means place the women's mean scale units above the overall mean. The negative test statistic can reflect the order of subtraction; it does not reverse that observed ordering. An appropriate pre-specified directional one-sided test would have a tail p-value approximately on the supplied calibration, but one cannot choose that direction after inspecting the results simply to halve a p-value.
There is a design issue behind the numerical calculation: the women are included in the overall sample. Comparing a subgroup mean with its containing sample mean requires accounting for shared observations. If is the women's sample fraction and the mean for the remaining respondents, thenThese two estimates are not independent. An ordinary independent-two-sample Student's t-test of women against the entire respondent sample would therefore use an inappropriate standard error. The interpretation above accepts the supplied test statistic and its stated null calibration; a valid analysis of the underlying data should compare disjoint groups, or calculate the shared-sample covariance correctly. The summary alone cannot establish which calculation was used. Simple random sampling supports sampling inference under the stated design, but an observed gender association does not establish a causal effect.
Each row of the contingency table is a conditional distribution of the safety category among respondents with that experience status. Thus the relevant comparison uses row percentages, rather than interpreting the larger number of respondents with some bad experiences as itself an effect on safety.
The sample proportions reporting feeling very safe are without bad experiences and with some bad experiences: the latter is lower by about percentage points. Feeling fairly safe rises from to , a difference of about percentage points. Feeling unsafe changes only from to , about percentage points. The main descriptive shift is therefore from very safe toward fairly safe, rather than a large increase in the unsafe category.
Pearson's chi-squared test tests the null hypothesis that experience status and safety category are independent. If that were true, the expected cell count would be its row total times column total divided by . The Pearson chi-squared statistic sums squared observed-minus-expected count differences divided by their expected counts. HereThe expected counts are comfortably large, with minimum approximately , so the ordinary large-sample chi-squared distribution approximation is appropriate under the sampling assumptions. There is evidence against independence even at the significance level. The reported likelihood-ratio result gives the same conclusion.
Magnitude is a separate question. Cramér's V giveswhich describes a weak statistical association. It does not mean that of safety is explained. Nor does the p-value measure the size of that association.
For ordinal direction, order the experience categories as none, some, and the safety categories from very safe toward unsafe. Goodman and Kruskal's gamma compares concordant pairs with discordant pairs after excluding tied pairs:Its small positive sign then corresponds to a weak tendency toward less safety among respondents with bad experiences. The sign would reverse if exactly one category ordering were reversed. Because this contingency table has many ties, the response-direction Somers' D, which retains response ties among pairs with different predictor values, is smaller:These coefficients describe ordered association; the omnibus Pearson's chi-squared test tests any departure from independence and does not supply a separate p-value for gamma.
The column-dependent Goodman and Kruskal's lambda makes the weak predictive improvement tangible. Predicting the overall most frequent safety category makes errors in this table. Using a separate most frequent category within each experience row makes , giving , only about a reduction in those classification errors.
The sample supports a statistically detectable but weak association, chiefly a reduced sample proportion feeling very safe. This observational study does not establish that bad experiences cause the change: reverse direction, reporting differences or confounding could also contribute. The numerical p-value also presumes the sampling and complete-case assumptions appropriate to the observations used.
Conditioning on marital status produces five contingency tables. In each, compare the conditional row percentages. The following differences are the sample proportion with some bad experiences minus the sample proportion without them, in percentage points; negative very-safe differences mean fewer respondents feeling very safe in the former group.
| Marital-status stratum | Difference: very safe | Difference: unsafe | Reported Pearson's chi-squared test p-value | Cramér's V | Goodman and Kruskal's gamma |
|---|---|---|---|---|---|
| Single | |||||
| Married | |||||
| Living with a partner | (inconsistent; see below) | ||||
| Divorced | |||||
| Widowed |
The p-values test independence within the respective strata; the magnitudes and directions come from the conditional percentages and association measures. Differences in the table are calculated from the counts before rounding.
Among single respondents, the very-safe sample proportion changes from to , while the unsafe sample proportion changes from to . The direction resembles the weak pooled pattern, but supplies little evidence against independence in this stratum. This is not evidence that the population association is exactly zero.
Among married respondents, the very-safe sample proportion changes from to and the fairly-safe sample proportion rises from to . Unsafe remains almost unchanged, versus . Thus the within-stratum association again chiefly shifts very safe toward fairly safe. Its is below the significance level, while still indicates a small association.
For respondents living with a partner, very safe changes from to , fairly safe from to , and unsafe from to . The very-safe difference is larger than in the married stratum. The printed p-value would be just below the conventional significance level. However, this particular output is internally inconsistent: recalculating Pearson's chi-squared test from its six displayed counts gives , , and . The reported agrees with the counts, whereas the printed would itself imply for two statistical degrees of freedom, rather than the printed . Using the displayed counts, this stratum does not reject independence at . The source PDF itself contains these incompatible figures; this is not resolved by rounding.
Among divorced respondents, very safe changes from to , but unsafe also decreases, from to , as fairly safe increases from to . This is a redistribution toward the middle category, not a simple shift toward greater unsafety. The near-zero gamma, , reflects the lack of a consistent ordinal direction, while can still register distributional differences without a direction. The p-value does not reject independence.
Among widowed respondents, very safe changes from to , and unsafe from to . The ordinal association is positive on the chosen ordering, with gamma . Its lack of conventional statistical significance, , does not imply a smaller estimated association than in the married group: the widowed stratum has only complete observations, versus in the married stratum, and therefore less precision. All five tables have sufficiently large expected counts for the reported approximations; even the smallest expected count is about .
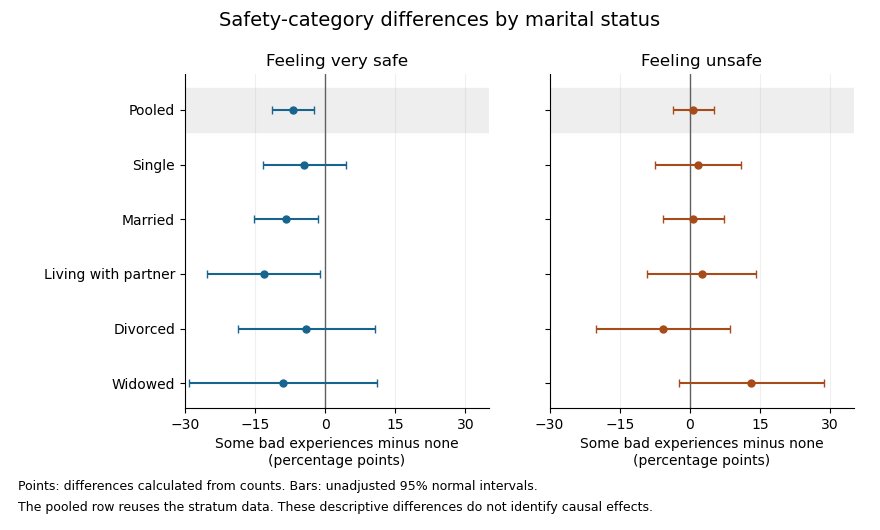

The plot uses large-sample Wald confidence intervals for the difference of independent sample proportions within each stratum. They concern the individual category contrasts, whereas the tabulated Pearson's chi-squared tests compare the full three-category distributions. The intervals are unadjusted for multiple hypothesis testing; the pooled row reuses the stratum observations, so it is not a sixth independent sample.
In the elaboration model, the persistence of a generally weak positive ordinal pattern within four strata is closer to partial replication than to a complete explanation of the pooled association by marital status. The differences in estimated patterns suggest possible specification: the divorced group's shift toward the middle category differs from the widowed group's shift toward unsafe. They do not by themselves establish population effect modification. In particular, significant and nonsignificant results need not differ significantly; compare the effects using an interaction contrast or a fitted model with the appropriate interaction terms, rather than comparing their separate p-values.[ref]
The Difference Between Significant and Not Significant is not Itself Statistically Significant by Andrew Gelman and Hal Stern. Printed p. 328, Introduction: comparing significance labels does not test the difference between estimates
One additional omnibus check can be derived from the supplied tables without assuming a common effect. Recalculating the five statistics from the counts, including the corrected living-with-partner statistic, the joint conditional independence test for stratified contingency tables givesUnder independent-stratum sampling this tests independence within every stratum jointly; it does not test whether the association is homogeneous across strata. It does not reject at , but this alone does not establish that stratification removed the population association: its ten-degree-of-freedom alternative is less focused than the pooled two-degree-of-freedom test, and nonrejection is not proof of equality.
The elaboration model also distinguishes an antecedent confounder from an intervening causal mediator. These cross-sectional tables do not establish the relevant time ordering or identify either role for marital status. Five separate stratum tests further require caution about multiple hypothesis testing: for example a Bonferroni correction at familywise would use per test, below all five individual p-values. That caution changes the interpretation of selected significance labels, not the observed conditional percentages.
The estimated patterns vary across strata, but the tables neither establish a population interaction nor prove that marital status explains away the association.
The ordinary least squares fit estimates the conditional mean of the continuous safety response as a linear function of the income coding:The regression coefficient for income is positive. Since larger response values mean greater safety, one additional coded income unit corresponds to an estimated increase of safety-scale units in the fitted mean. Following the question's stated units, a unit is a £10,000 income step. The observed coding also uses income bands with open end categories, so this is a linear trend per coded band step; it is not evidence of a known constant effect for every extra pound, especially within the open top band. The output's abbreviated variable label does not override the stated units.
The intercept is the fitted mean at income code zero. It is estimated as , but zero is outside the observed income codes, so that value is an extrapolated model baseline, not an observed estimate for a particular income category. Its small p-value tests a zero intercept; it is not the main test of the income association.
For the income coefficient, the standard error is . The reported test statistic and two-sided test giveproviding strong evidence against the null hypothesis of zero linear slope under the stated model assumptions. A Student t confidence interval, using residual statistical degrees of freedom, isThis is an interval for the population linear coefficient under the model, not an interval containing of individual safety scores. The large-sample estimate is precise enough to detect a positive association, but that does not establish substantial individual predictive power.
The coefficient of determination is : the fitted line accounts for about of the in-sample variation about the response sample mean. The adjusted coefficient of determination is about . Thus income alone explains very little of the observed variation, despite the small slope p-value. The residual standard error of response units describes substantial scatter about the fitted line. This is an estimated residual standard deviation, rather than the standard error of the slope or a complete individual prediction interval.
The overall F-test has on statistical degrees of freedom and . With one predictor and an intercept, it tests the same zero-slope hypothesis as the coefficient Student's t-test; , up to rounding. It is not an additional independent confirmation. In this simple linear regression, the Pearson correlation coefficient has the slope's sign and magnitude , another description of the weak linear association.
The regression uses complete observations and estimates two coefficients, giving residual statistical degrees of freedom. The deletion of observations is complete-case analysis; extending its conclusions to the full target population requires suitable assumptions about the missing-data mechanism. Classical reported standard errors also rely on an adequate linear conditional mean, independent errors and homoscedasticity; a normal linear model gives the finite-sample Student t-distribution and F-test calibration, while large-sample approximations can justify similar tests under weaker distributional assumptions. The printed summary alone does not establish these assumptions. Regression diagnostics and, where appropriate, heteroskedasticity-consistent standard errors address different parts of that assessment.
Finally, this unadjusted observational study estimates an association. Other covariates, such as age or experience status, may be related to both income and reported safety. Without additional design or causal identification assumptions, the positive fitted slope does not establish that increasing income would cause an increase in safety.
Articles by others on the same topic
There are currently no matching articles.