Source paper: released examination archive, member 2020/L/a10098w1.pdf.
The held cover identifies the Long Vacation sitting of 9 September 2021, distinct from the June paper carrying the same formal code. All eight questions and all 39 terminal leaves are answered. Scala snippets use Scala 2.13 style and the supplied interfaces. No Scala compiler is installed in the checking environment: independent models, exact calculations and Java numeric-helper checks are distinguished from native Scala or GUI execution.
Test each positive candidate divisor and count the successful remainder tests:The loop invariant is and , where denotes
def divisors(n: Int): Int = {
  require(n >= 1)
  var candidate = 1L
  var count = 0
  while (candidate <= n.toLong) {
    if (n.toLong % candidate == 0L) count += 1
    candidate += 1L
  }
  count
}candidate. A successful test adds exactly the new divisor; an unsuccessful test leaves the count unchanged. The loop variant is , which decreases by one. At termination , so the returned value is . A Long loop counter prevents the increment after the last positive Int candidate from wrapping around.Use a strict record test; tying the previous record is not enough:At the start of an iteration,
def emitHighlyComposite(): Unit = {
  var candidate = 1
  var best = 0
  while (true) {
    val count = divisors(candidate)
    if (count > best) {
      emit(candidate)
      best = count
    }
    candidate += 1
  }
}best is the maximum divisor count among the positive integers below candidate, taking the maximum of the empty family as zero. The already emitted values are exactly the highly composite numbers in that range, in increasing order. The next count exceeds best precisely when this candidate is a new strict record. Updating the record and advancing the candidate preserves both assertions. The program deliberately has no termination requirement; integer overflow in this unbounded enumeration is ignored as directed by the source.By the time the candidate is emitted, every positive integer has been examined. The straightforward divisor routine makes exactly remainder tests on . Consequently the total number isand the time is when remainder tests and the other fixed-width operations have constant cost and printing is cheap. Emitting only record candidates does not avoid computing the divisor count of the intervening candidates.
Every positive divisor has a unique prime factorization with . Conversely every such exponent choice gives a divisor. The exponent choices are independent, so the product rule givesFor the factorization is empty, and the empty product is one, corresponding to the divisor one.
Remove each prime power as soon as it is found, and stop trial division once the remaining value has no possible smaller factor:At an outer-loop boundary, write , where is the product of the prime powers already removed. The invariant states that
def divisors(n: Int): Int = {
  require(n >= 1)
  var remaining = n
  var factor = 2
  var result = 1
  while (factor.toLong * factor.toLong <= remaining.toLong) {
    var exponent = 0
    while (remaining % factor == 0) {
      remaining /= factor
      exponent += 1
    }
    result *= exponent + 1
    factor += 1
  }
  if (remaining > 1) result *= 2
  result
}result is , every prime divisor of is smaller than factor, and remaining has no prime divisor smaller than factor. Thus if factor divides remaining, it is prime; a composite factor would have a smaller prime divisor, contrary to the invariant.During the inner loop, with fixed, . Each division removes one copy, so the positive remainder strictly decreases and supplies an inner-loop variant. On leaving the inner loop the complete power has been removed; multiplying the result by
exponent + 1 uses part (d) and reestablishes the outer invariant after advancing factor. The outer factor increases and can never exceed the original while its guard holds, proving termination.At exit, a remainder greater than one must be prime: a composite remainder would have a prime factor no larger than its square root, which would still be smaller than
factor. It therefore contributes one final factor of two. A remainder of one contributes nothing. The algorithm returns using constant auxiliary space and no array. The widened multiplication in the loop guard prevents an Int overflow in the square test.The factorization-based version should produce the later outputs faster in this cost model. For an input , it performs at most trial-factor tests and successful divisions, because each successful division removes a factor at least two. The square test uses multiplication, so it does not introduce an extra division on every loop test.
Across all candidates through , the number of costly division or remainder operations is therefore at mostcompared with remainder operations for the straightforward routine. Small cases can still be affected by constant overhead; the conclusion concerns the growing enumeration workload, not a promise that every single call is faster.
Maintain the required boundary between entries strictly above the target and entries at most the target:The full invariant is , every entry before is greater than , and every entry at or after is at most . The array remains unchanged. Descending order justifies each update: if the middle value is greater, all earlier values are greater too; otherwise all values from the middle onward are at most the target.
def search(u: Array[Int], z: Int): Boolean = {
  var a = 0
  var b = u.length
  while (a < b) {
    val middle = a + (b - a) / 2
    if (u(middle) > z) a = middle + 1
    else b = middle
  }
  a < u.length && u(a) == z
}
The nonnegative loop variant strictly decreases, with each update retaining at most half the old candidate length. On termination , which is the first index whose value could be at most . Equality at that index is therefore necessary and sufficient for presence. Short-circuit evaluation makes the final test safe when , including the empty-array case. The time is , using constant auxiliary space.
Return immediately on equality and omit the final array inspection:An equality returns a genuine matching entry. After a nonequal comparison, descending order excludes the inspected middle entry and one whole side. In the half-open range, setting
def searchEarly(u: Array[Int], z: Int): Boolean = {
  var a = 0
  var b = u.length
  while (a < b) {
    val middle = a + (b - a) / 2
    val value = u(middle)
    if (value == z) return true
    if (value > z) a = middle + 1
    else b = middle
  }
  false
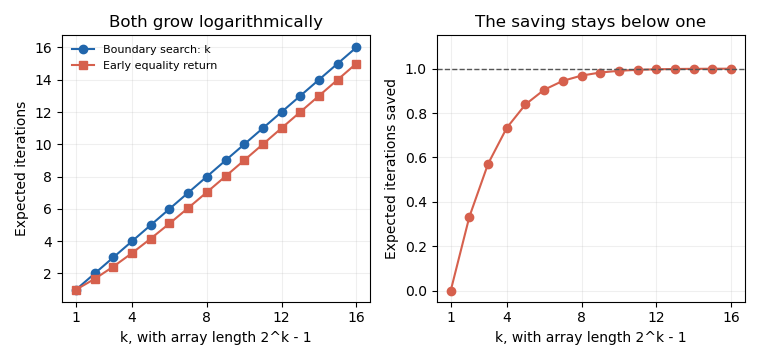
}b = middle already excludes the middle index; subtracting one would incorrectly exclude another possible entry. The candidate interval decreases as before, so absence is reported exactly when no possible entry remains.For an array of size , the first probe finds the uniformly selected target with probability . Otherwise it leaves a half of size ; conditional on entering that half, its target is uniform there. Counting the first iteration in every case givesFor , the successful-search decision tree has targets at depth , requiring iterations. ThusThe numerator is , as follows by induction or by shifting and subtracting a finite geometric sum. Substituting givesThe base gives one iteration, as required.
The expected number is exactly . In the boundary-search version, an interval of length is reduced to length whichever comparison branch is taken. It must therefore take exactly iterations to reduce length to zero, including when a probe has already equaled the target. The result holds for every target in this case, so averaging does not change it.
The expected saving on the specified successful searches iswhich tends to one iteration as increases. The fractional saving is , which tends to zero. Both versions have logarithmic expected time, and the improvement is a bounded average saving rather than a change of growth rate. A target at the first middle position benefits greatly, but the uniform distribution does not concentrate on that event. The extra equality branch and machine-level costs also matter when comparing measured execution times.

The abstract data type invariant constrains a total count function on integer keys as follows:The initial state has every count zero, and . These conditions make the abstract state a multiset supported on the allowed finite key range. Since the interface returns an
Int, the implementations below use representable nonnegative multiplicities; equivalently add to the invariant, where . The corresponding add precondition below prevents overflow. An idealized unbounded-integer specification can omit that machine bound.Write for the incoming state and . Use the following explicit contracts.
For
remove(x), the precondition is and . The postcondition is , with every other count unchanged. This convention rejects removal of an absent occurrence rather than silently treating it as a no-op.For
count(x), the precondition is . The result is and the whole abstract state is unchanged. Counts outside the allowed range are zero in the mathematical total function, but this chosen interface requires an in-range query.Implement the count function directly in a private array:The representation invariant is that
class ArrayIntBag(val MAX: Int) extends IntBag {
  require(MAX > 0)
  private val c = new Array[Int](MAX)
  private def inRange(x: Int): Boolean = 0 <= x && x < MAX

  def add(x: Int): Unit = {
    require(inRange(x))
    require(c(x) < Int.MaxValue)
    c(x) += 1
  }
  def remove(x: Int): Unit = {
    require(inRange(x))
    require(c(x) > 0)
    c(x) -= 1
  }
  def count(x: Int): Int = {
    require(inRange(x))
    c(x)
  }
}c has length MAX and every stored count is nonnegative. The abstraction function gives in range and zero outside it. Zero initialization establishes the invariant. An allowed addition changes exactly one entry without overflow; an allowed removal changes exactly one positive entry without making it negative; querying changes none. Thus each method implements its abstract postcondition as well as preserving the representation invariant. The private array prevents clients from bypassing those guarantees.Store the number of positive buckets, initially zero:Extend the representation invariant byThe abstraction function for the multiset is unchanged. The size operation has no precondition beyond a valid receiver; it returns the cardinality of the multiset support and changes no state. Replace the modifying methods inside the class byOnly transitions from zero to one or from one to zero change the support. Additions to an already positive bucket and removals leaving it positive preserve
private var distinct = 0

def size: Int = distinctdef add(x: Int): Unit = {
require(inRange(x))
require(c(x) < Int.MaxValue)
if (c(x) == 0) distinct += 1
c(x) += 1
}
def remove(x: Int): Unit = {
require(inRange(x))
require(c(x) > 0)
c(x) -= 1
if (c(x) == 0) distinct -= 1
}distinct. Thus size takes time, independently of MAX, and the other operations retain constant-time array access. Initialization still takes time.Use a finite sequence as abstract state, initially empty. One Scala interface isThe emptiness query has no precondition; its result is and its postcondition is . Adding on the left has no precondition and gives . Adding on the right gives . Both return
trait DoubleEndedQueue {
  def isEmpty: Boolean
  def addLeft(x: Int): Unit
  def getLeft(): Int
  def addRight(x: Int): Unit
  def getRight(): Int
}Unit.Each removal requires a nonempty incoming sequence.
getLeft() returns its first entry and leaves the remaining final sequence; getRight() returns its last entry and leaves the remaining initial sequence. These contracts remove exactly one occurrence, so duplicate values are permitted and do not collapse the sequence into a set.Keep private references
first and last, both initially null. A nonempty representation is a finite acyclic chain from first through next to last. Its representation invariant requires first.prev == null, last.next == null, and reciprocal links between every adjacent pair. The nodes reached by following prev from last are exactly the same nodes in reverse order. No internal node reference is exposed to clients.The abstraction function reads the
datum values along the forward chain, giving the abstract sequence from left to right. The empty representation has both endpoint references null; the invariant requires that either both are null or both are nonnull. A single node has both links null. Updating both endpoint references when removing that last node is therefore essential.The following class uses the node type supplied in the paper:An insertion connects a fresh endpoint to the old chain and updates its reciprocal link. A removal reconnects the exposed endpoint to null; the singleton case also clears the opposite endpoint. The remaining chain therefore satisfies the same representation invariant and has exactly the abstract sequence required by the specification. Every operation performs pointer work, excluding allocation costs for a newly added node.
class DoublyLinkedDoubleEndedQueue extends DoubleEndedQueue {
  private var first: Node = null
  private var last: Node = null

  def isEmpty: Boolean = first == null

  def addLeft(x: Int): Unit = {
    val node = new Node(x, null, first)
    if (first == null) last = node
    else first.prev = node
    first = node
  }

  def addRight(x: Int): Unit = {
    val node = new Node(x, last, null)
    if (last == null) first = node
    else last.next = node
    last = node
  }

  def getLeft(): Int = {
    require(!isEmpty)
    val old = first
    first = old.next
    if (first == null) last = null
    else first.prev = null
    old.next = null
    old.datum
  }

  def getRight(): Int = {
    require(!isEmpty)
    val old = last
    last = old.prev
    if (last == null) first = null
    else last.next = null
    old.prev = null
    old.datum
  }
}Add this method inside the concrete class:Its precondition is a valid receiver, including an empty one. Its postcondition leaves and prints the entries of from left to right in the displayed bracket format, followed by a newline. The loop invariant says that the printed entries are precisely the chain before
def display: Unit = {
  print("[")
  var current = first
  var separator = ""
  while (current != null) {
    print(separator)
    print(current.datum)
    separator = ", "
    current = current.next
  }
  println("]")
}current; the not-yet-printed entries are the chain starting there. Advancing along the acyclic chain terminates after its length. Printing changes the output stream, but it changes neither links nor payloads.With that display format the output isThe first removal takes the newly prepended left value . The right removal later takes the most recently appended . The next left removal takes the earlier , leaving the ordered sequence . The two equal values are different occurrences, and the displayed order follows the links rather than numerical sorting.
20
10
10
Queue status: [30, 40, 15]Use the empty reference as the base case:Induction on the tree proves the order: the first recursive call prints exactly the left subtree, then the procedure prints the root, then the final call prints exactly the right subtree. A finite acyclic tree supplies decreasing proper subtrees, so the recursion terminates. The traversal is valid for arbitrary integer labels; sorted output would additionally require a binary search tree invariant.
def printInorder(root: Tree): Unit = {
  if (root != null) {
    printInorder(root.left)
    println(root.datum)
    printInorder(root.right)
  }
}Split the index range at its middle:For , the child sizes are and , differing by at most one. Induction gives the same property at every descendant, so the result is nearly balanced. Its inorder traversal is the initial subrange, then , then the final subrange, reproducing exactly with every occurrence retained.
def MakeTree(u: Array[Int], a: Int, b: Int): Tree = {
  require(0 <= a && a <= b && b <= u.length)
  if (a == b) null
  else {
    val middle = a + (b - a) / 2
    new Tree(u(middle),
             MakeTree(u, a, middle),
             MakeTree(u, middle + 1, b))
  }
}There is one nonempty recursive call per constructed node and one constant-time base call per empty child position. Therefore construction takes time for , or including the empty case, and allocates exactly nodes. The balanced recursion has logarithmic stack depth. The input array need not be sorted: the required property concerns subtree sizes and inorder order, not a search-tree ordering.
Repeated right rotations expose the next inorder entry without a recursion stack:A right rotation replaces a local shape with inorder order by another shape with exactly that same order. The inner loop therefore preserves the inorder sequence of the remaining tree while moving its next output closer to the root. When the left child is null, the root is exactly the first remaining inorder entry. Printing it and advancing to its right child removes that entry from the remaining traversal.
def printDestructively(input: Tree): Unit = {
  var root = input
  while (root != null) {
    while (root.left != null) {
      val child = root.left
      root.left = child.right
      child.right = root
      root = child
    }
    println(root.datum)
    root = root.right
  }
}The outer-loop invariant is that the output already produced, followed by the inorder sequence of the current root, equals the original inorder sequence. Consequently the procedure prints every original entry once in order. It stores only a constant number of node references and uses auxiliary space. It changes the original links, as permitted; clients must not rely on the input tree retaining its earlier shape.
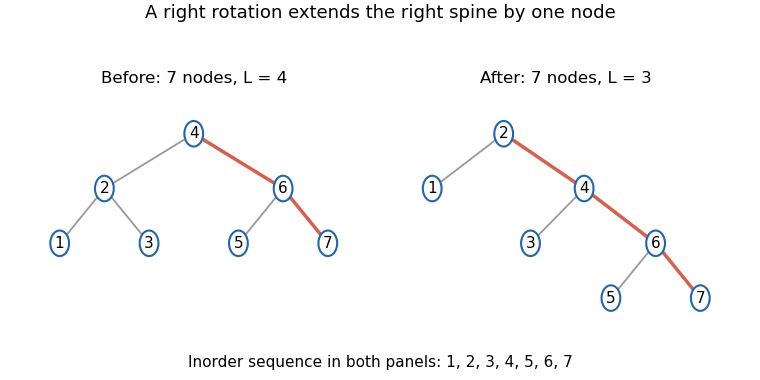

For a remaining tree , define the potentialThis counts the nodes not on the right spine, so . Consider a right rotation with old root , left child , and three untouched subtrees . Before the rotation the potential isAfter the rotation it is , so each rotation decreases by exactly one while preserving the number of remaining nodes. This supplies a nonnegative decreasing bound for the inner loop.
When the root has no left child, printing it and advancing to its right child leaves unchanged and decreases the remaining node count by one. Thus decreases on every rotation and every removal, proving termination of the whole procedure. Over the entire execution there are exactly printed nodes and exactly rotations, since the final potential is zero. Both quantities are at most , so the running time is for a nonempty tree, with constant auxiliary space. The nested syntax does not imply quadratic time: it is the total potential decrease across all iterations that bounds the inner work. The potential is a proof device and is not computed by the running program.
The iterator pattern exposes sequential traversal through a small interface while hiding the representation of the underlying data. A client asks whether another entry is available and requests the next entry; it need not know whether the producer uses an array, linked list, tree or generated sequence.
The key design benefit is encapsulation of traversal state and representation. The same consuming algorithm can work through the interface for different producers, and each traversal can keep its own cursor state when a fresh iterator is supplied. This independence requires separate consumption states; two references to one iterator share a cursor.
The two abstract methods areThe first reports availability; the second returns and consumes the next entry, or throws a
def hasNext: Boolean
def next(): TNoSuchElementException if none exists. Other standard iterator operations are supplied in terms of this interface. Repeated availability checks must not lose entries, although they may perform preparatory internal work.[ref]Scala 2.13 iterator API documentation. Iterator, abstract members hasNext and next; class-level mutation and reuse contract
Yes in special cases; an ordinary finite iterator that progresses through its input needs changing consumption state. For a genuine immutable counterexample, an iterator over an infinite constant sequence needs no changing fields:Removing the first entry of that sequence leaves the same sequence, so this satisfies the iterator behaviour without changing object state. A permanently empty iterator is another example.
final class Ones extends Iterator[Int] {
  def hasNext: Boolean = true
  def next(): Int = 1
}For a normal finite nonempty traversal, however, repeated
next() calls must eventually change the returned entry or availability, so the implementation needs mutable cursor state somewhere. Declaring only val fields is not a proof of deep immutability: those fields can refer to another mutable iterator, an array, or a stateful closure. The standard API's description of iterators as mutable captures the usual consuming case, rather than enforcing a mutable field in every possible implementation.Delay both initial skipping and every later skipped entry until a caller actually requests availability or an output:The state flag means that the next underlying entry, if present, must be skipped before the next selected entry can be exposed. It is initially false for odd positions and true for even positions. Returning a selected entry reinstates that obligation.
class HalfIterator[T](iter: Iterator[T], odd: Boolean)
    extends Iterator[T] {
  private var needSkip = !odd

  def hasNext: Boolean = {
    if (needSkip && iter.hasNext) {
      iter.next()
      needSkip = false
    }
    iter.hasNext
  }

  def next(): T = {
    if (!hasNext)
      throw new java.util.NoSuchElementException("empty half iterator")
    val result = iter.next()
    needSkip = true
    result
  }
}Construction does not call the underlying iterator at all. A successful availability check may discard the one required intervening entry, but does not fetch the selected entry. It then clears the flag, so repeated availability checks cannot skip again. To decide whether a second entry exists through this interface, consuming the preceding discarded entry is necessary. After
next() returns, it does not eagerly request the following skipped entry. This gives the intended laziness while retaining correct exhaustion behaviour, including an even-position iterator over a singleton input.Use short-circuit evaluation so that even an availability test of the second iterator is delayed until the first is exhausted:Each successful call returns from the first producer while it has entries, then from the second. There is no constructor-time request or element prefetch. This implements concatenation of the producers' remaining sequences, subject to their ordinary iterator contracts.
class ConcatIterator[T](first: Iterator[T], second: Iterator[T])
    extends Iterator[T] {
  def hasNext: Boolean = first.hasNext || second.hasNext

  def next(): T = {
    if (first.hasNext) first.next()
    else if (second.hasNext) second.next()
    else throw new java.util.NoSuchElementException("empty concatenation")
  }
}For the implementations above the value isThe first half-iterator returns the odd-position characters while consuming the even-position characters as its required skips. By the time it is exhausted, it has consumed the entire shared underlying iterator. The second half-iterator consequently has no entries left when concatenation reaches it. Sharing one source does not create two independent traversals. Neither constructor consumes anything, so it also does not shift the first output before iteration begins. The source's implementation references here should be read as parts (d) and (e); the printed reference to (c) and (d) is a cross-reference slip.
List('1', '3', '5', '7', '9')Programming language polymorphism lets a common interface or operation apply to values of more than one type. In subtype polymorphism, a variable typed by a base class or trait can refer to instances of different implementing classes. A method call is checked through that common interface, then dynamic dispatch selects the receiver's overriding implementation. For example, a consumer using
Iterator[Int] can accept either a filtering iterator or a concatenating iterator without knowing its concrete class.Inheritance can establish a subtype relationship, while method overriding provides distinct implementations of a shared method signature. The classes must still honour the common behavioural contract; sharing a name alone does not establish substitutability. Parametric polymorphism is different: the type parameter in
Iterator[T] or FiniteDist[T] lets a definition work uniformly over element types. Method overloading is a further form of software polymorphism in which the compiler selects a signature using the static argument types; it should not be confused with runtime receiver dispatch.Validate the parameter, and include exactly the outcomes of positive mass:The range test also rejects
final class Flip(p: Double) extends FiniteDist[Boolean] {
  require(p >= 0.0 && p <= 1.0)

  def getDom: List[Boolean] =
    if (p == 0.0) List(false)
    else if (p == 1.0) List(true)
    else List(false, true)

  def getProb(x: Boolean): Double = if (x) p else 1.0 - p
}NaN, since its ordered comparisons are false. At the endpoints one outcome has zero mass and must be omitted from the support; listing both unconditionally would violate the supplied interface contract. For an interior parameter the two masses are positive and sum to one.Use a widened interval width, so the arithmetic also handles endpoints near the limits of The support lists every integer in the inclusive interval once. Its cardinality is
Int:final class Uniform(l: Int, u: Int) extends FiniteDist[Int] {
require(l <= u)
private val width = u.toLong - l.toLong + 1L
def getDom: List[Int] = {
val builder = List.newBuilder[Int]
var value = l.toLong
while (value <= u.toLong) {
builder += value.toInt
value += 1L
}
builder.result()
}
def getProb(x: Int): Double =
if (l <= x && x <= u) 1.0 / width.toDouble else 0.0
}width, so assigning each atom mass gives total mass one. The loop counter is also widened, preventing an increment past Int.MaxValue from wrapping to a negative value. Returning the full support takes time and space proportional to its width and can be impractical for a very large interval; the mass query itself is constant-time. The full integer interval has width , which fits Long but not positive Int.Reject the empty string because it has no positive total count to normalize:The support contains each occurring character once, and a character absent from the string gets mass zero. The occurrence counts sum to the nonzero string length, proving normalization. For a separate example, the string
final class DistFromString(s: String) extends FiniteDist[Char] {
  require(s.nonEmpty)
  private val frequencies =
    s.foldLeft(Map.empty[Char, Int]) { (counts, c) =>
      counts.updated(c, counts.getOrElse(c, 0) + 1)
    }

  def getDom: List[Char] = s.toList.distinct

  def getProb(c: Char): Double =
    frequencies.getOrElse(c, 0).toDouble / s.length.toDouble
}"aba" gives masses and to its two characters. The interpretation follows Scala's Char elements, so it counts UTF-16 code units rather than imposing a separate Unicode-code-point representation. The Double results approximate the corresponding rational probabilities.Add a generic mapping method inside the supplied trait. Snapshot the finitely many source masses, and sum masses when different entries have the same image:Here the mapping is a mathematical function, and keys are assumed to have stable equality consistent with their intended identity. Each source atom is evaluated once when the new distribution is constructed. The distinct image list is exactly the finite support because all listed source atoms have positive mass. Summing collisions, rather than overwriting a previous mass, implements the probability pushforward.
def map[U](f: T => U): FiniteDist[U] = {
  val entries = getDom.map(x => (f(x), getProb(x)))
  val support = entries.map(_._1).distinct

  new FiniteDist[U] {
    def getDom: List[U] = support
    def getProb(y: U): Double =
      entries.foldLeft(0.0) { case (sum, (image, mass)) =>
        if (image == y) sum + mass else sum
      }
  }
}The sets of source atoms with a fixed image partition the original support. Hence nonnegativity is preserved and, in exact probability arithmetic,Thus the result is a finite probability distribution. For a constant mapping, every atom merges into one outcome of mass one. Floating-point additions in the implementation can introduce rounding error, so numerical tests of normalization should use a suitable tolerance rather than demand exact equality of
Double sums.Test-driven development uses a repeating sequence: write a small test for the next required behaviour, observe it fail for the expected reason, add enough implementation to make it pass, and refactor while keeping the tests passing. The initial failure checks that the test can actually detect the absent behaviour. This differs from writing a whole implementation first and only then constructing tests for it; it also uses the tests to guide interface and design decisions rather than only to inspect a finished program.[ref]
Test-driven development in the Agile Alliance glossary. Meaning of TDD and its short test/implementation/refactoring cycle
A mixture of test-selection styles is possible; the defining test-first step is normally behaviour-driven. Choosing inputs and expected results from a public contract is black-box testing with respect to the implementation, even if the developer writes the test. Knowing the internal branches can then motivate white-box tests for boundary paths or exceptional cases. TDD specifies the order of development activities, not a rule forbidding either source of test cases. It therefore does not guarantee branch coverage, and passing the growing test suite is not a proof of correctness for untested inputs.
The observer pattern connects one event-producing subject to a changing set of interested consumers. Consumers register through an observation interface; when a relevant change occurs, the producer notifies them through that interface rather than naming every concrete consumer. Consumers can be added or removed without rewriting the producer's core behaviour.
This is useful for keeping displays, controls or other derived views synchronized with changing state. The design avoids tight coupling from the producer to all concrete dependants, which otherwise makes every new consumer require changes to the producer. Publishing after the producer's representation invariant has been restored also lets callbacks observe a coherent state. The pattern does not by itself prevent notification cycles or obsolete subscriptions; update policy and unregistration still matter.
A widget or model implementing
Publisher is the subject. It calls publish(event) when an observable change occurs. An interested Reactor subscribes with listenTo(subject), and adds a partial function to reactions that handles the event types it understands. deafTo(subject) ends that subscription when it is no longer needed.The connection is therefore made through publisher and reactor interfaces rather than through a hard-coded list of particular application classes. A reactor may observe several publishers and inspect an event's source to distinguish them. The implementation's registration machinery delivers published events to interested reactions; registering a reaction alone is not a substitute for subscribing to the source.[ref]
Scala Swing event-system documentation. Official library README, event-system description; Reactor API entries listenTo, deafTo and reactions
For the converter, the three text fields are publishers and the frame is a reactor. Register the three fields once, then handle their edit-completion events to update the stored numeric state and refresh the appropriate displayed values.
Choose the following explicit policy: an edit of pounds recomputes euros; an edit of euros recomputes pounds; an edit of the rate keeps pounds fixed and recomputes euros. Amounts may be any finite signed values, while a rate must be finite and strictly positive. Invalid text, non-finite numbers and overflowing conversions leave the last accepted state intact and restore its display.The numeric state has the invariant and ; euros are derived instead of being stored independently. A proposal is validated before either stored value changes. The update flag prevents a synchronous programmatic display update from recursively committing another edit. Currency amounts display two decimal places, while the rate retains its parsed precision; display rounding is not repeatedly fed back into the numeric model.
import scala.swing._
import scala.swing.event.EditDone
import scala.util.Try

object CurrencyConverter extends SimpleSwingApplication {
  def top: Frame = new MainFrame {
    title = "Currency converter"
    val pounds = new TextField(8)
    val euros = new TextField(8)
    val rate = new TextField(8)
    private var poundsValue = 10.0
    private var rateValue = 1.15
    private var updating = false

    private def finite(x: Double): Boolean =
      java.lang.Double.isFinite(x)

    private def money(x: Double): String =
      java.lang.String.format(java.util.Locale.ROOT, "%.2f",
                              java.lang.Double.valueOf(x))

    private def showValues(): Unit = {
      updating = true
      try {
        pounds.text = money(poundsValue)
        euros.text = money(poundsValue * rateValue)
        rate.text = java.lang.Double.toString(rateValue)
      } finally updating = false
    }

    private def commit(field: TextField): Unit = {
      if (!updating) {
        val proposed = Try(field.text.trim.toDouble).toOption
          .filter(finite).map { value =>
            if (field eq pounds) (value, rateValue)
            else if (field eq euros) (value / rateValue, rateValue)
            else (poundsValue, value)
          }
        proposed.foreach { case (newPounds, newRate) =>
          if (finite(newPounds) && finite(newRate) && newRate > 0.0 &&
              finite(newPounds * newRate)) {
            poundsValue = newPounds
            rateValue = newRate
          }
        }
        showValues()
      }
    }

    contents = new FlowPanel {
      contents += new Label("Pounds")
      contents += pounds
      contents += new Label("Euros")
      contents += euros
      contents += new Label("Euros per pound")
      contents += rate
    }
    listenTo(pounds, euros, rate)
    reactions += {
      case EditDone(source) if source eq pounds => commit(pounds)
      case EditDone(source) if source eq euros => commit(euros)
      case EditDone(source) if source eq rate => commit(rate)
    }
    showValues()
  }
}Locale.ROOT ensures that formatted decimal points match the input parser.The code handles the
EditDone events used by the paper rather than trying to parse every intermediate keystroke. It uses Scala 2 style and Java 8-or-newer numeric helpers. No Scala compiler or Swing runtime execution was available in the checking environment; the state transitions were checked independently, and the API usage was compared with the supplied contract and official Scala/Swing documentation.[ref]Java 8 Double API documentation. isFinite(double), parseDouble(String) and toString(double)
Articles by others on the same topic
There are currently no matching articles.