Topics (318k) Articles (329k) Users (391) Discussions (237) Comments (383) Files (10k) New article
Past exam of the mathematics course of the University of Cambridge 2004 iii Paper 34 6 Solution by  Codex 0 Created 2026-10-03 Updated 2026-10-14
Let denote the time- price of a zero-coupon bond paying one at maturity , with . Information available at is the sigma-algebra in the market filtration. For a curve differentiable in maturity, the instantaneous forward rate and its diagonal short rate areThe last identity follows by integrating the maturity derivative and using . The continuous-time bank account reinvesting at the short rate is , and its reciprocal is the discount factor. Modelling forward rates means specifying a random maturity-indexed curve with an evolution consistent with the same pricing measure for every bond. The expectation below is under that money-market risk-neutral measure, not an unspecified physical measure.
For fixed maturity , if is a true martingale on , its terminal value is . ConsequentlyConversely, this representation gives , a conditional-expectation martingale by the tower property. For example, for , conditioning the right side on returns . These claims assume . A positive discounted local martingale alone need not equal the conditional expectation of its terminal value, so the word “martingale” cannot be weakened without an extra integrability argument.
In the Vasicek model, the Brownian motion and coefficients in must be understood under this pricing measure. Multiplying by and integrating gives, conditionally on ,Assume first , and put and . Integrating the explicit solution over yieldsThe interchange of the stochastic integrals is justified by their deterministic square-integrable kernels on the finite triangular domain; equivalently approximate the kernels by step functions, interchange finite sums, and pass to the limit using the Itô isometry. The last integral conditionally has a centered normal distribution independent of , with varianceA deterministic Brownian integral is Gaussian because its step approximations are sums of independent normal increments; their variances converge by the Itô isometry. Completing the square in the normal density proves for a normal variable of mean and variance . Hence the zero-coupon bond price is exponential-affine:An equivalent familiar form isAt , both coefficients are zero and the bond value is one. These formulas are valid for negative as well as positive nonzero on finite horizons, though a genuinely mean-reverting Vasicek model has . For , direct integration gives , andAll the exponential moments used above are finite, so the prices defined by the conditional expectation do give true discounted martingales.
To fit an initial bond curve, let its observed prices be positive, satisfy , and have a sufficiently smooth instantaneous forward rate . Set ; this compatibility is forced by the infinitesimal-maturity bond price. Replace by a deterministic function , with , so thatIts mean satisfies , . The variance of the integrated rate remains , since changing deterministic drift does not change the centered Gaussian process. ThereforeThe required mean is consequently . Solve its mean equation for :Combining the last two terms gives the explicit Hull-White model calibration in the question's parameter convention:With , the specified mean solves the same linear differential equation and initial condition as the model mean, so it is the actual mean. The resulting model forward curve equals ; integrating and using proves for every maturity. If the drift is instead written , its calibration parameter is , not itself.
The printed allowance of arbitrary constants needs a qualification for this final claim. If , replacing by changes no coefficient at all: regardless of . Its initial curve is fixed at . With , the compatible smooth observed curve is already a counterexample to the unconditional fitting claim. Thus arbitrary compatible smooth positive initial curves can be fitted by the stated replacement when ; it cannot fit arbitrary curves when . In that degenerate case one can instead introduce an independent deterministic drift in , choosing to recover the desired initial curve. Likewise an externally fixed is incompatible with exact fitting, and an arbitrary nonsmooth set of prices need not define the differentiable forward curve assumed in the model.
Past exam of the mathematics course of the University of Cambridge 2004 iii Paper 34 5 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Write , and specify the physical Black-Scholes model as , with constant and bank rate . The physical drift is needed for an expected utility calculation; a pricing model specified only under a risk-neutral measure does not determine the investor's preferences over risky positions. PutHere is the market price of risk, is the density of the risk-neutral measure , and is the state-price density. The Girsanov theorem makes a Brownian motion under .
For a dollar holding in the stock and consumption rate , the portfolio wealth equation isSince , integration by parts gives the useful deflated wealth equation with consumptionFor strategies with a true deflated gain martingale, terminal wealth and consumption obey the state-price budget constraintFor nonnegative wealth and consumption, the admissibility condition can instead give a budget inequality; increasing utilities use the full budget at an optimum. Conversely, suitable integrable payoff and consumption plans with this budget are financeable in the Brownian complete market. To construct the strategy, setBy the Brownian martingale representation theorem, write . The required dollar stock holding is ; substitution in the deflated gain equation verifies financing. Remaining wealth goes into the bank account. For square-integrable data the representation holds directly, and localization handles the customary integrable admissible data.
First take no consumption. For an increasing strictly concave differentiable utility function whose marginal derivative can be inverted, let . Choose so thatThis candidate is not merely a first-order guess. The concave supporting-tangent inequality gives, pointwise,Taking expectations and using the budget proves for every feasible competitor. Finance the optimizer by its risk-neutral pricing value , using the preceding representation to find the holdings.
For a merely concave differentiable utility function, the general formulation is to select from the maximizers of over its wealth domain, and choose the multiplier to satisfy the budget. If increasing utility is not assumed, the equality-budget multiplier may have either sign; the positive-multiplier inverse formula above is for increasing utility. Flat portions allow multiple maximizers; boundaries require one-sided inequalities rather than equality of marginal derivatives. Existence of a multiplier, integrability and an admissible maximizer must be checked. Concavity alone does not guarantee a well-posed problem: with unrestricted dollar positions, linear utility and permits unbounded expected terminal wealth. The explicit utilities below satisfy the needed conditions in their stated domains.
For exponential utility on , and . ThereforeThe budget is equivalently , since . Under , , giving . HenceMatching the Brownian coefficient of with gives the finite-horizon exponential-utility portfolioHold shares and invest in the bank account. This is a dollar amount, not a fixed wealth fraction. The Gaussian exponential formula also gives the optimal expected utilityThis calculation uses unrestricted wealth and an admissibility class permitting the displayed Gaussian terminal wealth, with integrable deflated gains and the relevant exponential moment. A nonnegative-wealth constraint would change the optimizer; no such constraint is imposed on this exponential-utility example.
For both terminal and running utility function, choose and a nonnegative adapted consumption rate to maximize subject to the combined budget. Pointwise maximization of and gives, for interior strictly concave cases,Apply the concave supporting-tangent inequality to and to at every time, then integrate and take expectations. The difference in objectives is at most times the difference in budget expenditures, which is nonpositive. This proves optimality, not just the marginal conditions. The financing value isThe question's consumption rate is denoted here to keep it distinct from interest-rate notation.
For logarithmic utility with , , assume and positive wealth and consumption. The marginal conditions and budget giveEach state-price-weighted payment is deterministic, so conditional valuation immediately gives . Put . Since the Itô formula gives , this value satisfiesComparison with the wealth equation verifies the complete finite-horizon logarithmic investment and consumption strategy:Thus the optimal share holding is , and the remaining value is in the bank account; borrowing or shorting is allowed if that value or the stock holding is negative. Terminal wealth is positive and consumption is positive throughout. Finally , so the optimal objective, if desired explicitly, isFinite-horizon lognormal moments ensure the budget and expected utilities are finite, completing the feasibility and optimality checks.
Past exam of the mathematics course of the University of Cambridge 2004 iii Paper 34 4 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Write and for the price of the unit zero-coupon bond maturing at , so . Let the stock satisfy with . Assume the value function is and the holdings have enough smoothness for the calculations below. The self-financing portfolio condition is the gain identityThe Itô formula expresses the left side asMatching the diffusion terms gives , or . Differentiating gives . Also . Matching the remaining drift terms consequently gives the two necessary conditionsThey are sufficient because substituting them into the Itô formula restores exactly the gain identity. Necessity first holds along the stock process; its positive lognormal density for every , together with continuity of the coefficient functions, gives the displayed identities for all and , and continuity extends them to the endpoints.
Equivalently, the smooth value of any self-financing portfolio satisfies the Black-Scholes equationIndeed, the gain identity after imposing has drift , which gives this equation. Conversely, if satisfies this equation, takeThe Itô formula then verifies that these holdings form a self-financing portfolio of value . This converse asserts existence of the correct holdings. It does not certify an arbitrary decomposition of into stock and bond holdings: for example, , , solves the value equation but fails . The Black-Scholes value equation needs delta-compatible holdings precisely for this reason.
For a constant-proportion portfolio, the stock value must satisfy . Since , integration of gives . Substituting into the Black-Scholes equation givesThus, for initial portfolio wealth and stock price , the complete explicit solution isHere counts shares and counts maturity- bonds; the initial cost is . Directly, the self-financing gain equation is , which also verifies the displayed value. Constant proportions concern the values of the holdings, not constant numbers of shares or bonds. The nondegenerate volatility assumption is necessary for the preceding diffusion matching; with , one only obtains a gain condition along the deterministic stock path.
Past exam of the mathematics course of the University of Cambridge 2004 iii Paper 34 3 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14A useful finite-horizon form of the Girsanov theorem is as follows. Let be a Brownian motion and an adapted, progressively measurable process with almost surely. Suppose its stochastic exponentialis a true martingale with mean one. The Novikov condition is a sufficient condition. Under the equivalent probability measure , the process is a Brownian motion.
For the proof sketch, the Itô formula gives . Integration by parts cancels the drift in , since from cancels . After localization, the Bayes formula for conditional expectation makes a continuous local martingale under . Its quadratic variation is still , because adding a finite-variation process does not change quadratic variation. One can see the Brownian conclusion directly: for real , the Itô formula makes a local martingale. Its modulus is bounded on the fixed horizon, so it is a true martingale. ThusThis is the conditional characteristic function of a centered normal distribution with variance , independent of the past. Continuity and these independent normal increments give the defining properties of Brownian motion.
Now put and , the standard normal distribution function. At zero drift the endpoint density of paths staying below isIndeed, reflect the portion of a path after its first hitting time of . By continuity and the independent symmetric Brownian motion increments after this stopping time, reflection preserves its probability law and maps a crossing path ending at to a path ending at . This subtracts exactly from the unrestricted endpoint density; it is the Brownian reflection principle.
Taking the constant drift tilt in the Girsanov theorem makes under have the same law as under . Therefore the desired finite-horizon maximum of Brownian motion with drift has probabilityCompleting squares gives and . HenceThe maximum has no atom at a positive level, so strict and weak barrier inequalities agree. This also follows from continuity of the displayed distribution function. At the formula reduces to .
For the up-and-out power claim, write and use the risk-neutral measure for the Black-Scholes model, under whichwith . The barrier survives exactly when . Its risk-neutral pricing value isThe factor inside the expectation is a mean-one Exponential martingale for Brownian motion. Under the probability tilted by it, is a Brownian motion, so the barrier process has drift . Applying the preceding survival formula yieldsAs , the bracket tends to one and the price becomes the discounted second moment . As , it tends to zero. If , use the deterministic path instead: the price is when , and zero otherwise. At , with , the price is simply .
Past exam of the mathematics course of the University of Cambridge 2004 iii Paper 34 2 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let the bank account be , where is the one-period riskless gross return. In the binomial market, is either or , with and both successors having positive physical probability. The information at time consists of the first moves. A trading strategy chooses its holdings using only this information. A self-financing portfolio funds rebalancing from its current value; there is no external contribution.
Absence of arbitrage requires . If , borrowing to buy the stock yields a nonnegative gain, strictly positive on the up branch; if , shorting the stock and investing its price yields the reverse arbitrage. When , define the risk-neutral probability in a binomial marketGiving each successive up move conditional probability defines an equivalent martingale measure , since every finite path has positive probability and .
For a contingent claim with successor values at a node of current stock value , solve the two replication equations. The number of shares and current cash value areThen and , so the replicating strategy costsHold bank-account units over that period. Starting with the terminal payoff and applying these equations backwards supplies an adapted self-financing strategy replicating every path-dependent contingent claim. This proves market completeness. A different claim price would permit an arbitrage by buying the cheaper claim or replica and selling the dearer one. Iterating the backward pricing relation gives the unique risk-neutral pricing formulaThe physical up probability affects real-world frequencies but does not enter this replication price.
For a terminal payoff , write . Its current price is the restriction to the available nodes of the functionIf is convex, each summand is convex in and each weight is positive; summing their defining convexity inequalities proves that is convex. This provides an explicit convex extension between the actual stock nodes, so “convex on the nodes” is unambiguous. If is strictly convex, each positive scaling preserves strict convexity, so is strictly convex as well.
For the replicating portfolio in a binomial market, the stock holding isFor , let . The next down and up holdings are the secant slopes of on the adjacent intervals with endpoints :For any convex function and , its defining inequality at rearranges to . The inequality is strict for a strictly convex function. Applying this to the three stock values orders the two next holdings. Meanwhile the backward pricing relation gives, by subtracting its values at and ,The coefficients are strictly positive and sum to one. Therefore the current share holding lies between the next two holdings:Both inequalities are strict for a strictly convex payoff. For an affine payoff the share holding is constant, explaining the required weak interpretation. These are numbers of shares, not the fraction of portfolio wealth invested in the stock.
Past exam of the mathematics course of the University of Cambridge 2004 iii Paper 34 1 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use the riskless financial asset as numéraire, normalized to have initial value one and terminal value . Write for the initial risky prices and for the finite, measurable terminal price random vector. Define the discounted gain vector . A risky holding financed by the cash holding has zero initial cost and discounted terminal gain . An arbitrage is such a portfolio with almost surely and . Allowing nonpositive initial cost is equivalent: invest any initial surplus in the riskless financial asset to obtain a zero-cost arbitrage.
An equivalent martingale measure is a probability measure with exactly the same null events as the physical probability measure , under which discounted asset prices are integrable and satisfy . Equivalently, . Such a measure rules out arbitrage: every zero-cost portfolio has mean discounted gain zero, whereas a nonnegative gain positive with positive -probability is also positive with positive -probability and has strictly positive -expectation.
For the converse, the probability space need not be finite, and the payoffs need not be integrable under . Here is a direct Gaussian-damped martingale density construction. SetThe set is a linear subspace. Choosing a finite basis of shows that almost surely: intersect the probability-one events on which each basis vector is orthogonal to . If , then is not almost surely zero. Absence of arbitrage implies both and , by applying the definition to and .
All the analytical steps in minimizing can be checked directly. On the integrand is bounded by , since . Its first two directional derivatives are bounded uniformly in by constants depending only on and the direction, because the functions are bounded for . The mean-value bound therefore proves continuity of , and the Taylor theorem remainder bound, integrated over , provesThus differentiation under the integral does not require an unproved physical moment assumption.
To prove coercivity, suppose in . A subsequence of converges to a unit vector . This elementary finite-dimensional compactness follows by successively taking convergent subsequences of the bounded coordinates. Since , some event has positive probability: the negative-gain event is the countable union of such events with and integer . Eventually on , and henceIf coercivity failed, an unbounded sequence with bounded would have just such a contradictory subsequence. Consequently a minimizing sequence for is bounded and has a convergent subsequence; continuity makes its limit a minimizer. If , simply take . In every case the directional derivatives vanish at . The vector lies in and is orthogonal to , so it is zero. Thereforeis a positive mean-one density defining an equivalent martingale measure. Integrability of under follows from the same Gaussian bound with . This establishes absence of arbitrage if and only if an equivalent martingale measure exists, without quoting a financial duality theorem or assuming a finite state space.
Now suppose the probability space is finite. Discard null states and enumerate its positive-probability atoms by . Every measurable terminal payoff is a vector in . Let be the matrix whose columns are the discounted terminal payoffs of the traded financial assets, with first column , and let be their initial price vector. A portfolio with holding vector replicates the discounted payoff , and an equivalent martingale measure is exactly a vector satisfyingThe first pricing equation includes . A complete market means . If both price the financial assets, then for every . Completeness allows to be each coordinate vector, so .
Conversely, if the financial market is incomplete, there is a nonzero vector with . To see this without invoking a duality theorem, perform row elimination on the homogeneous system: its number of pivots is , leaving a free variable and hence a nonzero solution. The constant payoff column gives . Existence of an equivalent martingale measure was already proved, so choose one strictly positive vector . Forboth and are distinct strictly positive probability vectors satisfying . Thus uniqueness fails. On a finite arbitrage-free market, completeness is equivalent to uniqueness of the equivalent martingale measure.
Past exam of the mathematics course of the University of Cambridge 2004 iii Paper 33 6 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For pure strategy sets and utility functions , a Nash equilibrium is a strategy profile such thatFor mixed strategies, replace payoffs by their expectations under independent randomization and allow each player to choose any probability distribution. Since expected utility is linear in a player's own distribution, checking all pure deviations suffices.
Pure equilibria need not exist. In matching pennies, player 1 receives for equal choices and for different choices, while player 2 receives the negative. At an equal pair, player 2 improves by switching; at a different pair, player 1 improves by switching. Thus no pure profile is a Nash equilibrium.
In the ranked university application game, every student must be admitted at a pure equilibrium. If someone were rejected, fewer than the total 50000 seats would be filled, so another university would have a vacancy. Moving there gives positive benefit instead of zero. Consequently all 50 universities have exactly 1000 applicants and admit all of them.
Choose a university with largest arithmetic mean admitted rank and let be its lowest rank. If an outside student of rank moved there, that student would be admitted in place of ; the new arithmetic mean would exceed the university's previous arithmetic mean, which was at least the student's current payoff. This is a profitable deviation. Therefore no higher rank is outside: that university consists of the highest 1000 ranks. Remove that block and repeat with the remaining university of largest arithmetic mean. At each step the same argument excludes omitted higher ranks from the remaining set. The admitted cohorts are necessarily the consecutive blocks
Conversely, assigning these blocks to labelled universities is an equilibrium. A student moving to a higher block is rejected. A student moving to a lower block displaces its lowest rank; all the other admitted ranks there are below every rank in the student's original block. Comparing the two arithmetic means with that student's own rank held fixed shows a strict loss. Thus every block assignment is an equilibrium, and the preceding argument excludes all other pure ones:
There is more than one further mixed equilibrium. We give two genuinely mixed profiles, rather than count the pure equilibria as degenerate mixed ones. First, let every student apply independently and uniformly to all 50 universities. For each fixed student the other players' distribution is invariant under every permutation of university labels. All 50 pure applications therefore give the same expected utility. Uniform mixing is a best response, so this is a Nash equilibrium.
For a distinct mixed equilibrium, assign each of the 48 highest consecutive rank blocks deterministically to a different university. Let each of the lowest 2000 students independently choose either of the two remaining universities with probability . For a low-ranked student these two universities have identical expected utility by label symmetry, and that payoff is positive: there is a positive-probability event on which the student is admitted. Applying to one of the 48 full higher-ranked blocks would guarantee rejection. Hence the specified mixture is a best response.
For a student in a deterministic higher block, moving to another deterministic block loses by the pure-equilibrium comparison above. It remains to rule out a move to a mixed university. Let the student's own block start at , and let their rank be . Their present payoff is . The number of low-ranked applicants at a specified mixed university has a binomial distribution with parameters , and the higher-ranked deviator is always admitted. If , all other admitted ranks are at most 2000, so the new arithmetic mean is at most , and thus at most . If , it is . Therefore the expected deviation payoff is at mostbecause the gap without the last term is . No such deviation improves the payoff. This proves a second mixed equilibrium, with only the lowest 2000 students randomizing. It is visibly different from the fully uniform profile. In particular,
Past exam of the mathematics course of the University of Cambridge 2004 iii Paper 33 5 a by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14 Past exam of the mathematics course of the University of Cambridge 2004 iii Paper 33 4 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For a transferable utility game, the characteristic function of a coalitional game assigns a coalition its largest total attainable revenue , with . The core of a cooperative game consists of payoff vectors satisfying efficiency, , and coalition stability, for every . A coalition receiving less could operate alone and distribute its extra value to make each member better off.
Use thousands of pounds as the monetary unit. The physical directed arcs are and , owned by , with capacities ; and , owned by , with capacities ; and , owned by , with capacity .
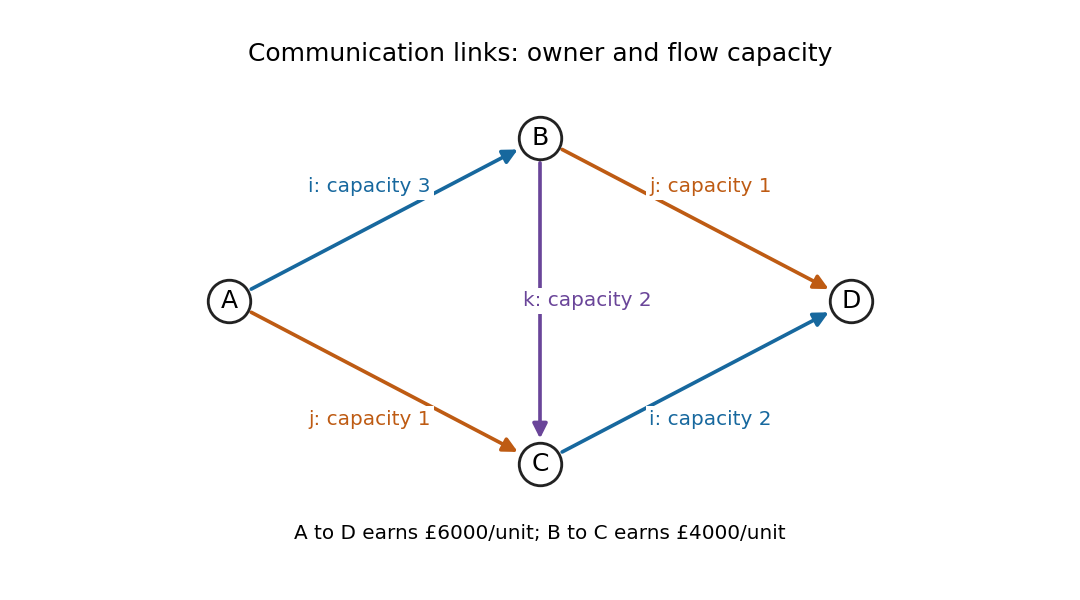
The physical network is acyclic. There are exactly three – graph paths and one – graph path. Let be the – flows on , , , respectively, and let be the direct – demand. Their capacities and revenue areEvery feasible traffic pattern decomposes into these graph paths, so these inequalities are exact. The first is redundant, since and imply it.
Formulate this as a minimum-cost flow through the two-resource path packing as minimum-cost circulation reduction. Use auxiliary vertices and the following arcs, whose entries are (capacity, cost):The first forward graph path carries , carries , carries , and carries . Conservation at imposes , and at imposes ; the individual finite-capacity arcs give the other bounds. The return arc closes the circulation. Its cost is exactly , so this is an ordinary minimum-cost circulation with precisely the required feasible traffic set. Unlimited capacities may all be replaced by , the maximum possible total graph path flow.
An linear programming optimality certificate is particularly short:The feasible choice attains equality. Thus the actual traffic is three units from to and one from to , andAll four positive terms in the bound must be tight at any optimum, so these graph path amounts are unique.
The two traffic demands must retain their identities. Merely adding fictitious return arcs and to the physical graph can create an invalid graph cycle combining both rewards: would credit the -only network with revenue even though it carries neither requested demand. The resource-flow formulation above avoids that problem.
For the characteristic function, only complete physical graph paths owned by a coalition are available. Company or alone has no requested graph path; company carries two units of – traffic. The pair carries one unit on each of ; the pair sends two units on rather than selling them at the lower – rate; and has only the two direct – units. ThereforeWriting payments in thousands, all stable divisions of the revenue are exactlyEquivalently, , and . This is the entire core, not just one acceptable allocation.
The nucleolus minimizes in lexicographic order the sorted decreasing excesses of a coalition over imputations. Empty and grand-coalition coalition excesses are fixed zeros and can be omitted. For the six other coalitions, efficiency givesThe two -related coalition excesses sum to , so their maximum is at least . This bound is attainable, and attaining it forces . All six coalition excesses are then at most precisely when and . The fixed pair of coalition excesses equals throughout these first-stage minimizers.
Minimize the largest of the remaining coalition excesses. They become , whose maximum is . Its unique minimum is at . Hence and . The sorted proper coalition excesses there are , and
Past exam of the mathematics course of the University of Cambridge 2004 iii Paper 33 3 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For a connected undirected weighted graph, a spanning tree connects all vertices without a graph cycle. A minimum spanning tree minimizes the sum of its edge weights. Disconnected input has no spanning tree, although the same methods produce a minimum spanning forest. Negative edge weights and ties cause no difficulty; a tree always contains exactly edges.
The central exchange argument is the minimum spanning tree cut property. Suppose a forest is contained in some minimum spanning tree , and consider a cut with no edge of crossing it. Let be a lightest crossing edge. If , adding it creates a graph cycle; the graph path in between its endpoints contains a crossing edge . That is not in , and . Thus is another spanning tree with no larger weight and still contains . It is also minimum and contains . This proves that the chosen edge is safe, rather than merely asserting a greedy choice.
Kruskal's algorithm sorts all edges by increasing weight, starts with the empty forest, and adds an edge precisely when its endpoints are in different components. Each added edge is lightest across a component cut respected by the current forest. The exchange proof inductively keeps the forest inside a minimum spanning tree; connectedness makes the final forest a spanning tree, hence an optimum. Sorting takes comparisons, and even a simple component-merging implementation takes only polynomial additional work. Efficient component tracking improves that overhead further.
Prim's algorithm instead grows a single tree, repeatedly adding a lightest edge from its vertex set to the outside. The same cut argument proves correctness. A dense implementation using an array runs in comparisons. The dual minimum spanning tree cycle property says a uniquely heaviest edge of a graph cycle belongs to no minimum spanning tree: exchanging it for a lighter crossing edge strictly improves any tree containing it. Ties must be handled carefully; a merely nonunique heaviest edge can occur in an optimum.
Complexity classes are formally classes of decision problems, so use the version asking whether a graph has a spanning tree of total weight at most a supplied threshold . Assume integer or rational weights and threshold are encoded in binary. The input length includes all these bits, not only the numbers of vertices and edges. P consists of decision problems decidable by a deterministic algorithm in time polynomial in that input length. NP consists of those with polynomial-size complexity certificates verified in deterministic polynomial time, equivalently decidable in polynomial time by a nondeterministic machine.
Kruskal's algorithm constructs the optimum and compares its weight with . Binary integer comparisons and sums are polynomial-time operations. Rational comparisons can be made by cross multiplication, and their summed numerator and denominator have polynomially bounded bit length: a product of input denominators has bit length no greater than the sum of their bit lengths. The combinatorial algorithm makes polynomially many such operations. Hence the minimum-spanning-tree decision problem is in P; the optimization version likewise has a polynomial-time algorithm.
For membership in NP, the complexity certificate is a list of selected edges. Check that every edge is present, that the edges connect all vertices and contain no graph cycle, and that their total weight is at most . A graph search and binary arithmetic do this in polynomial time. A successful complexity certificate need not establish that its tree is minimum: it proves the threshold question's yes-answer. Conversely, a yes-instance has such a tree as a complexity certificate. ThereforeMembership in NP does not arithmetic mean NP-hardness; here the explicit greedy algorithm provides the stronger tractability result.
Past exam of the mathematics course of the University of Cambridge 2004 iii Paper 33 2 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Given a feasible network flow , an original directed edge has forward residual capacity and a reverse residual arc of capacity . A source–sink graph path in this residual network permits an augmentation by the minimum residual capacity along it: increase forward flows and decrease the corresponding reversed flows. Capacities and flow conservation are preserved, and the flow value increases by that amount.
If no residual source–sink graph path exists, let be the vertices reachable from the source. The sink is outside . Every original arc from to its complement is saturated, and every original arc back into has zero flow, since a positive reverse residual arc would make its tail reachable. Conservation therefore givesThe flow equals this cut capacity, so the max-flow min-cut theorem proves it is maximum.
Termination needs a capacity or path-selection assumption. For integer capacities, starting from zero, every residual capacity and augmentation is integral; each augmentation increases the value by at least one, and the value is bounded by the total source-outgoing capacity. The algorithm therefore terminates. Rational capacities can be scaled to integers. With arbitrary real capacities, unrestricted graph path choices do not guarantee finite termination. A valid uniformly terminating implementation is the Edmonds–Karp algorithm, choosing a shortest residual graph path each time.
Here is why that choice works independently of numerical capacity sizes. Residual distances from the source cannot decrease after augmenting along a shortest graph path. Every newly created residual arc is the reverse of a graph path arc; if it could cause the first distance decrease, its previous distance relation would contradict that decrease. When an arc is saturated on a shortest graph path, . Before the same direction can be saturated again, it must have been restored by a reverse augmentation on a shortest graph path, at which time . Each arc is consequently critical only times. There are arcs and each augmentation saturates at least one, giving augmentations, each found by breadth-first search in time. Thus the shortest-path Ford–Fulkerson implementation terminates and finds a maximum flow in arithmetic operations.
For sports elimination by maximum flow, first give the target team all its remaining wins. This cannot hurt its chance to finish strictly ahead: changing a result to favour it also removes a rival's win. Let be its resulting win count. If any rival already has at least wins, strict victory is impossible. Otherwise give each unordered pair of rivals one game node. Its incoming capacity is , and its two outgoing arcs go to the participating team nodes. Their capacities may be replaced by the finite numbersince no arc can need more than the total number of remaining rival games. Team has sink capacity .
An integral flow of value saturates all game-node incoming arcs. Its two outgoing amounts allocate exactly wins to the two teams; the team-sink caps keep each rival strictly below . Conversely any successful completion of the league specifies such a flow. Integral capacities and augmentation give an integral maximum flow, soafter the initial negative-capacity rejection. Each actual game is counted once: making independent nodes for both ordered pairs would double-count it.
The network has nodes and arcs. If each input integer has at most bits, its derived capacities have bits. The shortest-path algorithm above uses arithmetic operations, each on integers of polynomial bit length. Therefore the decision problem belongs to P, even with part of the input. If is fixed, even the basic integral-augmentation bound is polynomial in . If varies, that particular bound is only pseudopolynomial; it is the shortest-path implementation that establishes polynomial bit complexity.
Past exam of the mathematics course of the University of Cambridge 2004 iii Paper 33 1 a by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14 Past exam of the mathematics course of the University of Cambridge 2004 iii Paper 32 6 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Fix the noise convention explicitly: is the total probability of a nonidentity Pauli error. The memoryless qubit quantum depolarizing channel iswith independent identical use on successive qubits, namely on an -qubit block. Its normalized Kraus operators are .
Write the Bloch sphere representation of a density matrix as , with . Its eigenvalues are , proving exactly this positivity condition. Conjugation by one Pauli operator preserves that coordinate of the Bloch vector and reverses the other two. Summing the three conjugations givessoThe Bloch ball contracts isotropically, collapses to the maximally mixed state at , and contracts with reversal for . That last interval still represents a physical Pauli mixture. If instead is the probability of replacing the state by , then , with and ; the usual replacement-probability range stops at complete depolarization.
Let , with endpoint limits. In bits per use, the unassisted product-state classical capacity and the entanglement-assisted capacity of a qubit depolarizing channel arewhere is Shannon entropy of the listed four probabilities. Equivalently . The first quantity is a classical capacity with product quantum inputs and potentially collective output measurements, not the quantum capacity. These are the requested capacity formulae; a proof of their coding theorems is not needed here. The maximally entangled input gives a Bell-diagonal joint state with those four probabilities, explaining the entropy appearing in . The original entanglement-assisted capacity calculation gives the depolarizing-channel expression.
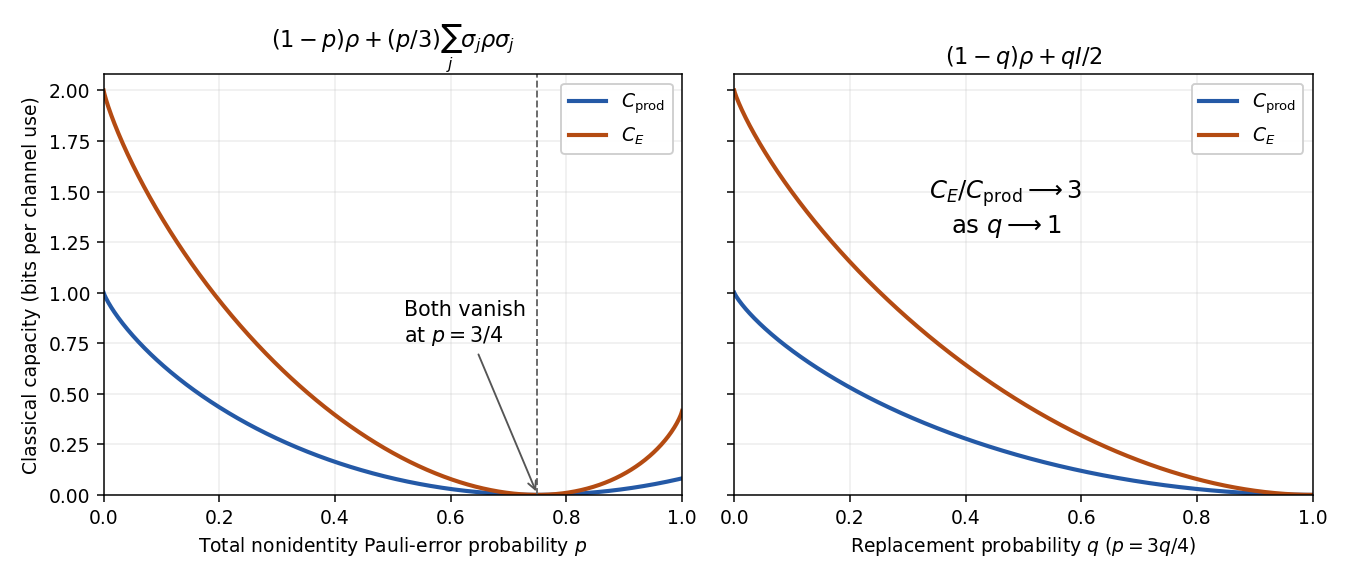
Product-state and entanglement-assisted classical capacities under Pauli-error and replacement-probability conventions
. Details. At the capacities are one and two. Both vanish at . On the full Pauli-error interval they increase again beyond that point, reaching and at ; on the replacement-probability plot both decrease to zero at . The two panels make this convention distinction explicit.
For the high-noise capacity ratio for qubit depolarization, put . Taylor expansion of binary entropy around one half givesThe four probabilities for are and three copies of . For a perturbation of the uniform four-outcome distribution, with , entropy expansion givesHere , hence . ThereforeThe reciprocal ratio is , and the same enhancement factor occurs as in the replacement convention.
Past exam of the mathematics course of the University of Cambridge 2004 iii Paper 32 5 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The Schumacher compression theorem concerns a memoryless quantum information source with average density matrix on a finite-dimensional Hilbert space. For uses the average state is . Compression consists of an encoding quantum channel into a space of dimension and a decoding channel back to the original block space, with asymptotic rate qubits per source use. The optimal reliable rate is : every larger rate is achievable, and no smaller rate is reliable. This holds for average pure-source fidelity; the direct construction also preserves a purification reference, and the converse for that stronger entanglement fidelity criterion holds with fidelity tending to zero below the threshold. The encoding and decoding are deterministic channels; no free classical transmission of the source label is allowed.
Diagonalize and omit zero-probability eigenvalues when sampling. Define the quantum typical subspace projector by retaining product eigenvectors withThe sampled random variable has expectation . The weak law of large numbers gives . Every retained eigenvalue is at least , and the total probability is at most one, soThis proves the two typical subspace theorem estimates used in the direct part.
Write . Encode its range isometrically into a compressed space and reserve one orthogonal failure flag. Decode the range back isometrically and the failure flag to a fixed pure state . This typical-subspace compression with a failure flag is a physical channel whose composite action isIndeed its Kraus operators are and , where the form an orthonormal basis of , and their adjoint products sum to . The Kraus formula for entanglement fidelity givesFor any pure-state ensemble of , the average squared quantum fidelity is at least this number: apply convexity of separately to the amplitudes with their source probabilities. Thus average fidelity also tends to one. The compressed dimension is at most , and its rate is at most . Choose for any prescribed . One may also take : the finite spectral information variance and Chebyshev's inequality still give , with rate tending to . A pure source, , can simply be re-prepared exactly without sending any qubits.
For the coherent converse, we prove the finite-dimensional quantum compression converse. If the compressed space has dimension , the state of reference plus compressed system has a pure-state decomposition with Schmidt rank at most . Applying decoder Kraus operators locally cannot increase the Schmidt rank of those vectors, so the final reference–output state has Schmidt number at most . Let purify the source, with squared Schmidt coefficients equal to the decreasing eigenvalues of . For any normalized vector of Schmidt rank at most , its reference support lies in a rank-at-most- projector . HenceThe last bound follows by maximizing subject to and their sum at most . Average over a Schmidt-rank-bounded decomposition of the final state to obtain .
At rate , choose . The total source probability outside the quantum typical subspace tends to zero, while every eigenvalue inside it is at most . Therefore for ,This argument allows arbitrary encoding and decoding channels, not only subspace projection.
For completeness, average pure-source reliability also forces the same rate, even though it is a weaker criterion than entanglement fidelity. Here is a separate converse for that formulation. Let the emitted block pure states be , with probabilities , and let be the decoded states. If their mean squared fidelity tends to one, then their mean trace distance tends to zero, since . This inequality follows by choosing a purification with that overlap and using contraction of trace distance under a partial trace.
We need only an elementary entropy continuity from Jordan decomposition bound, derivable from Question 4. If , write the positive and negative parts of as . The common density matrixand the two mixture bounds giveHere is increasing and concave, . Apply this in block dimension , both to the average states and to individual outputs, using convexity of trace distance and concavity of . Since the original ensemble is pure, its Holevo quantity is . The decoded ensemble hasThe Holevo quantity under a quantum channel cannot increase. To specify the entropy ingredient, Strong subadditivity of Von Neumann entropy states . Attach the classical source label , dilate the decoder isometrically to , and trace out . The displayed inequality says ; the isometry preserves the input mutual information. Since of a labelled ensemble is its Holevo quantity, this proves the needed decoder monotonicity. Before decoding, the system has dimension , so its Holevo quantity is at most . Thus and the rate cannot be below . Both operational fidelity formulations therefore have the claimed noiseless coding threshold.
Past exam of the mathematics course of the University of Cambridge 2004 iii Paper 32 4 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For a density matrix on a -dimensional Hilbert space, its Von Neumann entropy, in bits, iswhere the are its eigenvalues and . Each summand is nonnegative, proving , with equality exactly when one eigenvalue is one and the rest zero, namely for a pure state.
We first prove the nonnegativity of quantum relative entropy needed below. Diagonalize with eigenvalues and eigenvectors , and with eigenvalues and eigenvectors . Put and . Each row of sums to one. Concavity of the ordinary logarithm gives . ConsequentlyThe final Gibbs inequality follows directly from . Support failure gives ; zero eigenvalues can otherwise be handled by restriction or regularization. Equality requires and equality in the logarithm inequality on every positive-weight row. Thus is a eigenvector of eigenvalue wherever . The remaining diagonal entries of vanish and positivity makes the remaining rows and columns zero. Hence equality holds exactly when .
Taking gives , provingThe lower equality is attained exactly by pure states and the upper exactly by the maximally mixed state .
For , each positive-weight state has support contained in that of . Expanding the quantum relative entropy givesThis proves Concavity of Von Neumann entropy, with equality precisely when every positive-weight is the same state.
For the upper entropy bound for a quantum mixture, diagonalize each component, , and set . Form the rectangular matrix whose columns are . Then , while the Gram matrix has diagonal . The two matrices have the same nonzero eigenvalues: and map corresponding positive-eigenvalue eigenspaces isomorphically. Thus .
If there are columns, let , with . ThenAll the summands have the same Von Neumann entropy. The just-proved concavity therefore implies . Finally,We have proved both requested bounds:For the upper equality, strictness in the concavity argument forces to be diagonal. Its entries between two positive-weight component eigenvectors then force those vectors to be orthogonal. Thus upper equality holds exactly when the supports of the positive-weight component states are mutually orthogonal. In that case their classical label is perfectly distinguishable, explaining the extra bits.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact