Topics (374k) Articles (387k) Users (410) Discussions (242) Comments (383) Files (12k) New article

For a cusp form and coprime integers , the additive twist inserts the additive character . It is the Dirichlet series associated with the rational translate . Its completed Mellin transform uses the scale and the Gamma function.
In the Known-variance Gaussian mixture EM example, initialize both means at the same value . The mixture responsibilities are then for every observation. Each M-step sets both means to the sample mean, zero here; the next E-step again gives . Thus is a fixed point with log-likelihood , despite the better fit found from .
One can check the failure without trusting an iteration plot. Separate the means as and use the hyperbolic cosine identity:The Taylor expansion uses . Small nonzero separation therefore improves the log-likelihood, whereas translating both means to changes it by . This stationary point has both improving and worsening directions. Identical initialization cannot discover the separation because every observation keeps identical label probabilities. Trying several distinct initial fits and comparing their final log-likelihoods is useful, but does not prove global optimality.
Keeping the variance fixed also removes a different pathology. With known , every component probability density function is at most , so . If separate component variances are allowed to shrink without restriction, one mixture component can concentrate at an observation while another retains positive density at the other observations, making the likelihood function unbounded. The fixed positive variance in this example prevents that collapse; it does not remove initialization traps.
In coalescent units, independent waiting times satisfy , and total branch length is . Therefore . The variables are independent exponentials with rates , so has the same distribution as the maximum of independent unit exponentials, with density . The last identity follows either from its Laplace transform or from the independent spacings of exponential order statistics.
In Kingman's coalescent, the epoch with ancestral lineages lasts , independently across epochs. If each lineage carries an independent Poisson process of mutations with rate , its epoch mutation count satisfies . The total mutation count is . Under the infinite sites mutation model, this also counts segregating sites; without that assumption it still counts mutation events, which need not correspond one-to-one to observed polymorphisms.
For normalized Legendre polynomials, this kernel for density estimation reproduces evaluation at zero on every polynomial of degree below : expand in the orthonormal basis to obtain . Taking monomials proves integral one and zero moments of orders ; compact support gives finite absolute moments. If exact order requires a nonzero moment of order , add . Lower moments remain unchanged. Writing and evaluating the full expansion of at zero shows that the new moment is . A useful three-derivative example is , whose first two moments vanish and whose squared L2 norm is .
Suppose a probability density function and its third derivative are bounded. A square-integrable unit-integral kernel for density estimation with first two moments zero and has bias of a kernel density estimator at most , by Taylor theorem with Lagrange remainder and moment cancellation. Independence gives variance at most . The Cauchy-Schwarz inequality bounds the expected centred absolute deviation by the square root of this variance. Adding the bias proves the inequality uniformly in . The choice gives expected absolute error .
Let the kernel for density estimation have integral one, be bounded and have compact support. For a probability density function with bounded derivative, assume , and . The bias of a kernel density estimator is , negligible on the scale. For , . The centered summands divided by are uniformly small, so the Lindeberg-Feller central limit theorem applies. The condition alone is insufficient: with and a compactly supported kernel, with probability tending to one no observation enters the kernel window, producing a degenerate limit at a point with positive density.
For a nonnegative symmetric unit-integral kernel for density estimation with and , the canonical scaling satisfies . Since and , the unique scale is . Consequently its asymptotic mean integrated squared error is , where is invariant under kernel rescaling. The leading optimal smoothing bandwidth becomes , independent of the kernel shape. Unit second moment is a different normalization and does not have this separation property.
For a second-order kernel density estimator, if and , the leading pointwise asymptotic mean squared error is . Differentiation gives the displayed interior optimum. At a zero of , the leading variance term vanishes and this two-term approximation has no positive interior minimizer; at a zero of , a higher-order bias expansion is needed.
For independent observations with common density f, the kernel density estimator has mean . Its pointwise variance is . Integrate the variance and add integrated squared bias to get the displayed exact mean integrated squared error, assuming the integrals are finite. Since , this also separates the smoothing bias from the stochastic variance.
Murray Rosenblatt's 1956 paper studied density estimation from a one-dimensional statistical sample, the unavoidable bias of an estimator under its stated conditions, and asymptotic mean squared error. It is an early foundation of kernel density estimation. [ref]
https://doi.org/10.1214/aoms/1177728190. Rosenblatt, Remarks on Some Nonparametric Estimates of a Density Function, Annals of Mathematical Statistics 27(3), 832-837 (1956)
. Emanuel Parzen's 1962 paper developed statistical consistency and asymptotic normality for probability density function estimates and studied estimation of the mode. [ref]https://doi.org/10.1214/aoms/1177704472. Parzen, On Estimation of a Probability Density Function and Mode, Annals of Mathematical Statistics 33(3), 1065-1076 (1962)
.The authors' interests help explain the connection with smoothing. In a conversation recorded in 2006 and published in 2009, Rosenblatt recalled that his density estimation work grew out of estimation of the time-series spectral density and emphasized the connection with a smoothed histogram. This is his retrospective account of the motivation. [ref]
https://celebratio.org/Rosenblatt_M/article/891/. Brillinger and Davis, A conversation with Murray Rosenblatt, passage immediately before The Chicago, Indiana and Brown years
. Parzen's original paper lists Stanford University as his affiliation; its opening frames the problem as recovering both a probability density function and its mode from independent and identically distributed random variables. [ref].Take the realized statistical sample , the Gaussian density kernel and smoothing bandwidth . ThenAt , the three contributions are , , and , because and . Their sum isThis is a probability density function value, not the probability of observing exactly zero. Each of the three component curves has area , despite having a different height at zero.
Let be the cumulative distribution function of the standard normal distribution. The fitted probability of the interval is its area under the kernel density estimator:The shaded area in the diagram is this fitted probability. Its agreement to a few digits with is incidental: the empirical measure gives this interval mass exactly, whereas kernel density estimation redistributes that mass into neighboring intervals.
For an axisymmetric thin disc supplied at with the local Keplerian rotation specific angular momentum, the displayed source augments the Keplerian viscous diffusion equation. The radial velocity remains : subtracting local specific angular momentum times conservation of mass from conservation of angular momentum cancels the source term. The normalization of the Dirac delta function makes the integrated supplied mass per unit time equal to .
The relative skein module fixes finitely many framed endpoints on the boundary of a 3-manifold and uses properly embedded framed tangles with those endpoints. Local Kauffman bracket relations are imposed away from the boundary. Gluing compatible endpoint sets composes tangles; a rectangle cylinder with n endpoints on each horizontal side gives the Temperley-Lieb diagram algebra.
Here is the crossing count and is the number of connected components of the planar link diagram, not necessarily the number of link components. The all- and all- state counts satisfy , by summing the Turaev surface Euler characteristic bound over projection components. The Kauffman bracket breadth bound and give the displayed bound. It is sharp for an unlink diagram with , whose Jones polynomial has breadth of a Laurent polynomial .
For unforced homogeneous turbulence with isotropic turbulence statistics, put and . The longitudinal Kármán-Howarth equation is . Since , regularity at zero givesNeglecting the last term in a locally equilibrated small-scale range gives the displayed equation. The Kolmogorov four-fifths law follows where the viscous term is negligible as well.
For an infinite cardinal , the tree property says that every tree of height with nonempty levels of cardinality less than has a cofinal branch. In the all-trees-of-size- convention it also forces regularity: disjoint chains of lengths cofinal in a singular form a counterexample. It does not, by itself, imply strong inaccessibility. A strong limit cardinal with the tree property satisfies the self-partition relation by applying it to the end-homogeneous coloring tree. At a strongly inaccessible cardinal this is the usual weak-compactness characterization.
For a real scalar field with canonical field normalization, impose . The Källén–Lehmann spectral representation also represents its vacuum commutator as the weighted sum of free commutators. The equal-time derivative of each free commutator is independently of mass. Comparison therefore gives the displayed sum rule, whenever the canonical commutator and spectral integral admit this distributional limit. Since the measure is nonnegative, an isolated one-particle weight obeys , and is strictly positive if the field couples to that particle. Arbitrary rescaling of the field rescales the total spectral weight, so positivity alone does not imply this normalization or upper bound.
With fixed neighbor positions, independent equal-variance errors and weights , the displayed variance is minimized at , with value . Its bias is . Larger nearest-point weight often reduces smoothing bias, but neither the bias nor the variance is universally monotone over . If the nearest point is the target, the squared bias is .
// Target: probability-and-statistics.bigb
Resolve the two crossings in a skein relation using the Kauffman bracket, then correct by the writhe of a link diagram. The other smoothing cancels, leaving the displayed coefficient of the oriented smoothing. This relation and the value one on the unknot determine the Jones polynomial: crossing changes give descending diagrams, which are unlinks, while the smoothing terms have fewer crossings.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.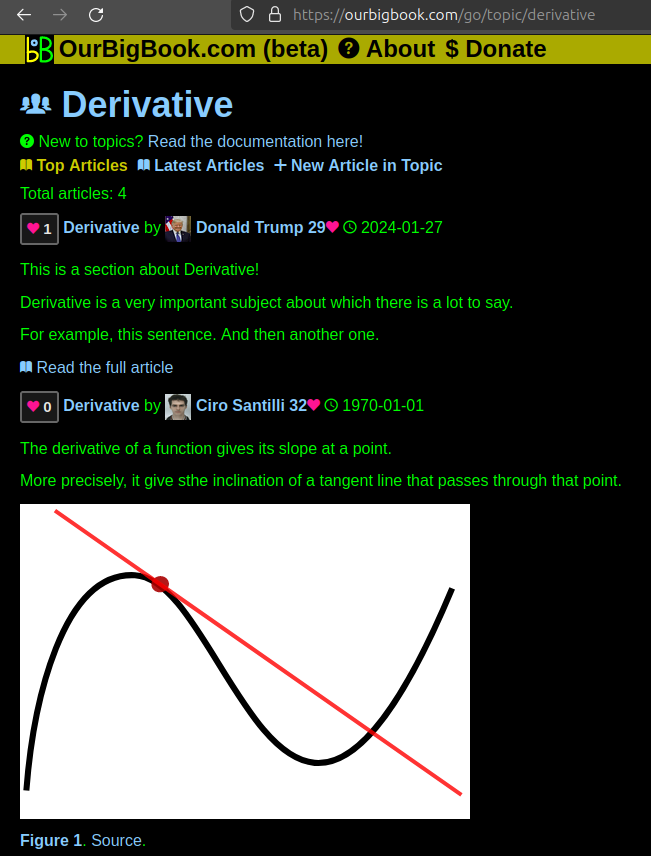
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control
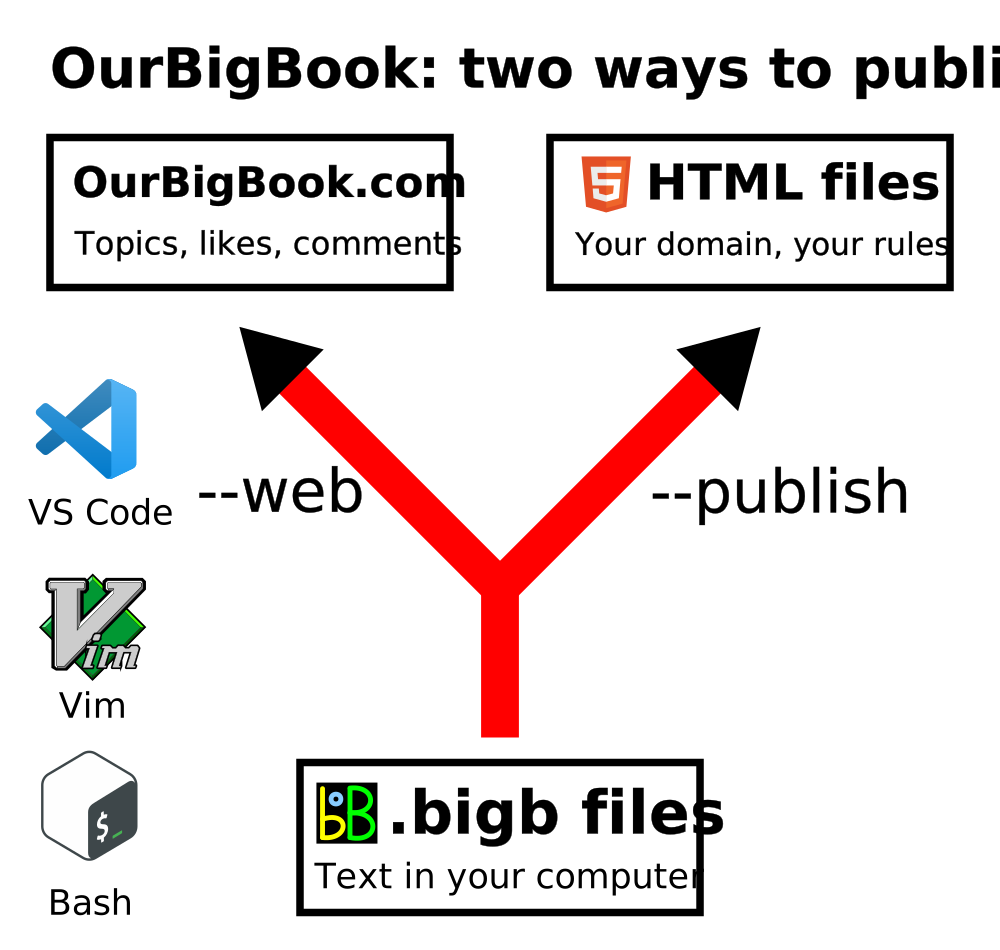
Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.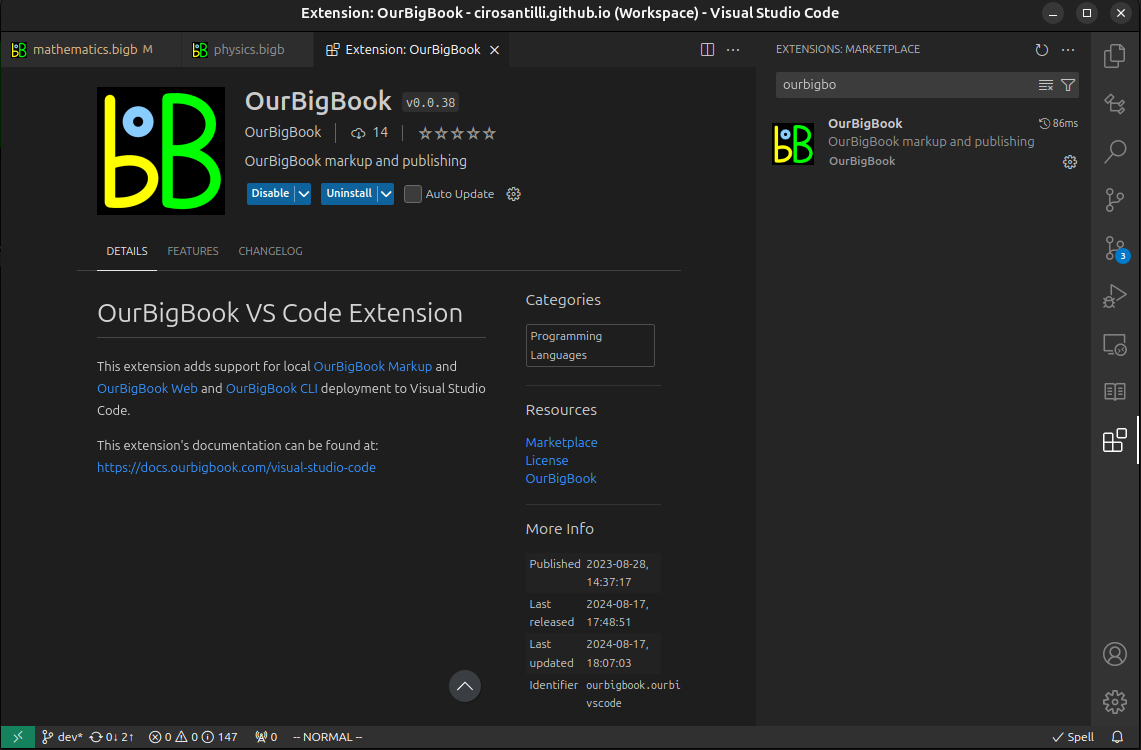
Figure 3. Visual Studio Code extension installation.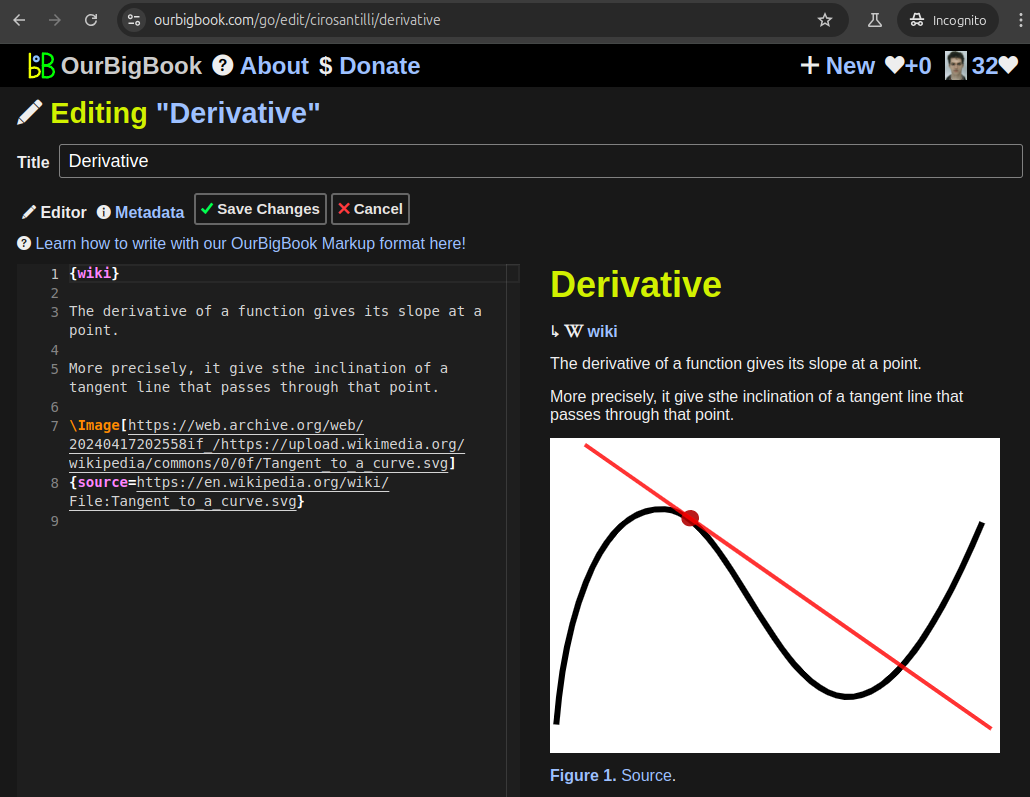
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 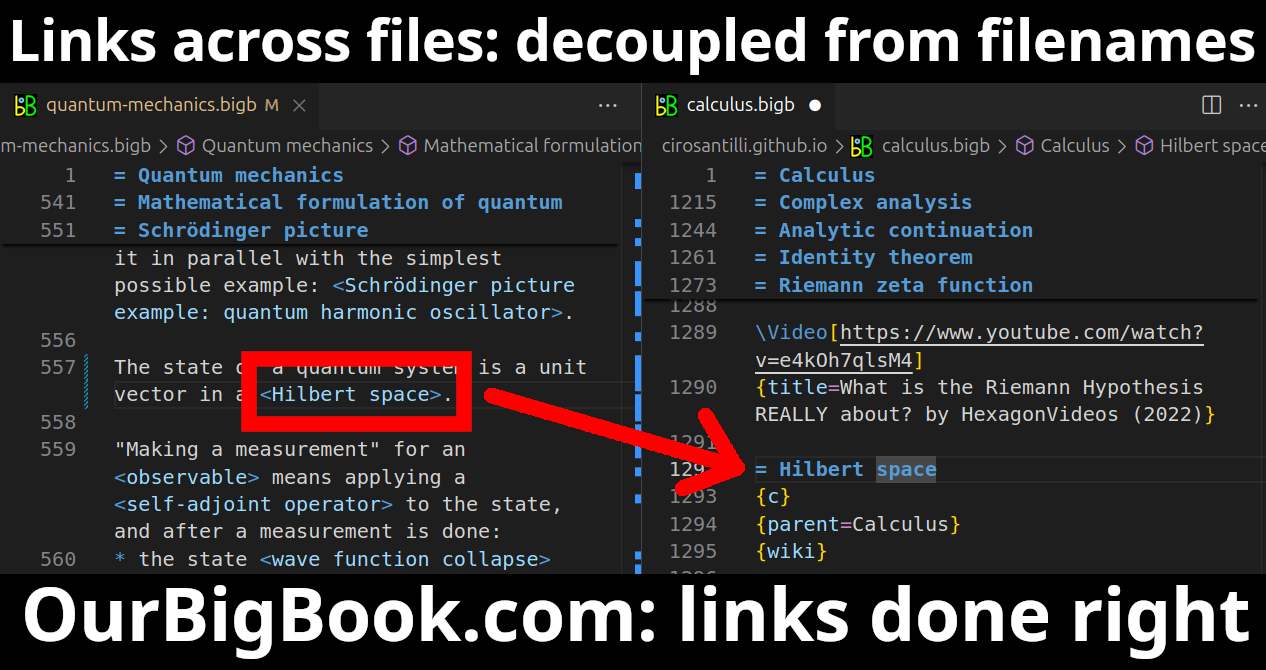
- Infinitely deep tables of contents:
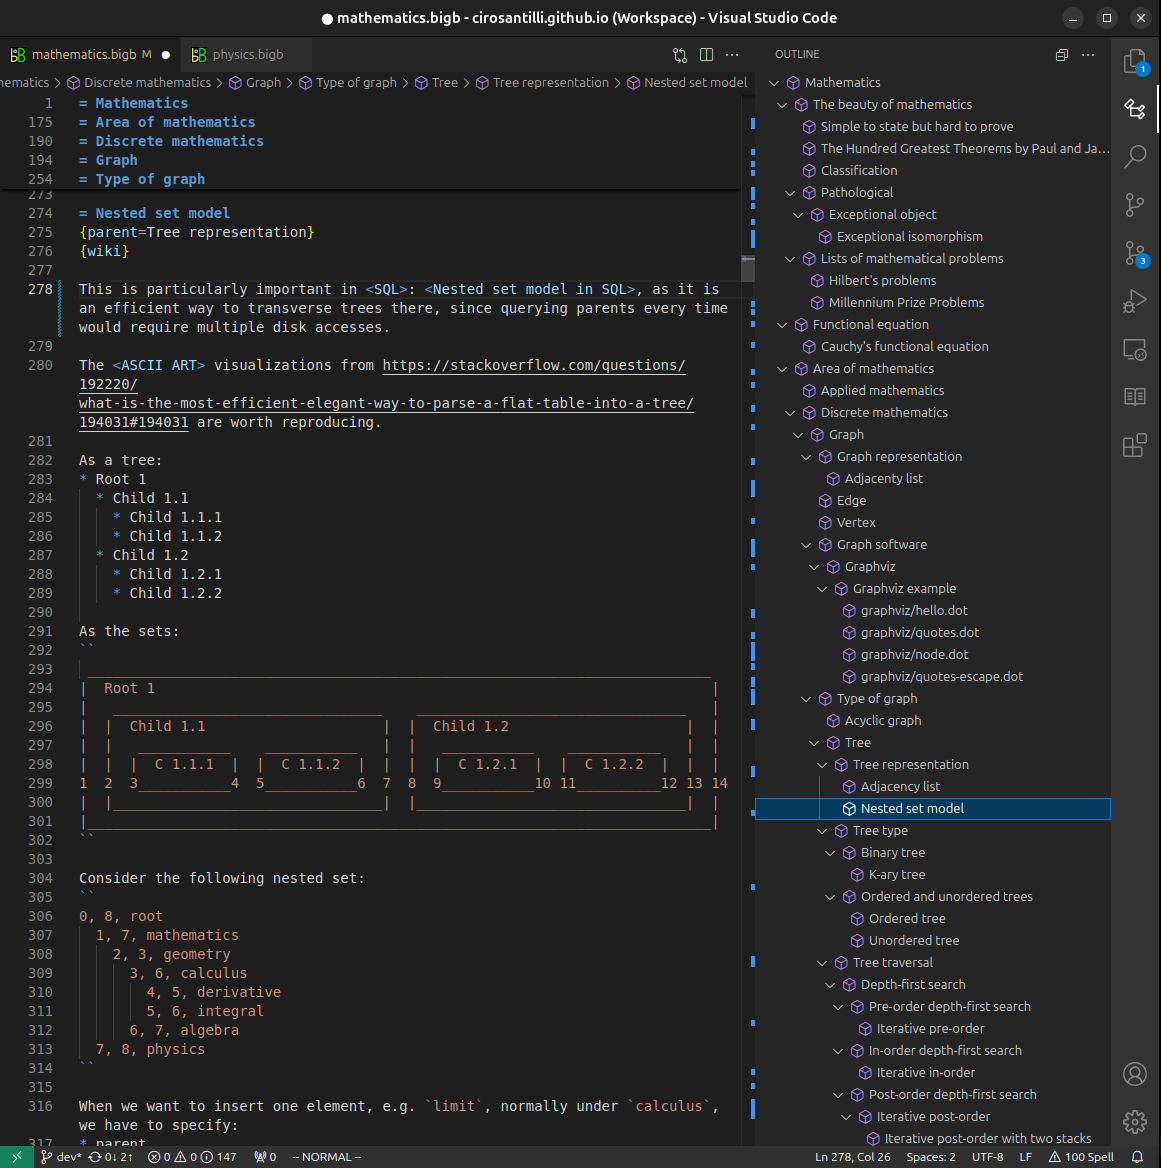
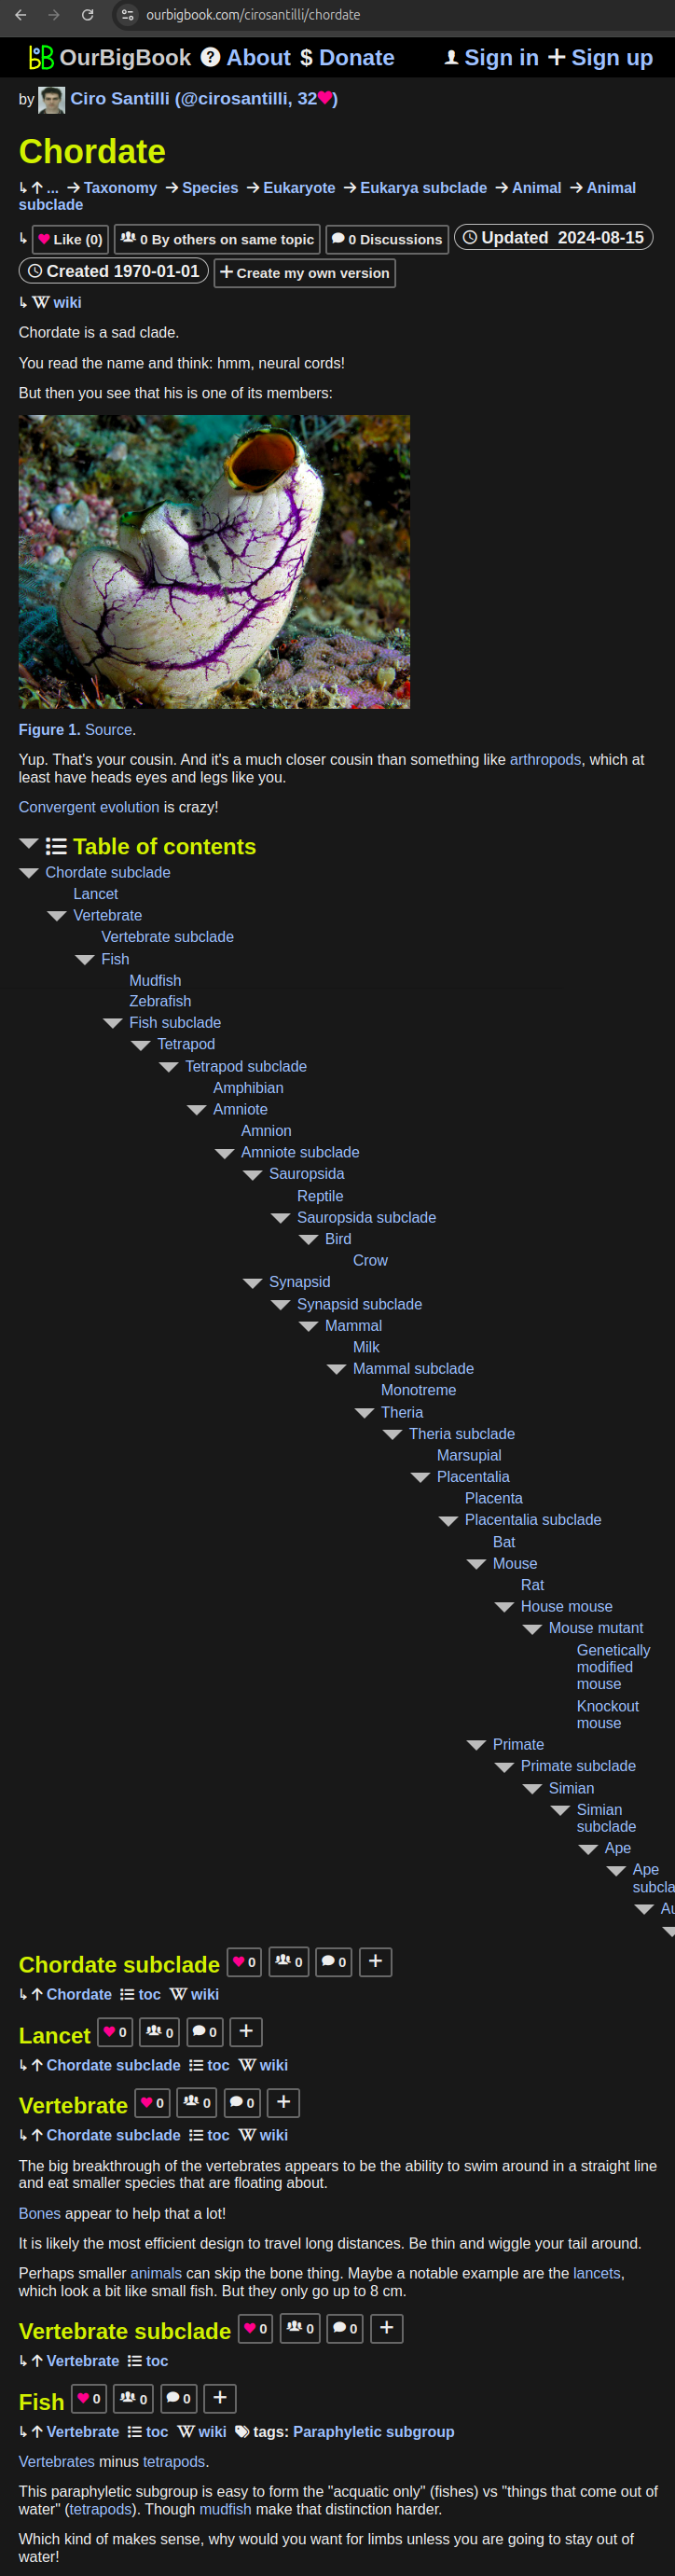
All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact