Topics (119k) Articles (119k) Users (270) Discussions (237) Comments (383) Files (706) New article
How to use an Oxford Nanopore MinION to extract DNA from river water and determine which bacteria live in it PCR by  Ciro Santilli 40 Updated 2026-08-21
More generic PCR information at: Section "Polymerase chain reaction".
Because it is considered the less interesting step, and because it takes quite some time, this step was done by the event organizers between the two event days, so participants did not get to take many photos.
PCR protocols are very standard it seems, all that biologists need to know to reproduce is the time and temperature of each step.
This process used a Marshal Scientific MJ Research PTC-200 Thermal Cycler:

We added PCR primers for regions that surround the 16S DNA. The primers are just bought from a vendor, and we used well known regions are called 27F and 1492R. Here is a paper that analyzes other choices: academic.oup.com/femsle/article/221/2/299/630719 (archive) "Evaluation of primers and PCR conditions for the analysis of 16S rRNA genes from a natural environment" by Yuichi Hongoh, Hiroe Yuzawa, Moriya Ohkuma, Toshiaki Kudo (2003)
One cool thing about the PCR is that we can also add a known barcode at the end of each primer as shown at Code 1. "PCR diagram".
This means that we bought a few different versions of our 27F/1492R primers, each with a different small DNA tag attached directly to them in addition to the matching sequence.
This way, we were able to:
- use a different barcode for samples collected from different locations. This means we
- did PCR separately for each one of them
- for each PCR run, used a different set of primers, each with a different tag
- the primer is still able to attach, and then the tag just gets amplified with the rest of everything!
- sequence them all in one go
- then just from the sequencing output the barcode to determine where each sequence came from!
Input: Bacterial DNA (a little bit)
... --- 27S --- 16S --- 1492R --- ...

|||
|||
vvv

Output: PCR output (a lot of)
Barcode --- 27S --- 16S --- 1492R
Code 1.
PCR diagram
. Finally, after purification, we used the Qiagen QIAquick PCR Purification Kit protocol to purify the generated from unwanted PCR byproducts.
How to use an Oxford Nanopore MinION to extract DNA from river water and determine which bacteria live in it Sequencing by Ciro Santilli 40 Updated 2025-07-16
Ciro Santilli 40 Updated 2025-07-16 How to use an Oxford Nanopore MinION to extract DNA from river water and determine which bacteria live in it Bioinformatics by Ciro Santilli 40 Updated 2025-07-16
Ciro Santilli 40 Updated 2025-07-16Because Ciro's a software engineer, and he's done enough staring in computers for a lifetime already, and he believes in the power of Git, he didn't pay much attention to this part ;-)
According to the eLife paper, the code appears to have been uploaded to: github.com/d-j-k/puntseq. TODO at least mention the key algorithms used more precisely.
Ciro can however see that it does present interesting problems!
Because it was necessary to wait for 2 days to get our data, the workshop first reused sample data from previous collections done earlier in the year to illustrate the software.
First there is some signal processing/machine learning required to do the base calling, which is not trivial in the Oxford Nanopore, since neighbouring bases can affect the signal of each other. This is mostly handled by Oxford Nanopore itself, or by hardcore programmers in the field however.
After the base calling was done, the data was analyzed using computer programs that match the sequenced 16S sequences to a database of known sequenced species.
This is of course not just a simple direct string matching problem, since like any in experiment, the DNA reads have some errors, so the program has to find the best match even though it is not exact.
The PuntSeq team would later upload the data to well known open databases so that it will be preserved forever! When ready, a link to the data would be uploaded to: www.puntseq.co.uk/data
How to use an Oxford Nanopore MinION to extract DNA from river water and determine which bacteria live in it Conclusions by Ciro Santilli 40 Updated 2025-07-16
Ciro Santilli 40 Updated 2025-07-16- against all odds, the experiment worked and we got DNA out of the water, despite a bunch of non-bio newbs actively messing with random parts of the experiment
- PuntSeq and Biomakespace people, and all those tho do scientific outreach, are awesome!
- biology is hard
- creating insanely media rich articles like this is also hard, but the following helped enormously:
- Wikimedia Commons to store large media files out of Git
- Asciidoctor extensions to easily include those media files. The lessons learnt in this article were then an important motivation for Ciro's OurBigBook Markup, to which this article was later migrated.
- Nomacs to give Google Photos photos meaningful names and to edit people's faces out of pictures ;-)
- some scientific Wikipedia pages may or may not have been edited with better pictures during the course of writing this article
How to use an Oxford Nanopore MinION to extract DNA from river water and determine which bacteria live in it External links to this page by Ciro Santilli 40 Updated 2025-07-16
Ciro Santilli 40 Updated 2025-07-16- 2021-03-25: Oxford Nanopore Technologies retweeted this article, that's awesome!
- 2021: hackaday.com/author/wd5gnr1/ "SEQUENCING DNA FOR METAGENOMICS" by Al Williams (2021). This came after Ciro Santilli self promoted at: stackoverflow.blog/2021/02/03/sequencing-your-dna-with-a-usb-dongle-and-open-source-code/#comment-1411921
Includes its own copy of sqlite3, you don't use the system one, which is good to ensure compatibility. The version is shown at: github.com/mapbox/node-sqlite3/blob/918052b538b0effe6c4a44c74a16b2749c08a0d2/deps/common-sqlite.gypi#L3 SQLite source is tracked compressed in-tree: github.com/mapbox/node-sqlite3/blob/918052b538b0effe6c4a44c74a16b2749c08a0d2/deps/sqlite-autoconf-3360000.tar.gz horrendous. This explains why it takes forever to clone that repository. People who don't believe in git submodules, there's even an official Git mirror at: github.com/sqlite/sqlite
It appears to spawn its own threads via its C extension (since JavaScript is single threaded and and SQLite is not server-based), which allows for parallel queries using multiple threads: github.com/mapbox/node-sqlite3/blob/v5.0.2/src/threading.h
Hello world example: nodejs/node-sqlite3/index.js.
As of 2021, this had slumped back a bit, as maintainers got tired. Unmerged pull requests started piling more, and
better-sqlite3 Node.js package started pulling ahead a little.- github.com/mapbox/node-sqlite3/issues/1381
FATAL ERROR: Error::ThrowAsJavaScriptException napi_throwwith Node.jsworker_threadsvsbetter-sqlite3Node.js package github.com/JoshuaWise/better-sqlite3/issues/237
Nick Leeson and the Fall of the House of Barings by Adam Curtis (1996) by Ciro Santilli 40 Updated 2025-07-16
Ciro Santilli 40 Updated 2025-07-16 Oxford Master Course in Mathematical and Theoretical Physics by Ciro Santilli 40 Updated 2025-07-16
Ciro Santilli 40 Updated 2025-07-16Isomers were quite confusing for early chemists, before atomic theory was widely accepted, and people where thinking mostly in terms of proportions of equations, related: Section "Isomers suggest that atoms exist".
Microwave only found applications into the 1940s and 1950s, much later than radio, because good enough sources were harder to develop.
One notable development was the cavity magnetron in 1940, which was the basis for the original radar systems of World War II.
How Microwaves Work by National MagLab (2017)
Source. A bit meh. Does not mention the word cavity magnetron! Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.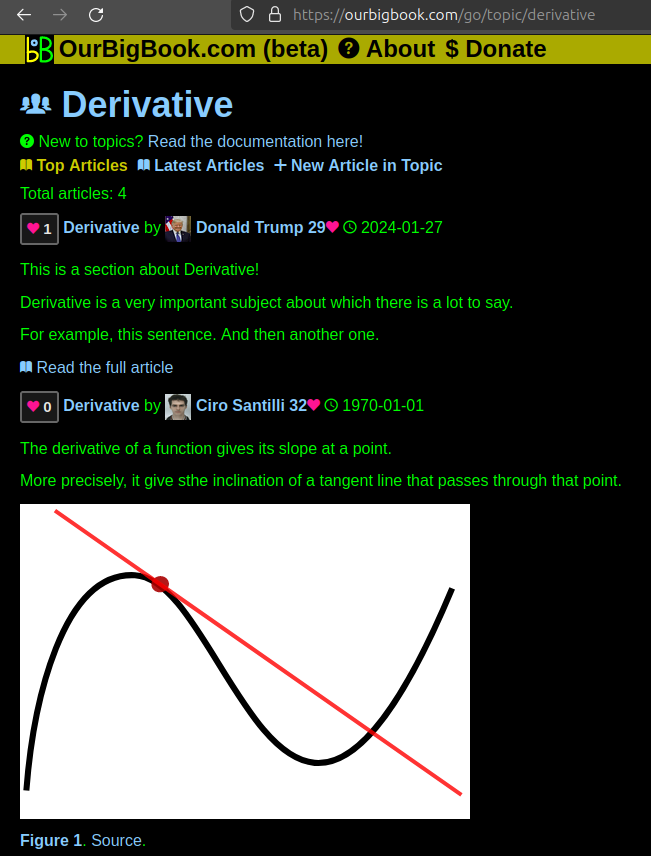
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control
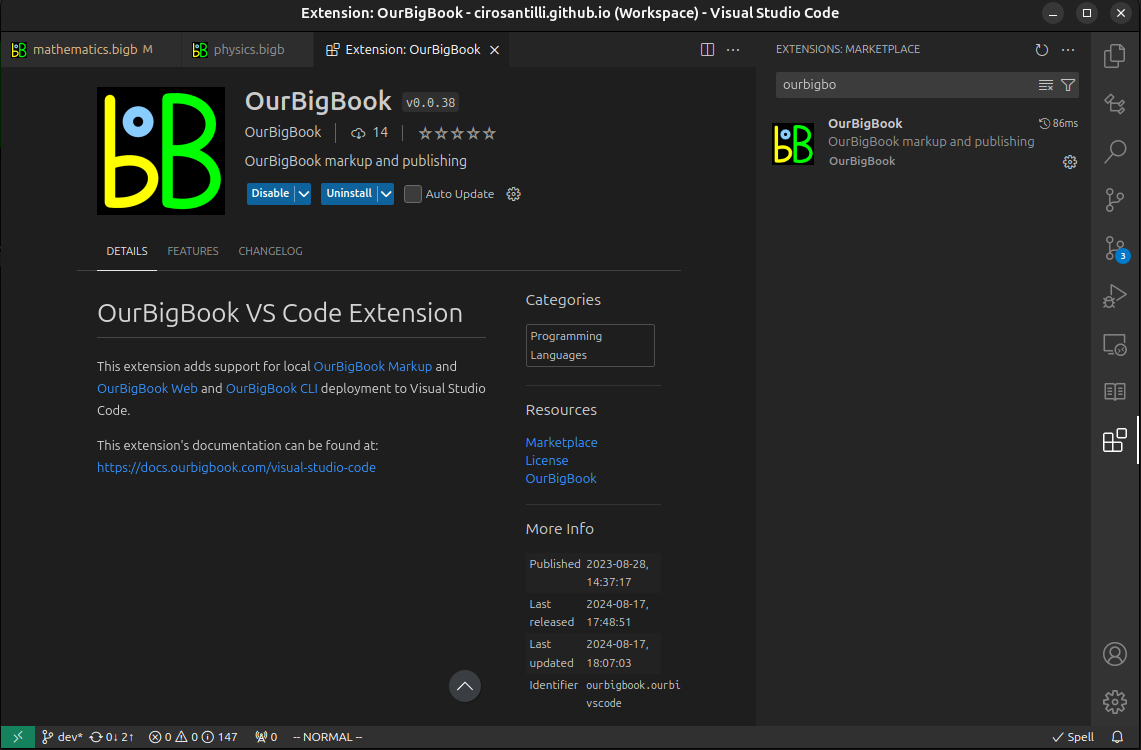
Figure 3. Visual Studio Code extension installation.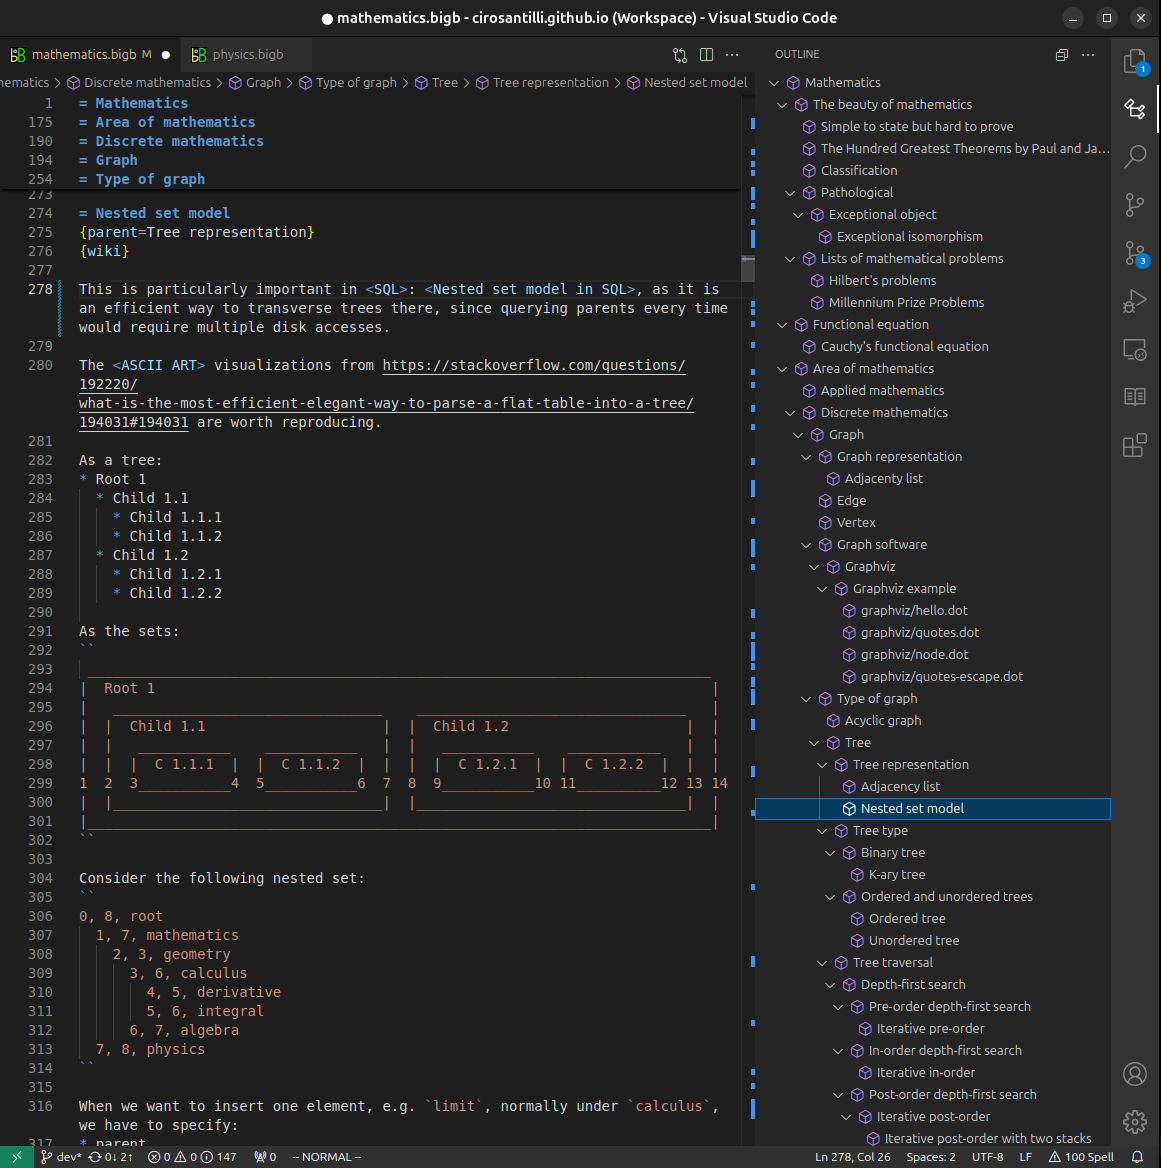
Figure 4. Visual Studio Code extension tree navigation.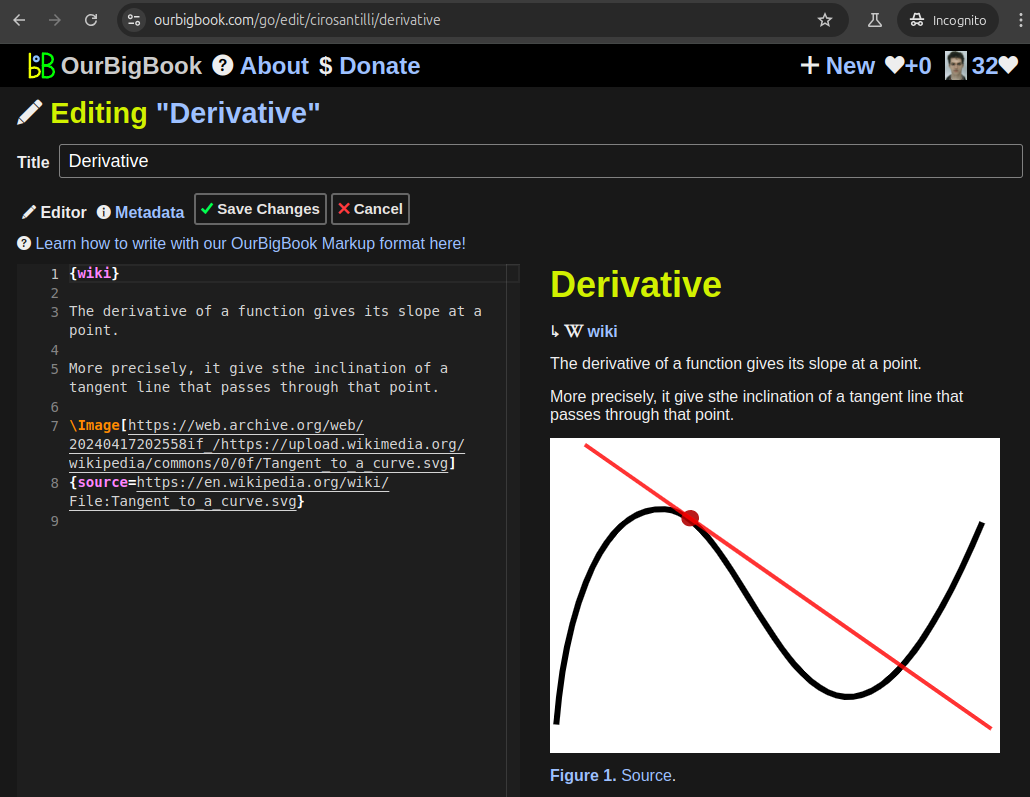
Figure 5. Web editor. You can also edit articles on the Web editor without installing anything locally.Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension.Video 4. OurBigBook Visual Studio Code extension editing and navigation demo. Source. 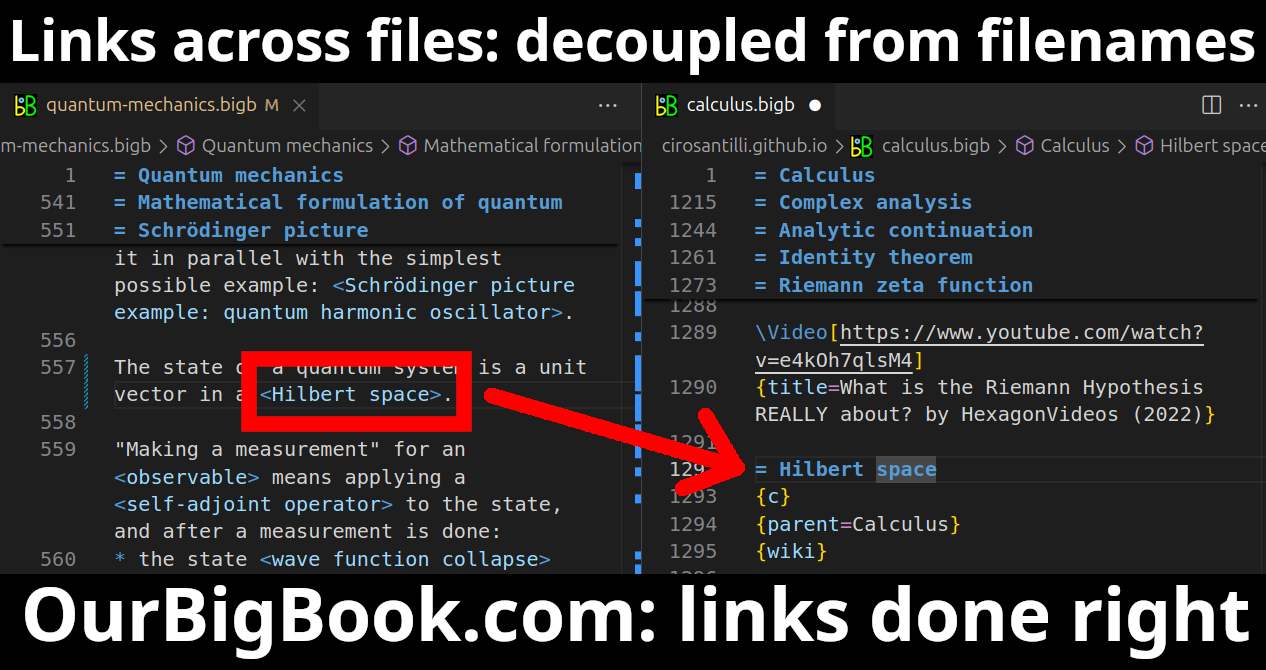
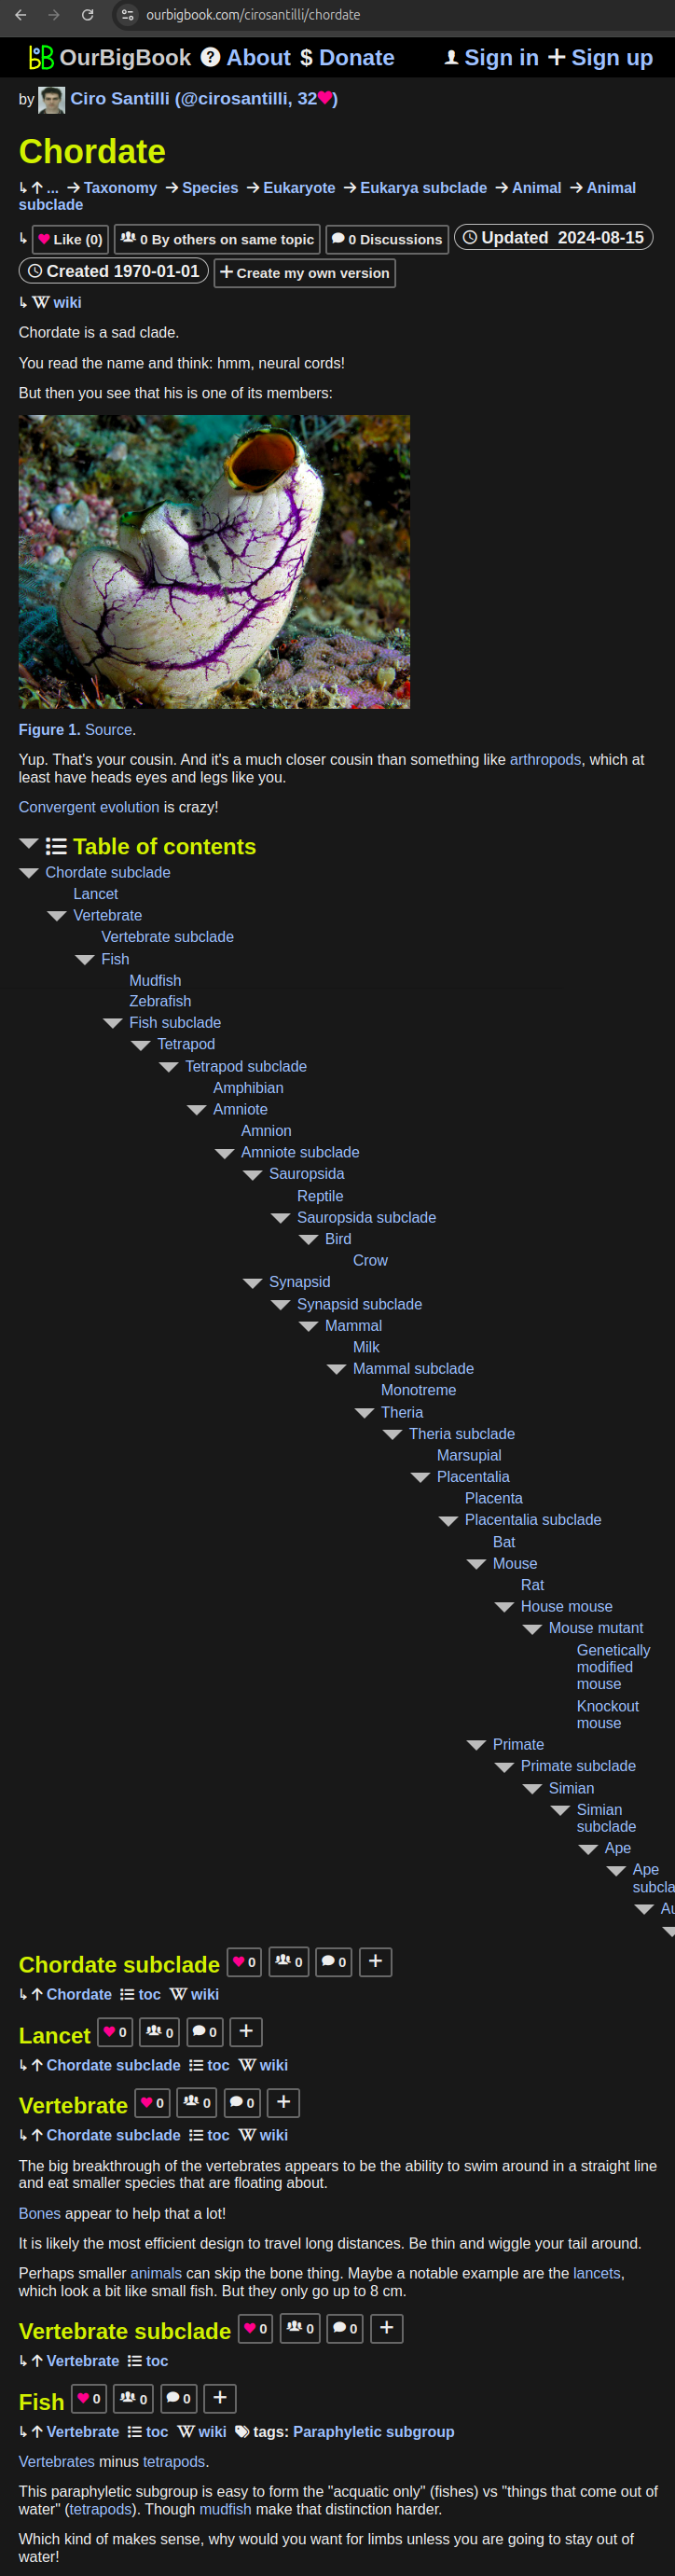
- Infinitely deep tables of contents:


All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact