Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
The modulation property of the Fourier transform adds shifted copies of the message spectrum. If those copies overlap, their complex amplitudes add before taking a magnitude; a frequency filter then acts on this sum. For a real even triangular message spectrum proportional to and carrier frequency , the translated spectra overlap over . A filter retaining therefore leaves a central plateau and sloping outer sections, rather than two disjoint triangular bands. Spectral Dirac delta lines at the cutoff need an explicitly specified filter gain: multiplying a distribution by a discontinuous mask is not defined by pointwise reasoning alone.
A micelle is a finite aggregate of amphiphiles in a solvent. In an ordinary aqueous micelle, hydrophobic tails occupy the interior and hydrophilic heads contact the surrounding water. Association can lower the Gibbs free energy by reducing unfavorable tail exposure, despite loss of molecular translational entropy. Head-group interactions and chain packing help select the aggregate size and shape. A micelle has a filled tail-rich core, unlike a lipid vesicle with a solvent-filled interior bounded by a lipid bilayer.
Triethanolamine is the tertiary amine . It combines a proton-accepting nitrogen with three hydroxyl-containing arms.
The different donor atoms permit metal coordination and hydrogen bonding, while nitrogen protonation changes its charge. The molecule therefore illustrates how several functional groups can give a compound multiple roles in solutions and formulations.
4-Nitroaniline is with amino and nitro groups opposite one another on a benzene ring. The electron-donating amino group and electron-withdrawing nitro group interact through the conjugated framework.
This arrangement affects visible/ultraviolet absorption and acid-base behavior. The positional descriptor matters: moving one group gives a different constitutional isomer, potentially with different spectra and intermolecular interactions.
Nα-benzoyl-DL-arginine-p-nitroanilide, a synthetic substrate releasing p-Nitroaniline in the trypsin colorimetric assay.[ref]
Enzymatic Assay of APROTININ - Sigma Quality Control Test Procedure. Enzymatic Assay of APROTININ, p. 1: Principle and abbreviation
Chapter of Algorithms by Jeff Erickson by its whole-book author Jeff Erickson; no separate chapter byline is established.
Accompanying software for Algorithms, 4th edition by Robert Sedgewick and others, credited to Robert Sedgewick and Kevin Wayne in its author declarations. GitHub hosts the author repository. The footer’s 2011 date identifies the textbook publication; the software has no established publication or revision date.
Algorithms, 4th edition by Robert Sedgewick and others WeightedQuickUnionUF.java by  Codex 0 2026-10-18
Accompanying software for Algorithms, 4th edition by Robert Sedgewick and others, authored by Robert Sedgewick and Kevin Wayne, as credited in the implementation. GitHub hosts the author repository. The footer identifies 2011 as textbook publication; no implementation publication or revision date is established.
Accompanying software for Algorithms, 4th edition by Robert Sedgewick and others, authored by Robert Sedgewick and Kevin Wayne, as credited in the implementation. GitHub hosts the author repository. The footer identifies 2011 as textbook publication; no implementation publication or revision date is established.
Online text: raw.githubusercontent.com/kevin-wayne/algs4/master/src/main/java/edu/princeton/cs/algs4/FordFulkerson.java
Accompanying software for Algorithms, 4th edition by Robert Sedgewick and others, authored by Robert Sedgewick and Kevin Wayne, both named in the implementation bylines. GitHub hosts their algs4 repository. The footer gives 2011 as the textbook publication year; its copyright interval does not date the implementation. These locators refer to the inspected software rather than to textbook pages.
Cited passages: Lines 12–35: maximum-flow/minimum-cut purpose and explicit implementation authors.; Lines 138–177: excess computes incoming minus outgoing edge amounts; isFeasible checks capacity constraints and conservation at nonterminal vertices.; Lines 180–209: check verifies feasibility, s-in/t-out membership, forward-only cut capacity sum and equality with flow value.; Lines 246–252: copyright interval and accompanying book authors, publisher, 2011 publication year..
Online text: raw.githubusercontent.com/kevin-wayne/algs4/master/src/main/java/edu/princeton/cs/algs4/FlowEdge.java
Accompanying software for Algorithms, 4th edition by Robert Sedgewick and others, authored by Robert Sedgewick and Kevin Wayne, both named in the implementation bylines. GitHub hosts their algs4 repository. The footer gives 2011 as the textbook publication year; its copyright interval does not date the implementation. These locators refer to the inspected software rather than to textbook pages.
Cited passages: Browser lines 0–3: class documentation, directed endpoints, real-valued capacity and flow, @author declarations.; Browser lines 4–6: constructors enforce nonnegative capacity and flow bounded between zero and capacity.; Browser lines 11–13: actual residualCapacityTo and addResidualFlowTo bodies distinguish forward capacity-minus-flow and backward flow.; Browser lines 14–16: footer credits whole-book authors, publisher and 2011 publication year..
Accompanying implementation by Robert Sedgewick and Kevin Wayne, explicitly credited by the source file’s author tags, for Algorithms, 4th edition by Robert Sedgewick and others. GitHub hosts the inspected source. The textbook publication year is 2011; no source-file publication date is established, and the copyright range is a separate date role.
Inspected source: raw.githubusercontent.com/kevin-wayne/algs4/master/src/main/java/edu/princeton/cs/algs4/BellmanFordSP.java
Inspected locators: class documentation and author tags; constructor; relax and check methods; textbook attribution footer. This is the queue implementation.
Given a nonempty finite sequence of integers, return its maximum value. Represent the sequence by an array whose contents remain unchanged during execution. The precondition requires an integer length and exact, terminating integer comparisons and variable assignments. The postcondition for returned value isThus the output belongs to the finite set of entries and is at least every entry. The contract permits ties and negative integers; it asks for a value, not the position of a particular occurrence. There is no maximum of an empty set of integers, so empty input is deliberately outside this precondition. A service accepting empty inputs needs a different formal specification, such as a separate absent result.
This Python implementation makes the variable assignments explicit. Its index arithmetic models exact integer arithmetic; fixed-width implementations additionally need enough index range for :For the original input , initialization gives and . Reading keeps ; reading changes it to ; reading and keeps . At successive condition checks, the pairs are . The returned maximum is .
def find_max(a):
    n = len(a)
    best = a[0]
    k = 1
    while k < n:
        if a[k] > best:
            best = a[k]
        k = k + 1
    return best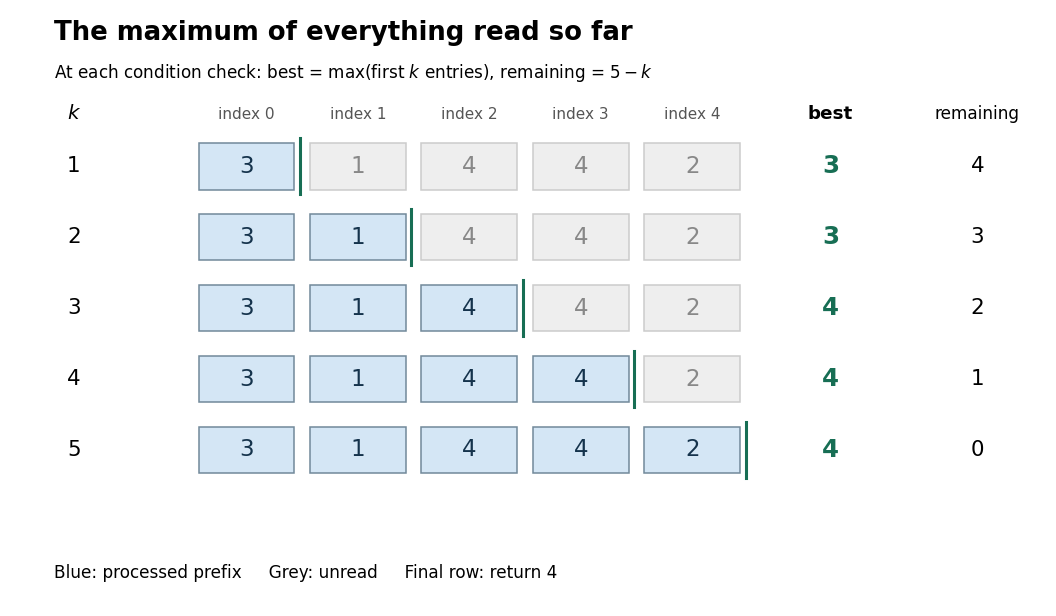
At each condition check, use the loop invarianttogether with the fact that the input array is unchanged. The prefix is the first entries of the sequence, so its finite set of values is nonempty. The maximum need not be unique as an occurrence: the invariant concerns its value.
Initialization establishes : and , the maximum of a one-element set. For preservation, suppose and hold. Then is a valid array entry. Either the comparison replaces with the larger value , or it keeps a value at least . Before increasing , the resulting value isThe variable assignment restores the complete loop invariant. Between the two variable assignments, the old prefix formula may temporarily be false; the loop invariant is required at condition checks, not at every instruction.
At exit, , while gives . Hence , and gives exactly the required postcondition. This establishes partial correctness. The preservation argument is mathematical induction on the number of completed iterations, covering every permitted integer sequence, rather than just the pictured input.
For algorithm termination, the loop variant is a nonnegative integer whenever holds. If , then . Every body terminates under the precondition and changes to . Starting at , it reaches zero after exactly iterations. For , the initial value is already zero and the body is never entered. Together with partial correctness, this proves total correctness.
Starting at zero instead of fails on the original negative input : it returns zero, which is neither an entry nor the maximum . Keeping forever preserves the correct initial prefix claim but loops forever when ; a loop invariant alone does not ensure algorithm termination. Using
>= instead of > still returns the same maximum value when entries tie, although a version returning a position would need an explicit tie rule.Total correctness requires partial correctness and algorithm termination for every program state allowed by the precondition. For a deterministic sequential program, every permitted start must reach a final program state satisfying the postcondition after finitely many steps. Thus an infinite execution can satisfy partial correctness, but refutes total correctness for a permitted start.
In the summation loop verification, the loop invariant establishes the answer conditional on exit, and the loop variant establishes exit. Both parts matter: replacing the body by a step that never returns would defeat total correctness even if every completed iteration preserved the loop invariant. Likewise, a terminating loop with the wrong sum fails partial correctness and therefore fails total correctness.
These obligations depend on the formal specification. A program that rejects every input might correctly implement a rejection service, but does not meet a contract promising a sum for every nonnegative integer. A proof of total correctness also gives no particular physical response-time guarantee: time complexity and the execution environment require their own assumptions.
Partial correctness means that every terminating execution begun in a program state satisfying the precondition finishes in a program state satisfying the postcondition . For a sequential program , the usual Hoare triple notation isHere the notation expresses partial correctness; it makes no promise that finishes. The precondition and postcondition describe permitted starting circumstances and required final circumstances, rather than tests performed automatically by the program.[ref]
An Axiomatic Basis for Computer Programming by Tony Hoare. Hoare, 1969, §3 Program Execution, p. 577, and §4 General Reservations, pp. 578–579; the paper instead labels the precondition P, program Q and result R
For a sharp example, take the precondition and the following sequential program over mathematical integers:The condition remains true, so execution never reaches the instruction after the loop. Consequently its partial correctness claim holds for the postcondition , and even for the impossible postcondition : there is no terminating execution with a wrong final result. This is vacuous truth, not evidence that the loop computes a sum. The same program fails total correctness for this permitted input.
i = 0
s = 0
while i < n:
    i = i
The distinction is useful in a proof: first show that an answer, whenever produced, is right; then establish algorithm termination. The summation loop verification supplies both arguments for a loop that actually progresses. Its finite trace illustrates one execution, while its loop invariant covers every permitted input.
Algebraic Techniques and Semidefinite Optimization, MIT 6.972, Spring 2006 Lecture 6: Resultants and Discriminants by Codex 0 2026-10-18
Codex 0 2026-10-18Lecture note in Algebraic Techniques and Semidefinite Optimization, MIT 6.972, Spring 2006. The printed heading is Lecture 6; Resultants and Discriminants is a descriptive subject title. The heading credits Pablo A. Parrilo as lecturer and leaves the scribe unidentified. No individual authorship or editing credit is inferred. The Massachusetts Institute of Technology issues the course material; MIT OpenCourseWare hosts this copy.
Lecture PDF: ocw.mit.edu/courses/6-972-algebraic-techniques-and-semidefinite-optimization-spring-2006/46bf636ecc6195991e396703bfe1a1ae_lecture_06.pdf
Cited passages: printed pp. 6–1 to 6–2, §1 Resultants, Sylvester matrix and equation (1); printed p. 6–2, §2 Discriminants, Definition 2; printed p. 6–3, §3.1 Polynomial equations, elimination and backsubstitution. The printed date is the lecture date; no separate online publication or revision date is established.
Algebraic notation represents variables, coefficients and algebraic operations by written symbols, so one expression can describe a family of equations.
A gel electrophoresis size calibration relates migration distance to known fragment lengths on the same gel. Here is an explicitly chosen model for linear double-stranded DNA, not measured data or a universal law. Let be the numerical length in base pairs and the numerical migration distance in millimetres from the wells:The logarithm has a dimensionless argument: is the length divided by 100 base pairs. The chosen DNA ladder fragments give , respectively. The gel bands therefore appear in the reverse order of length along the direction of migration.
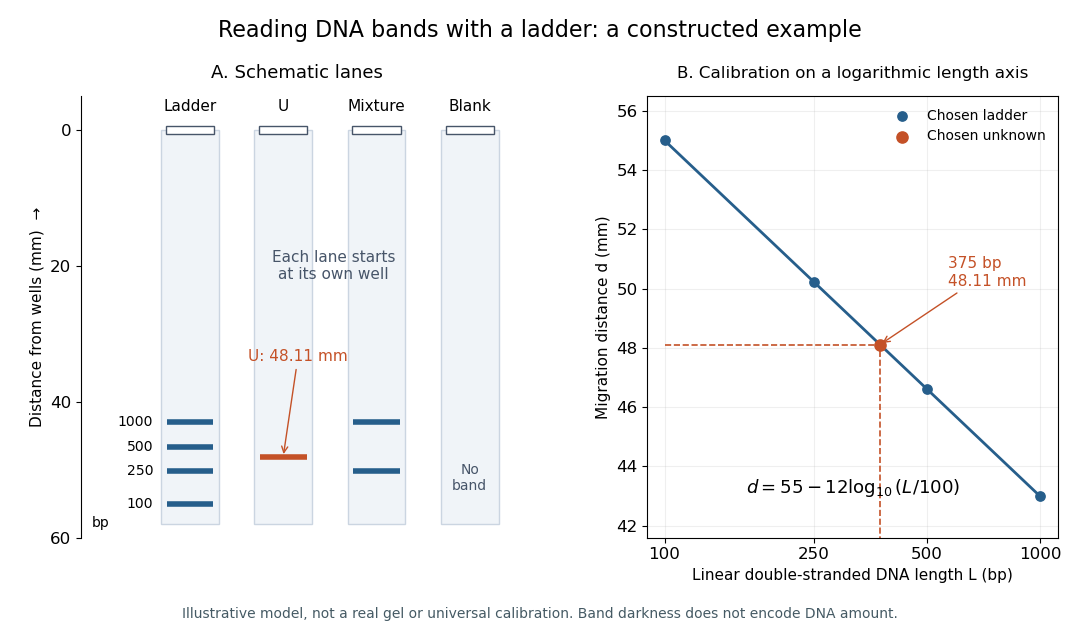
Constructed DNA ladder, unknown, mixture and blank lanes with a logarithm calibration. All positions follow the chosen model; the unknown is 375 base pairs at 48.11 mm, and darkness does not represent DNA quantity
. Details. To invert the calibration, rearrange the logarithm:Our chosen unknown gives , between the 250-base pair and 500-base pair references. Inserting that distance into the inverse recovers 375; retaining only gives about base pairs. The extra digits reflect rounding in this model, not the resolving power of a real gel.
For linear interpolation between those two reference gel bands, use the logarithm of length. Here the fraction of the distance from the 500-base pair reference toward the 250-base pair reference is , giving . Direct linear interpolation of lengths instead gives approximately base pairs. This difference explains why the choice of calibration coordinates matters. A real calibration must be checked over its usable range; folded RNA or circular DNA does not automatically share the linear double-stranded DNA calibration.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:




All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact