Descriptive statistics summarizes observed data, for example through location and spread statistics or graphical summaries such as a histogram.
A mode is a value at which a probability mass function or specified probability density function attains its largest value. There may be more than one. For the normal distribution the unique mode equals the mean; the Maxwell speed distribution has mode and a larger mean speed. For a continuous probability distribution, a mode maximizes density rather than the probability of an exact value, which is zero. Density modes can change under a nonlinear change of variables, as the distinction between Maxwell-Boltzmann velocity distribution and Maxwell speed distribution illustrates.
A scatter plot represents paired quantitative observations as points in a coordinate plane. Group labels, uncertainty and transformations can reveal nonlinear patterns or heterogeneous associations that a single correlation coefficient conceals. A visual association does not establish causation.
A box plot compresses a statistical sample into a box spanning its lower and upper quartiles , a line at its median , and two whiskers. It makes location and central spread easy to compare across groups on a common value axis. The box represents the central half in terms of quantile levels; with ties or interpolated quartiles, it need not contain exactly half the observations. Whisker endpoints require a stated convention: they can be the observed extremes, or they can stop short of separately marked observations. [ref]
https://www.itl.nist.gov/div898/handbook/eda/section3/boxplot.htm. NIST/SEMATECH, Box Plot, definition and variants
Here is one explicitly toy dataset, reused under histogram: twelve invented, unitless values, with repeated values counted separately, already arranged as order statistics:For this box plot we choose the interpolated quartiles defined under quartile, using R's type-7 rule. This givesThe interquartile range is . Our whisker convention uses the fencesThe whiskers end at the smallest and largest observations in the closed interval : here and . Values strictly outside the fences receive separate outlier markers: here only . An observation exactly on a fence is retained within the whisker under this convention. The fences are thresholds, not observed whisker endpoints; the upper whisker is at , not . R's documented whisker rule likewise includes observations no more than box lengths away, although its box uses hinges, which can differ from our type-7 quartiles. [ref]
https://stat.ethz.ch/R-manual/R-devel/library/grDevices/html/boxplot.stats.html. R grDevices documentation, boxplot.stats, coef and hinges
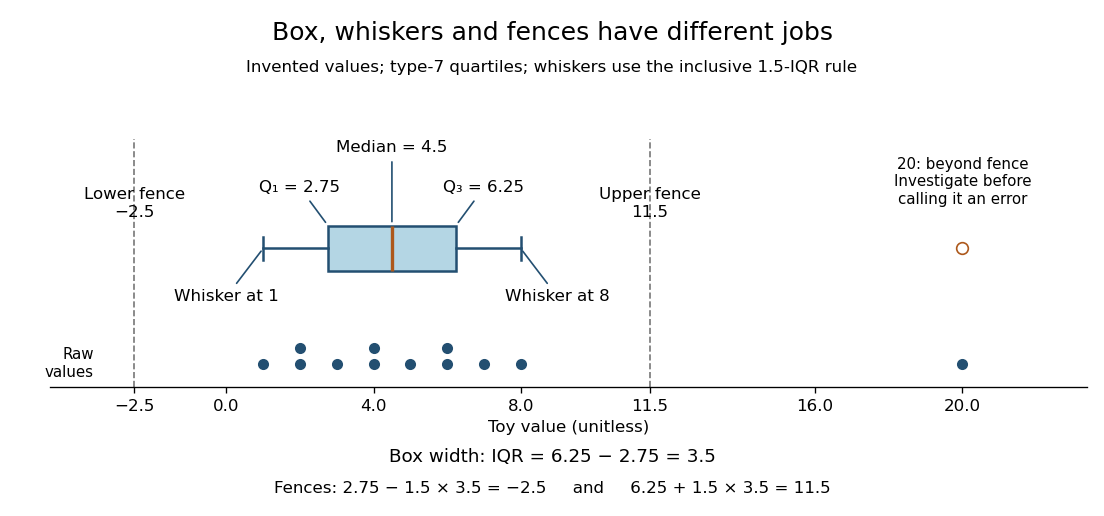
A separate outlier marker is a prompt to investigate, not a finding that the value is bad data and not an instruction to delete it. A distant observation can be a recording error, a legitimate unusual outcome, or evidence that the assumed statistical model misses some behavior. Check its provenance and context before deciding how to analyze it. No measurement-error claim is possible for our invented : we deliberately put it there to demonstrate the rule. [ref]
https://www.itl.nist.gov/div898/handbook/eda/section3/eda35h.htm. NIST/SEMATECH, Detection of Outliers, labeling and investigation
The beauty of a box plot is its compact comparison of ordered positions rather than every observation. That compression also loses information: many different statistical samples have the same quartiles and whiskers, so the box alone cannot reveal every cluster or gap that a histogram might show. For example, replacing the two invented values by and leaves the type-7 quartiles, whiskers and separate marker unchanged. Displaying the individual values alongside the box plot is especially helpful for such a small statistical sample. Always state both the quartile rule and the whisker rule; changing either can change which values are marked.
Quartiles are the quantiles at probability levels ; is a median. For a population we can use its quantile function, for . Finite-sample conventions differ. Our box plot uses linear interpolation between order statistics: for and , setThen . This is R's type-7 convention, described in the documentation authored by Ivan Frohne and Rob J Hyndman. It differs from the generalized-inverse sample quantile defined elsewhere in this wiki: for the twelve toy values, that rule selects ranks and gives , rather than . These are different stated conventions, not arithmetic disagreements. [ref]
https://stat.ethz.ch/R-manual/R-devel/library/stats/html/quantile.html. Frohne and Hyndman, R stats documentation, sample quantile types
The interquartile range measures the width between the lower and upper quartiles, in the same units as the observations. It describes central spread rather than the distance between the observed extremes. In our toy box plot, ; moving the largest value from to would leave the quartiles and interquartile range unchanged under the chosen rule, because the order statistics used in their interpolation would not change.
A histogram groups numerical observations into adjacent intervals called bins and draws one rectangle per bin. Its attraction is that a long list of values becomes a visible pattern of concentration, gaps and skewness. Specify the bin edges, the treatment of values on those edges, and what the vertical axis means: count, proportion, or density. Those choices are part of the graphic. [ref]
https://www.itl.nist.gov/div898/handbook/eda/section3/histogra.htm. NIST/SEMATECH, Histogram, definition and normalization
Let observations be covered by disjoint bins with positive widths and counts , so . For example, use left-closed, right-open bins, closing the final right edge too. The three common height choices have different meanings:
For the density convention, a histogram is a piecewise constant probability density function estimate:Its normalization follows by adding rectangular areas:If the observations have units, density has reciprocal units; a density height is not a probability and can exceed . With equal bin widths, count heights and density heights differ only by a common scale factor. With unequal widths, count-height areas give wider bins extra visual weight unrelated to their counts. Dividing by width removes that distortion. R's histogram documentation explicitly describes area-one normalization for unequal bins. [ref]
https://stat.ethz.ch/R-manual/R-devel/library/graphics/html/hist.html. R graphics documentation, hist, frequency versus density
Reuse the twelve invented values under box plot, with bins . The counts are and the widths are . Hence the density heights and areas are exactlyThe second and third bars have equal density heights even though the third contains twice as many observations: it is also twice as wide. The last bar contains only two observations; its count-height area would be , larger than the six-observation bar's . Its correct density area is only .
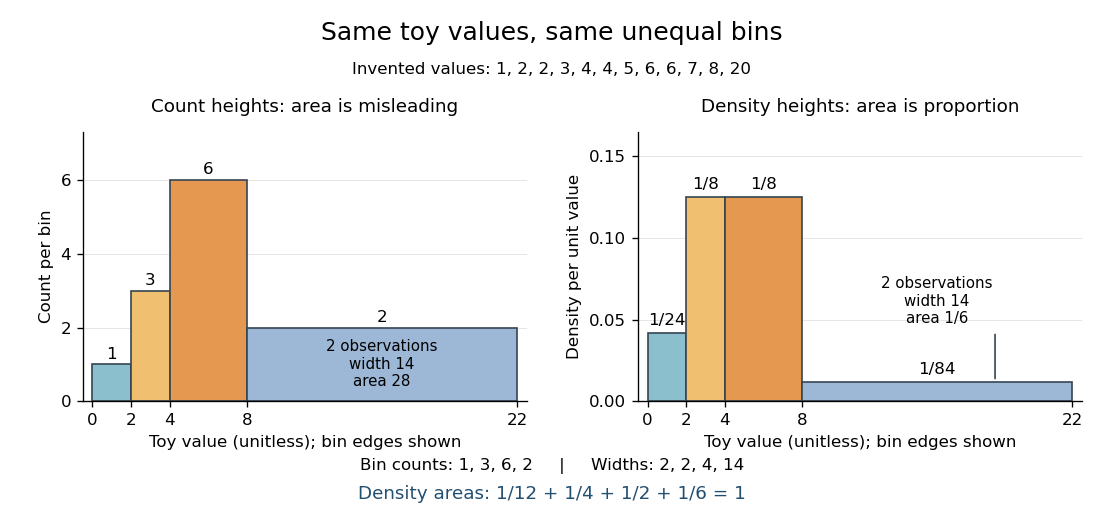
Bin choice trades detail against stability. Broad bins merge distinctions: the toy bin hides the empty stretch between and . Narrow bins expose gaps but can make each individual observation dominate a bar. With one-unit bins starting at , the bins each contain two values and appear equally prominent; that apparent pattern depends on grouping the repeated integers together. Moving the bin origin also changes membership without changing the observations. For density estimation, this is a form of the bias-variance tradeoff: averaging over broad bins loses local detail, while narrow bins give more variable density estimates across repeated statistical samples. [ref]
https://www.stat.cmu.edu/~cshalizi/uADA/24/lectures/ch14.pdf. Cosma Rohilla Shalizi, Estimating Distributions and Densities, Section 14.1
A useful practice is to compare a few plausible widths and offsets, keeping common edges when comparing groups. Automatic bin selectors are starting points, rather than guarantees of a unique correct picture. [ref]https://numpy.org/doc/stable/reference/generated/numpy.histogram_bin_edges.html. NumPy documentation, histogram_bin_edges, Notes on bin selectors
A histogram retains only bin membership. Its density estimate spreads each bin's fraction uniformly across that bin, so our last bar assigns density throughout even though the only toy values there are and . It does not recover within-bin positions or observation order, and a visually convincing shape does not establish a population probability distribution. A box plot provides a complementary compact summary of quartiles; neither graphic replaces the original observations.


