A real probability distribution with a continuous cumulative distribution function assigns probability zero to each individual value. Here this is the broad meaning of continuous probability distribution. Many elementary examples are more specifically absolutely continuous probability distributions, described by a probability density function with respect to Lebesgue measure. Some texts use "continuous" for that narrower class. The Cantor distribution shows why the distinction matters: its cumulative distribution function is continuous, yet no probability density function with respect to Lebesgue measure represents its whole law. [ref]
https://ocw.mit.edu/courses/6-436j-fundamentals-of-probability-fall-2018/9797310bed4c7f5b5d40d007783eec8d_MIT6_436JF18_lec04.pdf. MIT Lecture 4: continuous CDFs and the singular Cantor example
.For scale and shape , the log-logistic distribution has the displayed cumulative distribution function for , with density for . Its log-odds are affine in , giving the name and motivating a log-logistic probability plot. In the exam's parameterization, and .
For , plotting the logits of against sorted log observations gives an approximately straight line under the model. The probability integral transform makes a uniform order statistic with expectation , motivating these plotting positions. With those axes the slope is and the intercept is .
The unit-radius Wigner semicircle distribution has the displayed probability density function. Its graph is a rescaled upper semicircle. The area of the unit semicircle is , so the factor normalizes it. Symmetry gives mean zero, and the substitution gives variance .
A scaled radius- version has density on and variance . Rejection sampling from a uniform proposal on accepts a proposed with probability ; its average acceptance probability is . Thus the number of proposals for one output has geometric distribution with expectation . This law also describes the limiting empirical eigenvalue density in standard ensembles of large symmetric random matrices.
A probability distribution is singular continuous if it has no point masses and assigns probability one to a set of zero Lebesgue measure. Its cumulative distribution function is continuous, but the distribution has no probability density function with respect to Lebesgue measure. This distinguishes continuity of the cumulative distribution function from an absolutely continuous probability distribution, whose probabilities are integrals of a probability density function.
For , and , this probability density function has cumulative distribution function . Differentiating gives the density, while the endpoint limits are zero and one. Its quantile function is for , enabling inverse transform sampling.
Expanding the denominator as a geometric series givesTermwise integration, justified by the monotone convergence theorem, and the gamma function integral yield raw moments . Thus the polylogarithm expresses its mean, variance and higher moments. Here is the complement of the series parameter ; parameter conventions must be checked when comparing formulas.
The Cantor distribution is the law of a random variablewhere the are independent Bernoulli random variables taking values zero and one with equal probability. Its values lie in the Cantor set, and its cumulative distribution function is the Cantor function. Every individual value has probability zero, but the Cantor set has probability one despite having zero Lebesgue measure. A probability density function on that set would integrate to zero, so it cannot describe this law. The example motivates the distinction between a continuous probability distribution and an absolutely continuous probability distribution.
For two independent random variables taking values in a three-dimensional ball with constant volume probability density, the density of their distance is the displayed expression for , and zero otherwise. Both independence and the common radius are essential. To derive it, put , and integrate the product volume differential form over orientations. The law of cosines gives the angular Jacobian determinant , leaving over , . With , , the integrand becomes . Direct integration gives . An independent geometric derivation uses the overlap volume of two radius- balls displaced by , namely , multiplied by and divided by the square of . The density integrates to one and has mean .
For , this probability density function is obtained from a beta distribution variable by . Indeed and , and the change of variables formula gives the displayed density. In particular, the ratio of two independent equal-rate exponential distributions has , density and cumulative distribution function .
A triangular probability density function rises linearly from zero at to its mode , then falls linearly to zero at . Its peak is . Its inverse transform sampling rule is for , and otherwise.
If are independent random variables, each with the uniform distribution on for , then has the symmetric triangular distributionThe convolution of probability densities gives . The overlap of these two intervals has length for and is empty otherwise, proving the formula. By linearity of expectation and the variance of a sum,For , its upper-tail probability is .
A useful model for elapsed time measured from two independently truncated clock readings uses as the display resolution and as the endpoint-offset difference. Independence is essential: uniform marginal probability distributions alone do not imply this triangular distribution. For example gives with certainty. In general, with the same uniform marginals, .
The standard arcsine distribution is a continuous probability distribution on with probability density functionIt is the beta distribution with both parameters equal to . The density grows without bound toward both endpoints, yet neither endpoint has any probability mass. Its name comes from the inverse sine in its cumulative distribution function.[ref]
The Arcsine Distribution. Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist; The Standard Arcsine Distribution, Distribution Functions and Related Distributions: density, normalization, beta representation and CDF
A useful way to see the shape is to choose a point uniformly around a circle and project it onto a diameter. Equal angular intervals do not give equal horizontal distances: the projection moves slowly near either end. An ideal harmonic oscillator sampled at a uniformly chosen time in one complete period has the same endpoint concentration after rescaling its position. The distribution translates a simple geometric slowdown into a precise probability calculation.
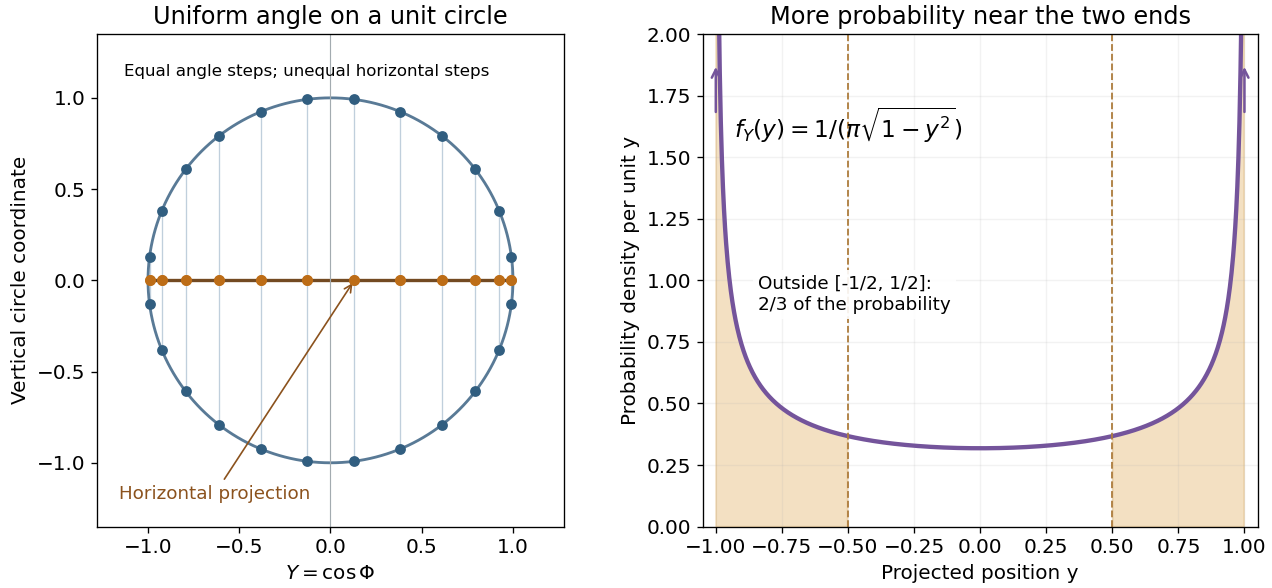
For an original comparison, take equal-length regions: the middle half , and the two outside quarters together. ThenA uniform distribution on instead assigns each region probability . Both distributions have mean ; the mean alone hides their different concentration.
Choose with uniform distribution on and set . Since the sine is increasing on this interval,Differentiation gives , and , prove normalization. This also evaluates the density's improper integral without treating its divergent endpoint values as infinite probability.
For the circle construction, instead choose with uniform distribution on and put . Each has two preimages in one revolution. The change of variables formula adds both contributions:The affine change of variables gives the standard arcsine distribution. A single monotone-branch calculation without the second preimage would give only half the total probability.
The same geometry explains the ideal harmonic oscillator , with amplitude and angular frequency . Choose uniformly in any complete period of duration . Its oscillation phase modulo is uniform, and has densityNear a turning point, is small, so a fixed position interval takes more time to cross. For the chosen amplitude , exactly one third of the period is spent in , and two thirds outside that central interval. These are calculations for an ideal sinusoid, rather than measured oscillator data.
The sampling assumption matters. Taking one observation every full period returns the same position each time. It does not produce this probability distribution. Uniformly random observation times and a fixed regularly spaced sampling scheme are different models; aliasing can conceal the motion altogether.
Paul Lévy used a related geometric construction in his work on stochastic processes: project a uniformly chosen point on a circle onto its diameter to divide a segment. The projection description appears explicitly in §5 of his paper, following its arcsine density calculation.[ref]
An unbounded probability density function does not imply an atom. HereThe last equivalence follows from . The endpoint interval has much more probability than the same interval under a uniform distribution, whose value is , but its probability still tends to zero. This is an integrable singularity.
For example, the first 1% of the unit interval contains about of the probability; the last 1% contains the same amount because the arcsine distribution is a symmetric probability distribution. Each exact endpoint still has zero probability. Density and interval probability answer different questions.
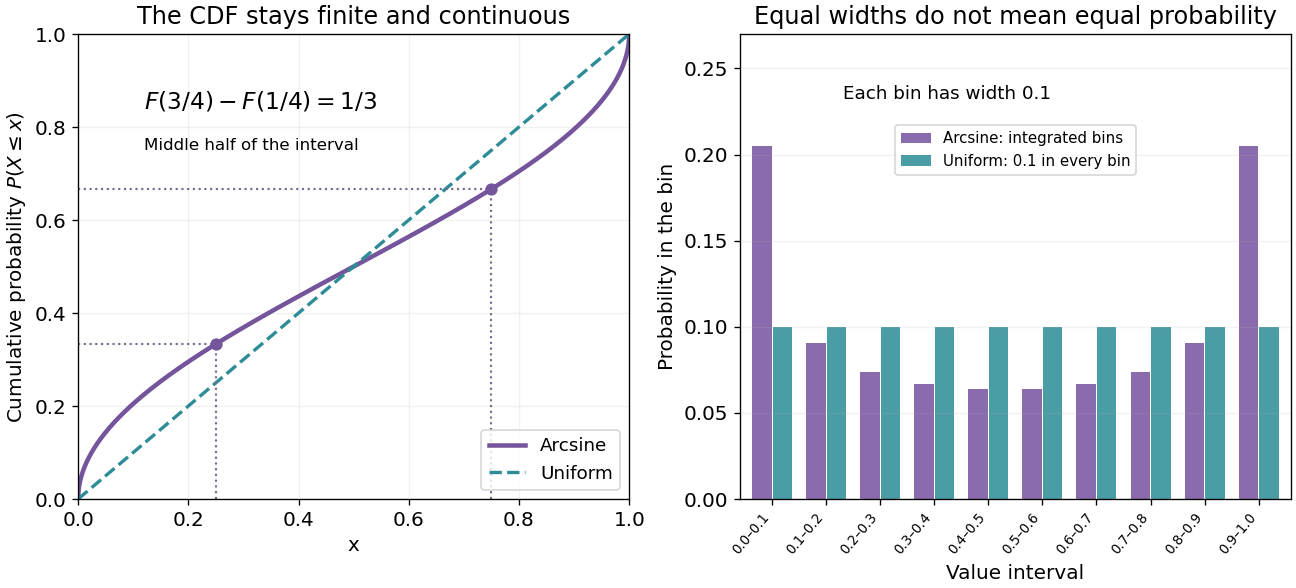
Endpoint density diverges, but every finite bin has finite probability
. Original exact curves and bin probabilities. Left: the arcsine cumulative distribution function compared with the uniform one. Right: ten equal-width bins have probabilities , not heights sampled from the divergent density. Their total is one. Details.A numerical integration routine must respect these endpoint integrable singularities. The substitution givesIt turns a difficult-looking density integral into a constant measure in angle. Integrating finite bins is also a faithful way to draw the distribution near its endpoints; sampling to make a bar height is not.
Inverting gives the quantile functionConsequently, inverse transform sampling uses with uniform on . The quartiles are , and .[ref]
The Arcsine Distribution. Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist; The Standard Arcsine Distribution, Distribution Functions and Related Distributions: quantiles, quartiles and random quantile construction
The first and third quartiles are about and , so the central half of the probability spans about of the unit interval. Under a uniform distribution, its width would be .
The symmetric probability distribution gives . The angle representation gives a short calculation of the second moment:Use to evaluate the integral. A uniform distribution on has variance ; the larger variance quantifies the greater spread toward the ends.
More generally, for a nonnegative integer , the beta function yieldsFor this is one; for it reproduces the values above. The central binomial coefficient thus appears in an exact moment calculation for a continuous probability distribution.
Specify whether two parameters mean endpoints or location and width. With endpoints , define for a standard arcsine distribution variable . ThenThis is a location-scale family with location and width . Its mean is and its variance is . A convention using parameters for location and width instead has right endpoint , so it must not be read as having endpoints .[ref]
The Arcsine Distribution. Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist; The General Arcsine Distribution, Definition, Distribution Functions and Moments: location-plus-width convention and alternative endpoint parametrization
For example, a chosen interval gives mean and variance , while its density still concentrates toward both endpoints. It is a bounded probability distribution; its endpoint singularities do not make its support infinite.
For , this density makes uniform between and . It is a proper finite-interval version of the scale-invariant prior. The chosen logarithm base changes only the endpoint coordinates.
The Pareto distribution describes a positive random variable whose tail probability falls as a power law. In the shape–minimum convention used here, has shape parameter and minimum , with probability support . Its probability density function isThe minimum has the same units as ; the shape parameter is dimensionless. At fixed , changing gives a scale family, since . This convention is also used in uniform-Pareto conjugacy.[ref]
Pareto Probability Density Function. NIST Dataplot Reference Manual; Description: standard Pareto density and lower bound; source gamma,a correspond to alpha,beta here
The survival function and cumulative distribution function areFor , solving gives the quantile functionIts right-hand limit at is ; it tends to infinity as .[ref]
The Pareto Distribution. Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist; The General Pareto Distribution, Distribution Functions: density, CDF and quantiles; source a,b correspond to alpha,beta here
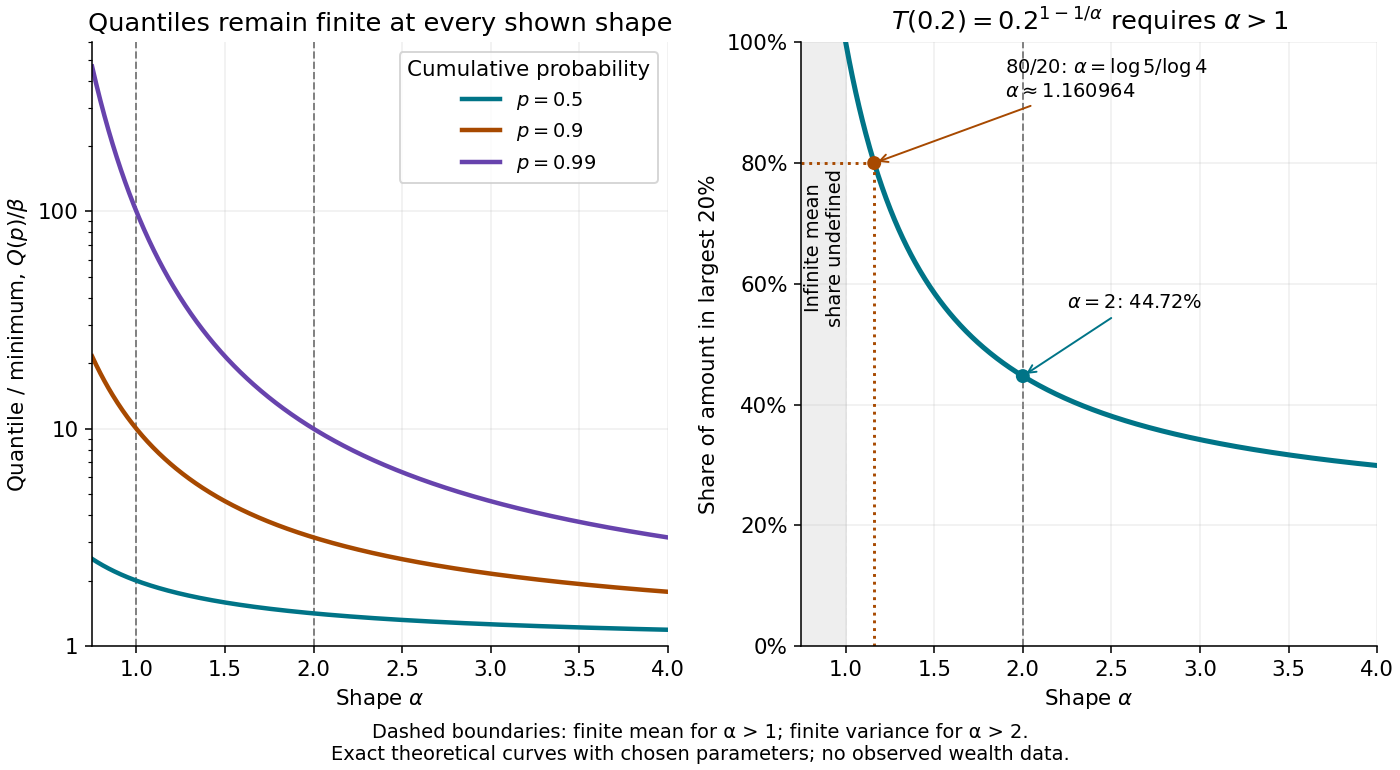
There is no probability mass at : changing a probability density function's value at that single point changes no probabilities.Choose and as an original theoretical example. Then , , the median is , and the 0.99 quantile is . These chosen values and all figures below describe mathematical probability distributions, not actual wealth observations.
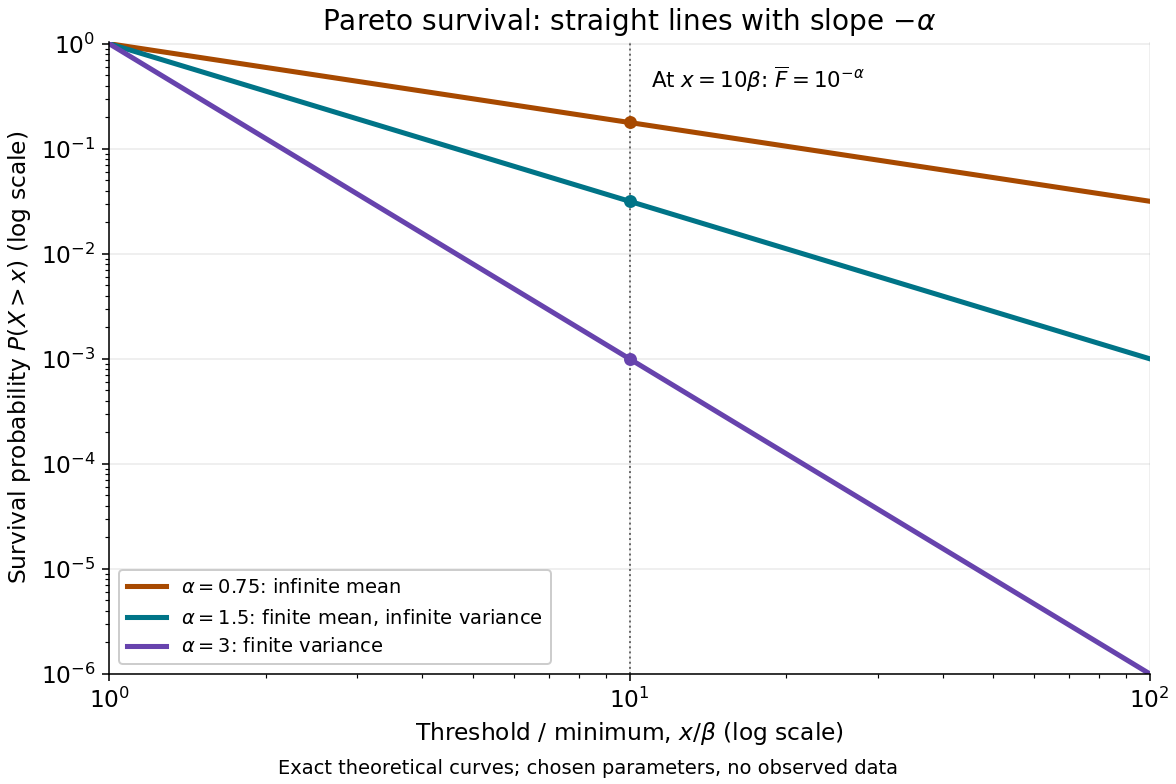
On this log-log plot, write to obtain . The slope is , whereas the probability density function has power exponent . Multiplying a threshold by ten divides its tail probability by . A larger therefore concentrates the Pareto distribution nearer ; a smaller makes extreme values more plausible. This exact scaling is useful when modelling large positive losses or sizes over several orders of magnitude.
The Pareto distribution is a heavy-tailed distribution: for every , the exponential moment diverges because eventually grows without bound. In contrast, the Laplace distribution has exponentially decreasing tails and some finite positive exponential moments. The Student's t-distribution also has power tails, but on both sides of the real line, with a smooth central region rather than a positive minimum.
If has a Pareto distribution with positive scale and positive shape , then for ,Thus the rescaled logarithm has an exponential distribution with rate . The tail probability calculation also identifies the support as .
Let have survival function for , with . Its expected value is . The tail-sum formula for expectation givesThe absolutely continuous probability distribution gives zero mass to the integers, so almost surely and . Taking expectations of gives , which rearranges to the displayed bounds on the Riemann zeta function. Finiteness is justified by and .
For the Pareto distribution of shape and lower bound , the density is strictly decreasing on . Its highest-density interval of probability , , must begin at . The tail probability makes the upper endpoint . If this is a posterior distribution, the result is its highest posterior density interval. In particular, Uniform-Pareto conjugacy supplies posterior shape and lower bound .
Let , where the summands are independent and identically distributed with Pareto distribution . Their positivity implies , so for fixed and ,Both outer expressions tend to zero. A single large summand already prevents a strictly negative exponential rate. No positive exponential moment exists, so the exponential-moment form of the Cramér theorem cannot be applied. The bound proves this logarithmic rate and does not assert an exact tail asymptotic. In particular, it remains true when lies below a finite mean, where the event need not even be rare. The stronger fixed-summand-count asymptotic in a heavy-tailed subexponential distribution is a separate statement.
A Pareto distribution is a proper probability distribution for every , even when its mean is infinite. To see both facts, integrate the probability density function against . For real ,The improper integral converges exactly when . At it diverges logarithmically; above that it diverges as a positive power of the upper endpoint. Setting gives one, proving normalization regardless of whether higher moments exist.
Taking and using when both terms are finite givesFor , the nonnegative random variable has expected value ; a centered variance about a finite mean is unavailable. For , the mean is finite and the variance is infinite.[ref]
The Pareto Distribution. Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist; The General Pareto Distribution, Moments: existence threshold, mean and variance
A finite total probability and a finite expected value answer different questions.At the chosen minimum , gives , and variance , but an infinite third moment. At , the mean is 30 and the variance is infinite; at , even the mean is infinite, while the median remains the finite number . At the boundary , the earlier example has mean 20 but infinite variance. A finite sample contains finite values almost surely; that fact cannot establish that the underlying mean or variance is finite.
Conditioning a Pareto distribution on exceeding a threshold changes its minimum while preserving its shape parameter. For and , the definition of conditional probability givesEquivalently, for ,The ratio to the threshold has the same Pareto distribution at every admissible threshold.[ref]
The Pareto Distribution. Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist; The General Pareto Distribution, Related Distributions: closure under right-tail conditioning
For the chosen , , only of outcomes exceed 20, but among those outcomes the probability of exceeding 40 is again . When , the same identity gives conditional expectation .This multiplicative scaling differs from the additive memoryless property of an exponential distribution. Indeed has exponential distribution of rate , because for . Thus logarithms turn multiplication into addition and explain the scaling property. Conversely, if has uniform distribution on , inverse transform sampling gives .
The excess conditional on has survival function for . In the generalized Pareto distribution convention , this means and . Here the excess starts at zero; the original Pareto distribution starts at .
The Rayleigh distribution is the probability distribution of the Euclidean norm of a two-dimensional random vector with independent zero-mean normal random variables of equal variance as components. If are independent, thenHere is the standard deviation of each component, not of the radius . At this gives the unit-scale probability density function .[ref]
The Rayleigh Distribution. Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist; The General Rayleigh Distribution, Definition and Distribution Functions: independent equal-scale centered normal components and radial density
This geometry turns two signed errors into one nonnegative distance. For example, suppose horizontal and vertical positioning errors are independent random variables. Their means both vanish, but the distance from the intended point is usually positive. The Rayleigh distribution with gives the probability of landing inside any centered disk. These are chosen model assumptions, rather than measurements of a particular instrument.
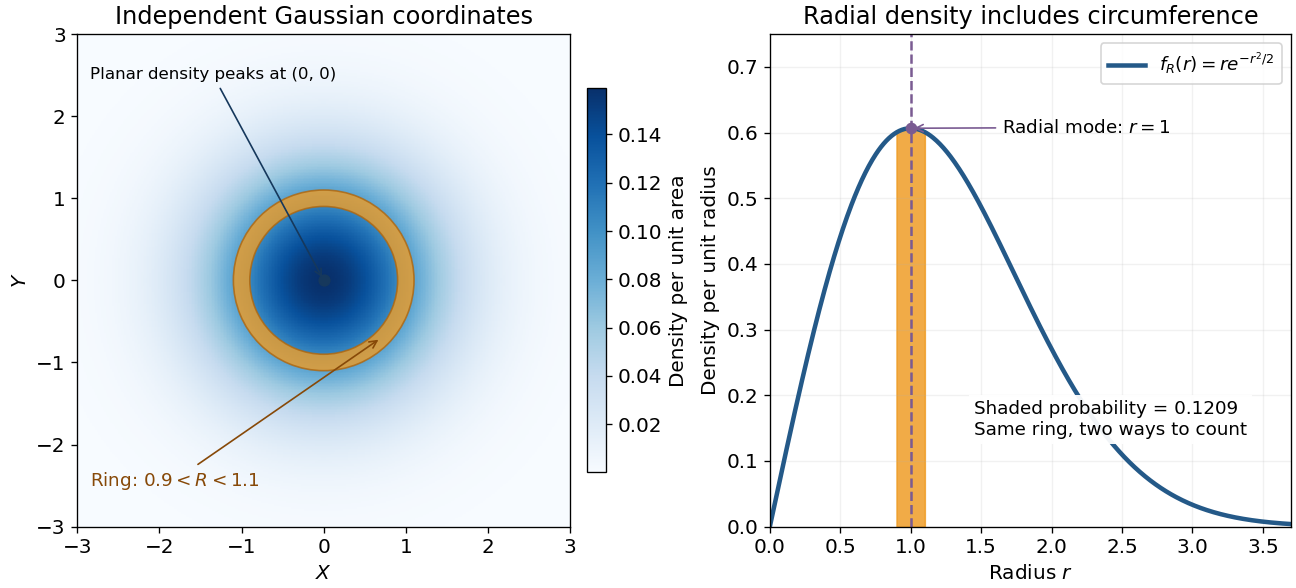
An apparently paradoxical feature is that the most likely location per unit area is the origin, while the radial mode is . A narrow annulus farther out has more area. Near zero that growing circumference outweighs the falling planar density; farther out the exponential function wins. Distinguishing densities measured against different elements of area or length resolves the paradox.
The joint probability density of isIn polar coordinates, , , and the absolute Jacobian determinant is . Thus the joint density of radius and angle factors asIntegrating over angle gives the Rayleigh distribution. The same factorization shows that the angle has uniform distribution and is independent of the radius. This is a short change of variables argument: an annulus of width has area to first order.
The assumptions are substantive. Unequal component variances give elliptical rather than circular density contours; a nonzero mean displaces the center. Even zero covariance and equal normal distributions do not suffice without independence. For an original counterexample, let and let be an independent Rademacher random variable. Put . Then has the same normal distribution as , and . Nevertheless, all points lie on or , and has densitywhich is positive at zero, unlike the Rayleigh distribution. This pair is not a Gaussian random vector.
For , integration gives the survival function and cumulative distribution functionSolving gives the quantile function[ref]
The Rayleigh Distribution. Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist; The General Rayleigh Distribution, Distribution Functions: CDF, quantile and survival functions
For the chosen positioning model ,The disk of radius one component standard deviation therefore contains about 39.35% of outcomes; the familiar one-dimensional normal interval percentage does not apply to a two-dimensional disk. The 95% and 99% radial thresholds areA circle defined by itself still has probability zero; its enclosed disk carries the stated probability.
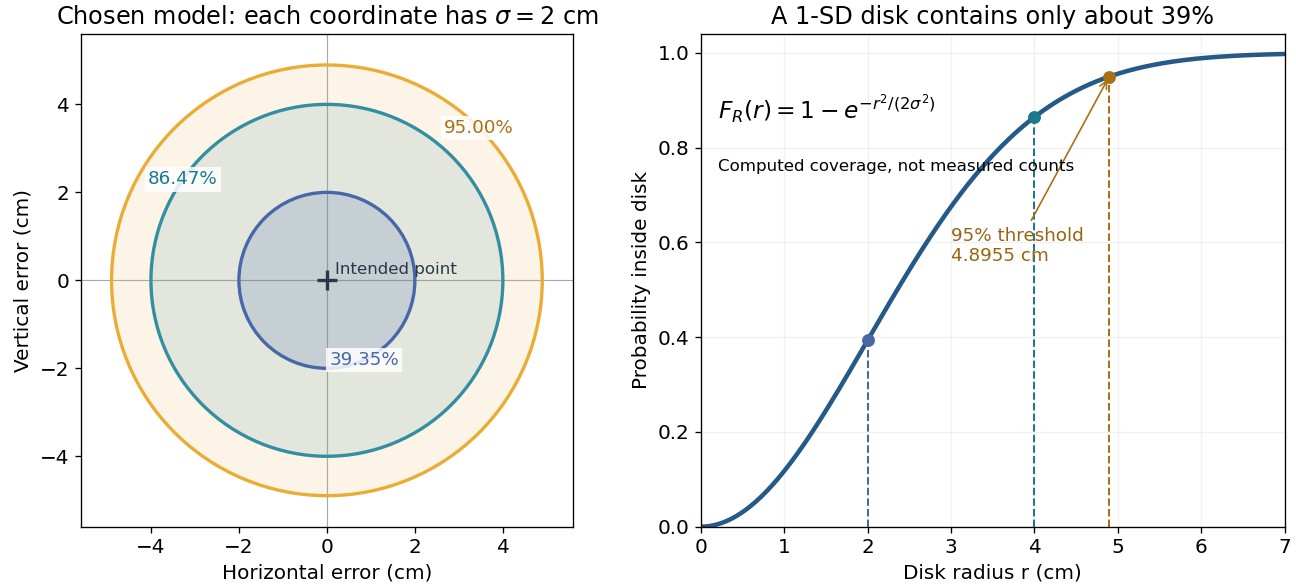
The closed-form quantile function also gives inverse transform sampling: if has uniform distribution on , then has Rayleigh distribution. Using instead gives the same law. Endpoints are excluded so that the logarithm stays finite.
Squaring a Rayleigh distribution variable produces an exponential distribution. For ,where the exponential distribution parameter is a rate. Equivalently, has chi-squared distribution with two degrees of freedom (statistics). An amplitude and its square therefore have different probability density functions, even though one determines the other.
This makes the Rayleigh-normal scale mixture transparent: at unit scale, is exponential, allowing a random normal scale to produce a Laplace distribution. Another equivalent parametrization uses a Weibull distribution with shape two and scale . Conventions that call this latter scale the Rayleigh scale differ by a factor of ; check the probability density function before comparing numerical parameter values.[ref]
Rayleigh Probability Density Function. NIST Dataplot Reference Manual; Description: chi distribution with two degrees of freedom; Weibull shape two and scale sqrt(2) times sigma; warning about Rayleigh scale conventions
Using in the defining expected value integral givesThe last integral is the gamma function. Near zero, the integrand before substitution behaves as , explaining the threshold ; at infinity the Gaussian tail controls every power. In particular,[ref]
The Rayleigh Distribution. Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist; The General Rayleigh Distribution, Moments: mean, variance and nonnegative integer moments; extension to real q greater than -2 follows from the displayed integral
For the chosen , the mean radius is about , its median is , and its mode is . Its root mean square is . Different summaries answer different questions; the component scale is neither the radial mean nor the radial standard deviation.
In an 1880 paper, John William Strutt, known as Lord Rayleigh, studied the resultant of many oscillations with a common frequency and arbitrary oscillation phases. His large-number calculation distinguished a mean intensity from a definite resultant amplitude and used planar coordinates followed by a polar integral. The resulting amplitude density is the Rayleigh distribution in a different scale convention. This is a large-number description, not an exact law for every finite collection of oscillations.[ref]
On the resultant of a large number of vibrations of the same pitch and of arbitrary phase by John William Strutt, 3rd Baron Rayleigh. Philosophical Magazine, Series 5, volume 10 (August 1880), pp. 73–74: expected intensity versus definite resultant; pp. 75–77: planar construction and polar integration; primary-paper transcription inspected on Scribd
To see the connection in a chosen model, take independent oscillation phases with uniform distribution on and equal component amplitude . The phasor sum has coordinatesBoth have mean zero, variance and zero covariance. The multivariate central limit theorem gives an approximately circular Gaussian random vector for large , with . Its amplitude is therefore approximately Rayleigh. For every finite , that amplitude is bounded by , whereas a Rayleigh distribution has an unbounded tail. At it is exactly . This simple endpoint check prevents the approximation from becoming a false exact identity.
A hypoexponential distribution is the distribution of a sum of independent variables with exponential distributions. For two positive unequal rates , convolution of independent random variables gives the probability density functionIt is zero for negative . Its equal-rate limit is the shape-two gamma distribution with rate .
Two sequential independent memoryless reaction waits have a hypoexponential distribution. Convolution gives . Equal rates give the Erlang distribution . A nonzero mode distinguishes this ideal two-event model from a single exponential wait, but does not chemically identify the events.
If the independent exponential random variables have rates , thenwhere the are independent exponential random variables of rate . To see this, the first of independent exponential clocks rings at rate ; after it rings, the memoryless property leaves independent rate- clocks. The successive order statistic gaps are therefore independent with rates . Their sum has the same distribution as . In particular, for , the tail at has logarithm , since . The sum divided by has a large deviation principle with speed and rate function on , infinity otherwise.
For independent exponential distributions with rates , let . Dividing the joint density of by the hypoexponential distribution density of gives a truncated exponential distribution on with rate . Its displayed conditional expectation supplies an E-step when only pair totals are observed. At equal rates the conditional split is uniform, with mean .
// Target: probability-and-statistics.bigb
The Student's t-distribution describes a standard normal random variable divided by an independent estimate of its scale. For any real , let have the standard normal distribution and let have the chi-squared distribution, with and independent. ThenThe parameter is called the number of statistical degrees of freedom. It need not be an integer: the chi-squared distribution is a gamma distribution with shape and rate . The independence assumption is essential; specifying only the two marginal distributions does not determine the probability distribution of their ratio.
Its probability density function on the whole real line iswhere is the gamma function. Every member is a symmetric distribution about zero. At it is the Standard Cauchy distribution; as it approaches the standard normal distribution. The essential shape change is the tail: at any fixed finite , decays like a constant times , much more slowly than the standard normal density's exponential decay. Thus it is a heavy-tailed distribution. [ref]
1.3.6.6.4. t Distribution. NIST and SEMATECH e-Handbook of Statistical Methods; NIST/SEMATECH e-Handbook, Section 1.3.6.6.4: density, Cauchy special case and normal limit; the ratio derivation here also permits noninteger degrees of freedom
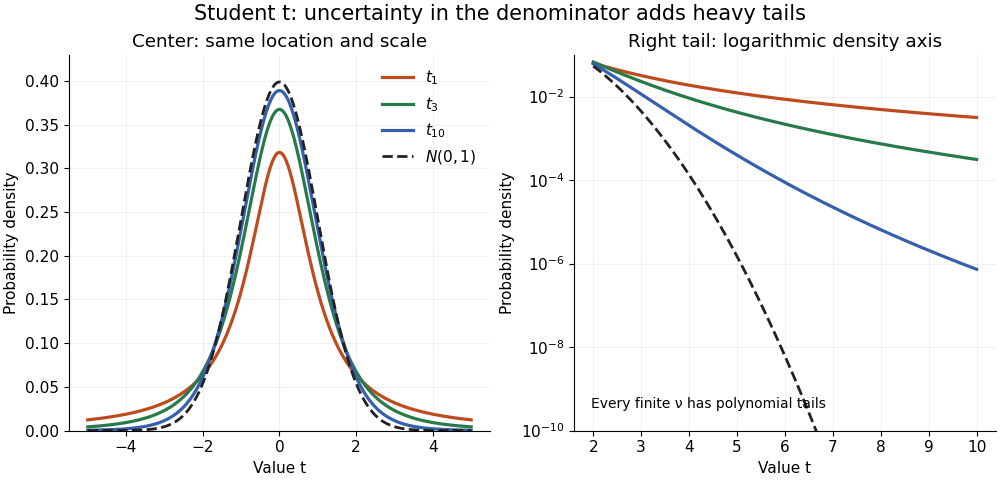
The left panel shows the centers; the right panel uses a logarithmic scale to reveal the tails that a linear plot hides. All four curves have location zero and scale one. They do not have the same variance: the curve has no finite mean or variance, whereas has variance 3 and has variance .
More generally, the absolute moment for is finite exactly when , as follows by comparing the tail integrand with . ConsequentlyFor there is no finite mean; symmetry alone cannot supply one. For the mean exists but the variance is infinite. For even the centered definition of variance is unavailable because the mean does not exist.
A shifted and scaled version , , has probability density function . The scale is not its standard deviation: for ,For example, and scale give standard deviation , rather than 2. The distinction matters when using a Student's t-distribution to model data with occasional extreme values, as well as when interpreting a Student t confidence interval.
For independent and , the displayed ratio has the Student t-distribution with statistical degrees of freedom. Equivalently, conditional on , has normal distribution . This is a normal scale mixture representation of Student t: a small latent denominator occasionally produces a much larger spread. The result is a heavy-tailed distribution even though every conditional probability distribution is a normal distribution.
For a short derivation, independence lets us multiply the conditional normal density and the chi-squared distribution's probability density function, then integrate over the unobserved :The resulting gamma function integral has shape and rate , yielding the normalized probability density function above. Also, for , conditional expectation gives . Thus unit scale does not mean unit variance. Finally, and imply convergence in probability to 1 by Chebyshev's inequality; Slutsky's theorem then gives the standard normal distribution limit.
If and are independent, then has the noncentral t-distribution with statistical degrees of freedom and noncentrality . It describes the test statistic of a Student's t-test under a shifted alternative hypothesis. At it reduces to the Student's t-distribution. This is different from adding a constant to a central Student t-distribution: here the shift is inside the random denominator. For a normal distribution sample tested against null hypothesis , the noncentrality is .
Suppose , , are independent and identically distributed with normal distribution , where the mean and standard deviation are unknown. Define the sample mean and sample variance byUnder these assumptions,Substitution gives the exact ratioThe unknown cancels. The denominator estimates the standard error of the sample mean; its sampling variability is precisely why the Student's t-distribution has wider tails than the standard normal distribution.
The crucial independence has a geometric explanation. Apply an orthogonal transformation to the standardized observations , choosing its first coordinate along . That coordinate is ; the remaining coordinates are independent standard normal random variables whose squared sum is . Their joint probability density factorizes because the transformation preserves the squared length. This also explains the loss of one statistical degree of freedom when estimating the mean. Uncorrelatedness alone would not establish the required independence for arbitrary data.
The result is exact for every under the stated normal distribution model. A small sample size by itself does not justify it: a sample from an arbitrary probability distribution need not have the displayed chi-squared distribution or the necessary independence.
Under the studentized normal sample mean assumptions, let denote the quantile at cumulative probability of the Student's t-distribution. For , rearranging the event gives a Student t confidence interval for the unknown mean with exact coverage probability . [ref]
Choose the list as an original arithmetic example, not as reported measurements or a claim that these five numbers establish a normal distribution. If such values were obtained under the assumed independent and identically distributed normal distribution model with unknown , thenThere are four statistical degrees of freedom. For a 95% confidence interval, , soUsing the standard normal quantile with the same estimated standard error would give only . That underestimates the correct margin by about 29.4%. Indeed its actual coverage probability under this normal distribution model is , rather than 0.95.
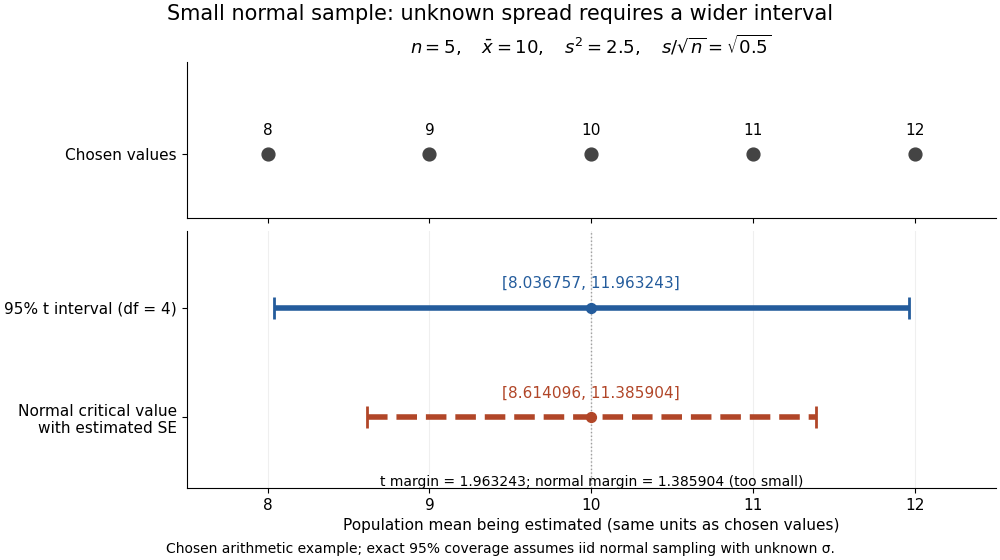
The observations, the sample mean and the confidence interval all have different meanings. The bar estimates the population mean; it is not an interval intended to contain 95% of individual observations. In repeated independent samples of size five from the assumed normal distribution, 95% of intervals constructed using the exact quantile cover the same fixed . This is not a 95% posterior probability that the fixed statistical parameter lies in this particular realized interval. Such a probability requires a separate Bayesian inference model.
For this four-degree case, the cumulative distribution function has an especially simple form:One can check the formula by differentiation: , with limits zero and one at the two ends of the real line. Solving the increasing equation by the bisection method gives the quantile used above.
For a normal sample of size , the central Student t confidence interval has width . Its squared width is therefore a fixed multiple of the sample variance. The exact sampling identity gives the displayed law. It quantifies the random variability in interval precision even when the sample size and coverage level are held fixed.
William Sealy Gosset worked at Guinness as a chemist and brewer and developed methods of statistical inference for small samples. He published under the pseudonym "Student". His employment as a chemist is independently recorded by MacTutor; the Dictionary of Irish Biography identifies him as an applied statistician and brewer and explains the pseudonym policy. [ref]
William Sealy Gosset by John Joseph O'Connor and Edmund Frederick Robertson. Biography, opening paragraphs and discussion of the name Student
[ref]Gosset, William Sealy (‘Student’) by Philip J. Boland. Philip J. Boland, Gosset, William Sealy ('Student'), opening paragraphs and pseudonym discussion; published and last revised October 2009
The 1908 paper The Probable Error of a Mean appeared in Biometrika 6(1), pages 1–25, with the byline "Student". Its introduction identifies the uncertainty introduced by estimating a standard deviation from few observations and explicitly assumes a normal distribution. Sections II and III develop the relation between sample spread and the standardized sample mean. Its notation uses a sample spread with divisor and calls the ratio ; with that convention, the modern equals . The modern exact independence argument is given under studentized normal sample mean. [ref]
The Probable Error of a Mean by William Sealy Gosset. 1908 original text: byline, Introduction, Section I definition of sample spread, and Sections II–III
Section VI describes a physical sampling check: 3,000 cards carrying existing paired measurements were shuffled, then divided into 750 groups of four. He compared observed frequencies of sample spread and standardized sample mean with theoretical frequencies. This was a check using finite, grouped, approximately normal distribution data; it did not prove exact calibration for arbitrary populations. [ref]
The Probable Error of a Mean by William Sealy Gosset. Section VI, Practical Test of the foregoing Equations: cards, groups of four and limitations from nonnormality and coarse grouping
The F-distribution with degrees of freedom is the distribution of for independent chi-squared random variables and .
An absolutely continuous probability distribution on the real line has a probability density function with respect to Lebesgue measure : for every Borel set , . Its cumulative distribution function is an absolutely continuous function, with derivative almost everywhere. The probability density function and cumulative distribution function example under probability distribution illustrates this class.
If a random variable has a probability density function, each singleton has probability zero because its density has zero integral there. For a countable set , remove duplicates to make the events disjoint. Countable additivity gives . The proof does not extend to uncountable unions merely because each constituent has zero probability.
A probability density function represents probabilities as areas under a nonnegative measurable function. For a real random variable with an absolutely continuous probability distribution, it satisfiesfor every Borel set . Its height is probability per unit of the outcome variable, not the probability of that exact outcome. Thus a probability density function may exceed one, while the probability of a singleton is zero. NIST describes the interval-probability interpretation through integration. [ref].
For the example on , , but and . The cumulative distribution function is within that interval, connecting density height to the local accumulation rate.
Changing the scale changes the density height. If , then on . At the corresponding value , its height is , while is unchanged. The factor compensates for the wider integration variable. This is a change of variables, not a change in the underlying probabilities.
A probability density function is determined only almost everywhere: changing its values on a Lebesgue measure zero set changes no probabilities. The Cantor distribution has no such representation, and a mixed probability distribution can have both a point mass and a density component, so differentiating its cumulative distribution function does not recover all its mass.
For a random variable with probability density function on an interval, let , where is a diffeomorphism onto another interval. The change of variables formula givesIndeed, integrating the right-hand side over an outcome interval gives the probability that lies in its inverse image. The absolute derivative preserves positive probability when reverses orientation. A gravity deflection of an atomic beam is a physical example: its speed-to-height transformation changes the probability density and its mode.
If has a joint probability density , the product has the displayed probability density function, interpreted almost everywhere. For fixed , substitute in the integral defining ; the absolute Jacobian determinant is . The Tonelli theorem then exchanges the nonnegative integrals. The line has two-dimensional Lebesgue measure zero, so its omission creates no probability mass. A density may be infinite at exceptional points without creating an atom.
For two independent uniform points on the surface of a sphere, rotational invariance permits fixing the first at the north pole. The surface area of a latitude band of angular width is , yielding the displayed density for their central angle. Equivalently their unit position vectors have a dot product uniformly distributed on . The law is independent of sphere radius.
Join three independent uniform points on a sphere when their central angle is acute. Given angle between the first pair, the third point's two favorable hemispheres overlap in a spherical lune of area fraction . If , connection requires membership in their union, of probability . If , it requires membership in their intersection, of probability . Integrating these against the central-angle density proves the displayed probability. Connectivity is weaker than all three pairwise angles being acute.
For three independent uniform points on a sphere, condition on the central angle between the first two. The third point makes acute angles with both exactly when it lies in the intersection of their positive hemispheres. That intersection is a spherical lune of opening , hence has probability . The first two points also need . Integrating against the central angle between independent uniform sphere points density gives .
A normalizing constant makes a nonnegative integrable function into a probability density function: if , then is a probability density function.
A density ratio compares two probability density functions relative to the same underlying measure. More generally it is a Radon-Nikodym derivative when one probability measure has absolute continuity of measures with respect to the other.
A probability density is log-concave when its logarithm is a concave function on its support. Tangent lines to a differentiable concave log density lie above its graph, giving exponential envelopes for rejection sampling.
For a probability density function on with Lipschitz bound , the triangular lower envelope gives . If is strictly positive everywhere, the inequality is strict. Equality forces the entire probability density function to coincide with the triangular envelope, which vanishes outside a finite interval.
A joint probability density satisfiesIts coordinate integrals are the marginal densities, and integrating it over a rectangle gives the corresponding joint distribution function.
If for a differentiable bijection, thenThis is the change of variables formula applied to probability density.
For the rate-parameterized Gamma distribution with shape and rate , integration of its probability density giveswhen , by the gamma function integral and a change of variables. The integral is infinite for . In particular the moment-generating function is finite on an open interval containing zero, so the uniqueness theorem for moment-generating functions applies. Multiplication of these moment-generating functions proves additivity of independent gamma distributions with a common rate.
The probability density function of a Gamma distribution with shape and rate . Integration against gives when ; the integral diverges for . Rate and scale are reciprocal conventions and must be distinguished.
A gamma distribution translated by a real constant . With shape and rate , its support is and its first three cumulants are , , and . Its skewness is . A negative shift permits negative values; introducing a shift does not automatically respect the nonnegative support of an insurance loss.
If and are independent random variables with Gamma distributions of shapes and the same rate , then has the Beta distribution with parameters , and has the Gamma distribution of shape and rate . Moreover and are independent. The inverse change of variables has absolute Jacobian determinant , which makes the joint probability density factorize on the product domain , . The common rate is essential for this factorization.
If are independent exponential random variables with one common rate , put . The change of variables for probability densities gives on . Its marginal density is , so the conditional probability density of given is on . This is the shape- case of beta-gamma independence. In particular is uniform on and independent of . Equality of the rates is essential: different rates leave an exponential tilt across the conditional interval.
If independent random variables have gamma distributions with shapes and one common rate , thenTheir Laplace transforms of nonnegative random variables multiply to , which is the transform of the displayed gamma distribution; uniqueness of the Laplace transform proves the claim.
Writing , , and puts the gamma density into exponential dispersion family formIts mean is and its variance is .
An inverse-gamma random variable is the reciprocal of a gamma distribution random variable up to scale. In shape-scale parameters its density is proportional to on .
For inverse-gamma distribution observations of known shape and scale , their likelihood function in is proportional to . A shape-, rate- gamma distribution conjugate prior therefore gives the displayed Bayesian posterior. The Bayes estimator under squared error loss of the conditional claim expected value is . It depends on reciprocals, rather than the sample mean of the claims.
The sum of independent exponential variables of rate has the Erlang distribution with densityConvolving with one more exponential proves the formula inductively.
If is a positive integer and are independent uniform variables, thenhas the gamma distribution with shape and rate , because each summand is exponential with rate .
The Dirichlet distribution is a probability distribution on vectors with nonnegative entries summing to one and density proportional to .
For independent exponential waits of rates and , their sum has density , obtained by convolution on . The limit at is and the mean is .
An exponential clock has an exponentially distributed waiting time. Independent clocks with respective rates have a minimum waiting time with rate .
Let be a fixed sum of independent exponential random variables with smallest rate , and let be the sum of independent rate- exponential random variables, independent of , with fixed and . At large-deviation speed , has rate function for ; the sample mean has rate function for . The product large-deviation principle and contraction principle for large deviations giveIndeed the derivative of the quantity minimized with respect to is . Its minimizer is . Beyond that transition, a single slow exponential random variable carries the extra excursion; the rate function becomes affine.
For independent exponential random variables with the same rate , the convolution density of is for . The cumulative distribution function of is , whose derivative is the same density. This is equality of probability distributions, not an almost-sure equality of the two expressions formed from the same sample.
For exponential rate , the integer part has mass on nonnegative integers. The fractional part has density for . The mixed joint density factors into those marginals, proving independence. The integer part is a geometric distribution on zero-based support, with expectation .
If , then direct integration gives
If , thenThus an exponential remaining lifetime has the same law regardless of the elapsed lifetime.
If and are independent exponential variables with the same rate, then is uniform on and is independent of .
For independent exponential variables of rates and , let and let be the minimizing index. ThenConsequently is exponential with rate , , and and are independent.
Let be independent random variables with exponential distributions of respective positive rates . Condition on and use the survival function of :At this is . Dividing by that probability proves that the positive difference conditional on again has an exponential distribution with rate . The memorylessness of the exponential distribution persists after an independent competing event has already occurred. Replacing the difference by a negative sentinel when adds an atom of a measure of mass at that sentinel without changing the positive tail.
If is geometric on with parameter , independently of unit-rate exponential variables , thenis exponential with rate . Its moment-generating function is for .
The cumulative distribution function of on is . Differentiating gives density on , which is the beta distribution probability density function with parameters . This also gives a simple instance of inverse transform sampling: to sample a density on , raise a uniform draw to the power .
For independent random variables with the uniform distribution on , use the probability density of a product of random variables and integrate over . The displayed probability density function is zero off and has integral one. More generally, for independent and identically distributed factors with this uniform distribution, satisfiesThe expectation of a product of independent random variables proves these identities directly.
For a sector of width and an independent uniformly distributed central bearing, a specified bearing is covered with probability . Two antipodal bearings cannot both be covered when . For , the allowable centre arcs overlap in two components of length , proving the displayed conditional probability. Averaging over the width's probability density function gives unconditional coverage probabilities.
For independent uniform on , real roots occur on , a region of probability . On that region both roots are nonpositive. Both lie in exactly when . Its area is , so the conditional probability of both absolute values being at most one is . Joint probability density integration turns algebraic discriminant and root constraints into simple planar areas.
A uniform random variable has a uniform distribution. Independent such variables can supply independent inverse transform sampling; reusing a single variable for two transforms generally creates dependence.
A Steinhaus random variable is uniformly distributed on the complex unit circle. It can be generated as using independent signs and an independent uniform angle . This conditional sign representation transfers Rademacher sum inequalities to random complex phases.
For independent Steinhaus random variables, condition on their acute angles and use the sharp Rademacher second-moment inequality on the sign coefficients . Their squared moduli sum to independently of the angles, so the conditional first moment is at least the same fixed square-root bound. Averaging proves the assertion.
The square of a uniform distribution variable on has cumulative distribution function and an integrable inverse-square-root probability density function. Reflection replaces by in that density.
Write . The two pieces in a uniform split are independent exactly whenSetting shows that for some . Thus the pieces are independent exactly when they are independent exponential variables of the same rate; equivalently, the total has gamma density .
The Laplace distribution, also called the double exponential distribution, is a location-scale family with probability density functionThe location is its mean, median and mode; controls its spread. In the centred rate convention, the same law has and , giving . Keeping track of whether a parameter is a scale or its reciprocal prevents reversing the effect of increasing it. [ref]
1.3.6.6.12. Double Exponential Distribution. NIST and SEMATECH e-Handbook of Statistical Methods; NIST/SEMATECH e-Handbook, Section 1.3.6.6.12, Probability Density Function and Common Statistics; NIST denotes the scale by beta
The two halves of the probability density function are reflected exponential decay curves, each with total probability . Their meeting point has a sharp corner: the left and right derivatives are and . This finite peak is not a positive probability mass at . Indeedso , just as for any absolutely continuous probability distribution.
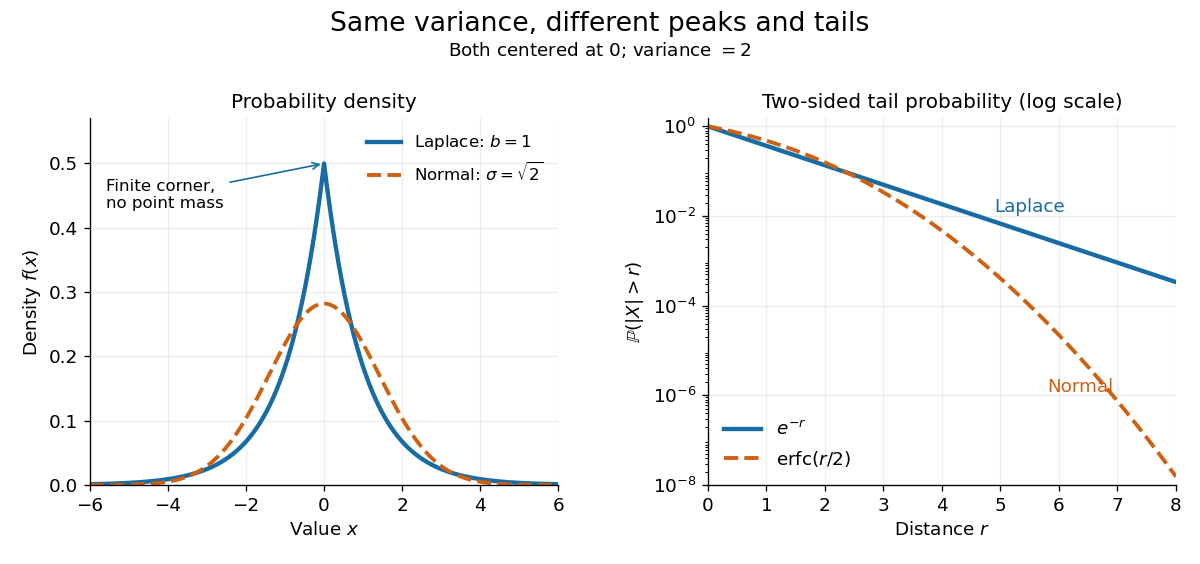
The figure compares a Laplace distribution with , against a normal distribution with mean zero and standard deviation : both have variance 2. The right panel uses a logarithmic scale for the two-sided tail probability . Its straight Laplace distribution curve comes from ; the normal distribution tail falls faster. Thus values far from the center can be more plausible under a Laplace distribution even after matching the variance. These are theoretical curves, not measured frequencies. The tails still have exponential decay; this is not a heavy-tailed distribution in the convention requiring every positive exponential moment to diverge.
Integrating either half of the probability density function gives the cumulative distribution functionIn particular . The basic moments areThus the scale is the expected value of the absolute distance from the center, and is not the standard deviation. [ref]
1.3.6.6.12. Double Exponential Distribution. NIST and SEMATECH e-Handbook of Statistical Methods; NIST/SEMATECH e-Handbook, Section 1.3.6.6.12, Cumulative Distribution Function and Common Statistics; rescale the standard form by x=mu+bz
A short way to obtain the moments is to note that has an exponential distribution with rate : for . Integrating gives and ; the symmetric distribution gives the centered first moment zero.For a random variable with probability density function , the event is for . Integrating the symmetric density gives the displayed cumulative distribution function; it is zero for negative . The density on is . Its integrable singularity at zero does not create an atom, because the cumulative distribution function is continuous there.
For an independent and identically distributed Laplace distribution sample with density and known rate , the sample mean has mean and variance . The central limit theorem gives the displayed asymptotic confidence interval for at confidence level . The sample mean need not be a maximum-likelihood estimator for this construction to be valid. The Laplace location and scale maximum likelihood location is a sample median; that is a different choice of statistic.
Suppose , , are independent and identically distributed with Laplace distribution , where . For realized values , the likelihood function and log-likelihood function areFor fixed , maximum likelihood estimation of the location therefore minimizes the sum of absolute losses. This connects the Laplace distribution to robust statistics: each observation contributes a cost growing linearly with its distance, whereas squared-error loss grows quadratically.
Why does a sample median minimize ? Between successive order statistics, moving a little to the right increases each distance to a value on the left and decreases each distance to a value on the right. Hence the slope is the number on the left minus the number on the right. It changes from negative to positive at the middle. More precisely, if , all minimizing locations areFor an even sample size, the objective is flat throughout the interval between the two central order statistics. The midpoint convention for the sample median selects one solution; it does not prove uniqueness. [ref]
Laplace (Double Exponential, Bilateral Exponential) Distribution. SciPy 1.18.0 documentation; SciPy reference guide, Laplace distribution, ML location estimator and the even-N interval between the two central order statistics
This is the finite-sample counterpart of median minimizes expected absolute loss.If , maximizing over givesThe derivative is positive below this value and negative above it. Moreover the maximized likelihood function is proportional to wherever , so the same minimizing locations give the joint maximum-likelihood estimates. [ref]
1.3.6.6.12. Double Exponential Distribution. NIST and SEMATECH e-Handbook of Statistical Methods; NIST/SEMATECH e-Handbook, Section 1.3.6.6.12, Parameter Estimation; median and average absolute deviation formulas
The scale estimate divides by ; this formula is not an assertion that it is an unbiased estimator.The boundary case matters: if all observations equal , choose . Then and as . There is no finite joint maximum-likelihood estimate in the parameter space . In particular, this always occurs for . Writing does not produce an admissible Laplace distribution.
Choose the five numbers as an original illustration. Their sample median is 2 and their sample mean is 4. The sum of absolute losses at the sample median isIf these numbers were modeled as an independent and identically distributed Laplace distribution sample, the joint maximum-likelihood estimates would therefore be and . Using the sample mean instead gives , so it does not maximize this likelihood function.
Now replace only 10 by 100. The sample median stays at 2, while the sample mean becomes . The minimized sum of absolute losses rises to , and the fitted scale rises to . Stability of the fitted location therefore does not mean stability of every fitted parameter.
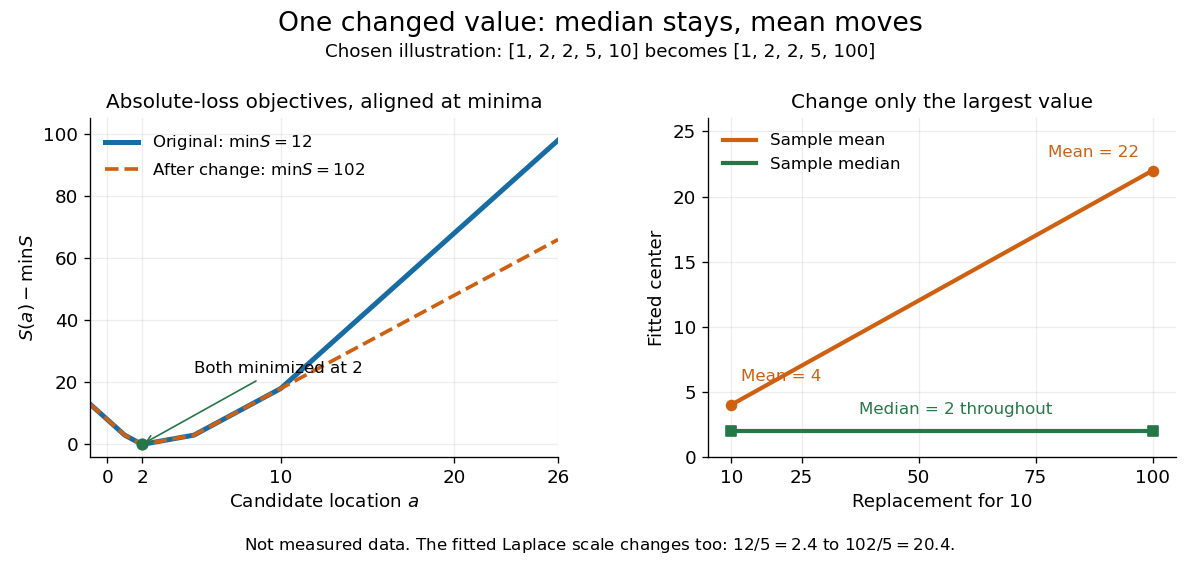


The left panel subtracts each objective's minimum so the two absolute loss curves can be compared despite the different totals. The right panel tracks the sample mean and sample median as the largest chosen value changes. This is an outlier sensitivity illustration, not actual observations or a check that a Laplace distribution fits any population. In applications, regression residuals and the data-generating assumptions need separate examination; a stable sample median alone does not validate a statistical model.
Articles were limited to the first 100 out of 102 total.
Articles by others on the same topic
There are currently no matching articles.