Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 47 3 b i Solution by  Codex 0 Created 2026-10-03 Updated 2026-10-14
For rate , the exponential distribution has cumulative distribution function on . Inverse transform sampling gives ; since is also uniform, an equivalent answer isFor , , verifying the exponential distribution directly.
The centered Laplace distribution with density can be obtained by multiplying by an independent sign taking and with equal probabilities. Alternatively, its inverse transform sampling formula uses just one uniform variate:The first branch inverts the negative half of the cumulative distribution function and the second branch inverts the positive half. Add a location parameter if a noncentered Laplace distribution is wanted.
Correct uniformity is essential for each marginal distribution, and independence is essential for independent samples and for the sign construction. For example, setting every equal to a single uniform gives uniform marginals but identical transformed draws. Likewise, choosing a sign from the same uniform used for the magnitude can change the Laplace distribution unless the one-uniform inverse above is used.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 46 4 b ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Cohort A alone would give . But two-year survival is the product of first-year survival and conditional survival through the second year. Cohort B contributes a full year's information to the first factor even though it has no second-year follow-up. Omitting it discards useful early deaths and survivors. The pooled estimate combines the first-year information from both cohorts with the conditional second-year information from cohort A.
Thus lack of two-year follow-up is handled by censoring, not by removing the entire short-follow-up cohort. This is cohort pooling under administrative censoring. The criticism assumes comparable time-since-entry survival distributions: if enrolment cohort or calendar period genuinely changes the hazard, naive pooling is not justified. One should model or stratify that effect, and an estimand specifically restricted to cohort A may appropriately use its own survival distribution.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 46 4 b i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use time since enrolment, and assume the cohorts share a common survival distribution with independent administrative censoring. The PDF starts cohort A in 2006, not the corrupted 2000 date in the TeX aid. During the first follow-up year the pooled sample begins with 200 subjects and has deaths, with no earlier censoring. By part (a),At one year, the 69 remaining cohort-B subjects are administratively censored. Cohort A supplies 72 subjects at risk for the second follow-up year, with 24 deaths and 48 survivors. ThereforeThe given grouped totals suffice because there is no censoring inside either follow-up interval; no assumption about the ordering or ties of its deaths is needed.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 46 3 b iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Set , , and . Then andThe integrated offsets are known and enter only as constants in estimation of . Let and assume and every at an event is small compared with . Expanding the score givesNow write and retain first-order terms in . Since , the equation becomes . Therefore the exponential rate with a small known additive hazard estimate isThe correction is negative: some event risk is already supplied by the known additive hazards. As a check, if every , the score equation gives the exact positive interior estimate . The approximation is intended for small offsets and a positive interior solution; a negative approximation or no observed events requires handling the boundary rather than reporting a negative rate.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 46 3 b ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Write and . The exponential survival likelihood has . Its score is , and for its second derivative is . Thus the exponential-rate estimation from censored exposure givesAll observation times, including censoring times, belong in . If , the likelihood decreases with positive and has its supremum as ; under the stated strict positivity constraint there is no interior maximum.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 46 3 b i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Put . With common Weibull distribution parameters and the hazard from part (a), substitution into the general log-likelihood givesThis is up to censoring-mechanism terms independent of . For and fixed , its maximizing rate is ; the shape still requires separate estimation if it is unknown.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 46 2 b iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14An ethical objection concerns the proposed saving of control-prison staff costs: the trial is explicitly based on individual informed consent, and institutional allocation does not justify omitting control participants' information, consent or appropriate outcome follow-up. These responsibilities remain in both arms. A cluster-randomized trial can sometimes be ethically defensible, but changing the randomized unit alone does not make those participant protections unnecessary.
The statistical objection is loss of independent information and potential prison-level imbalance. Outcomes within a prison may share baseline risks, management practices and release conditions, yielding positive intraclass correlation. For equal cluster size , the usual exchangeable approximation gives design effect , so the individual-randomization calculation understates the sample required when . There are also fewer independent randomized units, and prison-specific adoption of management practices can be unbalanced across arms. Thus randomizing prisons generally loses precision for this individually deliverable intervention, unless compensating design features and additional clusters are supplied.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 46 2 b ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use individual stratified randomization within each joint combination of prison and the three prespecified addiction-management categories. Within every joint stratum, use permuted-block randomization with equal numbers of active and control assignments in each completed block. This directly balances allocations within prison and within management category, rather than hoping that simple independent allocation will achieve both.
Run the allocation sequentially, since the availability and frequency of management categories change during recruitment. Completed blocks balance contemporaneously, so the expanding category is not assigned predominantly to one trial arm. Use varying block sizes and centrally protected allocation concealment to prevent prediction of future assignments. Incomplete final blocks allow a small residual imbalance, and an odd stratum total cannot be split exactly equally. If many joint strata are very sparse, a prespecified randomized minimization in clinical trials scheme can instead target the prison and management margins, retaining a random component. The analysis should account for the important design strata.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 46 2 b i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use equal individual allocation, a two-sided 5% test as in part (a), 80% power, complete four-week ascertainment and the supplied fatal-overdose endpoint. Then , , and . Substituting into the sample size for comparing two proportions givesRounding upward for equal allocation givesThe corresponding expected endpoint counts are about 148 in the control arm and 103 in the active arm. The one-third eligibility proportion affects how many prisoners must be screened, not the number of eligible participants randomized; at full consent and eligibility ascertainment, roughly three times this randomized total would need screening. Loss to follow-up, nonadherence or a changed baseline mortality risk would require a separate design adjustment.
The wording needs an endpoint qualification. The supplied risk is death from overdose, and the proposed effect concerns preventing those deaths. It does not give the incidence of all overdoses. Thus the calculation above sizes fatal overdoses, the intended endpoint supported by the data. For a literal 30% reduction in all overdoses, the unknown baseline incidence must replace in the formula, with . This is the endpoint-specific rare-event sample size issue: the same fatal risk can coexist with many nonfatal rates. For example gives about 29525 per arm, whereas gives about 2838; knowing only the fatal rate cannot determine that latter sample size.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 41 5 b i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Statistician B uses the more appropriate analysis. Its start–stop representation includes left truncation as well as right censoring. Both entry and exit are ages since opening, so a business belongs to the risk set at age only when . The event indicator distinguishes closure from a censored end of observation. The counting-process representation does not mean that multiple closures per business have been observed.
Statistician A records only exit and status and treats every sampled business as at risk from opening. That incorrectly adds already-established businesses to risk sets at ages before they entered observation, ignoring their necessary survival to entry. Its first risk count is , whereas B's is . The extra non-events dilute early estimated closure hazards and here bias the estimated survival upward. Correcting left truncation makes later risk sets capable of increasing as businesses enter at their respective ages.
For the Kaplan–Meier estimator with delayed entry, at event ages with closures and businesses at risk,The standard error follows from the Greenwood formula. Between event times this survival function estimate is constant. At age five the last preceding event is at , and at age ten it is at . Thus the requested estimates, including their precision, areandThese correspond to estimated proportions 46.2% and 28.0%, not to the probability of surviving five or ten additional years conditional on being sampled at an arbitrary age. A's corresponding estimates and use the inappropriate risk sets.
This interpretation assumes appropriately independent entry and censoring and a suitable common lifetime distribution across entry cohorts. A delayed-entry correction does not remove arbitrary informative sampling or calendar effects. More generally, if no observation covers the earliest ages, absolute survival from opening requires additional information about survival before the first observable age; the reported product-limit normalization is the one used in the supplied analysis.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 41 5 a iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14With left truncation, a subject is observed only if it survives to its entry time : subjects with are absent from the sample. A business already operating when observation begins has this delayed-entry mechanism. It joins a risk set only after its recorded entry age. Left truncation excludes earlier failures entirely; left censoring instead includes subjects whose event is known to have happened before a specified time. These mechanisms must not be conflated.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 41 5 a ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14With right censoring, an event has not occurred by the last observation time , so the data establish only . One records and , distinguishing an observed event from a censored exit. A business still operating at the follow-up deadline is administratively right-censored. Its observed age is a lower bound on its lifetime, not its eventual closure age. Standard survival analysis requires suitable independent censoring, possibly conditional on the fitted covariates.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 41 5 a i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Survival data describe the time from a specified origin to an event, together with covariates and information about how observation begins and ends. Some event times are observed exactly; others are subject to censoring or excluded by truncation. Here the time origin is the opening of a business and the event is its closure. An observed record contains an entry age, an exit age, an event indicator and the business characteristics. The time origin and observation mechanism are part of the data specification.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 4 5 b ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Take and . If , the Nagao module theorem with puts every vertex- summand of inside . In particular its Green correspondence summand satisfies .
Conversely a central idempotent acts as zero or one on the indecomposable module . If , apply the same theorem to . Its Brauer image is , so , incompatible with . Thus
For the unheaded induction request, write . We prove the sharper intersection bound, not just a drop in module vertex size. We use Green correspondence on permutation bimodules and the usual module vertex test for a permutation-module summand: its Brauer quotient of a module at is nonzero precisely when a module vertex contains a conjugate of . This test follows by restricting to the -group , decomposing the permutation basis into its orbits, and noting that proper-orbit sums are precisely the proper-subgroup transfer terms.
Consider as a -module, with . It is the transitive permutation module induced from . Set and ; the latter contains . Its restriction decomposes asEach outside term has stabilizer a conjugate of a subgroup of . If a diagonal subgroup embeds into one of these stabilizers, then for an outside representative. Thus its diagonal module vertices are in the intersection error family.
Every indecomposable -summand of has module vertex . To justify this, its endomorphisms are right multiplications by elements of . The coefficient projection on this algebra has nilpotent kernel: every nonsingleton -orbit sum lies in the kernel of , by part 1(b), and that kernel is nilpotent by part 1(a). Hence no nonzero idempotent endomorphism can have zero Brauer image. Its image summand has nonzero Brauer quotient of a module at , and its module vertex, already contained in a conjugate of , must be .
Apply the general Green correspondence from part (a) to . If an indecomposable summand of has module vertex outside the intersection error family, its correspondent must be a summand of , since the outside double-coset modules have only error-family module vertices. It therefore has module vertex . Consequently every summand of not having module vertex has module vertex conjugate into an outside diagonal intersection. An intersectionwith projects in its first coordinate into with ; this is the error family required in the question.
Now form the split permutation bimoduleIts Brauer quotient of a module at is zero. Indeed , left multiplication by becomes multiplication by , and right multiplication by remains multiplication by . ThereforeHere is central in , so the last product is zero. Every indecomposable bimodule summand of consequently has module vertex in the outside intersection family, by the preceding paragraph, and has trivial module source since it is a permutation-module summand.
Since has vertex , necessarily . Let be a module source of at . The splitting remains a splitting after applying , since . Inducing to and applying givesA trivial-source bimodule summand with module vertex conjugate into is a summand of . Tensoring with turns this into a module induced to from (with the appropriate conjugate restriction of ). Thus every summand on the right is relatively projective for some , . Each lies in the left-hand side, and Krull–Schmidt theorem now givesThis proves Juhász induction refinement. If there are no outside elements, the error family is empty and the complementary module is zero.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 4 5 b i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Put . By equivariance of the Brauer homomorphism, is a central idempotent of , since . The Nagao module theorem asserts that, if , thenand every indecomposable summand of is relatively projective for a -subgroup of not containing . Because is normal in , its module vertices cannot contain even after -conjugation.
Here is a direct proof. As an element of , is a linear combination of -conjugation orbit sums supported outside . An orbit represented by has sumIts stabilizer does not contain . On , the element acts as the identity. Map the orbit-sum expression into by left multiplication, and compose on both sides with the -linear projection onto . It follows thatReplace each centralizer by a Sylow -subgroup of it using trace transitivity and its invertible prime-to- index. Project this identity further onto an indecomposable summand of . Its endomorphism ring is local by Krull–Schmidt theorem. A sum of nonunits cannot be the identity in a local ring, so one of the trace terms is a unit in . Multiplying the endomorphism inside that trace by gives as a single relative trace. The D. Higman criterion makes relatively projective for that Sylow subgroup , and . This proves the assertion rather than just invoking the theorem's name.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 3 1 c ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let , whose Dynkin labels are . Since is the sum of the two simple roots, its boundary distances in the dominant weight multiplicity formula for sl3 are . ConsequentlyFor a module in , this multiplicity is one in the two families having or , and two for and . For a module in , it is two in the families having or , and three for and . In each case, increasing by one increases the minimum only if neither nor already limits it.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 3 1 c i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14In the finite-dimensional setting, let denote the irreducible highest-weight representation of highest weight , where are nonnegative integers. Thus are its Dynkin labels. The target has labels . Write the highest-weight difference in simple roots asThe dominant weight multiplicity formula for sl3 gives zero unless are nonnegative integers, and otherwise givesFor completeness, this multiplicity is an actual count. In the sl3 interlacing character formula, use top row and bottom entry ; the target diagonal exponents are . The middle row obeys andEach allowable integral gives one Gelfand–Tsetlin basis vector. Subtracting the lower bound from the upper bound gives the minimum of , which reduces to . This proves the displayed multiplicity formula in the case at hand.
Since both summands have a nonzero weight space and their dimensions at sum to three, their multiplicities must be one and two. For multiplicity one, the minimum is zero. The cases and give and ; the remaining cases or give and . Hence the full family isFor multiplicity two, the minimum is one. The cases and give and ; the remaining cases or give and . ThusThe minimum conditions exhaust all cases and each listed module has the stated multiplicity. All candidate unordered pairs are . There are infinitely many at this stage; the question imposes no upper bound on their highest weights.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 3 1 b iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use the positive simple-root raising operators and . On the weight space of , the first maps both and to , while the second annihilates both. Consequentlyis a nonzero highest-weight vector; the remaining positive-root operator also annihilates it. Its Dynkin labels are , and the generated submodule is the irreducible highest-weight representation with that highest weight.
Put and , acting on both tensor factors. Direct calculation givesDefine the linearly independent tensorsThey both have weight , andTherefore . To prove that they exhaust this weight space, its weight differs from the highest weight by . The Poincaré-Birkhoff-Witt theorem expresses all descendants at that difference using and : the third possible operator is their difference. Hence the space has dimension at most two, and the two independent vectors already found give
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 3 1 b ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Take the simple roots and . A weight represented by is in the Closed dominant Weyl chamber exactly when . Among nonnegative triples of total four, the possibilities are . Using , their explicit weight space bases areEach listed tensor has the required summed weight, and the monomial basis from part (i) shows linear independence and exhausts all possible tensors of that weight. Thus these are all the requested bases.
Past exam of the mathematics course of the University of Cambridge 2008 iii Paper 3 1 b i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let be the coordinate basis of the defining representation of . Write for . The six form a basis of the symmetric power , with weight . A basis for the tensor product of Lie algebra representations consists of all 36 ordered tensorsThe order of the two factors matters; there is no quotient identifying their interchange.
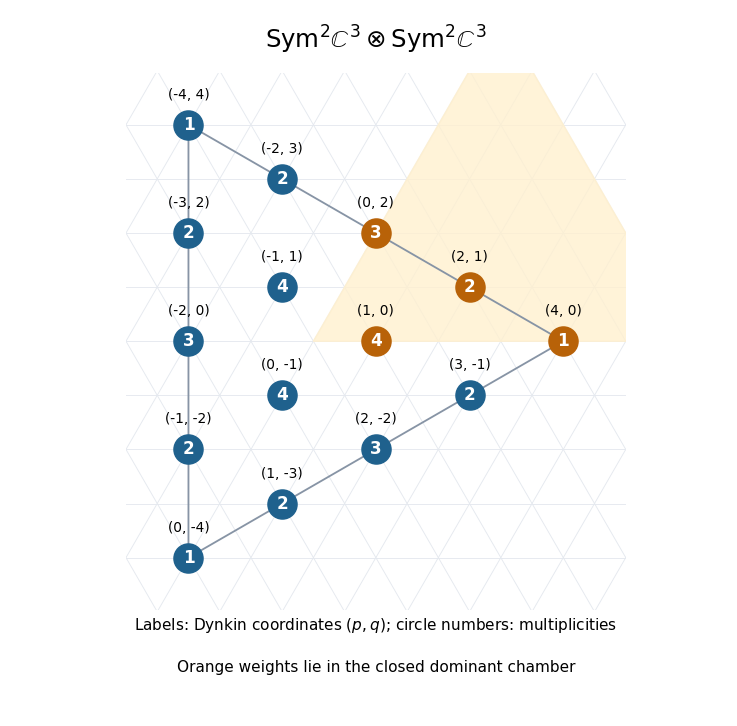
Each weight of a representation has the form , where the nonnegative integers satisfy . Its weight multiplicity is the number of ways to split this triple into two nonnegative triples, each summing to two. The possible patterns, including every permutation, areFor example, splits as , the reverse split, or , giving multiplicity three. For , the four splits pair with and with , each in both orders. The multiplicities sum to , verifying the dimension.
The following weight diagram uses Dynkin labels ; the circle numbers give multiplicities and orange points mark the Closed dominant Weyl chamber.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact