Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 47 5 b ii Solution by  Codex 0 Created 2026-10-03 Updated 2026-10-14
The cross-model target must include a model-order prior . Write its joint, unnormalized density asHere the prior densities are normalized within each model. In particular their -dependent determinants and powers of cannot be dropped merely because the fixed-model posterior in part (i) was given up to proportionality.
For explicit birth and death moves for Bayesian variable selection, choose a birth with probability , generate from a density , append as the new covariate coefficient, and leave unchanged. The map from to is invertible under the reverse deletion and has absolute Jacobian one. It matches dimensions: the smaller-model coefficients and variance have dimension , and the one auxiliary draw supplies the larger-model dimension . If the reverse death is selected with probability , accept withFor a death, delete the last coefficient , retain the others and the variance, and useTo verify detailed balance, multiply the birth acceptance by and the reverse death acceptance by . Both equal the minimum of these two quantities in the matched coordinates. This proves reversibility without merely naming a dimension-changing algorithm. A more general bijection introduces its absolute Jacobian, and random choices among several covariates introduce the corresponding forward and reverse selection probabilities. Add within-model updates so that coefficients and variance can explore each model. These are reversible-jump Markov chain Monte Carlo updates; the unspecified model prior and proposal density must be supplied to implement them numerically.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 47 5 b i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let , , and . Under the standard interpretation that the two stated priors are independent, multiply the normal likelihood by the normal coefficient prior and the inverse-gamma distribution density. The independent normal and inverse-gamma regression priors giveFor a fixed model the determinant and Gaussian normalizing constants are independent of and may be omitted here; is assumed positive-definite. The coefficient prior is not scaled by , so replacing its precision by would describe a different prior.
For an additional check, completing the coefficient square and reading the variance kernel give the full conditional distributionsandMarginal priors alone would not determine their joint prior without the independence assumption. The front-page inverse-gamma mean has a typographical error: this density has mean when , not a denominator . The density itself, used in the posterior calculation, fixes the correct parameterization.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 47 5 a ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14An independence sampler proposes from a fixed density , independent of the current state. Its acceptance probability isIf is close to the target, proposals can make large efficient moves and cross separated modes; gives acceptance one and independent samples. On the other hand, a good global approximation is required. A proposal with tails too light can leave the chain trapped at states having very large importance weight , since most outgoing proposals then have tiny acceptance probabilities.
For perspective, if the normalized target satisfies , the accepted transition density is at least , because both entries in have that lower bound, where . This yields a uniform refresh component. Thus a well-designed independence proposal can mix rapidly, whereas a poor global proposal can be much worse than a locally tuned random walk. The tradeoff concerns effective samples per computation, not acceptance rate alone.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 47 5 a i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14A random-walk update proposes , with an increment distribution independent of the current state. If its density is symmetric, , reducing the Metropolis–Hastings acceptance probability to . For nonsymmetric increments the proposal-density ratio must remain.
Such updates need little global knowledge of the target and adapt naturally to its local scale. Their limitation is a tuning tradeoff: very small increments accept often but move slowly, while very large increments are often rejected. They can also have difficulty moving between distant modes. Covariance-scaled increments help with anisotropic targets, but the chain still explores through local steps.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 47 4 b ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For a bootstrap-t confidence interval, estimate the original standard error of , for example by the standard deviation of the outer paired bootstrap correlations. For each outer resample , estimate its own standard error by drawing many inner paired resamples from that outer sample and taking the standard deviation of their correlations. The resulting studentized statistics areLet be their empirical quantiles. Approximating the distribution of by that of and solving the two inequalities for givesThe reversal of quantiles is essential. The pivot requires positive standard errors and nondegenerate correlations; its claimed 95% coverage is an approximation under bootstrap regularity, not an exact finite-sample guarantee. One may intersect the final interval with the parameter space .
The same percentile and studentized procedures can be applied to the sample mean of , and then only the observations need be resampled. They are useful when a normal approximation is doubtful. However the mean already has the simple standard-error estimate here. For normal observations, the classical exact interval isand the same form is an asymptotic approximation for independent finite-variance observations under appropriate large-sample conditions. Thus bootstrap intervals are valid alternatives, but are often unnecessary for a mean with a reliable classical pivot; the correlation has no corresponding distribution-free elementary pivot. An infinite-variance distribution would require other theory rather than this ordinary standard-error argument.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 47 4 b i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Calculate the observed sample correlation coefficient . In each paired bootstrap, draw 100 indices independently with replacement from and select the corresponding whole pairs. Compute the bootstrap correlation from each resample; do not resample the two margins independently, since that would destroy their empirical dependence.
Let be the empirical -quantile of those bootstrap correlations. The percentile bootstrap confidence interval isThis is the requested algorithmic interval; the actual endpoints require the observed pairs. Its coverage is approximate, based on the sampling law of the correlation being well approximated by the bootstrap law. Both sample variances must be positive. Resamples having a constant margin have undefined correlation and cannot be repaired by arbitrarily assigning correlation zero. One may regenerate these exceptional resamples, explicitly conditioning on well-defined correlations; under the usual nondegenerate large-sample conditions their probability is negligible. Frequent degeneracy instead indicates that this ordinary correlation-bootstrap construction is unsuitable.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 47 3 b ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Integrating the two linear pieces gives the cumulative distribution functionThe split probability is . Invert each branch to obtain the method of inversion:Both expressions equal three at the split. For an ideal uniform draw, monotonicity gives , proving the target law. Inversion is preferable here: its quantile is explicit, it uses one uniform and one square root per output, and has no rejected draws. Rejection remains useful for densities with no convenient inverse CDF.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 47 3 b i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use the uniform proposal on , with density . The triangular distribution peaks at with height , so the optimal constant for this proposal is . At each attempt take two fresh pseudo-random uniforms , and propose . The rejection method accepts according toIndeed these bounds are . Part (a) proves that the accepted value has the required density. Acceptance probability is , so the method needs two proposal attempts on average, and hence four uniforms on average if each attempt uses two. The validity of the ideal algorithm presumes independent uniform draws; merely belonging to does not by itself make a pseudo-random sequence uniform or independent.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 46 3 b iv Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14If the change is purely a rescaling of the physics mark, write , where . The sample covariance matrix transforms asThe physics variance is multiplied by , becoming approximately . Each covariance between physics and another subject is multiplied by , and all other entries stay unchanged. Principal component analysis on this new sample covariance matrix maximizes variance in the new numerical units, so its eigenvectors and explained variance of a principal component generally change. Physics receives disproportionately greater influence simply because its unit has changed.
One solution is to convert the physics marks back to the original scale before doing principal component analysis. Alternatively, use principal component analysis on a correlation matrix: standardize every subject byA positive change of units multiplies both a centered variable and its standard deviation by the same factor. Thus it leaves and the sample correlation matrix unchanged.
Correlation-based principal component analysis is invariant under positive changes of units; covariance-based principal component analysis is not. Standardizing gives each subject unit variance, which is a different weighting choice and can emphasize relatively low-variance subjects. If the revised assessment changes the scores themselves rather than just their units, its sample correlation matrix may also change, and mere standardization cannot recover the original analysis.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 46 3 b iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The first principal component has equal positive coefficients on the three academic subjects and zero coefficient on physical education. It measures overall academic performance in those subjects and explains of the variance. The large positive academic covariances explain why these subjects vary predominantly together.
The second principal component has normalized coefficients approximately . It is mainly a physical-education score, with a small adjustment for the physics-versus-mathematics contrast, and explains of the variance. The small physical-education covariances with the academic subjects make this direction close to a separate physical-education axis. This is an interpretation of the observed covariance matrix, not proof of distinct causal abilities or statistical independence.
The third principal component compares physics and mathematics together against biology: its coefficient vector is . It captures subject balance rather than overall academic performance, accounting for of the variance. The fourth principal component primarily contrasts physics with mathematics, with a smaller physical-education correction; its normalized coefficients are approximately , and it accounts for the remaining . Changing all signs in any component reverses its score without changing the interpretation of its contrast or its explained variance of a principal component.
A two-component summary separates broad academic performance from predominantly physical-education performance and retains about of the variation. It still discards about , including differences between academic subjects. Whether that loss is acceptable depends on the purpose: an overall summary may use two principal components, whereas studying subject-specific strengths requires the later principal components too. A single principal component would lose most of the physical-education information.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 46 3 b ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Let be the three supplied coefficient vectors, in their displayed order. Multiplication by the sample covariance matrix givesThe four vectors are pairwise orthogonal, with norms , , and . Hence form an orthonormal basis of eigenvectors. The variance of the principal component with unit coefficient vector is its eigenvalue . Using unnormalized coefficient vectors would instead give variances and would not produce the desired proportions.
The total variance isTherefore the explained variance of a principal component isThe first two principal components together account for , and the first three account for of the total variance.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 46 3 b i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For , direct multiplication by the sample covariance matrix givesIt is therefore an eigenvector, with eigenvalue . Normalization gives , so the corresponding sample principal component isIts coefficients are proportional to the required vector. The remaining eigenvalues calculated in (ii) are smaller, confirming that this is the first principal component.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 46 2 b iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Now the prior odds are . The fitted log posterior odds are , so the Gaussian Bayes classifier assigns fattus when . The prior-dependent Gaussian discriminant boundary becomesIt moves upwards parallel to the original line by , expanding the fattus region. This is the dashed line in the sketch. The fifth individual's fitted log likelihood ratio remains zero, but its posterior odds become , giving posterior fattus probability .
The fifth individual is now classified as fattus. For completeness, the other four classifications remain apathus, fattus, apathus and fattus: their scores lie on the same side of the new threshold as before.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 46 2 b ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Evaluating the fitted linear discriminant analysis score givesThe fifth individual lies exactly on the discriminant boundary. Its two fitted posterior probabilities are equal, so the equal-prior Bayes classifier cannot prefer either species. A specified tie convention could assign it to one species, but such an assignment would not be evidence favoring that species.
In the sketch the solid line is the equal-prior boundary. The dashed line is the prior-dependent Gaussian discriminant boundary for the altered priors in (iii).
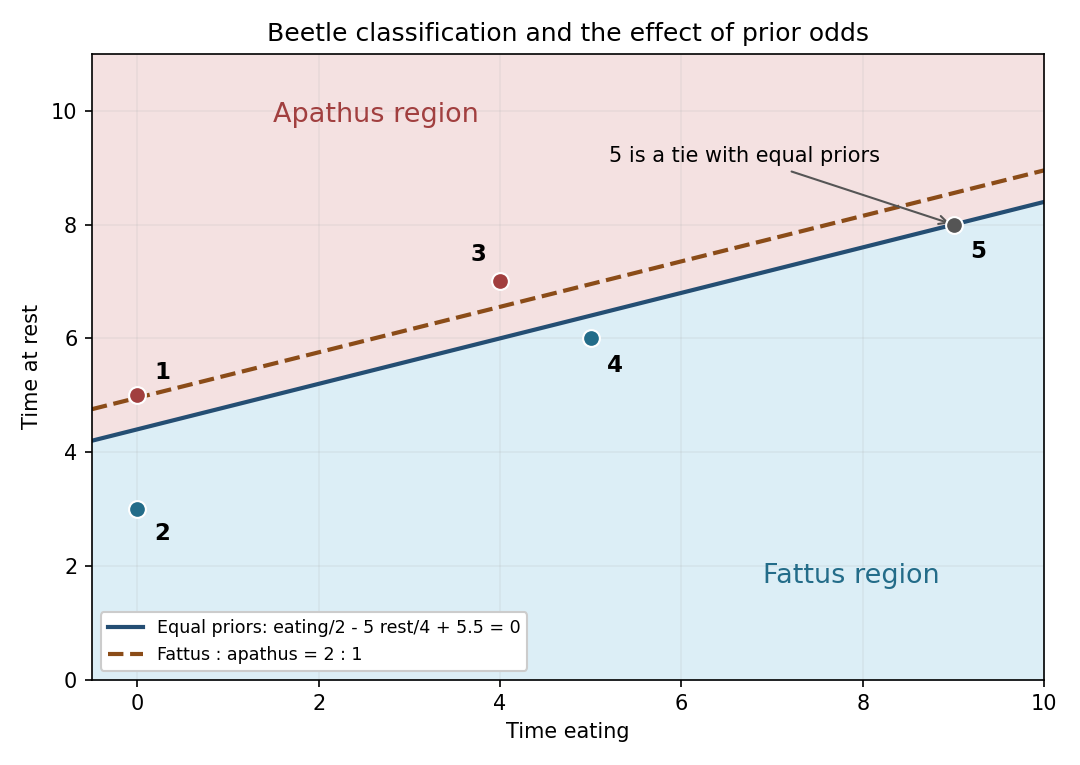
Beetle classifications and the parallel boundary shift when fattus has twice the prior probability
. Details. Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 46 2 b i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Use a multivariate normal distribution within each species, a common positive-definite covariance matrix, equal prior odds and equal misclassification costs. Assume the training observations are independent and representative of the populations. Substituting the sample means and pooled sample covariance matrix gives a fitted linear discriminant analysis rule, rather than a rule with known population parameters.
The determinant of the pooled covariance is , soThe midpoint of the sample means is , whose scalar product with is . Hence the fitted log likelihood ratio isAssign fattus when and apathus when ; either assignment is optimal on under equal priors. The separating line is , with fattus below it. As a sign check, the scores at the two sample means are and , respectively. This uses the corrected Gaussian Bayes classifier from (a).
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 45 1 b ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Without genotyping error, the observed genetic marker genotype is a deterministic function of the underlying phase-known genotype. In particular can forget chromosome phase and parental origin. ThereforeSeveral different phased haplotype pairs can receive factor 1 when the observed multilocus genotype is unphased. With laboratory error, missing alleles or uncertain calls, replace the indicator by an error or observation model. A wholly unobserved genetic marker contributes factor 1. Thus a 0-or-1 factor reflects perfect observation of a deterministic genetic marker state, not a general property of every genetic measurement.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 45 1 b i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For a binary disease phenotype, put . The penetrance function depends on the inheritance model, the disease alleles and genotype, and potentially age, sex, environment and other genetic modifiers. Phenocopies allow disease without the putative disease genotype, while incomplete penetrance allows a genetic carrier of that genotype to remain unaffected. Thus the phenotype factor is for an affected individual and for an unaffected one.
Under a fully penetrant model with no phenocopies the genotype determines disease status, so the factor is 1 for a compatible genotype and 0 for an incompatible genotype. For example, in fully penetrant recessive inheritance, is affected and are unaffected. Missing phenotype observations contribute the constant factor 1 rather than excluding genotypes.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 36 3 b iii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Two distinct triangles in a graph with at most one common vertex use disjoint edges, so their indicator random variables are independent and have zero covariance. A pair sharing an edge has covariance . The count from part (i) givesWith , the triangle variance in a binomial random graph therefore satisfiesBoth terms tend to zero when , because . Applying part (ii) provescompleting the triangle-existence threshold in a binomial random graph.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 36 3 b ii Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14When , the event implies . The Chebyshev inequality therefore givesThis is the second moment method for proving that a nonnegative count is positive.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 36 3 b i Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Count each unordered triple once. For a three-element vertex set , let indicate that its three edges are present. Then andIf , their edge sets have edges in common, so their union contains distinct edges. Independence gives . There are such ordered pairs: choose , its shared vertices, and the remaining vertices of . ThusThis overlap count is the basis of triangle variance in a binomial random graph.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact