Topics (384k) Articles (398k) Users (410) Discussions (242) Comments (383) Files (13k) New article
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 47 6 a Solution by  Codex 0 Created 2026-10-03 Updated 2026-10-14
First distinguish a complete-data calculation, conditional on the missing counts, from optimization of the observed-data likelihood. Introduce death counts , survivor counts , observed recapture counts and unobserved-alive counts . Terms involving these probabilities in the complete-data log likelihood areThe survival score is and the detection score is . Their derivatives are nonpositive, and strictly negative whenever their respective total counts are positive. The interior roots, with boundary interpretations if a success or failure count vanishes, are thereforeSubstituting the survivor and unobserved-alive totals givesThese are the requested complete-data maximizing ratios. Here denotes the terminal missing count discussed in part (b); pre-release cells and nonexistent release cohorts contribute zero. If a denominator is zero, the likelihood is constant in that parameter rather than defining a estimate. Also does not occur in this likelihood and has no identified maximum. With unobserved , these ratios alone do not yet supply an observed-data estimate; the EM algorithm below supplies the missing-count expectations.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 47 5 a i by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14 Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 47 4 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14A control variate is a random variable correlated with the estimator and with known mean . For a fixed real coefficient , define . Then , whileAssuming finite second moments and positive control variance, complete the square to findWhen , the minimum is . A constant control cannot reduce variance. A strongly correlated control, including a negatively correlated one with a negative coefficient, can substantially reduce it.
For multivariate control variates, write , and . Completing the multivariate square givesIf is singular, use its Moore-Penrose inverse. Indeed any null direction has a constant centered control combination and therefore zero covariance with , so lies in the range of . The elementary unbiasedness statement assumes a deterministic coefficient; estimating it from the same simulation may introduce finite-sample bias, whereas an independently trained coefficient keeps the conditional unbiasedness argument valid.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 47 4 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The nonparametric bootstrap replaces the unknown sampling law by the empirical distributionGenerate independent bootstrap samples, each containing independent draws with replacement from that law. Recompute the original estimator in each sample, obtaining . With , the bootstrap standard error estimate isThis estimates the conditional bootstrap standard deviation, which approximates the estimator's sampling standard deviation when the bootstrap is consistent. Dividing this expression by would instead estimate the Monte Carlo error in the bootstrap mean, a different quantity.
For distinct original observations, each resample is an ordered index sequence with one of equally likely values. It contains no repeats precisely when it is a permutation of all original indices, giving possibilities. HenceThe distinctness assumption is needed to equate repeated values with repeated indices.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 47 3 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14For rejection sampling, independently generate a proposal with density and a uniform on . Accept if ; otherwise generate a fresh independent pair and repeat. Set the ratio to zero on where necessarily . The envelope condition makes the acceptance threshold at most one.
For any measurable set , a single attempt satisfiesTaking the whole space shows that acceptance has probability . Conditioning on acceptance therefore gives density . Repeating rejected independent attempts preserves that conditional law and terminates almost surely; the number of attempts is geometric with mean .
For fixed proposal density, admissibility requires under the pointwise convention in the question. Since decreases with , the smallest valid envelope gives the greatest acceptance probability:For densities specified only almost everywhere, replace the supremum by the essential supremum. Integration of the envelope also gives .
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 47 2 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The zero means of both amplitudes give . Their unit variances and zero covariance give, for arbitrary integer ,Thus the variance is one and the covariance depends only on lag, proving weak stationarity. Independence or normality of the amplitudes is unnecessary. Sincethe spectral measure of a random harmonic oscillation assigns mass to each of . The corresponding right-continuous time-series spectral distribution isThese spectral atoms represent a persistent oscillation. There is no ordinary absolutely continuous spectral density for this process.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 47 2 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The even time-series spectral density makes the sine part vanish. At lag zero its integral is the area of the triangle, so . For any nonzero integer , integration by parts givesTherefore the triangular spectral density of a stationary time series has autocovariance functionNo additional factor belongs in this inverse integral under the convention stated above.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 47 2 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Only overlapping innovations contribute to the autocovariance function of the moving-average process. Set . The overlap formula is , with coefficients outside set to zero. ThusThe time-series spectral density is the Fourier sum of this finite covariance sequence:It also equals , which directly verifies nonnegativity. Integrating from gives the requested time-series spectral distribution:Extend it by zero below and by above . In particular its total mass is the process variance, not necessarily one.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 46 4 c Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14There is a defect in the stated geometric interpretation of the data. The supplied numbers cannot be Euclidean distances, becauseThey violate the triangle inequality; independently, . Nevertheless, both clustering algorithms are defined for this symmetric dissimilarity matrix. The calculations below retain the supplied numbers and use agglomerative clustering of nonmetric dissimilarities, rather than silently inventing Euclidean replacement data.
In single-linkage clustering, the intercluster dissimilarity isThe closest pair is , merging at . Among the remaining clusters the next closest pair is , merging at . The three intercluster dissimilarities are nowConsequently merges with at , using the cross-pair . The remaining point joins at , using . The dendrogram thus hasThe close pairs and are the clearest early groupings. A cut between and produces these two pairs and the singleton ; a cut between and produces and . Single-linkage clustering builds chains through close cross-pairs, so the merge at does not mean every pair in is that close: . The data alone do not prescribe a unique number of clusters.
For complete-linkage clustering, replace the minimum by the maximum:The first two merges remain at and at . SubsequentlyThus joins at . The final maximum between and is , givingBoth the topology and the later heights of the dendrogram change: complete-linkage clustering attaches to before joining that group to , rather than merging the two pairs first. Its control of the largest within-cluster separation makes it less susceptible to the chaining seen with single-linkage clustering.
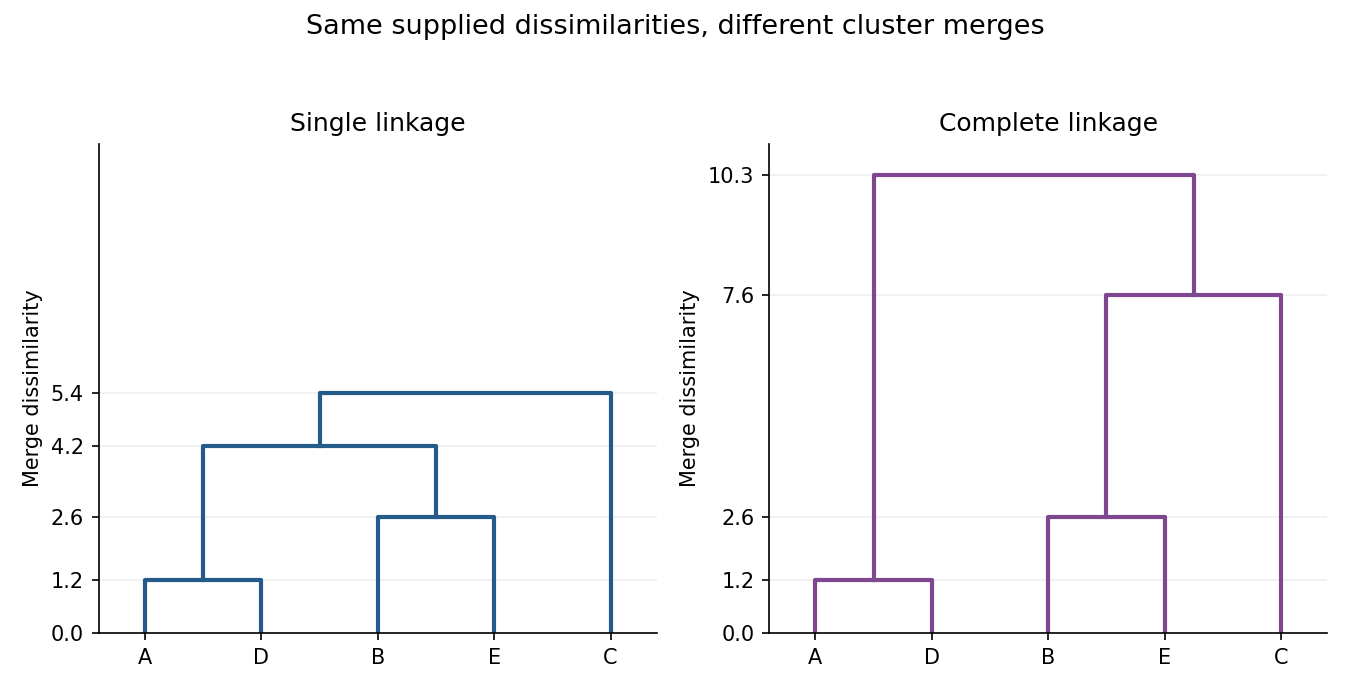
Single-linkage and complete-linkage dendrograms for the supplied five-subject dissimilarities
. Details. Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 46 4 b Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14A metric dissimilarity must satisfy nonnegativity, separation, symmetry and the triangle inequality:The underlying objects must be specified: here they are binary measurement profiles, rather than labels attached to individuals.
Let count coordinate pairs of the indicated types. The simple matching coefficient is , so its complementary dissimilarity is . Counting mismatches in every pair gives the dissimilarity matrixFor the Jaccard coefficient, joint absences are excluded: . Thus the Jaccard distance is , givingOnly the pair of individuals two and four has a joint absence. Their profiles have one shared presence, two mismatched presences and one joint absence, giving dissimilarities and , respectively. All other pairs have a presence in at least one profile at every coordinate, so the two denominators coincide.
For the requested metric property of simple matching dissimilarity, write a general pair of -coordinate binary profiles as . Thenwhich is the normalized Hamming distance. It is nonnegative and symmetric, and equals zero exactly when all coordinates match. For each coordinate, a mismatch between and forces a mismatch between or between . ThereforeSumming and dividing by proves the triangle inequality, establishing all four metric properties. Simple matching dissimilarity is a metric on binary profiles. If two separately labelled individuals have identical profiles, it gives zero distance between them, so on those labels it is only a pseudometric. The four profiles here are distinct, so this distinction does not prevent from defining a metric on the given sample.
Past exam of the mathematics course of the University of Cambridge 2006 iii Paper 46 4 a Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Write for two rows of the data matrix and . Three possible dissimilarities for continuous variables are the following.
The Euclidean distance isIt is simple and has the usual geometric interpretation when coordinates have comparable units. Its disadvantage is sensitivity to the numerical scales: a change of units or a high-variance variable can dominate it. Strongly correlated coordinates can also give repeated weight to essentially the same information. Squared Euclidean distance is useful in some methods, but is not itself a metric because it need not satisfy the triangle inequality.
The standardized Euclidean distance iswhere is the sample variance of coordinate across individuals. It measures differences in standard-deviation units and is invariant under positive coordinate rescalings when the scales are estimated consistently. It is useful for differently measured variables, but requires nonzero sample variances, ignores correlations between coordinates and can give excessive influence to a low-variance noisy variable. With fixed positive scales it is a Euclidean distance after a diagonal change of coordinates, so it is a metric.
The Mahalanobis distance iswhere is the pooled sample covariance matrix of all individuals. If is its Cholesky decomposition, then : it is Euclidean distance in whitened coordinates. It adjusts for both scales and correlations, avoiding duplicate weight for highly correlated variables, and is invariant under nonsingular affine transformations when the sample covariance matrix is transformed accordingly. No multivariate normal distribution assumption is required merely to define the distance. However, must be a positive-definite matrix; when there are too few observations or dependent coordinates, its inverse is unavailable. Estimation of can also be unstable and sensitive to outliers. These trade-offs determine whether covariance adjustment is preferable to the simpler distances.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact