
The pressure gradient and the gradient of mass density are misaligned in a baroclinic fluid. Their cross product contributes a source to the vorticity equation.
Paging divides an address space into fixed-size memory pages and main computer memory into equally sized page frames. Here assume byte addressing, one memory page size bytes, and an unsigned virtual address . Its virtual page number and offset areThe brackets denote the floor function, and gives the remainder in Euclidean division. If the page table maps to physical frame number and permits the access, the physical address isThe low bits are unchanged; the other bits select the memory page or page frame. A bit shift and bit mask can extract these fields. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/vm-paging.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 18: Paging, Introduction, sections 18.1–18.2
For a 16-bit virtual address and bytes, take in hexadecimal. Then and . A mapping to givesThus the eight high bits choose a mapping; the eight low bits choose the same position in the resulting page frame. The 256-byte size is for illustration, not a claim about an actual architecture's supported memory page sizes.
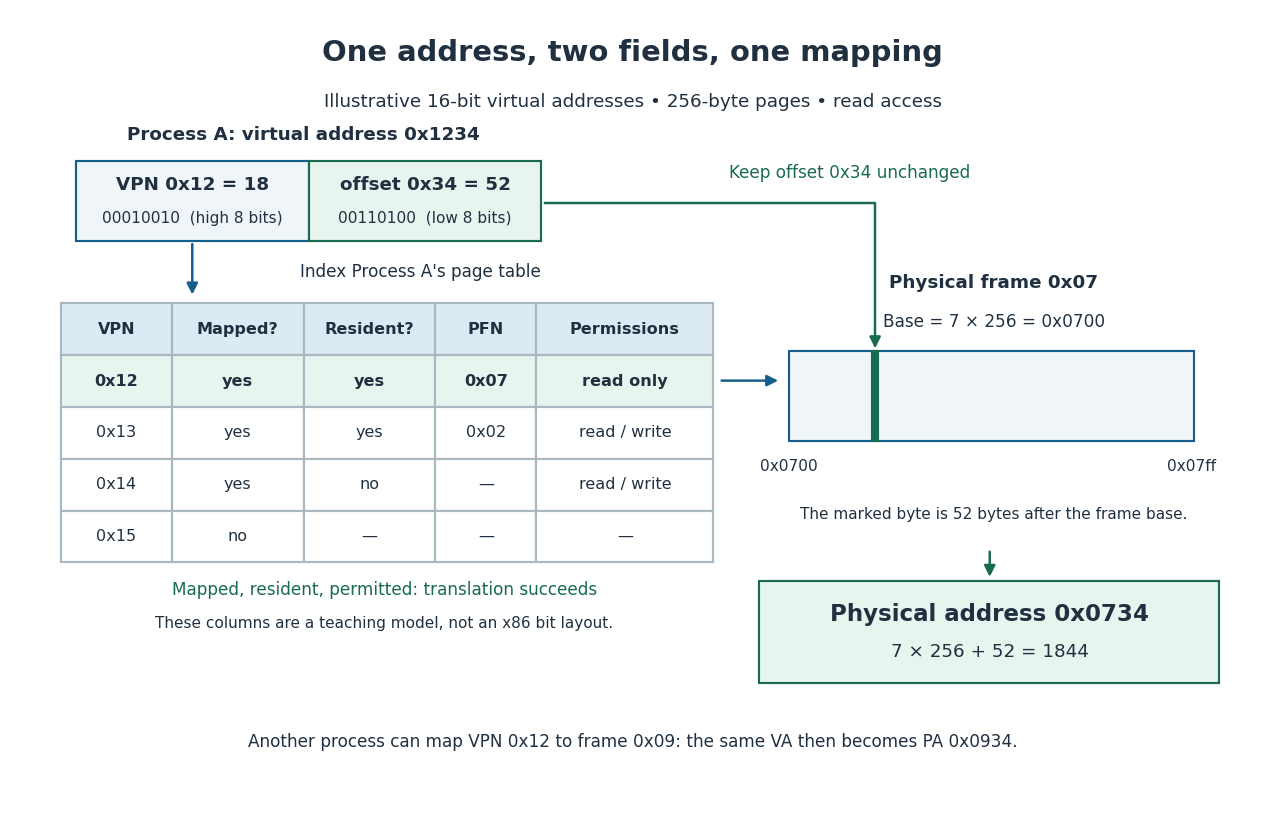
Translating 0x1234 through an illustrative page table, with a separate offset and access check
. Details. The useful freedom is that adjacent memory pages can occupy unrelated page frames. In the diagram, virtual pages
0x12 and 0x13 occupy page frames 0x07 and 0x02; virtual addresses 0x12ff and 0x1300 are consecutive, but translate to physical addresses 0x07ff and 0x0200. Uniform units simplify placement and page replacement, at the cost of page table storage and unused bytes within partly filled memory pages. For example, placing 300 bytes in exclusive 256-byte page frames requires two page frames, leaving bytes unused.Memory segmentation divides an address space into segments described by a base, limit and access attributes in the classic base-and-bound model. A logical address selects a segment plus an offset; the processor checks the offset against the limit and combines it with the base. This can associate different protections with code, stack and data. Paging instead divides mappings into fixed-size pages, and architectures can combine both mechanisms. Virtual-memory segmentation differs from an application's informal division of a flat address space into code and heap regions.
// Target: computer-science.bigb
A memory-mapped file makes a range of a file accessible through an operating-system process's virtual memory address space. Once the mapping exists, ordinary loads and stores address its contents instead of explicitly reading them into a separate application buffer. This is attractive for jumping between records in a large file: an offset becomes an address calculation, and demand paging can supply the needed memory pages. It removes the application's explicit read-and-copy step; it does not promise that every access avoids copying, input-output, page faults or overhead, or that mapping is universally faster.
The backing file, page cache contents and each operating-system process's page table play different roles. For ordinary buffered Linux kernel mappings, the page cache holds reusable file contents; normal reads and writes also use it. A valid mapping can exist before this operating-system process has a usable page table entry. A first load can therefore trigger a page fault even when another reader has already brought the contents into computer memory. If the contents are absent, servicing the page fault can require input-output; if present, the handler can install an address translation without that read. Special paths that bypass the page cache are outside this explanation.[ref]
Page Cache by The kernel development community. Page Cache, opening paragraph: normal reads, writes and mmaps go through the page cache; bypass paths exist
The following example and diagrams are an original toy model, not an actual benchmark or a trace of a running operating system. They assume ordinary buffered file mappings, successful accesses, two cooperating operating-system processes, no concurrent resizing, and explicitly ordered actions. Memory-mapped file offset translation explains where the accesses land; shared file mappings and private file mappings explain whose contents change; memory-mapped file synchronization explains the separate persistence boundary.
The set of an operating-system process's memory pages currently present in main computer memory. A resident set may omit recently used memory pages after page replacement, or retain memory pages that have left the chosen working set window.
// Target: computer-science.bigb
An operating-system process's working set is the set of distinct memory pages used in a declared recent window. Here the window counts memory references, not clock time: let identify the memory page accessed by the th memory reference, and let the positive integer be the window length. Immediately after reference ,Repeated memory references to the same memory page contribute only one set element. The working set size is the cardinality . This recent footprint estimates current demand; it cannot guarantee which memory pages future memory references will need. The resident set instead records which memory pages are actually present in computer memory.
For the 20-reference sequence in memory thrashing and , the successive working sets begin , , and . At , the window is references 2–5, namely , so again. Every later four-reference window contains all four memory pages. Under three-page frame LRU replacement, however, the resident set at is : page 2 was evicted. Consequently the working set size is four even though only three memory pages are resident. Under four-page frame LRU replacement, the resident set contains the complete working set after reference 4.
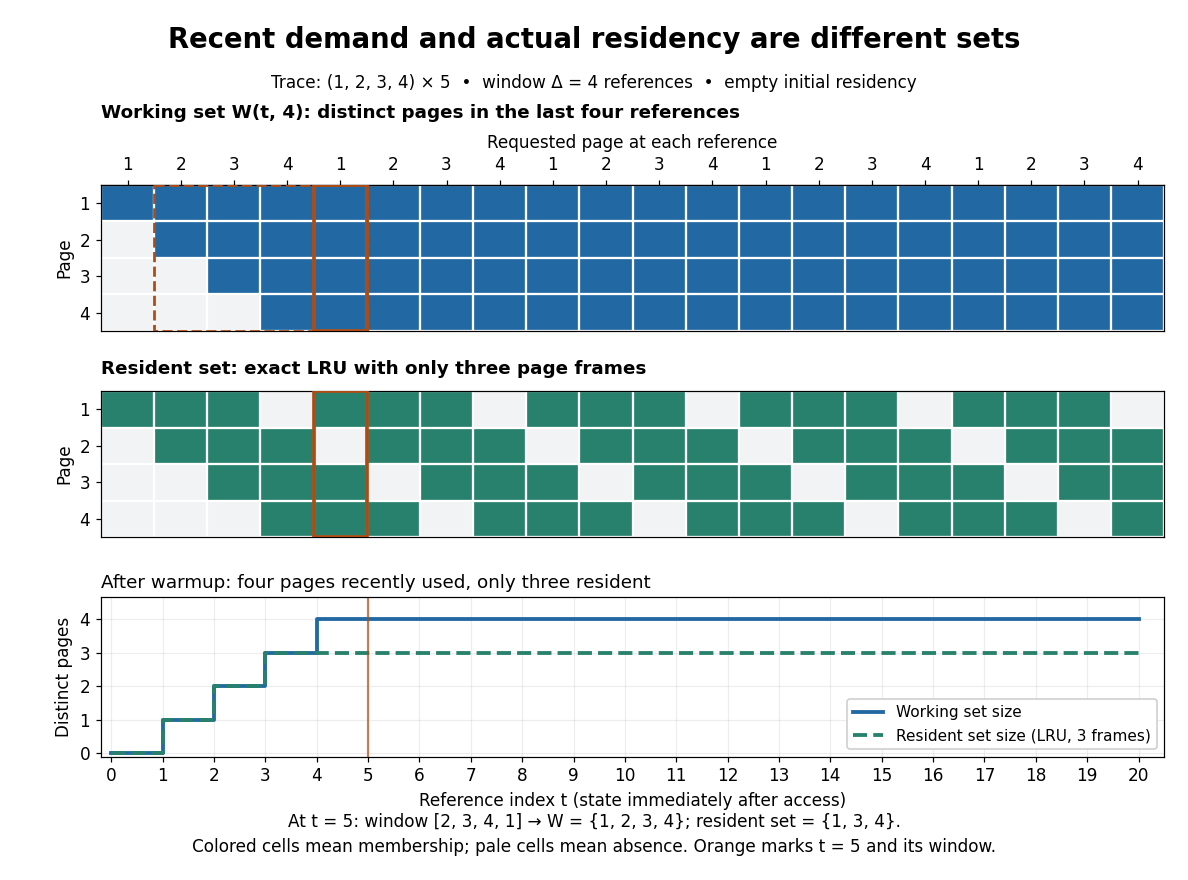
A four-reference working set remains four pages while a three-frame resident set contains only three
. Details. Window choice matters: on this same sequence, reports only two distinct memory pages after reference 2, despite the recurring four-page cycle. A short window forgets useful memory pages sooner; a long window retains evidence from older phases. Enlarging the window can only enlarge or preserve the working set at fixed , because the shorter window is contained in the longer one. No single window is best for every workload.
For a concrete multiprogramming budget, suppose three operating-system processes each have a four-page working set, no shared page frames, and only eight page frames are available for their data. Their combined demand is 12 page frames; all three working sets cannot be resident together. Letting two operating-system processes run while the third waits makes their eight-page demand fit in this simplified model. Real budgets also reserve computer memory for the operating system and other uses; shared memory pages must not be counted repeatedly as different physical copies.
Peter J. Denning's [ref]
https://denninginstitute.com/pjd/PUBS/WSModel_1968.pdf. The Working Set Model for Program Behavior, Communications of the ACM, May 1968, sections 3–4
formalized the working set using recent process execution time, rather than this article's reference count. Its central insight connected memory demand to process scheduling: deciding which operating-system processes run also decides which working sets need room. Temporal locality makes recent use informative, without making it a promise about the future. The beautiful distinction is between a large possible address space and the smaller footprint of the current activity.Memory thrashing is repeated costly cycling of memory pages out of and back into computer memory, leaving little useful computation between page faults. Active demand can exceed the available page frames, especially when multiprogramming admits too many operating-system processes. A high page fault rate during initial loading alone does not establish memory thrashing. [ref]
Beyond Physical Memory: Policies. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 22, section 22.11: Thrashing
Consider one operating-system process making the 20 memory references : five repetitions of four memory pages. Start with an empty resident set, use demand paging and exact LRU replacement, and assume no prefetching or competing operating-system processes. A hit finds the requested memory page resident; a miss requires a nonresident page fault. With three page frames, references 1–3 load pages 1–3. Reference 4 evicts page 1, reference 5 reloads page 1 and evicts page 2, and the cycle continues: every return finds its memory page evicted. With four page frames, only the first four references miss; all four memory pages then remain resident.
| Available page frames | Misses in all 20 memory references | Overall page fault rate | Misses in references 5–20 | Page fault rate in references 5–20 | 3 | 20 | 100% | 16 | 100% | 4 | 4 | 20% | 0 | 0% |
|---|
The four initial misses with four page frames are compulsory first-use misses from the empty resident set. They are startup work; the three-page frame case keeps faulting after startup. This makes the difference between memory thrashing and loading a new working set visible. For the three-page frame trace, each reused memory page has three distinct intervening memory pages, so LRU replacement has already evicted it before its next use.
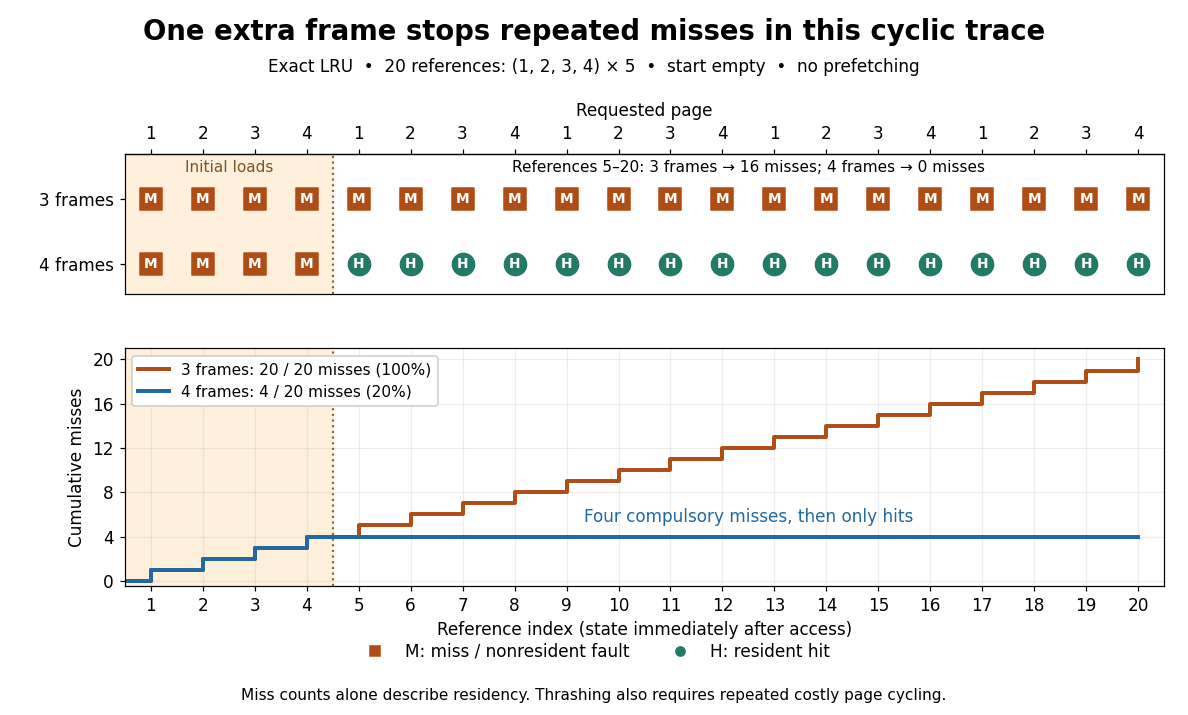
The same 20 memory references under LRU replacement: three page frames miss every time, four miss only during startup
. Details. To quantify the cost, assume each hit takes 100 nanoseconds and each miss incurs an additional 1 millisecond of page fault service, followed by the same 100-nanosecond memory access. These are toy latencies, not measurements. With miss probability , the expected value of access time isThe service cost is additional: it does not include the final 100 nanoseconds. Thus gives and gives , approximately a fivefold ratio over the complete trace. Over references 5–20, the corresponding ratio is : repeated page faults dominate the useful accesses. The expected value model follows the additive miss-penalty convention of OSTEP chapter 22, section 22.1. [ref]
Beyond Physical Memory: Policies. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 22, equation 22.1: average memory access time
Not every page fault performs disk input-output: demand paging can allocate zero-filled memory pages, and copy-on-write can copy an existing page frame. The toy service cost models expensive misses; the miss trace alone establishes residency behavior, while memory thrashing additionally concerns repeated costly cycling. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/vm-complete.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 23, section 23.1, Other Neat Tricks: demand zeroing and copy-on-write
Possible remedies are more resident page frames, less multiprogramming, or reorganizing accesses to improve temporal locality. For this toy sequence, one extra page frame suffices under LRU replacement; that is not a universal threshold or policy. Page replacement alone cannot make every simultaneously needed memory page fit.
// Target: computer-science.bigb
Copy-on-write defers copying until a modification needs private storage. With paging, separate address spaces can map their memory pages to the same page frames, using memory protection to prevent writes to the common contents. Reads need no copy. A permitted write to a shared page frame first separates the writer's storage, so the other operating-system process keeps the old contents. Sharing is safe because the common contents remain unchanged while shared; the logical private copies can still evolve independently.[ref]
Complete Virtual Memory Systems. pp. 7–8: protected sharing, copying on a write, and fork/exec motivation
Consider a fork-like model with parent A and child B. Each has a separate page table, with three inherited private, logically writable memory pages. Both initially map virtual page numbers
0x12, 0x13, 0x14 to page frames F0, F1, F2. The page table entries temporarily deny writes for copy-on-write; a read of x at offset 0x34 in virtual page 0x12 returns 7 in either address space. Separate page tables do not imply separate stored bytes.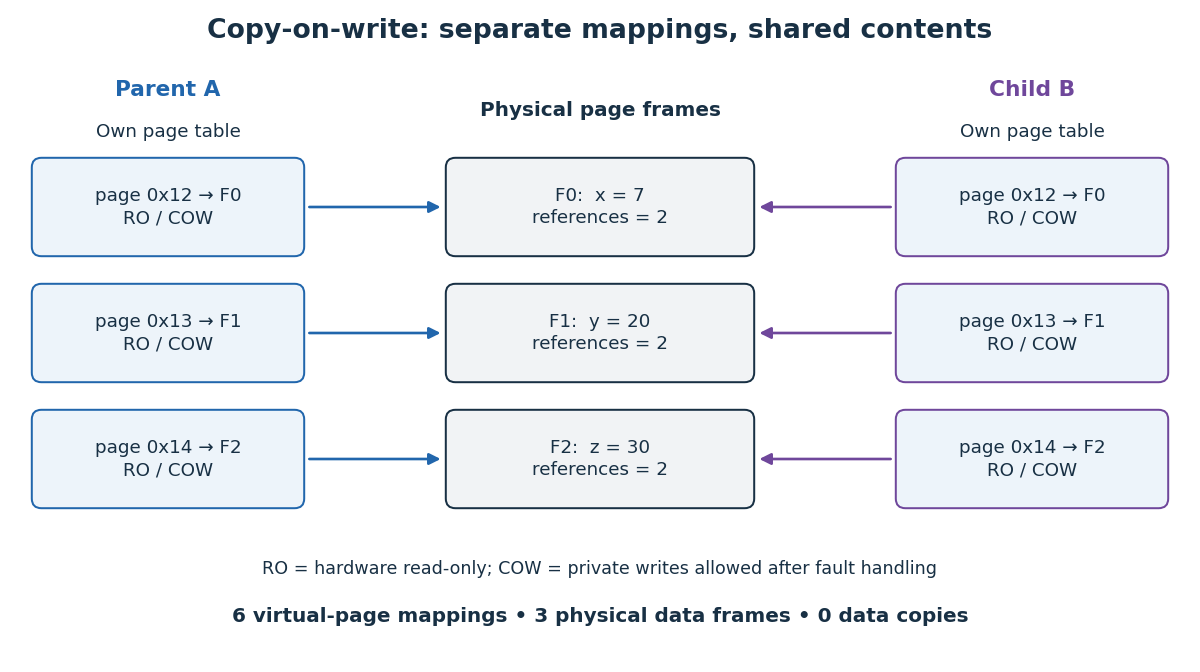


Now B writes
x = 42. In this model, copy-on-write fault handling allocates F3, copies all of F0's contents into F3, redirects only B's page table entry, enables its write, and retries the store. A still reads 7 through F0; B reads 42 through F3 at the same virtual address. F1 and F2 remain shared. The reference counting labels count mappings in this example: F0 drops from two to one, while F3 starts at one. Updating one byte can therefore copy a whole memory page.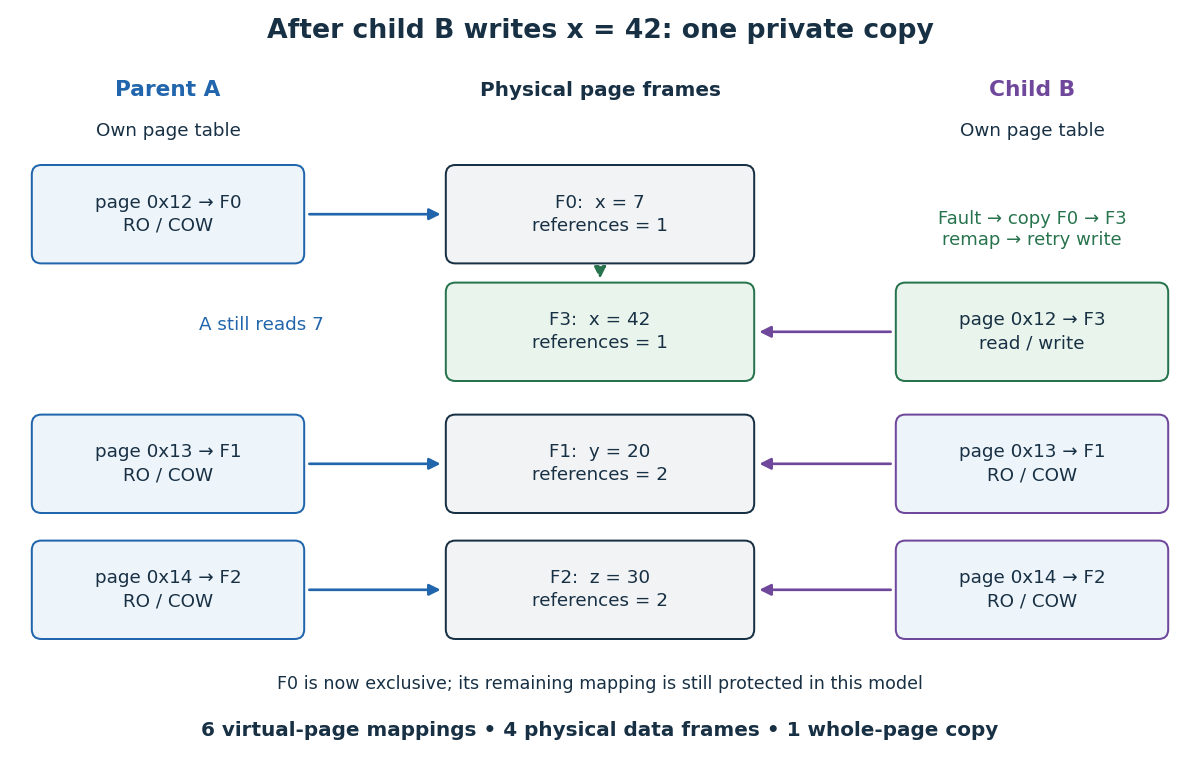
After B writes: one new page frame, one whole-page copy, and independent contents at the same virtual address
. Details. 
The attraction is avoiding work that may never be needed. If B only reads, this model makes no data copies; if B replaces its program and discards these mappings, copying them beforehand would have been wasted. Copy-on-write trades eager copying for protected sharing and later page faults. The page tables, reference counting, and operating-system process records still cost time and computer memory.[ref]
Complete Virtual Memory Systems. pp. 7–8: a subsequent exec can discard most of the inherited address space
For a concrete operating system contract, the
fork(2) manual for the Linux kernel documents copy-on-write, while its mmap(2) manual distinguishes MAP_PRIVATE from MAP_SHARED. Writes through MAP_PRIVATE are not propagated to other mappings or the underlying file; writes through MAP_SHARED are visible to other operating-system processes mapping that region. An inherited shared mapping therefore retains shared-write behavior. For a private memory-mapped file, visibility of later changes to the underlying file is unspecified: private writes alone do not guarantee a frozen snapshot of the file. [ref][ref]Nor does fork make every resource independent. With the Linux kernel, inherited file descriptors refer to the same open file descriptions, including shared file positions. Special mapping policies can omit a region from inheritance or zero it in the child. Thus the diagrams describe ordinary inherited private memory pages, not every resource reachable by a parent. [ref]
There are unlisted articles, also show them or only show them.