A decision tree represents a deterministic computation of a known Boolean function by inspecting input bits. Each internal vertex of its binary tree names a coordinate to query, its two outgoing edges carry answers 0 and 1, and each leaf carries the output 0 or 1. Starting at the root of a tree, read the named bit, follow its answer edge, and repeat until a leaf is reached. Correctness requires the leaf's label to equal for every input .[ref]
Complexity Measures and Decision Tree Complexity: A Survey by Harry Buhrman and Ronald de Wolf. Buhrman and de Wolf, Complexity Measures and Decision Tree Complexity: A Survey, section 3.1, manuscript p. 5: deterministic trees and D(f)
The next coordinate, or the decision to stop, can depend on earlier answers: this is adaptive querying. The same input always follows the same graph path; adaptivity does not require randomness. A correct leaf must have the same output for every completion of the observed bits. Thus a decision tree can stop as soon as the observations form a query certificate. Querying an already known coordinate adds no information, so we use decision trees without repeated coordinates on a graph path; an efficient tree also removes queries made after the output is already forced.
The motivation is exact computation with shortcuts. If inspecting an input entry is expensive, the question is how much of the input must actually be read. The decision-tree query cost counts these inspections, while local calculations on known values are free in this model; this cost need not equal an implementation's time complexity. Here the Boolean function is specified in advance and must be computed exactly on every input. Decision tree learning instead fits a predictor from data, with a different objective.
Three votes give a small but revealing majority function:Our decision tree queries , then . If these bits agree, return their common value: two equal votes already force the majority function. If they disagree, query and return its value. The first two queries have a fixed order, but whether a third query occurs is adaptive.
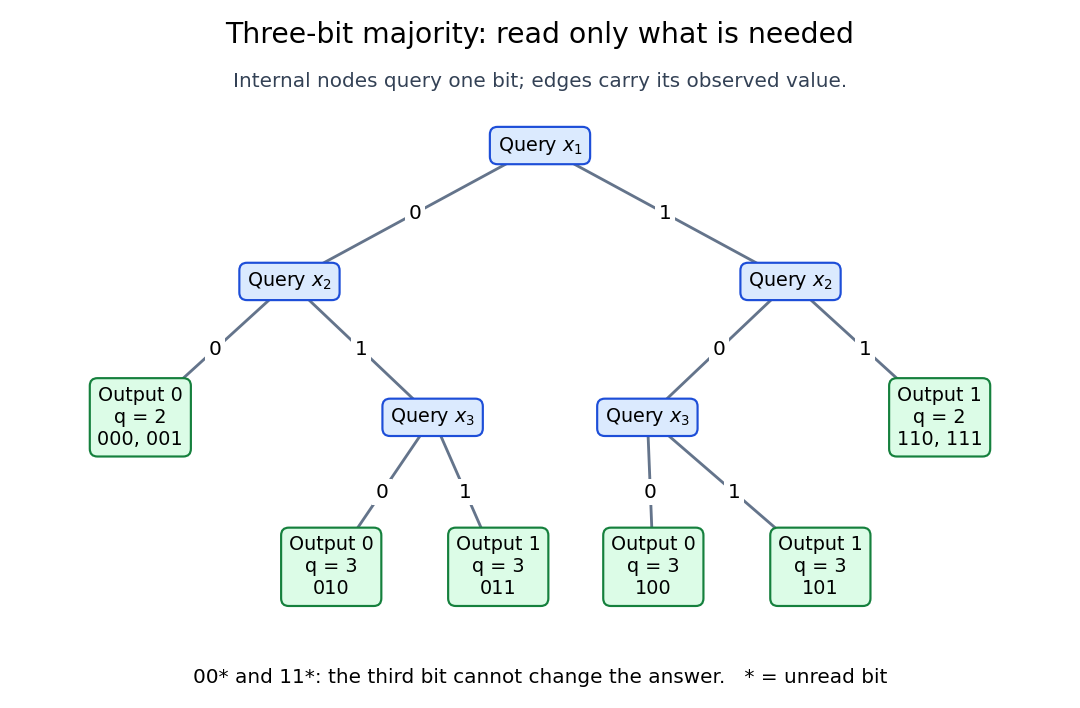

Each internal label in the diagram names the next bit to inspect. Each leaf lists its output, decision-tree query cost , and compatible inputs; an asterisk denotes an unread bit. The two shallow leaves each cover two inputs, while each deeper leaf covers one. Reading every bit would also compute the majority function, but would miss these exact shortcuts.
All eight inputs give the following exhaustive check. The parity column is the parity of , computed by exclusive or; its decision-tree query cost is justified under parity lower bound for Boolean queries.
The worst inputs for this decision tree are , exactly those with . Its actual depth is three. Every exact decision tree for this majority function has depth at least three: after the first query, an adversary can answer the second distinct query with the opposite bit, leaving the last bit decisive. Consequently its optimal decision-tree depth is , even though some inputs finish sooner. Every input has a two-bit query certificate, namely two agreeing votes; locating those votes can require a third query. This separates having a short query certificate from finding one.
For three bits, the Boolean function outputs one when is odd, where denotes exclusive or. Unlike the three-bit majority decision tree, an exact decision tree computing parity must inspect all three bits on every input. If any coordinate is unread, two completions differing only at that coordinate follow the same observed graph path but have opposite parity. A single leaf cannot correctly label both.
The same argument works for bits: parity needs all queries on every input, whatever their order. Thus its decision-tree depth is , its expected query cost is for every input probability distribution, and each coordinate revealment is one. The algorithm remains required to be correct on the whole Boolean cube, even if the chosen probability distribution assigns some inputs zero probability; a promise restricting permitted inputs would be a different computational problem.
For a particular decision tree , its decision-tree query cost is the number of queries along the graph path followed by input . Its actual tree depth isThe query vertices count as operations; each is followed by one answer edge. Thus a leaf reached after queries has graph path length , and a tree consisting only of an output leaf has depth zero. With no repeated coordinates, . The decision-tree depth minimizes over all correct decision trees for ; measures the chosen algorithm, while measures the Boolean function.
Choose an input probability distribution and let have that distribution. Then is a random variable even when the decision tree is deterministic. Its probability mass function describes how often each path length occurs, and its expected value is the expected query cost. None of these quantities changes the actual maximum depth of .
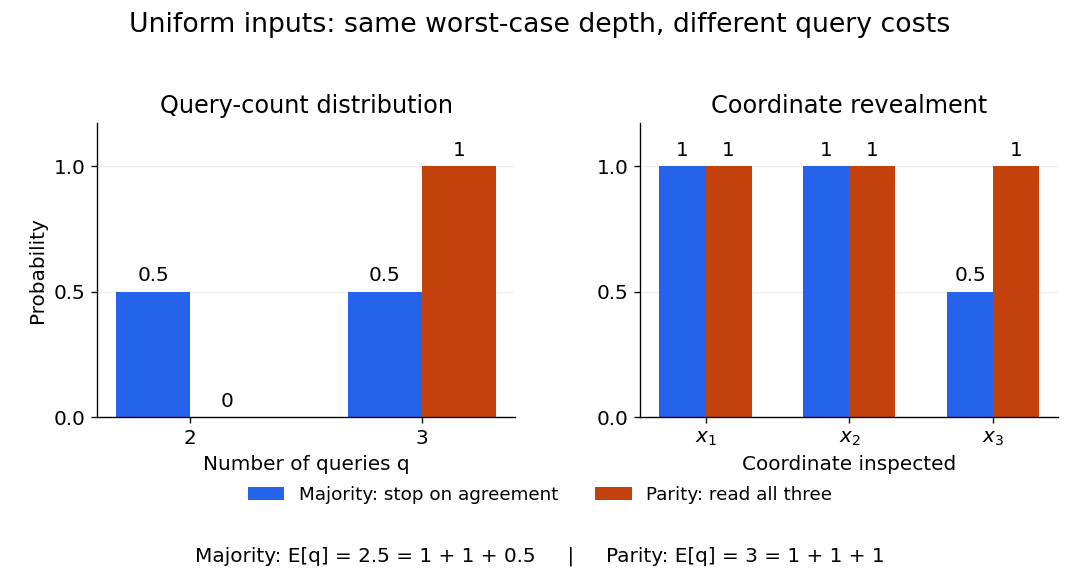
Uniform three-bit inputs: query-count distributions and coordinate revealment for majority and parity
. Details. 
The left panel aggregates the eight inputs from the three-bit majority decision tree: four cost two queries and four cost three. Parity always costs three. The right panel asks a different question, which coordinates are inspected: the majority function algorithm always queries coordinates 1 and 2, but queries coordinate 3 only on disagreements. These are probabilities of inspection, not probabilities that a bit equals one.
For a fixed decision tree and input probability distribution , its expected query cost isUnder the discrete uniform distribution on the eight three-bit inputs, the three-bit majority decision tree hasThis is an exact average, not a fractional query made during one execution. It is also optimal among exact deterministic decision trees under this discrete uniform distribution: one observed bit never determines the majority function; whichever two distinct coordinates are inspected first, their values disagree with probability , forcing a third query. In comparison, querying all three bits unconditionally has the same actual depth three but expected query cost three.
For an arbitrary input probability distribution, the same fixed three-bit majority decision tree gives . For three independent random variables, each a Bernoulli random variable with common one-probability , this becomes ; the value depends on . Averaging over inputs should also be distinguished from averaging over an algorithm's internal random choices at a fixed input.[ref]
The coordinate revealment of coordinate for a decision tree under input probability distribution isIt depends on the chosen decision tree and the probability distribution, not just on the Boolean function. Since no coordinate is queried twice on a graph path, indicator functions giveThe second equality uses linearity of expectation; it does not require independence of random variables or a product measure. The cited paper defines these inspection probabilities and their sum for product measures; the displayed indicator function argument extends the identity to any input probability distribution.[ref]
For the three-bit majority decision tree under the discrete uniform distribution, , whose sum is . Reading coordinate 3 first, then coordinate 1, and stopping on agreement gives the same majority function, depth and expected query cost, but coordinate revealments . The asymmetry belongs to the chosen query order. Parity gives for every exact decision tree without repeated queries. If repeated queries were charged, inspection probabilities would count distinct coordinates; total query count would instead require expected multiplicities.
The decision-tree depth of a Boolean function is the smallest possible maximum number of input coordinates queried along any root-to-leaf graph path of a decision tree computing :The actual depth of a particular decision tree can exceed this optimum. A constant function admits a depth-zero tree even though an inefficient algorithm could inspect its entire input before returning that constant. Expected query cost and coordinate revealment additionally require an input probability distribution; does not. The three-bit majority decision tree and three-bit parity both have optimal decision-tree depth three, although only the former has the two-query shortcuts described above.
A query certificate fixes some input coordinates to their values in a chosen input and must force the output for every completion. The smallest such size is ; maximizing over accepted or rejected inputs gives or , and maximizing both gives . A one-sided maximum over an empty output class is defined as zero. This is query certificate complexity, distinct from polynomial verification of a witness in NP.
For a Boolean function and a chosen input , a set of coordinates is a query certificate if every agreeing with on has . It fixes actual input bits rather than supplying an independently guessed certificate to an NP verifier. Minimizing its size at each input and then maximizing gives query certificate complexity.
A Boolean function is evasive when every deterministic decision tree computing it has a worst-case path that queries all input bits. The alternating-sum criterion for decision-tree evasiveness is one sufficient method for proving this lower bound.
A leaf reached before all input bits are queried leaves at least one coordinate free. Flipping that coordinate pairs its inputs with opposite alternating signs and equal output. Thus every such leaf contributes zero. If the total alternating sum is nonzero, a depth below is impossible.
To prove that a threshold function requires every input bit in the worst case, an adversary answers queries while keeping completions on both sides of the threshold possible. If this remains true until the final unqueried bit, every decision tree has depth equal to the number of variables.
Articles by others on the same topic
There are currently no matching articles.