Exactly , and can be sustained as constant stage game outcomes. Their long-run average payoffs are , and , respectively. We assume the usual repeated game monitoring convention: both players observe each completed joint action before the next round. The source's colour convention puts the blue lower-left row payoff first and the red upper-right column payoff second.
For necessity, row action earns against , so playing it forever guarantees a nonnegative long-run average payoff against every opposing pure strategy. Similarly, column action earns against and guarantees zero or more. Conversely, column action holds the row player's best possible stage payoff to , and row action holds the column player's to . Thus each player's minmax payoff is exactly .
Any Nash equilibrium must give both players at least zero, an individually rational payoff in a repeated game. Every off-diagonal cell has a negative payoff for one player: and hurt row, and hurt column, hurts row and hurts column. Repeating any such cell forever therefore permits a profitable unilateral deviation to the zero-guaranteeing action. The three diagonal cells pass this necessary test.
For sufficiency, fix target or . Each player's finite-state strategy has initial state and an absorbing state . In , output the player's component of ; remain in if the completed joint action equals , and otherwise move to . In , row always outputs and column always outputs , regardless of further observations. These are two-state grim trigger strategies; the separate machines are drawn below. The input is the observed joint action, so after any off-path history the prescribed continuation states agree.
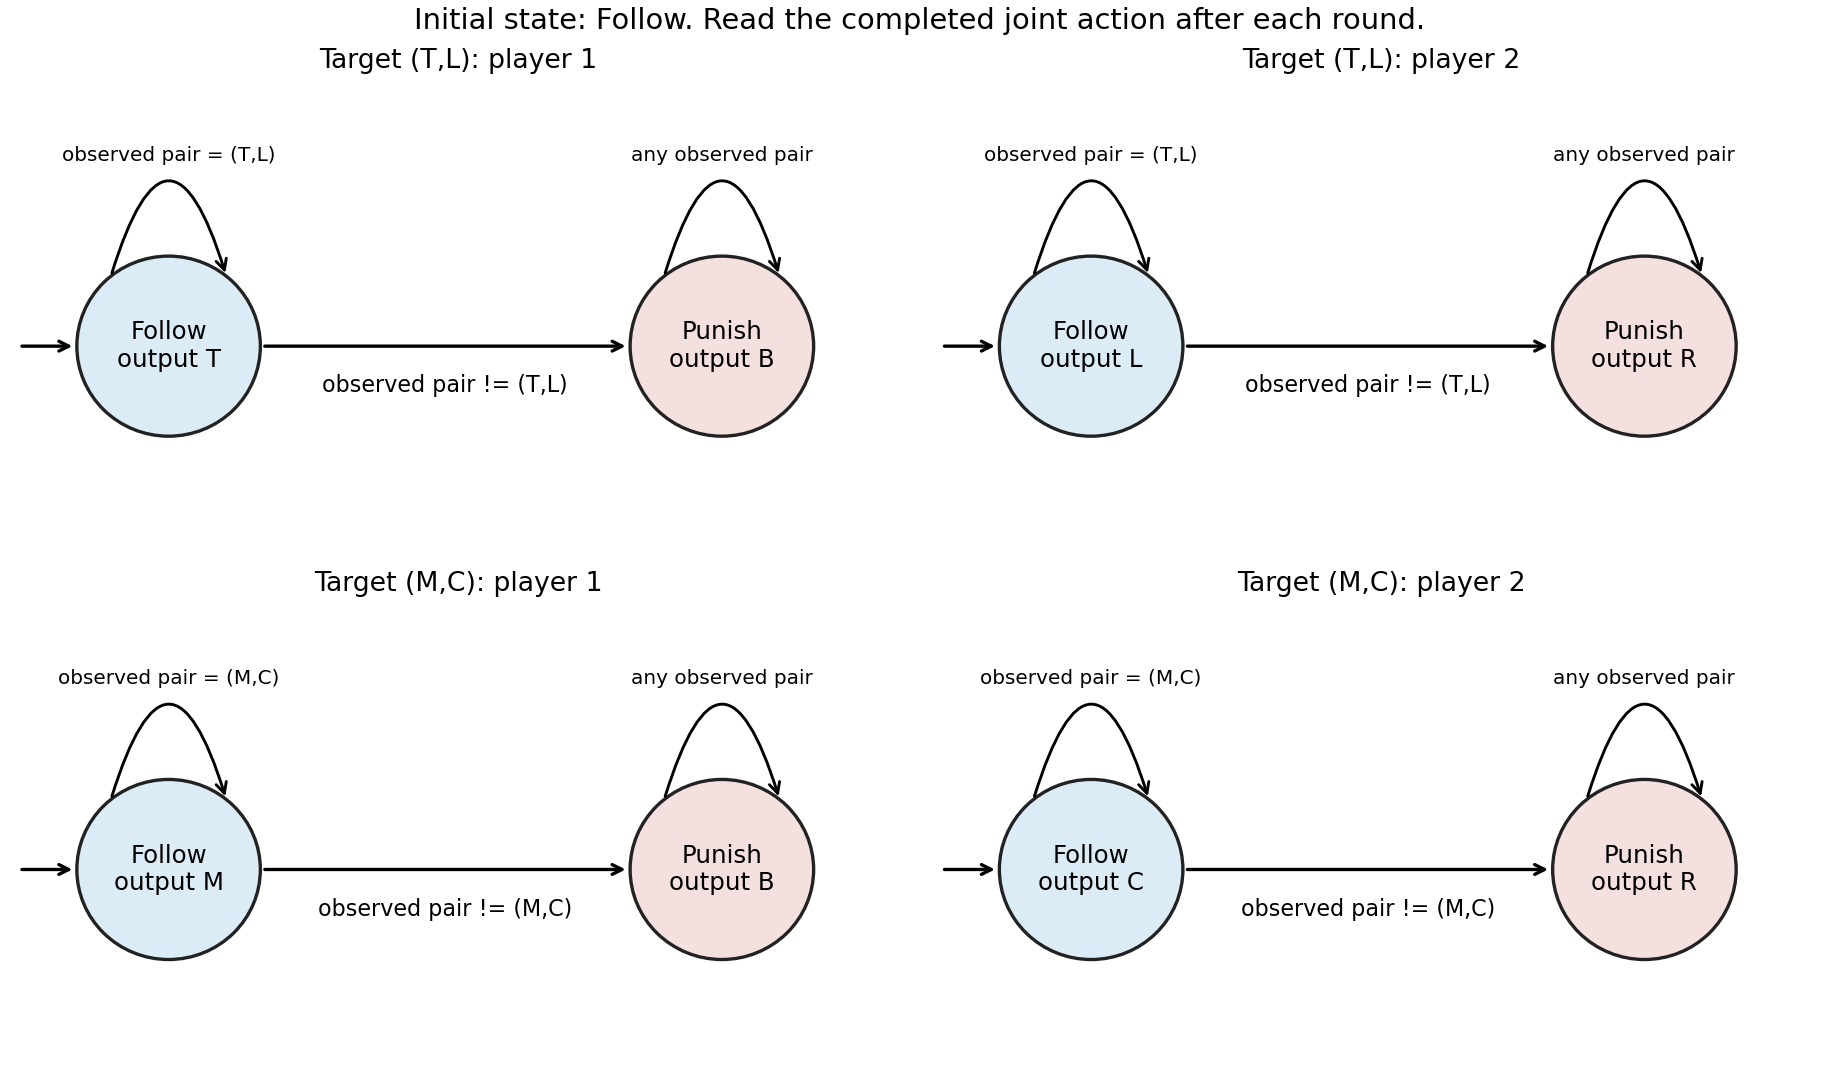

If neither player deviates, the target is repeated forever. If a player first deviates at a finite round , the opponent enters for all later rounds. Against column action , every row action earns at most zero; against row action , every column action earns at most zero. All payoffs are bounded, so the total reward before and at , divided by the horizon, tends to zero. The deviator's upper limiting average is therefore at most , below either target payoff or . This proof tests arbitrary future deviations, not merely a single changed action. It also rules out improvement by deviations whose averages fail to converge, if the criterion is extended by an upper or lower limit.
For target , one-state machines outputting and forever suffice: each is a best response to the other in every round. Their long-run average payoffs are zero and no unilateral deviation can improve them. In fact, the punishment is credible because is a stage Nash equilibrium, so the two positive-target constructions are also subgame perfect equilibria under the stated monitoring assumption. The general punishment mechanism is described in [ref]
Lecture 15: Repeated Games by Asu Ozdaglar. slides 12–15; those slides use discounting, while the finite-prefix argument here uses long-run averages
.“Outcomes of the stage game” here means a fixed action pair repeated forever. Allowing time sharing also sustains some average payoff vectors that are not stage cells: for example, a deterministic alternating cycle gives , with a two-phase finite-state strategy and the same permanent punishment. An off-diagonal cell may occur in a sustainable cycle; the impossibility above concerns its constant repetition, not every appearance on an equilibrium path. With finite-state pure strategies, an undisturbed path is eventually periodic, so its limiting cell frequencies are rational numbers.
Use the standard repeated game convention that the first round's joint action is observed before round two. The following original game tree represents simultaneous moves by making row move first in each round while hiding that current move from column. Terminal labels are total payoffs over both rounds, ordered row then column.
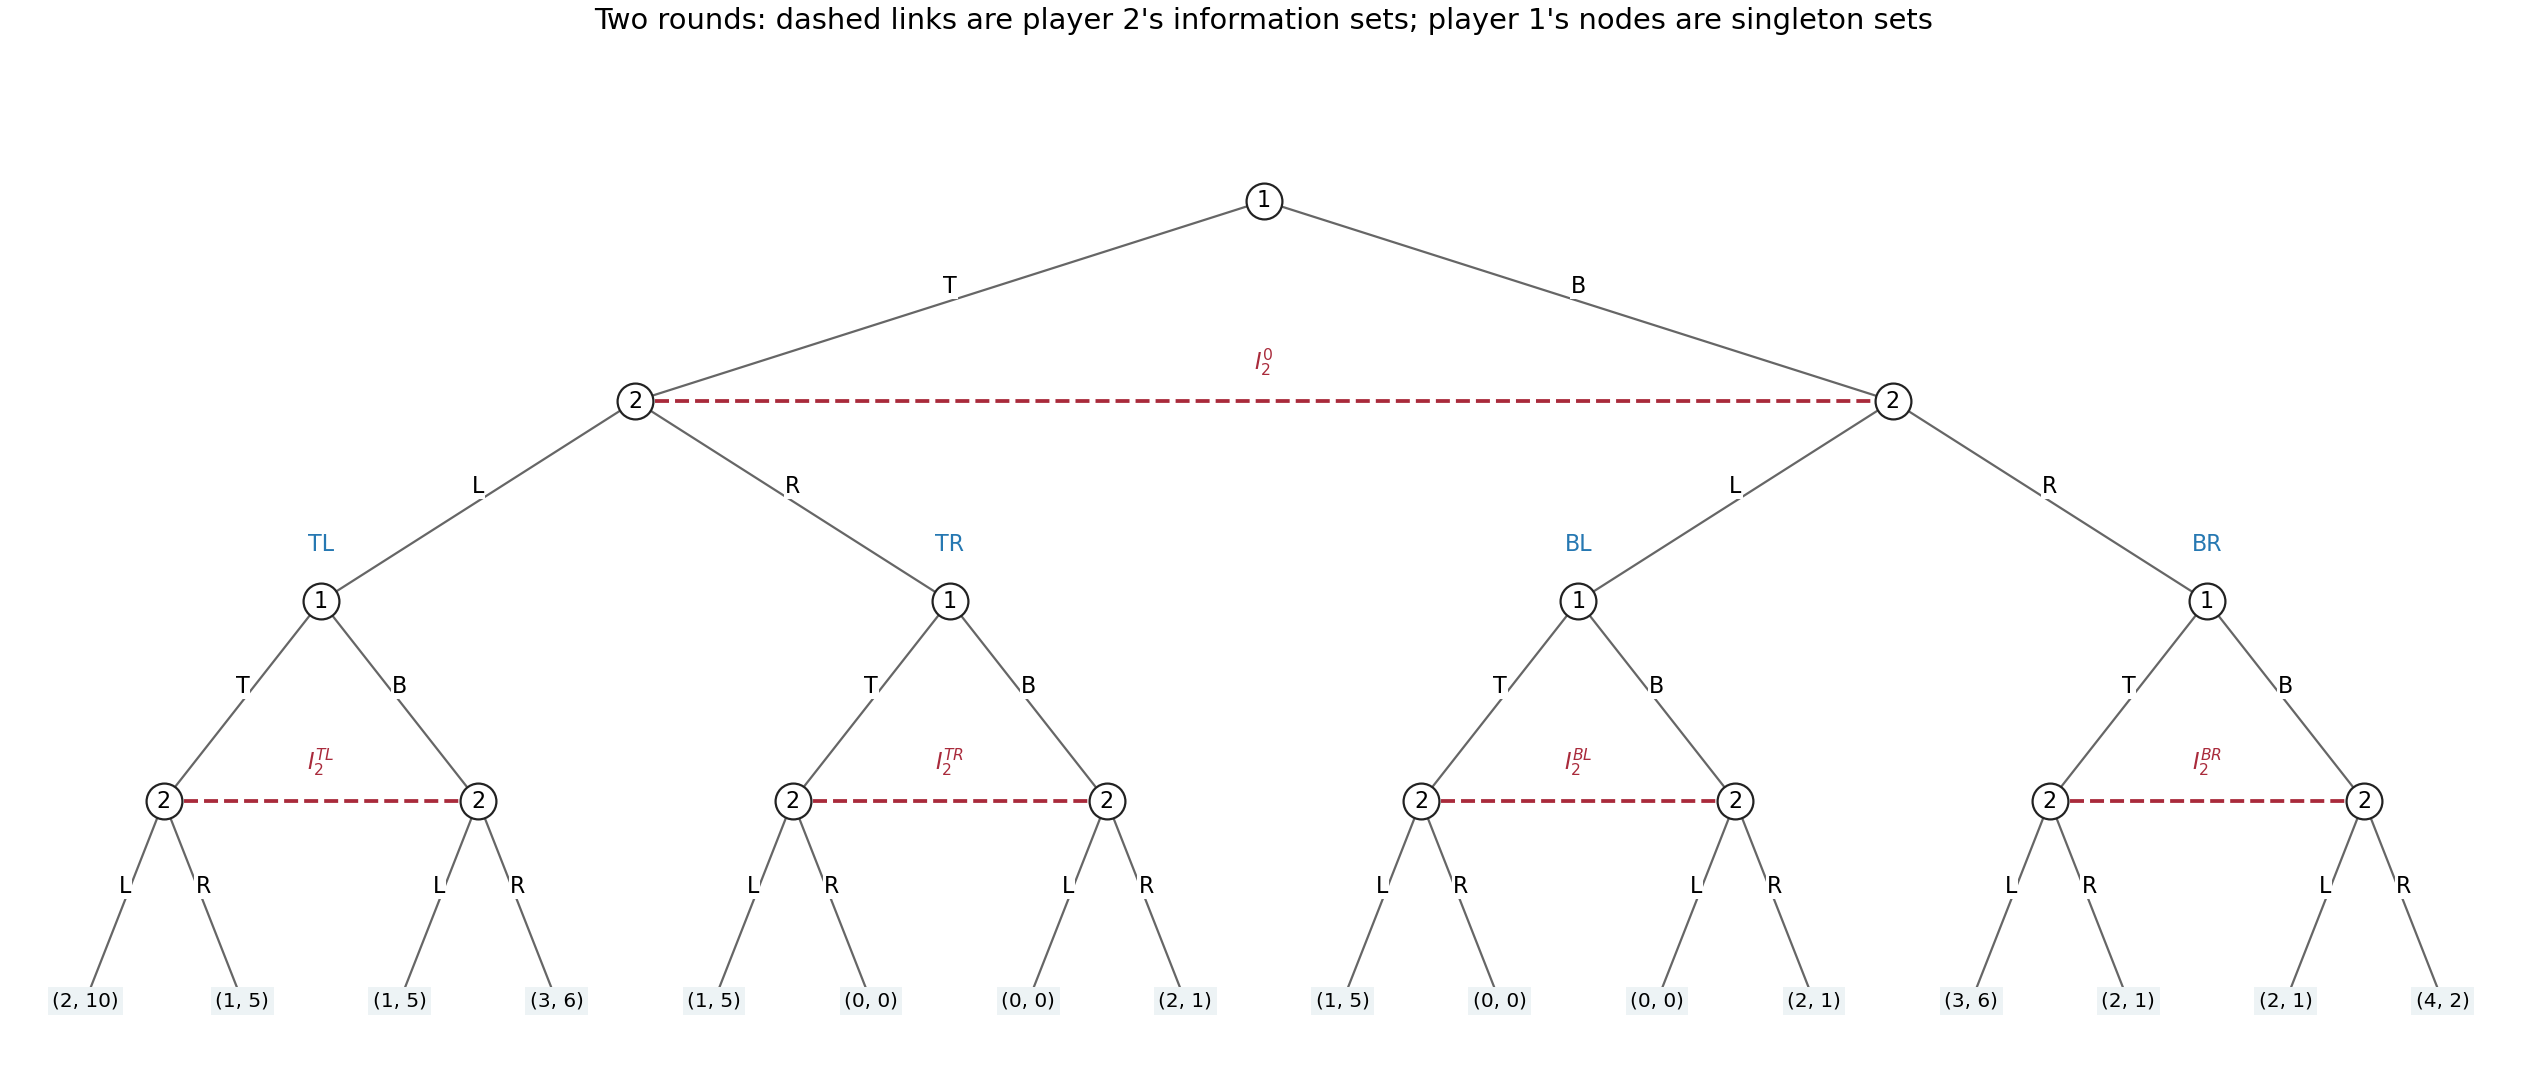
The full two-round extensive-form game, with all sixteen terminal payoff pairs and five column information sets
. Details. 
Formally, round one starts at a row decision with actions . The two ensuing column nodes form one information set , with available actions ; column cannot tell which current row action occurred. The four completed first-round histories are . At each , round two begins at a separate row node. Its two successors, after row's current or , form a column information set . Distinct have distinct information sets: both players know the whole first-round outcome. There are sixteen terminal histories , whose total payoff is , as displayed in the tree.
The row player's five information sets are the initial singleton and the four singleton round-two nodes, one per . The column player's five information sets are and the four two-node sets . Thus each player must specify one binary choice at each of five information sets, including histories that its own first choice might prevent:Counting only the four possible two-round action sequences would miss the distinct contingent responses to the opponent's first action.
For a concrete pair of complete pure strategies, order the second-round histories as and useThe first entry is the initial action, and the four remaining entries prescribe the action after each first-round history. This induces the unique path in round one followed by in round two. Hence the total payoff isThe off-path entries are part of each pure strategy, even though this pair does not reach them.
For randomization, a mixed strategy is a probability distribution over the complete plans, with free probabilities in a general distribution. A behavioural strategy instead gives one binary-action probability at each of five information sets, requiring five parameters. This game has perfect recall: a player never forgets a previous own action or a first-round observation, and the only concealed action is the opponent's current simultaneous choice. Consequently neither kind of randomization has a greater attainable-payoff advantage: Kuhn's theorem gives realization-equivalent strategies against every fixed opposing strategy.[ref]
Extensive games and the problem of information by Harold W. Kuhn. original article, pp. 193–216, equivalence under perfect recall
The equivalence can be verified directly here. Given a behavioural strategy, sample all five contingent actions independently before play; the resulting product probability distribution over complete plans is an equivalent mixed strategy. Conversely, let be a mixed strategy for player . Use its marginal probability for the initial action. At history containing own first action , choose second action with conditional probabilitywhenever the denominator is positive; if it is zero, choose arbitrarily at that unreachable history. The opponent's first-round action is simultaneous and cannot depend on the sampled hidden plan beyond the chosen first action. Thus conditioning on preserves exactly these conditional probabilities of actions, and multiplying the first- and second-round factors reproduces each terminal probability. Correlations between prescriptions at mutually exclusive second-round histories have no further observable effect. Behavioural strategies offer the more compact representation, while mixed strategies describe a single random choice of a full plan. Imperfect information here does not mean imperfect recall.
Articles by others on the same topic
There are currently no matching articles.