For events with , conditional probability isRestrict attention to the outcomes in , then renormalize their probability measure so its total mass becomes one. The resulting rule is itself a probability measure. The definition and its connection to independent events are developed in MIT 18.05, Reading 3: Conditional Probability, Independence and Bayes' Theorem.
For the two-dice model, let mean the sum is at least nine and mean the first result is six. Of the six outcomes in , four belong to : the second die can be 3, 4, 5, or 6. Thus . Reversing the information gives a different answer: four of the ten outcomes in have first result six, so . Both ratios use the same overlap; their denominators describe different information.
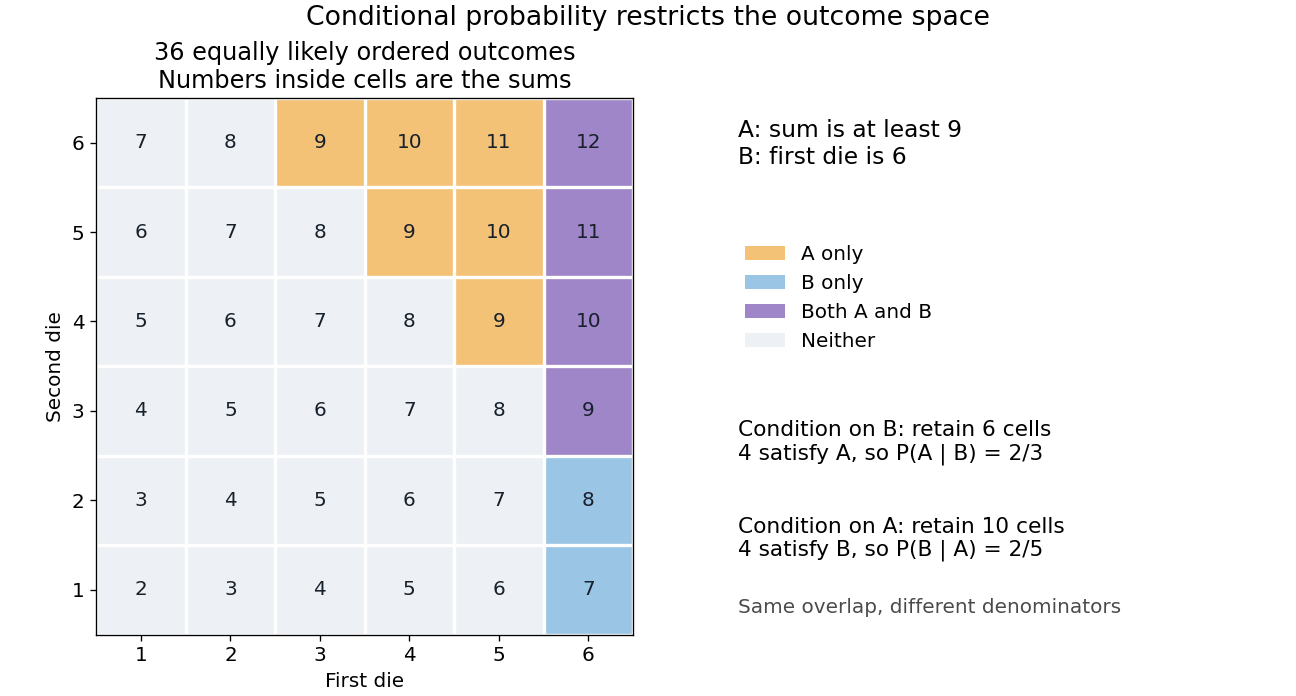
The definition requires positive conditioning mass. For a continuously distributed random variable , it cannot directly define when . A regular conditional distribution or conditional density supplies the appropriate extension, with the usual almost everywhere qualification. Nor does conditioning by itself justify causal inference: changing which outcomes are considered is different from physically changing how the experiment is generated.
A box contains one certainly red ball and independently coloured extra balls, each red with probability . Conditional on the first draw being red, a second draw without replacement is red with probability . To see the effect of using a conditional probability, let , where has a binomial distribution with parameters . The conditional probability is : histories with more red balls are more likely to produce the first red draw and therefore receive greater weight.
A messenger names an excluded candidate while concealing the uniquely selected one. The conditional probability depends on the naming rule. With three equally likely selected candidates and a messenger forbidden to name the observing candidate A, let be the probability of naming B when A is selected. When C is selected the messenger must name B, and when B is selected cannot name B. Thus the probability that A is not selected, conditional on B being named, is . Unbiased naming has and leaves this probability ; bias toward B gives , and bias toward C gives one. Conditioning on the name is different from conditioning only on B's exclusion.
When all conditioning events have positive probability, repeatedly apply the definition of conditional probability to factor a joint event into successive conditional factors. For a sequence of discrete responses, this yields the product of conditional masses along the actual outcome path. It requires no unconditional independence assumption.
For a probability measure on a standard Borel space and a measurable map to another standard Borel space, there is an almost-everywhere unique measurable probability kernel supported on . It integrates to , and realizes conditional expectation given . These measures are the conditional measures of a factor.
The fiber-supported measurable probability kernel supplied by the disintegration theorem for a probability measure for a factor map. For integrable , almost everywhere. The same construction applies to general measurable maps and countably generated sub-sigma-algebras modulo null sets.
A family of probability measures on a measurable space for which is measurable for every measurable set . This combines measurable dependence on a parameter with a probability measure at each parameter. The conditional measures of a factor form such a kernel, with the additional fiber-support property from disintegration.
For nontrivial events, strict attraction under conditional probability is equivalent to a positive covariance of their indicator variables. This condition is symmetric in the two events. Complementing exactly one of the events reverses the strict inequality. This two-event condition should be distinguished from association of an entire family of random variables.
For a finite measurable partition with positive probabilities, and an event of positive probability,Its beauty is that a model predicting observations from a hidden state can also describe uncertainty about the state after an observation. Each numerator is a joint probability; the denominator, supplied by the law of total probability, makes the answers sum to one. This is a direct consequence of conditional probability, rather than an extra axiom.
Select the coin from law of total probability once, then toss that same coin repeatedly, with conditionally independent tosses given its identity. Let denote the -head coin, initially of prior probability . After one head , its posterior probability isThe likelihood of a head is larger under , but remains less likely than the other coin because its prior probability was smaller. A large likelihood for an observation does not itself imply a large posterior probability for the hypothesis.
After an ordered sequence containing heads and tails, its likelihood ratio between the two coins is . Bayes' theorem therefore gives posterior oddsEach head multiplies the odds by and each tail by . Three heads give posterior probability , still below one half; four give , above one half. The finite-model update and the distinction between prior probability, likelihood and posterior probability are set out in MIT 18.05, Reading 11: Bayesian Updating with Discrete Priors.
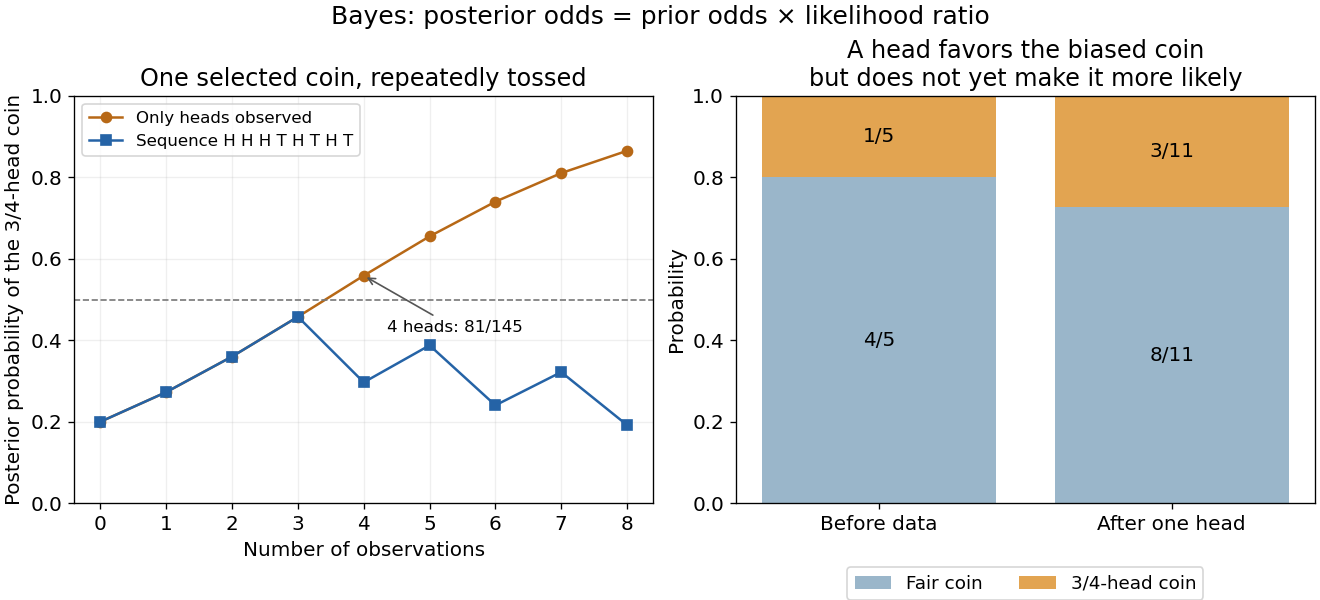
Updating uncertainty about one selected coin after repeated observations
. Details. The hidden selection also creates dependence. Each toss has marginal head probability , but two heads have joint probability , greater than . Their indicator covariance is . Seeing a head makes the head-favoring coin more likely, so it also raises the chance of a future head. This is covariance induced by a shared latent variable, despite conditional independence of the tosses given the coin.
Historically, Thomas Bayes's essay on an unknown success probability appeared in 1763 after his death, communicated by Richard Price. Its opening problem asks how observed successes and failures constrain that unknown probability; Price's introductory letter explains the connection to reasoning from experience. That is a more substantial inference problem than simply rearranging today's elementary identity. [ref]
https://www.gtfp.cs.rhul.ac.uk/pulskamp/Bayes/bayesessay-rjp.pdf. Bayes, An Essay towards solving a Problem in the Doctrine of Chances, 1763; original text transcribed, introductory letter and statement of the problem
Suppose exactly one of equally likely candidates is the source of an observation. A test is always positive for that source and is positive with probability for any nonsource candidate. For one randomly selected candidate, Bayes' theorem gives , proving the displayed result. Even a small false positive rate can leave a substantial chance of a different source when there are many alternatives. The model concerns one selected candidate with the stated prior; searching many candidates and selecting a match requires accounting for that selection procedure.
An urn has balls, including of one colour and of the other, with . After a uniform first draw, an independent decision returns that ball with probability ; the second draw is uniform from the remaining contents. Let mean the th draw has the first colour and mean replacement. The two relevant joint probabilities areApplying Bayes' theorem and cancelling the common factors gives the displayed conditional probability. It is independent of and satisfiesTwo different observed colours therefore decrease the posterior probability of replacement: removing the first colour makes the second more likely. The replacement decision must be independent of the first draw for this formula; its marginal probability alone does not specify the model.
Let have the positive-integer geometric distribution with success parameter , and conditionally toss independent coins with head probability . Exactly one head has conditional probability . Combining this with the prior by Bayes' theorem gives the displayed posterior with ; its normalization uses . For , the posterior is . It is also a shifted negative binomial distribution, with equal in law to the number of failures before two successes of probability .
If every model's likelihood is multiplied by the same positive factor independent of its parameter or model index, Bayes' theorem cancels that factor from the normalized posterior. Fixed-count Bernoulli sampling and sampling stopped at a specified positive head count give such proportional likelihoods for the same total heads and tails. This conclusion uses their actual sampling likelihoods; it is not a claim that every selection or stopping rule can be ignored.
If a hidden coin is selected once with prior probability of coin , repeated tosses are independent conditional on that coin. Bayes' theorem weights the prior by each all-heads likelihood. They need not be independent without conditioning on the chosen coin.
A conditional distribution is the probability law of one random quantity given information about another.
The probability mass function of a discrete conditional distribution. The elementary ratio requires ; a value of zero gives no event-conditioning definition through this ratio.
A regular conditional distribution of a random variable given is a Markov kernel such that, for all measurable sets ,For each , is a probability measure; for each , is measurable. Thus it assigns an actual probability distribution to a specified observation even when . Such kernels exist for standard Borel state spaces, including real-valued variables, and their uniqueness is only up to -null sets. With a joint density and positive marginal density, the ratio of the two densities defines the usual conditional density kernel. Values outside the marginal support or on a null set are not uniquely determined by the joint law.
Where the marginal density is positive, a joint probability density determines the conditional densityIt integrates to one in , and supplies conditional expectations by integrating against it. Its values on a probability-zero set of conditioning points are not fixed by the joint probability distribution.
A full conditional distribution is the conditional law of one component of a joint model given all the other components and the observed data. A Gibbs sampler updates components by drawing from these laws.
Articles by others on the same topic



Conditional probability is a measure of the likelihood of an event occurring given that another event has already occurred. It is denoted as \( P(A | B) \), which reads "the probability of event A given event B." Mathematically, conditional probability can be defined using the formula: \[ P(A | B) = \frac{P(A \cap B)}{P(B)} \] provided that \( P(B) > 0 \).