Solutions to the single paper shared by the two printed routes, dated 8 June 2021. Oxford examination source release. The probabilistic programming calculations below use only information supplied in the paper. Question 2 contains two notation or naming issues, identified at the affected parts; Question 3 requires an explicit choice of prior distribution.
Assume , and work on the support . In rejection sampling, choose a normalized proposal probability mass function and a known finite constant satisfying everywhere. Draw independent random variables and , accepting when . The joint probability of proposing and accepting is , so the overall acceptance probability is and the accepted value has probability mass function . Fresh trials therefore produce independent and identically distributed random variables with the desired probability distribution. For a fixed positive number of accepted values, the sample average is an unbiased estimator of the expectation when that expectation is finite. Its variance is if the second moment is finite. Finding a valid envelope can be difficult, and a small acceptance probability makes the method expensive.
For the Metropolis–Hastings algorithm, choose a proposal transition matrix and, at the current state , propose . Accept with the Metropolis–Hastings acceptance probabilityA proposal outside is rejected; an impossible proposal need not be assigned a ratio. Otherwise remain at . This constructs a Markov chain satisfying detailed balance with , without computing or a global envelope. Estimate the expectation by averaging over iterations, including repeated states after rejections. Keeping only accepted jumps generally changes the stationary distribution of the recorded process.
The Metropolis–Hastings algorithm produces dependent samples, so the variance of its average includes autocovariances; starting outside stationarity can also cause finite-run bias. With Markov chain irreducibility, suitable recurrence and an integrable , the countable-state Markov chain ergodic theorem gives consistency. Aperiodicity is additionally needed for the usual convergence of one-time probability distributions. In contrast, accepted rejection sampling values need no initial transient. Neither method is universally faster: envelope rejection competes with the proposal quality and mixing time of the Markov chain. Nonnegativity of alone does not guarantee a finite expectation or variance.
Here , with fresh proposal randomness independent of the past. For , the Metropolis–Hastings acceptance probability isThus is independent of , and are independent and identically distributed random variables with probability distribution , even if was chosen arbitrarily in . The method becomes ordinary Monte Carlo method sampling from . The average of is an unbiased estimator, with the variance stated in part (a). Including an arbitrary initial state would spoil this finite-sample property. This is the independent stationary proposal lemma.
Neither Markov chain irreducibility nor fast convergence follows from detailed balance. On two states, the identity transition matrix satisfies detailed balance for the uniform probability distribution, but neither state can reach the other.
Even after imposing Markov chain irreducibility and aperiodicity, considerIt satisfies detailed balance for . Its nontrivial eigenvalue is , and, from state zero, its total variation distance from after steps is . This approaches zero arbitrarily slowly as decreases. Detailed balance without rapid convergence separates correctness of a stationary distribution from reachability and speed.
Put and . For , the off-diagonal probability flux of the proposed rule isIf , define both acceptance probabilities to be zero; both fluxes are zero. The diagonal detailed balance equations hold automatically, including the probability of rejected proposals. Summing the detailed balance equations over gives stationarity:The alternative rule therefore preserves . The unknown normalizing constant cancels after replacing by . This Barker acceptance probability is no larger than the Metropolis–Hastings acceptance probability for the same proposed move: if , then . Preservation of still requires separate Markov chain irreducibility and convergence checks before it guarantees useful sampling.
Use the Poisson distribution with probability mass function on . A symmetric nearest-neighbour proposal with a reflecting boundary isAll other entries vanish. In particular, the boundary proposal does not force a move to one: retaining the probability makes .
The adjacent ratios of the Poisson distribution are and . The Metropolis–Hastings acceptance probability consequently giveswhere the symbol denotes the upward transition probability. Thus the complete transition matrix iswith no downward entry at zero and all other entries zero. In matrix form,Every row is nonnegative and sums to one. An executable Python step of this Poisson Metropolis chain is:
def poisson_step(n, lam, rng):
    if lam <= 0 or n < 0 or int(n) != n:
        raise ValueError("require lam > 0 and an integer n >= 0")
    y = n + 1 if rng.random() < 0.5 else max(0, n - 1)
    ratio = lam / (n + 1) if y > n else n / lam if y < n else 1.0
    return y if rng.random() < min(1.0, ratio) else n
Supply a pseudorandom number generator such as
random.Random(2021) and retain each returned state, including repeats. No normalizing constant or evaluation of a factorial is needed by the algorithm.For each adjacent pair, the detailed balance equations follows directly:For nonadjacent distinct states both fluxes vanish, and diagonal fluxes agree trivially. Since , this is a genuine stationary distribution, rather than merely an invariant measure of infinite mass.
Every upward and downward transition probability between neighbouring states is positive for . Any two states can therefore be joined by a finite path of positive probability: the Markov chain is irreducible. Moreover,State zero has period one; Markov chain irreducibility makes every state aperiodic. Finally, the standard countable-state recurrence theorem states that an irreducible Markov chain admitting a stationary distribution of total mass one is positive recurrent, with that stationary distribution unique. The countable-state Markov chain convergence theorem then states that Markov chain irreducibility, positive recurrence and aperiodicity imply for all states . The hypotheses just verified hold on the infinite state space , not merely on a numerical truncation.[ref]
Markov Chains by James R. Norris. Sections 1.7–1.8, invariant distributions and convergence to equilibrium
Consequently, the unique stationary distribution and the limiting distribution are both , from every initial state. The countable-state Markov chain ergodic theorem also gives almost surely whenever .[ref]
Variational inference replaces exact Bayesian inference by an optimization problem over a tractable family . A guide program samples from this approximating family. Optimizing an evidence lower bound is equivalent to minimizing . Its appeal is that a fitted approximation can be cheap to sample and may scale well when an exact posterior distribution is inaccessible. A restricted family, such as mean-field variational inference, can miss dependence or entire modes; a local optimum can add further error. More optimization cannot remove approximation error caused by an inadequate family.
Monte Carlo method inference instead estimates posterior expectations using simulated values or weighted values. Examples include rejection sampling, importance sampling and Markov chain Monte Carlo. Under their respective support and convergence assumptions, increasing computation can yield consistent estimates without choosing a finite-dimensional posterior family. Their uncertainty includes simulation error; an inefficient proposal or slow mixing time can make that error large. Markov chain Monte Carlo additionally requires convergence and dependence diagnostics.
The central trade-off is optimization within an approximate family versus simulation under a target probability distribution. It is not an absolute distinction between deterministic and random computation: variational inference often uses Monte Carlo method estimates of its gradient, while Monte Carlo method inference may use fitted proposals. Neither method automatically guarantees accurate uncertainty estimates or superiority at a fixed computational budget.
Let , take supported where , and assume the following expectations exist. By the definition of Kullback-Leibler divergence and Bayes' theorem,Therefore the evidence lower bound isNonnegativity of Kullback-Leibler divergence proves . The marginal likelihood is constant with respect to the variational parameter , so maximizing minimizes the stated Kullback-Leibler divergence.
The practical advantage is that evaluating logarithms of joint probabilities and requires no evaluation of the usually intractable marginal likelihood. One can estimate and its gradient with Monte Carlo method. Equality with the log marginal likelihood occurs only when almost everywhere. Merely maximizing the evidence lower bound over a restricted family neither computes the exact posterior distribution nor proves that the maximum attains this equality.
The discrete base factors in the displayed construction inherit their variational parameters. Accordingly write , not a parameter-independent , for the joint base probability mass function or probability density function. The continuous noise factors can be parameter independent while the discrete factors are dependent. Calling the entire base law parameterless while retaining its nonzero score function would be inconsistent.
Let push the base law forward to , and defineUse a fixed base measure , with counting measure for discrete coordinates and Lebesgue measure for continuous coordinates. Assume locally parameter-independent support, differentiability and an integrable domination permitting differentiation under the integral sign. A valid reparameterization gradient givesApply the product rule before simplifying:This is the required combined score and pathwise gradient estimator. A sample from and the integrand on the last line give an unbiased stochastic gradient under the stated regularity conditions. Its first term is a score-function gradient estimator contribution; the remaining terms differentiate the sampled objective along the continuous transformation. The same separation appears in the general stochastic computation graph construction.[ref]
All derivatives inside the expectation hold fixed. They still include both explicit parameter dependence and dependence through . For a continuous coordinate ,The model joint density is fixed as changes, but its composition with need not be constant. Discrete coordinates are not differentiated as real-valued paths; their changing probabilities enter through the score function. Moving supports or parameter-dependent branch boundaries require additional care and are not justified merely by formally interchanging a derivative and an integral.
The two limiting-case names in the printed bullets are reversed. Fully reparameterized continuous choices give a reparameterization gradient; non-reparameterized discrete choices give a score-function gradient estimator. Here are both reductions, including the extra term that vanishes only after taking an expectation.
When all choices are reparameterized with parameter-independent base noise, and . The expression in part (c) becomesDifferentiating along the sampled transformation is precisely the pathwise gradient, also called the reparameterization gradient. There is no score function of the parameter-independent base law.
When all choices are discrete and left untransformed, and . Set and . Since has no variational parameter, the integrand in part (c) isNormalization gives the zero-mean score function identityThusThe first expression is the usual score-function gradient estimator; the second has a constant score baseline of one. The two random integrands are generally different even though their expectations agree. A suitable constant score baseline can reduce variance, but one is not universally the optimal baseline.[ref]
Gradient Estimation Using Stochastic Computation Graphs by John Schulman and others. Section 4, Theorem 2 and footnote 3
For a concrete check, take with and , and a fixed target . Direct integration givesUsing , , the combined integrand has components , and . Their expectations are respectively , and , matching direct differentiation. Dropping the discrete score function term would incorrectly give zero for the first component. This calculation checks the combination without accepting the printed reversal.
Treat each observed arrival label as a constraint on an unobserved walking duration. Departures are treated as fixed design information. Writing for the minutes available until work starts, the derived late-label thresholds have frequencies ; the early-label thresholds have frequencies . These are censoring thresholds, not measured journey times. A late label means , and an early label means ; equality has probability zero under the continuous model.
The paper specifies no prior distribution. One explicit proper model iswith independent priors; all times are in minutes. These ranges are a transparent modelling choice, not information deduced from the observations. In particular, this is a prior on the standard deviation , not a uniform prior on the variance . The normal distribution permits negative durations; it is the mathematical approximation requested here, rather than a claim that such durations are physically possible. A truncated model would be a different model.
The following Python implements hard conditioning by rejection sampling.
None marks a rejected trace; an accepted Boolean answers whether all five future arrivals are late. The same parameters are shared across past and future days.import math
import random
LATE = {20: 1, 21: 3, 25: 3, 27: 1, 32: 2}
EARLY = {29: 1, 34: 1, 36: 3, 37: 1, 38: 1, 39: 1, 43: 1, 44: 1}
RECORDS = [(c, True) for c, n in LATE.items() for _ in range(n)]
RECORDS += [(c, False) for c, n in EARLY.items() for _ in range(n)]
def journey_trace(rng):
mu = rng.uniform(0.0, 60.0)
sigma = rng.uniform(1.0, 20.0)
# Twenty latent past durations and five future durations.
past = [rng.gauss(mu, sigma) for _ in RECORDS]
future = [rng.gauss(mu, sigma) for _ in range(5)]
if not all(t > c if late else t < c
for t, (c, late) in zip(past, RECORDS)):
return None
return all(t > 30.0 for t in future)
def accepted_average(trace, n, rng):
if n <= 0:
raise ValueError("n must be positive")
successes = accepted = 0
while accepted < n:
result = trace(rng)
if result is not None:
accepted += 1
successes += int(result)
return successes / nFor example,
accepted_average(journey_trace, n, random.Random(2021)) estimates the desired conditional probability from accepted traces. Accepting False is essential: treating a false answer as a rejected trace would condition on the desired conclusion. The model deliberately emphasizes clear semantics; rejection can be inefficient because all twenty past-label constraints must hold together.An idealized underlying probability space iswith the product Borel sigma-algebra. Its 27 independent random coordinates are , , twenty past standard-normal noises, and five future standard-normal noises. Define . Sampling an unknown variance does not mean drawing a new variance on each day; a single draw of applies to all durations in a trace.
Let be the event that the first twenty durations satisfy their corresponding observed inequalities. The observations are the twenty late/early labels, conditional on the fixed departure thresholds. They are not exact values of the latent . The posterior probability measure on traces isHere : at every interior parameter pair each strict normal-tail probability lies in , so their finite product has positive prior integral.
The returned outcome isThus the underlying sample space has dimension 27, the successful output space is , and the observations define the conditioning event . The desired output probability distribution is the pushforward measure of under . Rejection is an implementation device, not a third scientific answer:
None is discarded before forming the conditional output law.Write for the standard normal distribution function. Integrating out the twenty independent past durations gives the threshold-censored normal likelihoodThe frequencies are those in part (a). For a future day, the conditional late-arrival probability is . Conditional independence of the five future durations gives .
Exactly three primitive random coordinates suffice. Draw from the same priors and one independent . Reject if ; otherwise return whether . Conditional on acceptance and the parameters, is uniform on an interval of length ; the true-answer subinterval has length . Reusing this same uniform value is therefore intentional, not an independence mistake.
Indeed the two output contributions at each parameter value areThese are exactly the contributions obtained by integrating the original twenty-five duration noises. Multiplication by the common prior density and normalization therefore give the same joint posterior distribution of . The revised program preserves the query and parameter posterior, but does not retain individual latent durations. This is uniform-interval encoding of conditioning and a binary query.
Here is an executable version, reusing the definitions from part (a). Logarithms avoid multiplying many small probabilities.
def normal_logcdf(z):
    value = 0.5 * math.erfc(-z / math.sqrt(2.0))
    return math.log(value) if value > 0.0 else -math.inf

def journey_loglik(mu, sigma):
    return (sum(n * normal_logcdf((mu - c) / sigma)
                for c, n in LATE.items())
            + sum(n * normal_logcdf((c - mu) / sigma)
                  for c, n in EARLY.items()))

def collapsed_trace(rng):
    mu = rng.uniform(0.0, 60.0)
    sigma = rng.uniform(1.0, 20.0)
    log_likelihood = journey_loglik(mu, sigma)
    # This uniform lies in (0, 1], avoiding log(0).
    log_u = math.log(1.0 - rng.random())
    if log_u >= log_likelihood:
        return None
    log_h = 5.0 * normal_logcdf((mu - 30.0) / sigma)
    return log_u < log_likelihood + log_h
accepted_average(collapsed_trace, n, rng) consequently has the same target as the original program. The ideal three-dimensional sample space is with product uniform probability measure, conditioned on the displayed acceptance event. Finite-precision normal tails can underflow to zero in this simple implementation; the mathematical equivalence concerns exact probabilities, and the numerical check in part (d) independently integrates the likelihood in the region carrying appreciable posterior mass.For any chosen proper prior density on with positive evidence, Bayes' theorem givesThe prior density comes from the first two random draws. The likelihood is the probability of satisfying all observed-label constraints after integrating the past duration noises. The factor is the probability of the five-day outcome conditional on the shared parameters. The denominator is the probability of acceptance, which converts the numerator's joint probability into the required conditional probability.
For the independent uniform priors in part (a), the constant cancels and both integrals reduce to , . A prior on the variance would require transforming the density: this chosen prior has density for conditional on . One must not silently replace it by a uniform prior on .
There is no unique numerical probability until the prior distribution is chosen. As a check for the stated uniform priors, independent Gaussian quadrature calculations with 256 and 512 nodes per coordinate agree at the shown precision:The prior-predictive probability of all observed labels is approximately , explaining the rejection cost. These numbers are illustrations of the explicit model, not additional observed data.
A subtle point is that the five future days are independent only conditional on . Integrating shared parameter uncertainty gives , not . The latter is about for these priors and understates the five-day probability. Jensen's inequality gives , while gives . For two future late-arrival indicator functions, their posterior covariance is . This is the posterior predictive repeated-success identity.
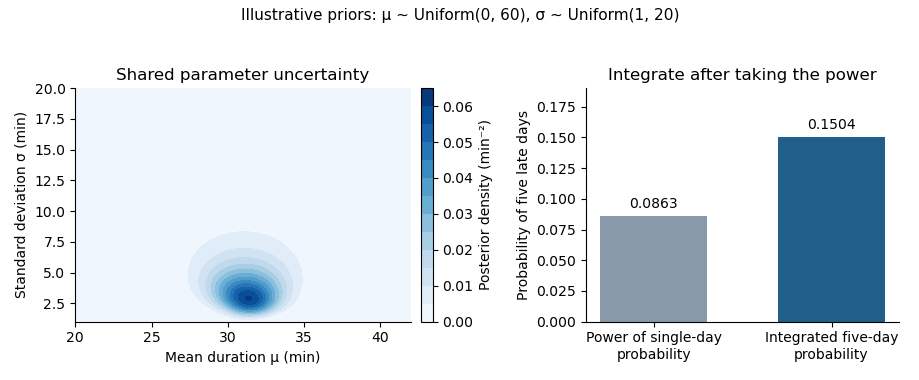
Posterior uncertainty and the five-day predictive probability for the explicitly chosen uniform priors. The contour is cropped to the parameter region carrying the visible mass; integration uses the full prior rectangle.
Details. I would first collapse the duration noises as in part (c), then use self-normalized importance sampling on the two shared parameters. Draw independent , give each the importance weight , and returnThis is likelihood weighting: the observations affect the weights rather than forcing repeated simulation of twenty latent inequalities. Integrating out both the constraints' auxiliary randomness and the future Boolean query is Rao-Blackwellization; at fixed parameters it removes randomness without changing the relevant conditional expectations.
The weights and weighted queries lie in , and the evidence is positive. The strong law of large numbers therefore makes the numerator and denominator averages converge to their corresponding integrals, proving almost sure convergence of their ratio to part (d). The finite- ratio is generally biased; the assertion concerns consistency rather than a finite-sample unbiased estimator. Use logarithms of importance weights to avoid numerical underflow:
def weighted_answer(n, rng):
    if n <= 0:
        raise ValueError("n must be positive")
    samples = []
    for _ in range(n):
        mu = rng.uniform(0.0, 60.0)
        sigma = rng.uniform(1.0, 20.0)
        samples.append((journey_loglik(mu, sigma),
                        math.exp(5.0 * normal_logcdf((mu - 30.0) / sigma))))
    offset = max(logw for logw, h in samples)
    if not math.isfinite(offset):
        raise ArithmeticError("all weights underflowed")
    scaled = [(math.exp(logw - offset), h) for logw, h in samples]
    den = math.fsum(w for w, h in scaled)
    answer = math.fsum(w * h for w, h in scaled) / den
    ess = den * den / math.fsum(w * w for w, h in scaled)
    return answer, ess
The returned effective sample size of importance sampling is a concentration diagnostic, not a proof of accuracy. Repeat runs and inspect the weights. If the prior is much broader than the posterior, improve the proposal with the corresponding importance sampling density correction, or use the Metropolis–Hastings algorithm targeting . Because this particular collapsed problem is only two-dimensional, deterministic numerical integration is also an excellent independent accuracy check; it was used for the figure and numerical illustration. Straight rejection of the original traces is correct but wastes most proposals here.
Source paper: released examination archive.
By the Von Neumann-Morgenstern utility theorem, use a representing utility function and apply a positive affine function to set and . This is possible because the given strict preference implies . The two specified indifference relations then giveTaking the expected utility of each lottery yieldsTheir difference is , establishing the stated strict preference. These numbers measure utility, not monetary reward or an assumed ordering of the subscripts.
Here is the underlying argument directly in terms of the axioms. The independence axiom for lottery preferences permits substitution of indifferent lotteries inside a common mixture. Replacing by its given mixture of , and then replacing , followed by reduction of compound lotteries, givesand consequentlyThe transitive relation axiom combines the successive substitutions. Finally, mixture monotonicity says that among mixtures of a strictly better and a strictly worse outcome, the greater probability of the better outcome is strictly preferred; this follows from the independence axiom for lottery preferences and transitivity. Since and , the comparison follows. Complete lottery preferences and continuity of lottery preferences are part of the representation theorem's hypotheses; the direct substitution calculation uses the already supplied indifferences and does not need to invoke continuity of lottery preferences again.[ref]
Expected utility theory by EconPort. “The Expected Utility Property” and the preceding preference axioms
No: these two strict comparisons violate the independence axiom for lottery preferences. Let denote the certain zero-money lottery. Reduction of compound lotteries givesFor example, the second expression assigns probability to the nonzero reward and to zero. The claimed must therefore implywhich is , contradicting the other claimed strict preference.
The same obstruction is visible in any proposed expected utility representation. Subtract from the utility function, and write and . The first comparison requires , hence , whereas the second requires . No real satisfy both. This argument requires neither risk neutrality nor an assumption that the utility function is increasing in money.
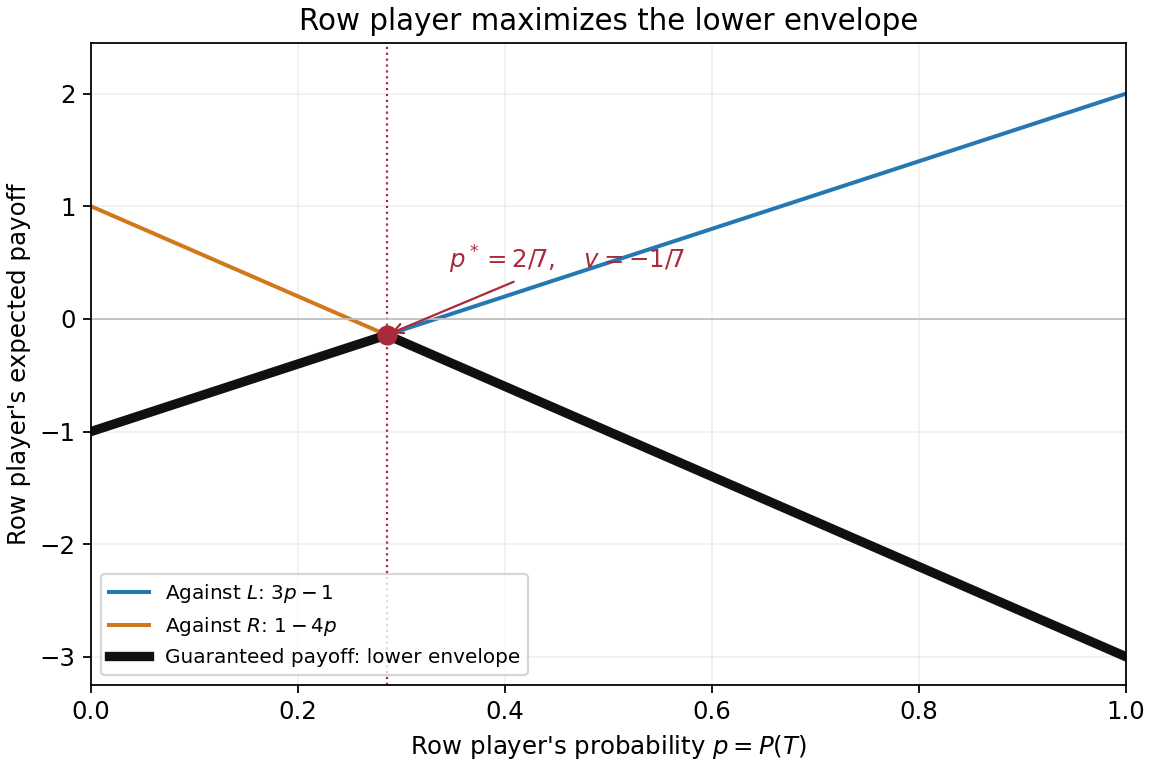
Put and , so the complementary probabilities are and . All four expressions are the row player's expected payoff, including those indexed by a column action. Direct expected value calculations giveThe column player's expected payoff is the negative of the row player's because this is a zero-sum game.
The bold black curve is the pointwise minimum of the two opposing-column expected payoff functions. It is the row player's security level payoff at the specified mixed strategy:The lines meet where , hence at . The first branch increases with slope and the second decreases with slope , so their intersection is the unique global maximum of the lower envelope:The endpoint values are and , both smaller. Since an opposing mixed strategy forms a convex combination of the two pure-column expected payoffs, it cannot make the row player's expected payoff lower than this envelope.
The bold black curve is now the pointwise maximum of the two pure-row expected payoff functions:It measures the largest expected payoff that the row player can achieve against column mixed strategy . The column player minimizes this quantity because its own payoff has the opposite sign. Equality of the two lines gives , or . The envelope decreases before that point and increases afterwards, givingThe endpoint values and are both larger. A row mixed strategy cannot exceed the greatest pure-row expected payoff, because its expected payoff is a convex combination of those two values.
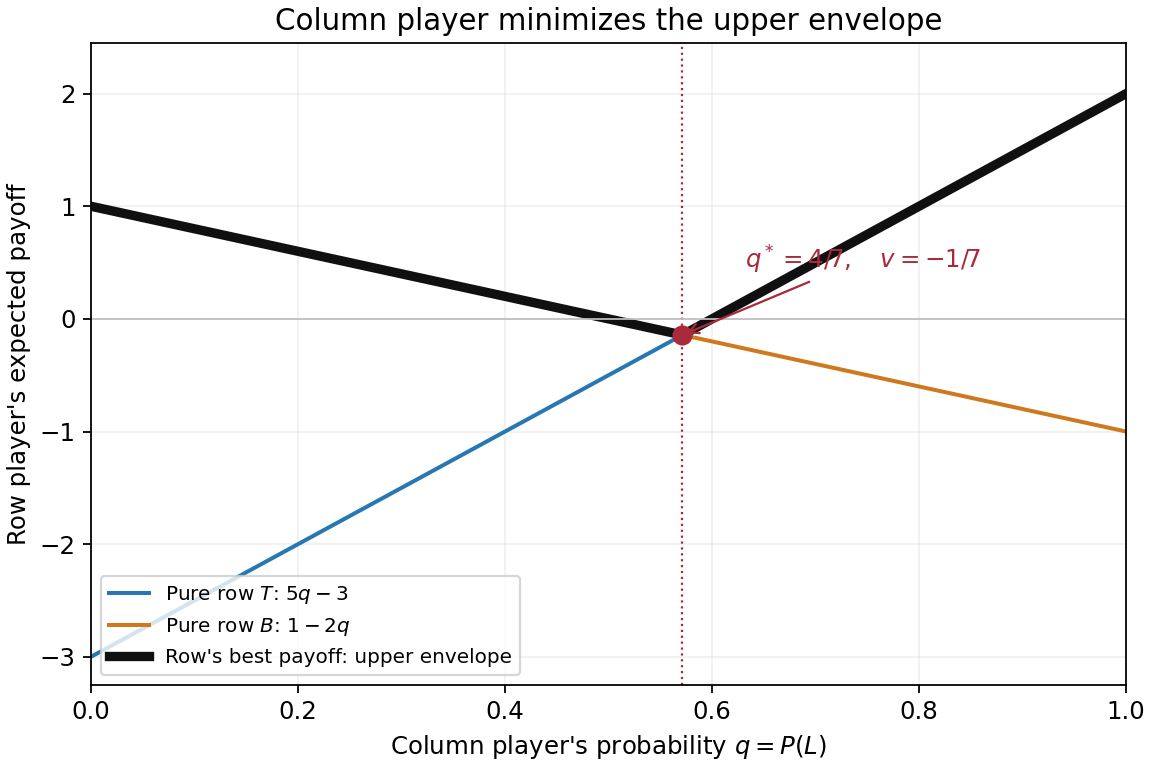
The unique Nash equilibrium uses row probabilities on and column probabilities on . The value of a zero-sum game to the row player is ; the column player receives .
The first graph solves the row player's max–min optimization: choose a mixed strategy guaranteeing the greatest possible worst-case expected payoff. The second solves the column player's min–max optimization: choose a mixed strategy placing the smallest upper bound on the row player's expected payoff. Their optimal heights agree, illustrating the minimax theorem.
There is also a direct Nash equilibrium certificate, so the conclusion does not depend on reading coordinates from a plot. At , both opposing pure columns give row expected payoff ; at , both pure rows give row expected payoff . By linearity, every unilateral deviation, including an arbitrary mixed strategy, leaves the deviator's expected payoff unchanged against the fixed opposing equilibrium mixture. Neither player can improve it. This is a mixed-strategy optimality certificate for a matrix game.
The equilibrium outcome is a probability distribution over cells, rather than one deterministic cell. Independent randomization givesThe resulting row expected payoff is . Finally, each envelope has a unique optimum, so any Nash equilibrium must use the displayed optimal mixed strategies. In particular there is no pure strategy Nash equilibrium.
Exactly , and can be sustained as constant stage game outcomes. Their long-run average payoffs are , and , respectively. We assume the usual repeated game monitoring convention: both players observe each completed joint action before the next round. The source's colour convention puts the blue lower-left row payoff first and the red upper-right column payoff second.
For necessity, row action earns against , so playing it forever guarantees a nonnegative long-run average payoff against every opposing pure strategy. Similarly, column action earns against and guarantees zero or more. Conversely, column action holds the row player's best possible stage payoff to , and row action holds the column player's to . Thus each player's minmax payoff is exactly .
Any Nash equilibrium must give both players at least zero, an individually rational payoff in a repeated game. Every off-diagonal cell has a negative payoff for one player: and hurt row, and hurt column, hurts row and hurts column. Repeating any such cell forever therefore permits a profitable unilateral deviation to the zero-guaranteeing action. The three diagonal cells pass this necessary test.
For sufficiency, fix target or . Each player's finite-state strategy has initial state and an absorbing state . In , output the player's component of ; remain in if the completed joint action equals , and otherwise move to . In , row always outputs and column always outputs , regardless of further observations. These are two-state grim trigger strategies; the separate machines are drawn below. The input is the observed joint action, so after any off-path history the prescribed continuation states agree.
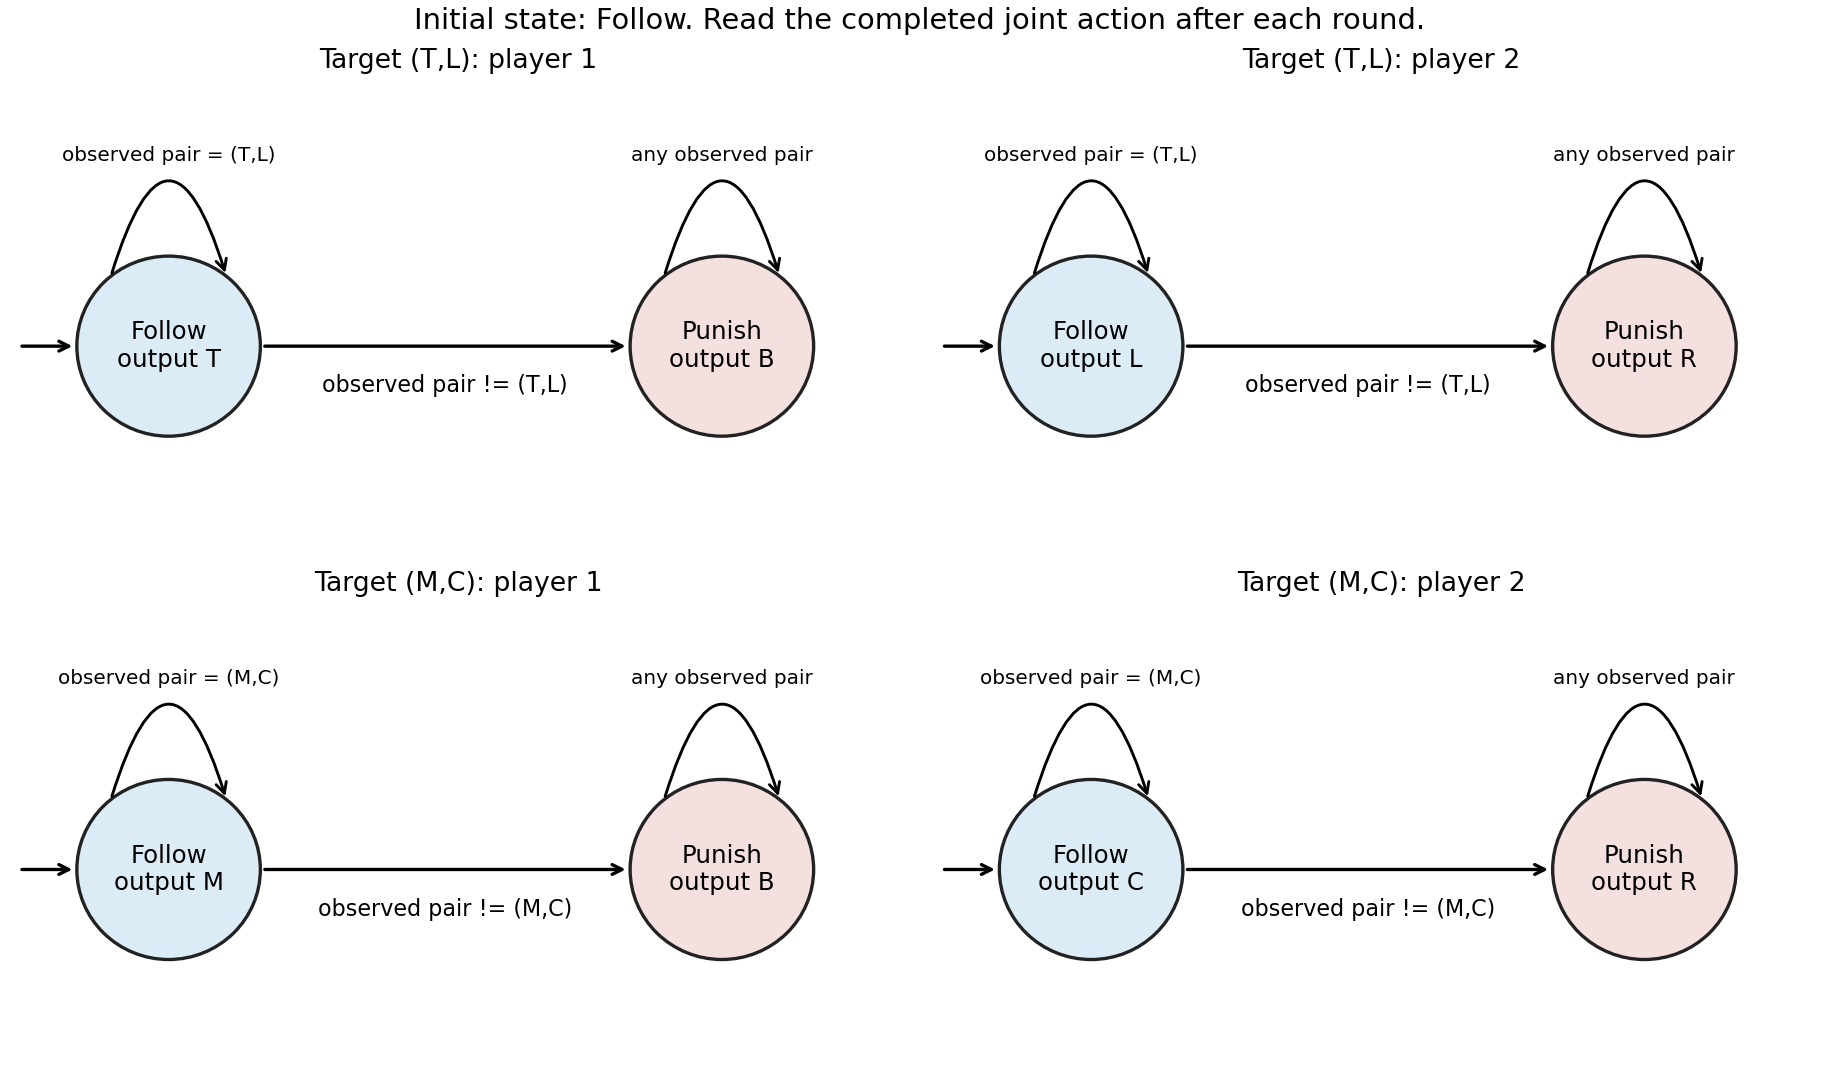


If neither player deviates, the target is repeated forever. If a player first deviates at a finite round , the opponent enters for all later rounds. Against column action , every row action earns at most zero; against row action , every column action earns at most zero. All payoffs are bounded, so the total reward before and at , divided by the horizon, tends to zero. The deviator's upper limiting average is therefore at most , below either target payoff or . This proof tests arbitrary future deviations, not merely a single changed action. It also rules out improvement by deviations whose averages fail to converge, if the criterion is extended by an upper or lower limit.
For target , one-state machines outputting and forever suffice: each is a best response to the other in every round. Their long-run average payoffs are zero and no unilateral deviation can improve them. In fact, the punishment is credible because is a stage Nash equilibrium, so the two positive-target constructions are also subgame perfect equilibria under the stated monitoring assumption. The general punishment mechanism is described in [ref]
Lecture 15: Repeated Games by Asu Ozdaglar. slides 12–15; those slides use discounting, while the finite-prefix argument here uses long-run averages
.“Outcomes of the stage game” here means a fixed action pair repeated forever. Allowing time sharing also sustains some average payoff vectors that are not stage cells: for example, a deterministic alternating cycle gives , with a two-phase finite-state strategy and the same permanent punishment. An off-diagonal cell may occur in a sustainable cycle; the impossibility above concerns its constant repetition, not every appearance on an equilibrium path. With finite-state pure strategies, an undisturbed path is eventually periodic, so its limiting cell frequencies are rational numbers.
Use the standard repeated game convention that the first round's joint action is observed before round two. The following original game tree represents simultaneous moves by making row move first in each round while hiding that current move from column. Terminal labels are total payoffs over both rounds, ordered row then column.
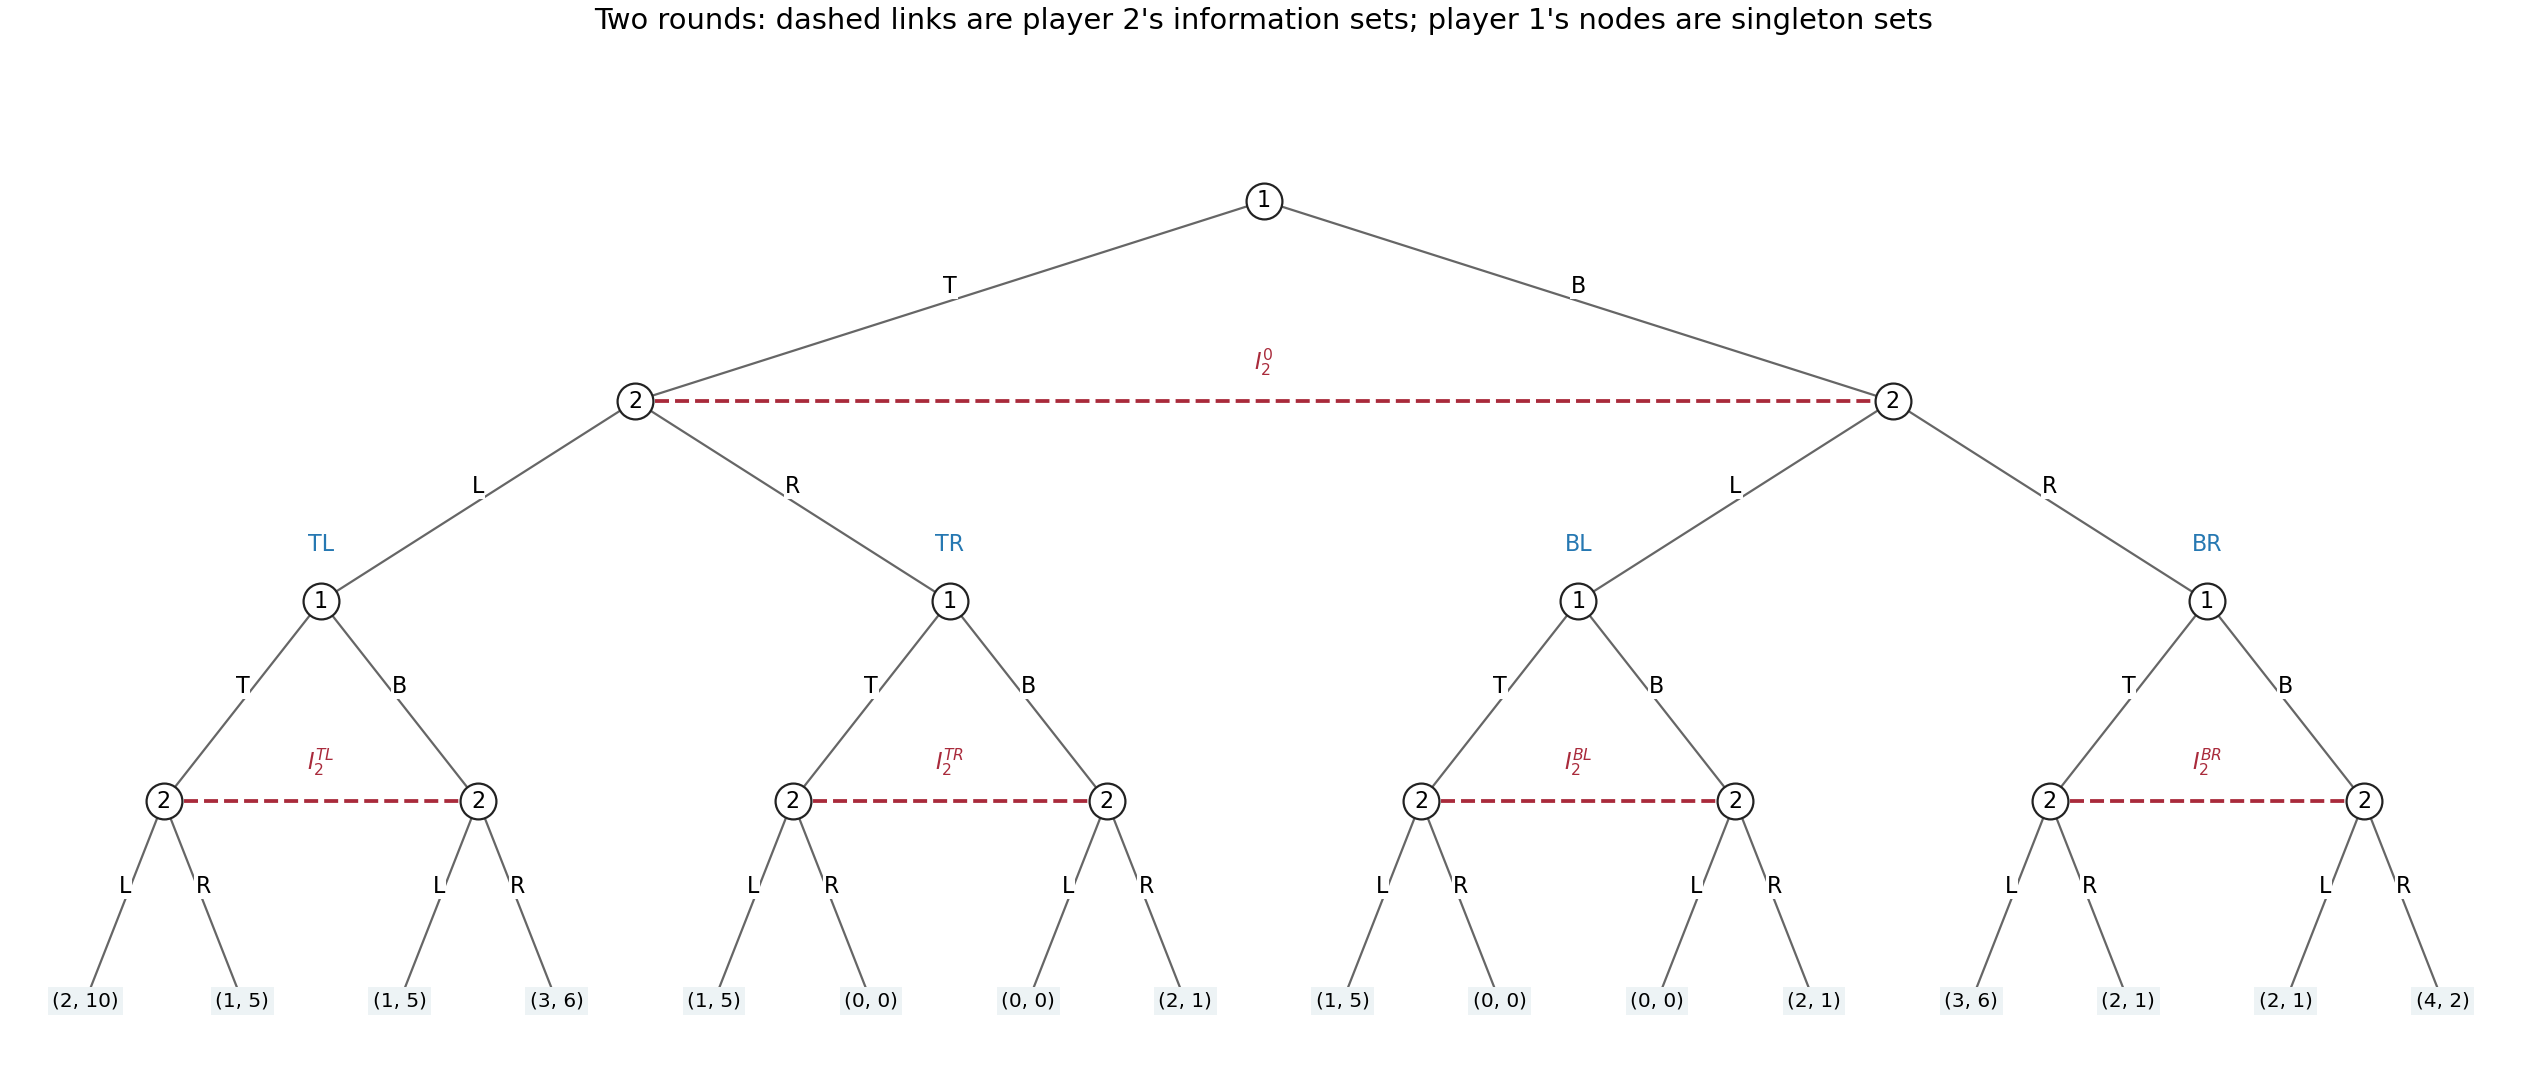
The full two-round extensive-form game, with all sixteen terminal payoff pairs and five column information sets
. Details. 
Formally, round one starts at a row decision with actions . The two ensuing column nodes form one information set , with available actions ; column cannot tell which current row action occurred. The four completed first-round histories are . At each , round two begins at a separate row node. Its two successors, after row's current or , form a column information set . Distinct have distinct information sets: both players know the whole first-round outcome. There are sixteen terminal histories , whose total payoff is , as displayed in the tree.
The row player's five information sets are the initial singleton and the four singleton round-two nodes, one per . The column player's five information sets are and the four two-node sets . Thus each player must specify one binary choice at each of five information sets, including histories that its own first choice might prevent:Counting only the four possible two-round action sequences would miss the distinct contingent responses to the opponent's first action.
For a concrete pair of complete pure strategies, order the second-round histories as and useThe first entry is the initial action, and the four remaining entries prescribe the action after each first-round history. This induces the unique path in round one followed by in round two. Hence the total payoff isThe off-path entries are part of each pure strategy, even though this pair does not reach them.
For randomization, a mixed strategy is a probability distribution over the complete plans, with free probabilities in a general distribution. A behavioural strategy instead gives one binary-action probability at each of five information sets, requiring five parameters. This game has perfect recall: a player never forgets a previous own action or a first-round observation, and the only concealed action is the opponent's current simultaneous choice. Consequently neither kind of randomization has a greater attainable-payoff advantage: Kuhn's theorem gives realization-equivalent strategies against every fixed opposing strategy.[ref]
Extensive games and the problem of information by Harold W. Kuhn. original article, pp. 193–216, equivalence under perfect recall
The equivalence can be verified directly here. Given a behavioural strategy, sample all five contingent actions independently before play; the resulting product probability distribution over complete plans is an equivalent mixed strategy. Conversely, let be a mixed strategy for player . Use its marginal probability for the initial action. At history containing own first action , choose second action with conditional probabilitywhenever the denominator is positive; if it is zero, choose arbitrarily at that unreachable history. The opponent's first-round action is simultaneous and cannot depend on the sampled hidden plan beyond the chosen first action. Thus conditioning on preserves exactly these conditional probabilities of actions, and multiplying the first- and second-round factors reproduces each terminal probability. Correlations between prescriptions at mutually exclusive second-round histories have no further observable effect. Behavioural strategies offer the more compact representation, while mixed strategies describe a single random choice of a full plan. Imperfect information here does not mean imperfect recall.
If the core is nonempty, it is exactly the singleton allocation for every . Take any in the core of a cooperative game and write . Core membership gives efficiency of the imputation, , and the coalition inequalitiesUsing the given complementary-coalition equality in this constant-sum cooperative game, the second inequality yieldsCombining upper and lower bounds gives for every coalition . In particular,Since this holds for any core member and at least one exists by hypothesis, the displayed allocation is in the core and is its only member. The argument also shows why nonemptiness is restrictive: it forces for every coalition, so the characteristic function of a coalitional game must be additive. No superadditive coalitional game or monotonicity assumption is needed.
cannot have an induced subgraph game representation. is represented by a weighted triangle with edge weights , , , and has Shapley value vector .
In an induced subgraph game, players are graph vertices and a coalition receives the sum of the weights of graph edges whose two endpoints lie in it. Therefore each two-player coalition determines the corresponding edge weight. For these weights would have to be , making the grand coalition worth , whereas its actual value is . No other edge weights can repair that discrepancy without changing a two-player coalition's value. Even a convention allowing vertex weights would not help: its singleton values force all such weights to zero.
For , the stated weighted graph triangle has grand coalition value and reproduces all three pair values. Empty and singleton coalitions contain no graph edges, so their values are zero. This verifies all eight coalitions and supplies the complete representation.
To compute the Shapley value, reveal players in a uniformly random permutation. An edge's weight contributes to an endpoint's marginal contribution precisely when the other endpoint appeared earlier. Each endpoint is later with probability , independently of where the third player appears. Linearity of the expected value therefore splits each edge weight equally between its two endpoints:The values sum to , as required by the Shapley value's efficiency property. This is the general Shapley value of an induced subgraph game formula, not an assumption that all three players are symmetric: player has a different incident-weight total.
The core is the singleton . Here the characteristic function of a coalitional game is , the two-person instance of the core of the miners game calculation.
Let be in the core. Efficiency requires , and every pair coalition requires . Summing the six pair inequalities counts each coordinate three times, giving . Efficiency makes this an equality; since every individual slack is nonnegative, all six pair inequalities must be equalities. In particular forces , and comparison with gives every .
Conversely, for the uniform allocation every coalition satisfiesand its total is . It is therefore a core member, completing both existence and uniqueness. In particular, a three-player coalition receives ; the pair constraints are the tight ones.
The core is empty. Efficiency would require . Each two-player coalition has value , so core membership would also requireAdding gives , contradicting efficiency, which makes the left side . Thus no allocation can meet all coalition demands. The obstruction uses only pair coalitions and the grand coalition; imposing individual rationality cannot remove it. The equal allocation is efficient but gives each pair only , so symmetry does not supply a core allocation.
Articles by others on the same topic
There are currently no matching articles.