Source paper: released examination archive.
Code follows Scala 2 style. Each question uses its own enclosing declarations and the supplied fields; alternative implementations with the same name are separate solutions. Mathematical correctness arguments use exact values unless floating-point arithmetic or machine-range bounds are discussed explicitly.
Use Horner's method, accumulating the high-degree coefficients before the low-degree ones:
def eval(x: Double): Double = {
  var i = a.length
  var value = 0.0
  while (i > 0) {
    i -= 1
    value = a(i) + x * value
  }
  value
}
At each while loop head the loop invariant isThe initial sum is empty. Decreasing
i and replacing the accumulator by a(i) + x * value extends that sum by one coefficient with the required powers shifted. The loop variant is i; on exit it is zero, so the accumulator equals . The code uses exactly multiplications and time, with constant auxiliary space, and also handles the empty coefficient array as the zero polynomial. Initializing from the last coefficient instead would save one multiplication for nonempty arrays.The invariant is an exact-arithmetic specification. With
Double, each arithmetic operation rounds; consequently the code evaluates the Horner expression in floating-point arithmetic, rather than guaranteeing the exact real value for arbitrary coefficients.The coefficient assumptions imply a nonconstant polynomial with and a positive leading coefficient. Thus as : dividing by its leading power of leaves the positive leading coefficient plus terms tending to zero. There is some with . A polynomial is continuous, so the intermediate value theorem supplies at least one positive root of a polynomial in .
This gives neither uniqueness nor monotonicity. Multiple crossings are possible. If the degree of a polynomial is an even integer, the same leading-term argument gives as , so there is also a negative root of a polynomial. For an odd integer degree of a polynomial no negative root of a polynomial is forced; a linear polynomial with negative constant coefficient and positive slope is a counterexample.
Maintain opposite signs at the endpoints, rather than assuming that the polynomial is monotone:
def floorRoot(X: Int): Int = {
  require(X > 0 && eval(0.0) <= 0.0 && eval(X.toDouble) > 0.0)
  var lo = 0
  var hi = X
  while (hi - lo > 1) {
    val mid = lo + (hi - lo) / 2
    if (eval(mid.toDouble) <= 0.0) lo = mid
    else hi = mid
  }
  lo
}
The loop invariant is and . Both branches preserve those signs, even when there are other roots of a polynomial or sign reversals elsewhere. When the interval width exceeds one, the midpoint is strictly between its endpoints, so the positive integer loop variant
hi - lo strictly decreases. On exit hi == lo + 1, giving the required postcondition . Continuity establishes a root of a polynomial between those adjacent integers, possibly at the left endpoint.The width is at most halved with rounding upwards, so there are at most midpoint evaluations, plus two endpoint evaluations in the precondition check. The midpoint expression avoids adding two large endpoints. The explicit positive upper-bound precondition supplies the interval order assumed in the question. For the literal computed-
eval contract, the same proof holds provided evaluated midpoints are not NaN; identifying its bracket with the real polynomial additionally requires trustworthy evaluation signs.First find a sign bracket by exponential search, then bisect that bracket without evaluating its endpoints again:
def floorRoot(): Int = {
  require(eval(0.0) < 0.0)
  var lo = 0
  var hi = 1
  while (eval(hi.toDouble) <= 0.0) {
    lo = hi
    require(hi <= Int.MaxValue / 2, "doubling bound exceeds Int range")
    hi *= 2
  }
  while (hi - lo > 1) {
    val mid = lo + (hi - lo) / 2
    if (eval(mid.toDouble) <= 0.0) lo = mid
    else hi = mid
  }
  lo
}
For the first while loop the loop invariant is , with
hi a positive power of two, and either or . Every previously tested power of two has nonpositive value. Let be the least nonnegative integer for which . It exists by the positive leading coefficient. If the current upper endpoint is , a mathematical loop variant is while the guard holds; the next doubling decreases it by one. The first while loop's postcondition is . The second while loop has exactly the invariant, variant and adjacent-integer postcondition established in part c.There are evaluations at powers of two. If , the final bracket has width and takes exactly midpoint evaluations. Including the initial sign check, the total is evaluations for , and two for . Thus evaluation cost is for the first positive dyadic bound ; it is not a claim about the first positive root of a polynomial when the polynomial is nonmonotone.
The mathematical argument uses unbounded integer endpoints and reliable signs. The guarded
Int implementation requires the successful dyadic bound to fit in Int; otherwise it explicitly fails rather than wrapping to a negative bound. The coefficient assumptions alone cannot guarantee that a requested integer result fits a fixed-width type. Floating-point overflow or unreliable signs likewise need a wider or certified evaluator for a fully general implementation.Scan the two suffixes until a mismatch or an endpoint:
def longestFrom(i: Int, j: Int): Int = {
  require(0 <= i && i <= N && 0 <= j && j <= N)
  var k = 0
  while (k < N - i && k < N - j && a(i + k) == a(j + k)) {
    k += 1
  }
  k
}
The loop invariant is and equality of the two array segments of length . The loop variant is , which decreases whenever the while loop runs. Short-circuit evaluation checks both bounds before indexing. On exit either a string suffix has ended or the next characters differ, so no longer common string prefix is possible. Thus the returned value is the longest common prefix length. Overlap is allowed: the code only reads the array, so the two matching segments need not occupy disjoint storage.
Compare every unordered pair of distinct starting positions:
def longestRepeated(): (Int, Int, Int) = {
  require(N >= 2)
  var besti = 0
  var bestj = 1
  var bestk = 0
  var i = 0
  while (i < N - 1) {
    var j = i + 1
    while (j < N) {
      val k = longestFrom(i, j)
      if (k > bestk) {
        besti = i; bestj = j; bestk = k
      }
      j += 1
    }
    i += 1
  }
  (besti, bestj, bestk)
}
After each comparison, the stored triple attains the largest common-prefix length among pairs processed so far; its positions remain distinct. The nested while loops enumerate exactly pairs. Reversing the two positions does not change their common-prefix length, so no omitted ordered pair could improve the answer. Initialization also supplies a valid length-zero answer if no character repeats.
Write for the final maximal length. Each comparison takes time, including a possible first mismatch. Hence time is , at worst , and auxiliary space is . Writing merely would miss the case. The explicit precondition excludes arrays with fewer than two valid starting positions; the requested distinct-position triple has no answer there under this domain convention.
All suffixes beginning with a fixed string form an interval in lexicographic order. To see this, suppose two suffixes start with a string , while a string suffix between them fails to start with . At its first differing character it must be either smaller than both or larger than both; if it ends before does, it is smaller than both. Either possibility contradicts its position between them.
Now take a longest repeated substring . Its two occurrences are prefixes of two distinct suffixes. Every string suffix between them also begins with , so at least one adjacent pair in that interval has a common string prefix of length at least . A greater length would contradict maximality of . Therefore the maximum common-prefix length over adjacent sorted suffixes equals the longest repeated-substring length. If the maximum is zero, any adjacent pair still attains it. The argument does not assume nonoverlapping occurrences.
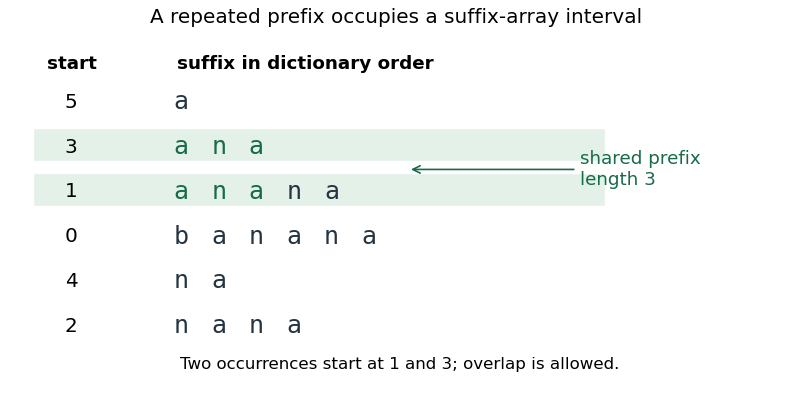
Original suffix-array example for banana: an interval of suffixes shares the repeated prefix ana
. Details. Reuse the verified longest-common-prefix scan, handling equality before scanning:
def before(i: Int, j: Int): Boolean = {
  require(0 <= i && i < N && 0 <= j && j < N)
  if (i == j) false
  else {
    val k = longestFrom(i, j)
    if (j + k == N) false
    else if (i + k == N) true
    else a(i + k) < a(j + k)
  }
}
There is no additional while loop: the helper's loop invariant is that the first
k characters agree and both indices remain in bounds. If the second string suffix ends first, the first cannot precede it; if the first ends first, it is a proper string prefix and precedes the second. Otherwise the first mismatching characters decide lexicographic order. Distinct suffixes cannot both end after the same number of characters, since their lengths differ.The
i == j case ensures a strict comparator, returning false for a string suffix compared with itself, in constant time. For distinct suffixes its running time is , where is the longest repeated-substring length of the full array.Sort string suffix starting positions, then examine only adjacent entries:
def longestRepeated(): (Int, Int, Int) = {
  require(N >= 2)
  val suffixes = (0 until N).toArray.sortWith(before)
  var besti = suffixes(0)
  var bestj = suffixes(1)
  var bestk = 0
  var t = 1
  while (t < N) {
    val i = suffixes(t - 1)
    val j = suffixes(t)
    val k = longestFrom(i, j)
    if (k > bestk) {
      besti = i; bestj = j; bestk = k
    }
    t += 1
  }
  (besti, bestj, bestk)
}
The while loop retains a best triple among adjacent pairs already visited. All string suffix starting positions are distinct, and the adjacent-suffix characterization proves that considering these pairs suffices. The two definitions named
longestRepeated in parts b and e are alternatives, not duplicate members of one software class.Assuming a comparison sort using comparator calls, sorting takes time, because each comparison scans characters. The final pass takes . Thus overall time is , at worst , with auxiliary storage for indices and ordinary sorting workspace. Merely storing indices does not make string suffix comparisons constant-time; claiming here would omit their cost. Faster suffix-array constructions require additional machinery beyond this comparator-based solution.
Use two finite integer lists , with the head of each list representing its stack top. Initially both are empty. A suitable abstract object interface is
trait DoubleStack {
  def pusha(x: Int): Unit
  def pushb(x: Int): Unit
  def popa: Int
  def popb: Int
  def isEmptya: Boolean
  def isEmptyb: Boolean
}
For the unbounded abstract data type, each push has no logical precondition. The postcondition of
pusha(x) is and ; pushb(x) symmetrically gives and . The precondition of popa is , and its postcondition is return value , new state , and unchanged . The specification for popb exchanges . Each emptiness query leaves both lists unchanged and returns exactly whether its corresponding list is empty.These frame conditions matter: an operation on one stack must preserve the other, not merely produce the right return value.
A fixed-capacity implementation needs a bounded contract: , and a push requires strict inequality. Pop preconditions and all successful-operation postconditions remain unchanged. An implementation that rejects full-array pushes cannot satisfy an unbounded specification promising every push; the capacity restriction must be part of the agreed abstract data type, or its resource-failure behavior must be specified.
Use one array and two boundaries
left and right. The first stack occupies indices below left and grows rightwards; the second occupies indices at least right and grows leftwards. The representation invariant isThe abstraction function isBoth lists are top-first. The unoccupied middle interval has length right - left; a push is possible exactly when this is positive. Thus every array position can be used by either stack, avoiding a rigid half-array allocation.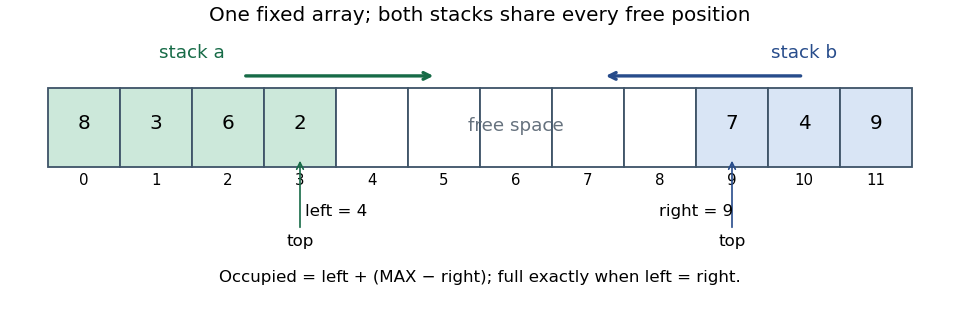


The implementation maintains the two boundaries from part b:
class ArrayDoubleStack(val MAX: Int) extends DoubleStack {
  require(MAX >= 0)
  private val data = new Array[Int](MAX)
  private var left = 0
  private var right = MAX

  def isEmptya: Boolean = left == 0
  def isEmptyb: Boolean = right == MAX

  def pusha(x: Int): Unit = {
    require(left < right, "double stack is full")
    data(left) = x
    left += 1
  }
  def pushb(x: Int): Unit = {
    require(left < right, "double stack is full")
    right -= 1
    data(right) = x
  }
  def popa: Int = {
    require(left > 0, "stack a is empty")
    left -= 1
    data(left)
  }
  def popb: Int = {
    require(right < MAX, "stack b is empty")
    val answer = data(right)
    right += 1
    answer
  }
}
Initialization gives empty abstract lists. Each push consumes one free position next to the appropriate top; each pop returns that top and releases its position. The guards preserve the ordering of the two boundaries and prevent invalid indexing. The abstraction function shows directly that the untouched stack is unchanged. Keeping
data private prevents clients from violating the representation invariant; this strengthens encapsulation relative to a publicly exposed implementation field without changing the six required operations.All six operations run in time, with a fixed array of
MAX integers and constant extra state. Creating and zero-initializing the array takes time, outside those operation bounds. Capacity zero gives a valid always-empty bounded structure whose pushes fail their precondition.For a finite acyclic linked list define the node sequence, retaining software object identities, byThen scan without changing any links:
def findMin(first: Node): Node = {
  require(first != null)
  var best = first
  var cursor = first.next
  while (cursor != null) {
    if (cursor.datum < best.datum) best = cursor
    cursor = cursor.next
  }
  best
}
At each while loop head, write . The loop invariant says is nonempty,
best belongs to , and its datum is no larger than that of every node in . Initially contains only first; comparing the next node extends the processed string prefix and preserves minimality. The loop variant strictly decreases. At exit the whole list is processed, so the returned reference identifies a minimum node. Ties retain the earliest minimum. Time is linear in the number of nodes and auxiliary space is constant.A sentinel node supplies a permanent predecessor for the first real node. Inserting or deleting at the front then uses the same
predecessor.next update as an interior operation. Its datum is not a multiset element: the chosen extreme integer is merely unused sentinel data.A representation invariant requires a nonnull fixed header, a finite acyclic chain starting at
bagHeader.next, and exclusion of the header from that chain. Each node identity occurs once, although different nodes may have equal data. Representation links are owned by the implementation, so outside mutation cannot alter them unexpectedly.The abstraction function counts occurrences:This yields nonnegative multiplicities and finite support. Initialization with a null successor gives the empty multiset. Excluding the sentinel is essential even when a real item equals its datum.
The precondition is
n != null and , using node identity rather than datum equality. Search for its predecessor:def delete(n: Node): Unit = {
var previous = bagHeader
while (previous.next ne n) {
previous = previous.next
}
previous.next = n.next
n.next = null
}The loop invariant states that
previous is the header or a preceding real node, and . The loop variant is the number of links from previous to n minus one. The precondition guarantees that this search reaches the predecessor before a null dereference. Replacing its successor by n.next bypasses exactly the requested node; clearing the removed node's link detaches it for later reuse. The order and identities of every other node remain unchanged. In abstract terms, only the multiplicity of n.datum decreases, by one. The worst-case time is linear; the pointer modification itself is constant-time.Check that at least one real node exists, then compose the two helpers:
def deleteMin(): Int = {
  require(bagHeader.next != null, "bag is empty")
  val smallest = findMin(bagHeader.next)
  val answer = smallest.datum
  delete(smallest)
  answer
}
The precondition check makes
findMin applicable. Its result belongs to the real-node sequence, satisfying delete's precondition. Consequently one minimum value is returned and exactly one occurrence is removed; duplicates remain as distinct nodes. Saving the datum before deletion also separates the return value from subsequent link mutation. Two linear traversals still give time for a multiset containing nodes, with constant auxiliary space.Let and describe the entry state. The postcondition is: the multiset is empty; the returned chain is sorted nondecreasingly; its node sequence is a permutation of . Thus it has exactly the original multiset of data and preserves all duplicates. Strict increase is impossible when the multiset contains repeated values.
def getAllSorted(): Node = {
  var head: Node = null
  var tail: Node = null
  while (bagHeader.next != null) {
    val nextSmallest = findMin(bagHeader.next)
    delete(nextSmallest)
    nextSmallest.next = null
    if (head == null) head = nextSmallest
    else tail.next = nextSmallest
    tail = nextSmallest
  }
  head
}
The loop invariant partitions the original node identities into the remaining multiset and the returned-prefix chain. The latter is sorted, its last node is
tail, and every datum in it is no larger than every remaining datum. Selecting a minimum and appending that detached node preserves all these facts. The loop variant is the number of real nodes remaining in the multiset, decreasing by one. When it reaches zero the string prefix contains the entire original node set, proving the postcondition. An initially empty multiset returns null.This is linked-list selection sort. Its time is in general, from successive scans of lengths , and it uses constant auxiliary space: it relinks original nodes instead of allocating a new node for each item.
Use null to indicate that the requested key is absent:
private def find(name: String, head: Entry): Entry = {
  var cursor = head
  while (cursor != null && cursor.name != name) {
    cursor = cursor.next
  }
  cursor
}
The loop invariant is that the skipped string prefix contains no entry with the requested name and
cursor starts the unsearched string suffix of the unchanged bucket. Its remaining length is a loop variant. Short-circuit evaluation prevents accessing a null entry. On exit, either cursor is null and the whole bucket has been ruled out, or its name equals the key. No list links or stored numbers are modified. String comparison here uses value equality; node deletion elsewhere uses reference identity.Assume the supplied hash function is stable and produces valid table indices. The representation invariant places each name in its hashed bucket, permits at most one entry per name, and requires finite acyclic, disjoint bucket chains.
def store(name: String, number: String): Unit = {
  val bucket = hash(name)
  val entry = find(name, table(bucket))
  if (entry == null) {
    table(bucket) = new Entry(name, number, table(bucket))
  } else {
    entry.number = number
  }
}
If the key exists, updating its associated number implements map override without creating a duplicate entry. Otherwise a new entry is prepended to the correct bucket and leaves every existing mapping unchanged. Its immutable name preserves bucket membership. Thus the mapping afterwards is the old mapping overridden at precisely the supplied key. Hash collisions between different names do not imply key equality and are handled by separate chaining.
Membership is exactly whether the bucket search finds an entry:
def isInBook(name: String): Boolean = {
  find(name, table(hash(name))) != null
}
By the bucket-placement representation invariant, an entry with this name can occur only in this bucket. The
find contract therefore proves true exactly for keys in the map's domain, with no state change. One hash calculation and one bucket traversal suffice; no insertion is performed during the query.Find the entry once and check the abstract membership precondition on that result:
def recall(name: String): String = {
  val entry = find(name, table(hash(name)))
  require(entry != null, "name is not in the book")
  entry.number
}
The check turns an invalid call into an explicit precondition failure rather than an accidental null dereference or an invented default number. For a valid call, the unique matching entry contains exactly the mapped value, so the stored number is returned and the map is unchanged. Testing membership by calling
isInBook first would traverse the same bucket twice; retaining the found reference avoids that redundant work.The relevant quantity is the hash-table load factor , where is the number of distinct keys and the bucket count. With a suitable distribution of hashes, separate chaining has expected operation cost , treating key operations as constant-cost. Keeping only one hundred buckets while grows therefore increases average search length.
Balanced binary search trees could reduce a bucket search from linear time in its occupancy to logarithmic time. Unbalanced binary search trees provide no such guarantee: insertion order can produce a chain. Even balanced trees add comparison and node-management overhead, which may dominate for small buckets.
A usual first remedy is grow the table and rehash its entries, keeping the load factor bounded. Geometric growth gives amortized constant resizing overhead per insertion; with suitable hashing, expected lookup, update and insertion costs remain constant. Resizing is when performed and is not a worst-case constant-time guarantee for that particular operation. Balanced buckets can still be useful for heavy or adversarial collisions, but replacing every bucket tree does not by itself repair a poor hash function. For variable-length strings, hashing and string comparisons add their own character-processing costs.
A single bucket holding about a quarter of all keys suggests severely nonuniform hashing or a strongly skewed/adversarial key set, rather than ordinary load growth alone. With one hundred well-used buckets the expected fraction in one fixed bucket is about one hundredth. Persistent concentration near one quarter is evidence to investigate, not a proof identifying one particular implementation bug.
Inspect the bucket histogram, raw hash outputs and patterns in the names. A hash depending only on an initial character, weak mixing of common prefixes, or an indexing rule using few possible buckets could create this behavior. Improve the hash so that it uses the complete key and spreads this workload across the table, then rehash every stored entry. Check the valid-index rule as well, including negative machine hash values.
Increasing the table size is useful if index reduction caused the concentration; it cannot separate keys that all receive the same raw hash. For maliciously chosen keys, randomized or keyed hashing and balanced collision structures may be appropriate. The observed occupancy does not justify assuming uniformly random hashes in a performance claim.
A suitable relationship is a circle implementing a read-only shape object interface whose operations include area. Every circle satisfies that object interface's behavioral contract, so clients using a shape can use a circle through subtype polymorphism; dynamic dispatch selects its area implementation.
A car is not appropriately modeled as a subclass of an engine merely because it needs engine behavior. Use object composition: the car contains an engine and delegates engine-related work to it. An engine is a component of a car, not a category containing cars. The design can replace the component independently without making all engine operations part of the car's public object interface. Class inheritance should reflect substitutability, rather than serve solely as a convenient way to obtain another software class's code.
Protected access makes
size available to subclasses implementing the set operations, while preventing ordinary outside clients from assigning arbitrary values to it. The implementations need to update the count when membership changes; clients should affect membership only through the public operations. A publicly writable count could make an emptiness query disagree with the stored elements.Protection supports encapsulation but does not prove the representation invariant. Subclasses can still update the field incorrectly and must maintain its relationship to the actual set cardinality. In particular, subclass code does not obtain unrestricted access to the protected field of every unrelated set software object.
Throw an informative exception, such as
NoSuchElementException, and leave the set unchanged. This makes a violated nonempty precondition visible at the point of misuse. Returning a distinguished integer would be ambiguous because every integer is a legitimate set member.A different object interface could return an optional integer, representing failure explicitly, but that changes the declared return type. For the supplied integer-returning operation, a checked failure is useful and consistent with the stated precondition.
Count each invocation before delegating, including duplicate insertions, and reset after clearing:
class IntegerSetWithCount extends IntegerSet() {
  private var attempts = BigInt(0)

  override def insert(x: Int): Unit = {
    attempts += 1
    super.insert(x)
  }
  override def clear: Unit = {
    super.clear
    attempts = BigInt(0)
  }
  def getCount: BigInt = attempts
}
The inherited implementation already maintains
size; the new counter measures insertion attempts, not successful increases in cardinality. Deletion and popping do not subtract from it. Incrementing before delegation also counts an attempted insertion that subsequently fails a capacity check. Arbitrary-precision arithmetic avoids silently wrapping the historical count, though its arithmetic is not constant-cost for arbitrarily large counts.As the source supplies no object constructor signature for the concrete set, this code uses a fresh default-constructible
IntegerSet, with matching default capacity. Its correct behavior also assumes the base implementation does not internally invoke these overridable operations in a way that interferes with the counter. Part e exhibits that dependency.Source-signature qualification for the following set implementations: the intended membership query must be declared
def contains(x: Int): Boolean. The printed abstract declaration omits its result type; interpreted literally as Scala 2 procedure syntax, it returns Unit. The solutions use the explicit Boolean query contract, and Unit for the two mutators. Parameterless clear is overridden without adding parentheses.[ref]Scala 2.13 basic declarations and definitions specification. Procedures: a method declaration omitting its result type implicitly has Unit result
A base-class change can preserve its own set abstraction while breaking a subclass that intercepts internal calls. For example, suppose
IntegerSet.delete(x) is reimplemented by collecting the elements to retain, calling clear, then calling insert for each retained element. Conceptually its body isval retained = snapshotOfElements.filter(_ != x)
clear
retained.foreach(insert)Here
snapshotOfElements denotes the base implementer's own internal snapshot operation in this hypothetical revision, not an API supplied by the examination. The algorithm still removes exactly the requested value and preserves all other set members.On an
IntegerSetWithCount, however, these unqualified calls use dynamic dispatch. The internal clear resets the subclass counter and the internal insertions increase it. After client calls insert(10), insert(20), insert(10), the correct count is three. Calling delete(10) with this revised base implementation leaves the right set, containing only the other value, but resets the counter and reinserts that value, leaving count one instead of three. The client made no further insertion attempt and requested no clear.This is the fragile base class problem: subclass correctness depends on the base implementation's internal call structure, beyond its public set postconditions. A change need not alter the base API to expose that dependence.
Give the wrapper exclusive ownership of a fresh delegate. It maintains its own inherited size so that inherited emptiness queries remain correct:
class IntegerSetWithCount extends IntegerSetPattern() {
  private val delegate = new IntegerSet()
  private var attempts = BigInt(0)

  override def contains(x: Int): Boolean = delegate.contains(x)

  override def insert(x: Int): Unit = {
    attempts += 1
    val wasPresent = delegate.contains(x)
    delegate.insert(x)
    if (!wasPresent) size += 1
  }
  override def delete(x: Int): Unit = {
    val wasPresent = delegate.contains(x)
    delegate.delete(x)
    if (wasPresent) size -= 1
  }
  override def pop(): Int = {
    if (isEmpty) throw new NoSuchElementException("set is empty")
    val answer = delegate.pop()
    size -= 1
    answer
  }
  override def clear: Unit = {
    delegate.clear
    size = 0
    attempts = BigInt(0)
  }
  def getCount: BigInt = attempts
}
Use the explicit membership signature and fresh default-constructible concrete set qualified in part d. The representation invariant is that the wrapper's
size equals the delegate's cardinality and its counter equals client insertion attempts since construction or the latest successful client clear. The updates shown preserve that invariant when delegated operations fulfill their set contracts and failure checks leave the delegate unchanged. A duplicate does not increase size; deleting an absent element does not decrease it. Size changes follow successful delegation, whereas an attempted insertion is counted immediately.Object composition prevents internal delegate calls from dispatching into the wrapper's counter object methods. It therefore survives the particular base revision in part e. The cost is forwarding code, another software object, some redundant size state imposed by the chosen abstract superclass, and extra membership queries. Future object interface additions must also be forwarded explicitly. This solution is an alternative definition of the software class in part d, not a second simultaneous definition.
Subtype polymorphism lets a reference with a common supertype denote values of different implementing classes. A call through that reference uses dynamic dispatch to select the concrete implementation.
Parametric polymorphism defines an operation or data structure using type parameters, such as a collection with an element-type parameter. Instantiations retain type information while reusing one generic definition.
Ad hoc polymorphism, commonly expressed by method overloading, gives several implementations the same name but different parameter signatures. The compiler selects a suitable overload using the available static types. This selection differs from later dynamic dispatch on the receiver of a selected instance method. A programming language can support all three in one program.
TODO: supply or verify the exact Ewoks practical version used for this examination, including its relevant object interface, implementing classes and call site. The printed paper names the editor but supplies no software class hierarchy or API from which its particular example can be reconstructed.
An earlier official 2015–2016 synopsis identifies Ewoks as a text-editor case study and associates that material with commands represented as software objects and with dynamic binding. That is historical context, not verification of the 2021 practical implementation.[ref]
Object Oriented Programming course synopsis of the University of Oxford (2015-2016). Designing with objects, lectures 6–8: Ewoks, commands as objects, and dynamic binding
The method for completing the answer is to identify a common command or editing object interface, two actual implementations from the verified project, and a client call made through the common object interface. Subtype polymorphism would let that client select different behavior without inspecting concrete classes, improving extensibility and separating editing behavior from the code that invokes it. No particular Ewoks software class names or object method signatures are asserted here, so this context-dependent leaf remains incomplete.
val square: Fun[Int, Int] = new Fun[Int, Int] {
  override def apply(x: Int): Int = x * x
}
Parametric polymorphism occurs because the generic trait is specialized by choosing its argument and result types. Subtype polymorphism occurs because the anonymous implementing software class is used through a
Fun[Int, Int] reference; calls to its apply operation use the object interface contract and dynamic dispatch. Multiplication itself is not the second polymorphism needed for this explanation.For values whose mathematical squares fit in a signed 32-bit integer, the result is the ordinary square. Outside that range, the supplied integer return type cannot represent every mathematical square, and the multiplication follows Scala integer-overflow behavior. An implementation requiring exact mathematical results for all integer inputs would need a wider result type or an explicit overflow exception.
A function accepting every
Base can safely be used where only Derived inputs will be supplied. The reverse direction is unsafe. A Derived argument is already a valid Base argument; restricting the possible callers introduces no new obligation for the function. This is the contravariant input rule of function subtyping.The printed trait has generic type invariance, so Scala does not directly permit either parameter-changing assignment. The safe behavior can be exposed using an explicit adapter without changing that trait:
def restrictInput(f: Fun[Base, Base]): Fun[Derived, Base] =
  new Fun[Derived, Base] {
    def apply(x: Derived): Base = f(x)
  }
For the unsafe direction, take illustrative classes in which a derived software object has an extra operation:
class Base
class Derived extends Base { def special(): Int = 1 }
val narrow = new Fun[Derived, Base] {
  def apply(x: Derived): Base = { x.special(); x }
}
def broadClient(f: Fun[Base, Base]): Base = f(new Base)
// broadClient(narrow) must be rejected.
If that substitution were accepted, the client could pass an ordinary base software object to code that calls
special, which that software object does not support. The rejected call is intentional counterexample code, not a promised compilable application. Variance annotations are needed to make sound direct conversions part of the generic trait's declared subtyping relation.[ref]Scala 2.13 variance annotations specification. Variance Annotations: missing annotation is invariant; method-input positions reverse variance
Fun[Base, Derived] can safely supply a Fun[Base, Base] contract; Fun[Base, Base] cannot in general supply a Fun[Base, Derived] contract. The input obligation is unchanged, while a derived result satisfies every base-result promise. This is the covariant output rule of function subtyping.With the invariant printed trait, implement the safe view explicitly:
def widenResult(f: Fun[Base, Derived]): Fun[Base, Base] =
  new Fun[Base, Base] {
    def apply(x: Base): Base = f(x)
  }
Using the illustrative classes from part i, an unsafe substitution would let a client assume a derived-only operation on a result that is merely a base software object:
val broadResult = new Fun[Base, Base] {
  def apply(x: Base): Base = new Base
}
def derivedResultClient(f: Fun[Base, Derived]): Int =
  f(new Base).special()
// derivedResultClient(broadResult) must be rejected.
The direct, variance-aware object interface that would express both safe directions is
trait Fun[-S, +T] { def apply(x: S): T }. Its object method consumes the contravariant parameter and produces the covariant parameter. This is an explicitly proposed variant of the printed invariant declaration, not an assumption that its annotations were already present.Give the two components independent upper type bounds and immutable fields:
final case class BoundedPair[+A <: Base, +B <: Base](first: A, second: B)Each component type must be a subtype of
Base, but the two need not be the same subtype. The pair's fields cannot be reassigned. Their read-only use permits covariant type parameters; the separate upper type bounds constrain admissible instantiations.[ref]Scala 2.13 basic declarations and definitions specification. Type Parameters and Variance Annotations: upper bounds restrict admissible arguments; immutable output positions permit covariance
The component accessors retain their precise static types. For example, a
BoundedPair[Derived, Base] exposes its first component as Derived, so derived-specific operations are available without a cast. A pair whose two fields are simply declared Base discards that distinction. Immutability here concerns the two stored references; it does not guarantee that the referenced software objects have immutable internal state.Override the operation and scale the result of exactly one superclass call:
class ScaledSumChannel(factor: Int) extends SumChannel {
  override def apply(n: Int): Int = factor * super.apply(n)
}
The superclass updates its previous-input state once and returns its ordinary sum; only that returned value is scaled. The inputs and superclass history are unchanged by the scaling. Reimplementing the state update is unnecessary and could accidentally diverge from the superclass contract. As in the supplied channel, arithmetic uses the declared fixed-width integer type.
Use the decorator pattern. The wrapper implements the same object interface as its component and delegates before changing the output:
class ScaledChannel(inner: Channel, factor: Int) extends Channel {
  override def apply(n: Int): Int = factor * inner(n)
}
It can wrap any channel software object, not only a sum channel. Constructing the wrapper at run time chooses the additional behavior for an existing component, and several wrappers can be composed without adding a subclass for every combination. Each call reaches the wrapped channel once, preserving its state evolution. Scaling the input instead would define a different transformation, particularly for a component that already has history.
Class inheritance offers a compact specialized implementation: the scaled sum is also a
SumChannel and can be used where that concrete type is required, while its inherited state handling is reused directly.The decorator supports run-time object composition over any
Channel implementation, including an already constructed stateful software object, without editing or subclassing each concrete software class. Its extra software object and delegation are a small cost. The two approaches therefore serve different reuse needs; the wrapper need not pretend to be the concrete sum-channel software class.Feed each returned output back as the next input to the same channel software object:
class RepeatedChannel(inner: Channel, times: Int) extends Channel {
  require(times > 0)
  override def apply(n: Int): Int = {
    var value = n
    var completed = 0
    while (completed < times) {
      value = inner(value)
      completed += 1
    }
    value
  }
}
The loop invariant says that
value and the component's current state are exactly those after completed successive applications starting from this invocation's input and the entry state. The loop variant is times - completed. On exit the specified number of applications has occurred; the component is not reset or replaced between them.For input one and a freshly created sum channel, the successive outputs areInitially the component's previous input is zero. The first output is one; on each later call its previous-input state is the input used on the preceding call. Consequently outputs follow the Fibonacci recurrence with initial outputs one and two. The answer is 89, rather than the result of repeatedly supplying the unchanged external input or recreating the component at every iteration. The component retains its final state for later wrapper calls.
The pipe object interface supports command-query separation: consuming an input changes state, while querying the result observes the current output without feeding another input. A client can inspect the result repeatedly, including an initial result when the concrete pipe defines one. That is useful for accumulated statistics.
The channel object interface instead packages an input update and its associated output into one call. For request-and-result processing this is simpler: the caller cannot forget which update precedes a query. A pipe caller must respect the intended order of operations, and interleaving other callers between consume and result can change the observation. A single channel object method is not automatically thread-safe either; synchronization is a separate property.
Neither object interface is universally better. The choice depends on whether clients need independent observation of state or a combined transformation step. The adapters below can reconcile their protocols, provided the initial-result policy is made explicit.
Use the adapter pattern, keeping the existing component software object in both directions:
class PipeAsChannel(pipe: Pipe) extends Channel {
  override def apply(n: Int): Int = {
    pipe.consume(n)
    pipe.result
  }
}

class ChannelAsPipe(channel: Channel, initialResult: Int) extends Pipe {
  private var last = initialResult
  override def consume(n: Int): Unit = {
    last = channel(n)
  }
  override def result: Int = last
}
The first adapter feeds the input before reading the pipe's output. The second invokes the channel exactly once per consume and caches its returned output; subsequent result queries do not advance it. Its initial result must be supplied explicitly, because a general channel object interface exposes no initial-output query. Calling the channel on a dummy input during construction would mutate arbitrary state and would invent behavior the object interface does not promise.
These adapters preserve the sequential update/output behavior after each real input, assuming no interfering access to the wrapped component. They do not claim a perfect inverse for every aspect of the original object interfaces: pipe initialization is additional observable state, whereas a channel alone does not specify that observation.
Garbage collection automatically reclaims allocated memory that is no longer reachable by the running program. Garbage collection roots such as active references and static storage lead through object-reference fields to reachable software objects in heap memory. A tracing garbage collection implementation preserves reachable software objects and can reclaim unreachable ones, including unreachable cycles.
An software object becoming unreachable is different from its state being old or its last object method call having finished. A retained reference can keep it live indefinitely. Collection timing is an implementation matter; automatic reclamation does not promise that an software object is reclaimed immediately when the final useful reference disappears.
Constructing channel implementations, decorators and adapters allocates software objects that hold state and references to other software objects. As configurations and temporary processing chains are replaced, some old software objects become unreachable. A typical Scala program on a managed runtime relies on garbage collection to recycle that storage; otherwise unreclaimed allocation can exhaust the available heap memory.
A reachable wrapper keeps its wrapped component reachable. Sharing a channel among several wrappers can extend its lifetime until all relevant references disappear. Many software objects alone do not imply that collection can free them: if the program deliberately retains every channel, those software objects remain live. The reason garbage collection is useful is repeated allocation combined with changing reachability, not an assumption that the integer-returning
apply operation allocates a fresh channel on every call. Articles by others on the same topic
There are currently no matching articles.