Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Virtual address
Address translation Created 2026-10-13 Updated 2026-10-14
Converting a virtual address to a physical address using the current address space's mapping, with access checks. In paging, the memory page number changes while the offset within it stays fixed.
Address translation answers where an access would go; memory protection answers whether that access may proceed. Neither answer is the stored value. Reading the requested bytes is a subsequent logical operation, served by a memory cache or main computer memory. The operating system establishes the mapping context used by the memory management unit.[ref]
Mechanism: Address Translation. Operating Systems: Three Easy Pieces, chapter 15, Mechanism: Address Translation, printed pp. 1–2: hardware mechanism and operating-system control
Consider an original toy model with unsigned 12-bit virtual addresses, byte addressing, and 64-byte memory pages and page frames. Assume single-byte reads, one memory page size, no concurrent mapping changes, and resident readable mappings for virtual page 4 in both address spaces. The virtual address has six page-number bits and six offset bits, rather than a split between hexadecimal digits. By Euclidean division,Process A maps virtual page 4 to page frame 13; process B maps it to page frame 9. Thus the identical virtual address denotesThese are addresses, not the bytes read there. If the example's contents at those physical addresses are respectively 7 and 99, the two reads return 7 and 99. The mapping calculation alone cannot determine either value.
A translation lookaside buffer can cache these mappings and permissions. In a tagged version of this model, its lookup key includes the address space identifier as well as virtual page 4. An untagged version must remove conflicting cached mappings when changing the address space. Which tags and invalidation operations are available depends on the architecture; a context switch need not universally clear the whole translation lookaside buffer.[ref]
Paging: Faster Translations (TLBs). Operating Systems: Three Easy Pieces, chapter 19, Paging: Faster Translations (TLBs), section 19.5, printed pp. 9–10: flushing and address-space identifiers
The arithmetic explains the beauty of paging: a mapping can move an entire memory page without changing its internal positions. Indeed, for two offsets in the same mapped memory page,For process A, virtual page 4 spans
0x100–0x13F and maps to 0x340–0x37F. Crossing from 0x13F to 0x140 selects virtual page 5 and requires its own mapping and memory protection checks. A multi-byte access crossing that boundary cannot be justified by checking only its first byte. Backing file 2026-10-14
The file supplying a memory-mapped file's initial contents. Its logical file offsets identify data independently of the virtual addresses chosen by different operating-system processes. Modified private file mapping contents have private storage; they are not updates waiting to be written to the backing file.
Copy-on-write 2026-10-13
Copy-on-write defers copying until a modification needs private storage. With paging, separate address spaces can map their memory pages to the same page frames, using memory protection to prevent writes to the common contents. Reads need no copy. A permitted write to a shared page frame first separates the writer's storage, so the other operating-system process keeps the old contents. Sharing is safe because the common contents remain unchanged while shared; the logical private copies can still evolve independently.[ref]
Complete Virtual Memory Systems. pp. 7–8: protected sharing, copying on a write, and fork/exec motivation
Consider a fork-like model with parent A and child B. Each has a separate page table, with three inherited private, logically writable memory pages. Both initially map virtual page numbers
0x12, 0x13, 0x14 to page frames F0, F1, F2. The page table entries temporarily deny writes for copy-on-write; a read of x at offset 0x34 in virtual page 0x12 returns 7 in either address space. Separate page tables do not imply separate stored bytes.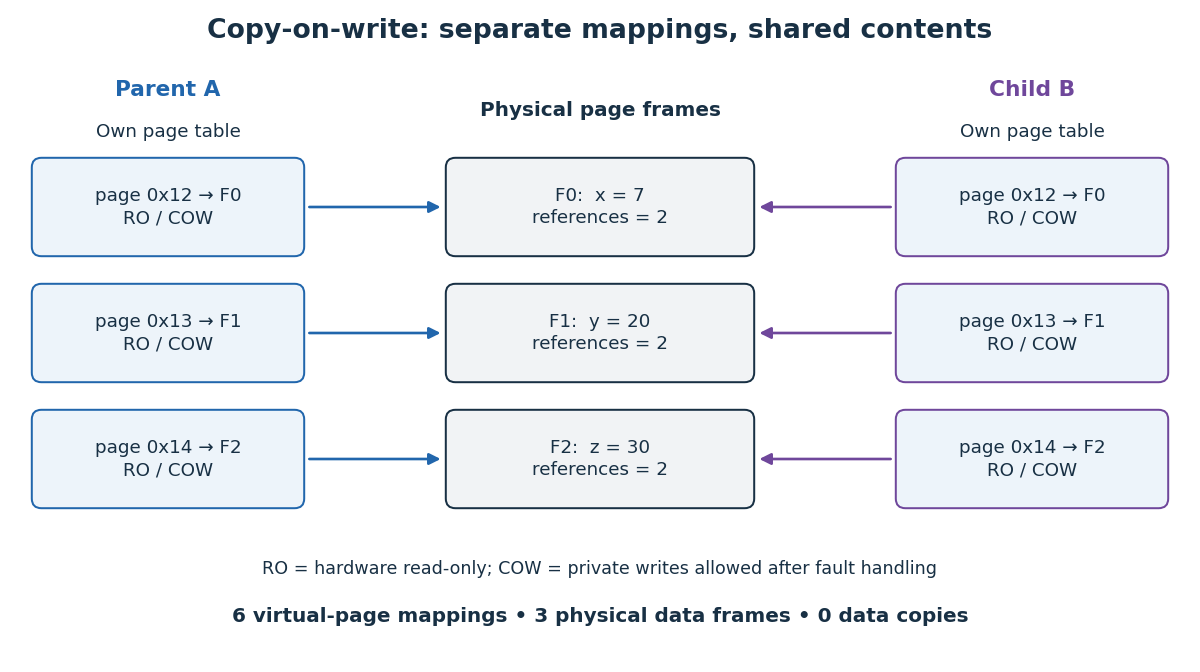
Now B writes
x = 42. In this model, copy-on-write fault handling allocates F3, copies all of F0's contents into F3, redirects only B's page table entry, enables its write, and retries the store. A still reads 7 through F0; B reads 42 through F3 at the same virtual address. F1 and F2 remain shared. The reference counting labels count mappings in this example: F0 drops from two to one, while F3 starts at one. Updating one byte can therefore copy a whole memory page.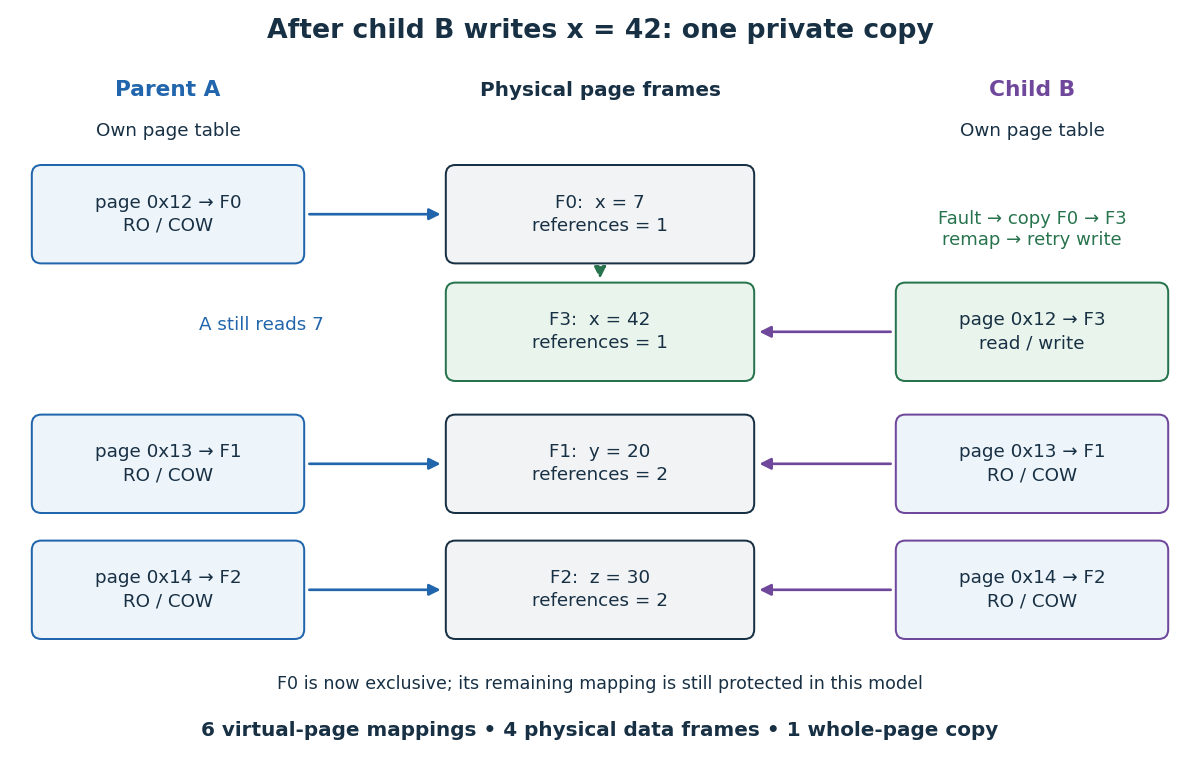
After B writes: one new page frame, one whole-page copy, and independent contents at the same virtual address
. Details. The attraction is avoiding work that may never be needed. If B only reads, this model makes no data copies; if B replaces its program and discards these mappings, copying them beforehand would have been wasted. Copy-on-write trades eager copying for protected sharing and later page faults. The page tables, reference counting, and operating-system process records still cost time and computer memory.[ref]
Complete Virtual Memory Systems. pp. 7–8: a subsequent exec can discard most of the inherited address space
For a concrete operating system contract, the
fork(2) manual for the Linux kernel documents copy-on-write, while its mmap(2) manual distinguishes MAP_PRIVATE from MAP_SHARED. Writes through MAP_PRIVATE are not propagated to other mappings or the underlying file; writes through MAP_SHARED are visible to other operating-system processes mapping that region. An inherited shared mapping therefore retains shared-write behavior. For a private memory-mapped file, visibility of later changes to the underlying file is unspecified: private writes alone do not guarantee a frozen snapshot of the file. [ref][ref]Nor does fork make every resource independent. With the Linux kernel, inherited file descriptors refer to the same open file descriptions, including shared file positions. Special mapping policies can omit a region from inheritance or zero it in the child. Thus the diagrams describe ordinary inherited private memory pages, not every resource reachable by a parent. [ref]
Direct memory access 2026-10-13
Direct memory access transfers data between a device and computer memory without the CPU executing a copy instruction for each item. The CPU still sets up the operation and observes completion. DMA answers who moves the data; an interrupt answers how a need for attention is announced. A DMA transfer can therefore finish with interrupt-driven input-output or with polled input-output. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/file-devices.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 36, section 36.5: DMA
For a toy receive operation, the CPU arranges a four-byte DMA buffer and tells the device its DMA address, length and direction. The device writes the bytes
A, B, C, D into that DMA buffer. After completion and any required DMA buffer synchronization, the CPU can read those four bytes. There are four payload bytes, but no four-item CPU copy loop on the device-to-computer memory path. This is a schematic example, not an instruction to operate real hardware.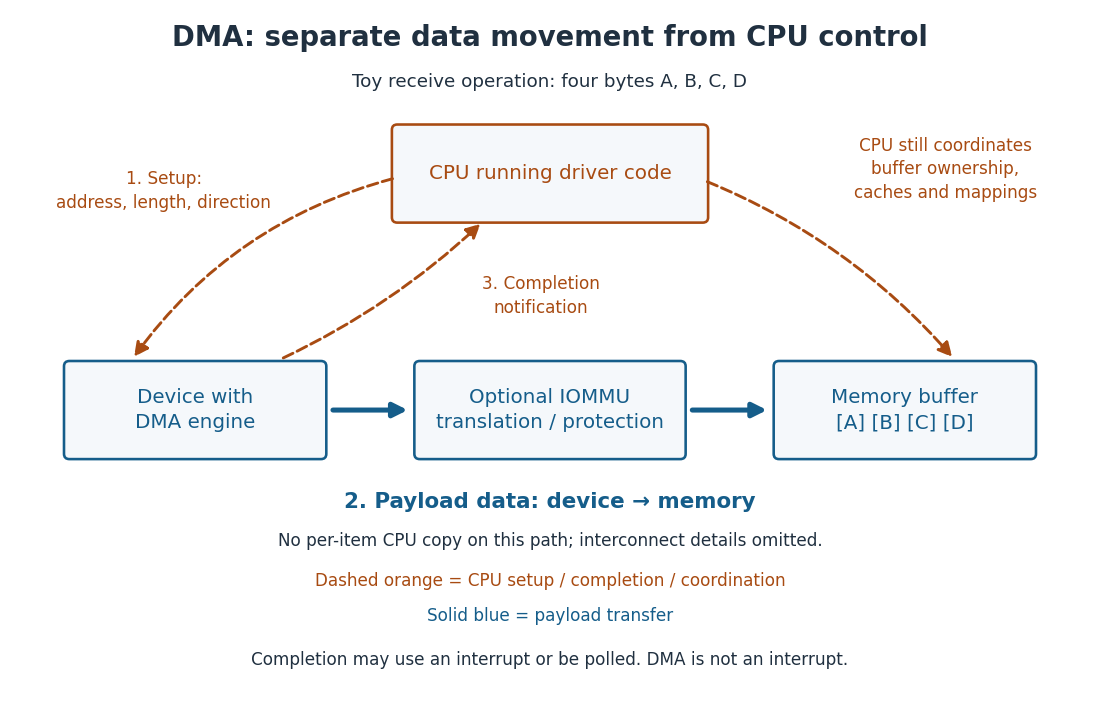
The useful separation is that the CPU can perform other work while a larger transfer proceeds. The reasoning is a division of responsibilities: setup specifies the destination and extent once; the transfer engine advances through the payload; completion reports the result. The data still crosses an interconnect such as a computer bus, which must share access among competing initiators. Setup, mapping, synchronization and completion cost work, so DMA does not promise a speedup for every transfer size. [ref]
https://docs.kernel.org/core-api/dma-api.html. James E. J. Bottomley, Linux DMA API, parts Ic–Id: mapping costs, addressing constraints and transfer directions
Correctness also requires keeping the DMA buffer alive and coordinating its ownership until the device is finished. A DMA address need not equal a CPU virtual address or physical address. An IOMMU, when present and configured, translates device addresses and can restrict access to authorized computer memory; it is not the CPU's memory management unit. Operating-system process isolation through virtual memory alone does not establish those device-access restrictions. [ref]
https://docs.kernel.org/core-api/dma-api-howto.html. Linux kernel documentation, Dynamic DMA mapping Guide: CPU and DMA addresses
[ref]https://docs.kernel.org/driver-api/vfio.html. Linux kernel documentation, VFIO: IOMMU protection and device isolation
DMA address 2026-10-13
An address supplied to a device for DMA, in the device's address system. The Linux kernel's mapping interface returns this separately from the CPU's virtual address; an IOMMU can translate it to a physical address. [ref]
https://docs.kernel.org/core-api/dma-api-howto.html. Linux kernel documentation, Dynamic DMA mapping Guide: CPU and DMA addresses
Memory-mapped file offset translation 2026-10-14
Let be the memory page size, the aligned starting file offset, the mapping length and its base virtual address. A valid displacement with corresponds to file offsetHere is the relative memory page index, the floor function selects its integer part, and Euclidean division gives the within-page displacement . The backing page begins at . This identifies file contents; the page table separately selects a resident page frame and enforces permissions.
Take , and bytes in a file of at least 12288 bytes. A has a shared file mapping at . B has a shared file mapping at and a private file mapping at . These bases are illustrative chosen results, not requested fixed addresses. All three mappings cover the same two backing pages: file offsets 4096–8191 and 8192–12287. Displacement selects relative page 1, within-page displacement 37 and file offset . Thus A's
0x10001025, B's shared 0x20001025 and B's private 0x30001025 initially identify the same byte. The adjacent displacement 4134 identifies file offset 8230. Different virtual addresses can reach the same backing contents.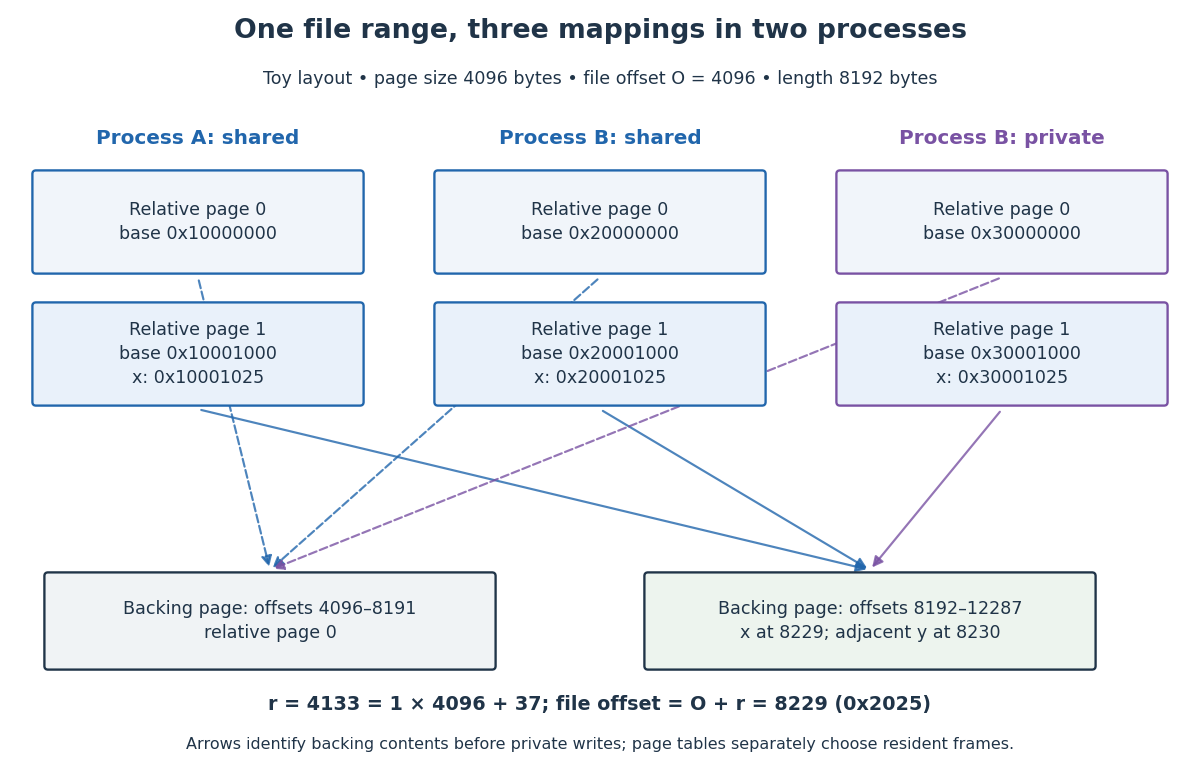
Two operating-system processes map two backing pages at different virtual addresses; displacement 4133 identifies file offset 8229
. Details. To access a requested file offset that is not aligned, choose and displacement . Mapping enough bytes to cover that displacement plus the requested length makes the desired data start inside the aligned mapping. Do not pass the unaligned directly as the Linux kernel
mmap offset. For example, uses and displacement 37; that one-page start differs from our two-page mapping's . Memory page 2026-10-14
A contiguous unit of an address space used for paging. In the example, virtual page
0x12 consists of virtual addresses 0x1200 through 0x12ff. Microkernel file-read example 2026-10-14
Consider an original toy file system service in address space B and a client in address space A, on one CPU. The service holds a five-byte cached file containing
LIME followed by a newline. The client already has service handle 9, permission to read that file, and a security capability to send requests to IPC endpoint E. Handle 9 is interpreted by the service; it is neither a virtual address nor an operating-system kernel object identifier. All relevant memory pages are resident, and this read needs no device driver.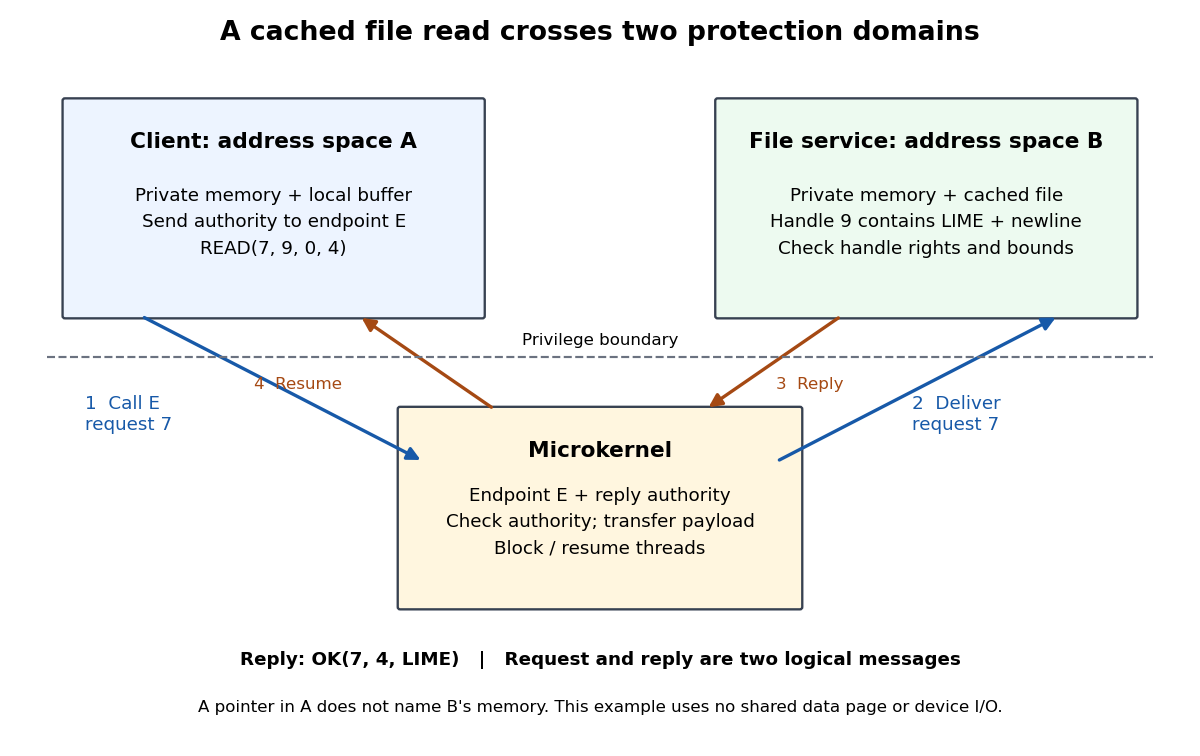
A cached file read uses IPC between separate address spaces, with authority checked by the microkernel
. Details. - The client submits
READ(7, 9, 0, 4): request identifier7, handle9, byte offset0, and requested length4. A system call enters the microkernel; the security capability is checked before delivery on IPC endpoint E. The client waits for a reply. - A waiting service software thread receives the request. The service checks the handle's read permission and the requested range, then obtains the first four bytes from its cached file. The microkernel transports the request; the service supplies its file system meaning.
- The service uses reply capability authority to return
OK(7, 4, LIME). The client resumes, checks the request identifier and returned length, and copies those four bytes into its own local buffer. There were two logical IPC messages: request and reply. The four arrows show delivery stages, not four separate requests.
This protocol is an illustrative design, not an actual seL4 file system interface. Its call/reply structure follows seL4's documented IPC:
seL4_Call waits using reply authority, and small payloads can travel in processor registers. [ref]An ordinary pointer in A refers to A's address space. Sending its numeric value does not make B's private computer memory appear there. This example explicitly transfers bytes. Sharing a mapped memory page instead would require intentional memory protection permissions and a protocol for ownership and synchronization; passing a pointer alone establishes neither.
The same IPC mechanism could carry
WRITE, but this client could still be refused by the service's read-only handle policy. Conversely, possession of an IPC endpoint security capability permits communication without automatically granting access to every file the service manages. The separation of mechanism and policy appears twice: endpoint authority gates delivery, and the service's handle policy gates the requested operation. Operating system Created 2026-10-13 Updated 2026-10-14
An operating system manages the resources that let programs run and cooperate. Operating-system processes organize running work, virtual memory supplies protected address spaces, and a file system supplies named files that can outlive the operating-system process that created them. The operating-system kernel enforces the core mechanisms; system calls let programs request its services. Separating these responsibilities makes it possible to share a file while keeping the participating operating-system processes' address spaces isolated. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/file-intro.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 39, introduction: processes, address spaces and persistent storage
A concrete example makes the separation useful: two operating-system processes can each use file descriptor
3, yet refer to different files; two different names can instead refer to the same file through hard links. Neither a name nor a small integer identifies an object without its context. Virtual memory has a related distinction: the same virtual address in different address spaces can designate different physical addresses.Unix provides an influential example of this design. In their July 1974 paper, Dennis M. Ritchie and Ken Thompson date its earliest version to approximately 1969–70 and describe operating-system processes, a hierarchical file system, and inodes separating directory entries from file metadata. This is a documented historical example, rather than a claim that every operating system uses Unix conventions. [ref]
Page fault Created 2026-10-14 Updated 2026-10-14
A page fault transfers control to the operating system when an access cannot proceed under the current paging translation or protection rules. The term includes both unavailable translations and forbidden accesses on x86. Intel's manual distinguishes these causes; AMD's error code likewise distinguishes ordinary not-present faults from protection violations. Other architectural causes, including malformed page table entries, also exist. [ref]
https://cdrdv2-public.intel.com/671200/325462-sdm-vol-1-2abcd-3abcd.pdf. Intel SDM, volume 3A, section 4.7: Page-Fault Exceptions
[ref]https://docs.amd.com/api/khub/documents/sD1_QL~h4Afq2_tvzxqqSQ/content. AMD64 Architecture Programmer's Manual, volume 2, revision 3.44, section 8.4.2: Page-Fault Error Code
The illustrative page table in paging separates three situations:
- A read at virtual address
0x1434targets a permitted but nonresident memory page. The operating system may supply it and retry the access. - A write at virtual address
0x1234targets a resident, read-only memory page. The page fault is caused by missing write permission, not by missing contents. - A read at virtual address
0x1534targets an unmapped part of the address space. The operating system must reject it unless its policy authorizes creating a mapping.
A page fault is not necessarily a program error or a storage-device read. Demand paging can allocate a zero-filled page frame without reading secondary storage. A copy-on-write write deliberately encounters read-only permissions; the operating system supplies a private copy and enables the write. A truly forbidden access may instead terminate the operating-system process. The handler interprets the fault using both architectural fault information and its own mapping policy. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/vm-complete.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 23: demand zeroing and copy-on-write
For a nonresident memory page whose contents must be loaded, the handler obtains a page frame, possibly invokes page replacement, supplies the contents, updates the page table, arranges any necessary translation lookaside buffer invalidation, and resumes the operation. If no mapping or permission can legally be supplied, it reports failure. This mechanism lets ordinary accesses request work only when it becomes necessary. [ref]
Beyond Physical Memory: Mechanisms. Operating Systems: Three Easy Pieces by Remzi H. Arpaci-Dusseau and others; Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 21: Beyond Physical Memory, Mechanisms, sections 21.3–21.5
// Target: computer-science.bigb
Paging 2026-10-13
Paging divides an address space into fixed-size memory pages and main computer memory into equally sized page frames. Here assume byte addressing, one memory page size bytes, and an unsigned virtual address . Its virtual page number and offset areThe brackets denote the floor function, and gives the remainder in Euclidean division. If the page table maps to physical frame number and permits the access, the physical address isThe low bits are unchanged; the other bits select the memory page or page frame. A bit shift and bit mask can extract these fields. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/vm-paging.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 18: Paging, Introduction, sections 18.1–18.2
For a 16-bit virtual address and bytes, take in hexadecimal. Then and . A mapping to givesThus the eight high bits choose a mapping; the eight low bits choose the same position in the resulting page frame. The 256-byte size is for illustration, not a claim about an actual architecture's supported memory page sizes.
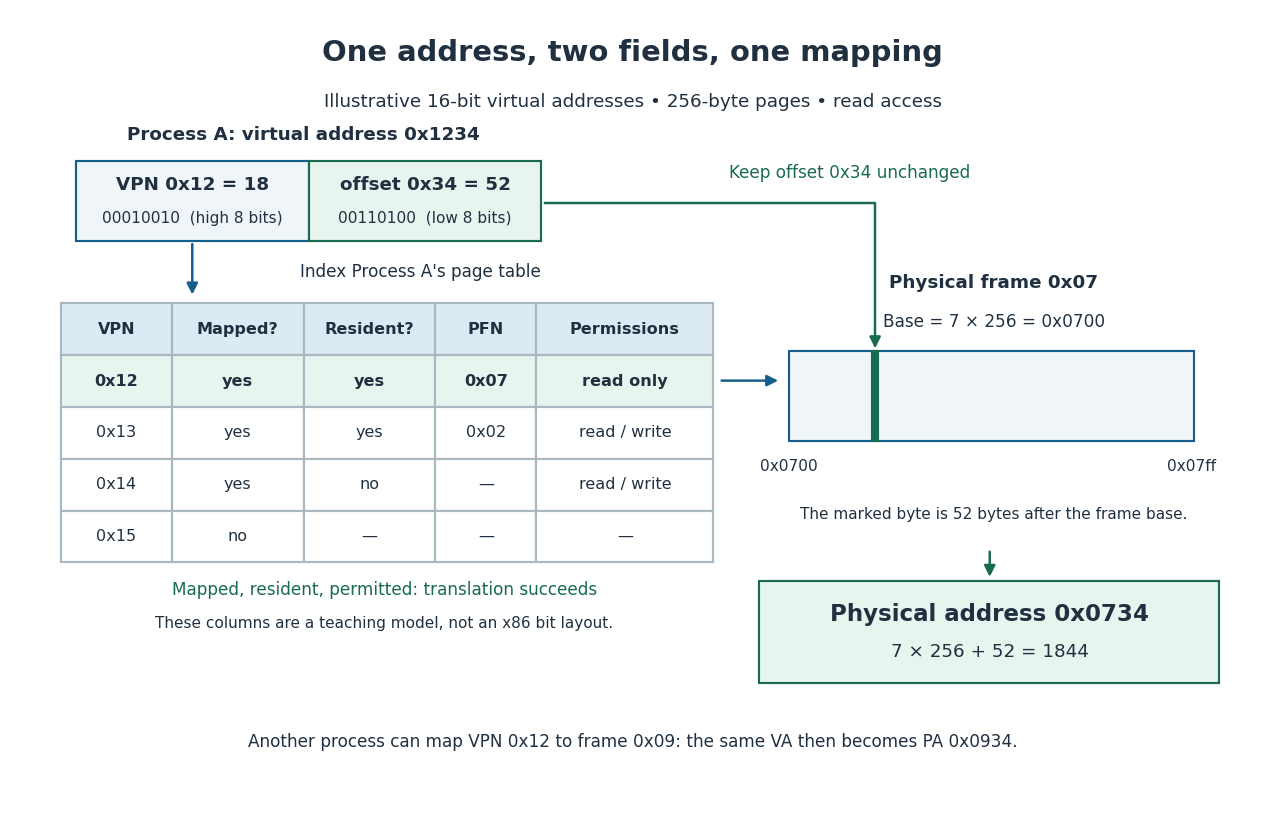
Translating 0x1234 through an illustrative page table, with a separate offset and access check
. Details. The useful freedom is that adjacent memory pages can occupy unrelated page frames. In the diagram, virtual pages
0x12 and 0x13 occupy page frames 0x07 and 0x02; virtual addresses 0x12ff and 0x1300 are consecutive, but translate to physical addresses 0x07ff and 0x0200. Uniform units simplify placement and page replacement, at the cost of page table storage and unused bytes within partly filled memory pages. For example, placing 300 bytes in exclusive 256-byte page frames requires two page frames, leaving bytes unused. Physical address 2026-10-13
An address in the physical address system, obtained from a virtual address by address translation in the examples here. Physical address ranges can also identify devices, so not every physical address denotes ordinary computer memory.
Process (computing) 2026-10-13
An operating-system process is an execution instance of a program, with an address space, one or more software threads carrying execution contexts, and operating system resources such as file descriptors. A program describes instructions; an executable file stores a form that can be loaded for execution. Starting the same executable twice can create two operating-system processes, each with its own evolving state. A operating-system process can be waiting for input-output or waiting for a turn on the CPU, rather than executing at every instant. [ref]
For example, start the same counter program as operating-system processes A and B. In this toy mapping, both use virtual address
0x1234 for a counter x, but A reads x = 7 while B reads x = 42. The number 0x1234 is interpreted through the current address space, so it need not denote the same contents in both operating-system processes. Writing A's ordinary private counter does not change B's counter. Compare virtual memory for an explicit mapping to different physical addresses.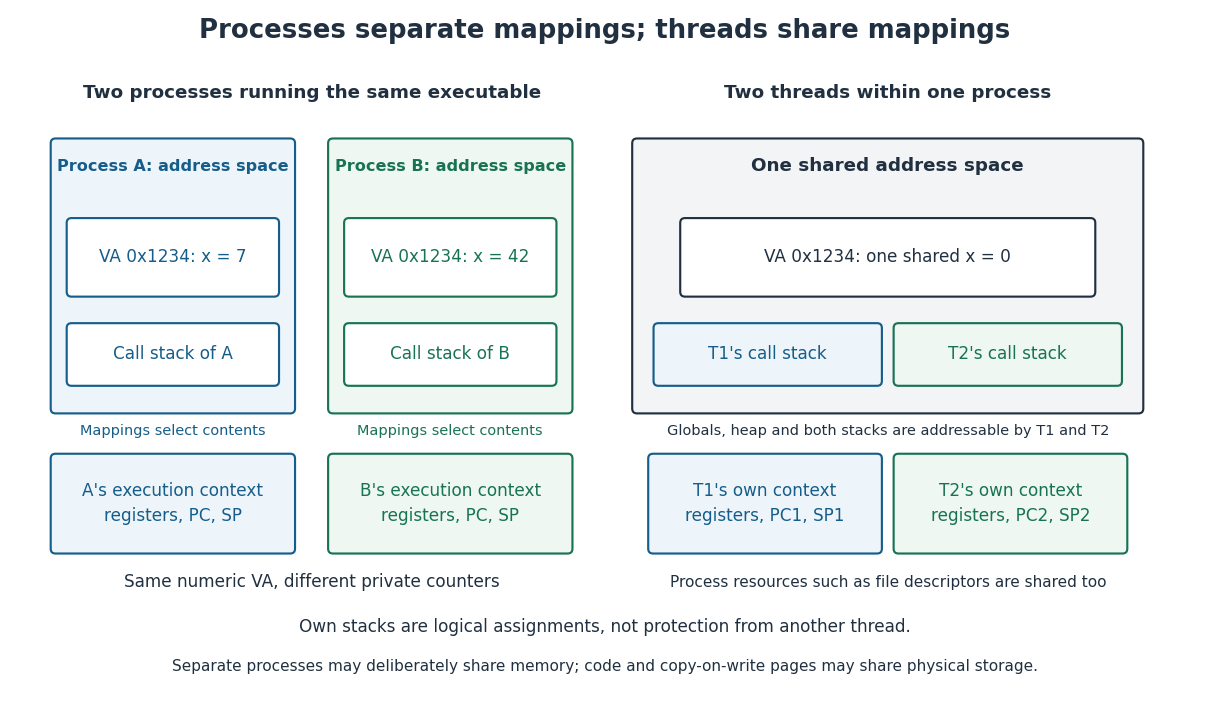
Separate operating-system processes can interpret the same virtual address differently; software threads in one process share an address space
. Details. Separate virtual memory address spaces provide a usual default isolation boundary, not a claim that all computer memory is universally private. Deliberately shared mappings let operating-system processes communicate through the same stored data. Even logically private contents need not occupy distinct page frames at every moment: read-only program code can be shared, and copy-on-write can keep a common memory page until a write requires a private copy. The distinction is between which accesses and changes are permitted and which physical storage is currently reused. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/vm-complete.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 23, section 23.1, Other Neat Tricks: copy-on-write and shared mappings
[ref]https://pubs.opengroup.org/onlinepubs/009695099/functions/shm_open.html. The Open Group, POSIX shared-memory object interface, shm_open: multiple processes can refer to the same shared memory object
This abstraction lets independent activities reuse the same executable while keeping their changing state separate. Process scheduling distributes CPU time; virtual memory interprets and protects addresses; file descriptors connect an execution to open resources. The useful design is controlled independence with explicit ways to share. Creating operating-system processes, maintaining their mappings and performing context switches require time and computer memory; isolation alone gives no universal performance guarantee.
Protection domain 2026-10-13
A boundary within which code exercises a particular set of permissions. An address space describes accessible virtual addresses; a protection domain also concerns authority over other objects, such as software threads and IPC endpoints. Two address spaces may deliberately share a writable memory page, so separation of address spaces alone does not make their contents independent.
Sv39 page table 2026-10-14
The actual Sv39 page table geometry uses three nine-bit indices and a twelve-bit offset for base 4096-byte memory pages. Each table contains 512 eight-byte page table entries, exactly one 4096-byte memory page; the
satp processor register identifies the root. A 64-bit virtual address must repeat bit 38 in bits 63 through 39. Higher-level terminal entries can also map aligned larger memory pages, shortening the page table walk. These rules differ from the 16-bit, four-byte-entry two-level address translation model. [ref]For ordinary Sv39 page tables, valid nonterminal page table entries reference the next table with read, write, and execute flags clear; those clear flags do not prohibit reading the eventual data. The terminal entry supplies access permissions, with additional processor privilege level and status checks. An invalid entry, malformed encoding, or denied access can cause a page fault. Thus the model's set intersection of read/write permissions at both levels must not be applied mechanically to Sv39 page tables. [ref]
In xv6 RISC-V source code, root allocation is separate from lower-level allocation:
uvmcreate() allocates and clears a root page table, while walk() with allocation enabled allocates and clears missing lower-level tables and installs valid references to them. With allocation disabled, a missing table makes walk() return failure. This software routine finds a page table entry for the operating system; it is not the hardware's complete permission-checking page table walk. [ref] Thread (computing) 2026-10-13
A software thread is an execution stream within a operating-system process. Each software thread has its own execution context, including processor registers, an instruction pointer, and a call stack selected by its stack pointer. Software threads in the same operating-system process share its address space, global variables, dynamically allocated storage (the memory heap), and resources such as file descriptors. Separate register states let two software threads pause at different instructions and later resume correctly. A context switch saves and restores those states; it does not copy the entire shared address space. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/threads-intro.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 26, introduction and figure 26.1: thread contexts and shared address space
[ref]https://pubs.opengroup.org/onlinepubs/9799919799/basedefs/V1_chap03.html#tag_03_189. The Open Group, POSIX.1-2024, sections 3.189–3.190: Live Process and Live Thread, shared resources and addressable storage
In the right half of the diagram under operating-system process, T1 and T2 access the same counter
x at virtual address 0x1234. Their call stacks occupy separate regions of the same address space, and their saved processor registers can contain different values. A software thread's own call stack means the stack used for its calls, not a hardware protection boundary against another software thread. Another software thread with a suitable address can access that stack's live data, subject to the program's lifetime and synchronization rules. Sharing an address space enables easy communication and makes accidental interference possible.Concurrency means that several activities can make progress over overlapping intervals; parallel execution means that several activities execute at the same instant. On one CPU execution slot, process scheduling can interleave software threads without simultaneous execution. Multiple processor cores can run eligible software threads in parallel, but merely creating software threads does not ensure parallel execution or a speedup.
Consider an explicitly abstract interleaving model: shared
x starts at , and each of T1 and T2 performs three indivisible logical steps in its own order: load x into its own register r, add to r, then store r into x. Each load sees the latest preceding store in the displayed order. These model assumptions specify the example; they do not describe every programming language or every hardware memory model. In serial order T1 finishes all three steps before T2 starts, so T2 loads and stores .An overlapping order instead gives T1 load , T2 load , T1 add to get
r1 = 1, T2 add to get r2 = 1, T1 store , and T2 store . The load/store subsequence is therefore T1 load , T2 load , T1 store , T2 store : final , although each software thread incremented its register correctly. The second store replaces the first with the same value, losing one intended update. This race condition is possible even with interleaving on a single CPU.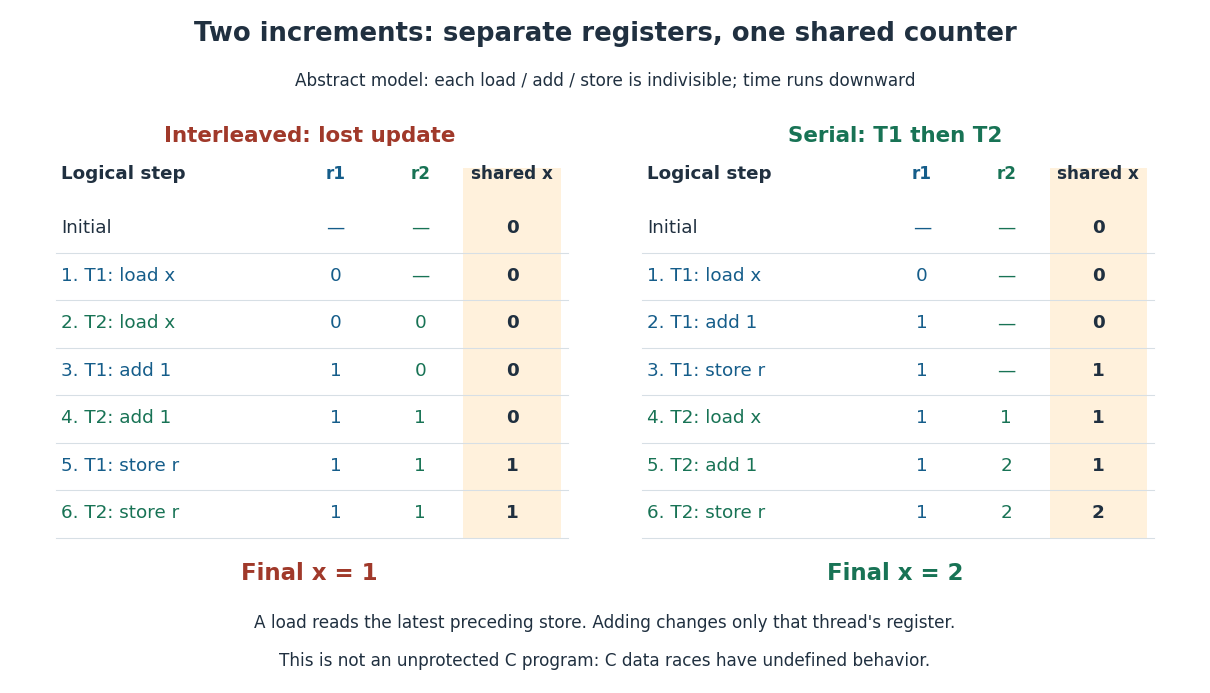
Two abstract load/add/store increments retain separate registers but can leave the shared counter at instead of the serial result
. Details. This is not an unprotected C implementation example. Conflicting unsynchronized accesses to an ordinary non-atomic C object from different software threads can constitute a data race, which has undefined behavior; the abstract trace is not a prediction of that program's allowed outcomes. [ref]
The repair explains why synchronization matters: mutual exclusion around the whole load/add/store sequence prevents the other software thread from starting an increment halfway through it. Alternatively, an appropriate atomic operation can make the complete increment one indivisible read-modify-write. In the toy model, either repair makes the two increments take effect in an order, producing . Making only each load and each store an atomic operation still permits the displayed lost update. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/threads-locks.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 28, sections 28.1–28.2 and 28.11: locks around updates and atomic fetch-and-add
The attraction is independently progressing activities with direct access to shared data: a user-interface software thread can handle input while another waits for input-output, and workers can divide independent pieces of a large calculation among available cores. The first benefit can exist on one CPU; the second requires suitable work and execution resources. Context switches, synchronization, register-state records and extra call stacks consume time or computer memory, so the useful partition depends on the workload. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/threads-intro.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 26, section 26.1: parallel work and overlapping input-output with other activity
Translation lookaside buffer Created 2026-10-14 Updated 2026-10-14
A translation lookaside buffer is a small hardware memory cache of virtual address to physical address mappings and their access attributes. A TLB hit finds a usable cached mapping for the current address space; access permissions still apply. A TLB miss means that mapping is absent from the translation lookaside buffer. It says nothing by itself about whether the memory page is resident. Evicting a translation lookaside buffer entry removes a cached translation, not the memory page's contents. [ref]
https://docs.amd.com/api/khub/documents/sD1_QL~h4Afq2_tvzxqqSQ/content. AMD64 Architecture Programmer's Manual, volume 2, revision 3.44, section 5.5: Translation-Lookaside Buffer
For the 256-byte example, a cached virtual page
0x12 to physical frame 0x07 mapping covers every offset from 0x00 to 0xff. Reads at virtual addresses 0x1234 and 0x1235 can reuse it to reach physical addresses 0x0734 and 0x0735. If the translation lookaside buffer is initially empty, the first read instead requires a page table walk; with a resident, readable mapping, it completes without a page fault. A write can fault even on a TLB hit because cached permissions deny it.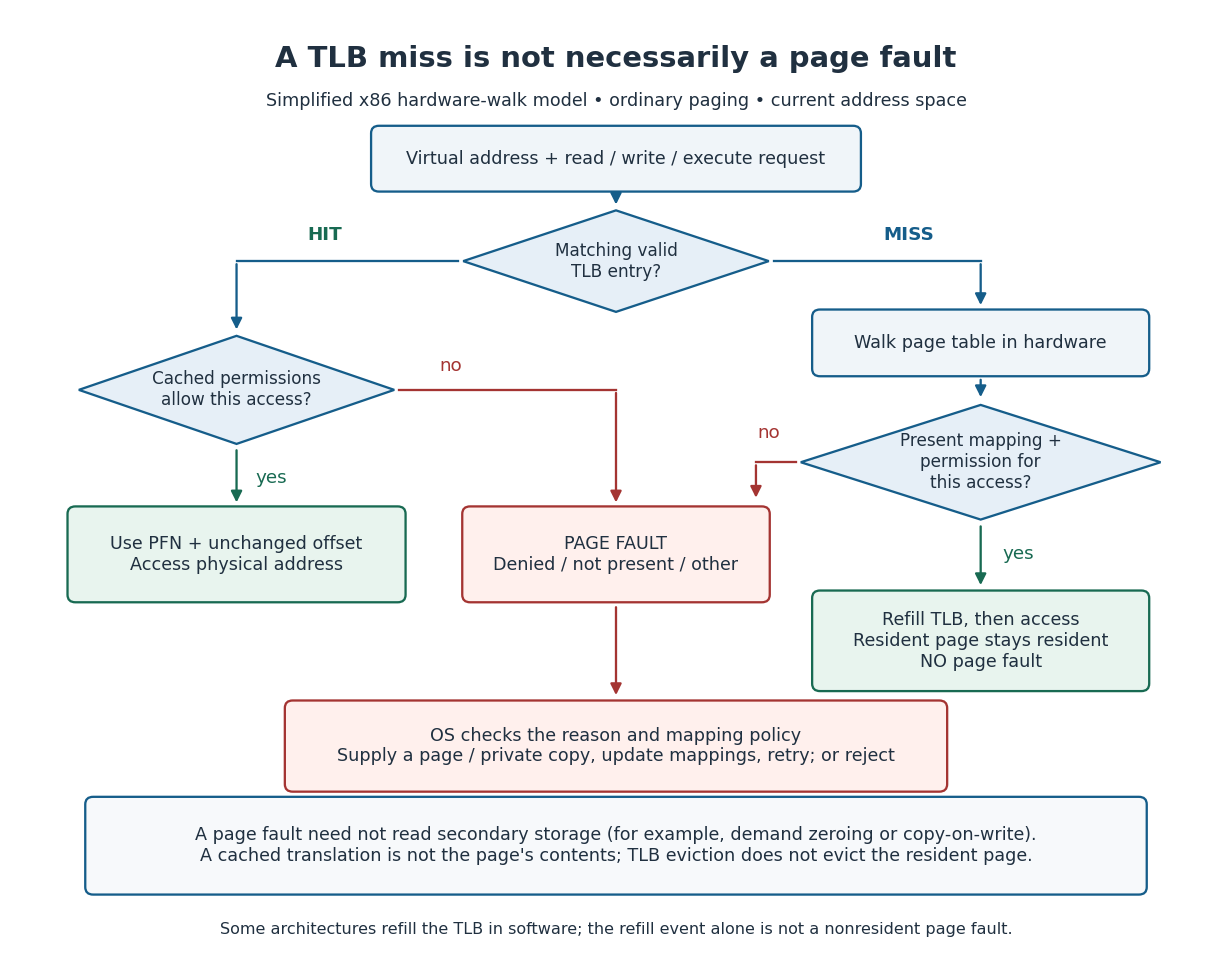
A TLB miss can refill a resident translation without a page fault; permission failures can fault on a TLB hit
. Details. The diagrams show an ordinary x86 model with hardware page table walks. Some architectures use an operating system handler to refill the translation lookaside buffer after a TLB miss; that refill event alone is not a nonresident page fault. Temporal locality helps a small translation lookaside buffer serve repeated accesses, and one entry can cover many bytes. [ref]
Paging: Faster Translations (TLBs). Operating Systems: Three Easy Pieces by Remzi H. Arpaci-Dusseau and others; Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 19: Paging, Faster Translations, sections 19.1 and 19.3
A context switch does not universally flush the whole translation lookaside buffer. An address space identifier can distinguish translations with the same virtual page number in different address spaces; Intel's PCIDs support retaining translations across appropriate switches. The operating system must still invalidate stale translations when mappings or permissions change, following the architecture's rules, including coordination with other processors that could use them. [ref]
Two-level address translation 2026-10-14
Choose an original teaching model with 16-bit virtual addresses, 16-bit physical addresses, and 256-byte memory pages and page frames. The eight high bits identify a virtual memory page; divide these into two four-bit indices. The eight low bits are the offset within the memory page. Thus each page table has 16 entries: the root selects a lower-level page table, and that table selects a data page frame. Every page table entry is four bytes, including its reference and flags. These are chosen model parameters, not a hardware entry encoding.
For a virtual address , extract the root index , lower-level index , and offset by Euclidean division:Here is the floor function and denotes the remainder in Euclidean division. Each index ranges from 0 to 15, and ranges from 0 to 255. In hexadecimal, virtual address
0x1234 splits into , , and ; its binary numeral system representation is 0001 | 0010 | 00110100.Fix the requested operation to be a one-byte user read. Assume both table nodes and the data page frame are resident, table reads are allowed, and no mapping changes during the page table walk. The model requires presence at both levels and takes the set intersection of the two entries' read, write, execute, and user-access permissions. This is an explicit memory protection rule for this model; Sv39 page tables use different rules. The root's physical address is
0x8000; the relevant entries are:| Record | Physical address of record | Reference held in the page table entry | Presence and permissions |
|---|---|---|---|
| Root entry 1 | 0x8000 + 1*4 = 0x8004 | Lower-level table at 0x9000 | Present; user; read/write; no execute |
| Lower-level entry 2 | 0x9000 + 2*4 = 0x9008 | Data page frame 0x07, base 0x0700 | Present; user; read-only; no execute |
The first lookup obtains a table reference, not the final data physical address. The second lookup obtains page frame number 7. Both entries permit a user read, so the original offset is added to the data page frame base:The page table walk therefore reads records at
0x8004 and 0x9008, then the requested read accesses data at 0x0734. All three are distinct physical addresses. These are two dependent table lookups followed by one data access, not a claim of three accesses to main computer memory: a memory cache can satisfy table lookups, and cached intermediate translations can skip them.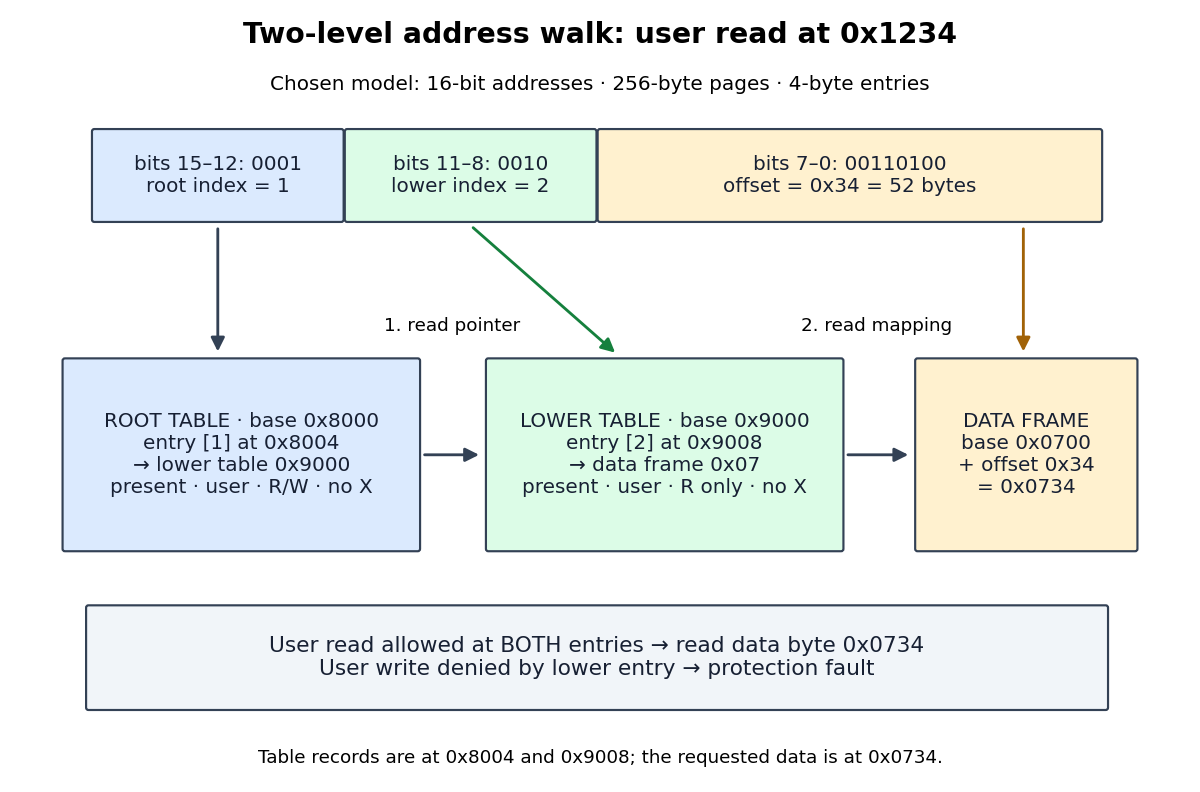


Under the same memory protection rule, a user write at
0x1234 fails because lower-level entry 2 denies writes, even though root entry 1 allows them. Clearing either entry's presence flag also prevents the access. An absent root entry stops the page table walk before any lower-level lookup. A page fault then requires the operating system to determine whether a permitted mapping needs storage or the access is invalid; absence alone does not establish demand paging eligibility.With an empty translation lookaside buffer, the permitted read causes a TLB miss and this successful page table walk, with no page fault. If the resulting mapping and permissions are cached for the current address space, a later read at
0x1235 can use a TLB hit to reach 0x0735. A later write can cause a protection page fault on a TLB hit because the cached mapping remains read-only. Assume cached permissions are current; changing them requires the architecture's prescribed invalidation. A TLB miss describes a missing cached translation, while a page fault describes an access that cannot proceed under the translation or protection rules. [ref]Page Tables by The kernel development community. MMU, TLB, and Page Faults: translation caches, page walks, and faults for missing or forbidden mappings
Virtual memory 2026-10-13
Virtual memory gives an operating-system process an address space whose virtual addresses are translated to physical addresses under operating system control. In a system using paging, each resident memory page maps to a page frame; page tables describe the mappings and access permissions, while the memory management unit enforces them. The same virtual address in two operating-system processes can refer to different page frames. A deliberate shared mapping can instead make different virtual addresses refer to the same page frame. [ref]
https://pages.cs.wisc.edu/~remzi/OSTEP/vm-intro.pdf. Arpaci-Dusseau and Arpaci-Dusseau, OSTEP chapter 13: Address Spaces
For example, with 256-byte memory pages, let process A map virtual page
0x12 to page frame 0x07, and process B map virtual page 0x12 to page frame 0x09. Their identical virtual address 0x1234 then denotes physical address 0x0734 in A and 0x0934 in B. The address acquires meaning from the current address space, not just its numerical value. See paging for the calculation.This separation makes programs easier to place in computer memory: consecutive virtual addresses need not occupy consecutive page frames. It also provides isolation and controlled sharing. Virtual memory does not require secondary storage: a system can translate and protect virtual addresses while keeping every allocated memory page resident in computer memory. Demand paging adds allocation or loading on first use, and can support an address space larger than available computer memory; the amount that can be used at once is still limited. Keeping a working set resident avoids memory thrashing.
An early concrete implementation was Manchester's Atlas. Kilburn, Edwards, Lanigan and Sumner's April 1962 paper describes automatically combining fast core storage with drum storage, transferring 512-word blocks and translating their addresses through page address registers. Its attraction was to spare programmers explicit transfers between these storage levels. This historical use of secondary storage is one application of virtual memory, rather than a requirement of every virtual memory system. The accessible text below is a reprint of the paper. [ref]
https://www.dcs.gla.ac.uk/~wpc/grcs/kilburn.pdf. Kilburn et al., One-Level Storage System, 1962, sections 1 and 3