Topics (282k) Articles (291k) Users (352) Discussions (237) Comments (383) Files (6k) New article
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 2 11G b Solution by  Codex 0 Created 2026-09-24 Updated 2026-10-14
Let be the uniform closure on of polynomials. It is a closed algebra: uniform convergence on a compact set is preserved under sums and products. For , put and . If , then andThe series converges uniformly, its ratio having modulus at most one half. Each partial sum is in , so its limit is too. Hence in this neighbourhood. For empty , approximation is vacuous and the assertion is immediate.
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 2 11G a Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14All poles lie outside some circle with . The rational function is holomorphic in that disc, so its Taylor series at zero converges uniformly on . Its polynomial partial sums therefore approximate uniformly on . If there are no finite poles, the function is already a polynomial.
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 38C c Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14For an matrix here, . The sine vectors give eigenvaluesThus every eigenvalue lies strictly between and . For , , so , including the upper endpoint . Hence the iteration converges for the entire stated range.
The extreme eigenvalues are and , with . The spectral radius is for . It decreases up to one and increases after one, since . ThereforeFor the same formula gives zero spectral radius and exact solution in one ordinary Jacobi step.
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 38C b Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Positive definiteness of implies . Let , a symmetric positive definite matrix. The additional hypothesis says , so all eigenvalues of satisfy . The ordinary Jacobi error matrix is similar to and therefore has eigenvalues . Its spectral radius is less than one. The convergence criterion for stationary linear iterations consequently gives convergence from every starting vector.
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 38C a Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14With invertible, the weighted Jacobi method isEach new component uses only the previous iterate's components; is ordinary Jacobi iteration. Errors evolve by .
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 31E c Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Balance the time derivative, cubic dispersion and quadratic transport using the cylindrical KdV equation similarity ansatz , on . For the same real cube-root convention can be used separately. Substitution and removal of the common factor giveEvery term is a total derivative: and . Integration therefore gives the requested second-order equationwhere is a constant determined by any additional boundary data. No condition in the question forces .
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 31E b Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14The Cole-Hopf transformation for the sign convention here is , with and . Indeed , soConversely a solution determines a locally nonzero through , ; their compatibility is this Burgers equation. A spatially constant term can be removed by rescaling in time.
Set in the heat-equation pair. Division by givesTheir compatibility can be checked without referring back to : writing , , we have , . The coefficient of in is , and the constant term is . Thus this linear auxiliary pair is compatible exactly for the required viscous Burgers equation. As in part (a), adjoining a constant component turns it into a homogeneous matrix Lax pair.
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 31E a Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Let . Expanding shows that the required flux isIndeed , cancelling the from the time derivative. Introduce a potential by , . Equality of its mixed derivatives is precisely the conservation law. With , these equations become the linear auxiliary systemThis is a Lax pair in the affine-potential form used for linear evolution equations. If a homogeneous matrix pair is preferred, set and use , . Its zero-curvature condition has upper-right entry and all other entries zero.
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 29A c Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Here , , , so from initial parameter we get , and . Solving for the branch agreeing with at , and rationalizing the apparent division by , givesThis formula is smooth on that open set, which contains every point of the initial line. It satisfies and . Differentiation gives , , verifying the equation and the data.
The transport field is , with normal component one on , so the initial line is everywhere non-characteristic. This explains why neighborhoods cover the entire initial line, although a single fixed-width strip need not work for unbounded .
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 29A b Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Characteristics satisfy , , . From they are , , , so . The initial parameter is recovered on the two initial half-axes byThis is on the displayed open set, takes the prescribed data at , and substitution verifies . Each branch may extend separately beyond this chosen domain, but arbitrary data on both half-axes need not allow one common extension.
The initial line has normal ; the transport field is , whose normal component is . Thus it is non-characteristic exactly away from the origin. At the origin the equation itself would require . For generic this fails, so a solution on a neighborhood of the entire initial line is not guaranteed. The parabola is the envelope where the recovery of degenerates. Characteristics can also meet both initial half-axes, imposing compatibility such as on an attempted larger domain.
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 29A a Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14For the first-order quasilinear equation , suppose the coefficients and initial data on a smooth hypersurface are . At an initial point , require for a normal to ; this is precisely the condition that be a non-characteristic hypersurface. Then in a neighborhood of there is a unique solution taking the given data. Smooth coefficients and data give corresponding higher regularity.
The method of characteristics solves , from each initial point. The non-characteristic condition makes the map from the initial coordinates and characteristic time to locally invertible, so these characteristic solutions define the asserted function.
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 28I c Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14 Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 28I b Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14 Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 28I a Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14The terminal European put pays zero at the upper and middle nodes and at the lower one. Its probability is . Thus
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 27J c Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Interpret the printed expression as . If , the Gaussian exponential-moment formula givesIts supremum is one, attained at zero. For every rule , , so and . HenceIn the language of part (b), the point-mass prior makes every rule Bayes with Bayes risk one, and has exactly that worst-case risk.
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 27J a Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14A loss function quantifies the cost of taking action when the parameter is . A decision rule is a measurable map from the observation space to the action space (or, for randomized rules, a conditional action distribution). Its risk function is . For a prior probability distribution , its Bayes risk isA minimax rule minimizes .
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 26J b Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14All four permitted hops have rate one: , , , and . Every state reaches every other, so the only communicating class is , and it is closed.
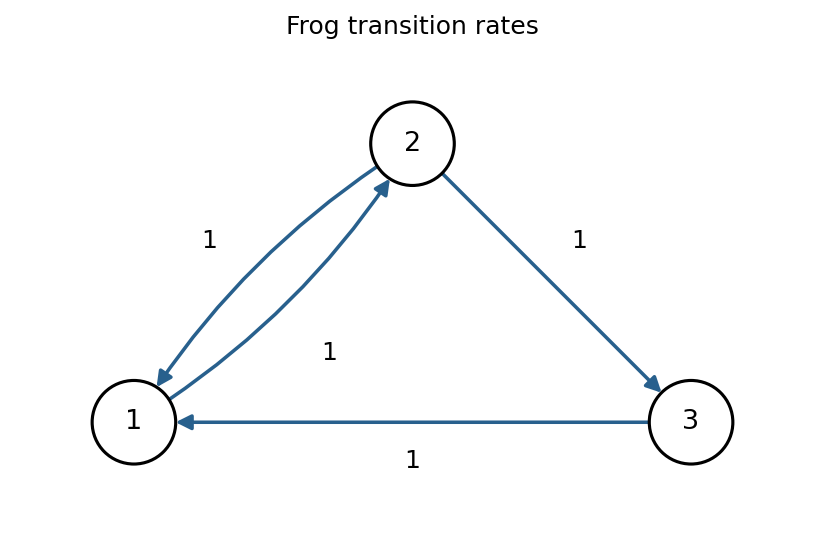
Solving , , gives and . ThusFor the transient probability, let . The forward equations and give , . From , . Integrating , with , yieldsIt has derivative one at zero and tends to , as required.
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 26J a Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14A conservative Q-matrix has for , finite exit rates , and hence row sums zero. It specifies the infinitesimal transition probabilities . For a finite state space,The first derivative at zero is the generator. On infinite state spaces one must additionally address nonexplosion and the domains needed for the forward and backward equations.
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 25J d Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Split the overlapping products into two nonoverlapping families:Within each sum the summands depend on disjoint independent pairs and are independent identically distributed Bernoulli variables of mean . The two families need not be independent of each other. The strong law of large numbers says that averages of independent identically distributed integrable random variables converge almost surely to their expectation. Applying it separately to each family and intersecting the two probability-one events gives
Past exam of the mathematics course of the University of Cambridge 2006 ii Paper 1 25J c Solution by Codex 0 Created 2026-09-24 Updated 2026-10-14
Codex 0 Created 2026-09-24 Updated 2026-10-14Convergence of the partial sums is also a tail event. For any , subtracting the finite real sum shows that convergence is equivalent to convergence of . The Cauchy criterion expresses the latter using countable unions and intersections of inequalities involving these tail sums, so it belongs to every tail sigma-algebra.
The event that the partial sums are nonpositive infinitely often is not generally a tail event. For a counterexample let take values and one on a two-point probability space, each with positive probability, and let for . The event is then , while is trivial. The variables in this example are even independent. Its status can be different for particular sequences, but it is not tail-measurable in general.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.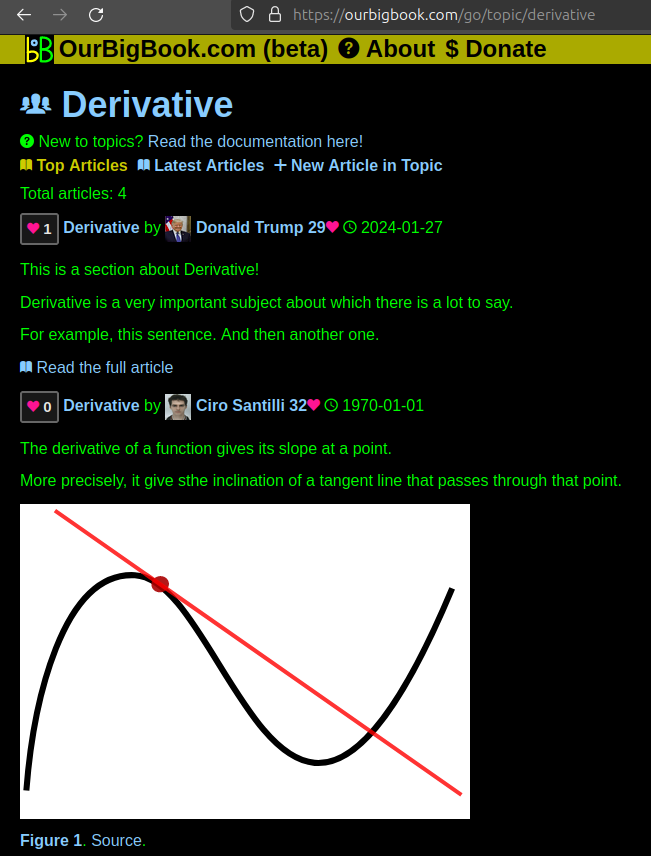
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.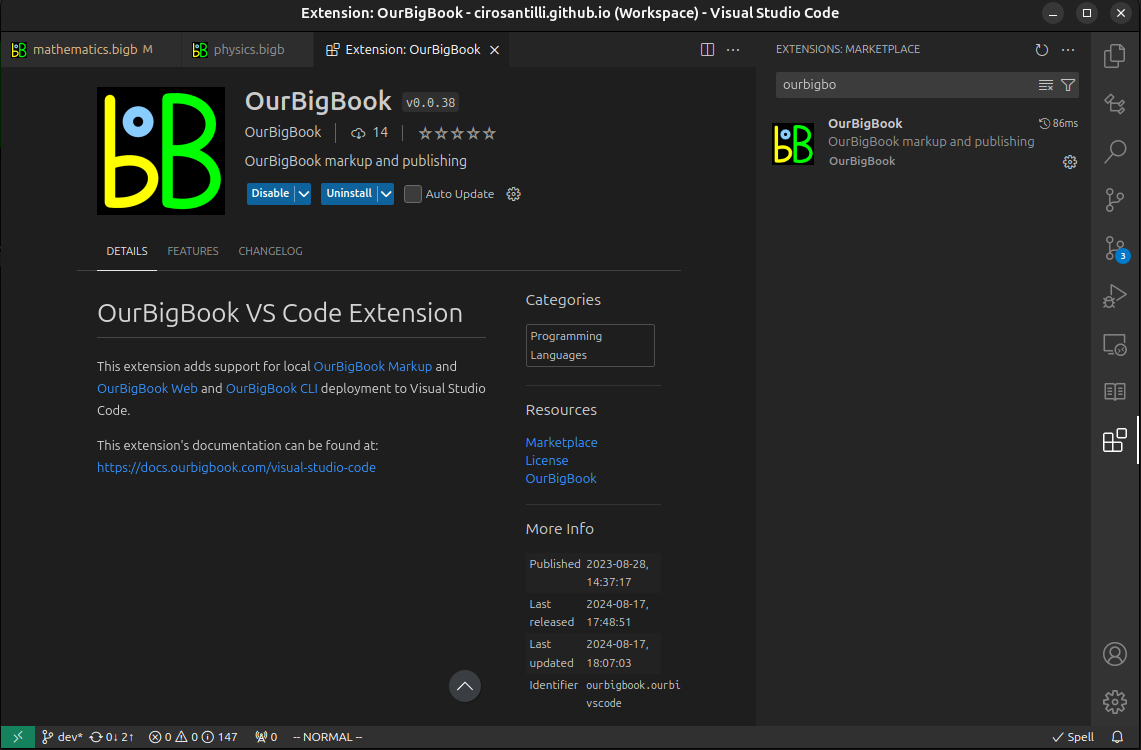
Figure 3. Visual Studio Code extension installation.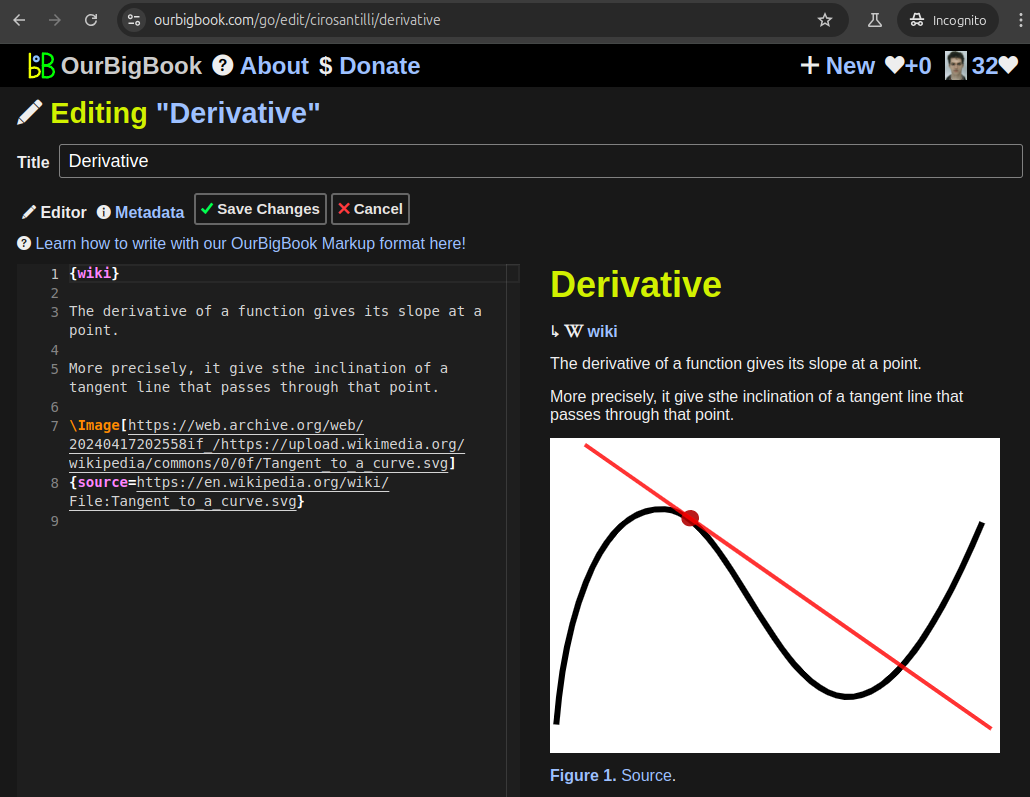
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 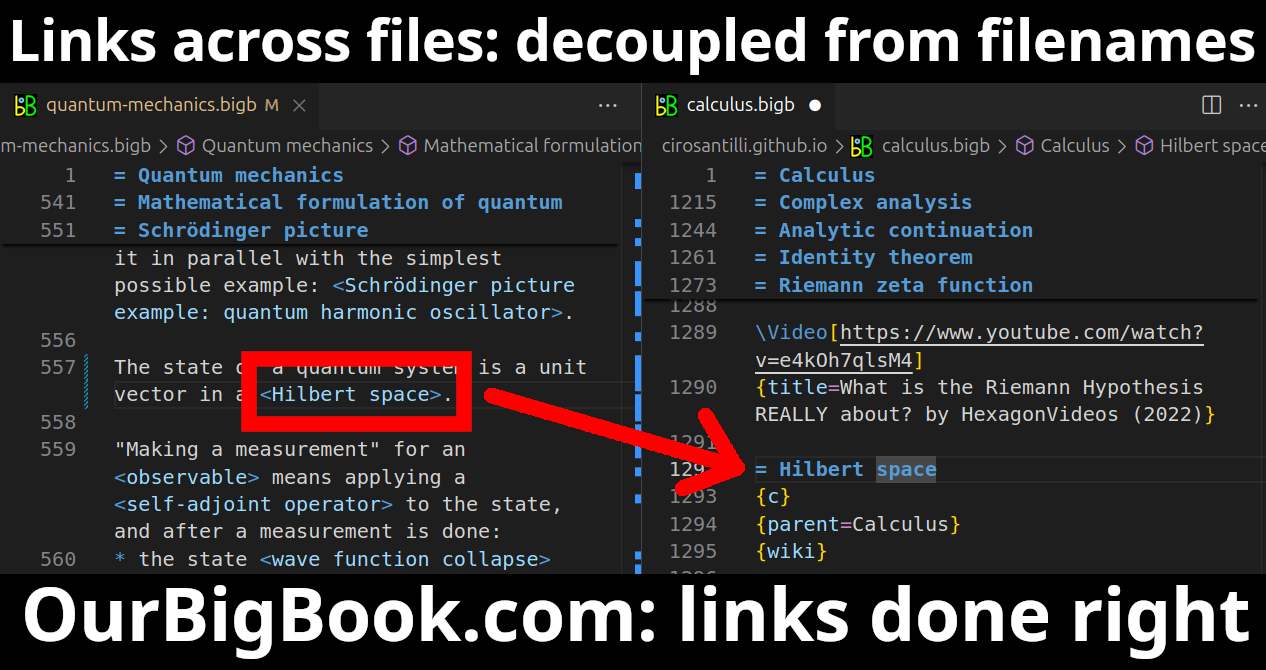
- Infinitely deep tables of contents:
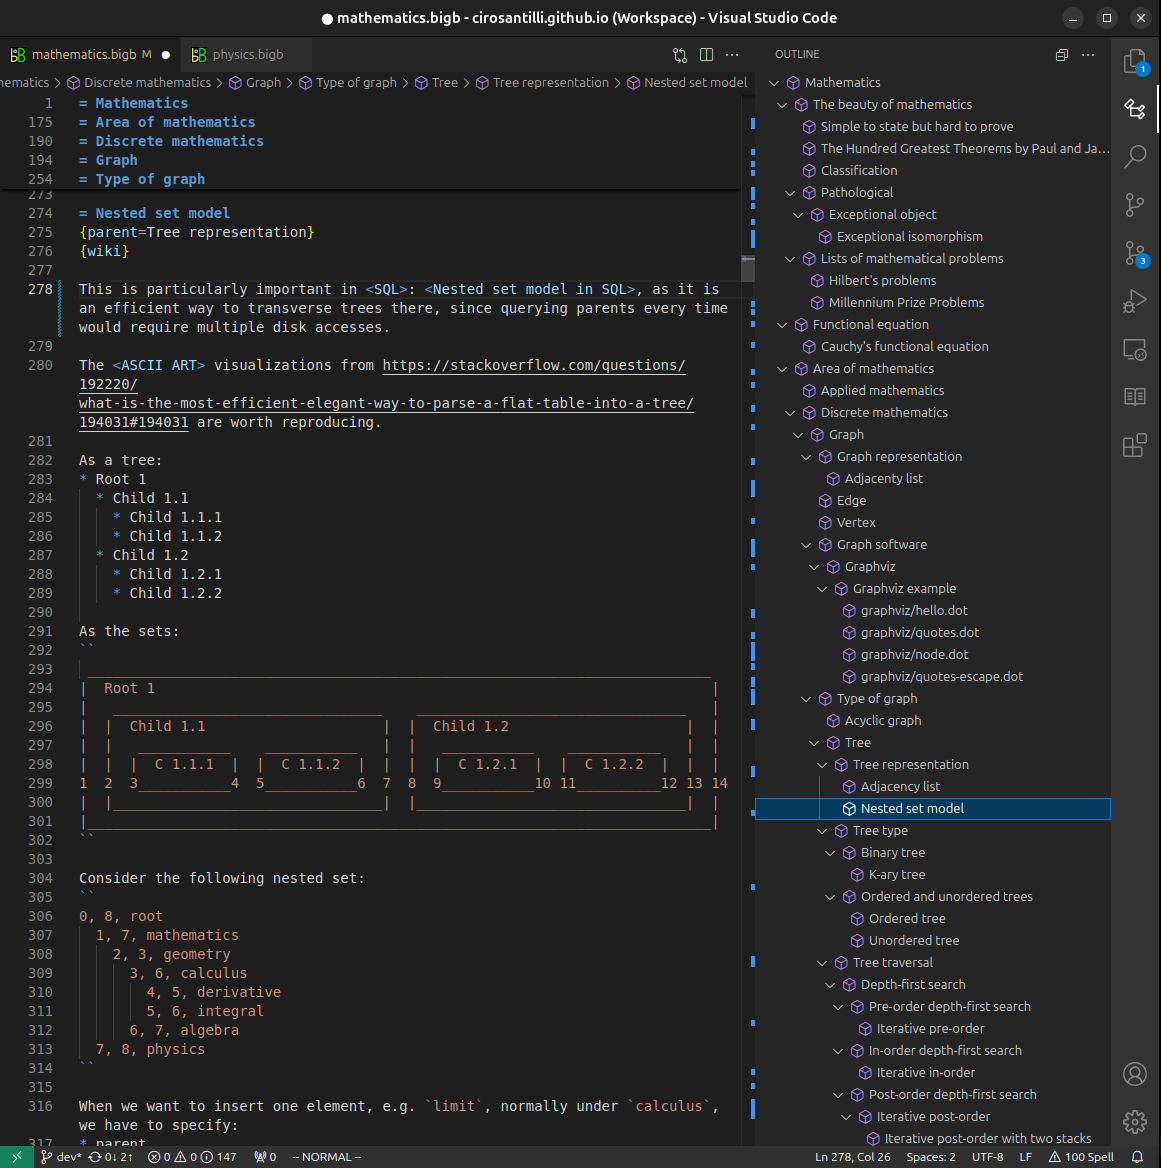
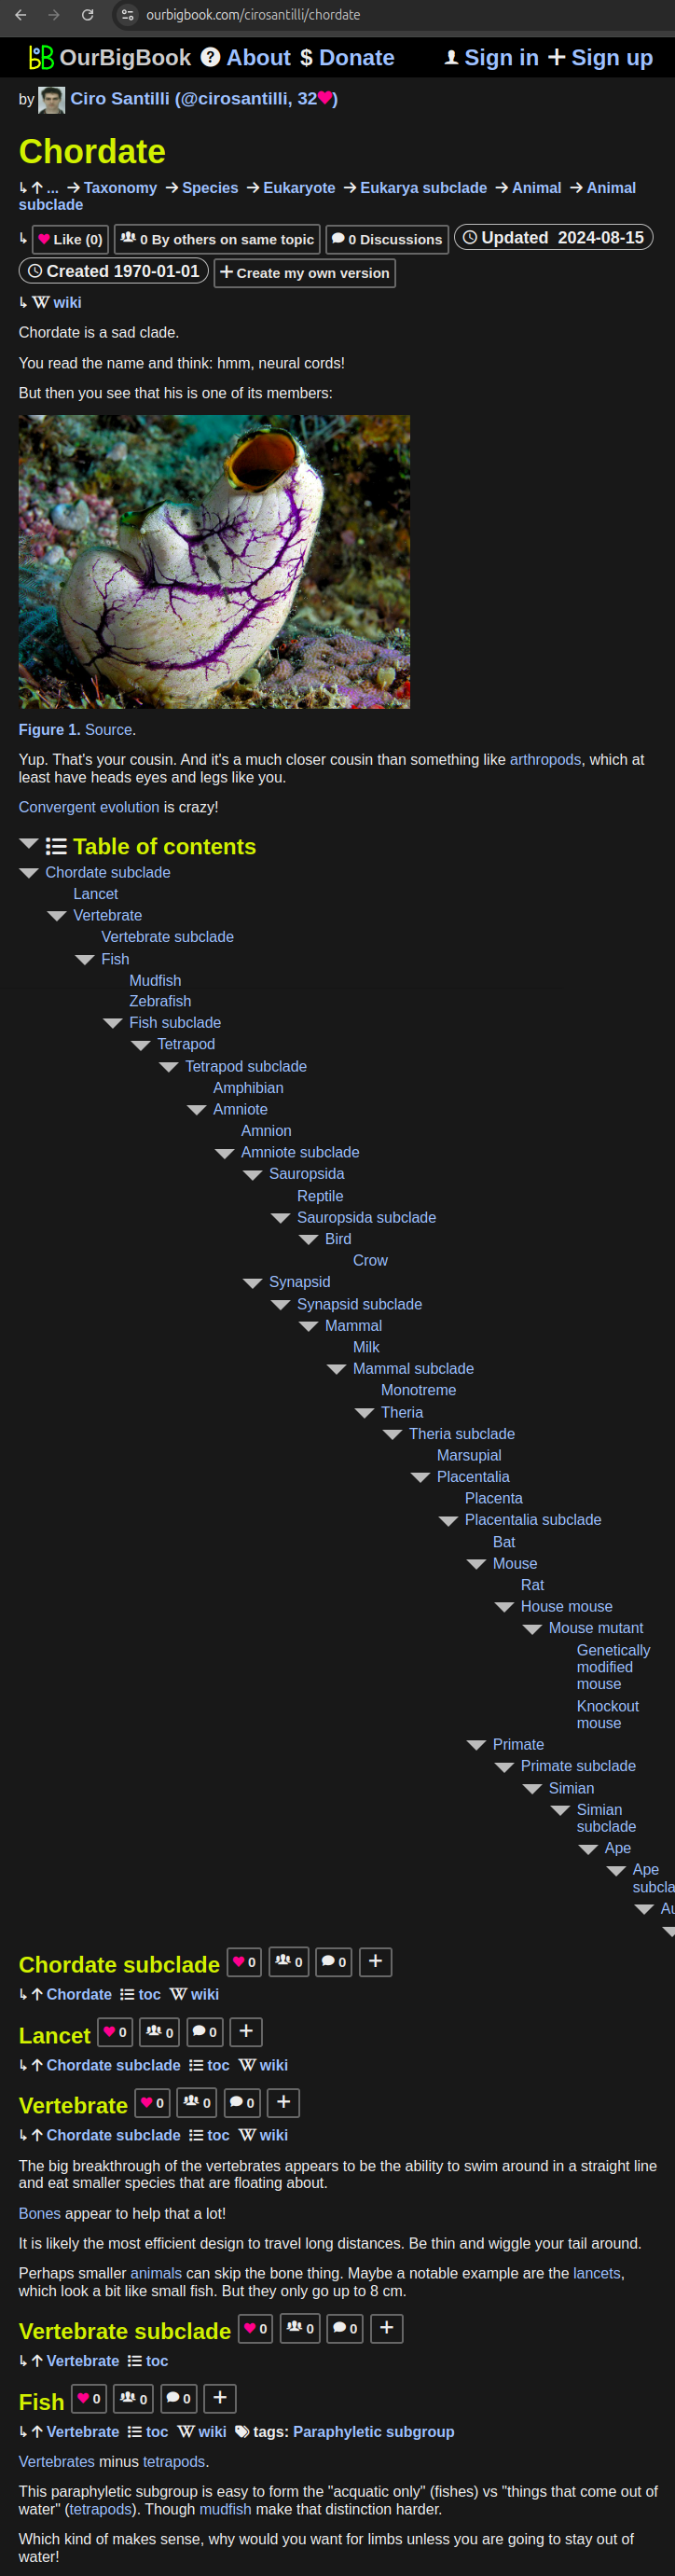

All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact