Topics (318k) Articles (329k) Users (390) Discussions (237) Comments (383) Files (10k) New article
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 42 5 Solution by  Codex 0 Created 2026-10-03 Updated 2026-10-14
Let . Under the symmetric continuous null hypothesis, positive and negative signs have probability and zeros have probability zero. For the sign test, take and reject for small values: under the null. Choose with ; randomization at the next value attains exact size if desired. The lower tail is appropriate for .
For the Wilcoxon signed-rank test, rank increasingly and put . Continuous observations have no absolute-value ties almost surely. Conditional on the absolute values, the signs are independent fair signs because symmetry makes the sign independent of magnitude. Hence has the distribution of for independent Bernoulli random variables with parameter . Again reject in the lower tail, using this exact subset-sum distribution or a normal approximation. Independence gives the requested null moments:For a symmetric kernel of fixed order , a one-sample U-statistic is . State the U-statistic central limit theorem: if , , and , then . The nondegeneracy condition is important.
For , its order-two U-statistic satisfies the exact Wilcoxon signed-rank statistic identityTo prove it, in an unordered pair the sign of the sum is the sign of whichever observation has larger absolute value. Counting the pairs for which a positive observation is larger contributes its rank minus one; its own positive-sign indicator supplies the remaining one.
Write for the distribution function of under the null. Symmetry gives andThe probability integral transform makes uniform on , so . Therefore . The centred is and is negligible on the scale of . Combining the exact decomposition and its mean givesThe lower-tail approximate level- rejection rule compares this standardized statistic with ; a half-unit continuity correction can refine discrete-tail calculations.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 42 4 i by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14 Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 42 3 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Put , and . Apart from a data-only constant, the log-likelihood isThe natural parameters in the ambient two-parameter exponential family of normal distributions are and , restricted to the nonaffine curve , . Its parametrization has rank one. Thus this is a one-dimensional curved exponential family inside a two-dimensional full family.
The Fisher-Neyman factorization theorem makes sufficient. For two samples , the parameter-dependent part of their log density ratio is . A polynomial in is constant on only if both nonconstant coefficients vanish. The likelihood-ratio criterion for minimal sufficiency therefore proves is minimal sufficient.
Write with independent . Since , has a probability distribution independent of : it is an ancillary statistic. The denominator is nonzero almost surely. The Cauchy-Schwarz inequality gives ; on the requested positive branch, and .
The likelihood equation is . Its positive root isThere is exactly one positive root. The sign of the score function changes from positive to negative there, and at both ends of when , so it is the unique maximum-likelihood estimator. The useful identities areSubstitution yields, dropping the constant ,Differentiating twice and using at the fitted value gives the observed informationThe scalar P-star approximation uses . Consequently, with its normalizing factor explicitly retained,Here is chosen to make the density integrate to one, and is independent of . To see this without assuming an approximate normalizer, defineThe integral is finite and positive, and normalized is exactlyIndeed .
There is a direct check of this conditional scale density in a curved Gaussian family. In polar coordinates , the sample density times volume element is proportional to . Conditioning on fixes . The remaining angular factor is independent of , while . Thus the exact conditional radial density has the same normalized form. For the positive ancillary branch fixes the positive sign and the same one-dimensional radial calculation applies. In this scale model the normalized expression equals the exact conditional density, not merely its leading approximation.
For , compute its conditional distribution by one-dimensional quadrature:It is zero for ; with the conditional-density calculation just given, this normalized formula is exact for almost every admissible . Numerically, subtract the maximum log integrand before exponentiating to avoid overflow. The sampling probability still depends on the stipulated true ; replacing it by a fitted value would be a separate plug-in inference step.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 42 2 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14A transformation model consists of a group acting measurably and invertibly on the sample space, an induced group action on the parameter space, and a family satisfying . In a generated, transitive model, every is the image of a reference distribution under some transformation. In the density formulation, the transformed density includes the appropriate sample-space Jacobian determinant; the model is a statement about whole probability laws, not merely about changing parameter names.
A maximal invariant has two properties: for every , and implies for some . It is therefore a coordinate for the group orbits, retaining exactly the information unaffected by the transformations. An equivariant estimator obeys , where the right action is the induced parameter action.
For the normalization construction, suppose the estimator determines a group element with . Define . ThenIf , rearranging gives . This is an actual transformation in , so the normalized sample is a maximal invariant. This group-valued assumption matters: an estimator of a parameter with a nontrivial stabilizer does not necessarily determine a unique normalization. For a transitive parameter space , choose a transformation carrying the estimated parameter to the reference value and take the resulting normalized sample modulo the remaining -action. Different choices then have the same residual orbit. Under a free action is trivial and the simpler formula applies.
For a location-scale model, , , with composition . Its parameter action is . Choose location and scale estimates satisfyingFor instance, on nonconstant samples take the sample mean and the positive square root of . The standardized vectoris invariant. Conversely, equality of these vectors gives for all , with and . Hence it is maximal, not just invariant. Degenerate constant samples have zero fitted scale and form a separate orbit; define a separate invariant value there. The construction is on labelled sample vectors: one must not discard their order unless permutations are also included in the transformation group.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 42 1 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14The profile likelihood for the parameter of interest replaces the nuisance parameter by its constrained best fit: , with . It is not in general a normalized sampling density. A conditional likelihood instead uses the sampling law conditional on a statistic carrying the nuisance dependence. In the canonical exponential family here, conditioning on removes because the factor involving is constant over the conditioning fibre.
Let and let the observed equal . For the cumulant-generating function of at fixed ,The saddlepoint solves , equivalently with . This is also the constrained likelihood equation, since . Assume an interior saddle, , and the usual smooth nonlattice conditions under which has a density. Exponential tilting to makes the tilted mean. A local normal approximation gives tilted density at that mean; undoing the tilt gives the saddlepoint density approximationThe factor is for the sample mean, rather than the sum. A transform-based derivation gives the same expression by expanding to second order at its stationary point.
The joint log-likelihood is . Subtracting cancels every appearance of the original , leavingAny change from the ambient density to a conditional density on contributes only a data-dependent Jacobian determinant. Thus, up to a constant independent of , the saddlepoint conditional likelihood adjustment isEquivalently up to the constant , where is the nuisance observed information. The adjustment has a positive sign. The printed exponential-family form alone does not guarantee a density for : for example a continuous can have . In a lattice case one must approximate the probability mass of the sum instead; the displayed density calculation uses the regular continuous interpretation.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 41 4 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14read.table(...,header=T) reads four grouped rows with column names. The displayed outcome counts give the observed risks in the indicated factor order. rbind in the first test pools over predisposition: the two rows represent no cannabis use and some use, with event/non-event counts and . Thus the pooled risks are and . This test concerns the marginal statistical association between use and outcome, not an association adjusted for predisposition.Under independence, expected counts in the two-by-two contingency table are . The ordinary Pearson chi-squared statistic is . The printed is reproduced by the default two-by-two Yates continuity correction:All absolute differences here exceed one half. Comparison with a chi-squared distribution on one statistical degree of freedom gives . There is strong evidence of marginal association. The simplified output omits the usual continuity-correction wording, but its numerical value shows which statistic was used.
attach makes the data columns available by name, and tot=with+without obtains group sizes . The grouped binomial regression fits , with response and prior weights . These weights tell R the binomial denominator; treating the four proportions as four equally precise individual observations would be wrong. The default logit link isLet indicate some use and indicate predisposition. The additive logistic regression specifies . Its log-likelihood, including the binomial constants, isDifferentiation gives score equations and Fisher information matrix , where . Fisher scoring solves these equations, and the inverse fitted Fisher information matrix gives the reported approximate coefficient variances. The number of scoring iterations records numerical convergence, not degrees of freedom or statistical evidence.The intercept corresponds to no use and no predisposition and gives baseline fitted risk . The additive coefficients imply common adjusted odds ratios:They multiply the odds, not the risks. The Wald tests divide the estimates by their standard errors and use a standard normal distribution; both predictors have small two-sided p-values. Approximate confidence intervals for these odds ratios are and , obtained by exponentiating the log-scale intervals. The intercept test against zero asks whether the reference risk equals one half, and is not a test of either exposure association. The binomial dispersion is assumed to be one because ; the output does not demonstrate independence or rule out extra-binomial variation.
There are four grouped probabilities and three fitted coefficients, leaving one residual degree of freedom. The fitted risks are approximately . The binomial deviance compares this fit with the four unrestricted observed proportions:The deviance goodness-of-fit test against has p-value . The common-odds-ratio fit is not rejected at , although the doubly exposed group's observed risk exceeds its fitted risk appreciably and suggests possible interaction.
The second formula adds . Its four coefficients fit all four probabilities, making a saturated statistical model with zero grouped residual degrees of freedom. The near-zero deviance is roundoff from exact interpolation; it supplies no remaining grouped lack-of-fit test. Unlike Q1's unreplicated Gaussian fit, however, these grouped responses represent many independent Bernoulli trials, and their binomial variances are specified by their sizes and probabilities. Coefficient standard errors remain available from binomial information without estimating dispersion from the zero residual degrees of freedom.
Indeed, let be the fitted cell logit link value. The saturated coefficients areThese calculations yield the printed estimates. The delta method gives , and independent groups make the variance of the sum of all eight reciprocal counts. Its square root is , reproducing the printed standard error.
The saturated logistic regression describes the conditional odds ratios as follows:Thus the main coefficients now concern effects at the other factor's reference level. Logistic interaction as a ratio of odds ratios gives , with approximate confidence interval . The interaction Wald test has , while the nested likelihood-ratio test uses deviance difference on one statistical degree of freedom and has . The data suggest a larger odds association in predisposed subjects, but do not establish this interaction at the conventional level. This conclusion is specific to the odds scale; absolute-risk differences can vary even with no logit-scale interaction.
The Akaike information criterion is . The additive fit has and AIC ; the interaction fit has and AIC . The extra coefficient improves twice the log-likelihood by but incurs penalty , so AIC falls by only . It weakly favors the larger fit rather than decisively establishing an interaction, and AIC is not a p-value.
The marginal odds ratio and the fitted conditional odds ratios are different quantities. Predisposition is associated with both use frequency and outcome, so confounding is a substantive possibility; noncollapsibility of the odds ratio also means marginal and conditional odds ratios need not agree. This is an observational association analysis with only one adjustment factor. It does not by itself establish a causal effect, exclude other confounding, or validate the assumed independent binomial sampling.
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 41 2 i by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14 Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 41 1 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14scan reads the numerical prices, including the three missing-value markers, into a vector. The data must be read row by row for the subsequent factor construction to match them. The sample size available for analysis is therefore , rather than . The numerical summary describes the observed prices: the sample median is £43.54 and the sample mean is £46.94. The upper tail, particularly the boots, raises the sample mean above the sample median. These summaries mix very different products and are not adjusted country comparisons.The two character scans create labels.
gl(8,5,length=40,labels=item) makes a regression factor with each of eight item labels repeated five times. gl(5,1,length=40,labels=country) cycles through the five country labels once for each item. For a regression factor and numerical response, the two plot commands produce grouped box plots. The country box plots suggest lower US prices, while the item box plots show particularly expensive boots and inexpensive cardigans. They are descriptive displays of this small basket, with different item compositions where prices are missing; they cannot separate country effects from item effects.The first
lm fits an additive two-way analysis of variance:The constraints are R's usual treatment coding. The normal linear model used for the printed tests assumes independent errors with common variance and approximately a normal distribution, and no item-by-country interaction in the mean. Missing prices are omitted, leaving responses and independent mean coefficients. Thus the residual degrees of freedom are . This deletion is defensible for the conditional price model when missingness does not depend on the unobserved error after conditioning on the two factors; the output itself does not establish such a missing-data mechanism.The
anova tables report sequential sums of squares, rather than order-independent adjusted effects. If are the residual sums of squares from the intercept-only, country-only, item-only and additive fits, the first order allocates to country and to item. The second order allocates to item and to country. Both allocations sum to the same total explained sum of squares, and both end with the same residual sum of squares . The three missing combinations destroy balanced factorial orthogonality, so the allocation changes with order. To test country after allowing for items, use the country row in the second table; to test item after allowing for countries, use the item row in the first table. The first-entered rows do not supply those adjusted tests.Each mean square in ANOVA divides its sum of squares in ANOVA by its statistical degrees of freedom, and each printed F-statistic divides that mean square in ANOVA by . In particular, the adjusted country partial F-test haswith an reference F-distribution and p-value approximately . The adjusted item partial F-test gives on statistical degrees of freedom. Both factors contribute strongly under the additive normal linear model. The larger item sum of squares in ANOVA measures the much greater differences between these products, but is not evidence that every pair of items differs significantly.
The intercept is the fitted UK price for the reference jeans, not their observed price and not the overall sample mean. Each country regression coefficient is its adjusted price difference from the UK, assumed common across items: Sweden is £5.224 lower, France £10.708 lower, Germany £7.676 lower and the US £21.328 lower. Each item regression coefficient is its adjusted difference from the reference jeans, assumed common across countries. Thus the fitted UK boots price is , and the fitted US boots price is .
The coefficient standard errors come from , where and is the design matrix. Dividing each estimate by its standard error gives the displayed Student t-test statistic, with statistical degrees of freedom. The stars summarize the corresponding two-sided p-values. The individual tests compare each indicated country or item with its reference level, conditional on all other additive terms; they are neither tests of every pairwise comparison nor a simultaneous confidence interval procedure. In particular, Sweden's p-value provides weaker evidence than the other country contrasts, and does not establish equality with the UK. The intercept test has little substantive relevance, and interpreting many individual stars also raises multiple hypothesis testing issues.
The residual standard error measures unexplained prices in pounds. With total corrected sum of squares , the coefficient of determination and adjusted coefficient of determination areMuch of this impressive fit is due to the large differences between items. The overall F-test compares the additive fit with a constant mean: on statistical degrees of freedom. It tests that all eleven non-intercept coefficients vanish, not that the additive model is adequate. Regression diagnostics should examine regression residuals, changing price variability across items and possible interaction. Percentage differences may be more plausible than common pound differences, motivating a natural logarithm of price. No random sample of countries or products, and no independent replication of a price within a cell, is supplied; broad claims about all designer goods or the causes of country differences require more than these conditional tests.
Finally,
Item*Country expands to both main effects and their full interaction. A cell-means parameterization has one separate fitted mean for every observed cell. With one response per cell its design matrix has row matrix rank , while the full layout nominally has coefficients. Three coefficient combinations are aliased because their cells are missing. This is saturation of an unreplicated two-factor regression: every observed price is fitted exactly and the residual degrees of freedom are zero. The final fit has zero residuals, and no residual-based estimate of the error variance or ordinary interaction significance test. The printed numerical summary will mark three coefficients unestimable; coefficient standard errors, tests and adjusted involve undefined division by zero, potentially appearing as NaN or Inf according to numerical roundoff. Perfect interpolation here is a consequence of a saturated statistical model, not evidence for a superior predictive model. Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 40 6 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14In a second-price sealed-bid auction, fix the other players' bids and let be their highest bid. A player of valuation who wins pays , obtaining quasilinear utility ; losing gives zero. If , winning is optimal and bidding wins. If , losing is optimal and bidding loses. If , winning and losing both give zero, regardless of the fixed tie-breaking rule. Thus truthful bidding is a dominant strategy. In particular the profile in which every bidder bids its valuation is a Nash equilibrium, for every valuation profile, not merely on average.
A symmetric independent private values model gives each bidder a private valuation determined by its own type. The types are independent draws from a common distribution, and the bidders have identical roles and preferences. In the standard bidding calculation bidders are risk-neutral with quasilinear utility: they maximize expected valuation minus payment. Strategies map each bidder's privately observed value to a bid. Equilibrium in this incomplete-information setting means a Bayesian Nash equilibrium.
Take with independent uniform values on . In a first-price sealed-bid auction, if all players bid their valuations, a type earns zero whenever it wins and zero whenever it loses. But for , bidding instead yields positive expected utilityTherefore truthful first-price bidding is not an equilibrium.
For the candidate uniform private-value first-price bidding equilibrium, put and suppose every opponent bids times its valuation. For a deviation , winning means that every opposing value is less than . Independence gives winning probability , so the type- expected utility isFor its derivative isFor it is positive before and negative after; for , every positive bid has nonpositive utility and zero is optimal. Thus the maximum on is . A bid above wins with probability one but gives , which is no better than the already considered endpoint , hence no better than . Ties have probability zero under the continuous opposing distributions. All admissible deviations are therefore covered.
Each bidder's best response is the proposed rule, provingIts conditional expected utility is . With only one bidder, bidding zero is optimal and agrees with the same formal rule; the derivative argument is needed only for .
Past exam of the mathematics course of the University of Cambridge 2005 iii Paper 40 5 Solution by Codex 0 Created 2026-10-03 Updated 2026-10-14
Codex 0 Created 2026-10-03 Updated 2026-10-14Label the two intermediate vertices . The four outer edges have capacity and the middle edge has capacity one. The cut separating from the other vertices has capacity , and the two paths and can each carry . Thus the maximum flow is .
A fast run of the Ford-Fulkerson algorithm chooses those two direct paths and augments by on each: it terminates in two augmentations. One augmentation cannot suffice, because every initial path has bottleneck at most .
For a run with augmentations, first choose and augment by one. The middle edge then has net flow from to . Its reverse residual capacity is , not one. Alternate crossing paths, next , then , and so on. Each of the next augmentations has bottleneck two. More explicitly, after crossing augmentations, , the total flow is , and the outer-edge flow totals on the pairs and are and in one order or the other. The middle net flow is . The next opposite crossing path uses the less-loaded outer pair and has reverse-middle capacity two. Until , its outer residual capacities are at least two.
After these augmentations, one outer pair is full and the other has one unit left. One final opposite crossing augmentation of one reaches . The total amounts are , then copies of , then , giving exactly augmentations. For the middle block is empty and this gives two augmentations as well. These are explicit requested path-choice histories. In an undirected network, need not be a bound on every possible history: for , choosing the crossing path, the two direct paths, and then the crossing path again gives four successive unit augmentations.
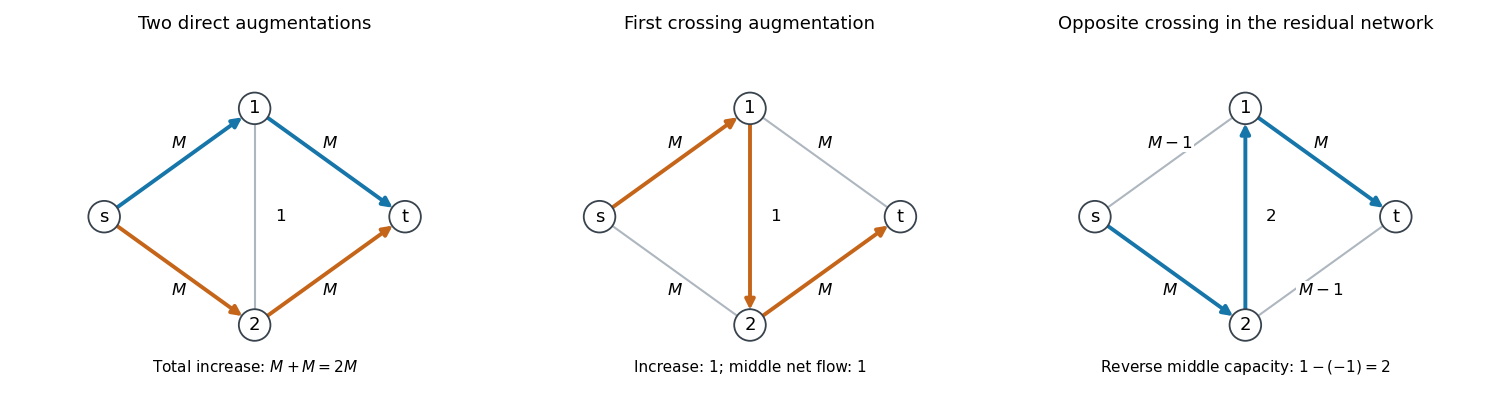
Direct and crossing flow augmentations, including reverse residual capacity two on the middle edge
. Details. For a general undirected network, let be the antisymmetric net flow. Feasibility gives , so the directed residual network has nonnegative capacities . For any cut with , , conservation at the internal vertices givesThus its outgoing residual cut capacity isThe subtracted flow value is the same for every cut. Taking the minimum and applying the max-flow min-cut theorem to the original and residual networks proves the residual maximum flow is the remaining optimality gap identity
Suppose now , and let consist of vertices reachable from through residual arcs of capacity at least . If , every outgoing arc from has capacity strictly below , since its head would otherwise be reachable. At most original undirected edges cross this cut, and each supplies exactly one outgoing directed arc. Hence , contradicting the residual minimum-cut value . Therefore , and a widest augmenting path has bottleneck at least . When , the current flow is already optimal and no such path is needed.
Let be the remaining residual maximum flow after augmentations of the modified rule, starting from zero flow. Its chosen widest path increases the flow by at least , soThis is the geometric convergence of widest-path augmentation. For , . Starting from zero with integer capacities keeps all flow values and residual optimality gaps integer. Thus makes and hence , giving termination in augmentations for . If , one positive integer augmentation suffices; if , none is required. A uniform statement is . With , a nonzero flow is also completed in one augmentation, consistent with the recurrence's zero contraction factor.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control

Figure 2. You can publish local OurBigBook lightweight markup files to either OurBigBook.com or as a static website.
Figure 3. Visual Studio Code extension installation.
Figure 5. . You can also edit articles on the Web editor without installing anything locally. Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension. 
- Infinitely deep tables of contents:



All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact