Topics (119k) Articles (119k) Users (316) Discussions (245) Comments (383) Files (707) New article
Running:outputs:
readelf -h hello_world.oMagic: 7f 45 4c 46 02 01 01 00 00 00 00 00 00 00 00 00
Class: ELF64
Data: 2's complement, little endian
Version: 1 (current)
OS/ABI: UNIX - System V
ABI Version: 0
Type: REL (Relocatable file)
Machine: Advanced Micro Devices X86-64
Version: 0x1
Entry point address: 0x0
Start of program headers: 0 (bytes into file)
Start of section headers: 64 (bytes into file)
Flags: 0x0
Size of this header: 64 (bytes)
Size of program headers: 0 (bytes)
Number of program headers: 0
Size of section headers: 64 (bytes)
Number of section headers: 7
Section header string table index: 3Running:outputs:
readelf -h hello_world.outMagic: 7f 45 4c 46 02 01 01 00 00 00 00 00 00 00 00 00
Class: ELF64
Data: 2's complement, little endian
Version: 1 (current)
OS/ABI: UNIX - System V
ABI Version: 0
Type: EXEC (Executable file)
Machine: Advanced Micro Devices X86-64
Version: 0x1
Entry point address: 0x4000b0
Start of program headers: 64 (bytes into file)
Start of section headers: 272 (bytes into file)
Flags: 0x0
Size of this header: 64 (bytes)
Size of program headers: 56 (bytes)
Number of program headers: 2
Size of section headers: 64 (bytes)
Number of section headers: 6
Section header string table index: 3Bytes in the object file:
00000000  7f 45 4c 46 02 01 01 00  00 00 00 00 00 00 00 00  |.ELF............|
00000010  01 00 3e 00 01 00 00 00  00 00 00 00 00 00 00 00  |..>.............|
00000020  00 00 00 00 00 00 00 00  40 00 00 00 00 00 00 00  |........@.......|
00000030  00 00 00 00 40 00 00 00  00 00 40 00 07 00 03 00  |....@.....@.....|
Executable:
00000000  7f 45 4c 46 02 01 01 00  00 00 00 00 00 00 00 00  |.ELF............|
00000010  02 00 3e 00 01 00 00 00  b0 00 40 00 00 00 00 00  |..>.......@.....|
00000020  40 00 00 00 00 00 00 00  10 01 00 00 00 00 00 00  |@...............|
00000030  00 00 00 00 40 00 38 00  02 00 40 00 06 00 03 00  |....@.8...@.....|
Structure represented:
# define EI_NIDENT 16

typedef struct {
    unsigned char   e_ident[EI_NIDENT];
    Elf64_Half      e_type;
    Elf64_Half      e_machine;
    Elf64_Word      e_version;
    Elf64_Addr      e_entry;
    Elf64_Off       e_phoff;
    Elf64_Off       e_shoff;
    Elf64_Word      e_flags;
    Elf64_Half      e_ehsize;
    Elf64_Half      e_phentsize;
    Elf64_Half      e_phnum;
    Elf64_Half      e_shentsize;
    Elf64_Half      e_shnum;
    Elf64_Half      e_shstrndx;
} Elf64_Ehdr;
Manual breakdown:
- 0 0:
EI_MAG=7f 45 4c 46=0x7f 'E', 'L', 'F': ELF magic number - 0 4:
EI_CLASS=02=ELFCLASS64: 64 bit elf - 0 5:
EI_DATA=01=ELFDATA2LSB: little endian data - 0 6:
EI_VERSION=01: format version - 0 7:
EI_OSABI(only in 2003 Update) =00=ELFOSABI_NONE: no extensions. - 0 8:
EI_PAD= 8x00: reserved bytes. Must be set to 0. - On the executable it is
02 00forET_EXEC.Another important possibility for the executable isET_DYNfor PIE executables and shared libraries.ET_DYNtells the Linux kernel that the code is position independent, and can loaded at a random memory location with ASLR. - 1 2:
e_machine=3e 00=62=EM_X86_64: AMD64 architecture - 1 4:
e_version=01 00 00 00: must be 1 - 1 8:
e_entry= 8x00: execution address entry point, or 0 if not applicable like for the object file since there is no entry point.On the executable, it isb0 00 40 00 00 00 00 00. The kernel puts the RIP directly on that value when executing. It can be configured by the linker script or-e. But it will segfault if you set it too low: stackoverflow.com/questions/2187484/why-is-the-elf-execution-entry-point-virtual-address-of-the-form-0x80xxxxx-and-n 40 00 00 00on the executable, i.e. it starts immediately after the ELF header.- 2 8:
e_shoff=407x00=0x40: section header table file offset, 0 if not present. The Intel386 architecture defines no flags; so this member contains zero.
- 3 4:
e_ehsize=40 00: size of this elf header. TODO why this field needed? Isn't the size fixed? 38 00on executable: it is 56 bytes long02 00on executable: there are 2 entries.- 3 A:
e_shentsizeande_shnum=40 00 07 00: section header size and number of entries - 3 E:
e_shstrndx(Section Header STRing iNDeX) =03 00: index of the.shstrtabsection.
Array of
Elf64_Shdr structs.Each entry contains metadata about a given section.
e_shoff of the ELF header gives the starting position, 0x40 here.So the table takes bytes from 0x40 to
0x40 + 7 + 0x40 - 1 = 0x1FF.Some section names are reserved for certain section types: www.sco.com/developers/gabi/2003-12-17/ch4.sheader.html#special_sections e.g.
.text requires a SHT_PROGBITS type and SHF_ALLOC + SHF_EXECINSTRRunning:outputs:
readelf -S hello_world.oThere are 7 section headers, starting at offset 0x40:
Section Headers:
[Nr] Name Type Address Offset
Size EntSize Flags Link Info Align
[ 0] NULL 0000000000000000 00000000
0000000000000000 0000000000000000 0 0 0
[ 1] .data PROGBITS 0000000000000000 00000200
000000000000000d 0000000000000000 WA 0 0 4
[ 2] .text PROGBITS 0000000000000000 00000210
0000000000000027 0000000000000000 AX 0 0 16
[ 3] .shstrtab STRTAB 0000000000000000 00000240
0000000000000032 0000000000000000 0 0 1
[ 4] .symtab SYMTAB 0000000000000000 00000280
00000000000000a8 0000000000000018 5 6 4
[ 5] .strtab STRTAB 0000000000000000 00000330
0000000000000034 0000000000000000 0 0 1
[ 6] .rela.text RELA 0000000000000000 00000370
0000000000000018 0000000000000018 4 2 4
Key to Flags:
W (write), A (alloc), X (execute), M (merge), S (strings), l (large)
I (info), L (link order), G (group), T (TLS), E (exclude), x (unknown)
O (extra OS processing required) o (OS specific), p (processor specific)The
struct represented by each entry is:typedef struct {
Elf64_Word sh_name;
Elf64_Word sh_type;
Elf64_Xword sh_flags;
Elf64_Addr sh_addr;
Elf64_Off sh_offset;
Elf64_Xword sh_size;
Elf64_Word sh_link;
Elf64_Word sh_info;
Elf64_Xword sh_addralign;
Elf64_Xword sh_entsize;
} Elf64_Shdr;Only appears in the executable.
Contains information of how the executable should be put into the process virtual memory.
The executable is generated from object files by the linker. The main jobs that the linker does are:
- determine which sections of the object files will go into which segments of the executable.
- do relocation according to the
.rela.textsection. This depends on how the multiple sections are put into memory.
readelf -l hello_world.out gives:Elf file type is EXEC (Executable file)
Entry point 0x4000b0
There are 2 program headers, starting at offset 64
Program Headers:
Type Offset VirtAddr PhysAddr
FileSiz MemSiz Flags Align
LOAD 0x0000000000000000 0x0000000000400000 0x0000000000400000
0x00000000000000d7 0x00000000000000d7 R E 200000
LOAD 0x00000000000000d8 0x00000000006000d8 0x00000000006000d8
0x000000000000000d 0x000000000000000d RW 200000
Section to Segment mapping:
Segment Sections...
00 .text
01 .dataOn the ELF header, and:
e_phoff, e_phnum and e_phentsize told us that there are 2 program headers, which start at 0x40 and are 0x38 bytes long each, so they are:00000040 01 00 00 00 05 00 00 00 00 00 00 00 00 00 00 00 |................|
00000050 00 00 40 00 00 00 00 00 00 00 40 00 00 00 00 00 |..@.......@.....|
00000060 d7 00 00 00 00 00 00 00 d7 00 00 00 00 00 00 00 |................|
00000070 00 00 20 00 00 00 00 00 |.. ..... |00000070 01 00 00 00 06 00 00 00 | ........|
00000080 d8 00 00 00 00 00 00 00 d8 00 60 00 00 00 00 00 |..........`.....|
00000090 d8 00 60 00 00 00 00 00 0d 00 00 00 00 00 00 00 |..`.............|
000000a0 0d 00 00 00 00 00 00 00 00 00 20 00 00 00 00 00 |.......... .....|Structure represented www.sco.com/developers/gabi/2003-12-17/ch5.pheader.html:
typedef struct {
    Elf64_Word  p_type;
    Elf64_Word  p_flags;
    Elf64_Off   p_offset;
    Elf64_Addr  p_vaddr;
    Elf64_Addr  p_paddr;
    Elf64_Xword p_filesz;
    Elf64_Xword p_memsz;
    Elf64_Xword p_align;
} Elf64_Phdr;
Breakdown of the first one:
- 40 0:
p_type=01 00 00 00=PT_LOAD: this is a regular segment that will get loaded in memory. - 40 4:
p_flags=05 00 00 00= execute and read permissions. No write: we cannot modify the text segment. A classic way to do this in C is with string literals: stackoverflow.com/a/30662565/895245 This allows kernels to do certain optimizations, like sharing the segment amongst processes. This member gives the offset from the beginning of the file at which the first byte of the segment resides.
But it looks like offsets from the beginning of segments, not file?- 50 0:
p_vaddr=00 00 40 00 00 00 00 00: initial virtual memory address to load this segment to - 50 8:
p_paddr=00 00 40 00 00 00 00 00: unspecified effect. Intended for systems in which physical addressing matters. TODO example? - 60 0:
p_filesz=d7 00 00 00 00 00 00 00: size that the segment occupies in memory. If smaller thanp_memsz, the OS fills it with zeroes to fit when loading the program. This is how BSS data is implemented to save space on executable files. i368 ABI says onPT_LOAD:The bytes from the file are mapped to the beginning of the memory segment. If the segment’s memory size (p_memsz) is larger than the file size (p_filesz), the ‘‘extra’’ bytes are defined to hold the value 0 and to follow the segment’s initialized area. The file size may not be larger than the memory size.
The second segment (
.data) is analogous. TODO: why use offset 0x0000d8 and address 0x00000000006000d8? Why not just use 0 and 0x00000000006000d8?Then the:section of the
Section to Segment mapping:readelf tells us that:TODO where does this information come from? stackoverflow.com/questions/23018496/section-to-segment-mapping-in-elf-files
Organization developing electron on helium quantum computer by  Ciro Santilli 40 Updated 2025-07-16
Experiments to measure it:
The 2019 redefinition of the SI base units defines it precisely and uses it as a measure of charge: en.wikipedia.org/wiki/2019_redefinition_of_the_SI_base_units#Ampere
He beats the The European Union is a failure drum pretty well.
- www.youtube.com/watch?v=iVxaTC7Qp44 The Global Minotaur: The Crash of 2008 and the Euro-Zone Crisis in Historical Perspective (2011)
- youtu.be/vNhkYXhYSSs?t=368 proposes that there is something missing from utility maximization, citing a lotus-Eater Machine idea
github.com/CovertLab/WholeCellEcoliRelease is a whole cell simulation model created by Covert Lab and other collaborators.
The project is written in Python, hurray!
But according to te README, it seems to be the use a code drop model with on-request access to master. Ciro Santilli asked at rationale on GitHub discussion, and they confirmed as expected that it is to:
- to prevent their publication ideas from being stolen. Who would steal publication ideas with public proof in an issue tracker without crediting original authors? Academia is broken. Academia should be the most open form of knowledge sharing. But instead we get this silly competition for publication points.
- to prevent noise from non-collaborators. But they only get like 2 issues as year on such a meganiche subject... Did you know that you can ignore people, and even block them if they are particularly annoying? Much more likely is that no one will every hear about your project and that it will die with its last graduate student slave.
The project is a followup to the earlier M. genitalium whole cell model by Covert lab which modelled Mycoplasma genitalium. E. Coli has 8x more genes (500 vs 4k), but it the undisputed bacterial model organism and as such has been studied much more thoroughly. It also reproduces faster than Mycoplasma (20 minutes vs a few hours), which is a huge advantages for validation/exploratory experiments.
The project has a partial dependency on the proprietary optimization software CPLEX which is freeware, for students, not sure what it is used for exactly, from the comment in the
requirements.txt the dependency is only partial.This project makes Ciro Santilli think of the E. Coli as an optimization problem. Given such external nutrient/temperature condition, which DNA sequence makes the cell grow the fastest? Balancing metabolites feels like designing a Factorio speedrun.
There is one major thing missing thing in the current model: promoters/transcription factor interactions are not modelled due to lack/low quality of experimental data: github.com/CovertLab/WholeCellEcoliRelease/issues/21. They just have a magic direct "transcription factor to gene" relationship, encoded at reconstruction/ecoli/flat/foldChanges.tsv in terms of type "if this is present, such protein is expressed 10x more". Transcription units are not implemented at all it appears.
Everything in this section refers to version 7e4cc9e57de76752df0f4e32eca95fb653ea64e4, the code drop from November 2020, and was tested on Ubuntu 21.04 with a docker install of
docker.pkg.github.com/covertlab/wholecellecolirelease/wcm-full with image id 502c3e604265, unless otherwise noted.By Tagkopoulos lab at University of California, Davies.
- www.nature.com/articles/ncomms13090 Multi-omics integration accurately predicts cellular state in unexplored conditions for Escherichia coli (2016)
- www.sciencedaily.com/releases/2016/10/161027173552.htm
The conventional starting point is not at the E. Coli K-12 MG1655 origin of replication.
biocyc.org/ECOLI/NEW-IMAGE?type=EXTRAGENIC-SITE&object=G0-10506 explains:If it is a bit hard to understand what they mean by "origin of transfer" though, as that term is usually associated with the origin of transfer of bacterial conjugation.
This site is the origin of replication of the E. coli chromosome. It contains the binding sites for DnaA, which is critical for initiation of replication. Replication proceeds bidirectionally. For historical reasons, the numbering of E. coli's circular chromosome does not start at the origin of replication, but at the origin of transfer during conjugation.
The mandatory xkcd: xkcd 927: Standards.
It is hard for complex organisms to evolve because longer DNA means longer replication time by Ciro Santilli 40 Updated 2025-07-16
Ciro Santilli 40 Updated 2025-07-16Because DNA replication is a key limiting factor of bacterial replication time, such organisms are therefore strongly incentivized to have very minimal DNAs.
Power, Sex, Suicide by Nick Lane (2006) 7 "Why bacteria are simple" page 169 puts this nicely:
Bacteria replicate at colossal speed. [...] In two days, the mass of exponentially doubling E. coli would be 2664 times larger than the mass of the Earth.Luckily this does not happen, and the reason is that bacteria are normally half starved. They swiftly consume all available food, whereupon their growth is limited once again by the lack of nutrients. Most bacteria spend most of their lives in stasis, waiting for a meal. Nonetheless, the speed at which bacteria do mobilize themselves to replicate upon feeding illustrates the overwhelming strength of the selection pressures at work.
Pinned article: Introduction to the OurBigBook Project
Welcome to the OurBigBook Project! Our goal is to create the perfect publishing platform for STEM subjects, and get university-level students to write the best free STEM tutorials ever.
Everyone is welcome to create an account and play with the site: ourbigbook.com/go/register. We belive that students themselves can write amazing tutorials, but teachers are welcome too. You can write about anything you want, it doesn't have to be STEM or even educational. Silly test content is very welcome and you won't be penalized in any way. Just keep it legal!
Intro to OurBigBook
. Source. We have two killer features:
- topics: topics group articles by different users with the same title, e.g. here is the topic for the "Fundamental Theorem of Calculus" ourbigbook.com/go/topic/fundamental-theorem-of-calculusArticles of different users are sorted by upvote within each article page. This feature is a bit like:
- a Wikipedia where each user can have their own version of each article
- a Q&A website like Stack Overflow, where multiple people can give their views on a given topic, and the best ones are sorted by upvote. Except you don't need to wait for someone to ask first, and any topic goes, no matter how narrow or broad
This feature makes it possible for readers to find better explanations of any topic created by other writers. And it allows writers to create an explanation in a place that readers might actually find it.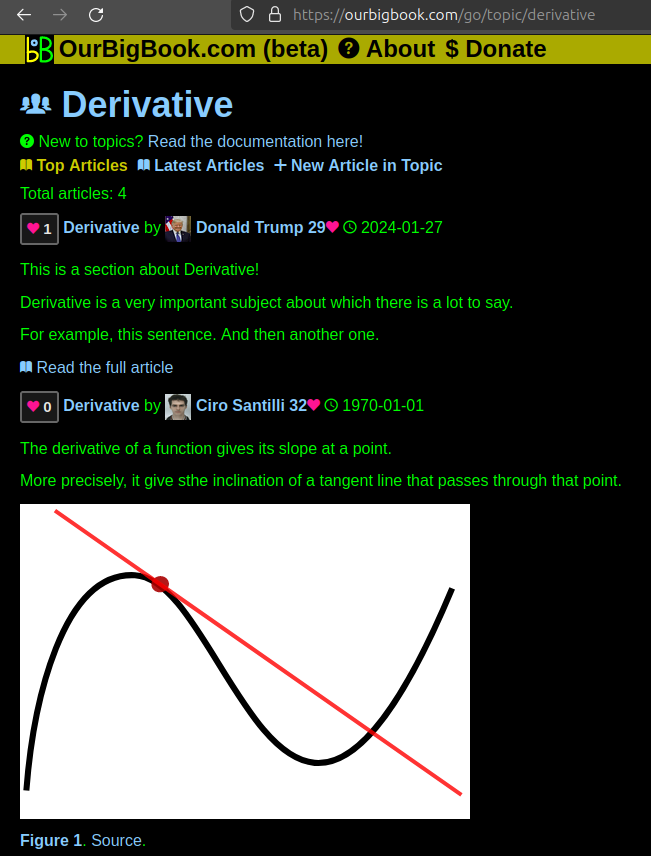
Figure 1. Screenshot of the "Derivative" topic page. View it live at: ourbigbook.com/go/topic/derivativeVideo 2. OurBigBook Web topics demo. Source. - local editing: you can store all your personal knowledge base content locally in a plaintext markup format that can be edited locally and published either:This way you can be sure that even if OurBigBook.com were to go down one day (which we have no plans to do as it is quite cheap to host!), your content will still be perfectly readable as a static site.
- to OurBigBook.com to get awesome multi-user features like topics and likes
- as HTML files to a static website, which you can host yourself for free on many external providers like GitHub Pages, and remain in full control
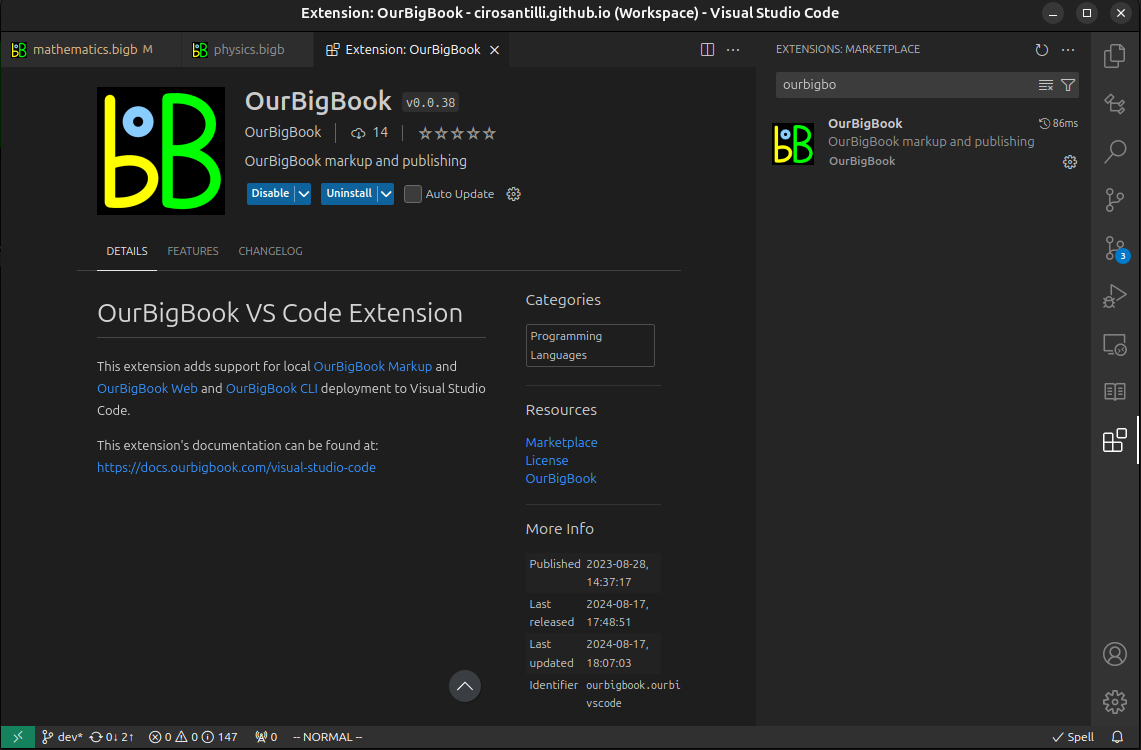
Figure 3. Visual Studio Code extension installation.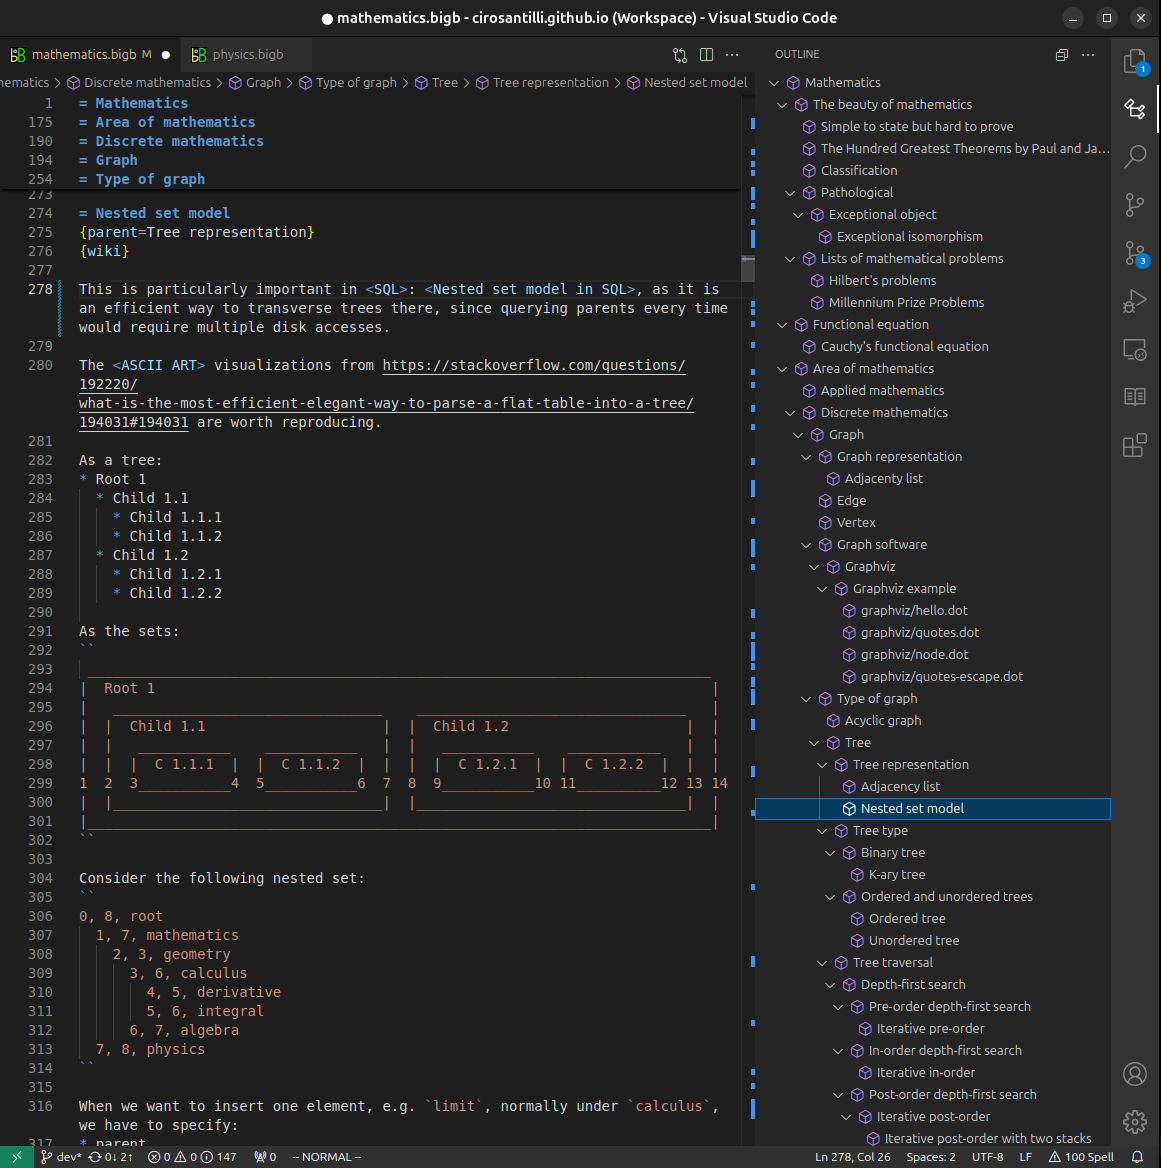
Figure 4. Visual Studio Code extension tree navigation.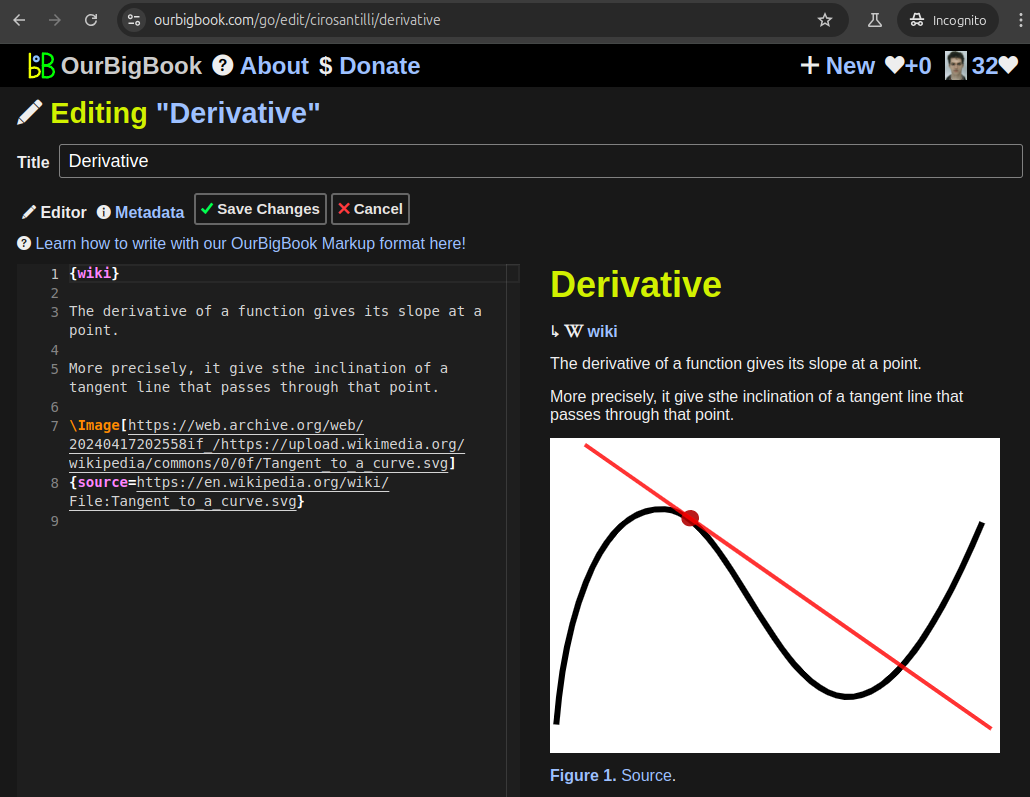
Figure 5. Web editor. You can also edit articles on the Web editor without installing anything locally.Video 3. Edit locally and publish demo. Source. This shows editing OurBigBook Markup and publishing it using the Visual Studio Code extension.Video 4. OurBigBook Visual Studio Code extension editing and navigation demo. Source. 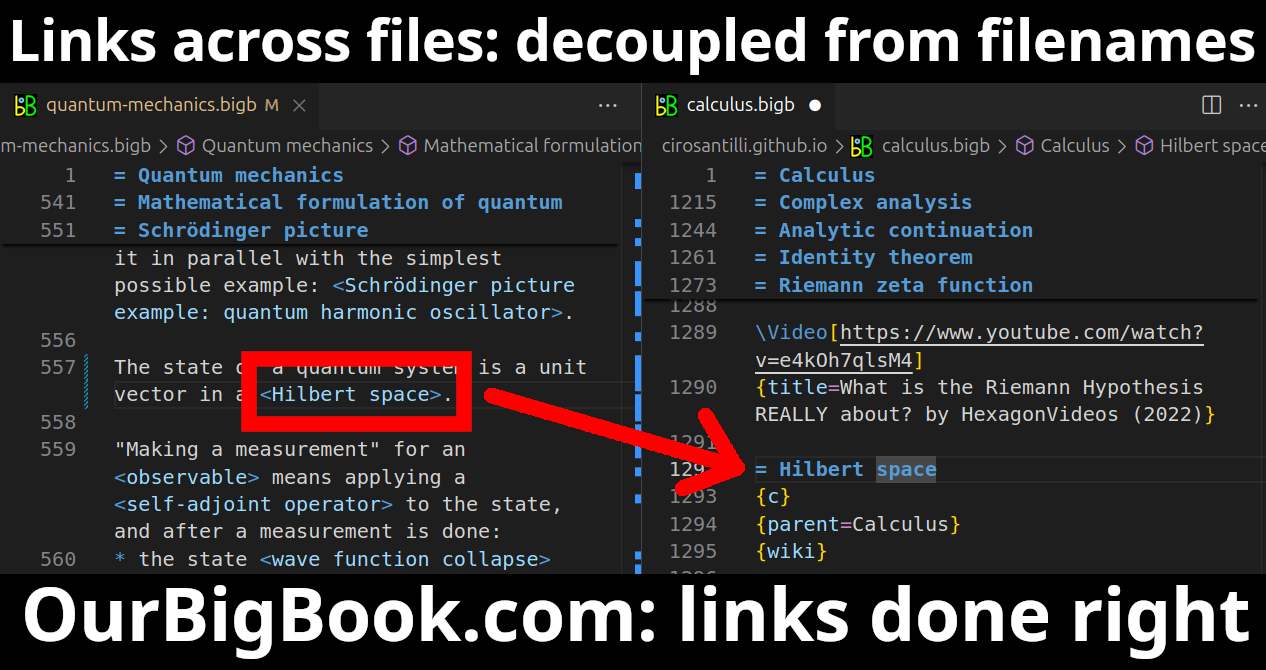
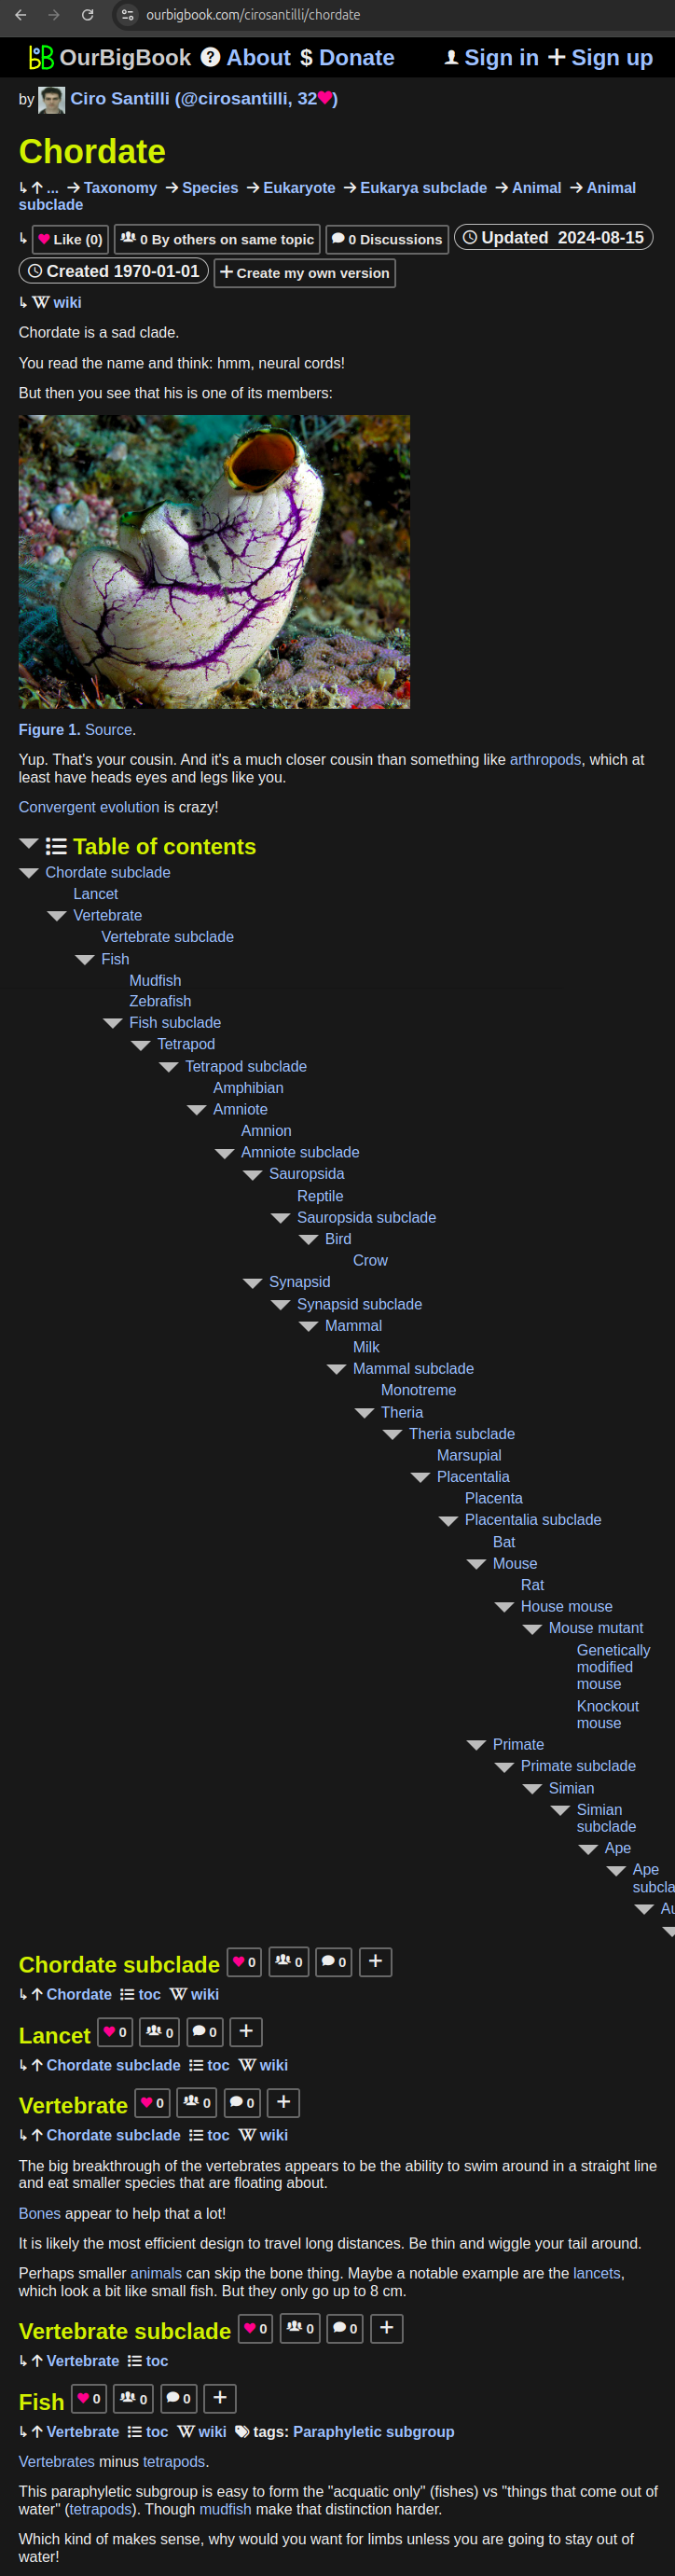
- Infinitely deep tables of contents:

All our software is open source and hosted at: github.com/ourbigbook/ourbigbook
Further documentation can be found at: docs.ourbigbook.com
Feel free to reach our to us for any help or suggestions: docs.ourbigbook.com/#contact